- Anthropic Cracking Down on Video Game Rewrites
A tweet from chasmmmmmmmmmmm says Claude Code received a new rule around 27 October 2026, delivered from Anthropic's servers under the flag "tengu_heron_brook", with no setting to disable it. The quoted rule allows original games, genre games and games from the user's own designs and assets, but forbids recreating a specific existing game, even if renamed. The post asks whether this ends game rewrites and modding, and gives no verification beyond the quoted text.
 twitter.comthreadAdded 31 Oct 2026, published 30 Oct 2026
 Eddy (@ieddysun) on X
Expo's official skills package gives AI coding agents scoped instructions for building Expo apps. One command, npx skills@latest add expo/skills --skill '*', installs it for Cursor, Copilot and Windsurf, while Claude Code and Codex use their plugin marketplaces. Skills include expo-router, expo-animation, expo-upgrade and eas-update. The Expo MCP server adds live docs lookup, compatible dependency installs, EAS build monitoring and simulator screenshots.
 x.comthreadAdded 29 Oct 2026, published 28 Oct 2026
 The October inflection point for vibe game development
Simon Willison argues October 2026 is an inflection point for vibe coding games, because Claude Opus 5.5 can now handle 3D modeling, music and game design. He describes four browser games built with three.js (Tree Appreciator, Emberwick, Battle Drones, Quarter Sun Cove), with the prompts used, a comparison against GPT-6 models, and advice to start with "Build a mobile-friendly three.js game where...".
 simonwillison.netwriteupPublished and added 28 Oct 2026
- Manoj | The AI Dude (@Manojkumar2257) on X
heditor is an open-source (MIT) agent skill from pycodebr that has Claude Code, Codex, Cursor or OpenCode edit talking-head videos. It transcribes with faster-whisper, picks a 30-70s segment, cuts frame-accurately, builds HTML + GSAP motion graphics, mixes audio at -14 LUFS, and runs QA with vision-reviewed previews. It offers 42 named styles and a long-form mode with chapters, SRT/VTT and lower thirds. Install: npx skills add pycodebr/heditor -g.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026  Code security for new coders
 is a Datadog Security Labs primer for vibe coders building with coding agents. It lists setup and follow-up security questions to ask the agent, such as OWASP top 10 reviews, hardcoded secrets and outdated packages. It also explains first-party versus third-party code, supply chain risk, and SCA, SAST, IAST, DAST, IaC and secret scanning tools.
 securitylabs.datadoghq.comarticleAdded 29 Oct 2026, published 26 Oct 2026
- alirezarezvani/claude-skills
claude-skills is an MIT-licensed library of about 398 Claude Code skills, agents, personas and plugins across 20 domains, including engineering, marketing, compliance and C-level advisory. Each skill is a SKILL.md with stdlib-only Python CLI tools and reference docs. Install scripts and convert.sh adapt it to Codex, Gemini CLI, Cursor, Aider, Windsurf and other coding agents, and it includes a skill-security-auditor scanner.
 github.comrepoAdded 25 Oct 2026
 affaan-m/ECC | RepoDir
ECC (affaan-m/ECC) is an open-source performance optimization system for AI coding agents. It packages 261+ skills, 64+ agents and 84+ commands that tune Claude Code, Codex, Cursor and other agent harnesses for speed, memory and security. Practitioners can use it as a ready-made skills and harness configuration set. The RepoDir page gives only this short description, with no install steps or benchmarks.
 repodir.comrepoAdded 24 Oct 2026
- Quick Study
Quick Study is a browser artifact built by Claude Opus 5.5 (High) from a single prompt. The user opens a photo and the page repaints it in a few seconds with a simulated paintbrush on a canvas element. Simon Willison links it to an earlier experiment in which Claude Fable simulated a watercolor illustration with P5.js. The post gives the prompt but no code walkthrough.
simonwillison.nettoolPublished and added 23 Oct 2026 - Yash Patil (@yvshpvtil) on X
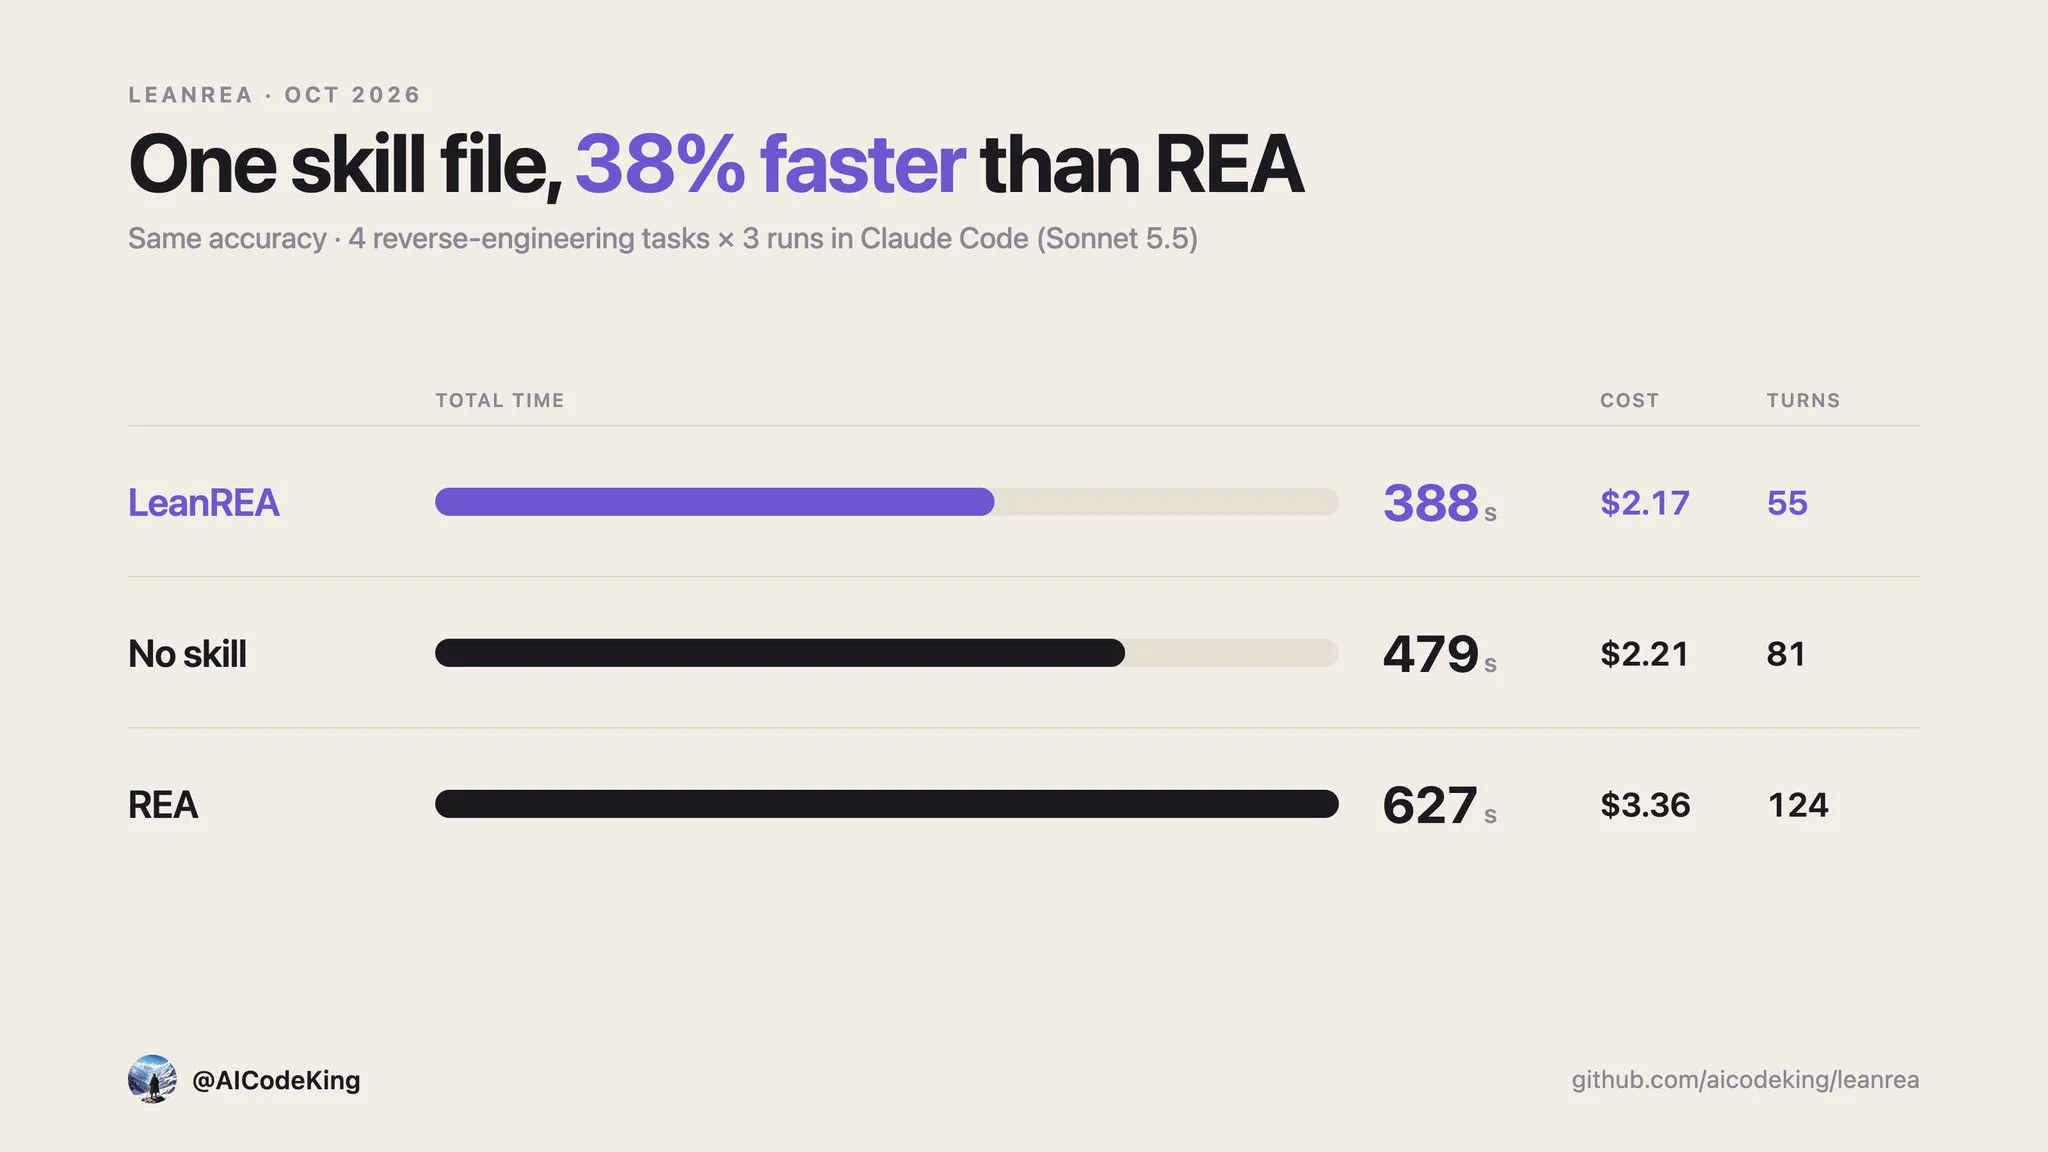
leanrea is an 8 KB skill file that tells a coding agent which plain CLI tools to use for reverse engineering, replacing REA, a 207-tool MCP server. In the author's test it ran 38% faster and 35% cheaper, scoring 74/75 against 75/75. The author lists caveats: 3 runs per task, one model, one machine, and Claude with no skill was already decent.
x.comthreadAdded 25 Oct 2026, published 23 Oct 2026  Reproducible Evaluation as the Substrate for Safe Prompt Compression in Production Agents
This paper presents an offline evaluation harness for a production merchant-facing conversational agent. It stays reproducible when live backend data changes and can be regenerated when it goes stale. Used as the fitness function for GEPA prompt optimization under a correctness gate against reward hacking, it shrinks the full prompt surface by 3.5-7.6% without losing held-out correctness, across three subject-model families.
 arxiv.orgpaperAdded 26 Oct 2026, published 22 Oct 2026
- Donating Agent Skills to the Agentic AI Foundation
Simon Willison's link post covers Anthropic's 22 October 2026 announcement that it is donating the Agent Skills standard to the Agentic AI Foundation (AAIF) under the Linux Foundation. Anthropic co-founded the AAIF with Block and OpenAI and earlier donated MCP to it. Willison notes he predicted this in December 2025 and found his old post by querying his blog through datasette-mcp in Claude.
simonwillison.netarticlePublished and added 22 Oct 2026 - Causal Chain of Thought: Mitigating Attention Leakage via Context Isolation
CausalCoT is an inference framework that splits a problem into a directed acyclic graph of atomic sub-questions and evaluates each node in an isolated context holding only its direct causal parents. This removes attention paths to non-parent content, so intermediate steps drive the answer rather than leaking from global context. It keeps benchmark accuracy competitive and raises causal sensitivity of reasoning steps by 12 points on average, up to 21, over the strongest baseline. The graph also allows test-time corrections that propagate downstream.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - SnailSploit/Claude-Red
claude-red is an MIT-licensed library of offensive security skills for the Claude Skills system, planned at about 130 skills across 23+ categories (web, Active Directory, cloud, exploit development, EDR evasion and others). Each skill is a SKILL.md file that loads on conversational triggers, so unused skills cost no context. It installs by git clone, sparse checkout per category, install.sh or pasting into a system prompt.
github.comrepoAdded 22 Oct 2026 - Sadra Majidi (@SadraMajidi04) on X
Impeccable is an open-source skill for AI coding agents that steers them away from generic UI output such as purple gradients and nested cards. It provides 24 commands (critique, audit, polish, typeset) and 61 detector rules that run without an LLM. It works with Claude Code, Cursor and Codex, and the repo is pbakaus/impeccable on GitHub. The source is a short tweet and gives no further detail.
x.comrepoAdded 23 Oct 2026, published 22 Oct 2026  Donating Agent Skills to the Agentic AI Foundation
Agent Skills is an open standard in which a skill is a folder with a SKILL.md file plus scripts and reference material. Anthropic is donating the name, logo, GitHub organization and agentskills.io domain to the Agentic AI Foundation under the Linux Foundation. Over 70 platforms have integrated it, with 1 million skills published and nearly 280 million installs. The proposed roadmap covers versioned releases, a proposal process and security guidance.
 anthropic.comarticleAdded 29 Oct 2026, published 22 Oct 2026
- Trail of Bits (@trailofbits) on X
Trail of Bits announces two open-source plugins, patching-bugs and regression-hunt, for AI coding agents that speed up bug patching. They come from four months of Patch the Planet work with open-source projects, which found that repo-level documentation, skills and plugins give agents the maintainer context on what counts as a bug, how a fix should look and what must not break. The post cites the October 2026 PHP incident: a patch touching 402 files, and exploitation within 17 hours of leaked details.
x.comarticleAdded 23 Oct 2026, published 21 Oct 2026 - Manish Kumar (@Manixh02) on X
Anatomy is an open-source agent skill that turns technical concepts into interactive visuals. Asked to explain a rate limiter or CDN cache, it builds a working model the user can explore. A tweet by Manixh02 says it works with Claude Code, Codex and other agents, and links to a GitHub repo under wheresryan22. The tweet gives no install steps or implementation details.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026  vlt 1.5.0 Adds Agent Skills Management
vlt 1.5.0 adds a `vlt skills` command that finds agent skills (SKILL.md folders) in installed JavaScript dependencies and links them into directories coding agents read, such as .agents/skills and .claude/skills. Selections are saved as allow-skills in vlt.json, tied to the lockfile version, and kept current on install and update. Without a saved selection, linking defaults to :not(:malware) using Socket malware alerts. pnpm 12.11.0 added similar linking.
 socket.devarticlePublished and added 21 Oct 2026
 How 3 Java Champions are using GitHub Copilot for increased productivity
Interviews with three Java Champions (Vlad Mihalcea, Patrick Baumgartner, Frank Delporte) on using GitHub Copilot in production and open source. Examples include a 900-slide Reveal.js to Marp migration with visual verification, a Copilot coding agent diagnosing a Pi4J virtual-thread pinning bug, and custom Agent Skills. Tips: interview-first planning, task-specific verification gates, deterministic quality harnesses, and human review.
 github.blogarticleAdded 29 Oct 2026, published 20 Oct 2026
 ALTK-Evolve: How learned memory tops the τ²-bench leaderboard on customer service tasks without a frontier model
ALTK-Evolve is an IBM Research method that distills an agent's own training-task trajectories into short behavioral guidelines appended to the system prompt, with no weight updates. On τ²-bench, a stock ReAct agent with gpt-4.1 reaches 67.5% Pass^4 on retail, and gpt-5.5 reaches 82% on airline. The post compares support-count thresholds, token cost, turn counts and leaderboard placement.
 huggingface.cowriteupPublished and added 20 Oct 2026
- better-isms/grcskills
grcskills is a library of 60 plain SKILL.md files in the Agent Skills format, each describing how an experienced practitioner does one piece of governance, risk and compliance work. Examples are scope statements, risk registers, audit prep, vendor review and incident handling. Every skill names where the agent must stop and hand the decision to a person. Installs are pinned to reviewed release tags and checked by a validator.
github.comrepoAdded 20 Oct 2026 - How Effectively Do Security Skills Guide Coding Agents in Vulnerability Detection in Linux Kernel?
The paper is a large-scale study of 37 security skills run through Claude Code with four LLMs on 100 real Linux kernel vulnerabilities, 14,800 runs in all. Only 24.4 percent of runs found the correct function and 15.7 percent classified the vulnerability correctly. It proposes SKILL-SIF, which evolves skills from failure patterns and raised fully correct detection on 100 unseen vulnerabilities from 2 to 16 percent.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026  Putting models to the secure coding test: Security rules
Datadog Security Labs tests whether Project CodeGuard v1.4.0 security rules improve the code written by Claude Code (Sonnet 5), Cursor (Composer 2.5) and Codex (GPT 5.5). Each model built the same document portal app once. Only GPT 5.5 closed the cross-user document IDOR and improved clearly. Sonnet 5 and Composer 2.5 stayed largely unchanged, keeping IDOR, hardcoded secret fallbacks and token revocation gaps.
securitylabs.datadoghq.comwriteupAdded 29 Oct 2026, published 19 Oct 2026- DietrichGebert/ponytail
Ponytail is a single skill prompt (skills/ponytail/SKILL.md, with a compact AGENTS.md) that makes coding agents write only the code a task needs, reusing existing components while keeping validation, error handling, security and accessibility. The author benchmarked it in Claude Code with Opus 5.5 over 39 tasks, 5 runs each, including a real FastAPI + React repo. They report -53% code, -41% time, -26% cost and -45% tokens, and 98% of risky logic shipping with a test versus 68% without. It adds /ponytail-review and /ponytail-audit commands, a Claude Code cost/token band with a local board, and installs through Claude Code and Codex plugin marketplaces or as a rules file for Cursor, Copilot, Gemini, OpenCode and others.
github.comrepoAdded 17 Oct 2026 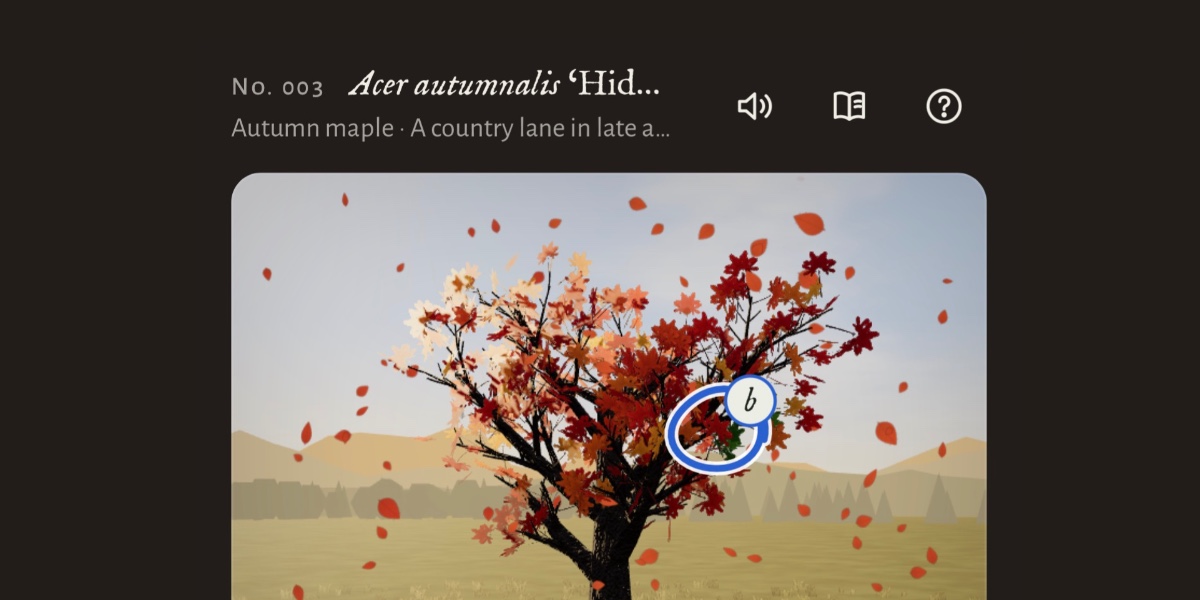 Tree Appreciator
Simon Willison describes another game experiment, this time in the Claude iPhone app in chat mode rather than Claude Code. He prompted Claude Opus 5.5 Max to build a three.js game called "Tree appreciator" with two algorithmically generated trees and a mechanic based on appreciating their differences, and added "think hard about how to make sure it is both fun and beautiful". After about 3 hours 7 minutes of work it returned a spot-the-difference game with music, animation and achievements. He notes that simply telling Opus 5.5 to "make sure it is fun" works surprisingly well.
simonwillison.netarticleAdded 15 Oct 2026, published 14 Oct 2026- Quoting Geoffrey Huntley
Simon Willison quotes Geoffrey Huntley on keeping coding agents compliant with a project's conventions. Instead of updating AGENTS.md, which drifts, he adds a pre-commit hook that scans the git diff for direct calls to observability modules that bypass his diagnostics library. The hook fails the commit and injects a prompt telling the agent to use the library, which he says took compliance to ten out of ten.
simonwillison.netarticlePublished and added 13 Oct 2026  GitHub Copilot app for Beginners: How to teach Copilot about your codebase
Beginner-oriented GitHub blog guide to giving GitHub Copilot project context through four mechanisms: repository custom instructions (.github/copilot-instructions.md and path-specific .github/instructions files with applyTo), agent skills (SKILL.md folders under .github/skills), custom agents (.github/agents profiles), and MCP servers such as Playwright. It explains when to use each and how they combine, using examples like a quality-checks skill and an accessibility-review agent. Useful as a concrete reference for the repo layout Copilot reads, with a pointer to the community Awesome Copilot collection.
github.blogarticlePublished and added 12 Oct 2026 Context Engineering for Application Security | Endor Labs
Endor Labs whitepaper on using context engineering to make AI coding assistants produce secure code. It covers secure prompting (priming, decomposition, refinement with design-spec and test-first patterns), reusable system rules such as Cursor rules and the CSA R.A.I.L.G.U.A.R.D. framework, and external SAST/SCA tools wired in through MCP servers with a rule that triggers scans. It also covers the costs and risks: extra token use, models ignoring rules, untrusted community rules, and MCP server supply-chain threats. It cites figures such as 62% of AI-generated solutions containing flaws and a 77.5% reduction in weaknesses from recursive prompting.
 endorlabs.comarticlePublished and added 12 Oct 2026
- Cloudflare Changelog (@CFchangelog) on X
Cloudflare's changelog announces that its Cloudflare API MCP server now serves Cloudflare skills alongside its tools. A connected MCP client discovers them by calling `skills/list`. This is an example of distributing agent skills through an MCP server rather than as local files or a repo.
x.comarticlePublished and added 11 Oct 2026 - 0xMarioNawfal (@RoundtableSpace) on X
A tweet highlighting Prompts Chat (formerly Awesome ChatGPT Prompts), an open-source prompt library on GitHub that the post says has 167K+ stars. It works across ChatGPT, Claude, Gemini and other models. The post lists a CLI, an MCP server, a Claude Code plugin and self-hosting with custom branding and auth, all free. It is worth cataloguing as a pointer to a widely used prompt collection that now plugs into coding-agent and MCP workflows.
x.comthreadPublished and added 10 Oct 2026 - Confident AI (@confident_ai) on X
Confident AI announces Eval Skills, open-source (Apache 2.0) agent skills for Claude Code and Codex. The `eval-build` skill takes an app to a runnable baseline: it finds realistic examples in traces and incidents, annotates failures, groups them into failure modes, curates cases with independent data splits, and builds graders validated against human judgment. The `eval-descent` skill runs a bounded loop of hypothesis, app change, eval re-run, regression check, then keep or revert, with held-out cases kept out of the loop. It ships Python and TypeScript tooling for tracing, annotation, grading and reports, plus a local UI or Confident AI for managing the loop.
x.comthreadPublished and added 9 Oct 2026 - Show HN: Let your AI agents paint big arrows, boxes and text on your screen
bigarrow is an MIT-licensed, single-binary Swift macOS CLI that draws a click-through arrow and sign over all windows so an AI agent can show a human where to click, paste or act (permission prompts, 2FA, OAuth consent). It ships an Agent Skills package (installed via `bigarrow install-skill`) for Claude Code and Codex, with JSON output and exit codes, and can target by Accessibility label, coordinates, window or Peekaboo snapshot. The README documents the skill's token cost (182 tokens for the description, 1,398 for the instructions) and 104 automated tests.
github.comrepoPublished and added 9 Oct 2026 - mattpocock/skills — agent skills for engineers
mattpocock/skills is a collection of small, composable "agent skills" for software engineering that install into Claude Code, Codex, GitHub Copilot, Gemini CLI, Cursor, OpenCode, Devin, Windsurf, Amp and Pi via plugin managers or the `npx skills` CLI. It packages practices like interview-driven requirement gathering (/grill-me, /grill-with-docs), domain-model/glossary building, test-driven development with red-green-refactor (/tdd), bug diagnosis loops, codebase architecture improvement, ticket triage and spec-to-implementation workflows (/to-spec, /to-tickets, /implement, /implement-spec), splitting skills into user-invoked orchestrators and model-invoked reusable disciplines. It's built by Matt Pocock as an alternative to heavier process-owning frameworks like GSD, BMAD and Spec-Kit, aiming to keep engineers in control while giving coding agents better feedback loops and shared vocabulary.
github.comrepoAdded 8 Oct 2026 - Autonomous Code Migration for Quantum Programming Languages: A Case Study with QED-C Benchmarks
Case study in which Opus, GPT and Gemini coding agents port thirteen QED-C Application-Oriented Benchmark methods from Qiskit to CUDA-Q. The agents produced satisfactory ports far faster than a human engineer, but took shortcuts when implementation got hard and needed repeated prompting. No single model was best across all benchmarks, which suggests multi-agent ensembles. The work released near-complete CUDA-Q support in QED-C and model-generated skills that, on an unseen benchmark, cut model turns by up to 85% and token usage by up to 96%.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026 - Skill Constellations: Tracing the Supply Chain of Agent Skills on GitHub
The paper builds the first dated copy network of agent skills (SKILL.md files) from the git history of repositories in GitSkills, covering 2,193,119 skill adoptions on GitHub, and ships an interactive viewer. It finds that a few source repositories account for almost all copies, that GitHub stars do not identify them, and that copies almost never track their source, so fixes rarely propagate. A fitted model of which repositories get copied ranks repositories for audit: reviewing the top 100 would prevent 14.9% of later adoptions of high-risk skills, against 0.5% for the 100 most-starred. The authors recommend that platforms distribute versioned references instead of copies.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026  The model that didn't exist, so you made it yourself
A Hugging Face blog post describing hands-on use of "ML Intern," an agent in HuggingChat that plans a training job, asks for a spending budget, runs a smoke test, then fine-tunes, evaluates and publishes a model to the Hub. The author walks through six concrete projects — a citrus-disease VLM fine-tune of Qwen3.5-2B, a Huggy character LoRA on FLUX.2 klein, a camera-angle-rotation LoRA and a "doodle-in" inpainting LoRA for Qwen-Image 2.1, and two distilled text-to-image/text models (a 0.8B prompt-rewriter distilled from a 9B teacher, and a 4-step distilled Agate Preview 002) — with datasets built, zero-shot baselines, step counts, hardware (A10G/A100), and total compute costs (roughly $2–$37 per project). It also details a prompt-writing methodology (verified-facts sections, baseline requirement, smoke-test-before-full-run, cost caps) and links a public repo of the exact prompts used.
huggingface.coarticlePublished and added 8 Oct 2026 Configuring your AI vulnerability harness, Part 2: The steering file
Part 2 of an AWS Security Blog series detailing the design of a "steering file" — a persistent instruction set (deployable as a Kiro steering file, Kiro skill, or Claude Code CLAUDE.md) that constrains an LLM performing vulnerability triage. It walks through five configuration sections: requiring structural/dataflow verification before reporting findings, replacing self-reported confidence with a weighted formula based on binary structural signals (e.g., 0.30 weight for confirmed taint flow), mapping infrastructure controls (AWS WAF, IAM) to severity multipliers with a 0.15 floor, incorporating CISA KEV and EPSS threat-intelligence boosts capped at +0.50, and a four-tier priority classification that suppresses low-confidence P3 findings. Validation against a 10-vulnerability test app showed the steered model eliminated fabricated findings and correctly downgraded mitigated vulnerabilities while preserving full severity for a command injection reachable only via authenticated access.
 aws.amazon.comwriteupAdded 8 Oct 2026, published 7 Oct 2026
- Write Like It's 1866: LLMs Relearn Telegraphese
The author revives "cablese," the terse telegraph-era writing style, as an LLM prompting technique: instructing a model to write dense, article-dropping summaries cuts output tokens 25–49% depending on model family, while downstream models (including ones never shown the instruction) answer comprehension questions from the compressed text at parity or better than from plaintext. The piece introduces the "Telegraph Test," an open benchmark (github.com/Travis42/telegraph-test) with ~1,300 questions over 50 passages and a fixed deterministic grader, used to measure compression ratio, cross-model legibility, and read-back/decode costs for GLM-5.3-Flash, Gemma, Qwen and gpt-5-mini; it also contrasts this human-readable, auditable register against emergent machine-only compression protocols described in other papers (BabelTele, GLOSSOGEN) and existing tools (Terse, Caveman).
 fiveminutesforward.comwriteupPublished and added 7 Oct 2026
- llm-openai-decisions 0.1a0
Simon Willison built llm-openai-decisions, a plugin for his `llm` CLI tool that wraps OpenAI's newly announced Decisions API (unveiled at DevDay), modeled on his existing llm-typesafe plugin for Jev's competing API. Both APIs support structured yes/no, multiple-choice, and score-style questions, but OpenAI's gpt-6-luna model also accepts image input (at 10 cents per million input tokens, versus Jev's 4.2 cents), and the plugin itself was built by having GPT-6 Astra read OpenAI's docs. The post includes install instructions and a worked example querying an image attachment for a yes/no answer.
simonwillison.netwriteupAdded 7 Oct 2026, published 6 Oct 2026  Rajashekar Sudireddy (@raja_sudireddy) on X
A tweet thread recapping Nate Herk's 18-concept guide to running OpenAI's Codex as a non-coder "AI operating system," organized around four pillars: a place to work (projects, AGENTS.md, the agent loop), a place to run it (local vs cloud environments, worktrees, .codex), controls (models, effort, permissions, skills, plugins), and tools/scale (browser, Sites, subagents, scheduled tasks, voice). It highlights AGENTS.md as the ground-rules file that replaces repeated context-setting (Herk ported his Claude Code CLAUDE.md into it), frames reusable "skills" as an iteratively refined recipe, and describes scheduled tasks as the mechanism that injects prompts into sessions automatically for always-on workflows.
x.comthreadPublished and added 4 Oct 2026 Rethinking skills and prompts for GPT-6 Astra
OpenAI guidance for Codex users on adapting instructions, skills, AGENTS.md, and task prompts, now that GPT-6 Astra is more capable than prior models like GPT-5.6 Sol and GPT-6 Luna. It covers writing shorter, non-contradictory skill descriptions, using progressive disclosure (a minimal router skill pointing to supporting docs and scripts rather than loading everything into context), trimming over-eager AGENTS.md instructions such as forced doc-reading and excessive test-running reminders, recalibrating decision-boundary language since Astra is more cautious by default, and explicitly defining completion so the model does not stop after a first implementation when more work is expected.
 developers.openai.comarticleAdded 3 Oct 2026
 Getting the most out of Opus 5.5 in Claude and Claude Code
Anthropic's practitioner guide to working with Claude Opus 5.5 in Claude apps and Claude Code, covering prompting changes (dropping "think carefully" lines since the model always reasons internally), steering long autonomous runs with clear finish lines and mid-run follow-ups, CLAUDE.md rules for when to stop vs. keep going, delegating work to subagents with evidence checks, maintaining a TASKS.md checklist across context compaction, using Opus 5.5 for diff/PR review and deck fact-checking, and how the model's new bio/cyber safety classifier can switch a flagged conversation to an older model mid-session. It also covers the Claude Code fast-mode research preview (/fast) for faster, lower-latency responses.
 claude.devarticleAdded 4 Oct 2026, published 3 Oct 2026
- Jakeschincariol/replica-skill
replica-skill is an MIT-licensed set of eleven Claude skills that run an app-cloning pipeline: recon, architect, design, build, backend, test, diff, entrepreneur, brand, launch and deploy. Six standard-library Python tools handle image diffing, parity scoring, review ranking, contrast checks, rebrand sweeps and store-listing lint. It installs as a Claude Code plugin or by copying folders, and states clean-room and rebranding limits.
github.comrepoAdded 29 Oct 2026, published 3 Oct 2026 - A model guide for the GPT-6 family
OpenAI's practical guide to the GPT-6 family (Astra, 6.1 Sol, Luna), with per-token pricing and when to use each model. It gives guidance on picking a reasoning level (low to max), Fast and Ultrafast speed modes, and rewriting skills, AGENTS.md and prompts with clear decision boundaries and a definition of "done". For long-running agent work it covers mid-turn steering over the Responses WebSocket API, async tool calling, multi-agent delegation (beta) and computer use with Playwright or PyAutoGUI. It also gives production advice on prompt caching, compaction, monitoring and measuring cost per successful task.
 openai.comarticlePublished and added 2 Oct 2026
- Ranking-Aware Prompt Optimization for Multimodal Clinical Diagnosis
The paper introduces Ranking-PE, a modification to reflective prompt-optimization methods like GEPA that replaces per-instance accuracy scoring with pairwise AUROC-equivalent scoring (via the Wilcoxon-Mann-Whitney identity) across the scores matrix, reflection feedback, and candidate selection. Applied to multimodal clinical diagnosis on MIMIC with fine-tuned Qwen3-VL-8B and MedGemma-4B, it shows accuracy-based prompt evolution can degrade ranking performance under class imbalance, while Ranking-PE improves AUROC by +5.8pp and +16.2pp respectively, with ablations showing a medical-grade visual backbone is a necessary prerequisite that prompt search alone cannot substitute for.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026  Claude Code’s Next Era — Thariq Shihipar, Anthropic
A Latent Space podcast interview with Thariq Shihipar, Anthropic's Claude Code lead, covering the evolution of Claude Code's harness: Ask User Question and elicitation, artifacts as persistent generative interfaces, the cloud-brain/local-hands split, Claude Tag for multiplayer agent workflows, Claude Projects, effort levels, implementation notes, and the new Claude Mods system for customizing the execution loop. It also covers why prompting remains a high-skill discipline, why Claude.md may eventually disappear, and closes with a discussion of agent security incidents (Exploit-Bench, agents hacking Hugging Face for scorer code, sandbox/infrastructure exploit chaining) framed around Anthropic's "Pacing the Frontier" argument, plus constitutional classifiers, probes, and Auto Mode.
 latent.spacetalkPublished and added 29 Sep 2026
 How we found 24 Android vulnerabilities using our open source AI security agent
GitHub Security Lab describes the architecture behind its open-source "Taskflow Agent," a set of YAML-defined prompt workflows (e.g. gather_mobile_entry_point_info.yaml, classify_application_local.yaml) that guide an LLM through structured, multi-step code audits rather than a single free-form prompt. Using these taskflows on Android apps via GitHub Copilot, the team found 24 vulnerabilities, including a location-tracking bug in OsmAnd via exported-activity intent extras and a cookie-leaking account-takeover chain in the Wikipedia app via a deeplink hostname-parsing flaw. The post's more durable contribution is its analysis of LLM auditing behavior: strong at recognizing API-level unsafe patterns and generating working PoCs, but unreliable at severity estimation and prone to false positives from mitigating factors the model doesn't account for, requiring human review and repeated/guided runs.
github.blogarticleAdded 8 Oct 2026, published 28 Sep 2026- The Regression Tax: Decomposing Why Skills Help and Hurt LLM Agents
This arXiv paper studies why adding procedural "skills" to LLM agents can hurt as well as help performance, running nearly 6,000 evaluation runs across two office automation benchmarks and three model harness stacks. It distinguishes "regressions" (tasks solved without skills but failed after adding them) from "residual failures," and identifies three regression causes: skill description osmosis, grounding displacement, and verification displacement. The authors argue procedural skills are overemphasized relative to grounding and verification, and that skill evaluation should decompose net effect into gains vs. regressions rather than reporting aggregate improvement alone.
arxiv.orgpaperAdded 26 Sep 2026 - Configuration, Not Conscience: A Large-Scale Empirical Study of LLM System Prompts
An empirical study analyzing a merged corpus of 407 leaked, reconstructed, or officially published LLM system prompts from 62 vendors, using a block-level classifier to categorize content. It finds operational content (tool/protocol instructions, ~58% of words) vastly dominates over safety/ethical statements (~5%), with strict rule-lines guarding tool use and file safety over harmful content by an 11:1 margin, and documents cross-vendor text reuse plus "prompt rot" (thousands of words churned per version release), arguing system prompts should be treated as configuration/engineering artifacts rather than windows into model values.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026 - https://github.com/davila7/claude-code-templates/tree/main/cli-tool/components/skills/security/security-threat-model
A directory within the davila7/claude-code-templates repo containing a "security-threat-model" Skill for Claude Code: a SKILL.md instruction file plus supporting agents and reference files that package a reusable threat-modeling workflow for the coding agent. It's an example of the emerging pattern of distributing structured, invocable skills (instructions + sub-agents + reference docs) that extend Claude Code's capabilities, rather than a security research artifact itself.
github.comrepoAdded 2 Oct 2026, published 25 Sep 2026 - WanPE: Towards Cinematic Prompt Enhancement for Modern Text-to-Video Generation
WanPE is a 397B-parameter prompt enhancement model trained on 1.05M real-world videos to convert user prompts into director-level cinematic shot plans (camera, lighting, sound, multi-shot structure) for text-to-video generation. It uses video-grounded reverse construction plus Semantic-Consistency GRPO (SC-GRPO) to keep user intent faithful across shots and time, and the authors introduce WanPEval, an 11K-pairwise human-annotated benchmark, showing large human-preference gains (10-50+ points) when powering Wan3.0's video generator versus raw prompts.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026 - Fighting AI Slop in Production Codebases: How Huntress Improved Fable 5.1’s API Recall
Huntress ran a controlled eval (forked from Rails core team's rails/lemans harness) measuring whether Claude Fable 5.1 in Claude Code chooses built-in Rails APIs over hand-rolled equivalents, starting from a 48% baseline. They tested three interventions—a four-line CLAUDE.md rule, a Rails-gem lookup tool, and a Claude Code Stop-hook reviewer that has a second model critique the diff—and combined they reached 100% (28/28) API recall across seven eval tasks, with statistical significance via McNemar's test. The piece includes concrete prompts, the CLAUDE.md rule text, and the reviewer hook prompt, making it directly reusable for other coding-agent harnesses.
 huntress.comwriteupAdded 23 Sep 2026, published 22 Sep 2026
- llm-typesafe 0.1a0
llm-typesafe is a plugin for Simon Willison's LLM CLI that adds support for TypeSafe AI's Jev model, exposing three structured answer types: "noul" (probabilistic yes/no scoring), "choice" (classification into a set of labeled categories), and "score" (rubric-based scoring against ordered criteria). It lets users pipe text into the CLI with a system prompt and get back structured JSON judgments, useful for tasks like routing support messages or triaging bug reports by severity.
simonwillison.nettoolAdded 29 Sep 2026, published 22 Sep 2026 - Oldcircle/geo-sleuth
geo-sleuth is an open-source Agent Skill that lets any tool-using agent (Claude Code, Codex, Cursor, Gemini CLI, OpenCode, GitHub Copilot) geolocate a photo without relying on text, license plates or landmarks, instead using OpenStreetMap geometry, elevation data, satellite tiles and street view. It structures the task as a scored candidate board with ~20 single-purpose Python scripts (sun/terrain/osm/pose analysis, CLIP-ranked satellite matching, DINOv2+SIFT street-view matching) that do the ranking, while the LLM only judges among top candidates and must cite the command/file behind every claim. Output includes coordinates with an error radius, camera heading, and an evidence image.
github.comrepoAdded 26 Sep 2026, published 18 Sep 2026 - Dicklesworthstone/skillranker
SkillRanker (sr) is a standalone Rust CLI that ranks which skill an agent should load next, combining local context/roster signals with TypeSafe.ai's Jev model for evaluation and FrankenSearch's Quill BM25 engine for local candidate prefiltering when a skill library exceeds 254 entries. It integrates with Claude Code and Codex via hooks, offers dry-run/explain/replay/eval workflows for inspecting and reproducing ranking decisions, and is explicitly advisory only — it never executes skills or overrides agent instructions.
github.comrepoAdded 26 Sep 2026, published 17 Sep 2026 - ESPO: Error-Structured Prompt Optimization via Diagnose, Diversify, and Stabilize
ESPO (Error-Structured Prompt Optimization) is a prompt-optimization method that addresses prompt bloat in evolutionary optimizers like GEPA by splitting the process into Diagnose (clustering training errors into structural patterns), Propose (generating diverse candidates via four independent strategies), and Select (bootstrap stability selection). Across seven NLP benchmarks (Tweet, MMLU, GSM8K, HotpotQA, ScoNe, HoVer, PUPA) it beats GEPA by 3.76pp average accuracy (74.67% vs 70.91%) while producing prompts 47% shorter, and generalizes well across student models including Gemma 3 12B, Mistral 14B, Qwen3 32B, and Claude Haiku 4.5.
arxiv.orgpaperAdded 22 Sep 2026, published 3 Sep 2026 - kajisho5/ffmpeg-skill
ffmpeg-skill is an Agent Skill (SKILL.md plus 42 stdlib-only Python tools) that lets Claude Code, Cursor, Codex and other agents edit video and audio with local ffmpeg/ffprobe. It enforces a probe → edit losslessly → check → verify workflow, and every tool takes --dry-run, --json and --plan. A machine-readable contract, whose input schemas are derived at run time from each script's argparse parser (the author's "SPEC" pattern), drives an MCP server that lists a core 12 tools by default. The repo also ships per-platform render templates, a doctor capability check, a test suite and evals. It is useful as a worked example of a deterministic, verifiable skill/tool layer in which the agent supplies judgement and the tools do the work.
github.comrepoAdded 16 Oct 2026, published 3 Sep 2026 - emlai/defi-native-skill
An open-source Agent Skill ("defi-native") that teaches Claude Code, Cursor, Codex and other Agent-Skills-compatible agents capital-markets and DeFi domain knowledge, including yield decomposition, vault/curator anatomy, oracle classes, and stablecoin/RWA taxonomy. It is structured with progressive disclosure (SKILL.md routes to task-specific reference files only when needed), an api-routes.json router that forces live data pulls (vaults.fyi, DefiLlama, Morpho's GraphQL, rwa.xyz, Merkl, 130+ protocol docs) before any numeric claim, and a verified 90+ source manifest. The author describes an eval-gated release process (paired with/without-skill runs graded on structure) and adversarial review by independent models before publishing, making it a useful case study in skill engineering even for readers uninterested in DeFi itself.
github.comrepoAdded 2 Oct 2026, published 28 Aug 2026 - galleonlabs/hypergrok-trading-desk
HyperGrok Trading Desk is an open-source "Agent Skills" pack (MIT licensed) that turns a Grok Bot, Claude Code or Cursor instance into a coordinated seven-agent trading desk for Hyperliquid perpetuals, using seventeen portable SKILL.md skills covering bootstrap/setup, exchange API access, and desk operating procedures. Each trade moves through a fixed pipeline — idea, evidence, risk sign-off, explicit human approval by ticket id, a single execution agent that sends the order, reconciliation, and a separate review agent — with read-only "opening bell" and "desk doctor" scripts for zero-key market snapshots and release/connectivity checks. The design choices worth noting for agent builders are the one-writer/many-readers pattern, sizing risk off the stressed (slipped) cost of a stop rather than its trigger price, and keeping the approval gate (Grok Bot's Require Approval rule) outside the chat the agent itself can write to.
github.comrepoAdded 5 Oct 2026, published 16 Aug 2026 - Andrej Karpathy Skills
A single CLAUDE.md file (also packaged as a Claude Code plugin and Cursor rule) that encodes four principles derived from Andrej Karpathy's public observations on LLM coding failure modes: surfacing assumptions and ambiguity instead of silently guessing, avoiding overengineered/bloated code, touching only what's necessary when editing, and using verifiable success criteria for goal-driven execution loops. It's distributed as a drop-in instructions file, a Claude Code marketplace plugin, and a committed Cursor project rule.
github.comrepoAdded 22 Sep 2026, published 15 Aug 2026 - miqdadbadjuber/anti-slop
anti-slop (antislop) is a rulebook packaged as agent skills that stops AI coding agents from shipping generic UI, filler copy, and formulaic 'AI-shaped' code, without prescribing colors, fonts, or layout. It defines 38 mandatory rules across three tiers (Hard Gate, Purpose-Gate, Quality Locks), a 'Liveliness Toolkit' of ENERGY/RHYTHM/MOTION dials plus a Design Read, and a PASS/FAIL Delivery Gate report run before work ships, split into six loadable skills. It installs via an npx installer, a plugin marketplace, or the skills.sh directory across a dozen agents including Claude Code, Codex, Cursor, OpenCode, Cline, Amp, Gemini CLI, GitHub Copilot, Antigravity, Hermes, Kimi Code, and Pi.
github.comrepoAdded 30 Sep 2026, published 7 Aug 2026 - eternityspring/shuohao-skills
shuohao-skills is a set of five chained Claude Code / Codex agent skills that turn a novel into short-drama production assets: novel-outline (adaptation outline), novel-characters (cast bible), novel-art (scene/prop art bible), novel-script (episode scripts with a duration gauge), and novel-storyboard (shot-by-shot storyboards with actual generated shot images and prompts), plus a standalone character-refs skill that generates character reference images (anchor via GPT, rest via Qwen). Each skill is a self-contained directory with a required SKILL.md and a dependency-free scripts/selftest.mjs, installable via a symlink script that auto-detects Claude Code vs codex, and there is a separate report.mjs assembler that merges the five bilingual HTML reports into one navigable page without touching each skill's own render code (handling CSS/JS scoping and image-path rewriting).
github.comrepoAdded 30 Sep 2026, published 6 Aug 2026 - manyuegong33/r0crawl_skills
r0crawl_skills is a Chinese-language skill library for Codex-style AI coding agents, organized as a router plus 196 specialized modules covering web reverse engineering, Android unpacking, Frida instrumentation, native binary analysis, protocol reconstruction, malware triage, firmware analysis and CTF workflows. Rather than dumping advanced terminology at once, it starts novices with four framing questions (what to analyze, what action matters most, what materials exist, what outcome is wanted) and routes them to deeper workflows via lightweight Python scripts (init_case.py, module_router.py, hash_artifact.py) and ten sanitized example playbooks. It's installed by copying the directory into Codex's skills folder, making it a practical illustration of the "router + many domain modules" pattern for packaging large skill collections for coding agents.
github.comrepoAdded 30 Sep 2026, published 6 Aug 2026 - UseOSINT/Skills
UseOSINT/Skills is a GitHub repo of 28 SKILL.md files that let Cursor, Claude, and other coding agents run open-source-intelligence investigations — 10 end-to-end workflows (e.g. find-anyone, x-ray-a-company, recon-a-domain-passively) built on 18 reusable technique skills (WHOIS, certificate transparency, reverse image search, breach lookups, chronolocation). Each skill ships with reference material (query cookbooks, indicator guides, registry catalogues) and an install script that symlinks the whole set into ~/.cursor/skills, illustrating a chained, workflow-plus-technique pattern for structuring and routing large agent skill libraries. The repo also documents scope/authorization gating and passive-by-default behavior as part of the skill design.
github.comrepoAdded 30 Sep 2026, published 2 Aug 2026 - ops-engineering-skills
ops-engineering-skills is an open-source library of 296 Agent Skills covering DevOps, DevSecOps, cloud, Kubernetes, CI/CD, GitOps, security scanning, SRE, compliance, databases, messaging, service mesh, serverless, internal developer platforms, MLOps and AgentOps. Each skill is written once to the open SKILL.md standard with machine-checkable frontmatter and eight required sections (prerequisites, steps, pitfalls with fixes, worked example), and works natively across Claude Code, GitHub Copilot, OpenAI Codex, Cursor and Gemini CLI without a translation layer. It ships an automated validator, cross-reference integrity checks, a marketplace/plugin structure for Claude Code, and a generic install.sh/npx installer for any Agent-Skills-compliant agent.
github.comrepoAdded 22 Sep 2026, published 1 Aug 2026 - Raytar (@Raytar) on X
A Twitter/X thread explaining Claude Code's /goal and /loop commands, which let Claude repeatedly prompt and check itself against a defined finish condition rather than requiring a human to babysit each turn. It contrasts single-prompt workflows (which can produce confidently wrong output, e.g. fabricated sources) with loop-based workflows that self-verify, and gives a copy-pasteable "charter" template covering goal, work discovery, self-checking, state persistence (LOOP-STATE.md), and stop conditions.
x.comthreadAdded 22 Sep 2026, published 31 Jul 2026 - Claude as Autonomous Bug Bounty Hunter
A Medium write-up on turning Claude Code into an autonomous bug bounty agent. The setup combines 124 custom skills, three hooks and a Kali Linux container for vulnerability discovery and reporting. It is a practitioner example of structuring a Claude Code harness with skills, hooks and a sandboxed tool environment. Only the blurb was available, so implementation details are unverified.
 medium.comwriteupAdded 10 Oct 2026, published 30 Jul 2026
 Using Claude’s Security Review Skill in Claude Code
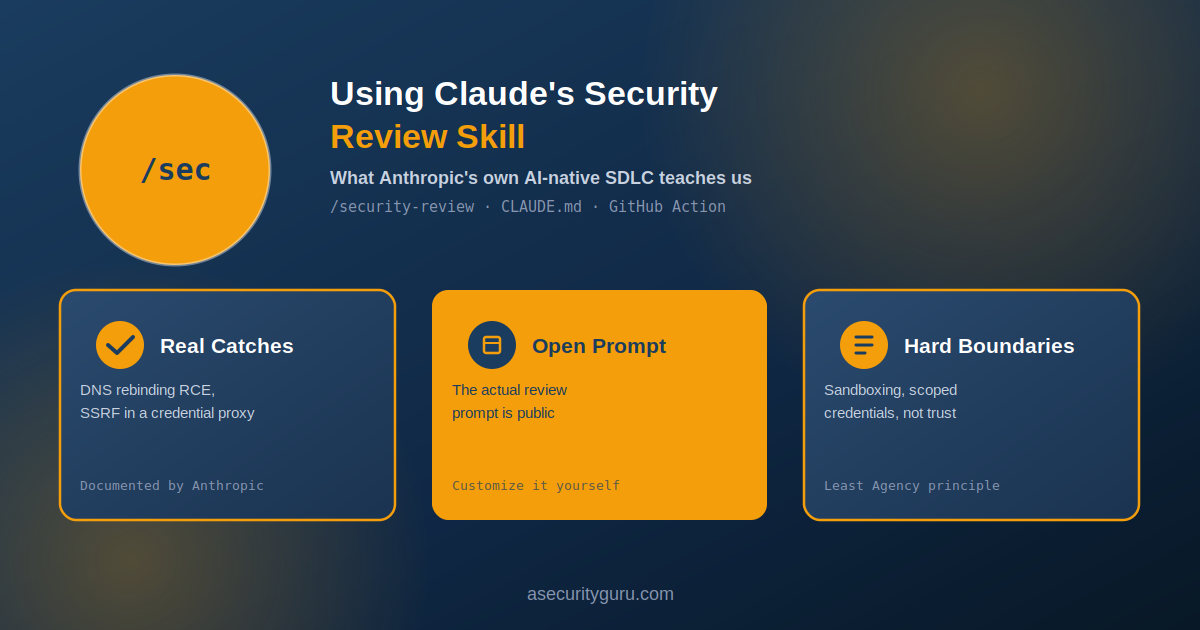
Walkthrough of Claude Code's /security-review slash command and the anthropics/claude-code-security-review GitHub Action. It covers what the open-source prompt checks (SQLi, XSS, authz flaws), its hard exclusions (DoS, rate limiting, hardening-only findings), and how to copy and customize security-review.md. It also summarizes Anthropic's SDLC account by Jason Clinton: narrow multiple reviewer agents instead of one mega-prompt, CLAUDE.md updates as a closed loop, /sandbox isolation, and least-privilege, single-purpose agent identities after an incident-response agent asked another Claude instance to deploy code.
 asecurityguru.comarticleAdded 13 Oct 2026, published 29 Jul 2026
- magnus919/agent-skills
A sprawling open-source collection of 100+ reusable "Agent Skills" (markdown instruction packs with YAML frontmatter following the open Agent Skills format) for agentic systems, compatible with Claude Code and any framework that supports the standard. Skills span multi-agent orchestration frameworks (AutoGen, CrewAI, LangChain, LangGraph, LlamaIndex, DSPy, Haystack, a PydanticAI-based multi-agent debate tool), production agent operations, evals, and AI governance, alongside dozens of narrower domain skills — CLI integrations for Jira, Confluence, Notion, Linear, HubSpot, Ghost, Fireflies, Grafana, PostgreSQL, Kubernetes, Docker Compose, FFmpeg, Ghidra-based binary triage, FPGA/ESP32 hardware design, and more. The page text was truncated at 40,000 of 71,286 characters, so later entries in the catalog are not reflected here.
github.comrepoAdded 1 Oct 2026, published 11 Jul 2026 - book-to-skill
book-to-skill is an open-source converter that turns a technical book, docs folder, or set of source files into a structured "Agent Skill" (SKILL.md plus per-chapter files) usable by Claude Code, GitHub Copilot CLI, Amp, Hermes Agent, and OpenClaw. It pairs a deterministic Python extractor (PDF/EPUB/DOCX/etc. → clean text) with a spec-driven generator that distills frameworks, decision rules, and anti-patterns, loading chapter content on demand to claim 24x-51x fewer tokens than dumping the whole document into context.
github.comrepoAdded 22 Sep 2026, published 10 Jun 2026 - Superpowers
Superpowers is an open-source composable skills library and workflow methodology for coding agents, enforcing a pipeline of brainstorming/spec, plan-writing, subagent-driven or inline TDD implementation, and code review across git worktrees. It ships as a plugin installable into Claude Code, Codex, Cursor, Gemini, Copilot, Grok, and many other agent harnesses, with skills like test-driven-development, systematic-debugging, and writing-plans that auto-trigger during a coding session.
github.comrepoAdded 22 Sep 2026, published 25 May 2026 - KKKKhazix/khazix-skills
khazix-skills is a GitHub repo of practical Agent Skills the author has been using daily in their own projects, following the open Agent Skills standard supported by Claude Code, Codex, Qoder, Kimi Code, iFlow, CodeBuddy, Cursor and 40+ other agents. Each skill is a structured instruction set (SKILL.md) an agent can load directly, with examples named like neat-freak, hv-analysis and khazix-writer; users can install by pointing their agent at a skill's GitHub subdirectory, or manually paste the SKILL.md content as project rules for agents without native skill support.
github.comrepoAdded 22 Sep 2026, published 8 May 2026