- Artificial Analysis (@ArtificialAnlys) on X
Hyperflow H3 is Video Rebirth's 8-step LoRA for MiniMax H3, released in September 2026 with open weights. Artificial Analysis ranks it #5 on AA-Video-I2V v2.1 and #3 on AA-Video-Editing v1.1, ahead of MiniMax H3 (768p). It costs $9.00 per minute for Image to Video and $18.00 for Video Editing at 1088p, under half of Dreamina Seedance 2.5 ($34.12 and $40.82). The thread gives per-capability and per-use-case breakdowns.
 x.comthreadAdded 31 Oct 2026, published 30 Oct 2026
 nemotron-halloween
MonsterHouse is a Halloween interactive projection built on the NVIDIA Nemotron Voice Agent: Nemotron Speech ASR, Nemotron 3.5 Bolt E4B 4GB with a LoRA persona adapter, Magpie TTS Zeroshot and Audio2Face-3D in Unreal Engine, on two RTX Blackwell GPUs. Median end-of-speech-to-audio is 1.70 seconds live and 0.72 seconds with cached responses. The post gives a build path and tips on caching and state handling.
 huggingface.cowriteupPublished and added 30 Oct 2026
- Show HN: Overtone – Transcribe, correct and cut captions for any screen shape
Overtone is a caption format (.overtone.json), a CLI and a video.js plugin that store each spoken word once and cut captions separately per screen shape (16:9, 9:16 or custom). The transcribe pipeline combines gpt-transcribe, Azure AI Speech and optional ElevenLabs Scribe, resolves disagreements with an LLM vote, and uses an LLM editor for corrections. A small public benchmark reports 5.3% word error rate and $0.023–0.025 per audio minute.
 github.comrepoAdded 30 Oct 2026, published 29 Oct 2026
 RADIOlogy: A Single-Pass Approach to Training-Free Zero-Shot Anomaly Detection
RADIOlogy is a training-free, single-pass zero-shot anomaly detection method that uses multi-head attention pooling in vision-language models. It scores anomalies by contrasting average similarity between vision features and sets of normal and abnormal prompts, with no windowed execution. RADIO agglomerative features drive a dense refinement pipeline for pixel-level segmentation, and the method is applied to medical images.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026
- PhysCount: Do MLLMs Count Visual Appearances or Physical Entities?
PhysCount is a benchmark of 546 real-world images and 4,595 human-written questions in 651 target-specific groups. It tests whether multimodal LLMs can separate visible appearances (direct view, reflections, glass) from the physical entities behind them. Across 40 MLLMs, counting appearances is much easier than linking them to entities, and the best model answers every question correctly in only 13.36% of groups.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026  Can Frontier Models See Past a Decoy? Elorian Tests Visual Reasoning
DecoyCount is a benchmark from Elorian and Mercor with 1,660 items that tests whether models count objects or fall back on visual shortcuts. Frontier models scored below 50%: GPT-6 Astra led with 43.17%, ahead of Gemini-3.8-flash (32.71%), Qwen3.8-max (28.31%) and Claude-Fable-5.1 (25.22%). CEO Andrew Dai says Elorian's Glimpse model scored 50.48% in a single internal run without tools, and contrasts visual reasoning with world models such as Atlas and Genie 4.
 latent.spacearticleAdded 28 Oct 2026, published 29 Oct 2026
- Benchmarking color judgment in multimodal LLMs with CIE-computable ground truth
A five-task benchmark tests multimodal LLM color judgment against CIE colorimetric ground truth: AWB pair judgment, skin-tone bias direction, CCT estimation, Delta E 2000 pair ordering, and color naming under changing illuminants. Eight endpoints were tested. On ColorChecker-24 stimuli, closed frontier models reach CCT MAE of 715-1056 K versus 1358-2133 K for open-weight models, and a non-ColorChecker control shows this gap is partly template-dependent.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026  Granite Switch 4.1.1 — Update models like you update software
Granite Switch 4.1.1 is a backwards-compatible patch release of IBM's modular Switch architecture, which configures a language model with specialized, cache-efficient adapters on one endpoint. It updates the Granite Speech ASR model (10 languages, native punctuation and capitalization) and the Decision adapter in granitelib-core, measured on the Jev Decision Index test set. Only the new adapters were retrained; the base model is unchanged. IBM plans tutorials and an Adapter SDK for third-party adapters.
huggingface.coarticlePublished and added 29 Oct 2026 Muhammad Waris (@WarisCodes) on X
Nemotron 3.5 Transcribe is a free open-weight speech-to-text model from NVIDIA covering 40 languages, including mixed-language speech. The post says it ties for first among open models with a 2.8% error rate. It says the model needs a large GPU such as an H100 or RTX 5090, so it will not run on a laptop. The post gives no benchmark name or model card link.
x.comthreadAdded 30 Oct 2026, published 29 Oct 2026- M-PFT: Angular Margin for Calibrated Prompt-Tuning of Fine-Tuned Vision-Language Models
M-PFT is an angular-margin method for prompt tuning of vision-language models that fixes base-to-novel dual miscalibration (underconfidence on base classes, overconfidence on novel classes). It adds two losses: minimizing the maximum cosine similarity between tunable class embeddings, and minimizing angular distance to each zero-shot embedding. Tests on 9 prompt-tuning methods and 15 datasets show lower novel-class calibration error at comparable accuracy and negligible overhead.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026 - Aligning Medical Vision Language Models at the Capability Boundary with Entropy Adaptive Rubric Grounding
MedCBR is a two-stage alignment framework for medical vision language models. Difficulty Weighted Boundary Preference Optimization (DBPO) trains on counterfactual preference pairs at the model's capability frontier. Entropy Gated Grounded Policy Optimization (EGPO) then applies distilled clinical rubrics according to prediction entropy. It reaches 61.2% average accuracy on six medical benchmarks, with the largest gains on differential diagnosis, and the two stages combine super-additively.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026 - 🚨 AI News | TestingCatalog (@testingcatalog) on X
Nemotron 3.5 Transcribe is an open-weight, promptable NVIDIA mixture-of-experts model with 30B total and about 4B active parameters. One checkpoint does transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding. The post says it ranked first in VoiceArena's comparison of 14 diarization plus ASR systems. The fetched text is cut off and gives no license or download details.
x.comthreadAdded 30 Oct 2026, published 29 Oct 2026  Introducing AnySpeechRecognizer and AnyDecisionModel: Open Models for Speech and Decisions on Apple Platforms
AnySpeechRecognizer and AnyDecisionModel are two Swift packages from Hugging Face. The first mirrors Apple's SpeechAnalyzer API with swappable engines (NVIDIA Parakeet, Alibaba Qwen3-ASR on Core ML) and adds Sortformer speaker diarization. The second returns typed yes/no, choice and score answers with probabilities via MLX, Core AI, llama.cpp, Jev or Ollama. The post gives M4 Max timings, model sizes and calibration options.
huggingface.coarticlePublished and added 29 Oct 2026- Leaving, Staying, or Living There? Duration Commonsense Reasoning with Human-LLM Co-annotations
This paper studies whether vision-language models can infer how long a person stays somewhere (living, staying, or leaving) from geotagged social media posts. The authors build a new corpus of geotagged tweets co-annotated by humans and LLMs. State-of-the-art models struggle even with multi-turn Chain-of-Thought prompting, often missing contextual cues and subtle hashtags while over-relying on prominent visual details.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026 - inkGround: Benchmarking Fine-grained Visual Grounding Capabilities of Vision-Language Models for Cursive Handwriting in the Wild
inkGround is a benchmark for stroke trajectory recovery from full-page, camera-captured handwriting, with 537 page images (about 18.7k words, 163k strokes) and pseudo-label references filtered by OCR agreement and human raters. Models get a page image and a target word, then output ordered stroke points. Seven VLMs were scored with DTW, Chamfer distance, readability and style similarity. Closed-source models, notably Gemini-3.1-Pro, did best, and the ranking held on IAM-OnDB.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026 - AskStream: When and What to Ask Proactively under Uncertainty in Streaming Video Understanding
AskStream is a multi-turn benchmark for streaming video understanding that adds a third proactive action, ask, alongside wait and answer, for cases where video or user information is incomplete. It has 438 videos, 2,714 manually annotated frame-level time windows (wait, ask, answer), four task categories and eight subtasks. The strongest model reaches only 52.18% on the proposed Ask-F1 metric, in both multiple-choice and open-ended settings.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026 - Quantize by Doing: Task-Guided Mixed-Precision Quantization of Vision-Language-Action Models
QbD-VLA is a mixed-precision post-training quantization method for vision-language-action models. It uses task success from short closed-loop evaluations to assign weight and activation bit widths, accounting for interactions between components. On four VLA models across all four LIBERO suites it holds task performance at about 4-bit weights and under 6-bit activations. The gain on SIMPLER is small. On a Franka Research 3 arm, X-VLA shows no detected loss, but π0.5 fails.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026  John Rood (@johnroodepic) on X
Nemotron 3.5 Transcribe is an open-weight, promptable 30B mixture-of-experts model from NVIDIA with about 4B active parameters, built for recorded audio. One checkpoint transcribes 40 languages, handles recordings up to an hour, labels up to eight speakers, translates, and answers questions about English audio. Weights and a demo are on Hugging Face. The post gives no benchmarks.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026 NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
Nemotron 3.5 Transcribe is an open-weight, promptable speech model that handles transcription in 40 languages, translation, diarization for up to eight speakers, and audio Q&A. It has about 4B active of 30B parameters and tops open-weight ASR and diarization leaderboards. The post also covers the Granary v2 curation pipeline (463,062 hours, 48 languages) and a medical fine-tuning case study that cut held-out WER by 45.8%.
huggingface.coarticlePublished and added 28 Oct 2026- Data Scaling Laws in Stereo Matching: From In-domain Fitting to Cross-domain Generalization
This paper studies data scaling laws in stereo matching and releases XStereo, a realistic synthetic dataset of 200 thousand samples. In-domain training on five large datasets shows two regimes: a standard power law, then saturation, with a transition point roughly fixed for a given model. Cross-domain performance depends only weakly on source data scale, and distribution and coverage diversity reduce domain gaps more.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026 - Complementing Text Based Moderation with Multimodal Grounding: Detecting Fraudulent Inducement Behaviors on Short Video Platforms
The paper studies detection and temporal localization of fraudulent inducements (prompts to follow, join chat groups, click links) in internet finance short videos. It compares OCR+LLM, OCR+MLLM and a zero-shot MLLM, and builds a dataset of 2,419 videos (66.49 hours, 3,194 events, four categories). OCR+MLLM reaches mIoU 26.52 versus 14.49 for keyframe OCR+LLM, with 67.0 percent macro recall, using a recall-weighted F2 localization reward.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026 - Improving the Dependency on Fine-Tuning Data in Transfer Learning for Speech Emotion Recognition
This paper proposes an fMLLR-based compensation mechanism that cuts the fine-tuning data needed in transfer learning for speech emotion recognition under train-test acoustic mismatch. An autoencoder reduces trainable parameters, and an affine transform in the encoder latent space models rotations and shifts. In a human-robot interaction task, mean CCC rose 16.8% with 12.9% of the training set and 14.4% with 50%.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026 - Know, then Draw: A New Learning Paradigm for Visual Generation
Know, then Draw is a learning paradigm for visual generation that uses autoregressive pretraining to acquire semantic knowledge and diffusion post-training for high-fidelity rendering. Controlled comparisons find autoregression the stronger pretraining objective, and semantic quality matters more than AR-only generation quality. This motivates a purely semantic tokenizer trained with language supervision only. A 3B text-to-image model trained in 6,600 H100 GPU-hours scores 86 on GenEval and 87 on DPG-Bench.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026 - Perceiving and Predicting Dynamic Sports: Spatiotemporal Intelligence in Vision Models for Egocentric Tennis Video
This paper presents an annotated egocentric tennis dataset (egocentric video synced with five allocentric views, global positions, contact times, stroke types) and evaluates image encoders, video encoders and vision-language models on seven prediction tasks. Best models reach 0.14 m player and 0.54 m ball localization error and 0.14 s contact-time error. Depth input helps 3D ball localization, and longer histories do not help forecasting. A conditional diffusion model generates whole-body tennis motion in real time.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026 - VideoLVR: Latent Visual Reasoning over Grounded Video Evidence
VideoLVR is a method that lets video multimodal LLMs build latent visual evidence from local regions at relevant moments and reason over it interleaved with text tokens. A visual token prediction objective, defined over a vocabulary derived from the input video, supervises the latents. It extends to reinforcement learning with sampled visual tokens as actions and final-answer rewards, and improves fine-grained video benchmarks without much context growth.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026 - As the Story Unfolds: Watching a Film and Identifying Characters as a Human Does
This paper defines a character naming task for films: given a name spoken in dialogue and its video context, the model must pick which visible character bears that name. It provides a dataset with annotations for character naming and first appearances, a video-and-dialogue model, and a comparison with proprietary multimodal LLMs. It also proposes a progressive framework that builds a character bank as the film plays, without cast lists or actor photographs.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026  Build specialized multimodal models with LFM3
LFM3 is Liquid AI's open-weight family of six ~2B-parameter models (text, vision-language, audio, omni and two d1 decision models), all branched from LFM3-1.7B-Base. The base model uses a tri-hybrid backbone of 13 gated short convolutions, 5 sliding-window attention layers and 6 global attention layers, pre-trained on 22T tokens with a 256K context. The post gives transformers snippets, benchmark comparisons against LFM2.5 and Qwen3.5, and a robotics fine-tuning example.
huggingface.coarticlePublished and added 27 Oct 2026 Introducing LFM3: Every Modality for Specialized Intelligence
LFM3 is Liquid AI's new family of open-weight multimodal models, six models of about 2B parameters branched from LFM3-1.7B-Base (22T pre-training tokens, 256K context). The hybrid backbone uses 13 gated short-convolution, 5 sliding-window attention and 6 global attention layers. Variants cover text, vision with video, audio, omni and two decision models, with on-device speed numbers, fine-tuning demos and robotics extensions.
 liquid.aiarticleAdded 28 Oct 2026, published 27 Oct 2026
- Genie 4: A new generation of world simulation
Genie 4 is Google DeepMind's real-time interactive world model, announced as a research preview for trusted testers. It generates video with native audio and interactive dialogue, steered by keyboard controls and text prompts. Gemini 3.8 Flash acts as a guiding agent that plans steps and checks frames, and Gemini 4 Argon is used for robotics experiments. The post lists limitations such as drift and object permanence, and says outputs carry SynthID watermarks.
 deepmind.googlearticlePublished and added 27 Oct 2026
 We’re announcing Genie 4, our new world model for real-time interactive simulation.
Genie 4 is Google DeepMind's world model for real-time interactive simulation, with native audio generated on the fly (ambient sound, music, dialogue). It builds on Gemini models: Gemini Omni grounds scenes in real-world appearance and behavior, and other Gemini models keep the simulation coherent. Users steer scenes by natural language. Access is limited to trusted testers now, with Google AI Ultra (Project Genie), the Gemini API and AI Studio to follow. The post gives no architecture or benchmark detail.
 blog.googlearticleAdded 30 Oct 2026, published 27 Oct 2026
- When Visual Evidence Is Insufficient: How Instructions, Post-Training, and Internal Activations Shape Refusal in Multimodal Language Models
This paper studies how multimodal LLMs refuse questions that an image cannot answer, using the MoHoBench benchmark on three MLLMs. It varies the meaning and placement of refusal instructions, compares supervised and preference-based post-training, and intervenes on a refusal-related activation direction. Instructions change refusal at the sample level in ways aggregate rates hide. Post-training raises refusal most but can mix refusal with attempted answers. Activation intervention gives smaller, transferable changes.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026 - Manoj | The AI Dude (@Manojkumar2257) on X
heditor is an open-source (MIT) agent skill from pycodebr that has Claude Code, Codex, Cursor or OpenCode edit talking-head videos. It transcribes with faster-whisper, picks a 30-70s segment, cuts frame-accurately, builds HTML + GSAP motion graphics, mixes audio at -14 LUFS, and runs QA with vision-reviewed previews. It offers 42 named styles and a long-form mode with chapters, SRT/VTT and lower thirds. Install: npx skills add pycodebr/heditor -g.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026 - Rohan Paul (@rohanpaul_ai) on X
Hi3D v1.0 (formerly Sparc3D) is an open-sourced image-to-3D model from Hi3D, which runs a closed v3.0 refining at 2048 cubes per side. In a test with 13 professionals in 3D algorithms, 562 judgments against eight other image-to-3D models favoured it 83.5% of the time. The thread also covers the Hi3D Agent and an MCP server for other agents. Back and bottom views were checked, where TRELLIS.2 collapsed a winged figure.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026 - AxisQ: Depth-Adaptive Channel--Frequency Quantization for Camouflaged Object Detection
AxisQ is a post-training quantization framework for camouflaged object detection (COD) that allocates activation bits by feature depth. It uses the channel domain for shallow features and the local-frequency domain for deep features, under a fixed per-layer average bit budget. It adds a boundary-aware Hessian approximation for reconstruction. On CAMO at W2A2, weighted F-measure improves 12.7% for CFRN and 33.3% for CamoFormer-P over the strongest baselines.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026  GPT-6.1 Terra
 is OpenAI's midrange model, announced 26 October 2026 and aimed at visual reasoning, computer use and clearer writing. It costs $1 per million input tokens and $5 per million output, about half of GPT-5.6 Terra and GPT-6.1 Sol and roughly 10x GPT-6 Luna. Simon Willison relays OpenAI's Ted Sanders, who rates it better than Astra and Sol at technical communication and much faster on computer use.
 simonwillison.netarticleAdded 27 Oct 2026, published 26 Oct 2026
 Test-time training in robotics shows no clear gains in demo response
This article reports a study submitted October 23, 2026 by Qiangong Zhou, Jiafeng Liang, Yimin Dong, Yang He and Hongxiang Li. They added Test-Time Training (fast-weight memory) to the vision-language-action models InternVLA-A1 and Pi0.5, trained on paired human demonstrations and robot trajectories. Shorter videos, full-trajectory gradient connectivity and contrastive regularization gave no clear gain in demonstration-guided target selection at the tested scale.
 en.cryptonomist.charticlePublished and added 26 Oct 2026
 A new AI method for saliency-aware image-text alignment improves image search
RoSA is a finetuning framework from Qiuyu Kong and three co-authors for long-text image-text retrieval. It targets "saliency collapse", where models over-rely on text tied to prominent visual features and miss contextual information. RoSA splits pairs into salient and contextual views using object-level saliency estimation and LLM text decomposition, then trains on both with plug-and-play auxiliary alignment objectives. Code and checkpoints are public.
en.cryptonomist.charticlePublished and added 26 Oct 2026- A 10-year-old CNN outperforms frontier LLMs for skin cancer diagnosis
A dermatologist tested GPT-6 Astra and Claude Fable 5.1 on 200 biopsy-proven lesions from MILK10k, giving each a clinical and a dermoscopic image. A CNN (Inception v3, fine-tuned for about twenty minutes on 68,011 ISIC images) named the right diagnosis for 62% of lesions, against 42% for both LLMs. The post lists caveats (small sample, single run, possible contamination) and links the cases, prompts, replies and scoring code.
 lynchlab.netwriteupAdded 26 Oct 2026, published 25 Oct 2026
- Explaining Navigation Decisions: Stage-Aware Visual Attribution for Vision-Language Navigation
A stage-aware visual attribution framework for Vision-Language Navigation (VLN) that explains a robot's action choices. It identifies "instruction-stage insensitivity", where existing explainers give similar outputs across navigation stages. The method builds action-conditioned temporal instruction-visual attributions, aggregates relevant historical evidence by stage, and applies an instruction-guided spatial filter. It improves attribution quality across several VLN policies and benchmarks, helps diagnose failure cases, and was tested on a Unitree G1 robot.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026 - Detecting and Understanding Ambiguity in Visualizations with Role-Playing Vision Language Model Interpretations
This paper presents a pipeline that uses persona-conditioned vision language models to surface interpretive ambiguity in visualizations. Topic-relevant personas elicit candidate takeaways, and a Target-Pattern-Scope framework lets LLM judges label statement pairs as Compatible, Disjoint or Opposing, which are summarized in an ambiguity profile. The authors benchmark VLMs on chart comprehension per chart type, check labeling against human annotations, and run case studies on public visualizations and a redesign.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026 - InteractiveWorld: A Verifiable Human-Centric Environment for Building Better Interactive MLLM Assistants
InteractiveWorld is an environment for closed-loop interaction between an AI assistant and a simulated human agent who sees the scene, follows instructions and acts independently. InteractiveBench, built on it, has 120 multi-turn tasks in six categories scored by verifiable, state-based rewards. Across 12 frontier MLLMs, the best model, Claude Fable 5.1, reaches at most 20% on long-horizon Guidance and 25% on Planning tasks.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026  Block's new voice AI sounds eerily human, sparking awe and scam fears
Dessa is a voice AI model from Block, trained from scratch on human speech only, with no text stage. It listens while speaking, so it handles interruptions, laughter and tone changes. Block says it trained on one Nvidia GB200 NVL72 system and that it runs locally on a MacBook Pro with M4 Max or better. Model size, benchmarks and release date are undisclosed. Early access goes to a small group of AI safety researchers. Reactions split between praise and scam fears.
 coindesk.comarticlePublished and added 24 Oct 2026
- OWLS: Open-world Language-conditioned Speed Fields for Zero-Shot Rover Navigation
OWLS (Open-world Language-conditioned Speed Fields) plans directly over a vision-language model's dense feature map. A text prompt describing traversable terrain scores every pixel of one camera image. The scores are projected onto the ground, adapted with two morphological operations, and used as the speed field of a minimum-time planner. It needs no training, terrain labels, map or extra sensors. It was tested on a physical rover, on simulated Mars and Moon rovers over 200 procedural terrains, and on real planetary imagery.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - Standing on Open Shoulders: Regional Fine-Tuning of Open-Weight Camera-Trap Models for UK Wildlife with Modest Data and Compute
DeepFaune-UK is a fine-tune of the open DeepFaune camera-trap classifier on 28 UK classes, paired with MegaDetector v6. On 20,212 MammalWeb images it reached 88.8% strict accuracy against 56.5% (DeepFaune v1.5.0) and 59.0% (SpeciesNet). Re-applying the recipe to the DINOv3-based classifier gave 90.6%. Fine-tuning on about 150 crops per class matched full-data out-of-distribution accuracy, and a DINOv2 run took about 22 minutes on under 4 GB of GPU memory.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - UAV-SwarmAgent: Scalable Multi-UAV Reconnaissance and Task Allocation via Code Generation and Vision-Language Reasoning
UAV-SwarmAgent is a hierarchical multi-agent system where an operator gives one natural-language sentence and a ground-station agent writes and runs code that produces per-UAV routes. A vision-language model grounds targets in an aerial map, and worker agents verify incidents with a compact onboard model. In simulation it located the incident in 244 of 255 missions (95.7%), and flight time followed an Amdahl-type law with speedup bounded at 1.52x for one to five UAVs.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - Efficient Zero-Shot Video Anomaly Detection via Signal-Aware Adaptive Fusion (SAAF)
Signal-Aware Adaptive Fusion (SAAF) is a training-free zero-shot video anomaly detection framework that cuts the compute cost of vision-language models. It combines a dual-signal sampler (frame-to-frame delta and rolling-context drift in embedding space, OR-gated with EMA thresholds), a threshold-gated cascade from frame-level to video-level analysis, and signal-aware score fusion. It reports AUC-ROC of 92.07% on XD-Violence, 86.70% on MSAD and 80.54% on ShanghaiTech, at 2.2x to 2.6x the throughput of the prior best zero-shot method.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - When to Stop Penalizing Actions? Martingale GRPO for VLA Reinforcement Learning
MART-GRPO is a variant of group-relative policy optimization for vision-language-action (VLA) reinforcement learning. It uses a LoRA-fine-tuned VLM to find the last visible error without recovery in a failed rollout video, keeps failure feedback up to that point, and drops it afterward. Martingale stopping conditions show this preserves the expected GRPO gradient and can reduce covariance. With OpenVLA-OFT on RoboTwin 2.0, it raises success rates over full-trajectory GRPO across multiple tasks.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - 4DMemory: Benchmarking Long-Horizon Spatiotemporal Memory with Harness-Augmented Agents
4DMemory is a benchmark suite for long-horizon spatiotemporal memory: the LongVideo dataset (about 900 hours of video, over 5,000 manually reviewed questions) and 4DMemoryBench. It also presents the 4DMemory Harness, combining four skills, 22+ tool models and a model-specific RAG system. Across 13 models, the harness improved every one by over 50%, and the same models scored over 10% lower than on a previous benchmark.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - MAST-VLA: Skill-Conditioned Adaptation with Trajectory-Affordance Priors for Multi-Skill Robot Manipulation
MAST-VLA is a vision-language-action framework for multi-skill robot manipulation that conditions on both the skill to execute and where and how to contact objects. It adds skill-conditioned LoRA Mixture-of-Experts adapters to the LLM backbone and turns a predicted affordance heatmap into a patch-level spatial prior for the action head. It reaches an Avg. Len of 4.65 on CALVIN ABC→D and was tested on a real robot.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - Sensorimotor Alignment: A Platonic Proxy for Embodied Policy Success
Sensorimotor Alignment (S^2) is a training-free offline metric that measures how well an embodied model's sensory representation aligns with the geometry of physical motion. It extends the Platonic Representation Hypothesis to motion trajectories. S^2 correlates positively with downstream robot task success across embodied model families, helps pick promising VLM backbones before fine-tuning into VLAs, and explains behaviours seen in VLAs and world action models.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - F2G-Pose: Geometry-Aware Foundation Feature Lifting for Direct RGB-D Category-Level Object Pose Estimation
F2G-Pose is a direct, single-pass framework that predicts category-level object pose, metric size and camera-frame completed shape from one RGB-D image. It lifts frozen RADIO foundation features onto partial point clouds, tokenizes local geometry with DGCNN, and fuses it with a Mixture-of-Experts Transformer. It trains only on synthetic SOPE data, leads on SOPE and ROPE at 28 FPS, and is tested on HouseCat6D, HANDAL and real manipulation.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - Progress Probes $P^2$: Lightweight Runtime Monitoring for Vision-Language-Action Models
Progress Probes (P^2) trains linear probes on a vision-language-action model's own activations, using demonstrations, to estimate task progress, then flags executions that deviate from expected progress. Tested on the open-source pi0.5 across simulated and real-world manipulation tasks, it matches or beats VLM-based monitors and failure-data-trained methods at failure detection, without an external foundation model.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - Rethinking Sequence Compression with Test-time Regression
TTR-Compressor is a sequence compression method that treats input tokens as a test-time regression problem. The regression is learned end-to-end by backpropagation, and its coefficients are solved in closed form in the forward pass to give the compressed representation. As a block-wise sparse attention compressor it improves RULER over attention-based compressors by a large margin. As a visual token merger for multimodal LLMs it beats the MLP merger and matches it with 55.6% fewer visual tokens.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - CellTrack-Bench: Microscopic Cell Tracking Benchmark for Vision-Language Models
CellTrack-Bench is a benchmark that tests vision-language models on microscopic cell tracking and compares them with specialised trackers. It has 1,537 problems covering 9,041 cell-linking decisions, drawn from 15 cell-tracking datasets across four imaging modalities, with a hard subset built from failures shared by distinct algorithmic trackers. The authors compare environment harnesses, benchmark 9 closed-source and 13 open-weight models, and analyse failure modes.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - DuoCook: An Overcooked-Inspired Benchmark for Visual Planning and Coordination
DuoCook is an Overcooked-inspired benchmark in which one vision-language model controls two cooks from top-down views in Unreal Engine environments built with coding agents. It has 20 maps in five categories covering equipment contention, changing terrain and handoff dependencies. Four VLMs were compared; the best, gpt-6-astra, reached 26.2% mean order completion. A notebook memory ablation had mixed effects: positive for Claude and Qwen, negative for GPT and Gemini.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026  OlmoEarth v1.3: State-of-the-art embeddings for the whole planet
OlmoEarth v1.3 is an open satellite embedding model from Ai2 that reads a year of Sentinel-1, Sentinel-2 and Landsat data and outputs a 128-dimensional vector per 10 m pixel (the first 64 dimensions also work alone). Its embeddings beat AlphaEarth Foundations and Tessera v2 on 20 of 27 evaluations. Precomputed global embeddings, a browser Embeddings Explorer and pre-training cost (about $2,720 of H100 time) are covered.
huggingface.coarticlePublished and added 22 Oct 2026- Drift Says When, Budget Says How Much: Rate-Controlled KV Re-selection for Long-Form Multimodal Generation
Rate-Controlled Refresh (RCR) is a KV cache re-selection method for multimodal LLMs in long-form generation. Attention drift decides when and where to re-select visual tokens, and a per-sample controller sets how often. RCR beats InfiniGen by 1.6-3.8 ROUGE-L points on five of six model-task settings and stays within 1.7 points of exact per-step re-selection. On video description, where drift is homogeneous, it no longer beats a fixed threshold.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - Beyond tree cover: mapping the world’s forest types
Forest Typology (ForTy) 2020 is a global 10-meter map from Google DeepMind, Google Research, WRI and IIASA. It sorts land into six FAO-based classes: primary, naturally regenerating, planted, plantation, tree crops and agroforestry, and other land. The model uses AlphaEarth Foundations embeddings and about 1.7 million labeled locations. It was 90% accurate on forest type across 9,000+ expert-checked sites. An early 2017 to 2025 time series is on Earth Engine.
deepmind.googlearticlePublished and added 22 Oct 2026 - Show HN: OnKey – I'm a bad singer, so I built an app to show where I'm off-key
OnKey is a free, MIT-licensed singing trainer for Apple Silicon Macs. After a song ends in Spotify, Apple Music or browser YouTube, it separates the lead vocal with UVR's MDX-Net Karaoke 2, tracks pitch with CREPE and turns it into syllable-level notes with the GAME model. On later plays it scrolls the notes, draws the user's live pitch and scores each line. Analysis runs on-device, and the repo explains the build steps and network requests.
github.comrepoAdded 24 Oct 2026, published 22 Oct 2026 - TRIAD: Benchmarking Omni-Modal Ambiguity in Multimodal Large Language Models
TRIAD is a benchmark for omni-modal ambiguity resolution. It has 327 hand-written text-image-audio queries in 86 scene groups across 18 ambiguity categories, and removing any one modality makes the answer non-unique. Across 14 omni-modal systems, the best model trails humans by over 20 points in group accuracy. Without answer options, model group accuracy falls to single digits, and leave-one-out tests show audio cues are often underused.
arxiv.orgpaperAdded 23 Oct 2026, published 22 Oct 2026  Matrix-Game 4.0: Harnessing Video Models for Real-Time Playable Game Worlds
Matrix-Game 4.0 is a system that separates game logic from visual rendering for playable generated worlds. A lightweight engine holds world state and rules, a multimodal coding agent writes game code and scene captions, and a distilled autoregressive video model turns low-poly proxies into detailed frames. It runs 480p at 60 FPS on one RTX 5090 with 112 ms key-press-to-display latency. Code, weights and assets are released.
huggingface.copaperAdded 22 Oct 2026- SpyTech Ai (@RizeOnline) on X
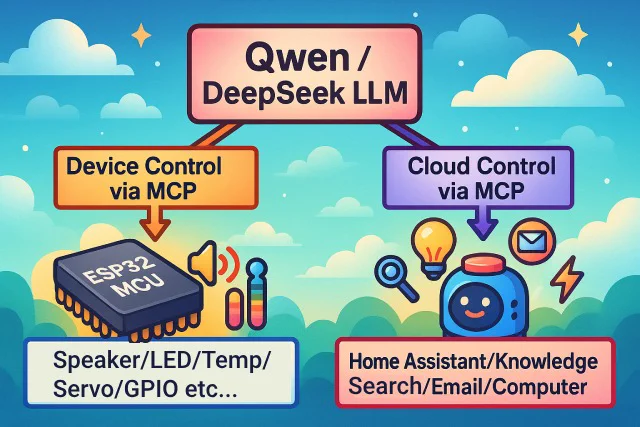
XiaoZhi ESP32 is an open-source, MIT-licensed firmware stack that turns ESP32 boards into MCP-based voice chatbots using models such as Qwen and DeepSeek. It streams Opus audio over WebSocket or MQTT + UDP through ASR, LLM and TTS, adds offline ESP-SR wake words, and uses device-side MCP to drive speakers, LEDs, servos and GPIO. It supports 138 board directories and builds with ESP-IDF 6.0.1 or newer.
x.comthreadAdded 23 Oct 2026, published 21 Oct 2026  Granite Speech 5.0: Transcribe, Translate, and Attribute more Accurately and Faster
Granite Speech 5.0 is IBM's update to its open speech model collection: the new granite-speech-5.0-2b, a multilingual granite-speech-5.0-470m-turboctc, and a revised granite-speech-4.1-2b-plus. The 2B model ranks #2 among open-weight models on average English WER (5.06%) on the Open ASR Leaderboard. Turbo CTC reaches 19,870 RTFx, and the 4.1 Plus revision cuts long-form WER 24%. All are Apache 2.0.
huggingface.coarticlePublished and added 21 Oct 2026- Vishesh Raheja (@entropyconquers) on X
GPT Voice is a free, open-source Mac app by Vishesh Raheja that brings ChatGPT's dictation to any macOS app. A shortcut starts recording, and the transcript is pasted where the user is typing. It uses the ChatGPT Pro subscription, so it needs no API key or extra subscription. The author built it after Handy handled coding prompts poorly and they did not want to pay for Wispr Flow. The thread gives no details on local versus API transcription or latency.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026  NVIDIA Cosmos3-H-Dreams: Bringing Clinical Surgery to Life Through Generative Simulation
Cosmos3-H-Dreams is NVIDIA's real-time generative surgical simulator, trained on clinical cholecystectomy video and kinematics from the CMR Surgical Versius platform. It builds on the 16B Cosmos3-H-Embodied-Nano, distills a bidirectional teacher into four-step and two-step causal students with Self-Forcing, and streams through FlashDreams on one RTX PRO 6000 GPU. Checkpoints and a recipe for custom data are released.
huggingface.coarticlePublished and added 20 Oct 2026 brenz. (@brenzhills) on X
Krea 3 is an image generation and editing model from Krea. A post on X says its "Fast" variant scores 1125 Elo on the Artificial Analysis image editing leaderboard, against 1124 for Google's Nano Banana 2, while producing 10 images in the time Google produces 2. It also says the "Ultra" variant ranks in the top 4, behind only OpenAI models. The post gives no methodology or model details.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026- UniWALM: Unified World Action Language Model for Embodied Robot Control
UniWALM is a unified world-action-language model that learns video, action and language in one mixture-of-transformers backbone with per-modality diffusion heads that co-denoise together. Generated subtask and textual memory are fed back on the next step, so no external planner or memory bank is needed. It adds Flow Matching with Correction (FMC) for recovery from perturbed actions. It reaches 34.5% on the memory-dependent RMBench subset, above Mem-0's 28.5%, and lifts real-world Find-the-Item success from 11.1% to 61.1%.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026 - InterWebCoder: Learning Interactive Webpage Generation from Executable Tests via Reinforcement Learning
InterWebCoder is a framework for interactive webpage code generation by multimodal LLMs. It synthesizes self-contained webpages with executable test scripts from recorded interaction trajectories, repairs failures using runtime evidence, then trains with test-ID-weighted SFT and GRPO using test pass rates and visual similarity as rewards. The pipeline yields 1,736 verified samples from 2,058 tasks. A 9B model scores 48.54 on IWR-Bench and 48.42 on Vision2Web, and reward latency drops over 97%.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026 - Agentic Ensemble with Vision-Language Models for Visual Anomaly Detection
AnomalyAgent is a post-training fusion framework for visual anomaly detection that ensembles pretrained detectors. It aligns scores and anomaly maps, summarizes disagreement, and treats fusion as a choice among score actions and map actions. A constrained vision-language model inspects high-conflict samples and picks the actions. It beats equal-weight fusion and gets the best mean image AUROC and pixel AP among compared fusion methods on MVTec AD and VisA.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026 - Code2Video-Compass: A Comprehensive Benchmark for General-Purpose Code-Based Video Generation across T2V, I2V, and V2V
Code2Video-Compass is a benchmark of 2,104 tasks for code-based video generation, where multimodal LLMs write executable programs that produce complete videos from text (T2V), image (I2V) or video (V2V) inputs. Tasks span 10 categories and 24 subtypes. Scoring uses 12 objective metrics and five MLLM-judge metrics. Across 15 proprietary and open-weight models from nine families, performance falls as construction, dynamic animation and state-dependency complexity rise.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026 - DIVE: Benchmarking Full-Duplex Interaction with Visual Engagement in Continuous Streams
DIVE is a benchmark for full-duplex interaction with visual engagement in continuous audio/video streams. It has 525 human-annotated samples across six tasks in three scenarios: proactive intervention, continuous engagement and interaction coordination. Evaluated real-time models reach sub-second average latency, but window response rates stay at or below 53.77%, and adapting ongoing responses to new information is hardest.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026 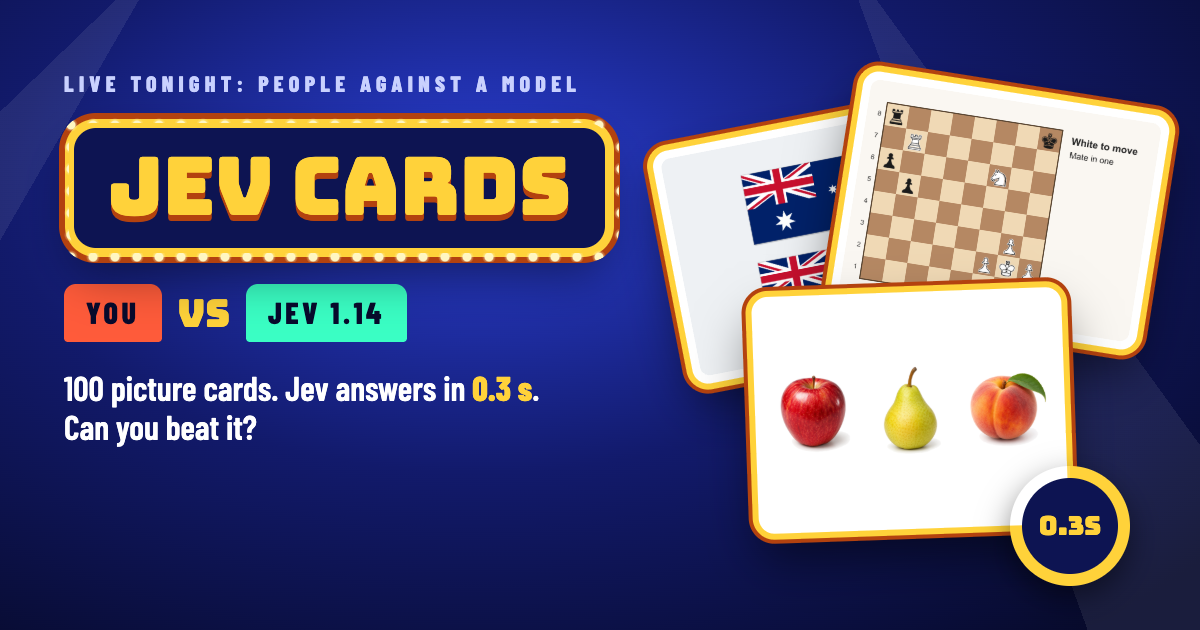 Show HN: Jev Cards, Can you beat a vision model at a picture quiz?
Jev Cards is a browser picture quiz where a player competes against Jev 1.14, a vision decision model. The 490 cards cover fruit, flags, maps, chess and illusions. Jev reads the image and question and returns a probability for every option, or a box for "tap the place" cards, in one call of about 0.25 seconds. It never writes text. The page reports 5,256 wins in 6,820 games.
 jevcards.comtoolAdded 21 Oct 2026, published 20 Oct 2026
- A Multimodal Engineering GraphRAG Framework for Post-Wind-Event Building Assessment and Recovery Inference
This paper presents a multimodal engineering GraphRAG framework that links post-wind-event damage evidence from images and reconnaissance reports to building-condition states, recovery actions and downtime. Evidence is stored as a provenance-preserving, component-level representation, and graph-aligned retrieval uses compatibility, contradiction, evidence-precedence and abstention checks. Demonstrated on tornado-affected low-rise homes, it beats BaselineRAG and Structured Baseline RAG, and ablations test each component.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026 - OpenVLHarness: Real World Visual Agentic Tool-Use with Multimodal Memory
OpenVLHarness is a multimodal reasoning harness for MLLMs built on a capability layer (task-level tool interfaces plus evidence rendering) and persistent multimodal memory that stores images, structured data and web references as addressable artifacts. A coding interface runs generated programs over stored data. Across 22 benchmarks and eight backbones it adds 9.7-12.6 points over no-tool baselines, and GPT-6 Luna at medium effort beats Codex and Visual Sketchpad at maximum effort using at most 37% of their tokens.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026 - Where is Physical RSI capability from? An Observational Scaling Law of LLM-as-policy
The paper introduces PhysRSI-eval, a five-axis metric for physical recursive self-improvement: first-attempt performance, efficiency, success, budget and improvement from failure. Several VLMs are tested on 18 manipulation tasks under a fixed interaction budget. It proposes the Physical Barrel Hypothesis and studies observational scaling. Workspace interventions show that removing history lowers late-round success, while frozen workspaces still help on unseen layouts.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026 - What Language Adds, and at What Cost: Four Controlled Probes of Pathology Vision-Language Models
This preprint grades evidence for pathology vision-language models and tests four claims with controlled probes on released checkpoints and public data. Stage-redacted report embeddings raise pooled C-index by 0.019 (progression-free interval) and 0.016 (overall survival) across 1,633 TCGA patients. Zero-shot prompting matches a linear probe. SlideChat scores 74.82% with the slide and 74.41% without it. Paraphrasing flips 8-23% of answers.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026 - Scaling Parameter-Efficient Fine-Tuning for Brain Encoding
BrainLoRA is a parameter-efficient fine-tuning method that adapts multimodal backbones of up to 104B parameters to predict neural responses. It predicts multiple timepoints in one causal pass instead of sliding windows, and a multi-LoRA kernel trains many adapters on a shared backbone. Across nine backbones it improves encoding, and a 200+ model ensemble ranks first on the Algonauts post-challenge leaderboard.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026 - Mise-en-Video: Fine-Grained 3D Control for Multi-Shot Video Generation
Mise-en-Video (MeV) is a multi-shot video generation framework where creators stage shots in 3D space and then generate the matching video. It combines hierarchical attention for multi-level narrative consistency with 3D-aware layout guidance for per-shot spatial control. The authors built a 160K-video dataset with hierarchical multi-shot texts and oriented 3D bounding boxes, and report gains over baselines in quality, consistency and subject controllability.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026 - HAF-VLA: Hierarchical Action Flow Framework for Humanoid Vision-Language-Action Control
HAF-VLA is a hierarchical action-flow framework that adapts a pretrained flow-matching vision-language-action model to humanoid whole-body loco-manipulation. It denoises a shared action space in stages: locomotion and head commands first, then waist refinement, then full-body manipulation. Learnable stage embeddings and cross-stage KV-cache conditioning carry dependencies between stages. The authors report gains over existing models on six real-world tasks.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026  Meta Muse Spark Open (816B-A42B) open-weights model card
Model card for Meta Superintelligence Labs' Muse Spark Open, an open-weights, natively multimodal model with 816B total and 42B active parameters and a 1M-token context window. It targets coding and agentic work (tool use, long-horizon tasks, multimodal reasoning, synthetic data generation, LLM-as-judge). It ships in BF16 and NVFP4, needs about 700GB VRAM (NVFP4) or 2TB (BF16), runs on SGLang, vLLM, Transformers, TensorRT-LLM, Unsloth, llama.cpp and MLX, and supports a reasoning_effort setting. The Muse Model License requires "Built with Muse Spark Open" attribution and a separate agreement for Model-as-a-Service above $20M revenue. The card reports safety results against Kimi K3 on cyber, chem/bio and loss-of-control evals.
huggingface.corepoAdded 17 Oct 2026- FedRAPP: Federated Test-Time Prompt Tuning for Vision-Language Models with Reliability-Aware Prompt Personalization
FedRAPP is a personalized aggregation framework for Source-Free Federated Test-Time Prompt Tuning (SF-FTTPT), where clients adapt CLIP soft prompts on unlabeled, non-IID test streams without source data. It combines reliability-aware client assessment, a server-side exponential moving-average prompt memory and similarity-guided peer aggregation. Across nine CLIP benchmark datasets and ImageNet variants it beats standard federated aggregation baselines while keeping prompt-only efficiency.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - FlexPart: Text-Controlled Semantics-Aware 3D Part Segmentation at Flexible Granularity
FlexPart is a framework for text-controlled 3D mesh segmentation that assigns discrete part IDs to mesh faces through a view-independent part-identity field. It uses a control prompt of part names with location and shape clauses, trained on a VLM-built multi-granularity dataset. On FlexPartBench it raises average mIoU by 22% over the strongest baseline, and by 15% with planner-completed prompts.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - A Language-Informed Loss for Visual Generation
LILIE (Language-Informed and Lossless Image Encoder) is an invertible image transform built from a normalizing flow transformer, trained jointly with a vision-language model via next token prediction so captions can be recovered from noised features. The encoder supplies a language-informed loss for text-to-image generation. JiT models trained with it cut gFD from 66.84 to 53.01 against a pixel-only baseline on the GPIC dataset. Code, encoders and models are released.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - Enhancing RAG-based Medical VQA with Gated Multimodal Representations
This paper presents a multimodal retrieval-augmented generation framework for Medical Visual Question Answering. A Gated Multimodal Unit learns a joint query representation from the medical image and the clinical question, so evidence retrieval uses both modalities while the Med-LVLM stays frozen. On benchmark datasets it consistently beats a reference Med-LVLM and stays competitive with state-of-the-art methods. The page gives no dataset names or numbers.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026  AmingIn_AI (@aming_inAI) on X
A tweet from AmingIn_AI describes a macOS screenshot-annotation tool. On release it saves the screenshot, a crop and the user's marks locally, then copies a 127.0.0.1 link. Claude Code or Codex on the same Mac can fetch that link and receive the marked image plus app/window info, and nothing is uploaded. It shows a local, privacy-preserving way to hand visual context to coding agents without MCP or cloud upload.
x.comthreadAdded 17 Oct 2026, published 16 Oct 2026- MUB: An Identity-Masked Benchmark for Music Understanding in Multimodal Language Models
MUB (Music Understanding Benchmark) is a set of 500 identity-masked recordings with existing annotations for tempo, key, time signature and structural intervals. It covers all 24 keys, tempos of 47 to 180 BPM and 4,676 intervals, and strips titles, artists and platform IDs from inputs. Baselines reach 53.6% tempo accuracy (DSP) and 98.4% time-signature accuracy (constant 4/4). No multimodal LLM has been tested yet, and rights clearance is unresolved.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - OpenMOSS/MOSS-Image
MOSS-Image is an open-source text-to-image model family from OpenMOSS with a 5B backbone, released October 2026 as MOSS-Image-Base and MOSS-Image-SFT. It supports JSON layout control with bounding boxes, text rendering inside images, and prompts up to 4K tokens. The repo gives a Diffusers pipeline, a Gradio app, a ComfyUI plugin, LoRA training guidance, a prompt-enhancer skill and day-0 SGLang and vLLM-Omni support.
github.comrepoAdded 20 Oct 2026, published 16 Oct 2026  Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint
IBM announces Granite-Switch-4.1-8B and -30B. Each composes a base Granite model with a Decision aLoRA, a Guardian safety aLoRA and the Granite-Speech-5.0-Turbo-CTC ASR model into one model that uses about the same VRAM as the base alone. Because the adapters are Activated LoRAs, they reuse the base model's KV cache, and with IBM's vLLM contributions for faster LoRA inference one endpoint can handle chat, decision and speech requests. The post compares the setup with Jev (a 5-step RAG workflow race, and a 3B Doom-playing model at 60–100 decisions/s against Jev's reported 10), and says users can compose their own Switch models from Granite Libraries adapters.
huggingface.coarticlePublished and added 15 Oct 2026 Vaibhav Sisinty (@VaibhavSisinty) on X
Social post reporting Meta's release of Muse Spark Open, described as the most capable US open-weight model: 816B total and 42B active parameters, a 1M-token context, and text, image, video and audio input in one model. It is pitched at coding and agentic work and tuned to run on two M5 Ultra Mac Studios, with weights available at release. The poster notes that in Meta's own chart, China's Kimi K3 and GLM 5.3 still beat it on coding.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026 Connor (@ConnorTalksAI) on X
A tweet relaying OpenAI's announcement of GPT-Live-1.1, an update to the voice model behind ChatGPT voice mode. It reduces how often the model says "checking", adds new voices and improves accents, including new voices in French, German, Hindi, Mexican Spanish, Korean and Japanese. It is rolling out to all users in ChatGPT, Codex and "dots", with API access coming soon. The poster frames it as a response to a new xAI/SpaceXSI Grok Voice release.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026



Showing 90 of 326
Show more