 simonwillison.netarticle
Introducing Mistral Large 4: Le chonk
Simon Willison's link-blog post on Mistral's preview release of Mistral Large 4, a 1 trillion parameter / 49 billion active parameter mixture-of-experts model trained on a cluster of 3,800 NVIDIA Grace Blackwell GPUs, available now via Mistral's API with open weights promised by end of month. He notes it only supports two reasoning levels ("none" and "high"), scores 38 on Artificial Analysis (just behind DeepSeek-V4.1-Flash's 552B model), and marks a big jump from Mistral Large 3's score of 9, putting Mistral roughly 6 months behind the frontier again.
Evidence
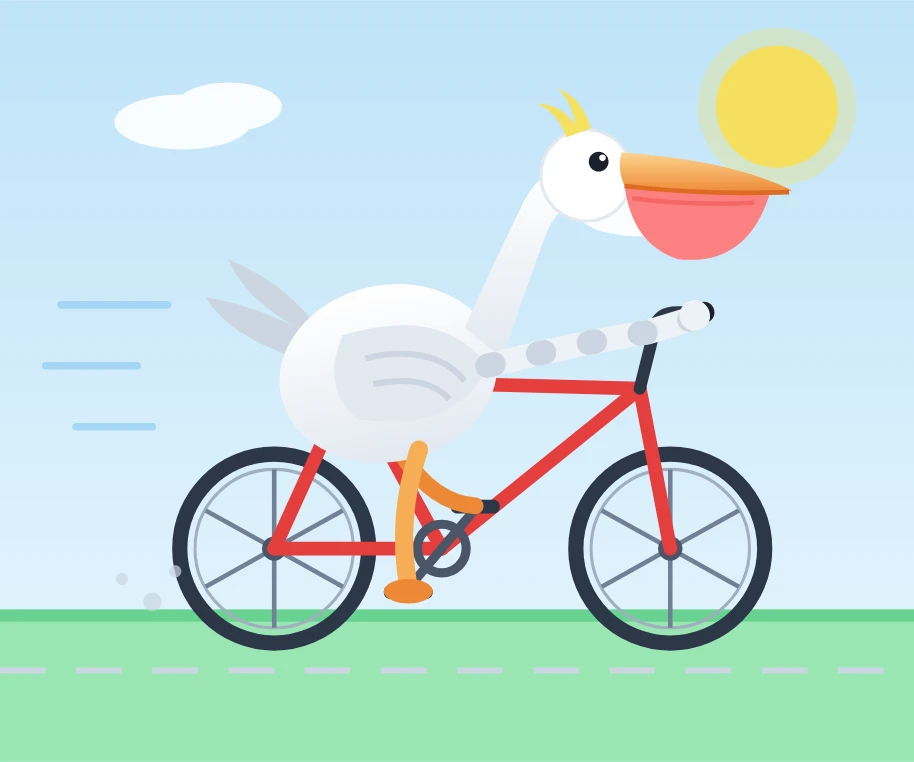
The one result the summary omits is Willison's informal "pelican" test, run on both reasoning levels through the Mistral API. This is a single drawing prompt, compared visually.
- "high": produced the better-looking pelican, using 2,717 output tokens.
- "none": used 3,275 output tokens.
Willison calls this surprising. On this one prompt, turning reasoning on cost fewer output tokens than leaving it off. It is a single sample, not a benchmark, but it is the only cost-relevant number on the page. It suggests you should not assume "high" is the more expensive setting. Measure token usage on your own prompts before picking a default.
For context, the Mistral Large 3 baseline (score 9 on Artificial Analysis) dates from last December, roughly ten months before this preview. Willison explicitly places Large 4 below "Fable-class" frontier models, consistent with his estimate of about 6 months behind.
How to use it
The page gives only these facts:
- Access: preview via the Mistral API.
- Reasoning: the only reasoning control is a two-value setting,
"none"or"high", with no intermediate levels. - Weights: open weights promised for the "end of this month", meaning October 2026.
The page gives no model identifier, no pricing, no context length and no weights licence.
Limits
- Preview status: this is a preview, and the open weights are a promise, not a release. Check the licence when the weights ship, because the page does not state it.
- Thin evidence: the token-usage comparison comes from one prompt, judged by eye.
- Single benchmark: the only quantitative quality signal is the Artificial Analysis aggregate. The page gives no task-level benchmarks, so check performance on your own workload.
- Architecture: the page states only total and active parameter counts. It gives no other architecture or training details beyond the GPU cluster.
Organisations named here
Technologies named here
Also named here
- DeepSeek-V4.1-Flash
- Simon Willison
Related in models