 simonwillison.netarticle
Claude Sonnet 5.5
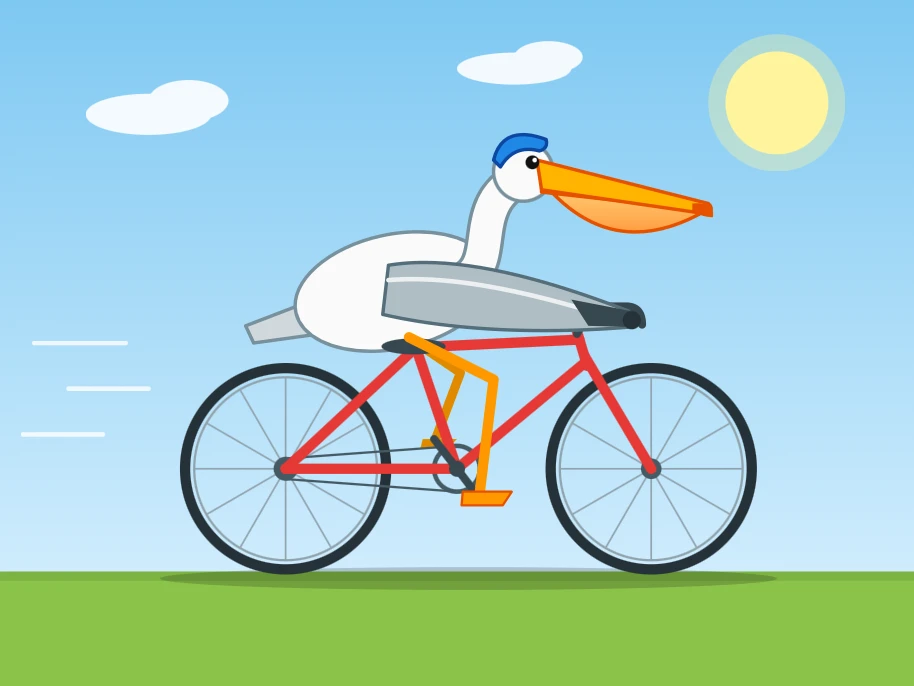
Simon Willison's first-look at Claude Sonnet 5.5, Anthropic's new Sonnet release priced the same as Sonnet 5 but described as 30%+ faster and up to 30% cheaper while beating it on benchmarks. He runs his standard 'pelican riding a bicycle' SVG/WebGL test across thinking-effort levels, notes Sonnet 5.5 hit the same runaway-thinking-token bug as Opus 5.5, and highlights that Sonnet 5.5 now powers the free tier of claude.ai, which he judges notably more capable than ChatGPT's free tier (running Luna 5.6).
What it claims
Anthropic released Claude Sonnet 5.5 on 28 September 2026. It is priced the same as Sonnet 5, and Anthropic says it "runs 30%+ faster, and costs up to 30% less for most work". Willison says it appears to beat Sonnet 5 on every benchmark, though the post cites no benchmark names or scores. Willison also judges it "almost as good as Opus 5.5 on some coding tasks", including viral 3D animation demos. Sonnet 5.5 is now the model behind the claude.ai free tier. ChatGPT's free tier runs Luna 5.6, and Willison calls Anthropic's free offering "much more capable".
Evidence
The post contains no benchmark tables, only Willison's informal pelican-on-a-bicycle SVG test at different thinking-effort settings:
| Effort | Tokens | Cost | Time | Result |
|---|---|---|---|---|
max | 128,000 (thinking, hit limit) | $1.28 | not stated | Failed: no SVG produced |
xhigh | not stated | 5.74 cents | 41 s | Working SVG |
On the free tier, the prompt build me an HTML page that renders a three-dimensional pelican riding a bicycle using WebGL returned what Willison calls "a solid effort". This is a single qualitative sample.
How to use it
- The thinking-effort levels named in the post include
maxandxhigh. - On this test,
xhighcost about 1/22 of whatmaxcost and actually produced output. - That makes
xhighthe practical ceiling to start from until themaxbehaviour below is fixed.
Limits
- Runaway thinking at
maxeffort: this is the same bug Willison saw with Opus 5.5. The model spent its whole 128,000-token budget on thinking and returned nothing, and the request was still billed ($1.28). If you route requests tomax, set token caps and handle empty responses. - No measured claims: the speed and cost claims are Anthropic's figures, and the post includes no measurements of its own.
- Coding comparison: "almost as good as Opus" is an impression from a few demos, not a measurement.
- Haiku 5.5: Anthropic says it is coming "in the coming weeks". Willison hopes it will be price-competitive with GPT-6 Luna. Its pricing is not yet known.
Technologies named here
Techniques named here
- Thinking effort setting
Related in models







