 xda-developers.comarticle
I'm not paying $20 for ChatGPT or Claude because a free local LLM does
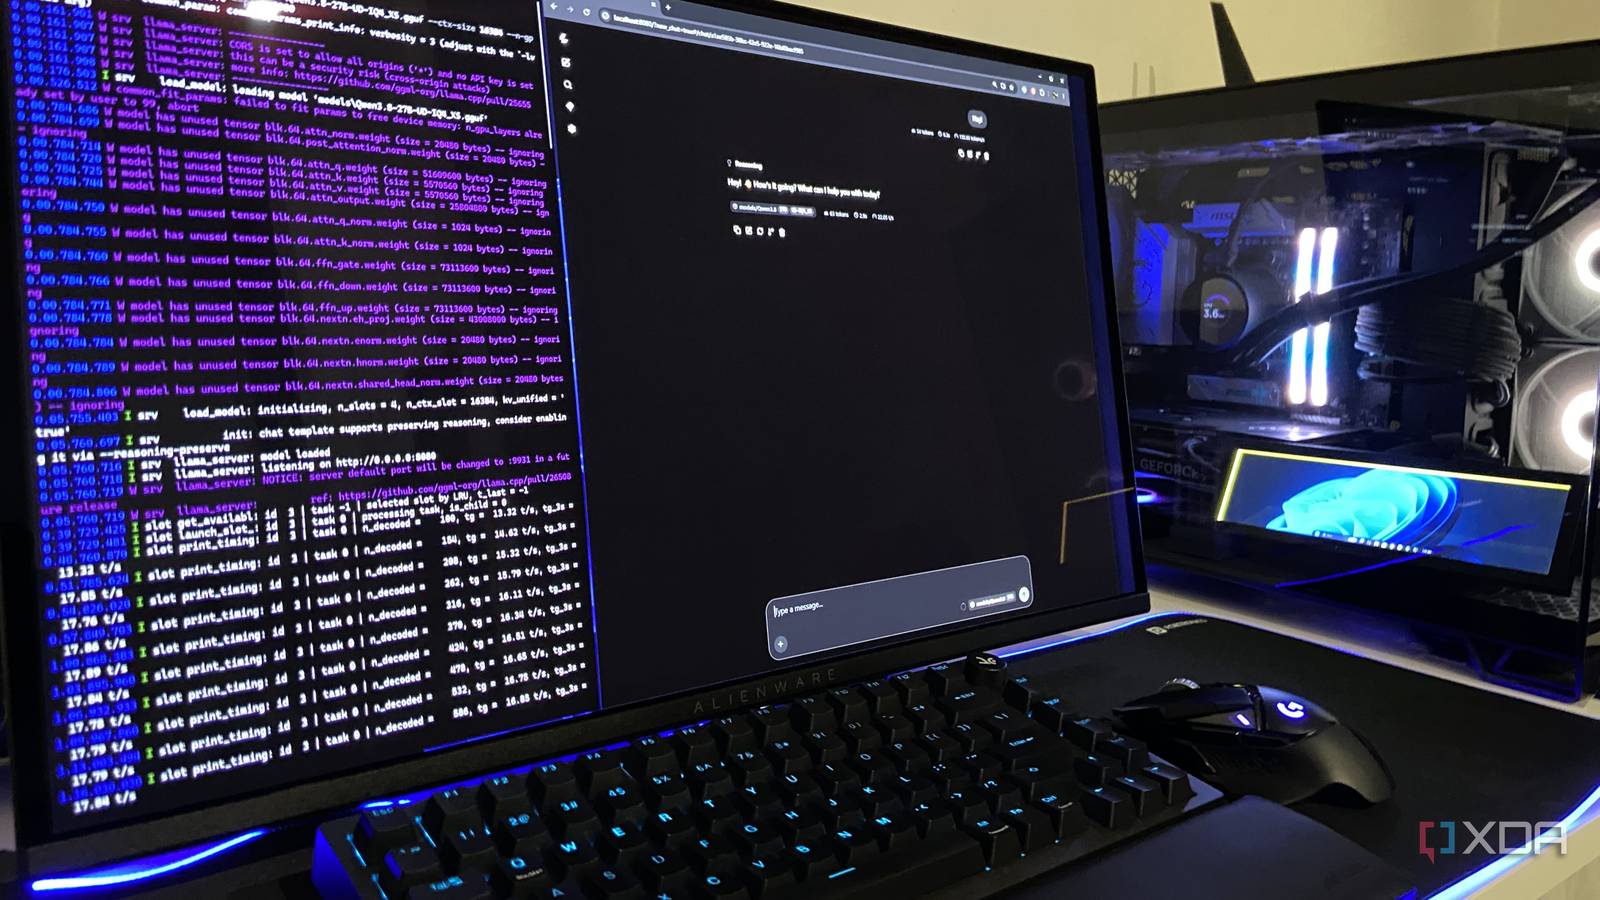
A personal workflow writeup describing how the author replaced $20 per month ChatGPT and Claude subscriptions with Qwen3.8-27B (Unsloth UD-IQ4_XS GGUF quant, 13.3GB) run locally via llama.cpp on a 4070 Ti Super GPU with 16GB VRAM, achieving about 33.7 tokens per second at a 16K context window. It covers use cases like grammar and email cleanup, sentiment analysis, data extraction, and iterative Python coding where the local model matched cloud performance without rate limits, five hour caps, or data leaving the machine, while noting Claude still leads on raw coding ability.
What it claims
A single user's account that Qwen 3.8-27B, run locally, covers most of what they used ChatGPT Plus and Claude Pro for. The author concedes the model "doesn't exactly top the benchmark charts" and that Anthropic's models remain better at coding. The argument is about workflow fit, not model quality. The title mentions Gemini, but the body never describes replacing it.
Evidence
All evidence is anecdotal and single-run. There are no comparisons against the cloud models on the same prompts.
- Coding: Asked for a working Snake game in Pygame as a single file, the model produced one in one shot. This is the only coding test described. The iterative Python work the author cares about is asserted, not demonstrated.
- Extraction: Given a deliberately rambling email about PC component prices containing about a dozen figures, the model pulled every number into a categorised table.
- Throughput: About 33.7 tokens/s, stated as holding "across runs". This is on a 4070 Ti Super with 16GB of GDDR6X VRAM, using the Unsloth UD-IQ4_XS build at 16K context and served by llama.cpp over localhost. Prompt length, generation length and llama.cpp flags are not given.
How to use it
The setup is the Unsloth UD-IQ4_XS GGUF of Qwen 3.8-27B (a 13.3GB file) served by llama.cpp on localhost. The page gives no commands, launch flags or download links.
The marginal running cost the author cites is the GPU's 285W wall draw, including when leaving the model iterating on a project overnight.
For smaller hardware, the author says Gemma-family models run "comfortably" on their 16GB laptop and smaller Qwen builds would run on older cards. No specific model sizes or quants are named for either.
Limits
- Claude stays ahead on coding by the author's own account. The local model's advantage there is the absence of five-hour and weekly caps and overage charges, not output quality.
- The 16K context is a VRAM-driven ceiling on a 16GB card. Longer contexts are not tested.
- The tasks covered are light: grammar and email cleanup, summarisation, sentiment analysis over forum threads, and number extraction. Nothing is reported on long multi-file codebases, tool use or agentic work.
- No accuracy checks are reported beyond the author's judgement.
Technologies named here
Related in inference



 arxiv.orgpaper
Minimally Invasive Steering of Language Models

 x.comthread
Samuel Zeng (@SamuelZengML) on X

 huggingface.coarticle