 latent.spacearticle
[AINews] The Future of Latent Space
The daily AINews digest from Latent Space rounds up a heavy week in AI: Claude Opus 5.5 topping SimpleBench and Terminal-Bench-Science, the GPT-6 family (Astra/Sol/Luna), Gemini 3.8 Flash, and Xiaomi's open-weight MiMo-V2.6-Pro; TypeSafe's Jev system-one decision model (and open alternatives like CLM) for cheap structured judgments; agent-infra launches from LangChain Interrupt and Perplexity's Rust retrieval engine Photon; inference speedups like Liquid AI's DSpark speculative decoder and GLM-5.3 on AMD MI355X; and research on harness distillation, agent failure modes, and autonomous-science efforts led by Sakana AI's RSI Lab with Jurgen Schmidhuber.
What it claims
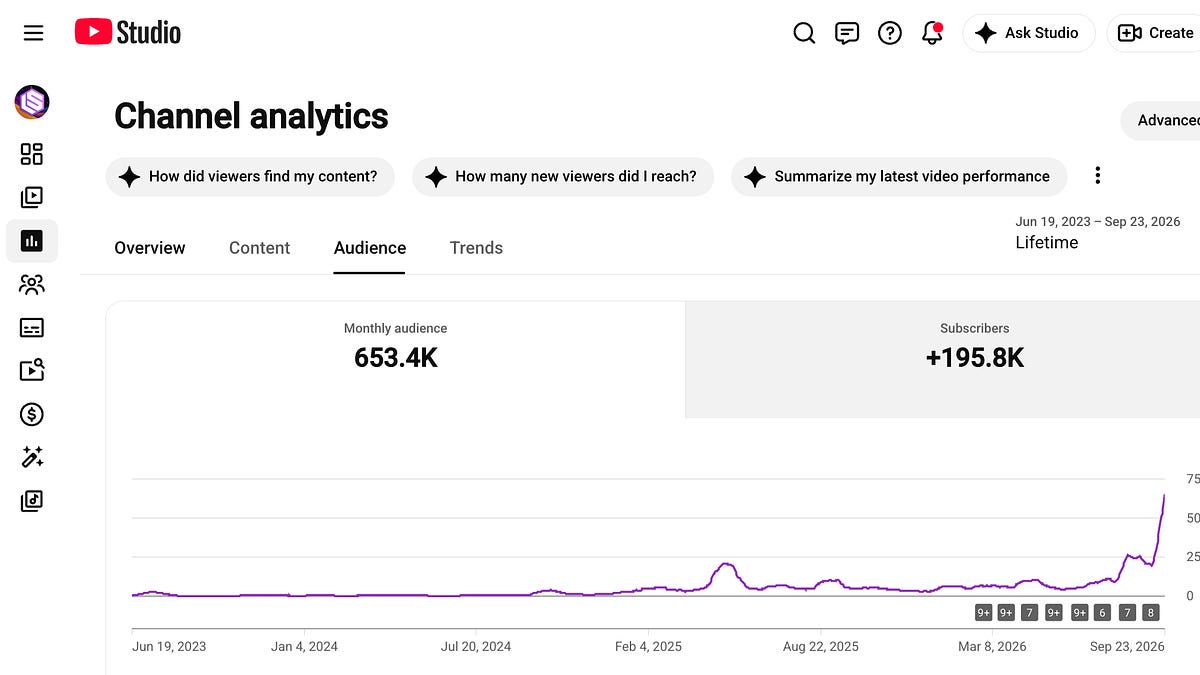
This is the AINews issue for 9/23–9/24/2026. It opens with an op-ed by swyx announcing changes to Latent Space:
- AINews v3 will merge the newsletter with the Latent Space Discord. The op-ed describes the Discord as tens of thousands of members, quieter than ever, and increasingly spammed.
- Latent Space will explore migrating to Beehiiv and launching a new homepage.
- It is reopening for sponsorships and tips.
The rest is the usual recap. What it adds over the summary is the numbers and settings behind each headline, plus several caveats and practical tips the summary omits.
Evidence
Frontier models
- Opus 5.5 scores 88.4% on SimpleBench. On Terminal-Bench-Science it goes from 24% at low effort to 62% at xhigh, then falls to 59% at max.
- GPT-6 Astra and Opus 5.5 lead Fable 5.1 by about 20 points. The best model from any other lab is Qwen3.8 Max at 12%.
- On vision, Opus 5.5 ranks above Fable 5 and GPT-6 Sol and below Astra, at roughly 60% lower cost than Fable 5.1.
Gemini 3.8 Flash
- 41 on the AA Intelligence Index at 291 tok/s with 1M context.
- ARC-AGI: 89.2% on v2 at $0.40/task and 98.5% on v1.
- On v3 it scores 10.4% with the standard harness and 35% with the provider harness, so the harness matters a lot.
MiMo-V2.6-Pro
- MIT licence, omni-modal, 1M context.
- Scores 46 on the AA index versus 47 for GPT-5.6 Sol, at $0.13 versus $1.99 per task.
- Xiaomi also released its RL code and training environments.
Jev-as-a-Judge
- $0.044 per 1K judgments at 152ms median latency, about 277× cheaper than GPT-6.
- Within 3 points on RewardBench and HaluEval, but 14.5 points behind on JudgeBench.
- A cascade that escalates low-confidence calls to Astra keeps 99% of accuracy at 57% of the cost.
- Ramp reports matching GPT-5.6 Luna on reranking with 300ms tail latency (10× lower) at 3× lower cost.
Perplexity Photon
- Internal p99 latency fell from about 800ms to about 65ms, on about 20% fewer machines, with 2.5× more data per document.
- It was built with hundreds of agents and about $300K in tokens.
- The Fast Search API runs at 160ms p50 / 230ms p95.
Liquid AI DSpark (drafter for LFM2.5-VL-3B)
- 3.13× decode speedup with MLX on M5 Max.
- 2.14× with llama.cpp on M3 Ultra.
- 2.66× with SGLang on H100.
Research
- Harness-Zero: with no harness at deployment, task success rises from 23.3% to 44.3%, beating the base model with the harness (41.7%).
- XYEval: a single confident, misleading user hint cuts scores by up to 46.7% relative.
- Meta memory agents: Sonnet 4.5 improves from 37.6% to 45.9%.
Transformers GGUF support (M2 Max throughput vs llama.cpp)
| Model | Transformers | llama.cpp |
|---|---|---|
| Qwen3.5-4B Q4_K_M | 70.4 tok/s | 71.8 tok/s |
| Qwen3.8-27B | 15.9 tok/s | 13.4 tok/s |
How to use it
- Reasoning effort: avoid "max" on Opus 5.5. It imposes a minimum reasoning budget, and xhigh scored higher.
- Weaviate 1.39 MMR: set
balanceexplicitly. The default of 0.0 means pure diversity. - GGUF in Transformers: load with
AutoModelForCausalLM.from_pretrained(..., gguf_file=...). - CLM: it is an open projection head (about 75 MB, fine-tunable) on Qwen3-8B. When serving through llama.cpp, use last-token pooling, because the heads were trained on last-token representations and mean pooling degrades scores: ``
llama-server --embedding --pooling last`` - Cheaper Jev-like options:
- Tev1 0.8B runs at about 50ms end to end locally on Ollama.
- GLiNER2.5-Decide runs at 167ms on CPU and 38–47ms on GPU.
- SmolDataEnvs: 5K+ verifiable data-science RL environments for sub-10B models, runnable on a single GPU.
Limits
Jev
- A widely upvoted r/LocalLlama critique argues Jev is constrained-choice classification, so it should be compared against NLI classifiers, cross-encoders and rerankers rather than LLMs.
- On Banking77, BGE-small plus logistic regression reportedly scored 93.3% against Jev's 83.2%.
- The "0% hallucination" claim only guarantees schema-valid output, not a correct choice.
CLM (self-reported limits)
- Weaker zero-shot breadth: 95.2% vs 99.2% on BFCL v4.
- Calibrated context of 2K–8K tokens, versus 64K for Jev.
- Its probabilities are normalized only over the supplied candidates, not on an absolute scale.
Other caveats
- MiMo's RL gains reportedly don't generalize to harder math evals.
- Anthropic's Claude-found ART enzyme system has unknown function. There is no evidence yet of gene editing.
- Most items are secondhand tweet or Reddit reports, so verify against the primary sources before relying on them.
Organisations named here
- Anthropic
- OpenAI
- Meta
- TypeSafe AI
- Xiaomi
- Google Research
- DeepMind
- xAI
- Databricks
- LangChain
- Perplexity
- Shopify
- Weaviate
- Liquid AI
- AMD
- Qualcomm
- Sakana AI
- C5R
- Fastino
- Ramp
- turbopuffer
- Supabase
- Baseten
- Fireworks
- Hugging Face
- SpaceX
- UkisAI
- Latent Space
- Google DeepMind
- Odyssey
- Harness-Zero
- Jev
- Jurgen Schmidhuber
- SciUniverse
- Terminal-Bench
- TypeSafe
- XYEval
Technologies named here
- LangChain
- Claude Opus 5.5
- Managed Deep Agents 0.8
- GPT-6 Astra
- GPT-6 Sol
- LangSmith Fine-Tuning
- GPT-6 Luna
- smithtune CLI
- Engine v2
- GPT-5.6 Luna
- Trajectories
- GPT-5.6 Sol
- Gemini 3.8 Flash
- Perplexity Photon
- Fast Search API
- Xiaomi MiMo-V2.6-Pro
- Grok 4.7
- Weaviate 1.39
- Quail
- Meta Muse Spark
- Liquid AI DSpark
- Fable 5
- vLLM
- TileRT
- Fable 5.1
- Pruna
- Qwen3.8 Max
- llama.cpp
- Jev
- MLX
- CLM
- Fastino GLiNER2.5-Decide
- SGLang
- Tev1
- Ollama
- Hugging Face Transformers
- AutoJev-27B
- LFM2.5-VL-3B
- Unsloth
- GLM-5.3
- Axolotl
- Qwen-Image-2.1
- bitsandbytes
- ComfyUI
- UkisAI Swift 1.5 27B
- UkisAI Swift Flash Next
- Heretic
- UkisAI Swift Bonsai 2
- Claude Code
- OpenRouter
- MiMo-V3
- Qwen3.5-4B
- TurboPuffer
- SmolDataEnvs
- Qwen3.8-27B
- Qwen3.5-35B-A3B
- Claude Sonnet 4.5
- GGUF
- LoRA
- GRPO
- Rust
- Qwen3
- Weaviate
- Hugging Face
- MiMo-V2.6-Pro
- Claude Fable 5.1
- Transformer
Techniques named here
- Speculative decoding
- Harness distillation
- MMR diversity at query time
- Reasoning effort scaling
- RL for Calibrated Decisions
- Confidence-based cascade escalation
- Contrastive ranking
- Disaggregated prefill/decode
- Dedicated memory agents
- GSPO RL with on-policy distillation
- Native GGUF loading in Transformers
Related in models






