
What it claims
Claude Haiku 5.5 is Anthropic's new fast, low-cost model. It is priced at $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100,000 tokens. That matches OpenAI's GPT-6 Luna and is a tenth of Haiku 4.5's $1/$5. Above 100,000 tokens the price rises 5x to $0.50/$2.50. Luna's price rises later, at 272,000 tokens, and only to $0.20/$0.75. The author's conclusion: for workloads under 100k tokens, Haiku 5.5 costs the same as Luna and reports higher benchmark scores. Above that, Luna "looks like a much better deal." No benchmark figures are given on the page.
The same day, Anthropic halved Sonnet 5.5 cache-read prices. It also added monthly API credits to subscriptions: $100 for Max 5x, $200 for Max 20x, and up to $500 for Team, pooled across users.
How to use it
Model ID used with the llm CLI is claude-haiku-5.5. The current llm-anthropic release picks up new models without a plugin update:
llm install -U llm-anthropic
llm anthropic refresh
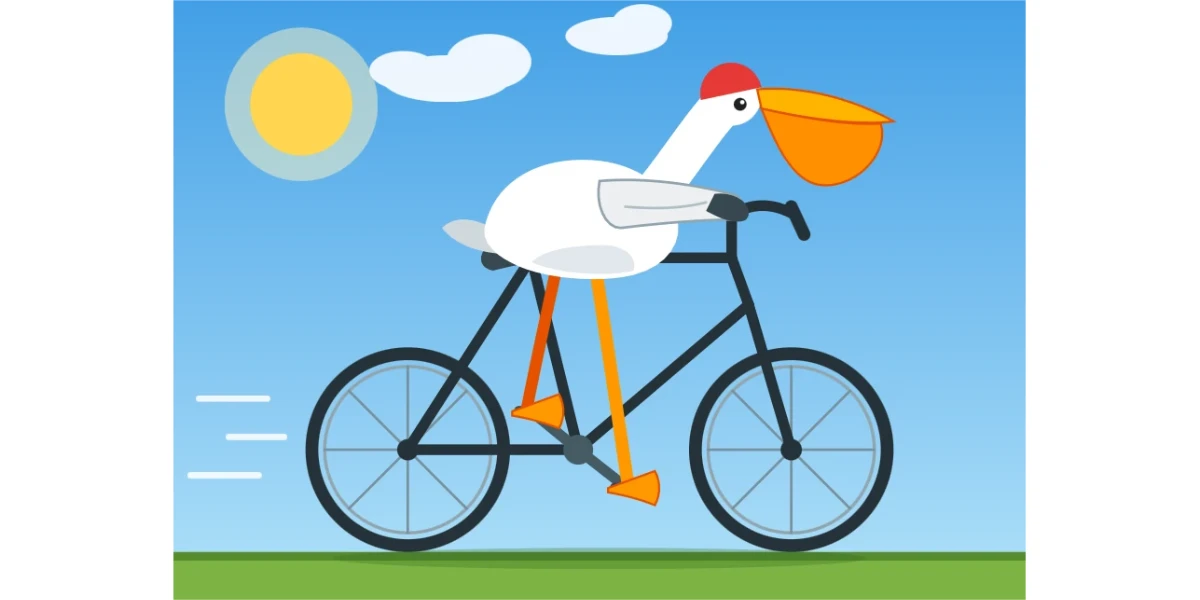
llm -m claude-haiku-5.5 "Generate an SVG of a pelican riding a bicycle" -o thinking_effort low
Reasoning effort levels are low, medium, high, xhigh and max. Reasoning cannot be disabled, and the default is medium.
Observed cost and latency for the pelican-SVG prompt:
| Effort | Cost | Time |
|---|---|---|
| low | 0.0936¢ | 7 s |
| max | 3.3826¢ | 5 min 9 s |
| Haiku 4.5, no reasoning levels | 0.7583¢ | — |
The bicycle frame came out well at every level above low.
To claim the subscription API credits, go to Settings → Billing and pick the API organization that should receive them. Auto-reload can be turned off, which makes "API requests … stop when your balance runs out." That avoids surprise bills.
Limits
- Hidden price increase from the tokenizer. Haiku 5.5 uses a new, less generous tokenizer. The same long prompt counted about 1.25x more tokens than with Haiku 4.5, so per-token prices understate the real cost.
- Long-context cost cliff. The 5x price jump at 100k tokens makes it much less competitive than Luna for long prompts.
- No way to turn off reasoning. This adds latency and cost even at the minimum. Max effort took over 5 minutes on a simple SVG prompt.
- Benchmark awareness. At max effort the reasoning trace began "This is the classic pelican-on-bicycle SVG test...", so the model recognized the test. The author ran a different prompt on xhigh as a cross-check. Treat familiar public prompts with suspicion when you evaluate it.
- Credits expire. Monthly API credits do not roll over.
- OpenAI alternative. OpenAI still lets Codex subscribers use their subscription for personal API calls. The author considers that a better deal for heavy API users.
- Unverified benchmark claim. "Higher benchmark scores" than Luna is stated without numbers or settings. Verify it on your own workload.
Technologies named here
- llm-anthropic
- Claude Haiku 5.5
- Claude Haiku 4.5
- LLM
- Claude Token Counter
- GPT-6 Luna
- Claude Sonnet 5.5
Techniques named here
- Reasoning/thinking effort levels
- Pelican riding a bicycle SVG test
Related in models







