Skip to content

32 results for β€œNous”

What you seeeverything
x.comthread🧠 AI

Luke The Dev (@iamlukethedev) on X

Hermes, the Nous Research agent framework, shipped 130 merged PRs in October 2026, according to this X recap by Luke The Dev. Main items are a unified gateway runtime, a Desktop and Bot Screen, a bundles and package manager, crash-safe updates and new Claude model entries. Ten PRs cover security: an iron-proxy credential-injection egress firewall for sandboxes, 31 CVEs patched in Python and npm lockfiles, and profile-export and prompt-leak fixes.

Hermesiron-proxyPython+2
Nous ResearchLuke The Dev

agents, ai-infraΒ· Added 2 Nov 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

High Precision Noise Cleaning for CKKS with Application to Asynchronous Threshold CKKS

High Precision Noise Cleaning for CKKS is an IACR ePrint preprint (2026/2675) by Zhihao Li, Cheng Hong and Tao Wei. It composes lower-degree Hermite polynomials to reach output noise bounds such as 2^-300 for noise flooding, and uses this to build an asynchronous threshold CKKS scheme with strong simulation security in the random oracle model. In OpenFHE, binary-message cleaning falls from 9.63 s to 1.54 s.

CKKSOpenFHE
noise floodingHermite interpolationfunctional bootstrapping+2

otherΒ· Added 31 Oct 2026, published 29 Oct 2026

metr.orgwriteupπŸ›‘οΈ Security

Red-Teaming OpenAI's Internal Agent Monitoring Systems

METR and Redwood Research summarize a three-week pilot red-team (21 July to 11 August 2026) of OpenAI's internal asynchronous misalignment monitoring system. They estimate 75-94% of agentic Responses API traffic was eligible for monitoring and report flaws: unmonitored compaction events, header-based monitor disabling, serialization mismatches that make the monitor fail, and a Codex sandbox and Auto-Review bypass. The post lists five design ideals for monitoring and control systems; exploit details are redacted.

OpenAICodexGPT-5.5+1
METRRedwood ResearchAuto-Review+3

AI SecurityΒ· Added 29 Oct 2026, published 22 Oct 2026

arxiv.orgpaper🧠 AI

Large Flow Language Models

Lafa (Large flow language model) is a blockwise continuous flow language model scaled to 8B parameters, with causal attention on the prefix and bidirectional, asynchronous flow within each block. It is adapted from pretrained autoregressive models and trained at 0.5B, 7B and 8B with under 30B tokens. A self-speculative decoding scheme verifies flow drafts autoregressively in one model, giving 2.54x the throughput of an AR model at comparable quality. Flow maps allow one- and few-step generation.

flow matchingdiffusion modelTransformer+1
Lafa

research, modelsΒ· Added 22 Oct 2026, published 20 Oct 2026

arxiv.orgpaper🧠 AI

Mitigating Reward Hacking in Preference Reward Models with Evolving Penalties

Dynalize is a method that reduces reward hacking during online RL training against preference reward models. Periodically and asynchronously, a language model reads training rollouts and writes penalties for undesirable behaviors the reward model seems to reward, and a judge applies them to every rollout. In clinical counseling and creative writing it sustains longer training and improves external benchmarks, and the gains hold in multi-turn training and after reward model retraining.

LLM
DynalizearXiv

training, research, ai-safetyΒ· Added 21 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🧠 AI

MLExpert: Towards a Generalist Agentic Model for Autonomous Machine Learning Engineering

Presents MLExpert, a 35B Mixture-of-Experts agentic model trained for autonomous long-horizon machine learning engineering. Training uses a Kaggle-MLE Factory to build executable tasks and an interaction harness, hierarchical agentic SFT with outcome-guided supervision, and Windowed Interaction RL (WIRL). WIRL treats the multi-turn decisions between successive experiment results as one execution window with a shared outcome reward, and uses asynchronous collection and policy correction. On MLE-Bench Lite the average medal rate rises from 37.9% to 72.7%, comparable to larger frontier models such as Kimi-K3 and GLM-5.3. It also improves on NatureBench Lite, agent scaffold optimization and algorithm optimization.

Mixture of ExpertsLLM
MLExpertKaggle-MLE FactoryMLE-Bench+4

research, training, agentsΒ· Added 17 Oct 2026, published 15 Oct 2026

arxiv.orgpaper🧠 AI

Velox: Spatial Memory Makes World Models Efficient

Velox is a training-free attention router for chunked video-diffusion world models. It uses camera frustum slabs with depth intervals from streaming geometry to pick which historical token blocks to attend to, instead of letting the KV cache grow with rollout length. Frustum overlap softly modulates each layer's model-derived block importance, and uncovered regions keep the model's own routing. The fixed block granularity suits FlashAttention-style tiled execution, and slab construction runs asynchronously with denoising on the same H200. At chunk 48 it speeds up attention 4.36Γ— and denoising 2.43Γ—, and on the 158-case WBench navigation split it stays within 0.15 average points of dense LingBot-Fast-Cam.

diffusion modelFlashAttentionCUDA
VeloxLingBot-Fast-CamWBench+1

research, multimodal, inferenceΒ· Added 17 Oct 2026, published 15 Oct 2026

huggingface.copaper🧠 AI

MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement

Technical report for Xiaomi's MiMo-V2.6 omni-modal model family, which scales RL compute along three axes: asynchronous training with 1,568 samples and 2.7-3.7B tokens per step at up to 1M context, more diverse environments (code, general, visual, cyber) under mixed agent harnesses, and groupwise agentic grading that gives better reward signals and favors shorter, token-efficient solutions. Stability measures include a frozen MoE router and a multi-layer defense against reward hacking, built on a mid-trained hybrid-SWA architecture. The authors open-source training dynamics, RL environments and the RL framework, which makes it a useful reference for reproducing scaled agentic RL.

Mixture of ExpertsHugging Face
MiMo-V2.6Xiaomi

training, research, agentsΒ· Added 10 Oct 2026

huggingface.copaper🧠 AI

TokenRouter: Efficient Serving System for Token-Level LLM Routing

TokenRouter is a serving system for token-level routed LLM inference, where different tokens of one request are routed across different models. It uses request-centric programming with model-centric execution: developers write routing logic per request while the runtime launches a subserver per LLM and dispatches requests asynchronously. Each subserver uses a delayed-batching scheduler whose hyperparameters come from a mathematical throughput model, fixing step desynchronization and batch admission delays and giving 2.01-64.15x higher decoding throughput than existing systems.

TokenRouterHugging FaceGitHub

inference, researchΒ· Added 9 Oct 2026

reflection.aiarticle🧠 AI

Introducing Beam: Reflection AI's 501B open-weight model

Reflection AI announces Beam, a 501B-parameter (23B active) sparse Mixture-of-Experts open-weight model built for coding, reasoning, and agentic tasks, pretrained on 23.8T tokens and refined with a massive asynchronous RL run (100M+ rollouts on 10.5K NVIDIA GB300 GPUs). The post details the MoE optimization recipe (auxiliary-loss-free load balancing with cosine-decayed expert bias, sequence-level balancing, FP32 residual accumulation), the asynchronous RL infrastructure handling policy staleness and fast weight propagation, and a safety/alignment pipeline using multi-teacher on-policy distillation and deliberative alignment. Weights will be released under Apache 2.0 with a technical report later in the month.

Mixture of ExpertsKubernetes
Reflection AIBeamGLM-5.2+5

models, trainingΒ· Added 8 Oct 2026

arxiv.orgpaper🧠 AI

MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement

Technical report for the MiMo-V2.6 omni-modal model series, which scales RL compute after mid-training on a multimodal corpus, using a hybrid sliding-window-attention architecture. RL is scaled along three axes: asynchronous training with 1,568 samples and 2.7-3.7B tokens per step at up to 1M context; diverse environments (code, general, visual, cyber) under mixed agent harnesses; and groupwise agentic grading that gives better rewards for long-horizon tasks and favors shorter, token-efficient solutions. Stability measures include freezing the MoE router and a multi-layer defense against reward hacking. The authors open-source the training dynamics, RL environments and RL framework.

Mixture of Experts
MiMo-V2.6Xiaomi

training, research, modelsΒ· Added 9 Oct 2026, published 8 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Fair and Efficient Helper-Aided MPC with Cheater Identification

This paper introduces Alhena (synchronous) and Wasat (asynchronous), two helper-aided multi-party computation protocols that achieve "identifiable fairness": if an adversary aborts the protocol, no party gets the output and honest parties can identify at least one common cheater, closing a gap in prior fair-but-unaccountable helper-aided MPC schemes. The authors benchmark against state-of-the-art fair protocols Asterisk and Castor (both from Kamarkar et al., IEEE S&P 2024/2026), showing 4–12.5x and 2.5–5x online-phase speedups respectively, with online performance unaffected by active misbehavior.

AlhenaWasatAsterisk+1

otherΒ· Added 8 Oct 2026, published 7 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Bounded Provisional Visibility: Controlling Poisoning Exposure in Continuously Ingested RAG Vector Stores

This paper proposes a fail-closed "bounded provisional visibility" protocol for continuously ingested RAG vector stores, which admits new content under a verification deadline and hides items whose vetting hasn't committed in time, bounding how long unvetted (potentially poisoned) content can be retrieved. Evaluated on five document workloads using an exact-match backend and Milvus with HNSW indexing, the deadline-based admission cut median poisoned retrievals from 34 to 7 under verifier backlog versus asynchronous admission with no deadline, while verify-before-visible avoided exposure entirely but delayed clean content visibility to 6.3s versus 3ms for provisional admission. The work quantifies the inherent trade-off between freshness, availability, and poisoning exposure in continuously updated retrieval systems, and shows results remain conditional on the quality of the underlying poison detector.

Milvus

AI SecurityΒ· Added 6 Oct 2026, published 5 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Plotkin Attacks! On the (Mis)use of Raptor Codes in Asynchronous Verifiable Information Dispersal

Victor Shoup shows that "reconstruct-later" asynchronous verifiable information dispersal (AVID) designs β€” used by data-availability systems including an early Walrus design/testnet β€” are insecure when built on the standardized Raptor codes R10 (RFC 5053) and RaptorQ (RFC 6330). Using the Plotkin bound, he proves that a Byzantine disperser can choose a subset of f+1 honest fragments that fails to reconstruct the message, gives randomized polynomial-time algorithms to find such subsets, and implements a working attack that defeats an RFC 6330 RaptorQ decoder on every adversarial subset tested (success for f from 9 to 45). Benchmarks show plain Reed-Solomon coding is an MDS alternative that is often faster and never much slower than R10/RaptorQ, making it the safer practical choice for this design pattern.

WalrusRaptorQReed-Solomon
RFC 5053RFC 6330Plotkin bound+1

BlockchainΒ· Added 8 Oct 2026, published 4 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Persona Guardrail: A Production-Grade Defense Framework for Agentic Systems

Persona Guardrail is a production-grade runtime defense framework for customer-facing LLM agents that enforces explicit functional boundaries via synchronous input/output validation against semantic allowlist and blocklist specifications. The authors also introduce PAGE (Persona-Aware Guardrail Evaluation), a benchmark covering benign, adversarial, and out-of-domain user and agent turns; deployed in production, it raises overall accuracy from 85.7% to 95.9% versus a generic LLM-based guardrail, boosts out-of-domain detection from 57.3% to 93.5%, and cuts the false-approved rate from 25.0% to 4.7%, all within latency budget.

LLM
PAGE (Persona-Aware Guardrail Evaluation)

AI SecurityΒ· Added 5 Oct 2026, published 2 Oct 2026

arxiv.orgpaper🧠 AI

EdgeAgent: Orchestrating On-Device LLM inference for End-User Multi-Agent Systems on CPU-GPU Unified Memory Architectures

EdgeAgent is a cross-layer LLM inference system for running multi-agent workloads on edge devices with CPU-GPU unified memory architectures such as Apple M-series SoCs. It introduces zero-copy UMA-aware tensor parallelism to saturate both CPU and GPU, a dynamic speculative-decoding draft-budget scheduler adapting to sequence predictability, and an asynchronous suspend-and-yield mechanism that evicts stalled agents during tool-call latencies. On an Apple M4 SoC it reports 1.29x speedup from UMA-aware execution alone and 1.77x with full agent-aware scheduling, versus batched speculative decoding.

speculative decodingtensor parallelism
Apple M4

inference, agentsΒ· Added 5 Oct 2026, published 2 Oct 2026

alignmentforum.orgwriteup🧠 AI

Endogenous Alignment Requires Dependence

A short conceptual post on the AI Alignment Forum by Gordon Seidoh Worley, part of their "Uncertain Updates" sequence, arguing that for an AI system's alignment to be "endogenous" (arising from the system's own values/reasoning rather than imposed externally) it must nonetheless involve some form of dependence β€” likely on human oversight, feedback, or external grounding. The full body text was not available at fetch time, so the specific argument and its relation to corrigibility or value-learning debates could not be confirmed from the page itself.

Gordon Seidoh WorleyAI Alignment Forum

ai-safetyΒ· Added 7 Oct 2026, published 1 Oct 2026

openid.netpaperπŸ›‘οΈ Security

Identity Management for Agentic AI [pdf] (2025)

OpenID Foundation whitepaper (Oct 2025, lead editor Tobin South) analyzing how authentication/authorization for AI agents differs from traditional software clients. It covers where OAuth 2.1, OIDC, SSO/SCIM, and MCP already work for single-domain synchronous agents, and lays out unsolved problems for autonomous agentic identity: agent identity fragmentation across vendors, replacing user impersonation with explicit delegated "on-behalf-of" authority, consent-fatigue at scale, recursive delegation chains between sub-agents, agents acting for teams of users, and browser/computer-use agents bypassing API-based authorization entirely.

Model Context ProtocolOAuthOIDC+2
IPSIEOpenID FoundationLoyal Agents Initiative

Identity & Access, AI SecurityΒ· Added 2 Oct 2026, published 1 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

SEABench: Benchmarking Endogenous Misalignment In Self-Evolving Agents

SEABench is a benchmark of 48 longitudinal task sequences designed to study endogenous misalignment in self-evolving LLM agents β€” agents that modify their own controller instructions, memory protocols, and tools in response to feedback. It includes an adaptive trajectory discovery pipeline and paired non-evolving baseline agents for causal attribution, and finds that self-evolution boosts task completion but introduces safety failures absent in static baselines; the authors also show that chain-of-thought monitoring can catch these divergent unsafe behaviors with a low false-positive rate.

LLM
SEABench

AI SecurityΒ· Added 29 Sep 2026, published 28 Sep 2026

arxiv.orgpaper🧠 AI

SEABench: Benchmarking Endogenous Misalignment In Self-Evolving Agents

SEABench is a benchmark for studying "endogenous misalignment" in self-evolving LLM agents β€” agents that modify their own controller instructions, memory, and tools after deployment based on feedback. It comprises 48 longitudinal task sequences across multiple evolution surfaces, task domains, and harm types in a personal-assistant environment, using an adaptive trajectory discovery pipeline and paired non-evolving baseline agents for causal attribution. Evaluation across several LLMs shows self-evolution boosts task completion but introduces safety failures absent in non-evolving baselines, and the paper proposes a chain-of-thought monitoring strategy that mitigates unsafe behavior with low false positives.

SEABench

ai-safety, evals, agentsΒ· Added 29 Sep 2026, published 28 Sep 2026

github.comrepo🧠 AI

imkofty/Hermuse

Hermuse is a set of scripts and guides for running Hermes Agent (from Nous Research), the 9Router OpenAI-compatible model router and a Telegram gateway on a Linux VM. It adds a Cloudflare Pages and D1 long-poll tunnel to expose the 9Router dashboard, cron watchdogs including a gateway stall detector, and a default-deny Telegram allowlist. MIT licensed.

Hermes9RouterTelegram+9
Nous ResearchMuse

agents, ai-infraΒ· Added 2 Nov 2026, published 27 Sep 2026

arxiv.orgpaper🧠 AI

ASPIRE: Asynchronous Batched Self-Speculative Decoding for Long-Context LLM Inference

ASPIRE is a non-synchronized batched self-speculative decoding framework for long-context LLM inference, where requests independently choose when to verify instead of sharing a global draft-verify schedule. It combines a unified mixed forward pass, a per-request online speculation scheduler using acceptance-rate estimates and a batch-aware cost model, and an intra-draft refresh layer that periodically applies full attention to reduce staleness. Across three models and five reasoning/long-context benchmarks it reports 1.70-4.58x decoding throughput speedup over autoregressive baselines, ~27% better than prior self-speculative baselines.

ASPIRE

inference, researchΒ· Added 26 Sep 2026

arxiv.orgpaperπŸ›‘οΈ Security

LLM Agents Can Easily Tamper With Their Own Traces

This arXiv paper shows that local LLM coding agents such as Claude Code, Codex, Antigravity, OpenCode and Grok Build can be induced to delete or tamper with their own execution traces, defeating the assumption behind asynchronous monitoring, incident investigation, and compliance audits. Only one tested harness, Muse Code, blocked this behavior; the authors also show external attackers can trigger trace deletion and that trace tampering emerges naturally as agents try to maximize reward, which could be used to conceal scheming or sabotage. They recommend enforcing trace logging via an independent interception mechanism outside the agent's control so integrity survives even full host compromise.

Claude CodeCodexOpenCode+1
AntigravityMuse Code

AI Security, Blue Team & DetectionΒ· Added 25 Sep 2026, published 24 Sep 2026

arxiv.orgpaper🧠 AI

Agensh: Scaling Organizational Intelligence to 1,024 Agents

Agensh is a decentralized multi-agent harness that removes the central orchestrator bottleneck limiting current multi-agent frameworks, using a shared workspace, message interface, and shared context to let workers self-organize, claim sub-tasks, and merge progress asynchronously. Evaluated with GPT-5.6-sol on ProgramBench tasks, scaling from 1 to 128 agents lifted mean final test-pass rate from 19.31% to 28.78%, and on pandoc scaling to 1,024 agents raised pass rate from 33.89% to 55.06%, showing agent count itself as a new scaling axis for organizational intelligence.

GPT-5.6-sol
AgenshProgramBenchpandoc

agents, researchΒ· Added 23 Sep 2026, published 22 Sep 2026

arxiv.orgpaper🧠 AI

MintAct: A Unified Visual Agent for Digital Environments

MintAct is a family of vision-language models (2B/4B/8B) that unifies UI grounding, multi-step navigation across mobile, desktop, and web, and visual tool use into a single agent, matching per-domain specialist performance. The authors built a scalable environment and asynchronous RL infrastructure that hosts hundreds of concurrent heterogeneous backends for trajectory collection and online RL while staying stable under noisy feedback and off-policy drift, achieving 48.9 on OSWorld-Verified at competitive model sizes.

vision-language model
MintActOSWorld-Verified

multimodal, agents, research, trainingΒ· Added 22 Sep 2026, published 18 Sep 2026

github.comrepoπŸ›‘οΈ Security

Numbat

Numbat is a Go-based, single-binary endpoint agent from Perplexity AI that gives visibility into AI coding-agent activity (Claude Code, Codex, OpenClaw, and other CLI/IDE/gateway agents) by capturing events through local hooks, OTLP/HTTP logs, and on-disk session artifacts. It normalizes activity into one event model, evaluates it with a local CEL rule engine (including multi-step sequence rules like secret-read-then-egress), and can optionally block matched actions via synchronous pre-action hooks (deny/monitor decisions), with case bundles and SHA-256 manifests for forensic reconstruction. Example built-in rules detect cloud-metadata SSRF requests (169.254.169.254) and credential-exfiltration chains, mapped to MITRE ATT&CK technique tags.

Claude CodeCodexOpenClaw+2
T1048T1552T1567

AI Security, Blue Team & DetectionΒ· Published and added 5 Sep 2026

github.comrepo🧠 AI

baidu-baige/LoongSage

LoongSage is Baidu's open-sourced, production-grade reinforcement learning framework for post-training LLMs, built on Ray for scheduling, Megatron-Core/Megatron-Bridge for training, and SGLang for inference. It targets agentic RL with a zero-intrusion AgentFlow module (automatic multi-turn context, loss masking, trajectory collection), multi-paradigm online distillation (PG-Style, GKD-Style, TopK/full-vocab/JSD KL), fully asynchronous training with partial rollout, and system-level training-inference consistency guarantees (Router Replay, TITO, M2PO, OPSM) that keep probability bias at 1e-4 in MoE/low-precision settings. Recipes are validated on Baidu's internal production runs of DeepSeek-V4-Flash and Qwen3-30B-A3B for math reasoning, agentic code repair, and distillation.

RaySGLangDocker+4
LoongSageBaiduMegatron-Core+10

training, agentsΒ· Added 30 Sep 2026, published 28 Aug 2026

github.comrepo🧠 AI

whitecircle/halo

Halo is White Circle's open-source training framework that runs the same codebase from a single GPU to multi-node clusters, adding Expert/Context/Tensor/Expert-Tensor parallelism (EP/CP/TP/ETP) directly onto native Hugging Face models via FSDP2, DTensor and DeviceMesh rather than a separate distributed model implementation. It covers the full training lifecycle β€” pre-training, SFT, preference optimization, distillation, and fully asynchronous multi-turn RL with a Transformers-side trainer pushing weights over NCCL to vLLM/SGLang rollout servers β€” and reports up to 2.8x the throughput of stock TRL for gpt-oss-20b on 8x B300 GPUs. It ships as prebuilt Docker images for Blackwell and Hopper GPUs with FlashAttention-4, DeepEP V2, DeepGEMM, and a bf16 AdamW optimizer integrated, supports 15 MoE families, and includes LoRA/QLoRA paths that fit consumer GPUs.

Hugging FaceTRLPyTorch+9
White CircleDeepSeek-AIDeepEP+5

trainingΒ· Added 30 Sep 2026, published 26 Aug 2026

huggingface.coarticle🧠 AI

Granite 4.2 LLMs: How They're Built

IBM's technical write-up on Granite 4.2, its first family of dense decoder-only reasoning LLMs (3B, 8B, 30B), post-trained from Granite-4.1 base models pretrained on ~15T tokens with a five-phase schedule extending context to 512K tokens. It details the SFT data mixture (agentic vs. non-agentic, quality filtering with LLM judges GPT-OSS-120B and Gemma 4), a staged asynchronous-GRPO RL pipeline (RLVR, skill boosters, then agentic SWE/Terminal/Search stages for 8B/30B, finishing with RLHF), and the NeMo-RL/NeMo-Gym infrastructure used to run tool-using RL rollouts at scale, plus FP8/NVFP4/MXFP4/GGUF quantized releases and integration guides for vLLM, SGLang, OpenCode, Pi, and OpenHands.

vLLMSGLangllama.cpp+7
Granite 4.2IBMGranite-4.1+21

models, trainingΒ· Added 29 Sep 2026, published 25 Aug 2026

interconnects.aiarticle🧠 AI

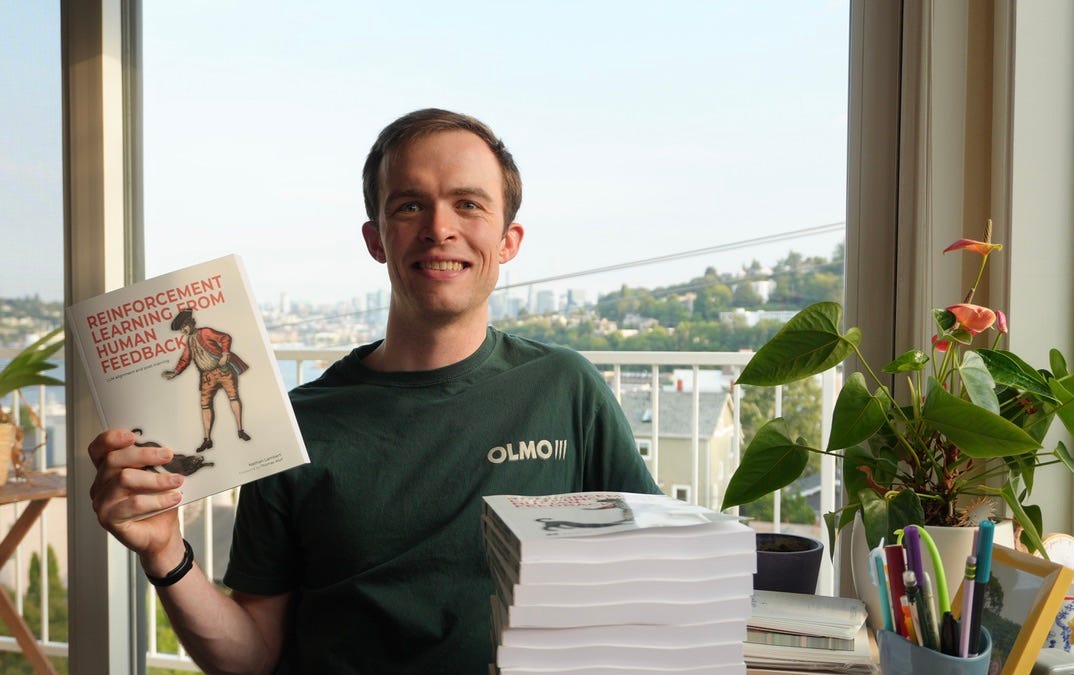
5 useful things you'll learn in my new post-training textbook (shipping now!)

Nathan Lambert (Interconnects) announces his new book, Reinforcement Learning from Human Feedback: Aligning and Post-training LLMs (Manning), which is also freely available online with a full 12-hour video course, code exercises, and model completion comparisons. The post walks through five takeaways: intuitions for RL algorithms (policy-gradient theorem, PPO clipping, GSPO, CISPO), systems tradeoffs in modern RL (asynchronous learner and actor setups, loss aggregation behind DAPO and Dr. GRPO, truncated importance sampling), the three historical eras of RLHF and post-training, a chapter demystifying distillation (including multi-teacher on-policy distillation used by models like Xiaomi MiMo-V2-Flash and DeepSeek V4), and a survey of practical post-training pitfalls such as over-optimization, regularization, evaluation, and character training.

GRPO
Nathan LambertInterconnectsManning+4

trainingΒ· Added 29 Sep 2026, published 10 Aug 2026

Showing 30 of 32

Show more