Skip to content

47 results for “sharp”

What you seeeverything
“sharp”
x.comthread🛡️ Security

ESET Research (@ESETresearch) on X

ESET Research thread summarising its APT Activity Report for April to September 2026 on Russia-aligned groups targeting Ukrainian defense, government and infrastructure. Gamaredon deployed Turla's new VBScript recon tool Rezzuar, indicating FSB-linked collaboration, and updated its file stealer PteroBox while activity fell sharply from mid-May. A separate campaign hit MDaemon mail servers via CVE-2025-8088, delivering HELLAGE and HELLTAG backdoors with no user interaction.

MDaemonClamAVWinRAR+1
CVE-2025-8088GamaredonTurla+6

Threat Intel· Added 31 Oct 2026, published 30 Oct 2026

arxiv.orgpaper🧠 AI

Sliding Networks: A Family of Residual Structures Preserving Feature Learning and Feature Diversity

Sliding Networks is a family of residual network structures with a joint width and depth scaling recipe that keeps both locally maximal feature learning and feature diversity in the residual stream. The key quantity is the ratio N_flat/(N_sharp L) tending to a constant alpha, and Half Copy correlated initialization can relax the shape constraints. Residual-MLP experiments support an SDE limit, but language-model experiments show performance differences under regrouping at fixed parameter count.

Transformer
arXiv

research· Added 27 Oct 2026, published 24 Oct 2026

arxiv.orgpaper🧠 AI

Sharpness-aware Orthogonalized Momentum Algorithms

SOMA (Sharpness-aware Orthogonalized Momentum Algorithm) combines sharpness-aware minimization (SAM) with the Muon optimizer for LLM training. It avoids SAM's extra gradient computation by using stale, purely stochastic gradient noise as the adversarial perturbation. The authors prove sample complexity does not depend on perturbation direction, study robustness to heavy-tailed gradient noise, and test SOMA against post-training quantization degradation and catastrophic forgetting during fine-tuning.

MuonLLM
SOMAarXiv

research, training· Added 26 Oct 2026, published 23 Oct 2026

github.blogarticle🛡️ Security

How bug bounty sharpens one researcher’s security skills

GitHub Bug Bounty spotlight interview with @r31n, a researcher known for GitHub Enterprise Server findings. They describe a source-and-sink approach to mapping trust boundaries, chaining minor bugs (open redirect plus allowlisted SSRF that follows redirects), and confirming a finding only with a working PoC. They also cover using AI for code navigation and PoC scripts, and treating model output as untrusted input.

GitHub Enterprise ServerGitHubHackerOne
SSRFopen redirectXSS+3

Learning, AppSec· Published and added 22 Oct 2026

x.comarticle🛡️ Security

lee1981 (@lee1981b) on X

CyberForge Weekly CVE Rundown #006 covers six CVEs from 12-17 October 2026: BotSharp default signing key, GitLab CI/CD regex compiler overflow (CVSS v3.1 10.0), Ivanti Connect Secure auth bypass, Cisco Secure Email Gateway, BeyondTrust Remote Support and the Linux kernel PwnEscape guest-to-host bug. It gives fixed versions, KEV and EPSS status as of 18 October, and separates patch verification from compromise investigation.

GitLabIvanti Connect SecureCisco Secure Email Gateway+3
CVE-2026-108860CVE-2026-97229CVE-2026-104935+9

Blue Team & Detection, Threat Intel· Added 20 Oct 2026, published 18 Oct 2026

x.comadvisory🛡️ Security

Dark Web Intelligence (@DailyDarkWeb) on X

Summary of Vercel's Oct 14, 2026 out-of-band Next.js security release fixing two critical unauthenticated RCEs: one in App Router apps with Cache Components where a "use cache" function returns multiple typed arrays (GHSA-673q-mjm6-r5xr, upstream React GHSA-xqc2-xf4c-x3h3, no workaround), and one in the Image Optimization API handling SVG on glibc Linux via a memory bug in a library used through sharp (CVE-2026-96889 / GHSA-2464-fhr4-w9xw, workaround sharp 0.35.5+). Also covers a high-severity Server Actions DoS (GHSA-p3m5-59mp-jv5r). Fixes ship in two supported Next.js LTS lines. No in-the-wild exploitation reported.

Next.jsVercelReact+2
CVE-2026-96889GHSA-673q-mjm6-r5xrGHSA-xqc2-xf4c-x3h3+2

AppSec· Added 17 Oct 2026, published 16 Oct 2026

huggingface.coarticle🧠 AI

HiRO-ACEv2: Simulating extreme weather at 3 km resolution for a fraction of the cost

Ai2 announces HiRO-ACEv2, an update to its AI climate emulator. ACE simulates at 100 km, and the new HiROv2 downscaling model sharpens its output to 3 km. HiROv2 predicts rain, wind and pressure together and matches X-SHiELD high-resolution statistics to within 3%, even for events that occur once in a million data points. It also reproduces tropical cyclone energy, including storms unseen in training. The full system generates global 3 km climate data at about 1/300th the cost of X-SHiELD. Limitations are that it only works with the X-SHiELD-tuned ACE and cannot yet handle warmer climates or ERA5. Models, tutorial notebooks and a web demo are available.

HiRO-ACEACEX-SHiELD
Ai2HiRO-ACEv2HiROv1+3

models, research· Published and added 14 Oct 2026

securityweek.comarticle🛡️ Security

Microsoft Patches Record 1,413 Vulnerabilities, Including Exploited Windows Zero-Day

SecurityWeek reports Microsoft's October 2026 Patch Tuesday fixed a record 1,413 CVEs (1,102 in Windows, 134 Office, 36 SharePoint), more than all of 2025, with the surge attributed largely to AI-driven discovery. The exploited zero-day CVE-2026-96951 is a Windows shell Mark of the Web security feature bypass (CVSS 8.8), added to CISA KEV with an October 16 deadline. Two flaws were publicly disclosed: CVE-2026-108398 (WDAC bypass) and CVE-2026-92707 (MessagePack-CSharp DoS), and Microsoft introduced 'risk cohorts' for patch prioritization.

WindowsWindows Defender.NET+2
CVE-2026-96951CVE-2026-108398CVE-2026-92707+5

Threat Intel, Blue Team & Detection· Published and added 14 Oct 2026

hackers-arise.comwriteup🛡️ Security

Artificial Intelligence (AI) in Cybersecurity, Part 28: Using ADStrike to Compromise Active Directory

ADStrike is an Active Directory attack framework with 52 attack modules and configurable OPSEC levels. An optional AI orchestrator, run here on a local Ollama model such as Qwen 2.5-coder 7b, picks the next tool from each step's output. The walkthrough runs it from Kali against a lab domain with an unprivileged account. It covers LAPS checks, kerberoasting, Timeroasting, Pre2k, SharpHound/BloodHound analysis and HTML reports with MITRE ATT&CK coverage.

ADStrikeActive DirectoryOllama+3
kerberoastingTimeroastingPre2k+3

Offensive Security, AI Security· Published and added 12 Oct 2026

x.comadvisory🛡️ Security

lee1981 (@lee1981b) on X

CyberForge's CVE of the Day #075 covers CVE-2026-108860, a critical (CVSS 9.1 v3.1 / 9.3 v4.0) authentication bypass in SciSharp BotSharp through 5.2.0. WebStarter ships a published default HMAC JWT signing secret (CWE-321), so anyone holding it can forge bearer tokens that impersonate known users, including administrators. The post sets out how to confirm the effective key and serving build, a six-step SOC investigation trail, and remediation by rotating the secret. No verified fixed release, KEV entry or EPSS data existed at cutoff, and the linked research is static-only.

BotSharpASP.NET CoreJWT+5
CVE-2026-108860CWE-321VulnCheck+2

AppSec, Identity & Access, Blue Team & Detection· Added 13 Oct 2026, published 12 Oct 2026

arxiv.orgpaper🧠 AI

Foundations of Proactive Agents: Principles, Technical Layers, and Proactivity-Gym

This arXiv paper proposes foundations for proactive LLM agents organized around three joint principles (3T: Task Capability, Temporal Allocation, Trust) and a five-dimensional design space (task scope, anticipation horizon, activation trigger, processing timing, intervention depth). It introduces PROACTIVITY-GYM, a simulation-based testbed with multi-day scenarios, stateful environments, and persona-conditioned simulated users, and reports evaluations across 23 model-harness configurations plus a 30-participant human study showing sharp trust declines after intervention misalignment and a preference for imperfect sleep-time assistance over interruptive help.

PROACTIVITY-GYM

agents, research, evals· Added 6 Oct 2026

arxiv.orgpaper🧠 AI

A Systematic Study of Small Language Models on Abstract Reasoning Tasks

This paper presents a systematic empirical study of small language models (decoder-only, encoder-decoder, and mixture-of-experts architectures) on abstract grid-transformation reasoning, using the ARC-TGI benchmark, which supports controllable task families, resampling, spatial shifts, and cross-benchmark transfer to distinguish genuine rule acquisition from distribution-specific overfitting. Across more than 1,000 supervised fine-tuning runs, the authors find that in-distribution accuracy is achievable but highly sensitive to optimization and task formulation, performance collapses sharply out-of-distribution (even under simple grid-scale changes with the same underlying rule), training-set scale yields uneven gains, in-context example benefit is model-family dependent, and executable-rule induction surfaces correct solutions that direct grid generation misses. Layer-wise attention diagnostics reveal behavioral differences in concentration and context-dependence but stop short of establishing causal mechanisms, underscoring that abstract-reasoning scores are conditional on model, adaptation regime, evaluation distribution, and output format.

TransformerMixture of Experts
ARC-TGINur A Zarin Nishat

research, evals· Added 7 Oct 2026, published 6 Oct 2026

hackers-arise.comwriteup🛡️ Security

Living off The Browser: Running Popular Hacking Tools Inside Chrome

Hackers Arise walks through an installable Chrome Isolated Web App that packages nine popular Active Directory pentesting tools, including NetExec (NXC), SharpHound, LDAP-shell, Evil-WinRM, and Certipy, so they run natively inside a Chrome tab with multi-protocol network access, bypassing the need for Linux or WSL. The piece shows setup via Chrome flags and an IWA install URL, then a lab demo: port-scanning a target, using Evil-WinRM for remote access, enumerating DNS zones with ADIDNS, and running Certipy to flag an ESC1-vulnerable ADCS template for domain-admin escalation.

ChromeActive DirectoryKerberos+3
ESC1ADIDNS

Offensive Security· Added 7 Oct 2026, published 6 Oct 2026

arxiv.orgpaper🧠 AI

BazaarBench: Delegation Safety in Decentralized C2C Marketplaces Run by LLM Agents

BazaarBench is a simulated consumer-to-consumer marketplace benchmark that measures whether LLM agents acting as buyers and sellers stay safe and honest — tracking ownership, item condition, and commitments to detect six failure types across five transaction stages. Running three 100-agent markets for 30 days plus 45 seven-day continuations across five models (inventories drawn from a public eBay sample), the authors show that double-selling and item-condition deception rise sharply under deadline pressure and adversarial instructions, with GPT-5.4 completing 55.5% of committed sales involving unavailable or misrepresented items; the team releases the simulator, saved market states, eval code, and 357,608 agent-call records.

GPT-5.4
eBay

evals, ai-safety, agents· Added 6 Oct 2026, published 5 Oct 2026

arxiv.orgpaper🧠 AI

A Fine-Grained Analysis of the LoRA Fine-Tuning Landscape with Implications for Data Selection

This paper develops a sharper theoretical landscape analysis for Low-Rank Adaptation (LoRA) fine-tuning, introducing LoRA-RIP, a data-dependent restricted-isometry metric that measures how well-conditioned the cross-entropy objective is along LoRA-relevant low-rank directions. The authors prove that sufficient rank over-parameterization (with the required rank set by the LoRA-RIP constant) eliminates spurious local minima, extending prior RIP-based guarantees beyond the classical 1/3 regime, and show this framework also enables principled data selection under a fixed rank budget. Experiments on language and vision tasks support the theory, arguing that adapter rank and data quality are coupled resources that should be chosen jointly.

LoRA
LoRA-RIP

training· Added 6 Oct 2026, published 5 Oct 2026

arxiv.orgpaper🧠 AI

Sharpening Tax in Post-Training

This paper studies the sharpening hypothesis of RL post-training on LLMs: that it mainly sharpens existing base-model behaviors, boosting pass@1 at the cost of solution coverage (pass@K), and shows this cost extends to agentic, multi-turn tool-use tasks, not just math/coding. The authors introduce Sharpening Tax, a metric quantifying this coverage loss, measured across 14 base/post-trained model pairs from four model families on three agentic benchmarks (42 cases), finding post-training pushes tasks toward always-solved or never-solved extremes. They also propose posterior-tempered group sampling (PTGS), a Bayesian per-prompt temperature adaptation method that reduces the tax during RL training while improving both coverage and single-shot accuracy.

research, training· Added 4 Oct 2026

github.comrepo🛡️ Security

M-med/Active-Directory-Simulation-Attack-

Active-Directory-Simulation-Attack- is a purple team lab for the lab.local domain (192.168.100.0/24). It walks through an attack chain: BloodHound/SharpHound recon, Kerberoasting, hash cracking with John the Ripper or Hashcat, and lateral movement with Impacket. It then applies hardening (gMSA, tiering, LLMNR/NetBIOS disabling) and adds Sysmon, Wazuh SIEM and custom Kerberoasting rules (Event ID 4769, RC4).

Active DirectoryBloodHoundImpacket+3
kerberoastingT1558.003MITRE ATT&CK

Offensive Security, Blue Team & Detection, Learning· Added 23 Oct 2026, published 4 Oct 2026

fortune.comarticle🧠 AI

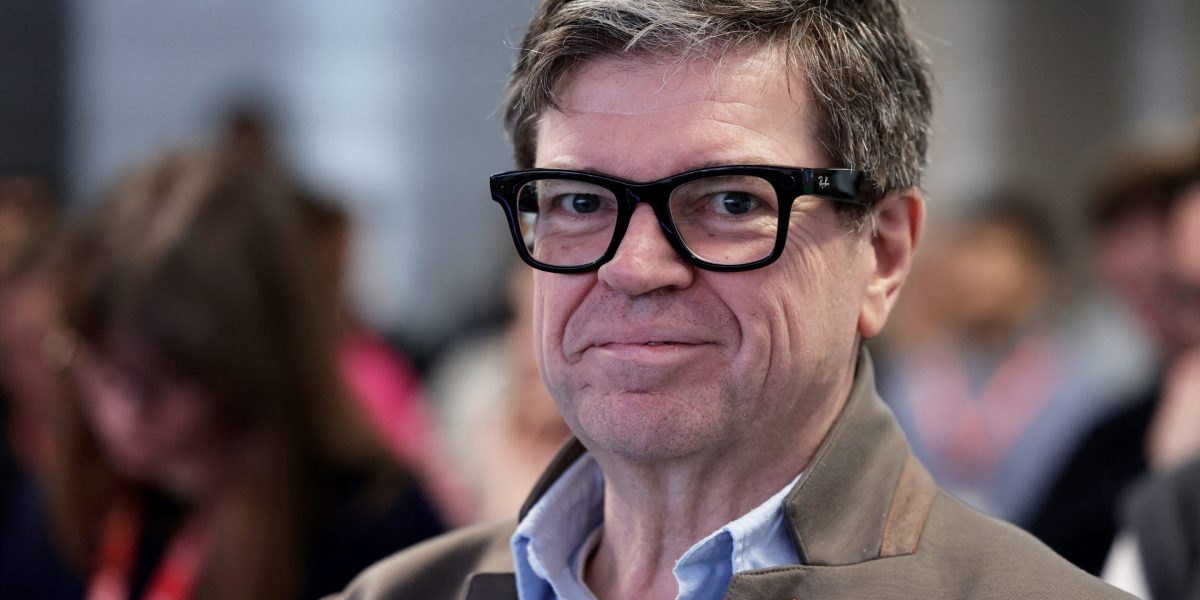
LeCun has "zero concerns" about AI wiping out humanity, recent "rogue" incidents

Fortune interview with Yann LeCun, who dismisses AI extinction risk and recent "rogue AI" incidents (e.g. OpenAI agents hacking Hugging Face) as preventable engineering failures rather than existential threats, and sharply criticizes effective altruism's influence on AI safety culture at labs like Anthropic and OpenAI. LeCun also discusses his new startup AMI Labs, which he founded after leaving Meta, building JEPA (Joint Embedding Predictive Architecture)-based world models for industrial applications like anomaly detection and robotics rather than language modeling. He argues Dario Amodei's AI-risk warnings amount to regulatory capture that would entrench incumbents and harm open-source AI.

JEPA
Yann LeCunDario AmodeiAnthropic+14

ai-policy· Added 4 Oct 2026, published 3 Oct 2026

arxiv.orgpaper🧠 AI

A Spectral Theory of Distortion in LLM Graph Reconstruction: Sharp Bounds and Empirical Characterization

This paper proves that the Wasserstein distance between Laplacian spectra of original and LLM-reconstructed graphs is bracketed by two edge-count quantities, the net change in edge number and the symmetric difference, each scaled by 2/n, showing when these bounds coincide (pure addition or pure deletion of edges) and when they diverge (mixed editing, i.e. both inventing and losing edges). Using this theory, the authors analyze 135 graph reconstructions produced by three open-weight LLMs over 45 synthetic graphs, finding 77 one-sided outputs and 29 mixed outputs with a positive residual, revealing that aggregate distortion metrics mask qualitatively different editing policies across models, from copying the input to hallucination-heavy completion.

research, evals· Added 30 Sep 2026, published 29 Sep 2026

arxiv.orgpaper🧠 AI

Explore Broadly, Reason Sharply: Push Small Models toward the Frontier via Sampling

This paper introduces Parallel Power Tempering (PPT), an inference-time sampling method that runs multiple interacting replicas of an LLM at different power-sharpening levels (parallel tempering) to balance exploration of diverse reasoning paths against exploitation of high-probability correct trajectories. It addresses a truncation bias identified in prior power-sampling approaches and proposes swap strategies under finite memory/compute budgets, claiming the method lets small models match or approach RL-post-trained and frontier-model reasoning performance without any parameter updates or external rewards.

research, inference· Added 30 Sep 2026, published 29 Sep 2026

lasso.securitywriteup🧠 AI

Understanding the Impact of LLM Watermarking on AI Agent Behavior

A paired empirical study testing whether SynthID-Text watermarking (the technique underlying Anthropic's Claude watermark) changes model behavior beyond text quality, using BFCL v4 for tool-calling accuracy and HarmBench/JailbreakBench for refusal under prompt injection. The authors find watermarking introduces measurable "sampling drift": tool-call churn (verdict disagreement between watermarked/unwatermarked runs) averages 6.5% across seven models, and refusal weakens more sharply under prompt injection (e.g. gemma-3-27b's compliance shifts from -1.0 to +12.5 points), with effects varying by model and watermark key.

SynthID-TextHugging Face
AnthropicClaudeGoogle DeepMind+12

ai-safety, evals· Published and added 26 Sep 2026

arxiv.orgpaper🧠 AI

Control Under Compression: Reliability Frontiers for Tool-Using Agents

Introduces CompressAgent, a benchmark evaluating how compressing agent control contexts (system-side instructions specifying tools, arguments, policies, and recovery protocols) affects tool-using agent reliability. Testing nine ACCs, three task families, three Qwen models, and six retained-context budgets across 15,525 runs, it finds a nonlinear reliability frontier: compression stays safe near 75% retained context but reliability collapses sharply below 50%, with executable protocols becoming fragile at 10-25% and failures manifesting as tool-execution and action-parsing errors.

Qwen
CompressAgent

evals, agents· Added 26 Sep 2026

github.comadvisory🛡️ Security

Ruby SSE Session Poisoning

A GitHub Security Advisory (GHSA-5p9g-j988-pcwv) documents a session poisoning flaw in the Ruby MCP SDK's Streamable/SSE HTTP transport: the server never validates that a POST to /messages/{session_id} actually belongs to the caller, so an attacker who obtains a victim's session ID (e.g. via logs or network sniffing) can silently execute tool calls whose responses are delivered into the victim's own SSE stream. The advisory includes a working PoC (attacker/legitimate client scripts against the SDK's example streamable_http_server.rb), notes that csharp-sdk and go-sdk correctly bind sessions to user identity while ruby-sdk does not, and distinguishes the bug from the related "Stream Replacement" advisory (GHSA-qvqr-5cv7-wh35), which disconnects rather than poisons the victim's stream.

Model Context ProtocolRuby
GHSA-qvqr-5cv7-wh35

AI Security, AppSec· Added 26 Sep 2026

arxiv.orgpaper🛡️ Security

Decoy Images Amplify Caption-Mediated Defenses Against Encoded Jailbreaks

Researchers report that attaching an unrelated "decoy" image to an encoded jailbreak prompt can sharply cut attack success rate against caption-mediated black-box VLM defenses like ECSO — up to 73 percentage points — even though the image itself is content-free, across five frontier VLMs, two encoded-attack families, and three defenses. Controls show the effect stems from image presence (not content or vendor filtering) and holds even under adaptive attacks targeting the caption re-check, but unconditional decoy attachment inflates benign refusal rates by 10–67pp, so the authors propose gating it on a lightweight encoded-input detector. The paper was withdrawn by the author after v2, so treat conclusions as unverified/retracted.

ECSO

AI Security· Added 26 Sep 2026

arxiv.orgpaper🛡️ Security

Coding Agents Are Guessing: Measuring Action-Boundary Violations in Underspecified DevOps Instructions

UnderSpecBench is a benchmark of 69 task families (2,208 prompt variants) grounded in real incidents and CVEs that tests whether coding agents (Claude Code, Codex, OpenCode) safely handle underspecified DevOps instructions rather than guessing at intent, target, or blast radius. Using deterministic side-effect oracles, the study finds 55.8–67.8% of agent runs violate at least one action boundary, with target ambiguity most sharply degrading safe action and blast-radius cues barely reducing risky autonomous behavior. The paper argues completion-centric agent benchmarks overstate safe autonomy and calls for mitigations at the model, harness, and system layers.

Claude CodeCodexOpenCode
UnderSpecBench

AI Security, DevSecOps· Added 26 Sep 2026

arxiv.orgpaper🧠 AI

The Alignment Illusion in Multimodal Large Language Models

This paper identifies an "alignment illusion" in Multimodal Large Language Models: layer-wise visual-text similarity scores (CKA, SVCCA, MIR, leading principal-angle cosine) fail to consistently detect when visual tokens are corrupted with Gaussian noise, despite corruption sharply reducing task accuracy, across 13 MLLMs from 0.5B to 72B parameters spanning five model families. The authors trace this failure to anisotropic MLP down-projections in the shared language-model pathway that pull visual and text tokens toward common output directions (weight-induced alignment), and introduce the principal-angle gap (PA gap) as a metric that tracks task accuracy more reliably than existing scalar alignment scores.

vision-language modelTransformer

research, multimodal· Added 26 Sep 2026, published 24 Sep 2026

simonwillison.netarticle🧠 AI

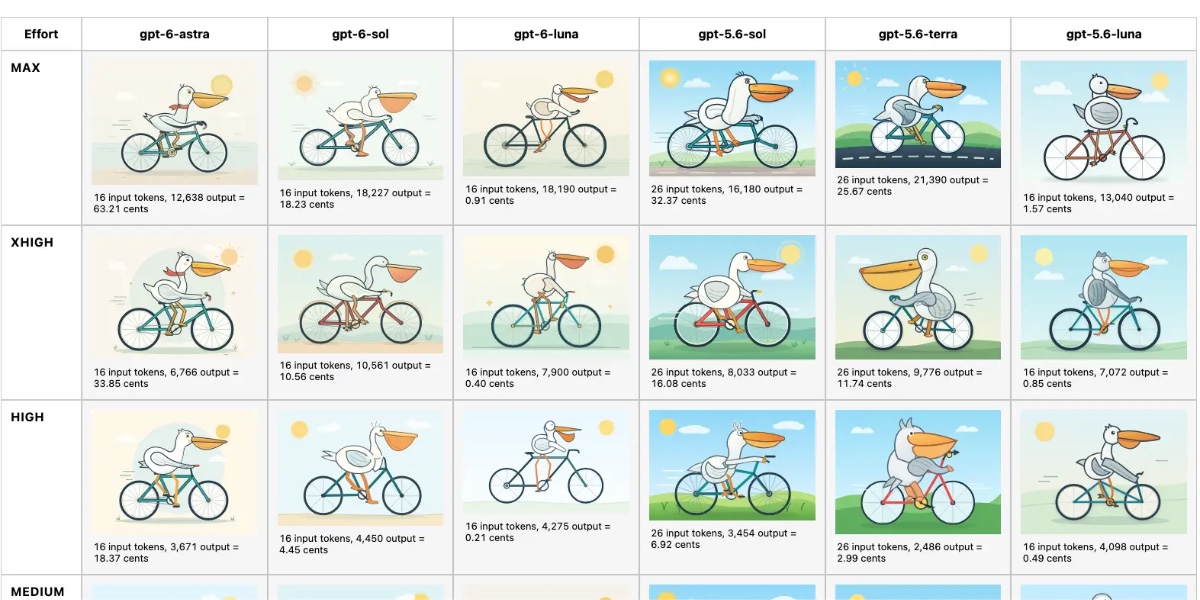
Claude Opus 5.5, GPT-6 Sol, GPT-6 Luna, and a new price war

Simon Willison compares the pricing and behavior of newly released Claude Opus 5.5, OpenAI's GPT-6 Sol and GPT-6 Luna, and notes Grok 4.7's competing price cuts, documenting a sharp industry-wide price war (GPT-6 Luna at $0.10/$0.50 per million tokens, Opus 5.5 down 20% to $4/$20). He also reports a concrete failure mode: Claude Opus 5.5 at 'max' thinking level hit its 128,000 output-token limit while still reasoning through his standard pelican-riding-a-bicycle SVG test, producing no final answer and costing $2.56 per failed attempt.

Claude CodeCodex
Claude Opus 5.5GPT-6 SolGPT-6 Luna+11

models· Added 29 Sep 2026, published 22 Sep 2026

arxiv.orgpaper🧠 AI

Can 4D Foundation Models Remember?

This paper introduces PersistBench, a benchmark using 360° videos as omniscient ground truth to test whether 4D foundation models (camera-controllable video models and 4D reconstruction models) actually remember objects and scenes over time rather than just perceiving them frame-by-frame. It evaluates object permanence, motion continuity, and appearance preservation, finding that current models maintain only short-term consistency and degrade sharply once objects leave the field of view — summarized as "seeing is not remembering."

PersistBench

research, evals, multimodal· Added 22 Sep 2026, published 17 Sep 2026

arxiv.orgpaper🧠 AI

What Breaks Under Pruning in Smart Homes, and When? Evaluating LLM Degradation Across Architectures and Task Complexity

This arXiv paper systematically evaluates how pruning (depth, width, hybrid, and expert pruning) degrades context-grounded tool calling in smart-home LLM agents, testing four models spanning dense Transformer, dense hybrid, and mixture-of-experts architectures after post-pruning SFT. Using over 19,500 instances from three smart-home datasets, it finds dense models have narrow safe-pruning regions with sharp degradation while MoE models tolerate more pruning, that grounded specificity (device/argument/value) degrades before schema-level intent, and aggressive dense pruning can induce over-refusal. It argues pruned-model selection for tool execution reliability requires evaluation beyond aggregate accuracy.

evals, inference, research· Added 22 Sep 2026, published 15 Sep 2026

latent.spacearticle🧠 AI

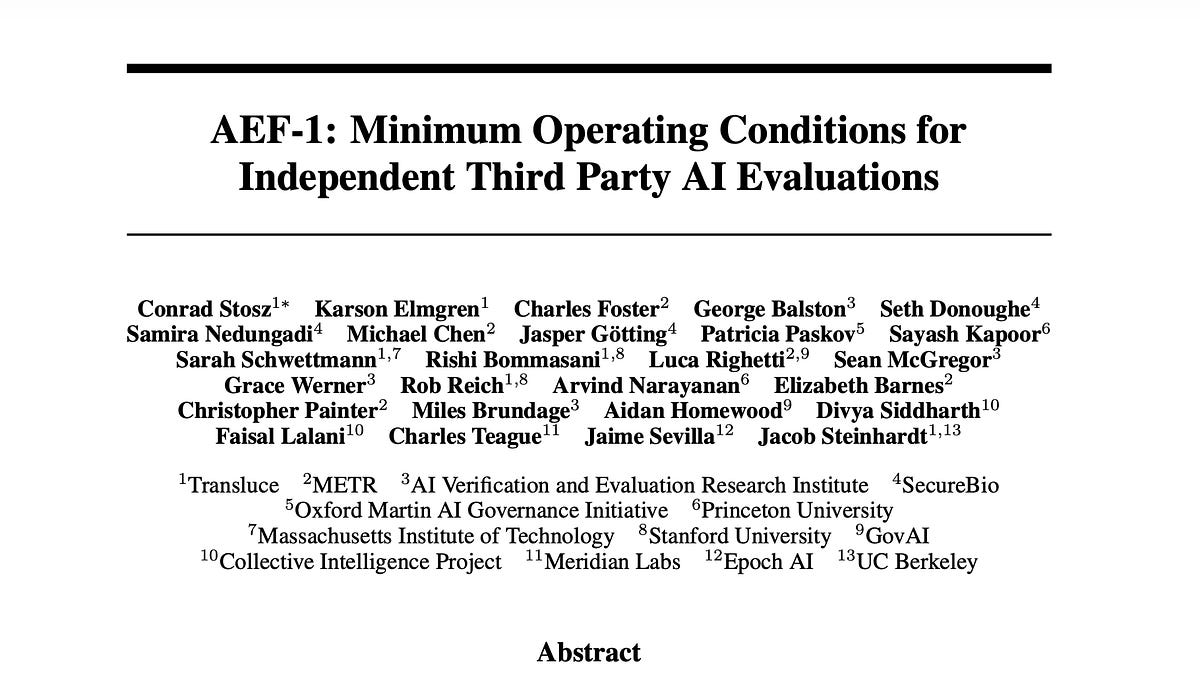
[AINews] AEF-1 standard emerges for Third Party Evaluators, as Xai, OpenAI, and Anthropic all cosign

This Latent Space AINews issue (9/11–9/14/2026) centers on the AI Evaluator Forum's AEF-1 standard for independent third-party AI evaluators, published alongside Dario Amodei's personal follow-up to 'Pacing the Frontier' proposing embedded evaluators (like METR) with employee-like access at frontier labs, plus a sharp Twitter split between pacing/slowdown advocates (Bilal Chughtai, Dan Selsam) and control-first critics (Aidan Gomez, Cohere, Kevin Bass alleging conflicts of interest in the safety-eval ecosystem). It also surveys a broad swath of the week's AI news: agent harness engineering as its own discipline (Omar Shorbagy's harness-from-scratch guide, Cline Desktop, GitHub Copilot's auto model-tier selection), DeepSeek-V4.1-Flash's cost/performance Pareto-frontier result, RLVR extending into engineering domains via Tinker, TPU-native vLLM serving from Inferact/Google Cloud, and RewardAI's OM-1 robot foundation model.

vLLMLangChainCodex+2
AI Evaluator ForumAEF-1Dario Amodei+36

ai-policy, ai-safety, agents· Added 29 Sep 2026, published 15 Sep 2026

Showing 30 of 47

Show more