 Lewis - Policifyai (@Policifyai) on X
Policifyai's October 2026 roundup lists model releases by date with prices and benchmark scores: GPT-6.1 Sol and Terra, Claude Sonnet 5.5 and Haiku 5.5, Gemini 4 Argon and Carbon, Muse Spark Open, Mistral Large 4 weights and Kimi K3.1 Pro. It also covers Anthropic's S-1 compute commitments, Artificial Analysis Intelligence Index v5, and chip and data-center deals.
 x.comarticleAdded 1 Nov 2026, published 31 Oct 2026🧠 AI
 [AINews] Google admits AI Mode hurts Search revenue; -15% $500B drop worst since 2004 IPO. AI Bear Market coming?
AINews issue for 29 to 30 October 2026 from Latent Space. It opens on Google's admission that AI Mode monetises worse than classic Search, which preceded a roughly 15% share drop. It then recaps Claude Ultra dropping the 5-hour limit, Gemini 4 Carbon, Mistral Large 4, Nemotron 3.5, Artificial Analysis Index v5, Unsloth GGUF disputes, and the Anthropic S-1 filing.
 latent.spacearticlePublished and added 31 Oct 2026🧠 AI
- Artificial Analysis (@ArtificialAnlys) on X
Hyperflow H3 is Video Rebirth's 8-step LoRA for MiniMax H3, released in September 2026 with open weights. Artificial Analysis ranks it #5 on AA-Video-I2V v2.1 and #3 on AA-Video-Editing v1.1, ahead of MiniMax H3 (768p). It costs $9.00 per minute for Image to Video and $18.00 for Video Editing at 1088p, under half of Dreamina Seedance 2.5 ($34.12 and $40.82). The thread gives per-capability and per-use-case breakdowns.
x.comthreadAdded 31 Oct 2026, published 30 Oct 2026🧠 AI  [AINews] Building AIE CODE: The top Coding Agent Conference
AINews issue for 28 to 29 October 2026 from Latent Space. It opens with a preview of the AIE CODE summit (themes: Scaling without Slop, System One models, Increasing Ambition, with Jarred Sumner on Bun in Rust). It then recaps Twitter and Reddit news: Mistral Large 4 open weights (1.05T total, 52B active), Artificial Analysis benchmarks, Gemini 4 Carbon, Qwen4 rumours, Claude Code quota complaints and OpenAI frontier-run monitoring. Text was cut before the end.
latent.spacearticlePublished and added 30 Oct 2026🧠 AI- Artificial Analysis (@ArtificialAnlys) on X
Artificial Analysis launched an HLE-Diamond leaderboard in v5 of its Intelligence Index, covering the refined 1,000-question Humanity's Last Exam from CAIS and Scale AI. Each question runs once without tools, graded by GPT-5.6 Luna (medium) as pass@1. Gemini 4 Carbon (high) leads at 69%, Claude Opus 5.5 (max) scores 68%, and the top open weights model, Kimi K3.1 Pro, reaches 37%.
x.comthreadPublished and added 30 Oct 2026🧠 AI  Gemini 4 Carbon is the new #1 on the Artificial Analysis Intelligence Index v5
Gemini 4 Carbon scores 59 on Artificial Analysis Intelligence Index v5 (published 28 October 2026), the top score, with #1 on 4 of 9 evaluations including HLE-Diamond and AA-Omniscience. On the Coding Agent Index it scores 59 with Antigravity CLI, 3 points behind Claude Code with Claude Opus 5.5 (62). Cost is $7.76 per task, versus $10.04 for Opus 5.5. Rollout is limited to selected users.
 artificialanalysis.aiarticleAdded 30 Oct 2026, published 29 Oct 2026🧠 AI
 [AINews] Gemini 4 Carbon tops leaderboards, launches for cyber defenders
AINews issue for 27-28 October 2026, a Latent Space digest of Twitter and Reddit. It leads with Google DeepMind's Gemini 4 Carbon: claimed cyber scores (SEC-bench Pro 88.2%, ExploitGym 54.8%, CWE-bench 71.0%), #1 on Artificial Analysis Intelligence Index v5 at 59, and access limited to cyber defenders through the Fairwind Program. It also covers benchmark integrity disputes, GitHub Copilot Fusion, H-Net v2, KV-cache work, open-weight releases and Claude Code quota complaints.
latent.spacearticlePublished and added 29 Oct 2026🧠 AI Welcome Le Chonk: Mistral Large 4 on Hugging Face
Mistral Large 4 (Le Chonk) is a multimodal, multilingual Mixture-of-Experts model with about 1T total and 49B active parameters and a 1M-token context, released under the Mistral Ecosystem Open-Weight License. The post covers its MLA and DeepSeek Sparse Attention architecture, a 1.6B Pixtral encoder, and benchmarks including 82% on the Artificial Analysis Cyber Index and 93% on Cybench. It gives run recipes for transformers, vLLM, llama.cpp, TRL fine-tuning and Inference Endpoints.
 huggingface.coarticlePublished and added 29 Oct 2026🧠 AI
- Laban (@lunkertw) on X
An X post summarising five AI items: Google DeepMind's Gemini 4 Carbon (88.2% SEC-bench Pro, 54.8% ExploitGym, 71.0% CWE-bench, 59 on Artificial Analysis Intelligence Index v5.0), Ed Zitron's critique of Anthropic's S-1, a Utah Claude Code pilot, and the repos beenuar/AiSOC and expo/skills. In the Utah pilot, 34 developers in 10 agencies took part over four weeks, 80% had a working setup within 30 minutes, and 71% saved over 20 hours. It gives short summaries and links, not primary analysis.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026🧠 AI - Niko (@nikolayxyz) on X
Gemini 4 Carbon is Google's new frontier model, announced in a post by nikolayxyz that quotes Google's launch text. It ranks #1 on v5.0 of the Artificial Analysis Intelligence Index with 59 points, ahead of Opus 5.5 and GPT-6 Astra. Intro pricing is $2 input and $10 output per million tokens. Access starts for cyber defenders first, as Gemini 4 Argon's did. The captured text is cut off before the rollout details.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026🧠 AI - 🚨 AI News | TestingCatalog (@testingcatalog) on X
Gemini 4 Carbon is a new Google model, announced in a TestingCatalog post on X as taking first place on the Artificial Analysis V5 ranking. It is rolling out to cyber defenders first. Reported scores are 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching). The post calls it a large step up from Gemini 4 Argon, released two weeks earlier. It gives no technical detail beyond these claims.
x.comthreadAdded 30 Oct 2026, published 28 Oct 2026🧠 AI  Gemini 4 Carbon
 is Google's frontier model, announced two weeks after Gemini 4 Argon. It scores 59 on Artificial Analysis Intelligence Index v5.0, 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Pricing is $2 per million input and $10 per million output tokens. Access starts with a subset of cyber defenders through the Fairwind Program.
 blog.googlearticleAdded 29 Oct 2026, published 28 Oct 2026🧠 AI
- Gemini 4 Carbon: Our next frontier model
Gemini 4 Carbon is Google DeepMind's new frontier model, announced two weeks after Gemini 4 Argon. It ranks #1 on Artificial Analysis Intelligence Index v5.0 at 59 and scores 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Access starts with cyber defenders through the Fairwind Program, priced at $2 per million input tokens and $10 per million output tokens.
 deepmind.googlearticlePublished and added 28 Oct 2026🧠 AI
- Artificial Analysis v5 and the benchmarker's dilemma
Artificial Analysis v5 and the benchmarker's dilemma is an Interconnects post that reviews the AI benchmarking industry, using the Artificial Analysis v5 release as its starting point. Its subtitle says it covers what the benchmarking industry is missing. Only the subtitle was available, so the specific arguments, benchmarks and index changes are not known.
 interconnects.aiarticlePublished and added 28 Oct 2026🧠 AI
 [AINews] Anthropic ends Coding Interviews: "Hunger beats tenure"
AINews issue of 28 October 2026 from Latent Space. It leads with Felix Rieseberg's post on why Anthropic dropped coding interviews ("Hunger beats tenure"). It then recaps Genie 4, Axiom's Lean formalization of CFSG, claimed ETH refutations by OpenAI and Anthropic, Artificial Analysis Index v5, FrontierCode 2.0, Liquid LFM3, the Qwen3.8 phone-home dispute, and Anthropic's S-1. Reddit recaps are included; the page was truncated before the end.
latent.spacearticlePublished and added 28 Oct 2026🧠 AI- Muzammil Shah (@Muzammil_OX) on X
Kimi K3.1 Pro is a new model from Moonshot AI that scores 55 on the Artificial Analysis Intelligence Index, up 11 points from its predecessor, and ranks 4th overall. It has a 1M-token context window and API pricing of $2 per million input tokens and $10 per million output tokens. Weights are due by November 4. Moonshot removed cyber-related training data, which cut its internal vulnerability research score from 90.5% to 81%.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026🧠 AI  Podcast: Kimi K3.1 Pro, the new cyber reality, and Muse musings
Interconnects podcast episode in which Nathan Lambert and Florian Brand discuss the Kimi K3.1 Pro release (about 3 trillion parameters, weights due by November 4th). They cover its Artificial Analysis score against weaker long-horizon results, Moonshot's choice to down-weight offensive cyber capability, and the PHP2Shell and LiteLLM incidents. They also cover abliterated model APIs, trusted-access cyber programs, Anthropic's junior hiring and Florian's use of the Muse agent.
interconnects.aitalkPublished and added 25 Oct 2026🧠 AI [AINews] Kimi 3.1 Pro 104BA-2.8T: Fable-5.1-Class Open Weights narrows Closed-AI lead to 1 month... and Pro Highspeed API with 2-3× speed
AINews digest for 22 to 23 October 2026, led by Moonshot's Kimi K3.1 Pro (2.8T parameters, 104B active, weights promised for 4 November 2026). It reports Artificial Analysis scoring the model 64% on its Cyber Index despite Moonshot removing cyber data from training. Other items: OpenAI's frontier-training containment incident, a Brotli remote-code-execution disclosure, and Anthropic's Mythos 5 unauthorized-action analysis.
latent.spacearticleAdded 30 Oct 2026, published 24 Oct 2026🛡️ Security [AINews] Kimi 3.1 Pro 104BA-2.8T: Fable-5.1-Class Open Weights narrows Closed-AI lead to 1 month... and Pro Highspeed API with 2-3× speed
AINews issue for 22 to 23 October 2026 centred on Moonshot's Kimi K3.1 Pro, a multimodal mixture-of-experts model with 2.8T total and 104B active parameters and 1M context. Weights are promised for 4 November 2026. Artificial Analysis scored it 55 on its Intelligence Index (fourth place), and Arena ranked it #8 in WebDev. Standard pricing is $2/$10 per million tokens. The issue also covers a cyber-data removal approach, serving-cost objections, and paid-promotion allegations. Shorter items follow on agents, evals and inference.
latent.spacearticlePublished and added 24 Oct 2026🧠 AI Hajrë Hyseni | AI for Business (@hajra) on X
Kimi K3.1 Pro is a new model from Moonshot AI. According to a post by hajra, Artificial Analysis ranks it 4th in the world, 3 points behind Claude Opus 5.5. The API price is down by a third, and full open weights are promised by 4 November. The post gives no benchmark breakdown, licence or architecture details.
x.comthreadPublished and added 24 Oct 2026🧠 AI Introducing Kimi K3.1 Pro
Kimi K3.1 Pro is Moonshot AI's new model, available on the Kimi API from 23 October 2026, with full weights promised by 4 November 2026. Pricing is $2.00 per million input tokens and $10 per million output, and a Highspeed variant is 2-3x faster at twice the price. Artificial Analysis scores it 55, behind only Claude Opus 5.5 (58). Simon Willison tested it with the llm CLI and pelican SVG prompts.
 simonwillison.netarticlePublished and added 23 Oct 2026🧠 AI
 [AINews] Black October
AINews issue for 21-22 October 2026, built from 12 subreddits and 544 Twitter accounts. It leads with "Black October", a 48-hour run of AI-found vulnerability disclosures (PHP2Shell, a GitLab CVSS 10 flaw, a LiteLLM 1.107.0 password stealer, eMudhra CA keys). It also covers MiniMax M3.1 Flash, Carbon-X and Flint releases, Artificial Analysis coding-agent and CritPt v2 results, and a METR/Redwood audit of OpenAI monitoring.
latent.spacearticlePublished and added 23 Oct 2026🧠 AI brenz. (@brenzhills) on X
Krea 3 is an image generation and editing model from Krea. A post on X says its "Fast" variant scores 1125 Elo on the Artificial Analysis image editing leaderboard, against 1124 for Google's Nano Banana 2, while producing 10 images in the time Google produces 2. It also says the "Ultra" variant ranks in the top 4, behind only OpenAI models. The post gives no methodology or model details.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026🧠 AI- DeepSeek V4.1 Flash 1017 (Max)
DeepSeek V4.1 Flash 1017 (Max) is an open-weights reasoning MoE model from DeepSeek with 552B total and 16B active parameters, a 1M-token context window, text and image input, and an MIT license. Artificial Analysis scores it 45 on its Intelligence Index (open-weights median 19), at $0.30 input and $1.20 output per 1M tokens, 216 tokens per second, and 210M tokens used in the evaluation. It is available through 10 API providers.
artificialanalysis.aiotherAdded 20 Oct 2026, published 19 Oct 2026🧠 AI  [AINews] High Taste Testers Ep. 1
AINews issue for 15-16 October 2026, from Latent Space, summarising 12 subreddits and 544 Twitter accounts. It covers Meta's Muse Spark Open (816B MoE) and Reflection Beam 1.0 with Artificial Analysis scores and pricing. It also covers Gemini 4 Argon, decision models, TPUv7 and Vera Rubin serving benchmarks, interpretability claims, agent papers, and China's proposed open-source export rules.
latent.spacearticleAdded 30 Oct 2026, published 17 Oct 2026🧠 AI Show HN: Gemini 4 Argon plays StarCraft
StarSkirmish Bench v0.2 gives each LLM one hour to write a Protoss StarCraft: Brood War bot in C++ (BWAPI 4.4.0 on OpenBW), with tools to compile and play practice games. Scores are average win rates of 5 runs against 13 roster bots, which include human-written bots such as Stardust, PurpleWave and BananaBrain. Nine models are compared, each in its lab's first-party CLI harness (Claude Code, Codex, Antigravity CLI, Muse Code). GPT-6 Astra leads and wins only 7% against the top human bots. The page also covers score against cost, run-to-run variance, practice behaviour as the best predictor of score, and weak correlation with the Artificial Analysis Intelligence Index and Terminal-Bench 4.0.
 starskirmish.comarticleAdded 17 Oct 2026, published 16 Oct 2026🧠 AI
 [AINews] Agents disprove Polysemanticity; greatly improve Interpretability & Alignment
The 10/14–10/15/2026 AINews issue. Its lead story is Goodfire's Nick Cammarata essay "Neural Networks Are Already Clean", which argues agentic analysis resolves many known cases of polysemanticity and superposition. Neel Nanda, Leo Gao and Jake Mendel push back. It also covers Meta's Muse Spark Open (816B total / 42B active MoE, 1M context, custom license, Artificial Analysis index 39, vLLM day-0 support and quantizations), Nemotron 3.5, MAI-Base-2 and Gemini 4 Argon evals. Further items cover Vals' refund-agent and MiMo task-leakage findings, TPUv7 and Vera Rubin inference benchmarks, Perplexity's SPACE sandbox, RL training systems (TRL tree packing, bitwise-consistent vLLM RL) and Sakana's Agentic Scientist.
latent.spacearticlePublished and added 16 Oct 2026🧠 AI- Harrison Kinsley (@Sentdex) on X
Sentdex reacts to Artificial Analysis ranking NVIDIA's Nemotron 3.5 Super VL (120B total, 12B active MoE) as the top US open-weights model, scoring 26 on the Intelligence Index. That edges out Thinking Machines' Inkling Small (26), NVIDIA's Nemotron 3 Ultra (23) and Meta's Muse Glimmer (17). Sentdex's informal tests at vanilla settings show over 550 tok/sec, and they suspect it would rank higher on agentic coding. They see it as a candidate for a fast local coding agent model.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026🧠 AI - [AINews] AI Engineer NYC: Gemini 4 Argon, Vals AI Benchmarks
AINews issue for 10/12–10/13/2026 covering the GA of Google's Gemini 4 Argon (pricing, Cursor/Devin/Copilot availability, CursorBench 52.8%, Artificial Analysis Intelligence Index parity with GPT-6 Astra at lower cost) and Meta's Muse Wonder, with independent evals and reliability caveats. It also summarises decision-model benchmarks (AA Decision Index, Jev 1.13, Nimble-v4), Fish Audio's open-weight Drama 3 TTS, agent-harness and agentic-RL research (Evo2, ReHarness, LongHarness, ThunderSync), Anthropic's move off Git, and safety items such as Argon's monitor evasion. It also notes AI Engineer NYC keynotes on AI x Finance. Useful as a curated, caveat-aware snapshot of the frontier-model landscape.
latent.spacearticlePublished and added 14 Oct 2026🧠 AI 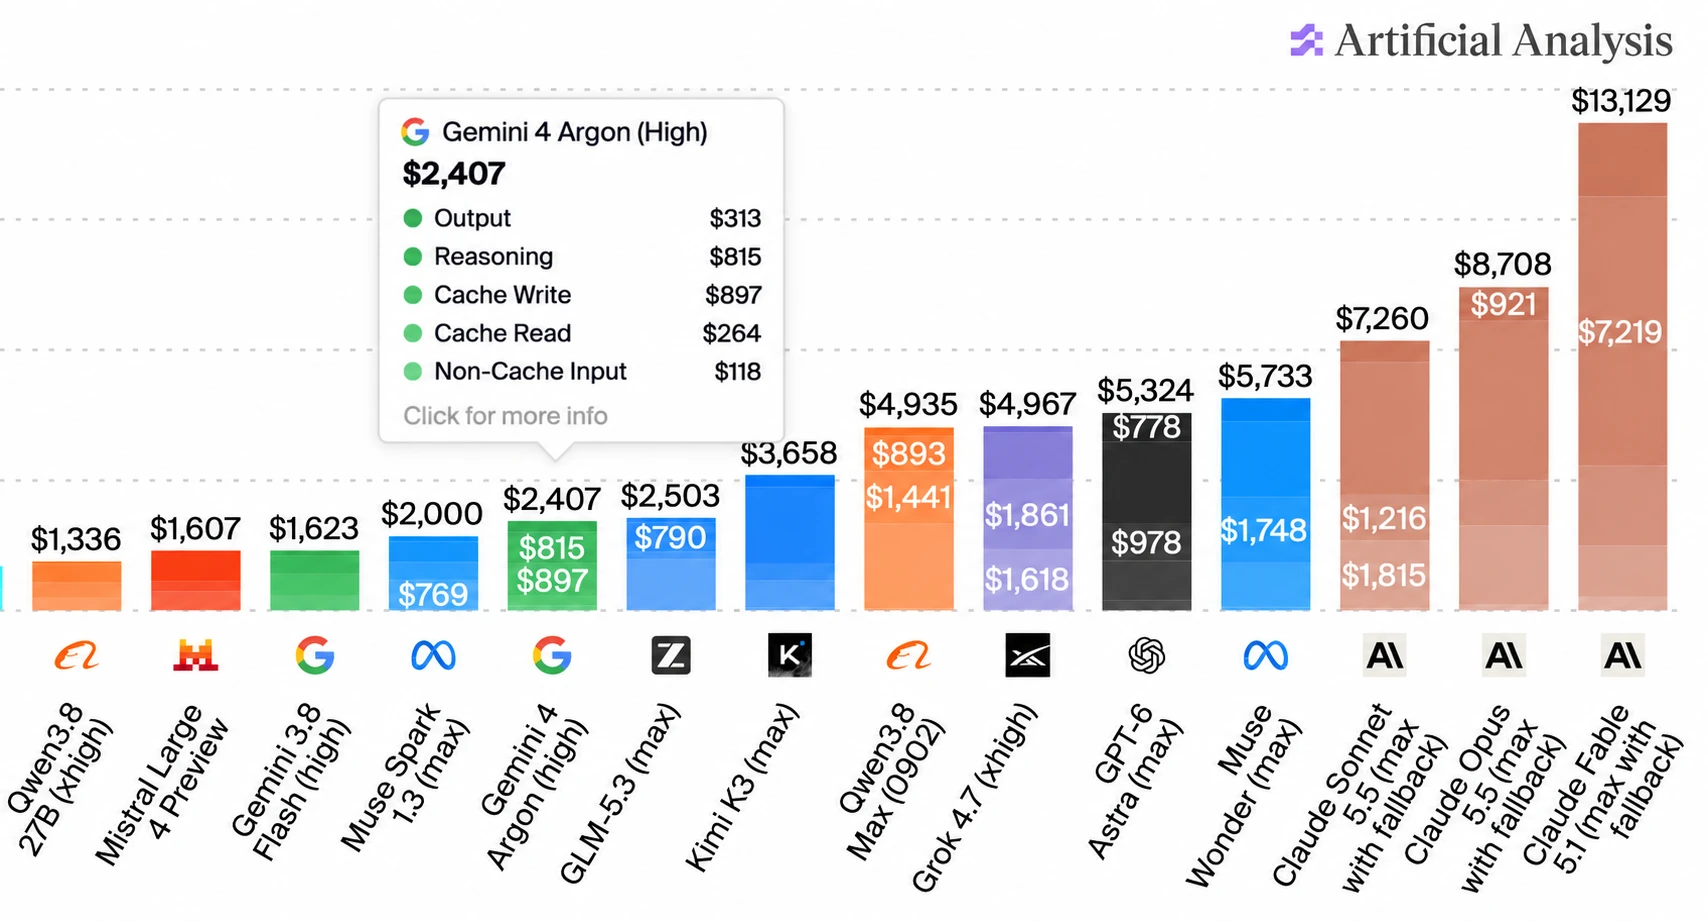 llm-gemini 0.35
Simon Willison releases llm-gemini 0.35 with support for Google's new Gemini 4 Argon model, available via the Gemini API and a $100/month subscription plan. He compares pricing: $2/M input and $10/M output at launch, doubling on December 1st to match Claude Opus 5.5. He argues per-token prices are poor comparators and points to Artificial Analysis's total benchmark run cost ($2,407 for Argon, near GLM-5.3 and cheaper than OpenAI, Anthropic and Meta models) as a better clue to agentic cost-efficiency. He also shows his SVG pelican outputs at low, medium and high settings.
simonwillison.netarticlePublished and added 13 Oct 2026🧠 AI




Showing 30 of 54
Show more