 news.fiu.eduarticle
FIU researchers reveal how altered images can bypass AI safeguards
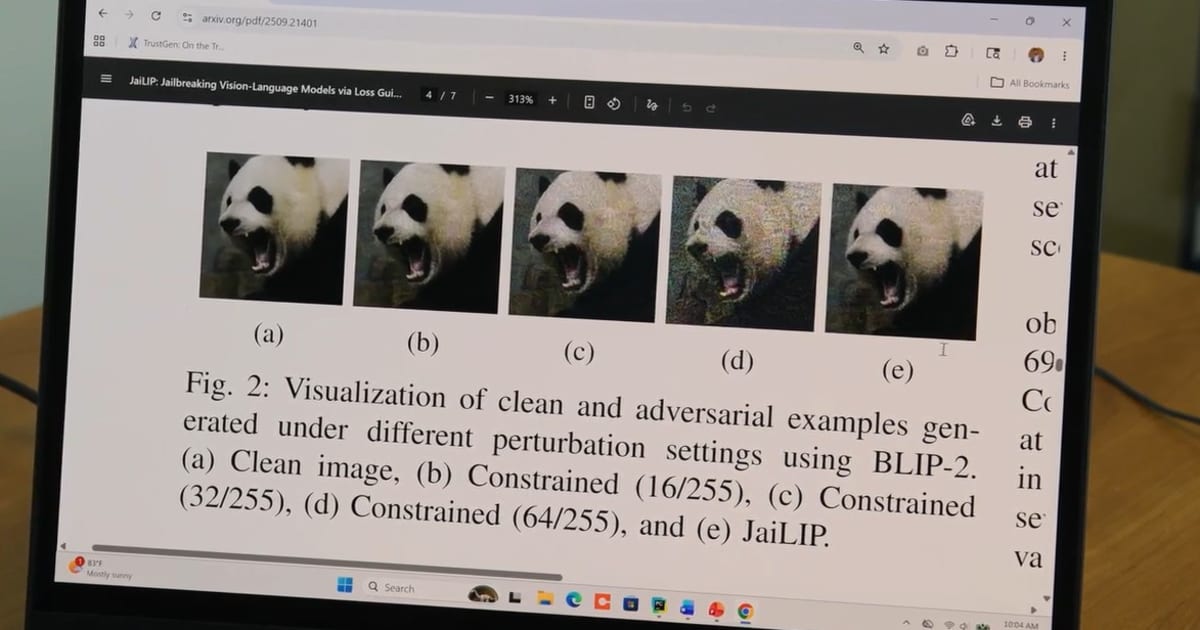
FIU researchers Hadi Amini and Md Jueal Mia developed JaiLIP (Jailbreaking with Loss-guided Image Perturbation), a technique applying optimized pixel-level perturbations to images to bypass safety guardrails in multimodal AI models. Tested against BLIP-2, JaiLIP-altered images nearly doubled the rate of harmful or unsafe responses generated by the model, including a manipulated stoplight image that tricked the system into giving instructions for running a red light undetected. The work, presented at ICMLA 2025, targets small-language models commonly used by small businesses for tasks like customer service and accounting, and is framed as red-teaming to inform future defenses.
Organisations named here
- Hadi Amini
- ICMLA 2025
- Md Jueal Mia
Technologies named here
- JaiLIP
- BLIP-2
- Small-language AI models
Techniques named here
- Image-based AI jailbreaking via pixel-level perturbation
- Adversarial red-teaming / vulnerability probing
Related in AI Security

 blog.talosintelligence.comtool
Introducing CAIRN: Frontier tracking for AI-integrated malware (Cisco Talos)
 github.comadvisory
Flowise MCP Security Bypass Enables RCE
github.comrepoYesWeHack Claude Kit

 jfrog.comarticle