 depthfirst.comarticle
Introducing dfs-large1: A New Frontier for Cybersecurity | depthfirst
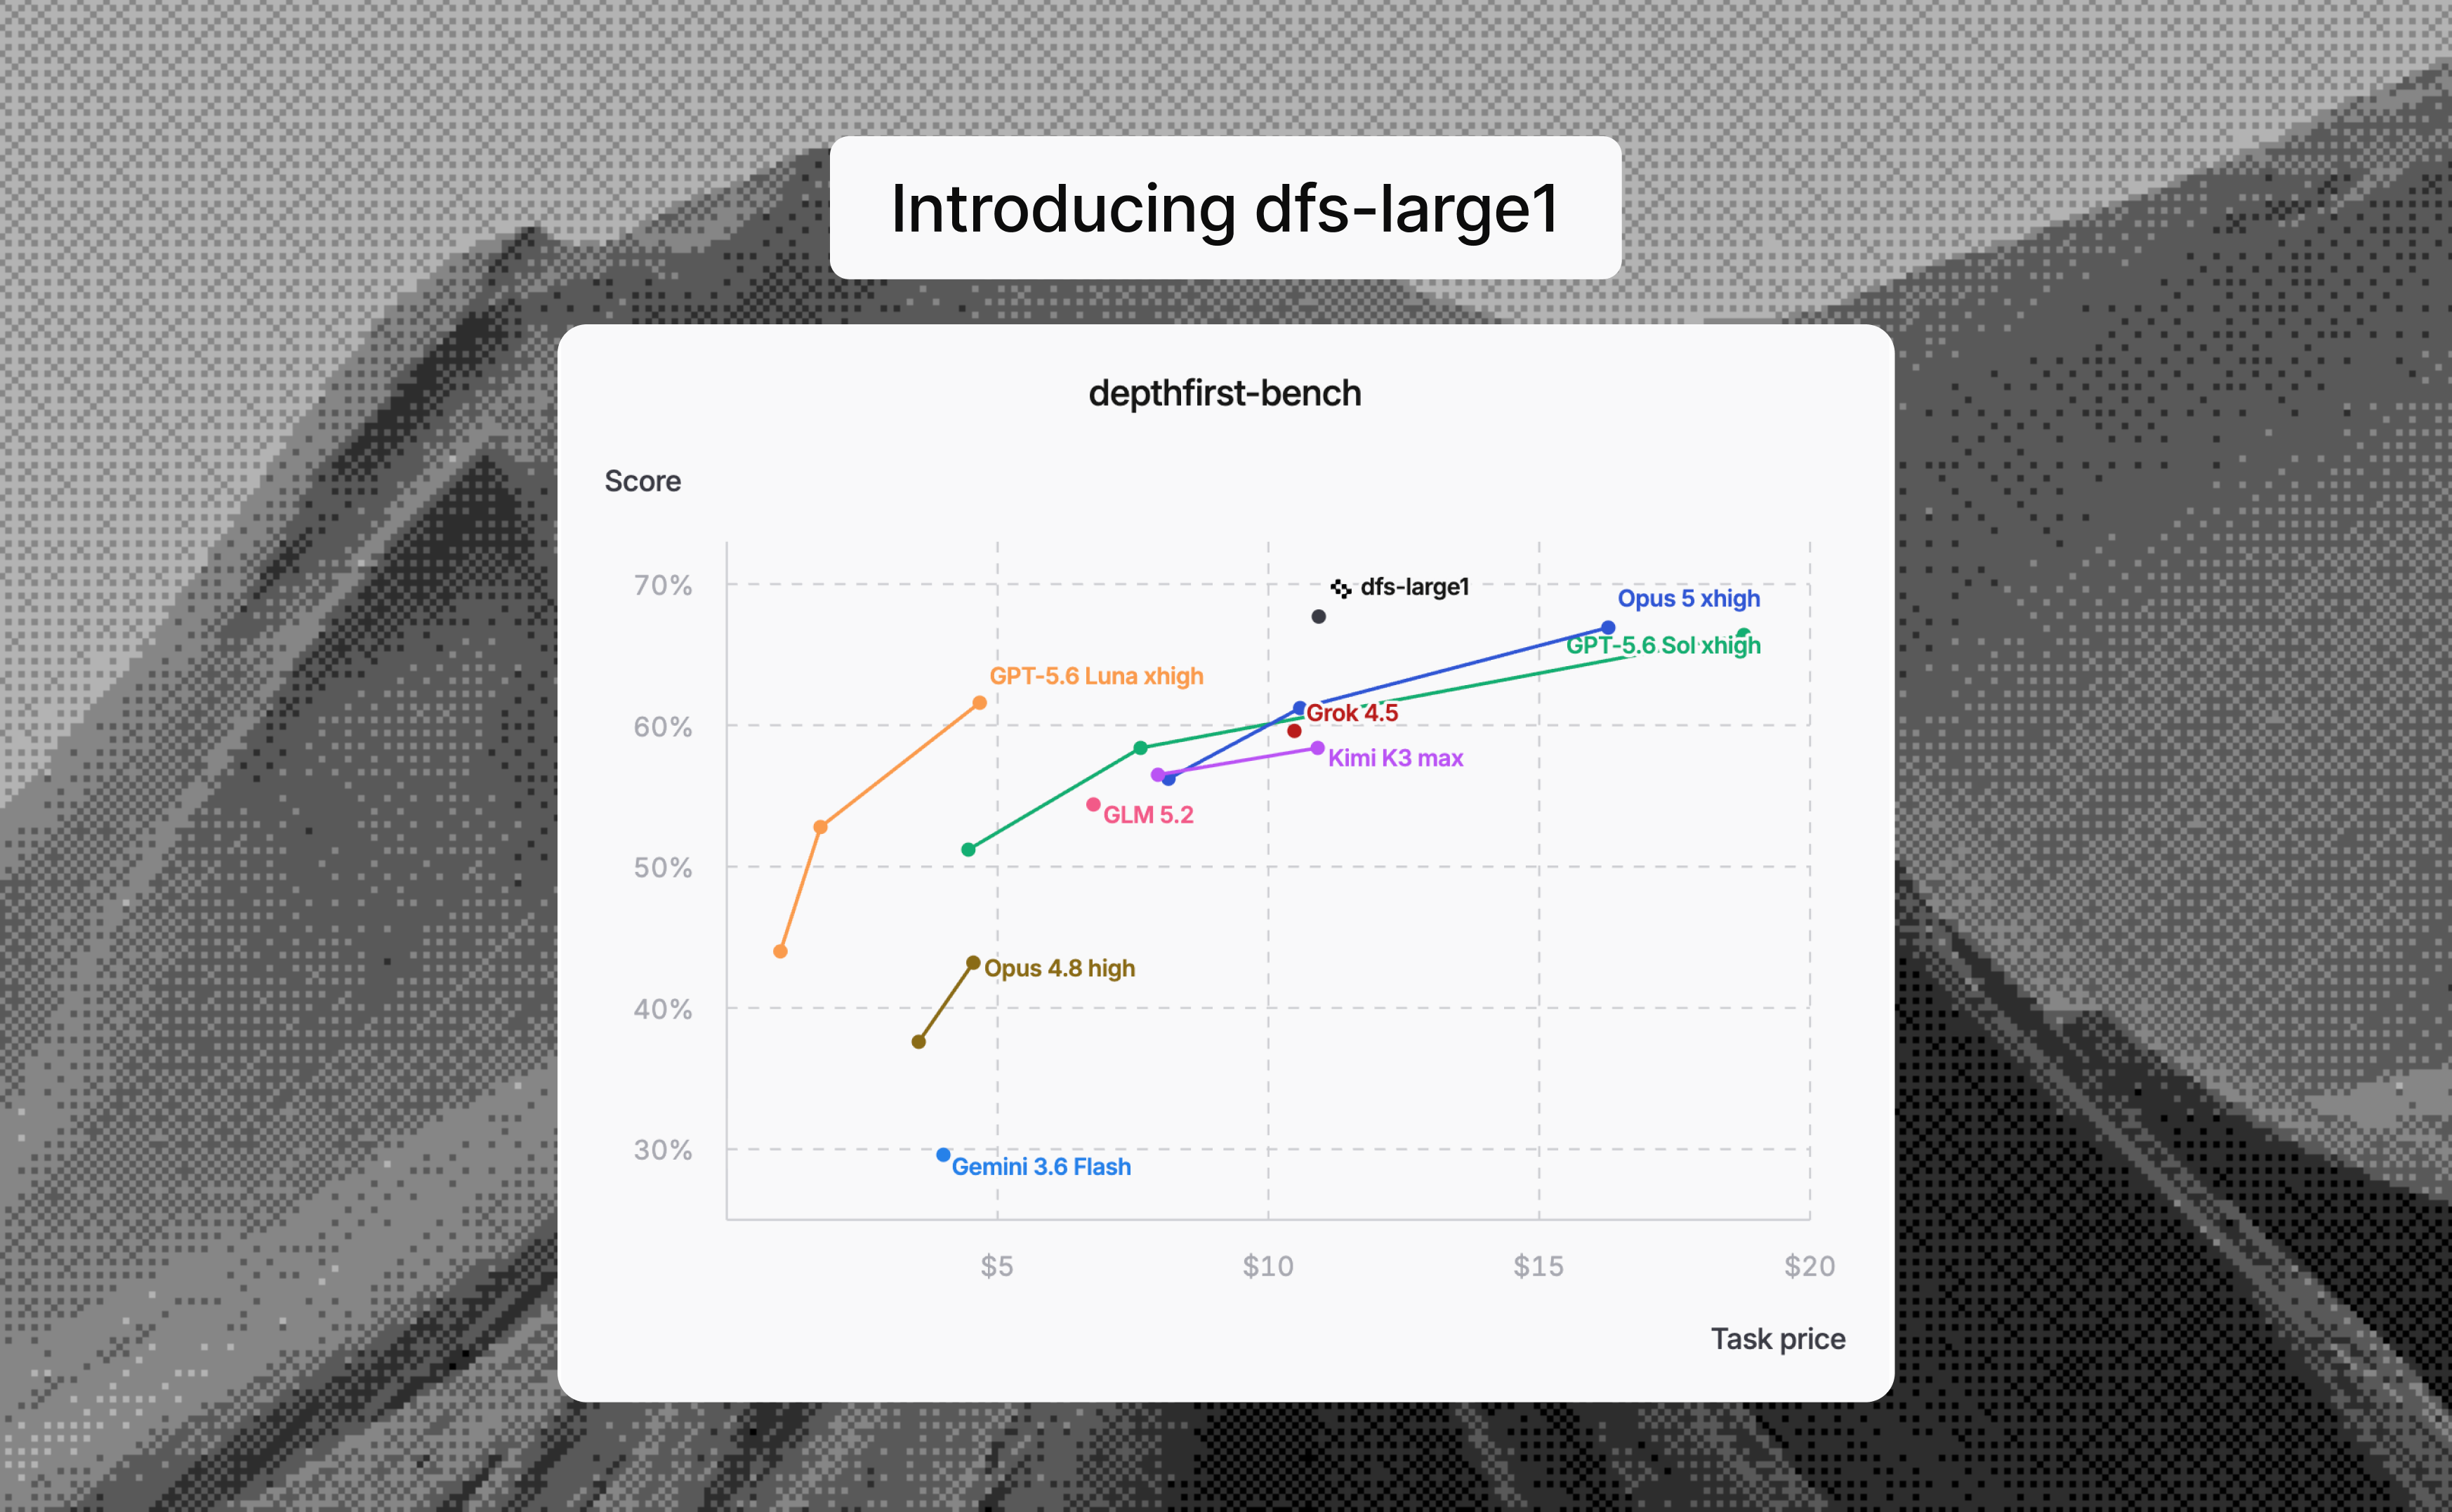
dfs-large1 is depthfirst's vulnerability discovery and validation model, post-trained from GLM 5.2 with multi-task RL inside its security agent harness, in partnership with Fireworks AI. The report covers the reward design (effort penalty, finding budget), masked importance-sampling optimization, task-level advantage normalization, summarization-based context compaction and the sandboxed evaluation setup. It reports that the learned audit strategy moved from broad enumeration to hypothesis testing with executable harnesses. Benchmark numbers and the dfbench methodology are not given.
What it is
dfs-large1 is depthfirst's vulnerability discovery and validation model, in preview inside the depthfirst platform. It is post-trained from GLM 5.2 inside depthfirst's security agent harness, with Fireworks AI scaling training and inference. It is trained jointly on three tasks: detection in application code, detection in low-level systems code, and validation of candidate findings. Systems code supplies strong verification signals, such as a reproducible ASan report. Web application findings are harder to verify automatically.
How it works
Harness. Each repository is split into audit scopes that run concurrently. An agent gets a bounded file list and a scoped threat model (attack surfaces, trust boundaries, data flows). Its shell stays rooted at the full repository, so it can trace callers and shared libraries outside its scope.
Effort penalty. The cost is λ·log(1+αx)/log(1+α). Here x is a linear combination of action tokens, agent rounds and tool-returned tokens. The concave shape penalizes extra work on short rollouts more than on long investigations. With the penalty, parallel tool use rose while rounds and action tokens held steady or fell. Without it, rounds and action tokens kept growing with more RL compute.
Finding budget. Reward is scaled by q = 1/max(1, n − B + 1), where n is the number of reported findings and B is the full-credit budget. B starts large and is lowered in stages, after baseline recall is established. In toy runs, removing it let the policy report locally plausible bugs with no reachability evidence.
Optimization.
- The pipeline is asynchronous, for tasks of about 100 agent turns.
- MoE expert routes are recorded per token and replayed in the training forward pass.
- The update is masked importance-sampling REINFORCE (from Periodic Labs), which drops tokens whose ratio falls outside (1−ε_l, 1+ε_h).
- This was more stable than clipping. CISPO, which keeps clipped tokens' gradients, was less effective here.
Advantages. Dr. GRPO is applied per rollout group, then normalized again per task, following AgentRL. This stops high-variance tasks from dominating the shared update.
Context compaction. The policy summarizes its own trajectory as context fills, reusing the recipe from dfs-mini1. Because the same policy is rewarded on the final outcome, compaction is learned behavior.
Results the page states
- Later checkpoints spent more turns tracing attacker-controlled input and used executable harnesses more often. Repository reads and searches declined. The authors suspect the finding budget, effort penalty and validation training all contributed.
- An earlier checkpoint supported the Ruby ecosystem campaign, which validated 105 vulnerabilities across 34 projects, about 61% of them memory-safety issues.
Evaluation setup
Models run at high thinking difficulty inside the depthfirst harness. Sandboxes have no internet and expose only a depth-1 clone with no history. LLM monitors flag reward hacking and attempts to find patch information. Every passing trajectory was reviewed, and no failures were attributed to safety refusals.
Caveats
- No benchmark numbers are given. "Best-in-class" and "new Pareto frontier" are depthfirst's own claims, measured on dfbench, whose methodology is deferred to a future post.
- The 105-vulnerability campaign used a previous checkpoint, not dfs-large1.
- The link between the reward terms and the strategy shift is stated as a suspicion, not an ablation result. The finding-budget evidence comes from "controlled toy runs".
- The page gives no values for λ, α, B or the ε bounds.
Organisations named here
- AgentRL
- CISPO
- Composer 2
- dfbench
- dfs-mini1
- Dr. GRPO
- GLM-5.2
- masked importance sampling
- Periodic Labs
Technologies named here
- dfs-large1
- AddressSanitizer
- GLM
- LLM
- AgentRL
- CISPO
- depthfirst security harness
- dfbench
- dfs-mini1
- Dr. GRPO
- Fireworks AI
- Masked importance-sampling REINFORCE
- Routing replay for MoE models
- Ruby ecosystem projects
Techniques named here
- Effort penalty
- Executable verification of findings
- Finding budget
- LLM behavioral monitors
- Scoped threat modelling and reachability analysis
- Summarization-based context compaction
Related in AI Security

 blog.talosintelligence.comtool
Introducing CAIRN: Frontier tracking for AI-integrated malware (Cisco Talos)
 github.comadvisory
Flowise MCP Security Bypass Enables RCE
github.comrepoYesWeHack Claude Kit

 jfrog.comarticle