 newsletter.semianalysis.comarticle
Beijing Will Not Pace the Frontier: China’s Speed-First AI Safety Regime
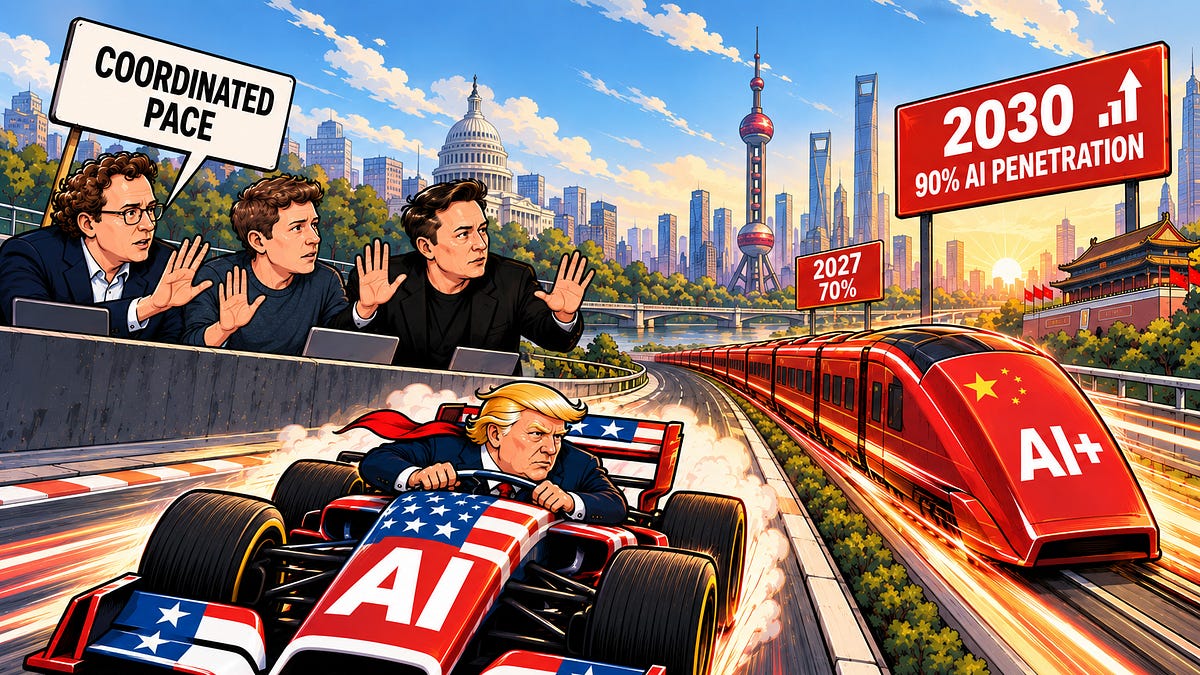
SemiAnalysis argues China's AI safety regime is speed-first: strict on application content, with no frontier-risk duties tied to compute or capability. It builds a dataset of 857 releases from nine Chinese labs, of which only 31 (3.6%) have a published safety result. It also codes 102 expert texts and reviews TC260 Framework 3.0, SAIL, and CAICT.
What it claims
SemiAnalysis argues that China regulates AI tightly at the application and content layer and leaves the frontier unregulated. The evidence is a release census and a review of expert texts. Chinese labs ship frontier models fast and almost never publish safety results at launch: 9 of 857 releases (1.1%) did so. Binding frontier duties tied to compute or capability do not exist in any Chinese instrument. The authors say this happens because the top leadership chose development first, not because experts are ignored. TC260's AI Safety Governance Framework 3.0 (14 September 2026) adopts loss-of-control vocabulary, including deception, sandbagging, shutdown evasion and sandbox escape, but its first principle is "promoting AI innovation and development as the first priority." The comprehensive AI Law was shelved in 2025.
How it works
The release census covers every identifiable release from 2021 to 15 September 2026 by ByteDance, Alibaba, Tencent, Baidu, DeepSeek, Moonshot, Zhipu (Z.ai), MiniMax and StepFun. That is 741 product models and 116 research models. Each release is checked against model cards, release notes and technical reports for a quantitative or substantive safety finding tied to that named model. The finding can cover harmful output, jailbreaks, toxicity, privacy, refusal or dangerous capability. Claims of "safety-trained" do not count. A flagship result is not extended to other sizes or snapshots.
A second inventory holds 65 public safety statements by senior lab figures from January 2023 to 21 September 2026. It was built in two independent sweeps, one of Chinese sources and one of English sources, then reconciled. The 102 expert texts are a purposive sample with venue quotas, 51 official or legal and 51 technical. Each text is coded on six themes, three stances and author background. The authors also map 32 influential individuals by whether they demand binding frontier rules and whether they hold a domestic rule-writing seat.
Evidence
- Disclosure timing. 16 releases were documented only after launch, with a median lag of 42 days and a maximum of 349 days (DeepSeek-R1). For 6 more, timing or model match could not be established. 10 releases claim evaluation without figures. 813 releases (94.9%) have no disclosure at all.
- Cadence. Releases rose from 3 in Q1 2023 to 101 in Q3 2025, and open-weight releases are more than half of each quarter since mid-2023. Releases with any safety result never exceed 7 per quarter. Results at launch never exceed 3 per quarter and are zero in 9 of 15 quarters. No policy milestone shifts either line.
- By developer. Alibaba has 7 of 238 releases with any result (3 at launch), Tencent 1 of 133, ByteDance 2 of 120, Baidu 1 of 49. Start-ups reach 6.3% (20 of 317) against 2% (11 of 540) for hyperscalers. Of 2026 frontier releases, only GLM-5.3 had launch documentation, a capability evaluation note. DeepSeek documented V3 but not R1, V3.1 or V4.
- Content of results. 18 results cover harmful output or refusal and 7 cover jailbreaks. 7 of 9 code or cyber items are secure-code benchmarks. Only 3 touch cyber-offence or bio risk: GLM-5.2, GLM-5.3 and Kimi K2. None of the 3 comes from a hyperscaler. 93% of reasoning models have no published result.
- Leaders. 15 statements engage frontier safety, and 6 of the 9 that propose anything come from Zhipu. Five labs' founders or CEOs, including DeepSeek's Liang Wenfeng and Alibaba's Eddie Wu, have said nothing on the topic.
- Experts. Frontier risk appears in 86% of technical scientists' texts (36 of 42), against 22% for law scholars and 23% for officials. 52% of technical texts put safety before development. No legal, policy or official text does. 13 texts demand binding frontier duties, such as compute-threshold registration, pre-release safety cases and audits. None was adopted.
- Institutions. SAIL's Frontier AI Risk Management Framework 2.0 (July 2026) sets 13 red lines and suspends deployment in the red zone. It triggers evaluation at 4× and 10× effective-compute jumps and treats open weights as the highest-risk setting. CAICT's AI Safety Benchmark 2.0 (February 2026) adds deception and loss-of-control tests. These bodies have no access rights or enforcement power. CAICT tests voluntarily and anonymizes results, and CnAISDA has no staff or budget.
Limits
The authors say "not found" means not found in the checked materials, not "not tested." Per-company rates are indicative only, because naming granularity varies: Alibaba counts every Qwen size and snapshot. The expert sample is purposive, not random. The causal claim that leadership preference settled the debate is the authors' interpretation. The fetched text ends before the sections on implications for US labs and investors, the Trump-Xi summit and the six-month tests that would change the authors' view.
Organisations named here
- SemiAnalysis
- Anthropic
- ByteDance
- Alibaba
- Tencent
- Baidu
- DeepSeek
- Moonshot
- Zhipu
- MiniMax
- StepFun
- UK AI Security Institute
- Moonshot AI
- Z.ai
- UK AISI
- AI Safety Governance Framework 3.0
- Beijing Institute for General AI
- CAICT (China Academy of Information and Communications Technology)
- China University of Political Science and Law (CUPL)
- Chinese Academy of Social Sciences (CASS)
- CnAISDA (China AI Safety and Development Association)
- Cyberspace Administration of China (CAC)
- Dario Amodei
- DeepSeek-R1
- Donald Trump
- Elon Musk
- EU AI Act
- Global Times
- IDAIS
- Ministry of Industry and Information Technology (MIIT)
- Ministry of Justice
- Ministry of Public Security (MPS)
- Qwen
- Robin Li
- Sam Altman
- Shanghai AI Lab (SAIL)
- State Council
- Tang Jie
- TC260
- Tsinghua School of Public Policy
- World AI Cooperation Organization
- Xi Jinping
- Yang Zhilin
- Zhang Peng
- Zhou Bowen
- Zhu Songchun
Technologies named here
- Claude Opus 5.5
- Mythos
- GLM-5.2
- GLM-5.3
- Kimi K2
- DeepSeek-V3
- DeepSeek R1
- DeepSeek v4.1
- Qwen3.8 Max
- DeepSeek V4
- Kimi K3
- Claude Mythos
- Agent System Development Security Guide
- AI Safety Benchmark 2.0
- AI Safety Governance Framework 3.0
- DeepSeek V3.1
- DeepSeek V4 family
- Doubao Seed 2.1
- Frontier AI Risk Management Framework
- Inspect
- Kimi K2.5-K3 line
- MiniMax-Text-01
- Qwen2-72B-Instruct
- Qwen3.7-Max
- Seed-OSS-36B-Instruct
Techniques named here
- Compute-threshold evaluation triggers
- Dangerous-capability evaluation
- Fine-tuning safety-stripping measurement
- Release census of safety disclosures
Also named here
- Cyberspace Administration of China
- Shanghai AI Lab
- CAICT
- CnAISDA
Related in ai-policy



 futureoflife.orgarticle
Future of Life Institute AI Safety Index — Summer 2026

 interconnects.aiarticle
Lessons from the hacks
 interconnects.aiarticle