 Inside mobile taint analysis: how source-to-sink tracking finds real data-leak paths | Oversecured Blog
Oversecured explains taint analysis for Android and iOS apps and contrasts it with pattern-matching SAST such as MobSF. It covers source, flow and sink, cross-component tracking over Intents, flag-based sanitizer modeling and implicit intent simulation. The case study is an unsafe Class.forName().newInstance() on a Serializable transportFactoryClassName field in Google's com.google.auth.oauth2 credential classes, which Google fixed with a $3,133.70 bounty.
 oversecured.comarticleAdded 29 Oct 2026🛡️ Security
 Android deep link vulnerabilities: how intent filters lead to account takeover | Oversecured Blog
Oversecured's article on Android deep-link vulnerabilities covers five patterns: custom scheme hijacking, open redirect into WebView, limited and full intent redirection, and domain takeover via an expired whitelist entry. It shows bypass payloads, intent selector abuse, and the HierarchicalUri reflection bypass. It also compares what SAST and DAST can find and gives a checklist for pentesters.
oversecured.comarticleAdded 29 Oct 2026🛡️ Security SDK security in mobile apps: the attack surface your team didn
Oversecured guide to SDK security in mobile apps, built around Microsoft's April 2026 disclosure of an intent redirection flaw in EngageLab's EngageSDK (50 million installs, fixed in 5.2.1). It covers SDK attack surfaces (exported components, WebViews, deep links, hardcoded secrets, payment crypto), a canhub image cropper file-overwrite example, why source-only SAST misses SDK code, and MASVS and PCI DSS expectations.
oversecured.comarticleAdded 29 Oct 2026🛡️ Security What took the Internet offline in Q3 2026
Cloudflare's Q3 2026 review of the 49 Internet disruptions seen by Cloudflare Radar between July and September 2026. Government-directed shutdowns led with 19 (18 exam shutdowns in Iraq), followed by 14 power outages and 5 natural disasters. It gives traffic-drop figures and durations for Cuba, Honduras, Ukraine, Guam, Colombia, Ethiopia's Tigray region and others, including a Honduran interconnection facility power failure that cut HTTP traffic 63%.
 blog.cloudflare.comarticleAdded 29 Oct 2026, published 27 Oct 2026🛡️ Security
 Code security for new coders
 is a Datadog Security Labs primer for vibe coders on first-party versus third-party code, hardcoded secrets and software supply chain risk (vulnerable and malicious dependencies). It lists security questions to put to a coding agent before and after code is written. It also defines SCA, SAST, IAST, DAST, IaC scanning and secret scanning, and cites the PHP2Shell vulnerabilities.
 securitylabs.datadoghq.comarticleAdded 29 Oct 2026, published 26 Oct 2026🛡️ Security
- Code security for new coders
Code security for new coders is a Datadog Security Labs primer for vibe coders building with coding agents. It lists setup and follow-up security questions to ask the agent, such as OWASP top 10 reviews, hardcoded secrets and outdated packages. It also explains first-party versus third-party code, supply chain risk, and SCA, SAST, IAST, DAST, IaC and secret scanning tools.
securitylabs.datadoghq.comarticleAdded 29 Oct 2026, published 26 Oct 2026🧠 AI - What Is SAST? Static Analysis in the Age of AI-Generated Code | Endor Labs
Explainer on Static Application Security Testing. It covers how SAST builds an AST and runs taint analysis from sources to sinks, which flaw classes it catches (SQLi, XSS, hardcoded secrets, weak crypto) and which it misses (IDOR and other access-control bugs). It compares SAST with DAST and SCA, cites false-positive and false-negative figures (91% false positives in a 2025 study of about 3,000 repositories; 47–80% of vulnerabilities missed), and argues for reachability analysis and reasoning-based AI SAST. It ends with evaluation criteria and a rollout plan; the vendor's own benchmark claims are preliminary.
 endorlabs.comarticlePublished and added 12 Oct 2026🛡️ Security
 Guide to Implementing Software Supply Chain Security | Endor Labs
Vendor-authored guide that defines a software supply chain as developers, code, dependencies, AI models, containers and CI/CD pipelines. It walks through program components: OSS governance, SAST vs reachability-based SCA, AI model security, SBOM/VEX (NTIA minimum elements, SPDX vs CycloneDX), secrets scanning, CI/CD hardening, and signing/attestation with Cosign/Sigstore. It cites figures such as 95% of vulnerabilities sitting in transitive dependencies and only 1% of SBOMs being fully NTIA-conformant. Each section closes with an Endor Labs product pitch, so treat the framing as vendor-flavoured. The fetched text was truncated, so the final attestation/provenance section was not seen.
endorlabs.comarticlePublished and added 12 Oct 2026🛡️ Security The OWASP Top 10 Gets Modernized | Endor Labs
Commentary on the 2025 OWASP Top 10 update presented at OWASP Global AppSec in Washington, D.C. Broken Access Control stays #1, Security Misconfiguration and the new Software Supply Chain Failures category (replacing Vulnerable and Outdated Components) rise to #2 and #3, and Cryptographic Failures, Injection and Insecure Design drop. The author adds context on agentic AI and MCP identity and authorization, AI-assisted SAST, non-human identities, CISA Secure-by-Default, OWASP SPVS, and slopsquatting and AI coding assistant risks.
endorlabs.comarticlePublished and added 12 Oct 2026🛡️ Security Context Engineering for Application Security | Endor Labs
Endor Labs whitepaper on using context engineering to make AI coding assistants produce secure code. It covers secure prompting (priming, decomposition, refinement with design-spec and test-first patterns), reusable system rules such as Cursor rules and the CSA R.A.I.L.G.U.A.R.D. framework, and external SAST/SCA tools wired in through MCP servers with a rule that triggers scans. It also covers the costs and risks: extra token use, models ignoring rules, untrusted community rules, and MCP server supply-chain threats. It cites figures such as 62% of AI-generated solutions containing flaws and a 77.5% reduction in weaknesses from recursive prompting.
endorlabs.comarticlePublished and added 12 Oct 2026🧠 AI- Context Engineering for Application Security | Endor Labs
Endor Labs whitepaper on using context engineering to make AI coding assistants write secure code. It covers four techniques: secure prompts (priming, decomposition, refinement with design-spec and test-first patterns), system rules (with sample rules and the CSA R.A.I.L.G.U.A.R.D. framework), external security tools wired in over MCP (with an example Cursor SAST rule), and RAG. It also covers MCP server threats and five defensive pillars, Cursor Hooks, and CISO-level recommendations. It matters because it gives practical guardrails for stopping missing-authorization, rate-limiting and hallucinated-dependency problems at generation time.
endorlabs.comarticlePublished and added 12 Oct 2026🛡️ Security  Frontier models found the vulnerabilities. Only the attacker found the chains.
Snyk benchmarks its Evo Continuous Offensive Security (COS) agent against Claude Security running Mythos on TaintedPort, a public deliberately vulnerable web app with 57 known vulnerabilities and 15 known exploit chains. Evo COS, run gray-box against the live URL plus source, confirmed 10 of 15 exploit chains with runnable proofs of concept — for example chaining an SSRF flaw with a hardcoded JWT signing secret into full admin account takeover — while Claude Security, reasoning over source code alone (white-box), found one additional critical bug but could not prove the vulnerabilities were actually reachable and chainable at runtime. The post argues that proving exploitability requires exercising the live application, not just reading code, and frames SAST-style code review and DAST-style live attack as complementary.
 snyk.ioarticlePublished and added 7 Oct 2026🛡️ Security
 SubQuery npm package (@subql/common) compromised with credential-stealing payload
StepSecurity recaps a 48-hour (May 18-19, 2026) software supply-chain attack wave that hit every pipeline layer at once: the Nx Console VS Code extension (2.2M installs) stealing tokens from GitHub/npm/AWS/1Password, the trusted GitHub Action actions-cool/issues-helper hijacked via tag replacement, a trojanized Microsoft durabletask PyPI package pulled within a 35-minute discovery window, a self-replicating Shai-Hulud npm worm, and GitHub's own disclosure that ~3,800 internal source repos were exfiltrated. The piece argues traditional SCA/SAST/EDR/CNAPP tooling missed all of it because none monitor CI/CD runner runtime behavior (e.g., attackers reading /proc/pid/mem to extract secrets) or developer-machine IDE extensions, and ties the incidents to StepSecurity's Harden Runner, Dev Machine Guard, Compromised Actions Policy and Secure Registry controls.
 stepsecurity.ioarticleAdded 6 Oct 2026🛡️ Security
 Why AI Coding Agents Keep Writing Broken Access Control
Snyk argues AI coding agents reliably write broken access control (BOLA/IDOR, OWASP's top category since 2021) because the facts needed to add an ownership check — what an object belongs to, who may access it, where tenant boundaries sit — are tacit product knowledge that exists nowhere in the code or prompt an agent sees. It explains why SAST tools catch patterned sub-categories like path traversal or SSRF but structurally cannot catch CWE-639/862/863 (missing or incorrect authorization), since there's no bad pattern to match, and proposes reasoning over an assembled "application-context graph" of architecture, data flows and trust boundaries instead. It closes with a five-step team checklist (inventory ID-accepting endpoints, document ownership rules, add authorization-specific PR review, write cross-tenant tests, run deep contextual analysis) and pitches Snyk's Evo Agentic AppSec as the tool built around that approach.
snyk.ioarticlePublished and added 1 Oct 2026🧠 AI- Why AI Coding Agents Keep Writing Broken Access Control
Snyk explains why AI coding agents reliably ship broken object-level authorization (BOLA/IDOR) bugs: the ownership rule that would prevent them (e.g. "invoices belong to organizations") lives in the product's data model and team knowledge, not in the prompt or surrounding code, so the agent produces code that is correct for the stated task but lets any authenticated user access other tenants' objects. The piece maps the flaw to CWE-639/862/863, contrasts it with pattern-matchable classes like SSRF and path traversal that SAST handles well, and lays out five concrete team actions (endpoint inventory, documented ownership rules, explicit authz review questions, per-resource cross-tenant tests, and periodic deep contextual analysis), while pitching Snyk's "application-context graph" and Evo Agentic AppSec as the tool for the pattern-less gap.
snyk.ioarticlePublished and added 1 Oct 2026🛡️ Security - 973 MCP Packages, 71% Single-Maintainer: A Practitioner
Suzu Labs guide to securing AI developer workflows across three surfaces: AI-generated code (Veracode 45% vulnerable, a formal-verification study at 55.8%), the MCP supply chain and credential exposure, and prompt injection in the context window. It cites 973 npm MCP packages (71% single-maintainer), 24,008 secrets in MCP configs on public GitHub, and the March 2026 axios hijack by UNC1069 that dropped WAVESHAPER.V2 and tampered with MCP configs. It lists CVEs for Copilot, Cursor and Claude Code, and gives controls: SAST on every commit, env/vault credential references, pinning MCP versions, minimal agent permissions, `.cursorignore`/Claude deny rules, and monitoring IDE DNS traffic.
 securityboulevard.comarticleAdded 26 Sep 2026🛡️ Security
 What is an agent harness (and how do you secure one)?
Adversa AI argues that AI agent security lives in the harness, the loop, tool executors, context/memory management, approval gates and sandbox wrapped around an LLM, not in the model itself, and catalogs nine recurring harness failure classes. It details the firm's own research: SymJack (a symlink-based approval-prompt bypass that let six tested coding agents write attacker-controlled MCP config), GuardFall (shell-matcher bypass exploitable in 10 of 11 open-source agents tested), and TrustFall (MCP servers auto-executing on folder-trust acceptance in Claude Code, Gemini CLI, Cursor CLI and GitHub Copilot CLI), plus references to IDEsaster's 30+ AI-IDE vulnerabilities, a Hugging Face download-counter side channel (CVE-2026-54316), and Novee Security's Black Hat findings on credential leakage across Gemini CLI/Codex trust boundaries. It closes with concrete mitigations: Meta's Agents Rule of Two, allowlisting over blocklisting, treating agent config as executable code, and chain-of-event monitoring mapped to the OWASP Top 10 for Agentic Applications.
 adversa.aiarticleAdded 7 Oct 2026, published 14 Sep 2026🛡️ Security
 Common C/C++ Vulnerabilities: A Practical Guide to Prevention | Blog | Endor Labs
Endor Labs guide to C/C++ memory-safety and input-handling vulnerabilities — buffer overflow (CWE-787/120/121), use-after-free (CWE-416), null pointer dereference (CWE-476), integer overflow (CWE-190), and format string bugs (CWE-134) — with vulnerable/fixed code snippets for each. It surveys detection tooling (Coverity, CodeQL, Clang Static Analyzer, AFL++/libFuzzer with ASan/UBSan, OSS-Fuzz) and argues that build-system complexity (Bazel, CMake, Conan, vcpkg) and high SAST false-positive rates make reachability analysis necessary, closing with a pitch for Endor Labs' AURI reachability engine.
endorlabs.comarticlePublished and added 11 Sep 2026🛡️ Security- Cursor Security: How to Secure AI-Generated Code in 2026 | Blog | Endor Labs
Endor Labs blog post detailing seven security risks specific to Cursor's AI code generation that its built-in controls (workspace trust, SOC 2, privacy mode) don't cover: indirect prompt injection via files/comments, malicious .cursorrules files creating persistent backdoors, AI-suggested typosquatted or outdated dependencies, hardcoded credential leakage in generated test/boilerplate code, cross-project context poisoning via repository indexing, and unreviewed agent auto-run execution. It contrasts Cursor's native controls with what external AppSec tooling (pitched as Endor Labs' AURI) needs to fill, recommending dependency pinning, egress filtering, secret-scanning pre-commit hooks, and reachability-based SCA/SAST.
endorlabs.comarticlePublished and added 11 Sep 2026🛡️ Security 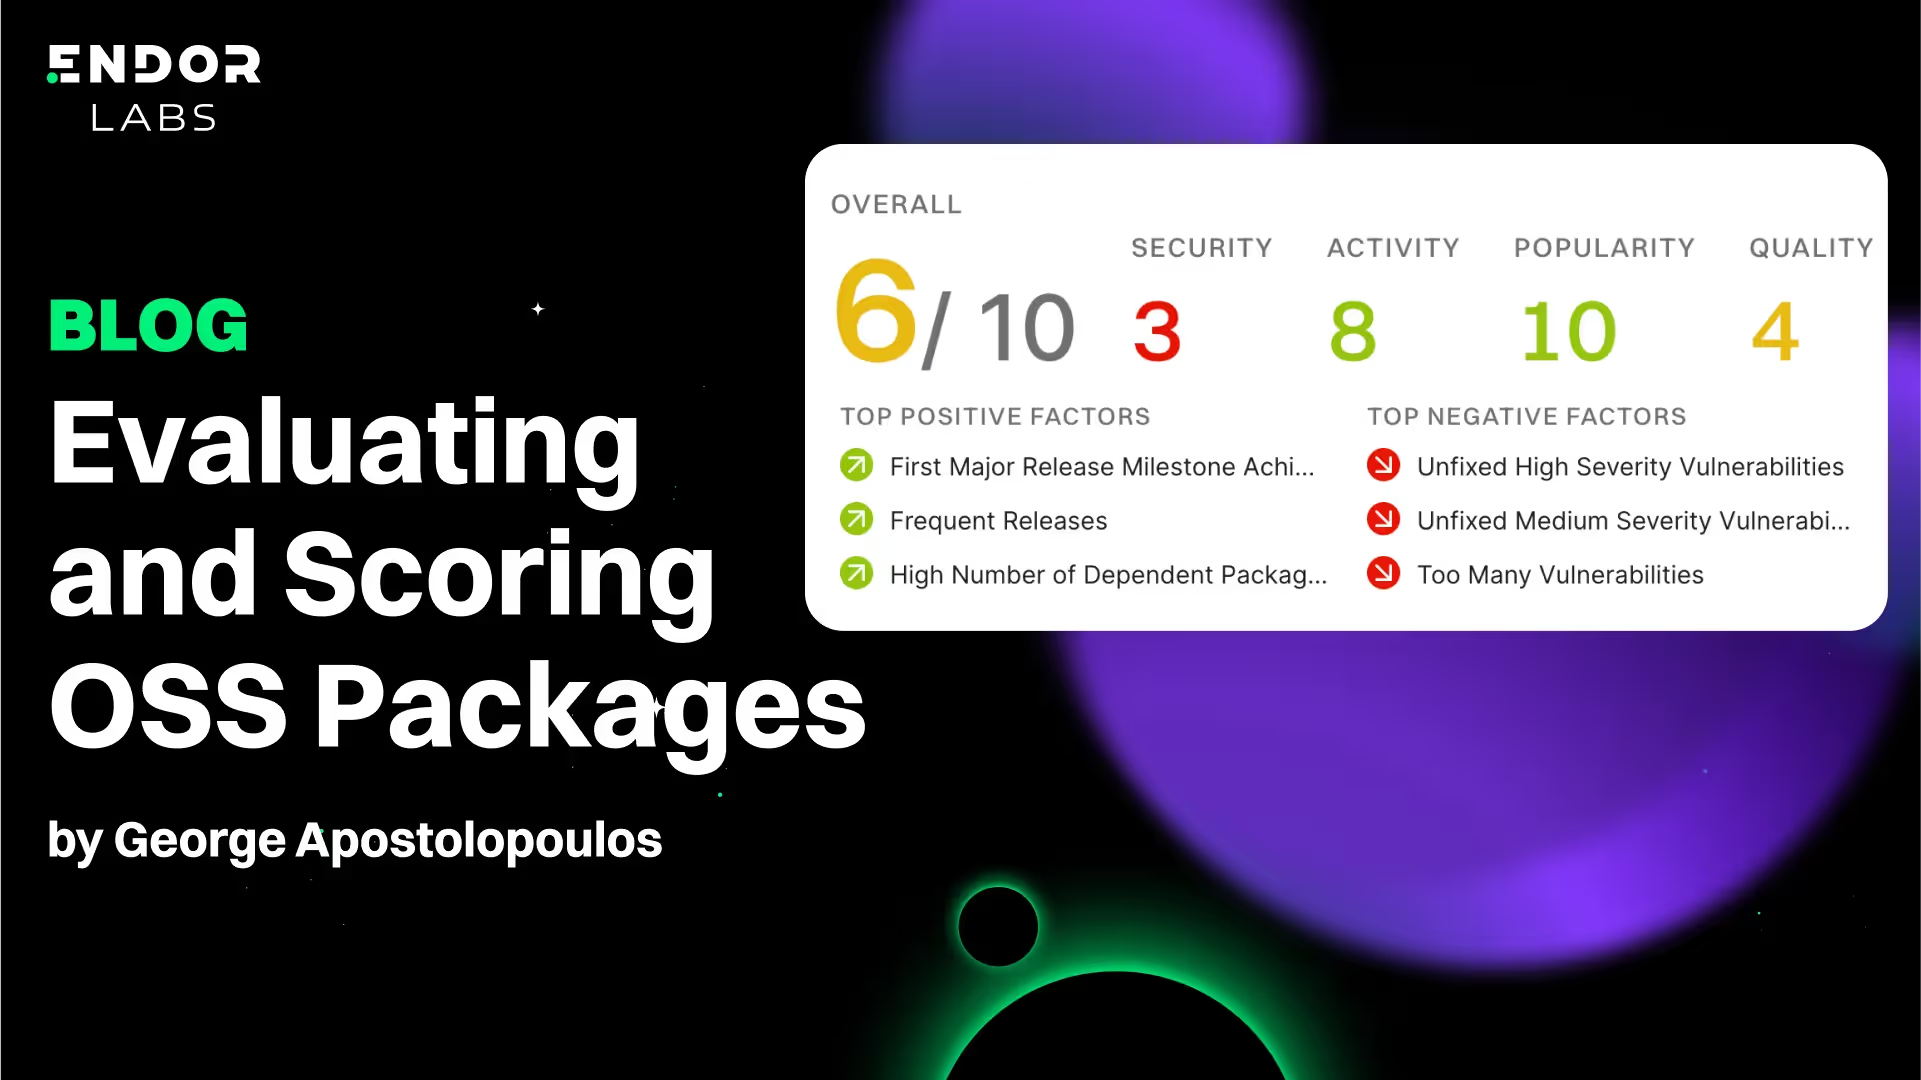 Evaluating and Scoring OSS Packages | Endor Labs | Blog | Endor Labs
Endor Labs blog post detailing their "Endor Score" methodology for evaluating open source package risk, distinguishing operational risk (activity, popularity, licensing, code quality) from security risk (vulnerabilities, secrets, malicious code, security practices). It argues against compressing everything into a single opaque score, favoring transparent, deterministic "facts" (e.g., recent commit counts, normalized SAST findings) that users can combine into custom policies, and discusses pitfalls like event-selection bias, threshold selection, and the unproven predictive power of these signals.
endorlabs.comarticlePublished and added 11 Sep 2026🛡️ Security How Endor Labs AI SAST Learns What Matters to Your Organization | Blog | Endor Labs
Endor Labs explains how its AI SAST product incorporates context beyond source code — automatically-ingested Infrastructure as Code (Dockerfiles, Terraform, CloudFormation, Kubernetes/Helm) and repository files (AGENTS.md, CLAUDE.md, skills files), plus optional analyst feedback and natural-language threat-model/architecture context — to build a deployment-aware model of an application and cut false positives. It cites a benchmark of 192 verified vulnerabilities across 8 projects, claiming 2.6x more true positives than the next tool (Claude Opus 4.7) and 63 findings no other tool caught, and walks through customer examples where external-auth annotations and WAF-mitigated XSS severity were tuned via this context.
endorlabs.comarticlePublished and added 7 Sep 2026🛡️ Security- AI Code Review: How to Actually Review Code an Agent Wrote | Blog | Endor Labs
Endor Labs explainer on "AI code review" as a discipline: pairing LLM reasoning with static analysis (call graphs, data flow) to catch security-relevant PR changes that AI coding agents introduce, alongside human reviewers. It cites research showing common AI-generated flaws (missing input validation CWE-20/89/78, hardcoded secrets CWE-798, broken auth CWE-306/284, hallucinated/insecure dependencies), Endor's finding that under 9.5% of vulnerabilities are reachable/exploitable, and a comparison of AI review against SAST, SCA, and secrets scanning, plus a rollout checklist referencing NIST SP 800-218A.
endorlabs.comarticleAdded 3 Sep 2026, published 2 Sep 2026🛡️ Security - SAST for AI-Generated Code: What Static Analysis Catches and Misses | Blog | Endor Labs
Endor Labs blog post arguing traditional signature-based SAST misses the logic and business flaws AI coding assistants introduce, since those flaws are "not pattern-shaped." It contrasts AI-assisted SAST (rules plus a thin AI layer) with AI-native SAST that traces dataflow across files and uses reachability analysis plus evidence-based triage to cut false positives, citing that Endor Labs' own tool (built on Opengrep with AI-agent triage) found a zero-day, CVE-2026-55407, in Anthropic's Rust buffa library and that only ~1 in 5 AI-recommended dependency versions are safe.
endorlabs.comarticleAdded 3 Sep 2026, published 2 Sep 2026🛡️ Security - Prompt Patterns That Make Coding Agents Write Safer Code | Blog | Endor Labs
Endor Labs breaks down prompt engineering patterns that reduce vulnerabilities in AI-generated code: a design-spec pattern that front-loads security requirements, naming specific CWEs to avoid (e.g. CWE-89, CWE-79, CWE-20), and a "secure-insecure diff" recursive self-critique loop, while warning that telling a model to role-play a security expert actually performs worse. It cites research showing these patterns cut vulnerability density by up to 56–77.5%, notes that repeated AI iteration can drift toward less-secure code, and flags that AI coding agents frequently suggest hallucinated or vulnerable dependencies (34% hallucinated per Endor's own dependency research), arguing prompts must be paired with SAST/SCA/secrets scanning and reachability-based prioritization.
endorlabs.comarticleAdded 3 Sep 2026, published 2 Sep 2026🛡️ Security - GitLab 19.3 release
GitLab 19.3 release notes cover dozens of features, with a significant cluster around AI agent tooling: a new "Flow Creator" foundational agent that generates runnable flow YAML for the GitLab Duo Agent Platform from natural language, GitLab Duo CLI plugin/marketplace support (compatible with existing Claude Code plugin marketplace files), new MCP tools (get_merge_request, list_merge_requests), pre-registered MCP OAuth applications, and a redesigned Agentic Chat UI for VS Code/JetBrains. It also ships GA features for Duo-based merge-conflict and review-discussion resolution, and security/SAST features like Agentic SAST vulnerability resolution flows.
 docs.gitlab.comarticleAdded 22 Sep 2026, published 27 Aug 2026🧠 AI
 Why C Has Always Broken Static Analysis | Blog | Endor Labs
Endor Labs analyzes four structural reasons C/C++ static analysis has historically underperformed: preprocessor/build dependence, hard pointer-aliasing tradeoffs (over- vs under-approximation), pattern rules poorly suited to length/lifetime bugs vs. web-style source-sink flaws, and the lack of dominant frameworks to model (unlike Spring for Java). It cites a study of 8,918 C++ programs showing LLM-generated code triggers confirmed runtime memory-safety violations (CWE-190, -122, -121) at 3.6x the human rate, bugs invisible to static-only CI gates and only caught by sanitizers/model checking. It surveys existing analyzer approaches (Coverity/Klocwork/CodeSonar build-based, Veracode binary-based, build-less scanners, generalist multi-language SAST) and their tradeoffs.
endorlabs.comarticleAdded 3 Sep 2026, published 25 Aug 2026🛡️ Security Remediation Agents, Demystified: Why Fixing Beats Finding
Recap of a Snyk "AI Security Engineers Community" livestream introducing Remediation Agent, now in public preview: an orchestration layer that sits between a developer's chosen LLM and Snyk's vulnerability intelligence (breakability assessments for OSS upgrades, package health/reachability scores, SAST fix generation, and ecosystem-specific upgrade playbooks) to auto-generate mergeable SCA and SAST fixes. It was demoed live against OWASP Juice Shop via the CLI (snyk fix --agentic --experimental --sca) and via an IDE path (Snyk Studio MCP server plus a /snyk-fix skill in Cursor, Windsurf, or VS Code), with Snyk reporting internal gains of 94% more mergeable SCA fixes and 13% more mergeable SAST fixes versus naively pointing an LLM at a vulnerability backlog.
snyk.ioarticleAdded 3 Sep 2026, published 19 Aug 2026🛡️ Security- Benchmarking Secure-and-Functional Remediation and How Snyk Agent Fix Lifts Frontier-Model Fix Rates by over 14%
Snyk built a Golden Test benchmark of about 150 real vulnerable code samples across Python, JavaScript, and Java, each scored on paired FAIL-to-PASS security and PASS-to-PASS functional unit tests, and ran Gemini 3.1 Pro, Claude Sonnet 4.6, and Claude Opus 4.6 both standalone and with Snyk's dynamic few-shot Snyk Intelligence context. Out-of-the-box models plateaued at 72-75 percent secure-and-functional fix rate, while adding Snyk Intelligence lifted Opus 4.6 from 74.6 to 85.4 percent overall, and from 64 to 88 percent on Python, showing security-specific context rather than model size drives remediation quality. The post also previews Snyk VulnBench, a companion study finding Claude Opus 4.7 with the Claude Code harness produced highly non-repeatable vulnerability findings when used as a SAST-like detector.
snyk.ioarticleAdded 3 Sep 2026, published 18 Aug 2026🛡️ Security  Finding vulnerabilities at every stage: what to run, and when
Aikido breaks down four distinct approaches to finding vulnerabilities in code: deterministic pattern-matching SAST, Deep PR Review (reasoning about a diff's impact on the wider codebase before merge), Code Security Audit/'AI SAST' (LLM-based reasoning across a whole repo without a live target), and AI pentesting (the same reasoning validated via live exploitation against a running app). It explains why each produces different false-positive profiles, why whitebox AI pentests (with source access) found a median 7x more high/critical findings than greybox in over 1,000 Aikido engagements at roughly half the compute cost per finding, and gives guidance on which layer to run at which stage of the SDLC and for which compliance needs (SOC 2, ISO 27001).
 aikido.devarticleAdded 3 Sep 2026, published 12 Aug 2026🛡️ Security
- Claude as Autonomous Bug Bounty Hunter
Author describes Aii-Aii Hunter, a bug bounty framework built on Claude Code with 124 markdown skills (35.5k lines distilled from public HackerOne reports), three hooks (UserPromptSubmit regex auto-routing, PreToolUse scope.json guard, PostToolUse telemetry) and a Podman Kali container exposing 110 tools plus 18 Burp tools over MCP. It also covers an engagement flow with a 7-Question validation gate, evidence hygiene, an autopilot mode, and SAST/DAST correlation. Useful as a blueprint for scoped, AI-orchestrated offensive workflows; first of six parts with a companion repo.
 medium.comarticleAdded 3 Sep 2026, published 30 Jul 2026🛡️ Security
Showing 30 of 42
Show more