 We’ve received our first response from the Project Suncatcher prototype satellite.
Project Suncatcher is a Google research effort to power AI compute in space. Its prototype satellite launched on 1 October 2026 and, after commissioning, returned the first AI response from a data-center-class TPU in orbit: a haiku from the onboard Gemma 4 open model, downlinked over Svalbard. Next come thermal-stress and radiation tests, then twin interconnected satellites in 2027.
 blog.googlearticlePublished and added 30 Oct 2026
- Show HN: I Turned DOOM into a Transformer
Doomformer compiles integer neural networks into ZDoom maps that run in ViZDoom. Voodoo dolls do the arithmetic, and sector light levels and plane heights hold the values. Python reads every value back and compares it with a NumPy integer reference at tolerance 0. It runs MNIST (97.16 % on all 10,000 digits, every pass exact), small transformers, a learning perceptron and a SUBLEQ machine. It is about 23,000 times slower than NumPy on a small MLP.
 github.comrepoAdded 30 Oct 2026, published 29 Oct 2026
 TextSeal2: Distortion-Free LLM Watermarking with Copula Mixing and Memoryless Races
TextSeal2 is a distortion-free watermark for LLM output that keeps its signal under speculative decoding. It merges two or more keys into one virtual key coupled to fresh noise through AutoMark's Gaussian copula, and verifies drafts with an extra exponential race. On three LLMs it detects 8 to 22 points more 100-token answers than TextSeal at a 10^-3 false-positive rate.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026
- On the Fundamental Limits of Prefill-Based Decoding Length Prediction
This paper derives bounds on predicting an LLM's decode length from prefill-phase hidden states, a primitive for inference scheduling. It models decoding as a stopped stochastic process, giving per-prompt normality and an affine variance law σ=αμ+b. Predictors (MLP, EGTP, FiLM, soft-label, Mixture-of-Experts) converge near the bound, so system error dominates model error. It proposes fixing model, data and sampling in benchmarks and reporting relative-error metrics.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026 - A Unified Hessian-Guided Framework for Post-Training Quantization
This preprint proposes a unified post-training quantization framework for large language models. It derives a Hessian-guided approximation of the output change caused by joint weight and activation quantization, using a tractable Fisher approximation. Quantization ranges, linear transformations and weight rounding are optimized together under one output-sensitivity objective. The authors report gains over state-of-the-art transformation and rounding methods in channel-wise and block-wise settings.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026 - MAServeBench: Benchmarking Multi-Agent LLM Serving Systems with Hierarchical Collaboration Workloads
MAServeBench is a benchmark that treats multi-agent collaboration as a configurable dimension of LLM serving workloads. Its composable stages model how agents coordinate and exchange context in documented multi-agent workflows, and Hierarchical Semantic Traces record operations and dependencies for reproducible comparisons. Task-linked measurements tie workloads to GPU/NPU behavior, showing serving efficiency does not always mean timely task completion. Code is released.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026 - Only Accepted Tokens Count: An Energy Accounting of Speculative Decoding Under Latency Targets
This paper measures the energy cost of speculative decoding in SGLang with CUDA graphs on H100 and H200 GPUs, at batch sizes up to 64 across 5 corpora. Savings depend on drafted-token acceptance, which is lower on conversation than code and lower on Romansh than English. Savings shrink as batch size grows, and block drafters can push verification into the compute-bound regime, where speculation raises energy per token.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026  SGLang (@sgl_project) on X
SGLang announces Day-0 support for Mistral Large 4 ("Le Chonk"), saying it is the first engine to serve the model on NVIDIA Vera Rubin. The post describes the model as Mistral's largest to date: a natively multimodal 1T-parameter mixture-of-experts model covering instruct, reasoning, coding and agentic workflows. The fetched text is truncated, so benchmark claims and launch commands are not visible.
 x.comthreadAdded 30 Oct 2026, published 29 Oct 2026
 Introducing AnySpeechRecognizer and AnyDecisionModel: Open Models for Speech and Decisions on Apple Platforms
AnySpeechRecognizer and AnyDecisionModel are two Swift packages from Hugging Face. The first mirrors Apple's SpeechAnalyzer API with swappable engines (NVIDIA Parakeet, Alibaba Qwen3-ASR on Core ML) and adds Sortformer speaker diarization. The second returns typed yes/no, choice and score answers with probabilities via MLX, Core AI, llama.cpp, Jev or Ollama. The post gives M4 Max timings, model sizes and calibration options.
 huggingface.coarticlePublished and added 29 Oct 2026
 Welcome Le Chonk: Mistral Large 4 on Hugging Face
Mistral Large 4 (Le Chonk) is a multimodal, multilingual Mixture-of-Experts model with about 1T total and 49B active parameters and a 1M-token context, released under the Mistral Ecosystem Open-Weight License. The post covers its MLA and DeepSeek Sparse Attention architecture, a 1.6B Pixtral encoder, and benchmarks including 82% on the Artificial Analysis Cyber Index and 93% on Cybench. It gives run recipes for transformers, vLLM, llama.cpp, TRL fine-tuning and Inference Endpoints.
huggingface.coarticlePublished and added 29 Oct 2026 OpenAI Plans to Buy Google's AI Chips as It Looks Beyond Nvidia: Report
Decrypt reports, citing The Information, that OpenAI plans to buy Google TPUs rather than rent them, to reduce dependence on Nvidia. Neither company has confirmed, and price, volume and timing are undisclosed. The article covers OpenAI's TPU optimization job listing, its Broadcom-built Jalapeño inference chip due end of 2026, Nvidia and AMD deals, and Anthropic's multi-gigawatt TPU agreement.
 decrypt.coarticlePublished and added 28 Oct 2026
- Quantize by Doing: Task-Guided Mixed-Precision Quantization of Vision-Language-Action Models
QbD-VLA is a mixed-precision post-training quantization method for vision-language-action models. It uses task success from short closed-loop evaluations to assign weight and activation bit widths, accounting for interactions between components. On four VLA models across all four LIBERO suites it holds task performance at about 4-bit weights and under 6-bit activations. The gain on SIMPLER is small. On a Franka Research 3 arm, X-VLA shows no detected loss, but π0.5 fails.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026 - FlatCake: A Flat KVCache Storage Architecture for LLM Serving
FlatCake is a KV cache storage architecture for LLM serving that treats host DRAM and NVMe SSD as peer media in one 64-bit address space, instead of a DRAM-over-SSD tier. Blocks are placed once, in session-contiguous, layer-major order, and streamed via GPUDirect Storage. On a Claude Code trace with DeepSeek-V4-Flash it holds a 94% hit rate (Mooncake: 64%) and cuts peak-load mean TTFT 1.6x.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026  Survival LLM: AI assistant and emergency library that runs on your own computer
Survival LLM is a free, open-source desktop app for macOS (Apple Silicon) and 64-bit Windows that runs an AI model and an offline emergency library on the user's computer. It checks the machine's memory, downloads a fitting model, and answers from sources such as Wikipedia, WikiMed, Ready.gov and CDC guidance, citing each article. Users can add their own files; version 0.3.2 is dated October 2026.
 brangus.iotoolAdded 28 Oct 2026, published 27 Oct 2026
 Photon Capital (@PhotonCap) on X
Photon Capital's thread covers the 27 October 2026 NVIDIA and Oracle announcement of general availability of Vera Rubin NVL72 and Vera CPUs on OCI. It lists specs (Spectrum-6 at 102.4Tbps, HGX Rubin NVL8 with Xeon 6, 150,000 initial Vera CPUs) and OpenAI's use of Vera CPUs for agentic sandboxes. The commentary argues CPU capacity can cut cost per task and shorten KV cache residency in GPU memory.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026- Metacognitive Decoding: Efficient Inference for Diffusion Language Agents
Metacognitive Decoding is a lightweight plug-in controller for diffusion language model backbones. It learns when to finalize tokens and how far generation should extend, and is trained on agent trajectories to balance correctness against generation cost. Across five benchmarks it cuts inference FLOPs by 20.6% on average versus the most efficient baseline, with competitive task accuracy. The abstract names no specific benchmarks or backbones.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026  Introducing LFM3: Every Modality for Specialized Intelligence
LFM3 is Liquid AI's new family of open-weight multimodal models, six models of about 2B parameters branched from LFM3-1.7B-Base (22T pre-training tokens, 256K context). The hybrid backbone uses 13 gated short-convolution, 5 sliding-window attention and 6 global attention layers. Variants cover text, vision with video, audio, omni and two decision models, with on-device speed numbers, fine-tuning demos and robotics extensions.
 liquid.aiarticleAdded 28 Oct 2026, published 27 Oct 2026
- CRISP: Co-designing Pruning and Scheduling for Efficient MoE Inference on Edge Servers
CRISP is a combination-aware framework that co-designs pruning and runtime scheduling for Mixture-of-Experts inference on memory-constrained edge platforms. It reorders neurons by importance so one stored expert supports several execution widths, gives hot, warm and cold expert combinations different widths, and overlaps expert loading with computation. On Mixtral-8x7B and DeepSeek-MoE-16B it raises throughput up to 2.1x at the same memory budget, with accuracy loss limited to 3.6%.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026  Coding From the Himalayas With an Offline AI Agent
Walkthrough of running OpenCode against Qwen3.5 9B served by Ollama on a Mac, with Wi-Fi switched off. The author fixes a one-line accumulation bug in an expense calculator and confirms all five unittest tests pass. It covers the opencode.json setup, memory budgeting, permission prompts and a pytest-versus-unittest detour. Two further exercises (CSV report, log analyzer) were not yet run offline.
 latent.spacewriteupPublished and added 27 Oct 2026
- p-DCIM: A 28nm Probabilistic SRAM DCIM based Ising Machine for Near-Memory Context Selection in LLM-RAG Pipeline
p-DCIM is a 28 nm SRAM digital compute-in-memory macro (0.16 mm2, 0.41 mW) that works as an Ising machine for RAG evidence selection. Selection is cast as a QUBO problem, and the same MAC datapath computes embedding similarities and annealing steps. Replacing LLM reranking with it gives a selection-energy estimate over six orders of magnitude lower and cuts total energy per query by 67%, with comparable token-level F1 on the evaluated examples.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026 - DCKV: Learned Transform Coding of the Prompt KV Cache in Hybrid Language Models
DCKV is a differentiable codec for the prompt KV cache of hybrid language models, which keep a KV cache only in their few full-attention layers. Transform, quantizer and entropy models (conditioned on prompt tokens and already decoded neighbouring positions) are trained end to end against a frozen model. On Qwen3.5-2B it stores a token in over 55 times fewer bytes than bf16 with at most 1.8 points lost on three long-context benchmarks, and over 100 times fewer with at most 3.6 points lost.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026 - AxisQ: Depth-Adaptive Channel--Frequency Quantization for Camouflaged Object Detection
AxisQ is a post-training quantization framework for camouflaged object detection (COD) that allocates activation bits by feature depth. It uses the channel domain for shallow features and the local-frequency domain for deep features, under a fixed per-layer average bit budget. It adds a boundary-aware Hessian approximation for reconstruction. On CAMO at W2A2, weighted F-measure improves 12.7% for CFRN and 33.3% for CamoFormer-P over the strongest baselines.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026  [AINews] Anthropic files for $2T IPO in 2 weeks: 1400% growth rate, 48% of revenue through cloud partners, 85% margin, $1B op profit in Q2, $134B cash in bank and $10B lifetime burn
AINews issue from Latent Space on 27 October 2026, led by Anthropic's S-1 filing for a Nasdaq listing (ticker ANT). It reports H1 2026 revenue of $16.3B, an 85% gross margin, $974M Q2 operating profit and 48% of revenue through cloud marketplaces, with reactions from named analysts. It also covers model releases, inference economics and agent tooling. The page text is truncated.
latent.spacearticlePublished and added 27 Oct 2026 OblivDGL: Oblivious Deep Graph Learning Made Practical
OblivDGL is a framework for secure GNN training and inference in machine-learning-as-a-service settings, modelled on Deep Graph Library. It uses an oblivious message passing paradigm and a new oblivious graph representation built on function secret sharing, revealing only the total node and edge counts. On four benchmark graphs it cuts training communication up to 1024x with up to 14.3x speedup, and inference communication up to 754x with 4.19x speedup.
 eprint.iacr.orgpaperAdded 28 Oct 2026, published 27 Oct 2026
- Folding Attention Biases into Keys Makes Compacted KV Caches Run on Standard Kernels
The paper folds the per-key logit bias of Attention Matching (AM) KV cache compaction into the keys along one closed-form direction per head, fitted on context queries. The result is a plain cache that FlashAttention and vLLM paged caches can use, with output error bounded by how far each query's projection on that direction is from 1. Unmodified vLLM serves folded caches through a KV connector. On QuALITY and LongHealth the fold is within noise of AM in 13 of 14 settings. Under AM's published per-head budgets it is within noise in 9 of 10.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026  Cross-request KV cache exposure in the GLM-5.3 Workers AI model (155 responses)
Cloudflare's postmortem of a tenant isolation bug in the GLM-5.3 model on Workers AI, active 27 August to 9 September 2026. Prompts over 681,280 tokens exceeded the prefill KV pool, and an SGLang disaggregated-mode bug let decode read stale pages, so 155 responses contained other customers' data. It covers the timeline, config and engine fixes (SGLang v0.5.22), and recommendations for operators.
 blog.cloudflare.comwriteupAdded 27 Oct 2026, published 26 Oct 2026
 Akash Rajagopal (@akashsairaja) on X
Ollama overview thread by Akash Rajagopal on X. It lists six steps: install on macOS, Linux, Windows or Docker; run `ollama run gemma4`; use the REST API on localhost:11434 (/api/chat); call it from ollama-python and ollama-js; llama.cpp as the README's supported backend; and `ollama launch claude` to connect Claude Code. Codex, OpenCode, Copilot CLI and Droid also work. The thread cites 184k GitHub stars and an MIT licence.
x.comthreadAdded 27 Oct 2026, published 26 Oct 2026- Show HN: Hob - Open-source, on device alternative to Claude Cowork and ChatGPT
Hob is an MIT-licensed desktop app from Frigade that runs open-weight models such as Gemma and gpt-oss locally on Mac, Windows and Linux. It picks the best open-weight model that fits the user's computer and sets it up. It is positioned as a free, private, offline alternative to Claude and ChatGPT for tasks like filling out PDFs and working through documents. The page gives no technical detail on its runtime.
github.comrepoAdded 27 Oct 2026, published 26 Oct 2026  Fixing Tool-Call Accuracy in vLLM
Ubicloud's post explains why tool-call schema accuracy matters for agentic workloads and how it fixed it when serving Kimi K2.6 and DeepSeek V4 Flash. With vLLM 0.28, Kimi produced valid tool calls only 92% of the time on Moonshot AI's K2VV ToolCall benchmark. Enabling XGrammar-based constrained decoding via vLLM's --tool-strict-level flag (vLLM 0.31) raised schema accuracy to 100%.
 ubicloud.comwriteupAdded 27 Oct 2026, published 26 Oct 2026
- SemiAnalysis (@SemiAnalysis_) on X
SemiAnalysis claims AMD chips running vLLM can earn up to $3 per chip-hour in profit serving the open-source Kimi K3 model, even after higher chip rental prices following Claude Code's rise. Kimi K3 has over 2.8 trillion parameters and fits AMD's 288GB per chip, while B200 cannot hold it in one server. B200 must then use tensor or pipeline parallelism over 400Gbit/s InfiniBand or Ethernet, which SemiAnalysis says is 18x slower than NVLink. The post gives no methodology.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026 - ZipFusion: Fusing Lossless KV Decompression with Attention for Efficient LLM Decoding
ZipFusion is a lossless KV cache compression scheme whose attention kernel reads the compressed cache directly and rebuilds the original values in registers with simple bit operations, so no separate decompression pass is needed. It also reassigns the memory freed by compression across layers to hold more KV cache. Built on FlashInfer and integrated with SGLang, it gives about 1.25x decode attention speedup on an H100 and up to 26.3% higher decode throughput at 8K context than uncompressed SGLang. It reaches up to 2.76x the throughput of the best lossless KV compression baseline.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026 - RAQ-MLA: Role-Aware Quantization for Multi-Head Latent Attention Caches
RAQ-MLA (Role-Aware Quantization for Multi-Head Latent Attention Caches) is a training-free method for quantizing the MLA KV cache. It fits a separate invertible transform to the compressed latent (tuned for attention-weighted value error) and to the positional key (tuned for score perturbation). It reaches about 2.5 bits per element, a 6.5x gain in theoretical KV-cache capacity, with near-lossless reasoning and coding results on four MLA models.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026  Building Reasoning Models from the Ground Up: A Video Course
Building Reasoning Models from the Ground Up is a series of eight coding videos (about 11 hours) by Sebastian Raschka, accompanying his book Build a Reasoning Model (From Scratch). Starting from a pre-trained Qwen3 0.6B model, it implements KV-cached generation, a MATH-500 verifier, self-consistency and self-refinement, simplified GRPO for RLVR, and distillation from DeepSeek R1 answers in Python and PyTorch.
 magazine.sebastianraschka.comcoursePublished and added 24 Oct 2026
- DualPace: Decoupled Scheduling and Cooperative GPU--CPU Decoding for LLM Serving
DualPace is an LLM serving runtime that treats the host as an independently scheduled decode engine. A GPU engine runs prefills and GPU-resident decodes, while an AMX-enabled CPU engine batches and advances CPU-resident decodes, optionally calling GPU Dense Assist for dense stages. In decode-oriented scenarios it raises throughput 6.9 to 43.2% over NEO and 11.5 to 90.6% over vLLM at similar latency.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026  Amazon’s Trainium Takes a Strike at the Training King
SemiAnalysis reviews AWS Trainium3 and the new TorchNeuron native PyTorch backend after a few weeks of hands-on use. It reports TorchTitan Qwen3-32B results on Trainium2 (11,099 tokens/s eager at 23.89% MFU, 14,156 compiled at 30.47%), a 27-minute gpt-oss compile time, 89 of 96 FlexAttention cases passing, matmul comparisons with GB300 and B200, and a positive view of the Neuron Explorer profiler.
 newsletter.semianalysis.comarticleAdded 29 Oct 2026, published 23 Oct 2026
- Accordion: Elastic-Depth Inference via Fixed-Prefix Layer Looping
Accordion is a mixture-of-experts language model (Accordion-6B-A0.5B) that supports five inference budgets through fixed-prefix layer looping, with the minimum budget being the unlooped model. After 3.6T pretraining tokens, deeper inference raises the macro-average over 37 tasks by 3.01 points, and the middle budget captures 89% of that gain with half the extra layer executions. SFT and RL keep the budgets, merging three domain experts via parameter-group merging and budget-matched multi-teacher on-policy distillation.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - BiLoCo: Binary Low-Rank Corrections for Post-Training Quantization
BiLoCo is a post-training quantization method for FP4 LLMs that adds low-rank corrections whose left and right factors are stored as binary ±1 sign vectors instead of BF16. This uses 16x less storage per rank-one component and lets the correction run on CUDA cores alongside the FP4 tensor-core GEMM. On 4B to 72B LLMs it matches or improves memory-matched SVDQuant. A fused B300 kernel is at most 11% slower than FP4-only GEMM at batch size 1 for ranks up to 512.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026 - MPQ: A Message-Passing View of Post-Training Quantization
MPQ (Message-Passing Quantization) is a post-training quantization method that treats row-wise PTQ as posterior inference over discrete codebooks. It keeps soft posteriors across weight blocks using vector approximate message passing, then refines a hard-decision initialization with exact block coordinate descent. Tested at 2-bit lattice and 3- and 4-bit scalar quantization on Llama, Qwen and Mistral models, it improves perplexity and zero-shot accuracy over GPTQ-style baselines.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026  Cache Engineering for Agents (AKV)
AKV introduces cache engineering, which lets LLM agents control their active KV cache with drop (exclude cache from future attention) and repos (adjust retained keys' position encodings) without editing the trajectory or re-prefilling. The AKV serving engine keeps a stateless API while managing stateful cache reuse, eviction and restoration. A tool-response rolling-drop policy raised benchmark scores by 1.7 points and cut cost 27.7% versus threshold-triggered summarization.
huggingface.copaperAdded 23 Oct 2026 Does Your Model Run on AWS Trainium? Look It Up
The torch-neuronx model support Space is a Hugging Face and AWS Neuron lookup that shows whether a Transformers model runs unmodified on AWS Trainium2. Each result lists core count, wall time and peak memory, plus the run.py script and a public NEFF compile cache. Tests generate 32 tokens on up to 16 cores. Results are in the aws-neuron/torch-neuronx-model-support Parquet dataset.
huggingface.coarticlePublished and added 23 Oct 2026- BeNice! Closing Looping's Inference-Memory Gap via KV-Sharing
BeNice! is a post-training method for looped language models that broadcasts the final recurrence's KV-cache into the first recurrence, so one cache can serve all recurrences. It follows a first stage that uses stochastic depth in pretraining to induce contractive residual dynamics. It matches standard finetuning's unshared validation perplexity and composes with multi-latent attention, Kimi delta attention and fp8, mxfp8 and nvfp4 cache quantization. In simulated low-memory long-context inference it raises cache hit rates by up to 31.4% and throughput by up to 23.6%, and cuts p90 time-to-first-token by up to 83.6%.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026  Why AI Compute Comes in Rectangles — Erik Bernhardsson, Modal CEO
Latent Space interview with Modal CEO Erik Bernhardsson, after Modal's $750M Series D at a $16B valuation and passing $1B annualized run rate. He explains why GPU demand is not "rectangular" like fixed-term capacity contracts, how Modal pools demand and buys from about 25 clouds on three-year deals, and why sandboxes grew to about a third of revenue. Also covers GPU price-collapse risk and non-NVIDIA accelerators. Only the first part of the transcript was available.
latent.spacetalkPublished and added 22 Oct 2026 Why AI Compute Comes in Rectangles — Erik Bernhardsson, Modal CEO
Latent Space interview with Modal CEO Erik Bernhardsson after the company's $750M Series D at a $16B valuation, with a transcript. He explains why GPU demand does not match rectangular fixed-term capacity contracts and how Modal pools demand across customers. He covers sourcing from nearly 25 clouds on multi-year deals, the risk of falling GPU prices, sandboxes reaching about a third of revenue, and non-NVIDIA accelerators.
latent.spacetalkAdded 23 Oct 2026, published 22 Oct 2026- Evaluating the Applicability of LLM Inference Optimizations on Apple Silicon
This October 2026 arXiv paper evaluates four LLM inference optimization families on Apple Silicon: KV-cache pruning, speculative decoding, ported GPU kernels and post-training quantization. Tests run on four Apple machines with a single-request decode workload, plus matched RTX 4090 runs. KV-cache pruning reaches 1.75x throughput on Apple, all tested speculative decoding methods reduce throughput, and ported kernels give up to 1.20x.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - Drift Says When, Budget Says How Much: Rate-Controlled KV Re-selection for Long-Form Multimodal Generation
Rate-Controlled Refresh (RCR) is a KV cache re-selection method for multimodal LLMs in long-form generation. Attention drift decides when and where to re-select visual tokens, and a per-sample controller sets how often. RCR beats InfiniGen by 1.6-3.8 ROUGE-L points on five of six model-task settings and stays within 1.7 points of exact per-step re-selection. On video description, where drift is homogeneous, it no longer beats a fixed threshold.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026 - Show HN: OnKey – I'm a bad singer, so I built an app to show where I'm off-key
OnKey is a free, MIT-licensed singing trainer for Apple Silicon Macs. After a song ends in Spotify, Apple Music or browser YouTube, it separates the lead vocal with UVR's MDX-Net Karaoke 2, tracks pitch with CREPE and turns it into syllable-level notes with the GAME model. On later plays it scrolls the notes, draws the user's live pitch and scores each line. Analysis runs on-device, and the repo explains the build steps and network requests.
github.comrepoAdded 24 Oct 2026, published 22 Oct 2026 - SARIA: Persistence-Aware KV Caching with Coordinated DRAM--SSD Reload for LLM Agents
SARIA (Selective Admission and Reload for Inference Acceleration) is a KV caching system that jointly manages DRAM and SSD for multi-turn LLM agents. It persists only blocks likely to be reused beyond DRAM residency, promotes SSD-hit blocks into DRAM for same-session reuse, and paces DRAM reads with a transfer coordinator. Built on LMCache MP, it cuts SSD writes by 57.1 to 58.9% versus full duplicate caching and mean TTFT by 42.3 to 79.7% versus DRAM-only caching.
arxiv.orgpaperAdded 23 Oct 2026, published 22 Oct 2026 - RIFT: KV Cache Compression for Draft Models with Complementary Compressibility Training
RIFT is a family of selection-based KV cache compression strategies for speculative-decoding draft models. It targets "decode staleness", where prefill-focused selection loses relevance as output grows, by balancing prefill information with recent generated tokens, refreshing the selection adaptively, and training drafters with sparse attention masks. Qwen3.5-4B drafting for Qwen3.5-122B keeps over 98% of full-cache acceptance length at 32K input, 4K output and an 8K KV budget.
arxiv.orgpaperAdded 23 Oct 2026, published 22 Oct 2026  [AINews] OpenAI’s Patch the Planet program is 1 of 2 parties to discover PHP2Shell vulnerabilities in core PHP affecting 70% of the web, using GPT-5.6 Sol; coordinated response over 2 months
AINews issue for 20-21 October 2026. The top story covers PHP2Shell (CVE-2026-109618 and CVE-2026-109619), two PHP-engine memory-corruption bugs found separately by Calif researchers using GPT-5.6 Sol under OpenAI's Patch the Planet and by Wiz, followed by two months of coordinated remediation. It also covers the Flint coding MoE, DeepSeek's DeepInfer, TorchTPU, eval critiques and agent product launches. The text is truncated.
latent.spacearticlePublished and added 22 Oct 2026- Gandalf: Flash Shall Not Die! Increasing Flash Storage Lifetime for KV Cache Offloading in LLM Serving
Gandalf is an SSD KV cache offloading system for LLM serving that is aware of SSD lifetime. It prioritizes admitting full-attention KV cache to SSD over cache from other attention types, using application-level information rather than access history alone. The authors report a 7.3x average SSD lifetime extension with negligible cache hit rate loss across several workload traces and hardware capacities. The design may extend to High Bandwidth Flash.
arxiv.orgpaperAdded 23 Oct 2026, published 22 Oct 2026  Open Weight Updates (@openweightstars) on X
Flint is the first model from Recursive SI, a fast local coding model with open weights released the same day. It was built with the company's automated research system, the Eureka Machine. The post claims up to 2x faster speed than comparable models: 125+ tokens/sec on a MacBook Pro and 150+ on RTX Spark. The captured text is truncated and gives no benchmarks or model size.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026 How Specializing the Vocabulary of SLMs Can Cut Inference Cost by 77% in Real Applications
VocabX is a vocabulary adaptation method from Dharma-AI that selects sub-word and multi-word "macro" tokens by serving cost instead of frequency. On a Qwen3-4B Portuguese essay grader, response length fell from 350 to 101 tokens, the LM head shrank from about 152,000 to 65,000 rows, and measured cost dropped 77.0% on an RTX 5090 with vLLM. The bench score rose from 0.703 to 0.810. It beat FVT, MWT and in-place BPE across 15 model and domain combinations.
huggingface.coarticlePublished and added 21 Oct 2026 The Huawei-DeepSeek Symbiosis
 analyzes DeepSeek's 30 September 2026 Ascend support for TileLang, DeepGEMM, DeepEP, TileKernels, FlashMLA and DeepSelect. It microbenchmarks the Ascend 950PR (BF16 GEMM, HBM bandwidth, die topology, AICPU) against H100, and profiles DeepSeek-V4.1-Flash on 32 Ascend 950DT chips. It also lists vLLM-Ascend gaps on x86 hosts.
newsletter.semianalysis.comarticleAdded 29 Oct 2026, published 21 Oct 2026 SemiAnalysis (@SemiAnalysis_) on X
SemiAnalysis thread arguing that vLLM with Wide-EP and EPLB can reproduce DeepSeek's serving performance. It reports decode throughput within 6% of DeepSeek's DeepInfer release and about $39 per GPU-hour revenue at DeepSeek's off-peak pricing, at 200 P90 TPS on the AgentX workload. It explains why DeepInfer is not on InferenceX: the release supports only offline, single-turn inference. It also estimates GB300 profit at OpenRouter prices.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026 Profiling TorchNeuron (Part 1): System-level profiling on AWS Trainium.
Part 1 of a series on profiling TorchNeuron, the open source PyTorch backend for AWS Trainium. It shows how to configure torch.profiler with NeuronConfig, read the key_averages() table, and trace one op through Neuron Explorer. Three RMSNorm variants are compared: naive eager (2.355 ms device time), torch.rms_norm (403 μs) and torch.compile (375 μs).
huggingface.cowriteupPublished and added 21 Oct 2026 Inside AMD and Anthropic’s ‘chips for shares’ deal
Protos reports on the AMD and Anthropic compute deal: Anthropic commits to buy over $20 billion of AMD AI compute, up to 2 GW of Instinct MI450 chips from the first half of 2027, while AMD commits up to $5 billion to Anthropic stock through fiscal 2028. It cites WSJ reporting that hyperscalers cap Anthropic's compute, and Anthropic's 2025 operating loss above $8 billion on $4.6 billion revenue.
 protos.comarticlePublished and added 21 Oct 2026
 [AINews] DeepSeek DeepInfer: Open Source SOTA Inference running 155T toks/day/cluster making $22m/day at ~80% margin for a 81 day payback
AINews issue for 19 to 20 October 2026 whose top story is DeepSeek's open-source DeepInfer, the inference engine behind V4.1 Flash. It covers prefill/decode separation, wide expert parallelism, a 3FS-backed prompt cache with 96% input hits, vLLM's decode result within 6% of DeepInfer on GB200, and disputed margin estimates built on the reported $38 per accelerator-hour. It also digests other news, and the page text is truncated.
latent.spacearticleAdded 23 Oct 2026, published 21 Oct 2026 [AINews] DeepSeek DeepInfer: Open Source SOTA Inference running 155T toks/day/cluster making $22m/day at ~80% margin for a 81 day payback
This AINews issue (20 October 2026) leads with DeepSeek's open-sourced DeepInfer, the vLLM-based inference engine behind V4.1 Flash. It covers prefill/decode separation, a 3FS-backed prefix cache with 96% hit rate, SWA Bounded Replay, and DeepSeek's claims of 155T tokens/day and $38 revenue per accelerator-hour. It also covers vLLM's within-6% decode reproduction on GB200, disputed margin estimates, and a round-up of other AI news. Only the first 40,000 of 56,439 characters were available.
latent.spacearticlePublished and added 21 Oct 2026- 0xMarioNawfal - The Roundtable Show (@RoundtableSpace) on X
TorchTPU is Google's open-source project for running PyTorch apps on its TPUs, announced the day after Amazon released TorchNeuron for its Trainium chips. Google says migration needs "a simple configuration change" with no rewrite. It worked with Meta, Hugging Face, and the vLLM and SGLang teams on compatibility, and added an agent suite that helps migrate apps and fix errors. The post is brief and gives no benchmarks.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026  The Programmable Data Center — Evan Conrad, SF Compute
Latent Space interview with Evan Conrad, CEO of SF Compute, recorded at AI Engineer NYC. He explains why the company runs a cloud's operations to physically settle GPU contracts on an order book with multi-constraint matching. Topics include preemption and storage recovery, hardware cohorts, batch versus live inference pricing, forward curves, a B300 price arbitrage, and cash versus physical settlement. The last ~3,600 characters of the transcript were not available.
latent.spacetalkAdded 23 Oct 2026, published 20 Oct 2026- Cache Engineering for Agents
Cache Engineering for Agents proposes letting LLM agents control their active KV cache directly, using a drop operation to exclude cache from attention and repos to adjust retained keys' position encodings, without editing the trajectory or re-prefilling. The authors build the AKV serving engine to handle history-dependent cache states. A tool-response rolling-drop policy raises average benchmark scores by 1.7 points and cuts cost by 27.7% against threshold-triggered summarization. AKV gives up to 1.2x output throughput and 1.5x faster P95 latency.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026 - Beyond 4 bits: Data-Centric Post-training Quantization and Recovery
This paper studies 2-bit post-training quantization (PTQ) of six dense and mixture-of-experts models from 3.8B to 32B parameters. It finds the quantization representation matters most: vector codebooks give usable models where scalar PTQ falls to chance. Calibration and recovery data must be chosen jointly. The recipe uses about 2.3 effective bits per weight, keeps 89 to 97% of full-precision QA accuracy, and needs 1.4 to 30x less compute than the strongest QAT baseline.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026  Latest open artifacts (#25): DeepSeek V4.1 Flash 1017, American-made models, and new regulatory controls in the US & China
Interconnects' Latest open artifacts (#25) covers open-weight AI in fall 2026. Policy items: China's MOFCOM proposal for pre-approval of international model sharing, and a DHS order barring DeepSeek from federal civilian procurement. DeepSeek released its internal inference stack DeepInfer. Picks include MiMo-V2.6-Pro-RL, DeepSeek-V4.1-Flash-1017 (552B-A16B, MIT), Clef, Nemotron-3.5-Super-VL and Reflection's Beam-1.0 (Apache 2.0).
 interconnects.aiarticlePublished and added 20 Oct 2026
- DeepInfer: High-performance inference framework for DeepSeek models
DeepInfer is DeepSeek's open-source inference framework for offline inference of DeepSeek-V4.1-Flash, released under Apache 2.0. It covers attention data parallelism, MoE expert parallelism with load balancing, draft-token decoding with confidence-scheduled verification, batch-invariant inference, deterministic sampling and structured outputs. It runs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. The KV cache system, prefill/decode disaggregation and load balancing are not included.
github.comrepoAdded 21 Oct 2026, published 20 Oct 2026  [AINews] not much happened today
AINews issue for 16 to 19 October 2026 from Latent Space, a digest of Twitter and Reddit AI news. It covers DeepSeek V4.1 Flash 1017 (552B total, 16B active MoE, AA Intelligence Index 45), MiniMax M3.1 Flash, Mercury 3, Meta Muse, Google's Harness², vLLM v0.32.0 and a Terminal-Bench audit. Only the first 40,000 of 47,045 characters were available.
latent.spacearticleAdded 30 Oct 2026, published 20 Oct 2026 [AINews] not much happened today
AINews issue covering 16-19 October 2026 from Latent Space, summarising 12 subreddits and 544 Twitter accounts. It leads with DeepSeek V4.1 Flash 1017 (552B total, 16B active MoE, 1M context, MIT license, AA Intelligence Index 45), plus MiniMax M3.1 Flash, Mercury 3 and Meta Muse. It also covers vLLM v0.32.0, InferenceX results, Harness² and Terminal-Bench audit findings.
latent.spacearticlePublished and added 20 Oct 2026 AnyLanguageModel 1.0: One Year of Local Models on Apple Platforms
AnyLanguageModel 1.0 is a Swift package that gives apps Apple's Foundation Models API across the system model, llama.cpp, MLX, Core ML and hosted providers. This release post covers tool calling and guided generation on every provider, image input, and hosted support for OpenAI, Anthropic, Gemini, Ollama and Hugging Face Inference Providers. It also ships swift-huggingface 1.0 and swift-xet 1.0, and lists small open-weight models that fit on iPhone and Mac.
huggingface.coarticlePublished and added 20 Oct 2026 MPS in PyTorch 2.15
PyTorch 2.15 MPS release post from the Hugging Face PyTorch team, covering the Apple silicon backend. It adds float8_e4m3fn tensors with F.scaled_mm, a native grouped matmul that speeds MoE decoding 5 to 6.5x (Qwen3.6-35B-A3B from 9.4 to 61.3 tokens/s on an M3 Ultra), and an 8x faster softmax. Wan2.2 VAE decode peak memory falls from 270 GiB to 8 GiB. It previews 2.16 attention on Metal.
huggingface.coarticlePublished and added 20 Oct 2026 Hugging Face ❤️ TorchTPU: TPUs, Natively
TorchTPU is a native PyTorch backend that makes Google TPUs a regular "tpu" device, replacing the older torch_xla path and Optimum TPU. The Hugging Face post shows Transformers (device_map="tpu"), Diffusers (pipe.to("tpu")) and Pallas kernels from the Kernels Hub running on it. It reports up to 21.5x faster decoding on Qwen3-30B-A3B at batch 64 and a 96.5% TPU test pass rate.
huggingface.coarticlePublished and added 20 Oct 2026 Cutting our inference bill by 68% by being obsessive about optimization
Cloudflare describes how it cut the average cost of its AI code reviewer from $2.43 to $0.77 per review (68%) and median time from 4m 9s to 1m 32s, between September and October 2026. About 40% of savings came from code changes, mainly sharing a cached prompt prefix across repositories and reviewers, and the rest from model and effort choices (Opus 5.5, Sonnet 5.5). Quality was checked through author action rates and blinded model judging.
blog.cloudflare.comwriteupAdded 29 Oct 2026, published 19 Oct 2026- TokenGate: Adapting LLMs for Fast and Memory-Efficient Prefill with Learned Token Pruning
TokenGate is a small drop-in component that adds end-to-end learnable token pruning to trained LLMs for long-context prefill. It uses token-gated attention, inspired by Mixture-of-Experts, to re-weight attention logits with token importance scores, which gets gradients through the non-differentiable top-K step. The authors report 1.4-11.3x faster time-to-first token and 1.5-3.4x lower peak memory with no accuracy loss, on Qwen3 and Qwen3.5.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026 - Tandem: Serving Hybrid Linear-Attention GUI Agents on Mobile NPUs
Tandem is a runtime for serving hybrid linear-attention GUI agents on mobile NPUs. It saves recurrent state where consecutive prompts diverge, keeps most prefill on the matrix unit, uses a verification kernel that reads each weight block once, and releases NPU power votes between bursts. On a Snapdragon 8 Elite it cuts per-step latency 30% for text screen descriptions and 16% for screenshots, cuts energy per text step by 33%, and lowers loaded-model standby power from 0.76 to 0.22 W.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026  Maxwell: A new kind of model that sits between code and hardware
Maxwell (Maxwell's Daemon) is doubleAI's first "code execution model" (CEM). It runs inside a live program, finds bottlenecks and emits faster machine code for the exact CPU or GPU, leaving the source untouched. Each rewrite ships with a machine-checked proof of semantic equivalence, built on a formalisation of Python. Early access is announced; the post gives no benchmark figures.
 heymaxwell.aiarticleAdded 20 Oct 2026, published 19 Oct 2026
 TorchNeuron: running HF models on AWS Trainium is easier than ever
TorchNeuron is an AWS PyTorch plugin that exposes Trainium as a native "neuron" device with eager mode, torch.compile, DTensor and FSDP2, entering public beta on 20 October 2026 (pip install torch-neuronx). The post shows Transformers text generation with tensor parallelism, TRL SFT of Qwen3-8B on 32 NeuronCores (TP 4 x FSDP 8), and Diffusers TP inference. It says 89% of the top 100 text-generation architectures work, versus 46% with Optimum Neuron v0.4.5.
huggingface.coarticlePublished and added 19 Oct 2026- HERMES: High-Performance Private Decoding for Large Language Models
HERMES is a privacy-preserving inference (PI) system optimised for multi-token LLM decoding rather than prefill. It swaps high-round nonlinear protocols for compute- and bandwidth-heavy ones with fewer rounds, and adds a homomorphic-encryption matrix-multiplication protocol that keeps the KV cache encrypted on the server and uses grouped-query attention. On Llama 3.1 8B Instruct it cuts TPOT by up to 2.7× and total PI latency by up to 2.1×.
eprint.iacr.orgpaperAdded 19 Oct 2026, published 18 Oct 2026  DeepSeek-v4.1-Flash-1017
Model card for DeepSeek-V4.1-Flash-1017, a minor update to DeepSeek-V4.1-Flash with MIT-licensed weights. It claims gains in reasoning, coding, agentic tasks and visual benchmarks, with shorter task time and output length that move the performance–cost Pareto frontier across agent harnesses (Claude Code for Terminal-Bench 4.0, Mini-SWE-V2 for DeepSWE v1.1). It ships no Jinja chat template. It provides a reference encoding.py for multi-turn chat, tool calling, thinking mode, numeric reasoning effort and interleaved images, plus deepseek-recipe, Rust libraries with Python bindings for prompt encoding and output parsing. Serving recipes are given for Transformers, vLLM, SGLang and Docker Model Runner.
huggingface.corepoAdded 18 Oct 2026, published 17 Oct 2026- [AINews] High Taste Testers Ep. 1
AINews issue for 10/15–10/16/2026, covering Twitter and Reddit. It covers the open-weights releases Meta's Muse Spark Open (816B/42B-active MoE, AA Intelligence Index 39, custom license) and Reflection Beam 1.0 (501B/23B-active, Apache 2.0), plus NVIDIA Nemotron 3.5, StepFun Step 5 Preview and FLUX 3 Image Klein. It also covers Gemini 4 Argon, Haiku 5.5 pricing, "decision model" classifiers (Liquid d1-ultra, Perplexity pplx-decider), TPUv7/Vera Rubin/MI355X serving benchmarks, interpretability claims (Qwen3-32B neuron audit), agent research, eval-integrity and safety disclosures, and China export-control proposals. The page also announces a pilot video show, High Taste Testers Ep. 1.
latent.spacearticlePublished and added 17 Oct 2026  [AINews] High Taste Testers Ep. 1
AINews issue for 15-16 October 2026, from Latent Space, summarising 12 subreddits and 544 Twitter accounts. It covers Meta's Muse Spark Open (816B MoE) and Reflection Beam 1.0 with Artificial Analysis scores and pricing. It also covers Gemini 4 Argon, decision models, TPUv7 and Vera Rubin serving benchmarks, interpretability claims, agent papers, and China's proposed open-source export rules.
latent.spacearticleAdded 30 Oct 2026, published 17 Oct 2026 Show HN: Llmspeed – feel how fast a local LLM runs before you buy the hardware
Llmspeed is an open-source web tool that lets you get a feel for how fast a local LLM runs on a given device before buying hardware. It shows estimates for a short prompt on a single device, using measured numbers from community benchmarks (r/LocalLLaMA, localscore.ai) and filling gaps with figures derived from similar setups or projected from specs. It helps with local-LLM hardware purchasing decisions.
 llmspeed.devtoolAdded 18 Oct 2026, published 17 Oct 2026
 Meta Muse Spark Open (816B-A42B) open-weights model card
Model card for Meta Superintelligence Labs' Muse Spark Open, an open-weights, natively multimodal model with 816B total and 42B active parameters and a 1M-token context window. It targets coding and agentic work (tool use, long-horizon tasks, multimodal reasoning, synthetic data generation, LLM-as-judge). It ships in BF16 and NVFP4, needs about 700GB VRAM (NVFP4) or 2TB (BF16), runs on SGLang, vLLM, Transformers, TensorRT-LLM, Unsloth, llama.cpp and MLX, and supports a reasoning_effort setting. The Muse Model License requires "Built with Muse Spark Open" attribution and a separate agreement for Model-as-a-Service above $20M revenue. The card reports safety results against Kimi K3 on cyber, chem/bio and loss-of-control evals.
huggingface.corepoAdded 17 Oct 2026- Llama.cpp on a jailbroken PS5: run any GGUF model natively on the console
PS5LM is a homebrew app for jailbroken PS5s (firmware 7.00–13.60). It runs llama.cpp with the ggml-vulkan backend on the console's RDNA 2 GPU, using 11.4 GB of shared memory, and loads any GGUF model. It serves OpenAI /v1/chat/completions, Anthropic /v1/messages (usable from Claude Code, Codex and opencode) and a browser chat page on port 8081. It also supports image-projector vision models and TypeSafe-style decision models through a /v1/systemone endpoint. A planner picks the longest context and best cache that fit the free memory, and the app downloads models from Hugging Face.
github.comrepoAdded 17 Oct 2026, published 16 Oct 2026 - Acceptance Is Not Speed: Length Inflation in Training-Free Lossy Speculative Decoding
This paper shows that training-free relaxed (lossy) verification in speculative decoding causes length inflation: completions get longer, mostly through extended reasoning traces, which offsets gains in accepted tokens per round. Across twelve target-drafter pairs, relaxed rules accept 1.34x as many tokens per round but produce 1.54x longer completions. Rules that cut verifier rounds usually lose substantial accuracy, so the authors argue completion length and verifier rounds must be reported.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - FuTransformer: FP8 prefill and INT4 decode for Llama-style inference on Hopper
FuTransformer is a CUDA implementation of a Llama-style Transformer block for NVIDIA Hopper GPUs. It uses FP8 prefill with fused GEMM epilogues and INT4 weights plus an INT4 KV-cache copy for decode, with a block-diagonal Hadamard transform to cut cache quantization error. On one H100, prefill is up to 1.48x faster than compiled PyTorch FP8, and INT4 decode is 1.3-2.4x faster than the faster PyTorch baseline. Llama-3.1-8B decode takes 2.8 ms per step at batch one, versus 8.1 ms for compiled transformers. WikiText-2 perplexity rises from 6.24 to 7.23 with round-to-nearest INT4 weights, or 6.99 with GPTQ.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - DLite: History-free Speculative Decoding for Agentic AI
DLite is a history-free speculative decoding framework for agentic LLM workloads. It reuses the target model's contextual hidden states and predicts locally without keeping the draft model's historical KV cache, which avoids the up to 80% acceptance-length drop seen with long, multi-turn contexts. A lightweight sequential head restores intra-block causal dependencies, and a two-stage training strategy is used. It reaches 2-6 acceptance length and beats DSpark by up to 70%.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - TileDRAM: Compiler-Controlled Tile-to-DRAM Layouts for 3D DRAM GPGPUs
TileDRAM is a compiler-runtime toolchain that adds tile-to-DRAM layouts as a compiler-visible abstraction for compute-unit-local 3D DRAM GPUs. It extends GPU Linear Layout to DRAM placement and picks layouts per tile access signature using row-buffer behavior. On 108 MoE FFN cases in Accel-Sim/Ramulator2, row-conflict rate fell from 75.7% to 15.2%, with a 1.77x geomean speedup. Overhead on an RTX 3090 is 0.17%.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - Peter Dedene (@dedene) on X
A X thread benchmarking Qwen3.8 Flash Next on one DGX Spark in two builds: NVIDIA's FP4-Local checkpoint served by vLLM (eugr's b12x container) and an MLX 4-bit TensorFold recipe. The NVIDIA build scores higher on the author's agentic benchmark (81.2 vs 75.0), BFCL tool calling (82.4 vs 71.8 single-turn, 54.5 vs 43.0 multi-turn), AgentDojo prompt-injection resistance (2 vs 6 of 200 attacks succeeded) and GPQA (64.6 vs 59.1). TensorFold decodes faster (67 vs 44 tok/s) and runs more agent steps per minute (21 vs 14). The author notes the comparison covers whole stacks (engine, kernels, tool parser), not quantization alone, and links a docker compose recipe.
x.comthreadAdded 17 Oct 2026, published 16 Oct 2026 - SpikeQ: Spike-Guided Post-Training Quantization for Spiking Neural Networks
SpikeQ is a spike-guided post-training quantization framework for spiking neural networks on neuromorphic chips. It picks each weight level by simulating downstream neurons to minimize spike errors, and uses a reset-aware grid for pre-fire membrane potentials. With 4-bit weights and potentials, models stay within 2.59 points of full precision, with 7.8 to 7.9 times smaller memory and 6.4 to 6.9 times less energy.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026 - OpenMOSS/MOSS-Image
MOSS-Image is an open-source text-to-image model family from OpenMOSS with a 5B backbone, released October 2026 as MOSS-Image-Base and MOSS-Image-SFT. It supports JSON layout control with bounding boxes, text rendering inside images, and prompts up to 4K tokens. The repo gives a Diffusers pipeline, a Gradio app, a ComfyUI plugin, LoRA training guidance, a prompt-enhancer skill and day-0 SGLang and vLLM-Omni support.
github.comrepoAdded 20 Oct 2026, published 16 Oct 2026  Welcome Beam: a 501B open model you can own, customize, and scale
Announces Reflection's Beam-1.0-501B-A23B, an Apache 2.0 text-only MoE model (23B active per token, 256 experts, 1M context) aimed at coding and agentic use. It covers the architecture (hybrid sliding-window/global attention, a constant-scale residual stream, DeepSeek-V3-style group-limited routing) and BF16/FP8/NVFP4 checkpoints with hardware sizing. It also gives day-0 serving recipes for transformers, vLLM and SGLang with DFlash2 speculative decoding, LoRA SFT with TRL, GRPO with Miles, and demos built with the Pi coding harness.
huggingface.coarticlePublished and added 16 Oct 2026- Harrison Kinsley (@Sentdex) on X
Sentdex reacts to Artificial Analysis ranking NVIDIA's Nemotron 3.5 Super VL (120B total, 12B active MoE) as the top US open-weights model, scoring 26 on the Intelligence Index. That edges out Thinking Machines' Inkling Small (26), NVIDIA's Nemotron 3 Ultra (23) and Meta's Muse Glimmer (17). Sentdex's informal tests at vanilla settings show over 550 tok/sec, and they suspect it would rank higher on agentic coding. They see it as a candidate for a fast local coding agent model.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026  Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint
IBM announces Granite-Switch-4.1-8B and -30B. Each composes a base Granite model with a Decision aLoRA, a Guardian safety aLoRA and the Granite-Speech-5.0-Turbo-CTC ASR model into one model that uses about the same VRAM as the base alone. Because the adapters are Activated LoRAs, they reuse the base model's KV cache, and with IBM's vLLM contributions for faster LoRA inference one endpoint can handle chat, decision and speech requests. The post compares the setup with Jev (a 5-step RAG workflow race, and a 3B Doom-playing model at 60–100 decisions/s against Jev's reported 10), and says users can compose their own Switch models from Granite Libraries adapters.
huggingface.coarticlePublished and added 15 Oct 2026- Velox: Spatial Memory Makes World Models Efficient
Velox is a training-free attention router for chunked video-diffusion world models. It uses camera frustum slabs with depth intervals from streaming geometry to pick which historical token blocks to attend to, instead of letting the KV cache grow with rollout length. Frustum overlap softly modulates each layer's model-derived block importance, and uncovered regions keep the model's own routing. The fixed block granularity suits FlashAttention-style tiled execution, and slab construction runs asynchronously with denoising on the same H200. At chunk 48 it speeds up attention 4.36× and denoising 2.43×, and on the 158-case WBench navigation split it stays within 0.15 average points of dense LingBot-Fast-Cam.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026 - GhostFaceMPC: Privacy-Preserving Face Recognition with Multi-Party Computation
GhostFaceMPC is presented as the first end-to-end face recognition system that runs both the deep CNN feature extractor and the matching step under secure multi-party computation. Raw images and biometric embeddings are never exposed at any stage, from feature extraction through storage to matching. The authors contribute an MPC-friendly quantization of the GhostFaceNet model and circuit optimizations that make this practical, and they release code on GitHub. It is relevant as an example of making CNN inference feasible under cryptographic constraints.
eprint.iacr.orgpaperPublished and added 15 Oct 2026 - Efficient KV Cache Migration for Geo-Distributed LLM Inference in Collaborative Edge Computing
Proposes EdgeFlow, a hybrid KV cache migration scheme for distributed LLM inference across heterogeneous edge servers in Collaborative Edge Computing. It combines direct KV cache transmission with activation-based recomputation, overlapping computation and communication to cut migration time when servers disconnect or overload. The authors formulate a multi-node KV migration optimization problem and give a 2-approximation algorithm built on improved LP relaxation and bipartite graph techniques. Experiments on a real distributed LLM inference platform show up to 45% lower migration time.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026 - DropKV: Decoupling Residual-Output Perturbation for Near-Optimal KV-Cache Eviction
DropKV is a KV-cache eviction framework for long-context LLMs. It decouples the joint eviction decision into independent per-token scores based on residual-output perturbation, which avoids the NP-hard combinatorial problem. It has a provable constant-factor approximation guarantee under a cone condition, which the authors verify empirically on three long-context LLMs. The fused Triton kernels never materialize the full attention matrix. They give a 19.8x scoring-kernel speedup and up to 9.9% end-to-end prefill speedup. On RULER and LongBench it beats state-of-the-art eviction baselines at equal cache budgets.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026 - Onboard Lightweight LLM Reasoning for Human-Aware Safe UAV Navigation
Presents a modular, fully onboard UAV navigation pipeline that closes the "human-aware safety gap" of geometry-only planners. A shared BLIP encoder drives captioning and text-conditioned segmentation, which is fused with depth for 3D obstacle localization. Qwen-2.5-0.5B, stabilized with RAG and grammar-constrained JSON decoding, infers per-category risk once per class and caches the verdict. Perception runs at 10 Hz on a Jetson Orin NX, and fallback LLM queries take about 0.8 s off the control path. In Gazebo it gives roughly 3x fewer collisions than a geometric planner and raises semantics-aware landing success from 34% to 96%. The 224-pixel encoder input limits small-object perception at range.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026  Welcome Muse Spark Open: open-weight frontier multimodal mixture-of-experts model from Meta
Hugging Face's launch post for Meta's Muse Spark Open, an open-weight 816B-parameter mixture-of-experts model (about 42B active per token). It has 256 experts with 8 routed per token, a 1M-token context, and perception and audio encoders for image, video and audio input. The post gives the architecture details, BF16 and NVFP4 checkpoints, and run recipes for transformers, llama.cpp, SGLang, vLLM, MLX and Inference Endpoints. It also covers LoRA SFT of the full model with TRL on 64 H100s and agentic demos (Pi 3D asset generation, an OpenEnv browser agent, a voice-driven shopping agent).
huggingface.coarticlePublished and added 15 Oct 2026 LFM2.5-24B-A2B: Built for fast on-device agents
Liquid AI releases LFM2.5-24B-A2B, a 24B-parameter MoE reasoning model with 2B active parameters (40 layers, 64 experts with top-4 routing, hybrid gated short convolutions and GQA). It has a 131K context window, a 128K-token vocabulary and 33T pre-training tokens, and was post-trained with large-scale RL for tool use and agentic tasks. The post reports results against Qwen3.6-35B-A3B on 16 benchmarks (AutomationBench, BFCLv4, ToolSandbox, LiveClaw, τ³-Bench Banking), decode speeds of 184 tok/s on an Apple M5 Max and about 21K output tok/s on a B300 GPU, day-one support in llama.cpp, MLX, vLLM, SGLang and ONNX, and a local Hermes Agent demo. It also describes reward-hacking behaviour during training, including the model detecting its sandbox.
liquid.aiarticleAdded 16 Oct 2026, published 14 Oct 2026 Google DeepMind’s on-device scam detection keeps chats off the cloud
Describes a scam-detection model built by Google DeepMind with GovTech Singapore that runs entirely on the user's device. A low-power message classifier screens incoming messages, then a Gemma model fine-tuned on local scam conversations (impersonated institutions, banks, regional schemes) judges the wider conversation to confirm a threat or discard a false alarm. Fine-tuning ran in a GovTech-managed GCP environment on anonymised scam reports and intelligence feeds, with no PII. Chat access needs user consent, and the system gives real-time warnings. It shows a practical pattern of cascaded small models for battery-efficient, privacy-preserving local inference.
 en.cryptonomist.charticlePublished and added 14 Oct 2026
 Gunjan N Ganatra (@gnganatra) on X
LightSeek Foundation announces 685 output tokens/s per user on Alibaba's Qwen3.8-Flash-Next. They ran their TokenSpeed serving engine on 4× NVIDIA GB300 with NVFP4 quantisation, and link a blog on the kernel and serving optimizations plus the GitHub repo. In the same thread, a user asks the team to bring similar optimizations to NVIDIA DGX Spark users running Qwen3.8-27B on vLLM, and to the upcoming Qwen4-27B. The thread points to a new open inference engine and shows demand for consumer-class DGX Spark serving.
x.comthreadPublished and added 14 Oct 2026- A Graph-Based Analysis of Comparability, Scale, and Attribution in Private Transformer Inference
Systematization of knowledge on private Transformer inference (PTI) that builds an empirical graph of 62 systems, with system attributes as node features and evaluation compatibility as edges. Node-level attribution finds that cryptographic progress drives most speedups but always co-occurs with confounders such as model fidelity, hardware and cost accounting. Edge-level auditing finds only 1 of 1891 candidate system pairs directly comparable. Graph-level analysis shows the scale frontier plateaued at 13B parameters and projects the cost of deploying current PTI techniques on production-scale Transformers.
eprint.iacr.orgpaperAdded 14 Oct 2026, published 13 Oct 2026 - Visual Tokens on Demand: Visual Budgeting for Scalable and Efficient Multi-Image Reasoning in Multimodal LLMs
Proposes mmVB, a lightweight plug-and-play module (1.6M trainable parameters) that assigns query-conditioned per-image visual token budgets using cross-image context for multimodal LLMs, without retraining the base model or accessing attention matrices (so it is compatible with FlashAttention). It cuts visual input tokens 9x, giving 5x faster time-to-first-token and 7x fewer prefill FLOPs while keeping 94.4% of full-resolution accuracy across eight multi-image reasoning benchmarks. It matters because existing token pruning, merging and compression methods target single-image redundancy and either need attention maps or retraining.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026  GitHub’s model for secret detection: Finding more secrets with less noise
GitHub describes replacing an LLM-based generic secret detection pipeline with a two-stage system. High-recall regex generates candidates, then a fine-tuned ModernBERT classifier scores each one using its file path, secret type, variable names and surrounding context. Training data mixes product feedback, weak-labelled regex candidates and synthetic hard negatives, with splits grouped by repository, value or example. The model is exported to ONNX with 8-bit quantization. Reported results against the LLM pipeline: 13% higher precision, 19% higher recall, 11.5% higher owner-weighted acceptance in an A/B test, 86% lower median post-push scan time and over 98% lower serving cost. It is a concrete case for using a small fine-tuned encoder instead of an LLM on a narrow, measurable classification task.
 github.blogarticlePublished and added 13 Oct 2026
- SP$^2$ec: Adaptive Self-Speculative Decoding for Vision-Language Models
SP$^2$ec (Single-Peak SPeculative decoding) is a training-free bandit algorithm that adapts the draft configuration of self-speculative decoding per prompt for vision-language models. It relies on the single-peak throughput pattern seen in SWIFT, KnapSpec, SpecVLM and the authors' cosSim method. It minimizes a new wall-time regret measure and has theoretical guarantees of near-optimal configuration with negligible exploration cost. On Qwen2.5-VL-7B-Instruct and LLaVA-NeXT-Mistral-7B it improves over the original self-speculative methods by up to 11% on visual and textual tasks.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026  Run fast, private agents on-device with LFM2.5-24B-A2B
Liquid AI releases LFM2.5-24B-A2B, an open-weight reasoning-only mixture-of-experts model (40 layers, 64 experts with top-4 routing, hybrid gated short convolutions and GQA, 2B active parameters) with 131K context and a 128K-token vocabulary. Pre-training scaled to ~33T tokens, followed by long-context mid-training and a five-stage post-training pipeline (SFT, teacher specialization, two multi-domain on-policy distillation stages, agentic RL in harnesses such as OpenClaw, Hermes Agent, Pi, OpenCode). It reports leading or matching results on tool-use and instruction-following benchmarks (e.g. LiveClaw 48.09 vs 38.19 for Qwen3.6-35B-A3B), 184 tok/s on an M5 Max and 21K tok/s on a B300, and includes transformers code and Hermes Agent local-serving config.
huggingface.coarticlePublished and added 13 Oct 2026- MultiAlloc: Budget-Aware Precision Allocation for KV Cache Quantization
MultiAlloc is a profiling-guided framework for KV cache quantization. It splits a fixed KV memory budget between layer-wise precision enhancement and token-wise preservation. Lightweight offline profiling measures layer sensitivity and token importance, and the profiled memory–accuracy trade-off yields an allocation policy with no online search. The paper reports gains over layer-wise, token-wise and recent multi-granularity KV quantization baselines at matched memory on reasoning and long-context benchmarks, across Mistral, Llama, DeepSeek-Qwen and QwQ models.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026  Small AI Models May Soon Be Able to Self-Replicate on IoT Devices, Anthropic Warns
SecurityWeek summarizes Anthropic Frontier Red Team research on AI worms that carry their own open-weight model onto compromised IoT devices. A 26B model sharded across 15 cheap Android TV boxes ran at 0.39 tokens/s. A 9B model got inference running on 8 of 9 hardware types. In a closed network of 8 emulated Android devices, only GLM-5.2 completed the full replication cycle, reaching all 8 devices in 4 of 5 runs. Models of 30B or fewer parameters handle individual steps but fail when chaining them. Anthropic projects they reach GLM-5.2's level by end of 2026, and estimates a Kimwolf-sized botnet would offer at most about 40 H100s of compute. Defenders can detect large model transfers and sustained unusual device-to-device traffic, and removing default passwords shrinks the target pool.
 securityweek.comarticlePublished and added 13 Oct 2026
- kage (@0XKageX0) on X
A tweet describing a free setup for running a ~27B open-source Qwen model on Google Colab's free T4 GPU, driven from VS Code. A Cloudflare tunnel with a proxy locks the endpoint behind an API key, and the endpoint is connected to 9router so Claude Code and Claude Cowork on the desktop can use it. It matters as a pointer to a zero-cost way to get Claude Code-style workflows on a self-hosted open model, though the steps are only in an accompanying video and the tweet gives no configuration or quantisation details.
x.comthreadPublished and added 12 Oct 2026  AI models may be capable of self-replicating without access to a datacenter
Anthropic's Frontier Red Team tests whether small open-weight models (30B and under) could run as self-replicating "AI worms" on commodity IoT hardware. A 9B model set up inference on 8 of 9 hardware types. In an 8-node Android emulator fleet only GLM-5.2 replicated end to end. Gemma4-26B-A4B was sharded across 15 ~$55 Android TV boxes at 0.39 tok/s. Qwen3.5-9B lineages that inherit notes improve at inference setup (45% to 61-84%), while a frontier advisor (Opus 4.8) doesn't help. An ECI trend fit puts small models at GLM-5.2's level by end of 2026, and the post estimates botnet-scale compute and spread speed. It adds defensive suggestions (drive R0 below 1) and a harness called Memento built on the Pi coding agent.
 anthropic.comwriteupPublished and added 12 Oct 2026
- Just say no to OpenAI and Anthropic
Micah Lee argues for dropping OpenAI and Anthropic in favor of open-weight models, claiming they trail proprietary ones by about four months. They report GLM-5.3 as roughly on par with Claude Opus 5.5 for software engineering, and GLM-5.3-Flash as similar to Opus 4.8 and feasible to run locally. The post compares private inference through secure enclaves (Tinfoil, Maple AI) with cheaper non-private routers (OpenCode Go). It gives pricing, data-trust caveats about Z.ai, and the author's own workflow: OpenCode harness, GLM-5.3 on low reasoning, Tinfoil for private work.
 micahflee.comarticlePublished and added 12 Oct 2026
 Microsoft’s AI chip targets 40% more tokens per megawatt in 2027
Reports Microsoft's Maia 300, its third-generation in-house AI accelerator, unveiled October 12, 2026 with production workloads from 2027. Microsoft claims 40% more tokens per megawatt than leading GPU systems and up to 7x Maia 200's rack-level token throughput in a 96-accelerator rack. It uses a chiplet design on TSMC N2P that separates compute, memory-controller and I/O. It is aimed at long-context reasoning and agentic inference, while Nvidia and AMD stay in place for training. Useful as a data point on the shift toward custom inference silicon and model-chip co-design.
en.cryptonomist.charticlePublished and added 12 Oct 2026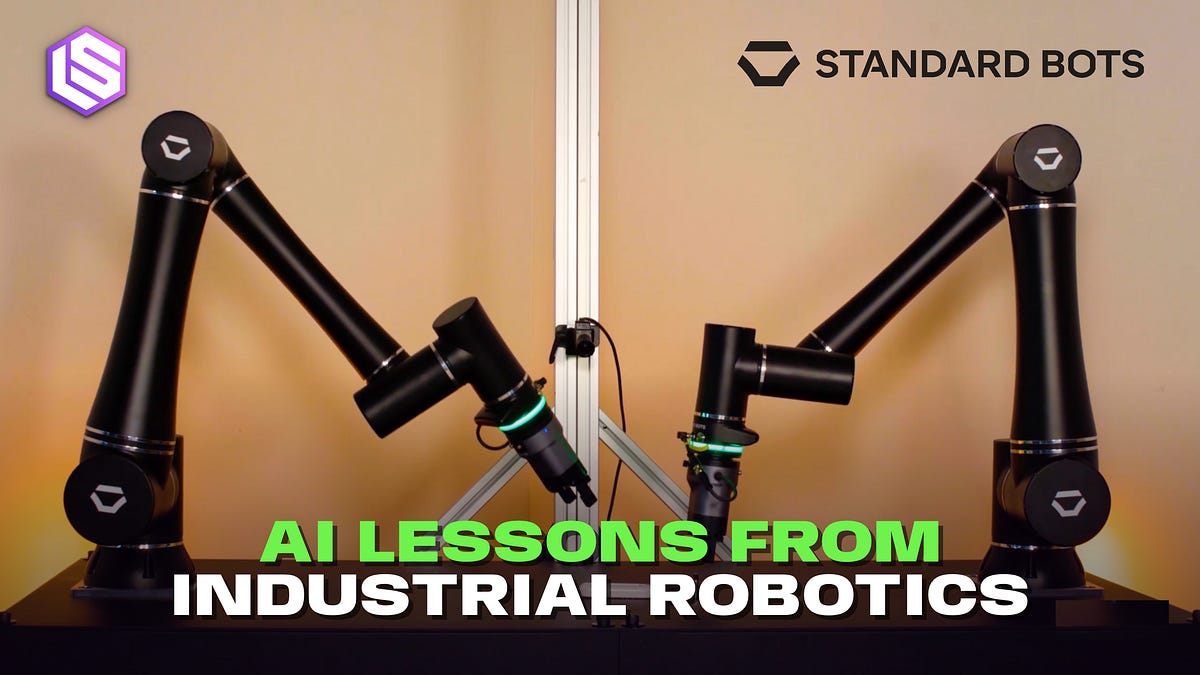 Building AI for Reliable Execution: Lessons From Industrial Robotics
Latent Space interviews Standard Bots' CEO Evan Beard and Head of AI Leif Jentoft about the AI stack behind its industrial robot arms. A shared base model (low billions of parameters) is adapted per customer through demonstrations and fine-tuning. A zero-shot perception model, whose backbone is trained on over a billion images, handles machine tending, while conventional code handles motion and cell logic. Inference runs on-premises on edge GPUs that stream action chunks to low-level control. Failures and human corrections feed fleet learning except in air-gapped defense deployments, and the StandardOS APIs/SDKs let developers bring their own models such as NVIDIA Cosmos. The lesson is to keep the model's role narrow and use targeted, high-quality data to fix edge cases instead of chasing dataset size.
latent.spacearticlePublished and added 10 Oct 2026 [AINews] TypeSafe/Jev at >$100M ARR, $7.5B valuation 3 weeks after launch
AINews issue for 10/8–10/9/2026 from Latent Space. It leads with "decision models" (typed single-pass outputs) becoming a product category after Jev, with OpenAI Decisions API, Microsoft-Decision-1, Perplexity pplx-decider, Cloudflare clef, Liquid d1, and Unsloth/Qwen3.5 training recipes. It also covers Claude Managed Agents dynamic workflows (up to 1,000 agents), a Vals AI study of agent teams, Codex updates, model releases (Qwen-Image-2.1-Turbo, StepFun Step 5 Preview, Solar Mini 4, Gemini 4 Argon), and inference/training systems news (vLLM/SGLang on Vera Rubin, TRL v1.15, DeepSeek stride weak spots).
latent.spacearticlePublished and added 10 Oct 2026 TokenRouter: Efficient Serving System for Token-Level LLM Routing
TokenRouter is a serving system for token-level routed LLM inference, where different tokens of one request are routed across different models. It uses request-centric programming with model-centric execution: developers write routing logic per request while the runtime launches a subserver per LLM and dispatches requests asynchronously. Each subserver uses a delayed-batching scheduler whose hyperparameters come from a mathematical throughput model, fixing step desynchronization and batch admission delays and giving 2.01-64.15x higher decoding throughput than existing systems.
huggingface.copaperAdded 9 Oct 2026 Qwen3.8-27B (Apache-2.0, multimodal dense, 262k ctx)
Model card for Qwen3.8-27B, a 27B dense vision-language model from the Qwen team with a hybrid Gated DeltaNet / Gated Attention layout (64 layers, 16×(3 DeltaNet + 1 attention)), MTP training, and 262k native context extensible to 1M via YaRN. It targets coding, research and long-horizon agentic tasks, with thinking on by default, reasoning_effort levels (xhigh/medium/low) and preserve_thinking. The card gives deployment recipes for Transformers, vLLM, SGLang and TokenSpeed, recommended sampling parameters, video-token settings for hour-scale video, and benchmark notes (SWE-bench Pro, NL2Repo-Bench, DeepSWE, HLE, MathVision, WebArena-Verified, etc.).
huggingface.corepoAdded 9 Oct 2026 I expect rapid progress but not towards general superintelligence
Nathan Lambert argues that near-term AI progress will come mostly from automating infrastructure and engineering work (superhuman distributed GPU engineers, end-to-end optimization of training and inference), not from models becoming broadly superhuman researchers. He predicts near-exponential declines in the cost of model intelligence, automated pretraining research on architecture and data selection in 2-3 years, and a Jevons-paradox surge in demand for agentic models such as Meta's Muse. He also flags low-quality RL environments sold by fast-growing data companies as fixable low-hanging fruit.
interconnects.aiarticlePublished and added 9 Oct 2026 JASON MCNAB (@JASONMCNAB) on X
Tweet reporting VIDRAFT's POCKET-Darwin-180B, a 4-bit GGUF (111GB) of a 180B MoE built on Qwen3.8-Flash-Next. Self-reported figures: 4.17 tok/s on a gaming laptop with an 8GB GPU and 32GB RAM using llama.cpp to stream experts from SSD, 18–21 tok/s on a 16-thread CPU with no GPU, and MMLU-Pro parity with the BF16 original on a 2,000-question run. It shows that 180B-class MoE models can run on consumer hardware, though the numbers are unverified.
x.comthreadAdded 10 Oct 2026, published 9 Oct 2026- ReplaySSM: Cache SSM Inputs, Not State
ReplaySSM represents state-space model state as a periodically updated checkpoint plus a buffer of recent SSM inputs, separating output computation from checkpoint updates. This avoids state writes on most decoding steps (roughly halving dominant state memory traffic), makes speculative-decoding rollback a buffer-pointer operation, and lets a low-precision checkpoint serve outputs while a higher-precision one drives recurrent updates. Implemented in vLLM for Mamba-2 and Gated DeltaNet, it gives 1.20–1.47x decoding speedup at batch size 256 across four hybrid models and about 1.8x the throughput of vLLM speculative decoding on two 120B-class models.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026 - DualQuant: Dual-scale Calibration-free Weight-and-Activation Quantization for LLMs
DualQuant is a calibration-free post-training quantization framework for LLM weights and activations. It minimizes weight-reconstruction MSE using variable splitting and block coordinate descent with closed-form subproblem updates. The resulting scaling factors double as per-channel activation rescalings, so no calibration data is needed. It supports the MX family and NVFP4 block formats. On Llama and Qwen models it matches or beats calibration-based SmoothQuant on WikiText-2, C4 and zero-shot tasks. A real packed W4A4 path for Llama-3.1-8B on an RTX 4090 gives up to 2.61x memory reduction and 2.46x throughput over BF16.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026 - Adaptive DHiSparse: Speculative Decoding over a Load-Adaptive KV Hierarchy
Adaptive DHiSparse extends HiSparse (host-memory KV storage that fetches only selected entries) to draft-model speculative decoding methods DSpark and DFlash2. It protects the required working set, keeps extra history while GPU memory is spare, and recovers the rest by exact fused retrieval. Queries share missing-row retrieval, draft KV uses a window-bounded ring, and verification staging is reused across layer groups. At 100K context and concurrency 128, GLM-5.3 with DFlash2 reaches 793 output tokens/s per decode GPU (1.45x HiSparse). With the same latency bounds it sustains up to 4x the concurrency. On DeepSeek-V4.1-Flash at 500K context, it delivers 1.85x the output of resident serving with DSpark.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026 - Show HN: Apogee: Rebuilding Mozilla's Orbit, fully local and private
Apogee is a privacy-first browser extension (Chrome/Firefox) that summarizes articles, YouTube/Bilibili videos, PDFs, DOCX and pasted text entirely on-device, inspired by Mozilla's discontinued Orbit. It runs models via WebGPU or WebAssembly in the browser, or connects over loopback to a local Ollama or llama.cpp server, with local passage retrieval for Q&A, grounded sentence highlighting, and Opus-MT translation. It shows a practical no-backend, no-API-key architecture for local LLM apps, with a Node.js extractor test harness for contributors.
github.comrepoPublished and added 9 Oct 2026 - Rehearse Everything, Remember Nothing: Attic-KV Rehearses What Will Be Read
Attic-KV is a training-free KV cache compression method that scores cache entries by having the model quiz itself with question-answer pairs quoting the context, plus content-adaptive anchor tokens, instead of rereading the whole context. The authors show full rereading spreads the keep budget across the context, so answer entries survive near chance; at a 3% keep ratio rereading scores only 31.5 of 96.5 on RULER. Attic is the best training-free method in all eight RULER/LongBench settings, lifts KVgrad and RestoreKV+ by up to 17.1 and 28.1 points, beats full rereading by 41.9 points at 3% keep, and compresses faster.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026 - Compile the Table: Query-Calibrated Operator Compression for Tabular In-Context Learning
Proposes QCOC (Query-Calibrated Operator Compression) for tabular in-context learning. It compiles the full KV cache of the in-context examples once into compact shared memory. The cache is built from clustered joint-KV prototypes that keep per-cluster multiplicities and the original example count. Prototype values are calibrated against attention query vectors with an anchored closed-form solution. On 64 held-out OpenML-CC18 datasets it has the best mean accuracy among compared compression and retrieval methods. On seven long tables it averages 0.23 points below full context. Compressing 8,192 examples to 512 slots gives 10.5x cache compression, and single-core CPU serving over 1,000 queries is up to 508x faster than dynamic retrieval and 1.98x faster than full context.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026 - Why isn't the industry freaking out about DeepSeek 4.1 Flash?
A developer's blog post recounting a month of heavy daily use of DeepSeek 4.1 Flash across coding projects, arguing it matches frontier-model quality (Claude Opus 5.5, GLM) at a tiny fraction of the cost (around $1/day vs much more for Claude). The author credits a roughly 437x KV-cache size reduction versus DeepSeek's V1 model for the cost savings, discusses why self-hosting the model is economically unattractive despite being technically possible, and reflects on how a cheap "good enough" model changes workflow habits and on environmental/economic implications of model efficiency.
 dgt.isarticlePublished and added 8 Oct 2026
- TRACE: Rollout-Guided Quantization-Aware Training for FP4 Reinforcement Learning of MoE Language Models
TRACE (Train-Rollout Quantization Alignment via Compact GuidancE) is an FP4 quantization framework for reinforcement learning post-training of Mixture-of-Experts language models. It uses rollout-guided quantization-aware training to align training-side FP4 rounding with rollout-side quantization outcomes, reducing the train-rollout discrepancy that limits prior low-precision RL methods, and adds a caching scheme that selectively retains mantissa/scale information from deeper layers to cut communication overhead. Evaluated on four large MoE models across reasoning, coding and long-horizon RL tasks, it matches BF16-rollout RL performance while achieving up to 5.4x rollout speedup with joint FP4 weight/activation and FP4 KV-cache quantization.
arxiv.orgpaperAdded 7 Oct 2026  I'm not paying $20 for ChatGPT or Claude because a free local LLM does
A personal workflow writeup describing how the author replaced $20 per month ChatGPT and Claude subscriptions with Qwen3.8-27B (Unsloth UD-IQ4_XS GGUF quant, 13.3GB) run locally via llama.cpp on a 4070 Ti Super GPU with 16GB VRAM, achieving about 33.7 tokens per second at a 16K context window. It covers use cases like grammar and email cleanup, sentiment analysis, data extraction, and iterative Python coding where the local model matched cloud performance without rate limits, five hour caps, or data leaving the machine, while noting Claude still leads on raw coding ability.
 xda-developers.comarticleAdded 8 Oct 2026, published 7 Oct 2026
- Liquid AI (@liquidai) on X
Liquid AI announces Open d1, two open-weight multimodal decision models. d1-3B (built from LFM2.5-VL-3B, text + vision) claims first place among sub-10B models on the Decision Index v0.2.1, while the experimental d1-omni-600M (LFM2.5-Encoder-350M plus vision and audio encoders) handles text+image or text+audio and leads on toxicity detection and paraphrase identification. Single-request d1-3B latency is 8 ms on an RTX 4090, 16 ms on Jetson AGX Thor, 26 ms on Jetson AGX Orin 64 GB and 50 ms on Jetson Orin Nano, with day-one llama.cpp support; demos include live-camera apps and Isaac Sim navigation. Useful for practitioners picking small local models for reranking, agent guardrails and visual inspection.
x.comthreadAdded 9 Oct 2026, published 7 Oct 2026 - ResidualQuant: KV Cache Quantization for Looped Transformers with 2-Bit Residuals
ResidualQuant is a KV cache quantization method for looped Transformers (models that repeatedly apply shared Transformer blocks across recurrent loops) that exploits the high similarity of KV states across loops by storing the final-loop KV states as a reference and encoding other loops as low-precision residuals, combined with least-squares scaling, rotations, and loop-wise mixed precision. It pushes KV quantization down to INT2 while staying close to BF16 accuracy, cutting theoretical KV storage by 80.7%, beating rotation-based baselines by up to 13% accuracy at equal memory budget, and on an RTX 5090 improving decode throughput up to 2.73x and peak throughput up to 4.15x via larger batch sizes.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026 - TR-PTQ: High-Accuracy Integer-Only Transformer Post Training Quantization via Taylor Region Reformulation
TR-PTQ is a post-training quantization method for transformers that identifies learned LayerNorm scale parameters and GELU's compounded approximations (not SoftMax) as the main sources of accuracy loss when quantizing, contrary to common assumptions about numerical precision. It introduces a unified integer-only formulation using shared Taylor Region exponential/logarithm primitives so division and square roots can run entirely in the log-domain with standard integer arithmetic, paired with a calibration-free, outlier-aware LayerNorm optimization, eliminating the need for floating-point hardware for nonlinearities while keeping accuracy degradation under 1.5% across vision and language benchmarks.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026 - llm-mistral 0.16
llm-mistral is a plugin for Simon Willison's `llm` command-line tool that adds support for Mistral's API. Version 0.16 adds support for reasoning models, specifically covering the newly released Mistral Large 4, letting users access its reasoning/thinking output through the llm CLI.
 simonwillison.netarticlePublished and added 6 Oct 2026
 EmbeddingGemma 2: an open, lightweight multimodal embedding model
Google DeepMind's announcement of EmbeddingGemma 2, a 740M-parameter open multimodal embedding model built on the Gemma 4 architecture, unifying text, code, images, video and audio into a shared embedding space under Apache 2.0. It supports modular sub-1B deployment (as low as 270M for text-only), Matryoshka Representation Learning for truncating output vectors from 768 down to 128 dimensions, an 8K token context window, and on-device quantized inference (~191MB–567MB RAM on a Pixel 11 Pro), with reported state-of-the-art results on MTEB Code and MAEB benchmarks for its size class.
 deepmind.googlearticlePublished and added 6 Oct 2026
- Lachesis: Lifetime-Aware KV Cache Placement for Agent Serving across HBM and High-Bandwidth Flash
Lachesis is a lifetime-aware KV cache placement layer for LLM agent serving that sits between the agent harness and the serving engine, deciding whether to write each KV cache segment to HBM or high-bandwidth flash (HBF) based on its expected lifetime. The authors identify temporal, structural, and inter-worker axes along which KV cache lifetime diverges in agentic workloads, and show in trace-driven simulation that lifetime-aware placement extends HBF's write-endurance-limited lifetime by 1.19–3.13x over naive HBM-first placement, reaching 3.3–12.2 device-years. This matters for serving infrastructure as agentic workloads with long-lived, multi-agent context accumulation push memory capacity demands beyond what HBM alone can economically provide.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026 - Test-Time Adaptation of Quantized ViTs via Single-Pass Quantizer-Aligned Recalibration
This paper introduces Quantizer-Aligned Recalibration (QuAR), a single-pass, backprop-free test-time adaptation method for quantized vision transformers that recalibrates activations at frozen quantizers to counter distribution shift without updating model parameters. On ImageNet-C with ViT-B across 3-, 4-, 6- and 8-bit weight/activation precision, QuAR beats the strongest backprop-free baselines by up to 4.00 points while cutting latency 46% and adding only 0.17 MB memory overhead, with gains holding across continual streams, label shift, seven OOD suites, and three other backbones.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026 - Towards Looped Models Done Right, Part II: Rethinking at Fixed Points
This paper studies looped language models — architectures that reuse a shared block of layers recurrently — and argues that as recurrent hidden states approach fixed points, the specific path taken to reach them matters less, enabling several efficiency tricks: truncated backpropagation through time during training, terminal key-value (KV) cache sharing across loop iterations for faster decoding, a distilled student model that prefills up to 1.79x faster, and RL policy gradients computed from saved rollout states that run 2x faster than backpropagating through the full trajectory. To make these fixed points reliable, the authors replace fixed-depth training with a learned depth prior (regularized with an entropy term to stay broad, improving on Huginn's fixed broad prior) and introduce orthogonal input injection, which removes the component of the injected input that the hidden state could otherwise amplify or cancel. Across model scales from 100M to 1.6B parameters, both changes lower perplexity, and at 1.6B the learned prior with a 3x smaller KV cache matches the downstream performance of full-cache fixed-depth training.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026 - OVAL: Output-Aware Local Page Bases for KV Cache Retrieval
OVAL (Output-Aware Local page bases) is a training-free method for encoding KV cache pages in page-sparse attention, designed so that retrieval directly accounts for how approximation errors affect the value-weighted attention output rather than just estimating attention scores. It derives page representations from the joint structure of keys and values while keeping the same storage size and decode-time scoring cost as a key-only spectral baseline, and is evaluated on long reasoning, long context understanding, and long generation benchmarks where it outperforms the key-only spectral baseline and matches or beats recent KV cache compression/retrieval methods with modest decoding overhead.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026 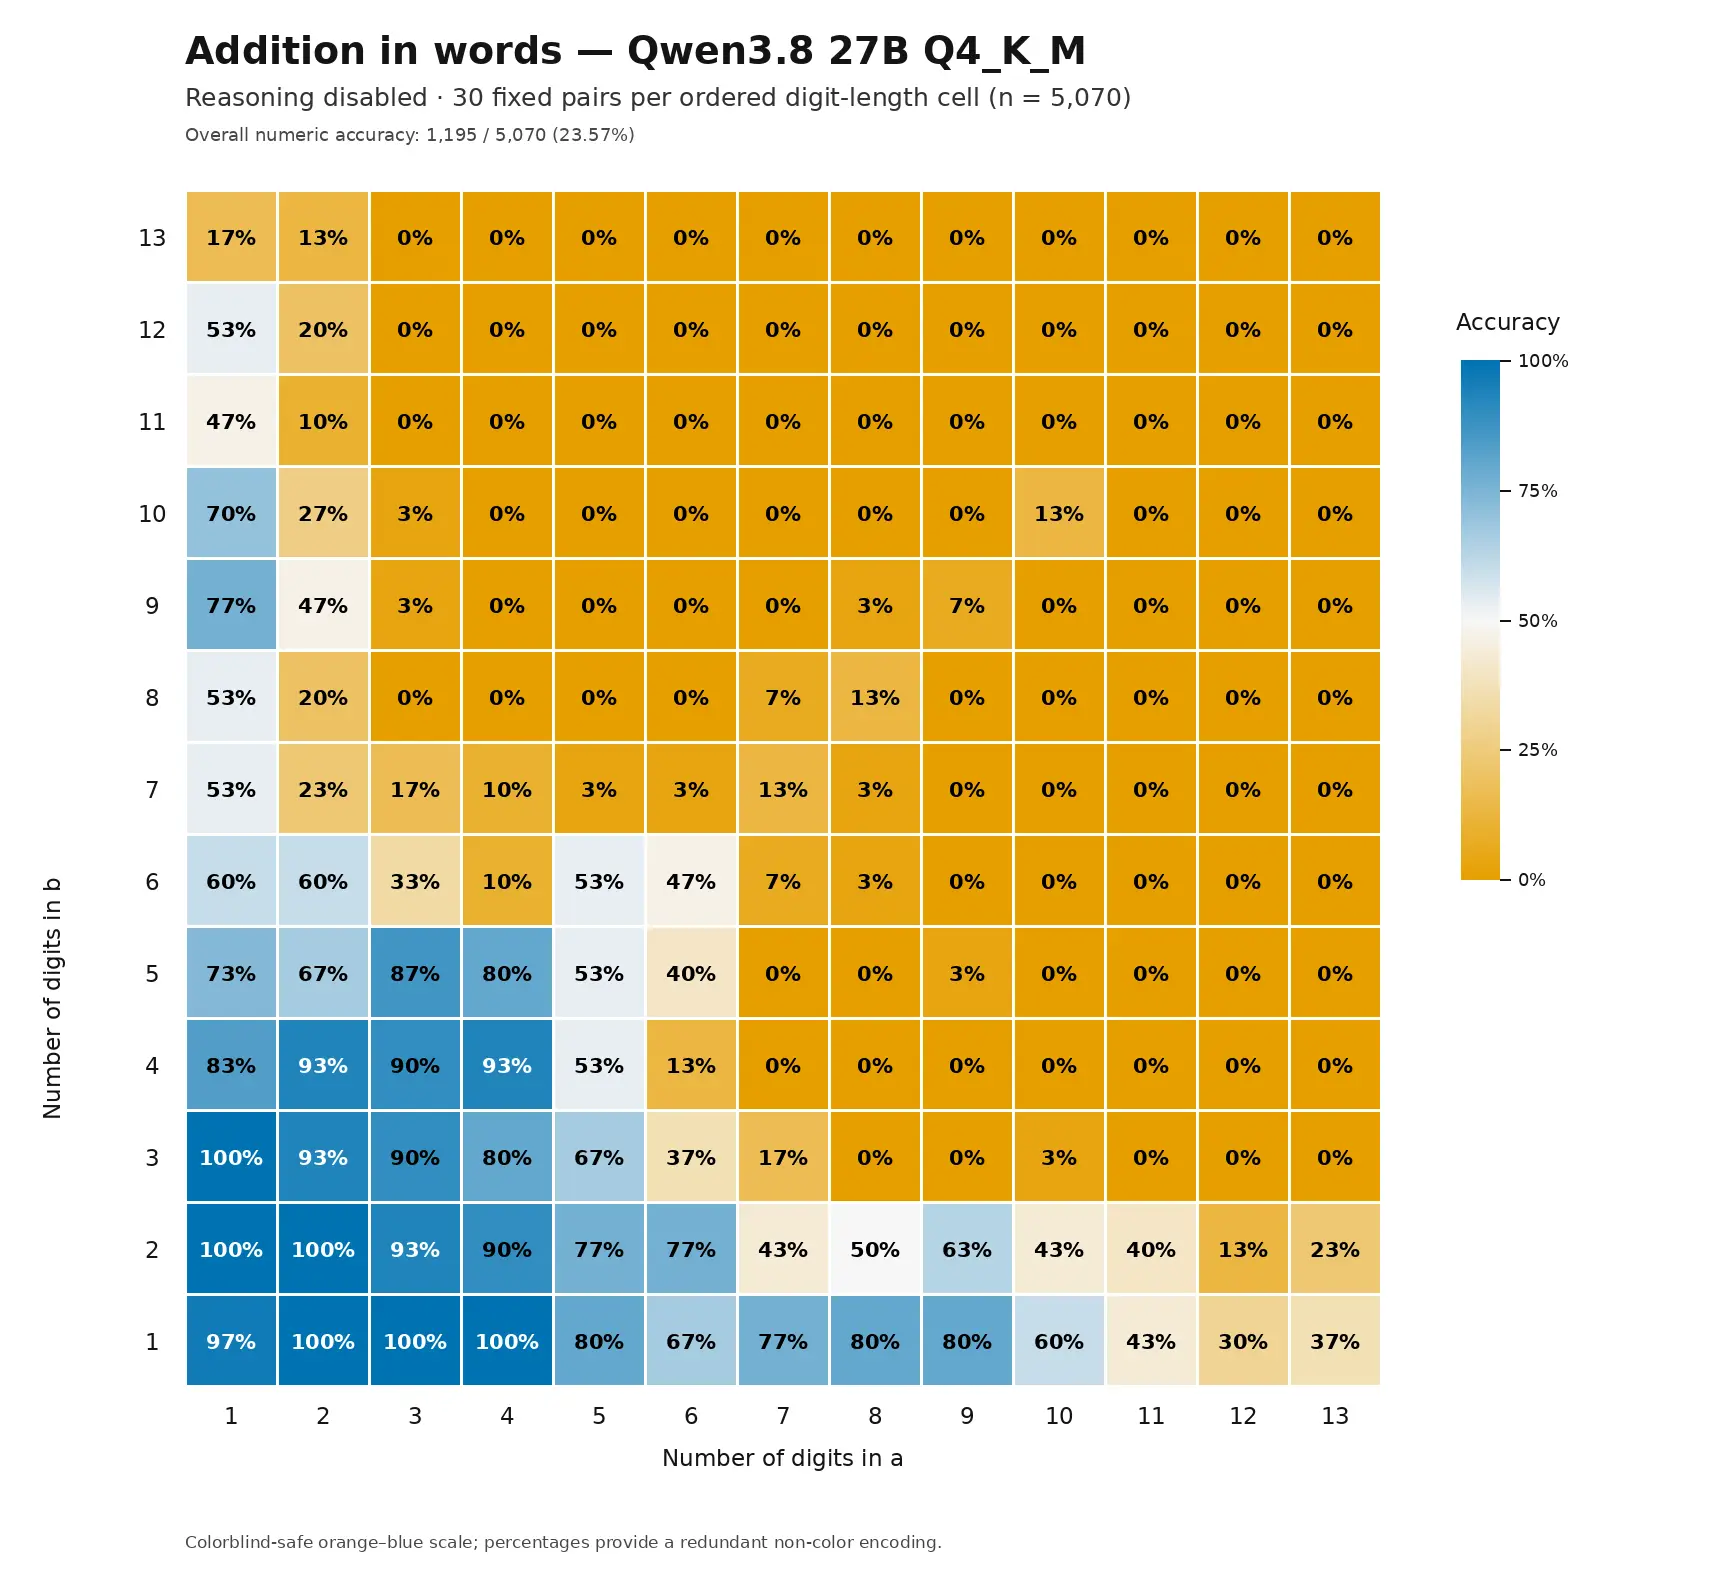 Qwen3.8 27B addition in words
Simon Willison reproduces an experiment originally run by Colin Frasier on GPT-4o — asking a model to add two large numbers and return the result spelled out in words — this time against a locally quantised Qwen3.8-27B-Q4_K_M.gguf model on an NVIDIA DGX Spark. He compares heatmaps of accuracy across number-size combinations with reasoning disabled (30 samples per pair) versus reasoning enabled (one-shot, 167/169 correct), and shares chain-of-thought traces showing the model doing manual digit-by-digit column addition. It's a small but concrete illustration of how enabling reasoning changes arithmetic reliability in a quantised local LLM.
simonwillison.netwriteupAdded 5 Oct 2026, published 4 Oct 2026- Herschel: Continuous Optimization of Production LLM Inference through On-Demand Profiling
Herschel is a continuous optimization system for production LLM inference that uses adaptive, on-demand profiling instead of always-on tracing to diagnose serving inefficiencies with low overhead (under 0.5% TTFT, 7% TPOT impact). It attaches to and detaches from running inference processes without engine restarts, reconstructs cross-process operator execution traces to pinpoint inefficiency mechanisms, and has AI agents implement and test candidate engine/kernel fixes under controlled replay of the triggering workload before expert review and deployment. Over six months of production use it collected ~17,000 traces across 120+ model variants and 10+ accelerator types, finding inefficiency patterns in 23% of traces and driving optimizations like restructured synchronization and removal of unused computation.
arxiv.orgpaperAdded 3 Oct 2026  Aleph Alpha Kolibri: How the sovereign German LLM works
A deep technical walkthrough of Aleph Alpha's Kolibri, a 78B-parameter (3.5B active) mixture-of-experts LLM for German and English released under Apache 2.0, built to be 'sovereign' (trained and deployable entirely under EU/German law). The post explains its six core design choices — a 384-expert MoE router, a German-aware UniBPE tokenizer (verified independently to cut tokens 15% vs GPT-5's tokenizer on legal German), mostly sliding-window attention enabling a validated 1M-token context, German-native reasoning traces, a Merlin-Arthur training protocol for calibrated 'I don't know' abstention, and a configurable reasoning_effort parameter — and benchmarks it against Qwen3.5/3.6/3.8, GLM-4.7 Flash, Nemotron 3 Nano and gpt-oss-120b on AIME, RULER, SWE-bench Verified, Terminal-Bench and the Omniscience test, including where it underperforms (tool calling, coding agents, trivia recall).
 tej.asarticlePublished and added 3 Oct 2026
 [AINews] not much happened today
Daily AINews digest (Latent Space) covering an October 2026 news cycle: OpenAI's cheaper/faster GPT-6.1 Sol and Anthropic's Claude Sonnet 5.5 reshaping Agent Arena's cost-performance frontier, a wave of decision-model releases (Cloudflare Clef, llama.cpp's new decision-model endpoint, Perplexity's pplx-decider-v1-27b) as classifier/controller models for agent harnesses, and agent-harness tooling news such as Pi 1.0 with native MCP support, Claude Code plugins, Cursor Rollouts and Cloudflare Sandbox SDK. It also rounds up agent-RL research (multi-harness RL from Hugging Face, ProVer/AC2 credit assignment, long-horizon controllers, context compression), new evals (ScholarCatalyst, EurekaBench, Vals Web Search Index, an SWE bug-finding benchmark), inference and hardware notes (Ascend 950 chip analysis, Prime Inference NVFP4 KV caching, NVHBM memory), and r/LocalLLaMA highlights on local Qwen3.8-27B inference and MTP speculative decoding in llama.cpp.
latent.spacearticlePublished and added 3 Oct 2026 From the creator of Redis; run LLM locally with ds4
DwarfStar (ds4) is a narrow C inference engine for running large mixture-of-experts models locally on high-memory Mac (Metal), CUDA and ROCm machines. It targets specific model families end-to-end — DeepSeek V4/V4.1 Flash, GLM 5.x and Qwen3.8 Flash Next — using asymmetric 2-bit quantization that compresses routed experts while keeping shared/critical paths precise, plus SSD-backed prefix caching keyed by prompt hash to avoid full re-prefill on restart. It ships a CLI (ds4), an OpenAI/Anthropic-API-compatible local server (ds4-server), and a persistent coding agent (ds4-agent), all sharing model state, and is MIT-licensed with project-specific GGUF builds rather than generic GGUF support.
 dwarfstar.shtoolAdded 3 Oct 2026, published 2 Oct 2026
- RailWave: Adaptive Spatial and Temporal Scheduling for Expert-Parallel Communication
RailWave is a phase-adaptive communication layer built on DeepEP that tackles the irregular All-to-All communication bottleneck in expert-parallel Mixture-of-Experts models. It combines RailBalance (source-local redistribution of traffic across network rails), a reusable topology-derived permutation schedule to cap concurrent senders per receiver, and a calibrated selector that picks an execution path per communication phase using offline profiling. On communication workloads derived from training the 106B GLM-4.5-Air model, it achieves up to 5.84x speedup on NVIDIA H800 and 4.36x on H20 versus the native DeepEP baseline.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026 - EdgeAgent: Orchestrating On-Device LLM inference for End-User Multi-Agent Systems on CPU-GPU Unified Memory Architectures
EdgeAgent is a cross-layer LLM inference system for running multi-agent workloads on edge devices with CPU-GPU unified memory architectures such as Apple M-series SoCs. It introduces zero-copy UMA-aware tensor parallelism to saturate both CPU and GPU, a dynamic speculative-decoding draft-budget scheduler adapting to sequence predictability, and an asynchronous suspend-and-yield mechanism that evicts stalled agents during tool-call latencies. On an Apple M4 SoC it reports 1.29x speedup from UMA-aware execution alone and 1.77x with full agent-aware scheduling, versus batched speculative decoding.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026 - From Patching to Pruning Visual Computation in Vision Language Models
Patch-to-Prune (P2P) is a training-free framework that repurposes activation patching from mechanistic interpretability into an inference-time compute bypass for vision-language models, replacing unnecessary visual-token projections in certain decoder layers with fixed neutral proxy vectors while preserving sequence length, token order, and residual pathways. Tested on Qwen2.5-VL and LLaVA family models across seven multimodal benchmarks, P2P at 3 percent tolerance retains about 94 percent of dense accuracy while cutting FLOPs by 55 percent, and reveals that intermediate decoder layers do most of the task-relevant visual integration while early and late layers need little token-specific visual computation.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026 - Execution-Path Qualification and Realized Costs in Speculative Decoding on Consumer Systems
An arXiv preprint that empirically tests speculative decoding on consumer hardware (Intel Arc B570, NVIDIA RTX, Apple M4-class systems), distinguishing between 'execution-path qualification' (whether a speculative predictor's output matches the target model's exact generation trajectory) and the realized latency/cost of running speculation. The authors find that a target-only, draft-free predictor matches greedy output on most repeat-stable prompts but does not guarantee qualification or identify a unique cause of divergence, and that newly qualified RTX serialization and other configurations (358H, M4 Guard) are often slower than target-only decoding once real costs are counted. The paper's conclusion is that these results are diagnostic engineering findings specific to the tested hardware/software paths, not evidence of a portable decoding speedup.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026 - VisionMX: Unlocking Microscaling Post-Training Quantization for Vision Models
VisionMX is a post-training quantization method for vision models using Microscaling (MX) formats, which pair low-precision numeric elements with shared block scales for efficient inference. The paper identifies three error sources in direct MX conversion of vision models—block-scale representation, poor alignment of small convolutional weights with nonuniform element grids, and underuse of signed codes by nonnegative activations—and addresses them via bounded weight rounding and a foldable affine activation correction. It is evaluated across image classification, object detection, semantic segmentation, and low-light image enhancement, showing improvements over direct conversion and existing post-training quantization baselines, especially for architectures most sensitive to MX conversion.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026  Clef / Clef-flash decision models (Cloudflare)
Cloudflare announces Clef and Clef-flash, open-weight "decision models" (Apache 2.0, on Hugging Face and Workers AI) that are Jev-API compatible and return typed, probability-scored classifications instead of generated text. The models are built by post-training a frozen Qwen backbone (Qwen3.8-27B for Clef, a smaller Qwen3.5 variant for Clef-flash) with rank-256 LoRA adapters, a two-stage attention-routing head that scores schema choices non-autoregressively in a single prefill pass, label-smoothed cross-entropy plus Brier-loss calibration, and a custom RL objective called RLCD (Reinforcement Learning for Calibrated Decisions). Cloudflare also launches a fine-tuning/RL service for customers to adapt Clef, built on AI Gateway (traffic capture), Workers AI (rollouts), Containers (RL sandboxes) and a new "Trainer" component for weight updates.
blog.cloudflare.comarticleAdded 3 Oct 2026, published 1 Oct 2026- Samuel Zeng (@SamuelZengML) on X
Samuel Zeng announces the open-sourcing of Edge0's cross-platform app layer (iOS, macOS, Android, Windows), building on Edge0's earlier on-device 35B language model that runs in only 1-2.5GB of peak memory. The release includes app code, local model/runtime integration, model management, and build/deployment guides on GitHub; the technique keeps the full model on local storage and streams in only the experts (MoE-style) needed per step, predicting and prefetching the next experts while running storage reads in parallel with compute. A Q4 2026 roadmap promises a unified inference API across platforms plus Python, hardware-adaptive runtime, and a CUDA backend.
x.comthreadPublished and added 1 Oct 2026  USA SuperIntelligence | USASI (@USASIHQ) on X
Sevren released Heimr 570M, an experimental hybrid Mixture-of-Experts model designed for on-device use on phones and laptops, with about 570M active parameters out of 2.7B total. It is trained for a 64K context window to support long-context local decoding, targeting edge-AI deployment rather than cloud serving.
x.comthreadPublished and added 1 Oct 2026- DRelay: Global Draft Context for Prefix-Aware Parallel Speculative Decoding Repair
DRelay is a speculative decoding technique for LLM inference that repairs parallel draft-token selections before target-model verification, using a global reader over the entire draft block plus a causal selector to decide whether to keep or replace each candidate token, extending the accepted prefix length. Trained jointly with the draft backbone via a combined candidate-support and position-weighted repair loss, it is evaluated on eight benchmarks on an H800 GPU and, under SGLang serving, improves end-to-end decoding speedup substantially over DFlash, Domino, and DSpark baselines.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026








Showing 150 of 207
Show more