Skip to content

37 results for β€œRecursive”

What you seeeverything
newsletter.semianalysis.comarticle🧠 AI

GDPx: Measuring Frontier Model Capabilities Across the Most Valuable Domains

GDPx is a SemiAnalysis benchmark of agentic tasks across 11 high-value domains, including chip design, cybersecurity, biology, finance, legal, quant trading and recursive self-improvement. Tasks come from 14 RL-environment partners and run in rich simulated environments with an 8-hour limit. The best model scores 12%. The article criticises OpenAI's GDPval for lacking environments and for noisy rubric graders. The fetched text is truncated, so later domain sections are missing.

Claude CodeCodexGoogle Antigravity+8
SemiAnalysisGDPxGDPval+30

evals, agents, trainingΒ· Published and added 2 Nov 2026

x.comthread🧠 AI

Daily Vibe Casting (@vibecastingapp) on X

Daily Vibe Casting is an X thread dated 24 October 2026 that summarises ten tech news items from the previous 24 hours. The AI items are Cloudflare's model-independent agent security audit skill, Recursive SI's Apache 2.0 Flint local coding model (125+ tokens/s on an M4 Pro), Anthropic's Claude Duet preview and Claude API version 2026-10-21, which drops temperature, top_p and top_k. It also covers HeyGen Voice Turbo and Gemini in Google Maps on CarPlay.

CloudflareClaudeGemini+2
CVE-2026-110264Recursive SIFlint+6

models, coding-agents, agentsΒ· Added 24 Oct 2026, published 22 Oct 2026

arxiv.orgpaper🧠 AI

Chunk Recomputation under Real Document Revisions: Measuring Update Cost and Retrieval Quality of Fixed, Recursive, and Content-Defined Chunking

Chunk Recomputation under Real Document Revisions measures how much text must be re-embedded after edits for three stateless chunkers (non-overlapping fixed-size, recursive paragraph-first, content-defined) on 120 pairs of adjacent Chinese and English Wikipedia revisions. Fixed-size recomputes 57-68% of the new-version workload, recursive 38-56%, content-defined 43-54%, while evidence recall at a 2048-token budget differs by under two points. The authors argue update cost should be reported alongside retrieval quality.

RAG
WikipediaarXiv

llm-apps, research, evalsΒ· Added 24 Oct 2026, published 22 Oct 2026

x.comthread🧠 AI

Open Weight Updates (@openweightstars) on X

Flint is the first model from Recursive SI, a fast local coding model with open weights released the same day. It was built with the company's automated research system, the Eureka Machine. The post claims up to 2x faster speed than comparable models: 125+ tokens/sec on a MacBook Pro and 150+ on RTX Spark. The captured text is truncated and gives no benchmarks or model size.

RTX SparkMacBook Pro
FlintRecursive SIEureka Machine+3

models, inference, coding-agentsΒ· Added 22 Oct 2026, published 21 Oct 2026

blog.talosintelligence.comwriteupπŸ›‘οΈ Security

Parasitizing trust: How legitimate infrastructure becomes a delivery pipeline for attackers

Cisco Talos research on attackers using legitimate infrastructure to deliver lures, with abuse seen across more than 25 platforms in the past year. It details two campaigns (about 1,400 messages) that put attacker phone numbers into Staples and Dell order notifications that passed DKIM and DMARC. It also covers list bombing as content delivery and bounce (DSN) abuse, and recommends content-aware validation and recursive MIME inspection.

Microsoft 365Proton Mail
platform-as-a-proxylist bombingbounce abuse+7

Threat Intel, Blue Team & DetectionΒ· Published and added 21 Oct 2026

arxiv.orgpaper🧠 AI

Where is Physical RSI capability from? An Observational Scaling Law of LLM-as-policy

The paper introduces PhysRSI-eval, a five-axis metric for physical recursive self-improvement: first-attempt performance, efficiency, success, budget and improvement from failure. Several VLMs are tested on 18 manipulation tasks under a fixed interaction budget. It proposes the Physical Barrel Hypothesis and studies observational scaling. Workspace interventions show that removing history lowers late-round success, while frozen workspaces still help on unseen layouts.

vision-language modelLLM
PhysRSI-evalPhysical Barrel HypothesisarXiv

research, evals, multimodalΒ· Added 21 Oct 2026, published 19 Oct 2026

ethresear.charticleπŸ›‘οΈ Security

Faster, Aggregatable and Quantum Safe Privacy Pools

Ethresear.ch post porting Tornado Cash to Flock, a post-quantum binary-field SNARK, proving a depth-32 SHA-256 withdrawal in about 19.5 ms (203.6 KiB proof), with recursive aggregation at about 0.68 s per withdrawal. It also proposes a ZIP 2005-inspired recovery protocol: wallets derive note secrets from a seed, the pool freezes on a discrete-log break, and users withdraw through a post-quantum verifier. Security is argued under an epoch assumption, with Grover-bounded pre-image attacks.

Tornado CashFlockGroth16+2
ZIP 2005IronwoodGrover's algorithm+5

BlockchainΒ· Published and added 19 Oct 2026

hackers-arise.comarticleπŸ›‘οΈ Security

Open-Source Intelligence (OSINT): Turn One Username into a Full Digital Dossier with Maigret

Hands-on walkthrough of Maigret, an open-source Python tool that checks a username against 3,000+ sites (top 500 by default) and builds a profile dossier by parsing public profile pages and recursively searching newly found usernames. Covers installation from GitHub, single-site and tag filtering, username permutation, HTML/PDF/CSV/JSON reports, graph output, and an optional LLM summary via OpenRouter. Positioned as a more thorough successor to Sherlock for username reconnaissance.

MaigretPythonKali Linux+2
Sherlock

OSINT, LearningΒ· Published and added 16 Oct 2026

arxiv.orgpaper🧠 AI

Grounding Generative Verification in 3D Content

The paper introduces 3DVerifierBench, a 10-task benchmark for generative verification of 3D content. It scores accept/reject decisions, rejection explanations, and responses to controlled changes in specifications and candidates. A human study shows a 21.6-point gap to the strongest tested model, GPT-6 Astra. The authors also build a pipeline of multi-view fact extraction, controlled 3D editing and native annotations. It yields 14,126 training examples with contradiction explanations and linked counterfactuals. Verification-guided selection raises complete factual success from 26.7% to 90.0% with oracle selection over sixteen candidates, and human-guided recursive refinement satisfies all seven requirements for every input in an eight-input study.

multimodal large language model3D generation
3DVerifierBenchGPT-6 AstraarXiv

research, evals, multimodalΒ· Added 17 Oct 2026, published 15 Oct 2026

decrypt.coarticle🧠 AI

Google Says AI Isn't Building Itself Yetβ€”Even Though It Writes 75% of the Code

Decrypt reports on the Gemini 4 Argon Safety & Security Report, where Google DeepMind found no statistically significant acceleration of ML R&D. Its internal GCI v1 index (123 models, 92 benchmarks) shows steady ~0.1 points/month progress, with Argon slightly above trend, attributed to compute and investment. Over 75% of production code is AI-written and fully delegated pull requests rose from 7.5% to 11.9%, yet ~88% of PRs still need human steering or authorship. This is relevant evidence on the recursive self-improvement debate and on how much of AI research is automated.

Gemini
Google DeepMindGemini 4 ArgonHaydn Belfield+5

ai-safety, evals, coding-agentsΒ· Published and added 15 Oct 2026

arxiv.orgpaper🧠 AI

Recursive Reward Improvement via Adversarial Meta-Prompt Evolution

Introduces Recursive Reward Improvement (RRI) for recursive self-improvement on open-ended expert tasks without answer keys, where a proposer writes both a task and a rubric. Before the solver trains, an adversary writes a rubric-gaming but useless answer, the same model writes an honest answer without seeing the rubric, and up to two repair steps revise the rubric until the honest answer wins. Exploits found also rewrite future task and rubric generation. On HealthBench Professional it beats a Generation Only baseline by 10.9 points at 9B and 12.4 at 27B (10.3 with no external model), and the 27B model transfers to PRBench Hard (+6.6) and ProfBench (+8.0).

LLM
HealthBench ProfessionalPRBench HardProfBench+2

research, trainingΒ· Added 17 Oct 2026, published 15 Oct 2026

huggingface.copaper🧠 AI

Harness^2: Recursive Agent Harnessing for an Open World

Harness^2 is a plug-and-play framework that recursively improves LLM agent execution harnesses in open-world settings where no ground-truth verifiers exist. Task-level recursion uses a contrastive Propose-Probe-Compose step to guide harness edits for the current task, and it scales through parallel or sequential recursion. Harnessing-level recursion distills experience from those edits into a continual-improvement harness for future tasks. A single step improves GLM-5 and Gemini 3.5 Flash over their base harnesses by up to 11.5 points on WorkBuddy-Bench, 4.5 on JobBench and 11.8 percentage points on LAB.

GLMGeminiHugging Face
GLM-5Gemini 3.5 FlashWorkBuddy-Bench+2

agents, researchΒ· Added 14 Oct 2026

endorlabs.comarticle🧠 AI

Context Engineering for Application Security | Endor Labs

Endor Labs whitepaper on using context engineering to make AI coding assistants produce secure code. It covers secure prompting (priming, decomposition, refinement with design-spec and test-first patterns), reusable system rules such as Cursor rules and the CSA R.A.I.L.G.U.A.R.D. framework, and external SAST/SCA tools wired in through MCP servers with a rule that triggers scans. It also covers the costs and risks: extra token use, models ignoring rules, untrusted community rules, and MCP server supply-chain threats. It cites figures such as 62% of AI-generated solutions containing flaws and a 77.5% reduction in weaknesses from recursive prompting.

CursorModel Context ProtocolClaude+1
Endor LabsOWASPCloud Security Alliance

prompting, coding-agents, llm-appsΒ· Published and added 12 Oct 2026

arxiv.orgpaper🧠 AI

ReSI: Recursive Safety Improvement toward Resistant and Resilient AI

ReSI is a recursive safety improvement framework that automates rounds of safety alignment. Each round applies diverse red-teaming methods to the current target model, develops training recipes to fix the vulnerabilities found, and promotes the update with the largest safety gain among those passing a Pareto gate on capability retention. On four dense and mixture-of-experts models it matches or exceeds frontier models on in-distribution and out-of-distribution safety benchmarks. It cuts mean X-Teaming attack success rate from 86.01% to 31.45%, against 56.69% for the best frontier model (GPT-5.6 Luna), while largely preserving general capabilities.

Mixture of Experts
ReSIRΒ²AIX-Teaming+1

ai-safety, research, trainingΒ· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

ReSI: Recursive Safety Improvement toward Resistant and Resilient AI

ReSI is a recursive safety improvement framework. Each round runs diverse red-teaming methods against the current target model, develops training recipes for the vulnerabilities found, and promotes the update with the largest safety gain among those passing a Pareto gate on capability retention. Across four dense and mixture-of-experts models it cuts mean X-Teaming multi-turn jailbreak attack success from 86.01% to 31.45%, versus 56.69% for the best frontier model evaluated (GPT-5.6-Luna). It also beats alignment baselines on nearly all safety evaluations while largely preserving general capability. It frames the goals as resistance to known threats and resilience to unforeseen ones, following RΒ²AI.

LLM
X-TeamingR2AIGPT-5.6-Luna

AI SecurityΒ· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🧠 AI

Recursive Video In-Context Learning for Agentic Robot

This paper introduces Recursive Video In-Context Learning (RV-ICL), a training-free method that lets an LLM agent orchestrating frozen vision-language-action (VLA) policies learn from a single demonstration video rather than from full video or fixed keyframes. The demonstration is converted into a navigable hierarchy (task keyframes, phases, moments, short clips) built around sub-events like grasps and releases, exposed to the agent as read-only tools it queries coarsely during planning and drills into for contact-level detail during execution. Built on the RPent agent, it raises task success from 92.6 percent to 96.5 percent on LIBERO-PRO and from 86.7 percent to 95.8 percent on LIBERO-Plus with only one demonstration per task.

vision-language-action model
RV-ICLRPentLIBERO-PRO+1

research, agents, multimodalΒ· Added 6 Oct 2026, published 5 Oct 2026

arxiv.orgpaper🧠 AI

MobiAgent: Dual-Loop Recursive Policy Self-Improvement for Long-Horizon Mobile Manipulation

MobiAgent is a dual-loop agentic framework for long-horizon mobile manipulation that separates deployment execution from policy self-improvement. An Inner Loop uses vision-language models for receding-horizon planning and visual reflection to compose atomic skills executed by flow-matching experts sharing a unified VLM backbone, while an Outer Loop autonomously segments, verifies, and clusters deployment rollouts to discover new atomic skills and continuously fine-tune the skill library without human annotation. On BEHAVIOR-1K it beats pi_0.5-TA by 22.5 percentage points, and autonomous data recycling raises RoboCasa success from 7.50% to 27.50% and Astribot S1 success from 32.5% to 57.5%.

vision-language modelflow matching
RoboCasaBEHAVIOR-1KAstribot S1+1

research, multimodalΒ· Added 5 Oct 2026, published 2 Oct 2026

github.comtoolπŸ›‘οΈ Security

https://github.com/praetorian-inc/gato

Gato (GitHub Attack Toolkit) from Praetorian is a Python CLI for enumerating and attacking GitHub organizations' CI/CD pipelines: it identifies poisoned pipeline execution risks, abuses self-hosted runners via workflow and run-log analysis, exfiltrates Actions secrets, and automates fork-PR/workflow-based command execution. Version 1.7 added an Actions Artifacts Secrets Scanner that downloads and recursively scans workflow artifacts with NoseyParker, which Praetorian used to find critical secrets leaks in prominent open-source projects. The project is now archived/superseded by Praetorian's multi-platform tool Trajan, which merges Gato (GitHub) and Glato (GitLab) attack capabilities.

GitHub ActionsGitHubPython+2
poisoned pipeline execution

DevSecOps, Offensive SecurityΒ· Published and added 2 Oct 2026

latent.spacewriteup🧠 AI

Academia is for Ambition β€” Alex Zhang, MIT

A Latent Space podcast transcript/interview with MIT PhD student Alex Zhang, creator of Recursive Language Models (RLMs) and a core contributor to GPU Mode and KernelBench, who discusses using recursive subagent calls, context offloading, and shared memory to let models work beyond fixed context windows. The conversation ranges across AI-generated GPU kernels and their verification gap, research taste in academia versus industry labs, why "harnesses" (as in Claude Code, Codex, and Pi) function as compositional generalizers, the Jev model's non-autoregressive output-space trade-offs, and large-scale agent swarm experiments at OpenAI, Kimi, and Sakana AI. It offers a researcher's-eye view of where capability overhang and new agent/harness architectures may be heading beyond today's standard transformer decoder.

TransformerCUDAClaude Code+2
Alex ZhangMITGPU Mode+27

agents, researchΒ· Published and added 2 Oct 2026

openid.netpaper🧠 AI

Identity Management for Agentic AI [pdf] (2025)

A whitepaper from the OpenID Foundation, led by Tobin South with contributors from WorkOS, Stanford's Loyal Agents Initiative, and the Artificial Intelligence Identity Management Community Group, mapping how authentication and authorization standards apply to AI agents. It surveys current fixes (OAuth 2.1, Model Context Protocol authorization, enterprise SSO/SCIM provisioning, IPSIE profiles) and lays out unsolved problems for autonomous agents: delegated "on-behalf-of" identity versus user impersonation, consent fatigue at scale, recursive sub-agent delegation, multi-user shared agents, and browser/computer-use agents that bypass API-based authorization entirely.

Model Context ProtocolOAuthSCIM
OpenID FoundationTobin SouthWorkOS+7

mcp, agents, ai-policyΒ· Added 2 Oct 2026, published 1 Oct 2026

openid.netpaperπŸ›‘οΈ Security

Identity Management for Agentic AI [pdf] (2025)

OpenID Foundation whitepaper (Oct 2025, lead editor Tobin South) analyzing how authentication/authorization for AI agents differs from traditional software clients. It covers where OAuth 2.1, OIDC, SSO/SCIM, and MCP already work for single-domain synchronous agents, and lays out unsolved problems for autonomous agentic identity: agent identity fragmentation across vendors, replacing user impersonation with explicit delegated "on-behalf-of" authority, consent-fatigue at scale, recursive delegation chains between sub-agents, agents acting for teams of users, and browser/computer-use agents bypassing API-based authorization entirely.

Model Context ProtocolOAuthOIDC+2
IPSIEOpenID FoundationLoyal Agents Initiative

Identity & Access, AI SecurityΒ· Added 2 Oct 2026, published 1 Oct 2026

x.comthread🧠 AI

Rohan Paul (@rohanpaul_ai) on X

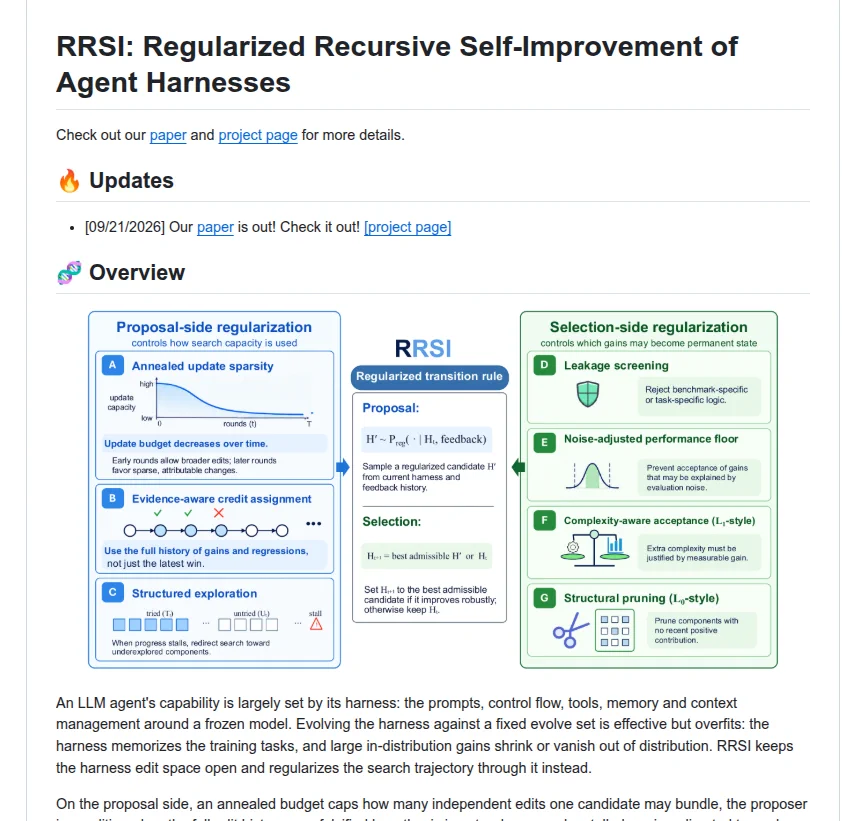
A tweet describing Google's RRSI (Regularized Recursive Self-Improvement of Agent Harnesses), a framework that automatically evolves all non-model components of an LLM agent β€” prompts, control flow, tool use and memory β€” while keeping the underlying LLM weights frozen. The "regularized" aspect suggests constraints added to recursive self-improvement loops to keep the evolved harness stable or bounded, distinguishing it from unconstrained self-modifying agent approaches.

Google

agentsΒ· Published and added 1 Oct 2026

arxiv.orgpaper🧠 AI

Latent Twin Operator

Latent Twin Operator (LTO) is a latent-space neural surrogate for time-evolving PDEs that uses a Convolutional Conditional Neural Process (ConvCNP) style encoder and decoder to ingest sensor observations at arbitrary, irregular placements and resolutions, paired with a learned latent evolution map that advances the encoded state directly between time points independently of the input and output discretizations. The paper derives an explicit convergence rate for context discretization error and validates it on a 2D heat-equation benchmark, showing LTO transfers across spatial resolutions with fixed parameters and, on Navier-Stokes, that direct latent evolution reduces error over long horizons compared to recursive rollout.

Navier-Stokes

researchΒ· Added 29 Sep 2026, published 28 Sep 2026

github.comrepoπŸ›‘οΈ Security

Sandyaa β€” open-source autonomous code auditor that proves bugs with working exploit PoCs

Sandyaa is an open-source autonomous code-audit tool that points at a local directory or git URL and runs end-to-end, driven by the Claude Code CLI (optionally Gemini) with no separate API key required. It uses a Recursive Language Model approach β€” the model drives a Python REPL to chunk code, spawn sub-LLM queries, and aggregate results β€” running eight recursive passes (call-chain tracing, data-flow expansion, vulnerability chaining, exploitability proof, etc.) and an attacker-control-reachability analyzer to filter unreachable findings, then writes each finding with a working exploit PoC and an evidence.json linking claims to file/line. Maintained by SecureLayer7, who report using it to surface zero-days; it's alpha-stage, macOS-tested, Linux/WSL2-expected-to-work, and unsupported on native Windows.

Claude CodeGeminiNode.js+2
SecureLayer7

AppSec, AI SecurityΒ· Added 26 Sep 2026

openai.comarticle🧠 AI

Sam Altman’s remarks at the United Nations Security Council

Transcript of Sam Altman's address to the UN Security Council. He names two failure modes for AI progress: losing control of the future to AI, especially with recursive self-improvement, and concentrating power in too few hands. He sets out three principles (people at the center of decisions, benefits by and for people, individual empowerment) and calls for complementary national and international frontier AI standards. Those standards would cover capability measurement, risk assessment, safeguard sufficiency, oversight, incident reporting and secure channels for sharing vulnerabilities. He also claims an OpenAI model solved the Navier-Stokes Millennium Prize Problem. The speech shows how a leading lab frames international governance.

Sam AltmanOpenAIUnited Nations Security Council+3

ai-policy, ai-safetyΒ· Added 29 Sep 2026, published 23 Sep 2026

interconnects.aitalk🧠 AI

Debating RSI, the US-China Gap, and Jaggedness with JS Denain of Epoch AI

A transcribed podcast conversation between Nathan Lambert and Epoch AI's JS Denain covering recursive self-improvement (RSI) evidence from OpenAI/Anthropic's acceleration blog posts, the size and drivers of the US-China frontier model gap (estimated at 4–9 months using Epoch's Capabilities Index, ECI), the role of distillation and "Claude router" data leakage in closing that gap, robotics as a bottleneck for industrial-scale AI acceleration, and jaggedness in AI capability progress (e.g. why math benchmarks may overstate general progress). It's grounded in concrete data points like Codex spending growth, METR/Epoch research, and named model comparisons (Kimi K3, GLM 5.2/5.3) rather than speculation alone.

CodexTransformer
JS DenainEpoch AINathan Lambert+17

ai-policyΒ· Added 29 Sep 2026, published 22 Sep 2026

openai.comarticle🧠 AI

Building standards for the next phase of AI

OpenAI argues that the United States should lead an effort to build global technical standards for frontier AI, with a focus on automated AI research and recursive self-improvement (RSI). It proposes using the network of AI safety institutes, coordinated through CAISI, to produce standards for RSI-relevant evaluation, human oversight (including which automated research processes should trigger human review), and incident classification and reporting. The standards would not be licenses or mandatory pre-release approval. The post cites aviation and financial stability as models, and it positions OpenAI's research-acceleration report and misalignment reporting framework as early contributions.

OpenAISam AltmanJakub Pachocki+7

ai-policy, ai-safetyΒ· Added 29 Sep 2026, published 21 Sep 2026

arxiv.orgpaper🧠 AI

ScienceBuddy: Recursive-in-Recursive Self-Improvement for Interactive Scientific Agents

ScienceBuddy is an interactive scientific research workspace with continually improving agents that turn researcher requests, feedback, and execution evidence into training tasks and evaluation rubrics. Its core contribution is "recursive-in-recursive self-improvement," where an inner recursion evolves the agent harness with the model fixed, and an outer recursion trains the model via RL under the improved harness, with each shaping the other over time. The paper presents case studies across four scientific task families and releases the system as a research product.

ScienceBuddy

agents, training, researchΒ· Added 22 Sep 2026, published 15 Sep 2026

interconnects.aiarticle🧠 AI

One resignation turned the embers of AI fear into a wildfire

An Interconnects essay analyzing why AI researcher Jacob Coxon's resignation (citing safety risks, alongside Evan Hubinger's >10% extinction-risk claim) went viral and polarized AI safety discourse toward extremes. The author argues the "recursive self-improvement" (RSI) fast-takeoff narrative overstates near-term risk, proposes an alternative "lossy self-improvement" view of AI's jagged capability profile, and argues the bigger near-term danger is frontier labs' weak infrastructure hardening (citing the OpenAI-HuggingFace incident) rather than existential catastrophe.

Hugging Face
Jacob CoxonEvan HubingerDaniel Kokotajlo+5

ai-policyΒ· Added 29 Sep 2026, published 10 Sep 2026

soliditylang.orgadvisoryπŸ›‘οΈ Security

Spill Slot Collision Across Mutual Recursion Bug

The Solidity team disclosed a compiler bug (fixed in Solidity 0.8.37) where the IR pipeline's stack-to-memory spill mechanism can assign the same fixed memory offset ("spill slot") to two simultaneously-live local variables when a contract's call graph contains mutual recursion, silently corrupting values without any revert or warning. The bug requires --via-ir compilation plus a narrow set of conditions (mutual recursion, >16 live locals in reachable non-recursive functions, a variable read back after the recursive call) and affects Solidity 0.7.2 through 0.8.36; a rescan of ~319,000 Sourcify-verified contracts found no affected deployments. The writeup includes full technical detail on the buggy depth-first slot allocator, an annotated PoC contract reproducing the silent overwrite, and the strongly-connected-component fix.

SolidityEthereum
Ng Sze HonEthereum Foundation bug bounty programUnsound Spill In Mutual Recursion Bug+1

BlockchainΒ· Added 29 Sep 2026, published 10 Sep 2026

soliditylang.orgadvisoryπŸ›‘οΈ Security

Solidity 0.8.37 Release Announcement

Solidity 0.8.37 release notes disclosing three EF bug-bounty-reported compiler bugs with security implications: deleting an element of a memory bytes array (or converted string) zeroed the full 32-byte word instead of one byte, corrupting adjacent data in the evmasm pipeline (all versions ≀0.8.36); a stack-to-memory spill-slot collision in mutually recursive functions under --via-ir silently overwrote live variables (0.7.2–0.8.36); and require() with a custom error using named arguments encoded parameters in call-site rather than declaration order, producing structurally valid but semantically wrong revert data. The release also adds two non-security miscompilation fixes, an experimental planning-based stack shuffler for the SSA CFG backend, support for the Amsterdam EVM's SLOTNUM opcode (EIP-7843), and removes/deprecates several experimental features.

SolidityEthereum
shaheenfazimNg Sze HonCantina Security+2

BlockchainΒ· Added 29 Sep 2026, published 10 Sep 2026

endorlabs.comarticleπŸ›‘οΈ Security

Prompt Patterns That Make Coding Agents Write Safer Code | Blog | Endor Labs

Endor Labs breaks down prompt engineering patterns that reduce vulnerabilities in AI-generated code: a design-spec pattern that front-loads security requirements, naming specific CWEs to avoid (e.g. CWE-89, CWE-79, CWE-20), and a "secure-insecure diff" recursive self-critique loop, while warning that telling a model to role-play a security expert actually performs worse. It cites research showing these patterns cut vulnerability density by up to 56–77.5%, notes that repeated AI iteration can drift toward less-secure code, and flags that AI coding agents frequently suggest hallucinated or vulnerable dependencies (34% hallucinated per Endor's own dependency research), arguing prompts must be paired with SAST/SCA/secrets scanning and reachability-based prioritization.

Endor LabsClaude CodeCursor+1
CWE-89CWE-79CWE-20+1

AI SecurityΒ· Added 3 Sep 2026, published 2 Sep 2026

github.comrepo🧠 AI

context-labs/whip

WhipCode (context-labs/whip) is an open-source coding agent written in Go, with a Desktop app, terminal UI and web client on a shared daemon. A recursive language model loop runs short Starlark or JavaScript programs to inspect context, call tools and delegate to subagents. It supports MCP servers, skills and provider-routed models, and solved 20 of 30 tasks in a retained evaluation.

GoModel Context ProtocolNode.js+5
Context LabsTerminal-Bench

coding-agents, agentsΒ· Added 2 Nov 2026, published 20 Aug 2026

github.comrepoπŸ›‘οΈ Security

QM

QM is an MIT-licensed, self-hosted "multiplayer" agent harness that lets a company deploy a shared coding/ops agent across Slack and a web app, with per-person and per-room isolated sandboxes, memory, keychains, permissions, and crons. Its security model centers on an org-wide posture (Strict pauses every tool call for approval; Auto blocks private-network access and applies optional content screening; Dangerous disables both) layered under a predeclared command policy that hard-denies things like recursive deletes, plus an explicit Isolated/Open sharing posture that governs cross-scope memory and file access with provenance labeling and audit trails. It supports pluggable harnesses (Pi, OpenCode, Codex, Claude Code) behind a common core and documents its threat model and operator assumptions in SECURITY.md.

Claude CodeOpenCodeCodex+3

AI SecurityΒ· Added 3 Sep 2026, published 1 Aug 2026

soliditylang.orgadvisoryπŸ›‘οΈ Security

Solidity 0.8.36 Release Announcement

Solidity 0.8.36 release notes disclose two medium-severity compiler bugs: a Yul optimizer call-cycle detection flaw that let stack-to-memory spilling be wrongly applied to mutually recursive functions, causing separate invocations to share and overwrite the same memory slots; and a storage-layout warning bug that could reverse the AST's linearizedBaseContracts annotation when a contract's variables sit very close to the end of storage, corrupting constructor/state-variable initialization order. The release also adds experimental stack-to-memory spilling to the new SSA-form CFG code generator (behind --experimental --via-ssa-cfg) and removes the now-obsolete experimental EOF backend after EOF's rejection from the Fusaka upgrade.

Solidity
Unsound Spill In Mutual Recursion BugInheritance Order Reversal On Storage End Warning Bug

BlockchainΒ· Added 29 Sep 2026, published 9 Jul 2026

lilianweng.github.ioarticle🧠 AI

Harness Engineering for Self-Improvement

Lilian Weng's long-form post argues that the "harness" surrounding a base model β€” the system that orchestrates planning, tool use, context, memory and evaluation β€” is as important to recursive self-improvement (RSI) as raw model intelligence. It surveys harness design patterns (workflow loops, file-system-as-memory, sub-agents) and traces an optimization progression from prompts to context engineering (ACE, Meta Context Engineering) to workflow search (ADAS, AFlow) to self-editing harness code (STOP, Self-Harness, Agentic Harness Engineering, Darwin GΓΆdel Machine, Hyperagents) and evolutionary program search (AlphaEvolve, ShinkaEvolve). It closes with open problems for auto-research and self-improving agents: weak evaluators, memory/context lifecycle, negative-result bias, diversity collapse, reward hacking, and the durable need for human oversight, plus a benchmark appendix (PaperBench, CORE-Bench, RE-Bench, MLE-bench, KernelBench). Note: the fetched text is truncated partway through the references/appendix.

Claude CodeCodexOpenCode+1
Lilian WengAnthropicOpenAI+36

agents, coding-agents, researchΒ· Added 29 Sep 2026, published 4 Jul 2026

github.comrepoπŸ›‘οΈ Security

Teycir/SkillsGuard

SkillsGuard is a zero-dependency static security scanner for AI agent skill packages (SKILL.md files and bundled scripts) that detects prompt injection, exfiltration, obfuscated payloads, persistence, and privilege escalation before an agent reads or executes them. It recursively decodes base64/hex/URL-encoded blobs to catch hidden attacks like a base64-wrapped reverse shell, computes a 0-100 risk score, and integrates into CI (SARIF/JSON output), git pre-commit hooks, and Claude via an MCP server (scan_skill tool) or a free hosted Cloudflare Workers API. The README also situates it against competing agent-skill scanners (NVIDIA, Cisco, Snyk, Mondoo, SkillSpector, SkillScan), noting it's the only one requiring no account/API/LLM dependency versus SkillSpector's LLM-augmented semantic analysis backed by a study of 42,447 scanned skills.

Node.jsModel Context ProtocolSARIF+3
SkillSpector

AI Security, DevSecOpsΒ· Published and added 21 Jun 2026