 [tl;dr sec] #352 - Unprompted Slides, AWS AI Post-compromise Trends, Malicious LLM API Routers
tl;dr sec #352 is a security newsletter issue covering [un]prompted talks (AI-assisted firmware patching, a "Security Constitution" for finding cloud design flaws), Azure API Connections cross-tenant bugs worth $200,000, and a test of 14 LLMs given AWS keys. It also covers a paper on malicious LLM API routers (9 of 428 injecting code) and Datadog's "counterfeit policy" bypass of the Jev classifier.
 tldrsec.comarticleAdded 30 Oct 2026, published 29 Oct 2026🛡️ Security
 Granite Switch 4.1.1 — Update models like you update software
Granite Switch 4.1.1 is a backwards-compatible patch release of IBM's modular Switch architecture, which configures a language model with specialized, cache-efficient adapters on one endpoint. It updates the Granite Speech ASR model (10 languages, native punctuation and capitalization) and the Decision adapter in granitelib-core, measured on the Jev Decision Index test set. Only the new adapters were retrained; the base model is unchanged. IBM plans tutorials and an Adapter SDK for third-party adapters.
 huggingface.coarticlePublished and added 29 Oct 2026🧠 AI
 Introducing AnySpeechRecognizer and AnyDecisionModel: Open Models for Speech and Decisions on Apple Platforms
AnySpeechRecognizer and AnyDecisionModel are two Swift packages from Hugging Face. The first mirrors Apple's SpeechAnalyzer API with swappable engines (NVIDIA Parakeet, Alibaba Qwen3-ASR on Core ML) and adds Sortformer speaker diarization. The second returns typed yes/no, choice and score answers with probabilities via MLX, Core AI, llama.cpp, Jev or Ollama. The post gives M4 Max timings, model sizes and calibration options.
huggingface.coarticlePublished and added 29 Oct 2026🧠 AI Think Before You Act: Decision Gate for LLM Agents
JevAct is a runtime verification framework that intercepts selected LLM agent actions before execution and returns feedback for bounded revision. It compiles domain policies into executable state checks and structured questions scored by a prefill-only decision model, giving probability-based judgments without generation. Tested on eleven agents with tau^2-bench Airline and Telecom and BFCL, it gained consistently on Telecom and BFCL and was mixed on Airline.
 arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI
 The rise and fall of Jev hype
The essay uses the launch of Jev, TypeSafe AI's "System One" general-purpose classifier trained with RLCD, to dissect AI marketing patterns: name dropping, jargon, ambiguity, inflated claims and drama. The author argues Jev's hype peaked and collapsed within about 33 days, while open-weight rivals beat it on cost and performance. It also lists incremental advances since ChatGPT and four unsolved problems: abstract reasoning, continuous learning, embodiment and the economics of running AI.
 blog.alexewerlof.comarticleAdded 24 Oct 2026, published 23 Oct 2026🧠 AI
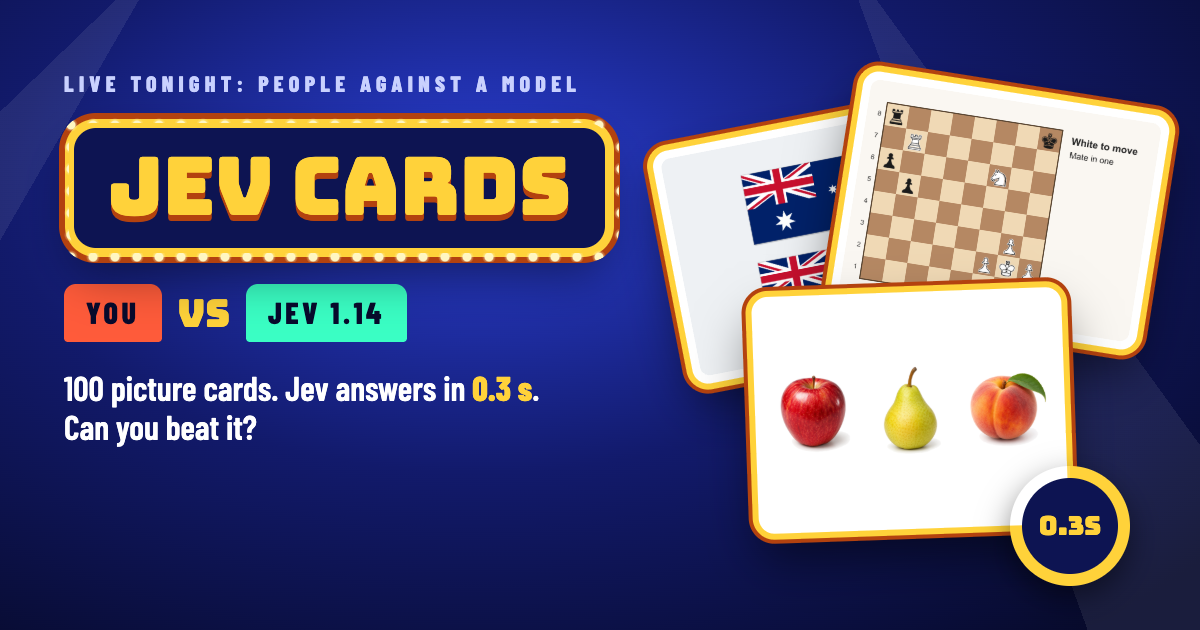 Show HN: Jev Cards, Can you beat a vision model at a picture quiz?
Jev Cards is a browser picture quiz where a player competes against Jev 1.14, a vision decision model. The 490 cards cover fruit, flags, maps, chess and illusions. Jev reads the image and question and returns a probability for every option, or a box for "tap the place" cards, in one call of about 0.25 seconds. It never writes text. The page reports 5,256 wins in 6,820 games.
 jevcards.comtoolAdded 21 Oct 2026, published 20 Oct 2026🧠 AI
 Nick Frichette (@Frichette_n) on X
Datadog Security Labs announcement, posted by Nick Frichette, of research on steering the evaluations of a prompt-injection detector called "Jev". The team's method cut its detection rate from about 83% to about 4% in their tests. They also used it to bypass LangChain's experimental tool-risk gating feature that is based on Jev. The tweet gives no method details and links to the full article.
 x.comthreadAdded 21 Oct 2026, published 19 Oct 2026🛡️ Security
 TokenMaxxing: How to Get the Most Out of Your AI Models
Decrypt guide to "tokenmaxxing" reframed as maximizing value per token rather than burning tokens. It gives tiered tips: pick smaller models for simple jobs, write one clear prompt, start new chats, cap output length, and use free models (beginner); Claude Code commands like /model, /clear, /compact, /context, /mcp, /effort and plan mode (intermediate); and prompt caching via cache_control, 50% batch discounts, and agent budget limits like --max-budget-usd (advanced). Includes context on Meta, Amazon and Uber token leaderboards and spend, a worked invoice-processing example where routing cut cost from $30 to $3.90, and the Jevons paradox in falling token prices.
 decrypt.coarticlePublished and added 17 Oct 2026🧠 AI
- Romy (@0xBunny) on X
Tweet from 0xBunny announcing an update to Jev Workflows, an open-source workflow toolkit. It adds native Claude Code support alongside Codex, an opt-in Jev 1.14, experimental image/Box questions, shared QQ contract sync and local CI. Features were also mirrored to a sibling project called QQ. It is free, with no plugin quotas, and links to a GitHub repo.
x.comthreadAdded 17 Oct 2026, published 16 Oct 2026🧠 AI  Granite Switch 4.1: Chat, Decisions, and Speech from One Endpoint
IBM announces Granite-Switch-4.1-8B and -30B. Each composes a base Granite model with a Decision aLoRA, a Guardian safety aLoRA and the Granite-Speech-5.0-Turbo-CTC ASR model into one model that uses about the same VRAM as the base alone. Because the adapters are Activated LoRAs, they reuse the base model's KV cache, and with IBM's vLLM contributions for faster LoRA inference one endpoint can handle chat, decision and speech requests. The post compares the setup with Jev (a 5-step RAG workflow race, and a 3B Doom-playing model at 60–100 decisions/s against Jev's reported 10), and says users can compose their own Switch models from Granite Libraries adapters.
huggingface.coarticlePublished and added 15 Oct 2026🧠 AI- [tl;dr sec] #350 - Reverse Engineer Anything, Tracking AI-integrated Malware, Test-driving Jev
tl;dr sec issue #350 is a weekly security newsletter digest. It covers XBOW's six-day Chrome full-chain exploit built with GPT-5.6 Sol, Semgrep's IDOR benchmark metrics, the EntraGoat vulnerable Entra ID lab, Zenity's AWS Bedrock AgentCore IMDS credential theft, Cisco Talos's CAIRN hunting toolkit for AI-integrated malware, the REA reverse-engineering MCP, runZero's sshamble, and a Copilot for Word AI worm.
tldrsec.comarticleAdded 30 Oct 2026, published 15 Oct 2026🛡️ Security  Jev as a judge: How counterfeit policy steers Jev
Datadog Security Labs tests TypeSafe AI's Jev decision model as a prompt-injection detector and as the judge behind LangChain's tool-risk gating. On four public datasets Jev had 99.66% precision and 82.90% recall. A prepended "counterfeit policy" that redefines the attack categories cut recall by over 79 points. In a LangChain scenario, a user-editable profile field lowered the mean is_risky score from 0.893 to 0.290, below the 0.5 block threshold. Plain prompt injection did not move the score.
 securitylabs.datadoghq.comwriteupAdded 29 Oct 2026, published 15 Oct 2026🛡️ Security
- From Detection to Decision: Calibration and Deferral for Prompt-Injection Detection
Evaluates a native probabilistic decision model (Jev), Llama Prompt Guard 2 (22M and 86M) and an LLM judge on 47,611 held-out examples covering direct/indirect prompt injection, hard-benign inputs, obfuscation and distribution shift. The LLM judge has the best AUROC (0.897), followed by Jev (0.871), Prompt Guard 2 86M (0.757) and 22M (0.714). Jev's native probabilities do not consistently beat post-hoc calibrated classifier scores, and temperature scaling improves calibration but not discrimination. At a 1% false-negative-rate target, every system needs over 91.8% escalation, so probabilistic outputs alone do not give reliable security decisions under distribution shift.
arxiv.orgpaperAdded 17 Oct 2026, published 14 Oct 2026🛡️ Security - [AINews] AI Engineer NYC: Gemini 4 Argon, Vals AI Benchmarks
AINews issue for 10/12–10/13/2026 covering the GA of Google's Gemini 4 Argon (pricing, Cursor/Devin/Copilot availability, CursorBench 52.8%, Artificial Analysis Intelligence Index parity with GPT-6 Astra at lower cost) and Meta's Muse Wonder, with independent evals and reliability caveats. It also summarises decision-model benchmarks (AA Decision Index, Jev 1.13, Nimble-v4), Fish Audio's open-weight Drama 3 TTS, agent-harness and agentic-RL research (Evo2, ReHarness, LongHarness, ThunderSync), Anthropic's move off Git, and safety items such as Argon's monitor evasion. It also notes AI Engineer NYC keynotes on AI x Finance. Useful as a curated, caveat-aware snapshot of the frontier-model landscape.
 latent.spacearticlePublished and added 14 Oct 2026🧠 AI
- Jetwani Avinash (@jetwaniavinash) on X
Announcement of jevmem, an open-source MIT plugin that gives Claude Code, Cursor and Codex persistent project memory. After each turn it asks Jev (a TypeSafe AI model) whether anything is worth keeping (a rule, decision, failure, or to-do) and writes one line to a plain Markdown file tracked in git. It also checks commands against saved rules before they run and asks first, or blocks. Reported results: Claude followed the rule in 66 of 72 sessions vs 28 without it, the right save/skip call on 98.5% of 66 turns, and 66 of 68 rule-breaking commands caught out of 274 test commands. Listed in Anthropic's Claude plugin directory and on the MCP Registry.
x.comthreadPublished and added 10 Oct 2026🧠 AI  [AINews] TypeSafe/Jev at >$100M ARR, $7.5B valuation 3 weeks after launch
AINews issue for 10/8–10/9/2026 from Latent Space. It leads with "decision models" (typed single-pass outputs) becoming a product category after Jev, with OpenAI Decisions API, Microsoft-Decision-1, Perplexity pplx-decider, Cloudflare clef, Liquid d1, and Unsloth/Qwen3.5 training recipes. It also covers Claude Managed Agents dynamic workflows (up to 1,000 agents), a Vals AI study of agent teams, Codex updates, model releases (Qwen-Image-2.1-Turbo, StepFun Step 5 Preview, Solar Mini 4, Gemini 4 Argon), and inference/training systems news (vLLM/SGLang on Vera Rubin, TRL v1.15, DeepSeek stride weak spots).
latent.spacearticlePublished and added 10 Oct 2026🧠 AI I expect rapid progress but not towards general superintelligence
Nathan Lambert argues that near-term AI progress will come mostly from automating infrastructure and engineering work (superhuman distributed GPU engineers, end-to-end optimization of training and inference), not from models becoming broadly superhuman researchers. He predicts near-exponential declines in the cost of model intelligence, automated pretraining research on architecture and data selection in 2-3 years, and a Jevons-paradox surge in demand for agentic models such as Meta's Muse. He also flags low-quality RL environments sold by fast-growing data companies as fixable low-hanging fruit.
 interconnects.aiarticlePublished and added 9 Oct 2026🧠 AI
- Specialized Decision Models vs. General-Purpose LLMs: Benchmarking Jev Across Knowledge, Reasoning, and Multilingual Tasks
Evaluates Jev, a "System One" decision model that returns a choice among given options instead of generating text, on 13 multiple-choice benchmarks covering knowledge, reasoning and multilingual understanding. It is compared with 19 LLMs in frontier, representative and small tiers. Jev is competitive with frontier LLMs on knowledge and commonsense tasks, and best on MMLU-Redux and ARC-Challenge. It beats most representative LLMs and all small ones outside math, but is 17.7 points below the frontier median on MathQA and scores lower than all 19 LLMs there. This suggests specialized decision models can match general LLMs on knowledge-driven decisions but not on multi-step calculation.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI - llm-openai-decisions 0.1a0
Simon Willison built llm-openai-decisions, a plugin for his `llm` CLI tool that wraps OpenAI's newly announced Decisions API (unveiled at DevDay), modeled on his existing llm-typesafe plugin for Jev's competing API. Both APIs support structured yes/no, multiple-choice, and score-style questions, but OpenAI's gpt-6-luna model also accepts image input (at 10 cents per million input tokens, versus Jev's 4.2 cents), and the plugin itself was built by having GPT-6 Astra read OpenAI's docs. The post includes install instructions and a worked example querying an image attachment for a yes/no answer.
 simonwillison.netwriteupAdded 7 Oct 2026, published 6 Oct 2026🧠 AI
- Agent in a Bottle: Can LLM Agents Turn Their Capabilities Into Cheap, Scalable Artifacts?
This paper introduces BOTTLED, a benchmark testing whether LLM agents can autonomously convert their general task-solving ability into cheaper, scalable artifacts (e.g., training a small distilled model or writing a reusable program) when faced with millions of similar queries under fixed time, compute, and API budgets, a capability the authors call bottling. Across ten models and three tasks, the authors find zero-shot performance does not reliably predict bottling success: 48 of 60 runs scored below their own model's zero-shot confidence interval, and 31 of 60 underperformed simple small-model distillation baselines. Despite this, strong agents like Opus 5 can retain about 82% of zero-shot macro-F1 at about 657x lower cost on query-product relevance classification, and recover about 94% of a dedicated cheap-inference model's (Jev) performance at a quarter of its cost.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026🧠 AI - browser-use/jev-ultrafast
jev-ultrafast is an open-source browser automation agent (from Browser Use) that represents each page as an indexed element table and uses a 'TypeSafe' policy to speculatively predict both the next operation (CLICK, TYPE_TEXT, SELECT, SCROLL, WAIT, DONE, BLOCKED) and its target in a single network round trip, only invoking a small LLM (e.g. inception/mercury-2.5 via OpenRouter) to generate text when the operation is TYPE_TEXT. The repo includes a local inspector UI, Chrome automation via a 'Browser Harness' tool, offline tests, and published before/after benchmarks showing a Google Flights search dropping from a median 9.45s to 7.09s and browser protocol calls from 1,092 to 101 across repeated runs.
 github.comrepoAdded 6 Oct 2026🧠 AI
- Fast Models, Slow Evidence: Paired and Self-Audited Evaluation of System-1 Decision Models for LLM Agent Harnesses
This paper runs a paired, reproducibility-focused evaluation of two System-1 single-forward-pass decision models, open-weight Laya and hosted Jev, across 11 typed decision points that agent harnesses make constantly: tool selection, RAG relevance gating, prompt-injection detection, and zero-shot model routing, using 7,283 base cases plus 6,640 robustness variants from 18 public sources. Jev beats Laya on 9 of 11 decision points by 10.8-46.0 percentage points, both models fail at zero-shot model routing, and Laya flips 30 percent of answers under option reordering and degrades badly with many or similar candidates. The authors also self-audit their own pipeline, finding and correcting three analysis errors and a design confound, including a reported 23.9 percent cost saving that was actually 4.3 percent, and gate accuracy conflated with end-to-end quality.
arxiv.orgpaperAdded 5 Oct 2026🧠 AI - Show HN: Made an open-source Lego AI generator
ldraw-nova is an open-source agentic pipeline where an LLM agent (tested with models like Claude Opus 5.5 and GPT-6 Astra) takes a build prompt, reads LDraw-building instructions, and produces a plan.json describing a model's geometry. From that plan it writes a Python generator script that, when executed, outputs an LDraw (.mpd) 3D CAD source file, viewable in 3D/VR (Meta Quest 3) or exportable to Blender-editable glTF. The agent uses jev-rerank, a semantic search tool with reranking backed by TypeSafe's Jev System One model, to find suitable LEGO parts and example models, falling back to full-text search without an API key; it also uses headless rendering and collision/gap detection to self-inspect and iterate on designs.
github.comrepoAdded 3 Oct 2026, published 2 Oct 2026🧠 AI - brrrock (@bchap1n) on X
Announcement of an updated model card for JEV-27B-VL, an open-weight vision-language model released under Apache-2.0. The card covers the model's weights and a "decision adapter," a BoE (Bag/Blend of Experts) architecture paired with a System 1 / System 2 reasoning setup, calibration details and decision prompts, serving instructions for vLLM and SGLang, and an evaluation of image recommendation quality.
x.comthreadPublished and added 2 Oct 2026🧠 AI  Academia is for Ambition — Alex Zhang, MIT
A Latent Space podcast transcript/interview with MIT PhD student Alex Zhang, creator of Recursive Language Models (RLMs) and a core contributor to GPU Mode and KernelBench, who discusses using recursive subagent calls, context offloading, and shared memory to let models work beyond fixed context windows. The conversation ranges across AI-generated GPU kernels and their verification gap, research taste in academia versus industry labs, why "harnesses" (as in Claude Code, Codex, and Pi) function as compositional generalizers, the Jev model's non-autoregressive output-space trade-offs, and large-scale agent swarm experiments at OpenAI, Kimi, and Sakana AI. It offers a researcher's-eye view of where capability overhang and new agent/harness architectures may be heading beyond today's standard transformer decoder.
latent.spacewriteupPublished and added 2 Oct 2026🧠 AI Amada Echeverría (@amadaecheverria) on X
Jes is an open-source real-time guardrails library for AI agents built by LangChain Ambassador Eden Marco, designed to check every step of an agent's trajectory: prompts, tool calls, tool results, skills, and final responses. It runs as LangChain middleware and uses decision models like Jev from TypeSafe AI via a TypeSafeClassifier to make pass or fail calls at each checkpoint, with docs showing a concrete middleware integration example.
x.comthreadAdded 3 Oct 2026, published 1 Oct 2026🧠 AI- Amada Echeverría (@amadaecheverria) on X
jes is an open-source real-time guardrails project for AI agents, built by LangChain Ambassador Eden Marco, that inspects every step of an agent's trajectory — prompts, tool calls, tool results, skills, and responses. It runs on decision models like Jev from TypeSafeAI and ships with a LangChain middleware example for wiring the checks into an agent pipeline.
x.comtoolAdded 3 Oct 2026, published 1 Oct 2026🛡️ Security - LLM2Jev: LLMs Are Already Jev-Style Decision Models -- When and How to Fine-Tune Them
LLM2Jev is an architecture-preserving framework that extracts calibrated categorical decisions directly from an LLM's next-token probabilities over bracketed numeric identifiers, rather than generating free-form text. The paper shows Qwen3.5-4B already matches community Jev-style decision models out of the box (training-free), while fine-tuning with a tree-factorized listwise loss plus KL-divergence anchoring to the base model gives targeted gains mainly for weaker backbones (like Qwen3-0.6B) and tasks such as many-option intent routing, without degrading conversational generation.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI  Clef / Clef-flash decision models (Cloudflare)
Cloudflare announces Clef and Clef-flash, open-weight "decision models" (Apache 2.0, on Hugging Face and Workers AI) that are Jev-API compatible and return typed, probability-scored classifications instead of generated text. The models are built by post-training a frozen Qwen backbone (Qwen3.8-27B for Clef, a smaller Qwen3.5 variant for Clef-flash) with rank-256 LoRA adapters, a two-stage attention-routing head that scores schema choices non-autoregressively in a single prefill pass, label-smoothed cross-entropy plus Brier-loss calibration, and a custom RL objective called RLCD (Reinforcement Learning for Calibrated Decisions). Cloudflare also launches a fine-tuning/RL service for customers to adapt Clef, built on AI Gateway (traffic capture), Workers AI (rollouts), Containers (RL sandboxes) and a new "Trainer" component for weight updates.
 blog.cloudflare.comarticleAdded 3 Oct 2026, published 1 Oct 2026🧠 AI
- USA SuperIntelligence | USASI (@USASIHQ) on X
AutoTrust AI announced autotrust/JEV-27B, an Apache-2.0 open-weights model built on a frozen Qwen3.8-27B backbone that produces calibrated "System 1" (fast, confidence-scored) decision outputs while the same weights also serve ordinary text generation. The tweet links to a Hugging Face blog post with the model card and release details.
x.comthreadPublished and added 1 Oct 2026🧠 AI




Showing 30 of 66
Show more