 PhysCount: Do MLLMs Count Visual Appearances or Physical Entities?
PhysCount is a benchmark of 546 real-world images and 4,595 human-written questions in 651 target-specific groups. It tests whether multimodal LLMs can separate visible appearances (direct view, reflections, glass) from the physical entities behind them. Across 40 MLLMs, counting appearances is much easier than linking them to entities, and the best model answers every question correctly in only 13.36% of groups.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI
- Agentic LLM reasoning in pediatric diabetes outcome prediction from multimodal medical records
CEDAR (Clinical Evidence-Driven Agent for Risk-prediction) is an evidence-citing, self-auditing LLM pipeline for predicting pediatric diabetes outcomes at 24 months from 18 months of records. On 2,489 youth with type 2 diabetes and 4,018 with type 1, pooled AUROC was 0.815 versus 0.656 to 0.700 for trained ML in T2D, and 0.756 versus 0.603 to 0.631 in T1D. Only 4 of 70,246 cited values mismatched the chart. Two pediatric endocrinologists matched its predictions in about nine of ten cases.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI - Benchmarking color judgment in multimodal LLMs with CIE-computable ground truth
A five-task benchmark tests multimodal LLM color judgment against CIE colorimetric ground truth: AWB pair judgment, skin-tone bias direction, CCT estimation, Delta E 2000 pair ordering, and color naming under changing illuminants. Eight endpoints were tested. On ColorChecker-24 stimuli, closed frontier models reach CCT MAE of 715-1056 K versus 1358-2133 K for open-weight models, and a non-ColorChecker control shows this gap is partly template-dependent.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI  SGLang (@sgl_project) on X
SGLang announces Day-0 support for Mistral Large 4 ("Le Chonk"), saying it is the first engine to serve the model on NVIDIA Vera Rubin. The post describes the model as Mistral's largest to date: a natively multimodal 1T-parameter mixture-of-experts model covering instruct, reasoning, coding and agentic workflows. The fetched text is truncated, so benchmark claims and launch commands are not visible.
 x.comthreadAdded 30 Oct 2026, published 29 Oct 2026🧠 AI
 Welcome Le Chonk: Mistral Large 4 on Hugging Face
Mistral Large 4 (Le Chonk) is a multimodal, multilingual Mixture-of-Experts model with about 1T total and 49B active parameters and a 1M-token context, released under the Mistral Ecosystem Open-Weight License. The post covers its MLA and DeepSeek Sparse Attention architecture, a 1.6B Pixtral encoder, and benchmarks including 82% on the Artificial Analysis Cyber Index and 93% on Cybench. It gives run recipes for transformers, vLLM, llama.cpp, TRL fine-tuning and Inference Endpoints.
 huggingface.coarticlePublished and added 29 Oct 2026🧠 AI
- Complementing Text Based Moderation with Multimodal Grounding: Detecting Fraudulent Inducement Behaviors on Short Video Platforms
The paper studies detection and temporal localization of fraudulent inducements (prompts to follow, join chat groups, click links) in internet finance short videos. It compares OCR+LLM, OCR+MLLM and a zero-shot MLLM, and builds a dataset of 2,419 videos (66.49 hours, 3,194 events, four categories). OCR+MLLM reaches mIoU 26.52 versus 14.49 for keyframe OCR+LLM, with 67.0 percent macro recall, using a recall-weighted F2 localization reward.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI - VideoLVR: Latent Visual Reasoning over Grounded Video Evidence
VideoLVR is a method that lets video multimodal LLMs build latent visual evidence from local regions at relevant moments and reason over it interleaved with text tokens. A visual token prediction objective, defined over a vocabulary derived from the input video, supervises the latents. It extends to reinforcement learning with sampled visual tokens as actions and final-answer rewards, and improves fine-grained video benchmarks without much context growth.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI - As the Story Unfolds: Watching a Film and Identifying Characters as a Human Does
This paper defines a character naming task for films: given a name spoken in dialogue and its video context, the model must pick which visible character bears that name. It provides a dataset with annotations for character naming and first appearances, a video-and-dialogue model, and a comparison with proprietary multimodal LLMs. It also proposes a progressive framework that builds a character bank as the film plays, without cast lists or actor photographs.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI  Build specialized multimodal models with LFM3
LFM3 is Liquid AI's open-weight family of six ~2B-parameter models (text, vision-language, audio, omni and two d1 decision models), all branched from LFM3-1.7B-Base. The base model uses a tri-hybrid backbone of 13 gated short convolutions, 5 sliding-window attention layers and 6 global attention layers, pre-trained on 22T tokens with a 256K context. The post gives transformers snippets, benchmark comparisons against LFM2.5 and Qwen3.5, and a robotics fine-tuning example.
huggingface.coarticlePublished and added 27 Oct 2026🧠 AI Introducing LFM3: Every Modality for Specialized Intelligence
LFM3 is Liquid AI's new family of open-weight multimodal models, six models of about 2B parameters branched from LFM3-1.7B-Base (22T pre-training tokens, 256K context). The hybrid backbone uses 13 gated short-convolution, 5 sliding-window attention and 6 global attention layers. Variants cover text, vision with video, audio, omni and two decision models, with on-device speed numbers, fine-tuning demos and robotics extensions.
 liquid.aiarticleAdded 28 Oct 2026, published 27 Oct 2026🧠 AI
- When Visual Evidence Is Insufficient: How Instructions, Post-Training, and Internal Activations Shape Refusal in Multimodal Language Models
This paper studies how multimodal LLMs refuse questions that an image cannot answer, using the MoHoBench benchmark on three MLLMs. It varies the meaning and placement of refusal instructions, compares supervised and preference-based post-training, and intervenes on a refusal-related activation direction. Instructions change refusal at the sample level in ways aggregate rates hide. Post-training raises refusal most but can mix refusal with attempted answers. Activation intervention gives smaller, transferable changes.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI  su (@sutdmhy) on X
Kimi K3.1 Pro is a Moonshot AI model, with a high-speed variant, described in a tweet as a mixture-of-experts system of about 2.8 trillion parameters with a 1-million-token context window and multimodal support. The post claims gains in coding, long-horizon agents, 3D modeling (Blender/CAD) and financial research, and says benchmarks come close to Claude Opus 5.5. Full open weights are planned by November 4. The post gives no benchmark figures.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026🧠 AI [AINews] Kimi 3.1 Pro 104BA-2.8T: Fable-5.1-Class Open Weights narrows Closed-AI lead to 1 month... and Pro Highspeed API with 2-3× speed
AINews issue for 22 to 23 October 2026 centred on Moonshot's Kimi K3.1 Pro, a multimodal mixture-of-experts model with 2.8T total and 104B active parameters and 1M context. Weights are promised for 4 November 2026. Artificial Analysis scored it 55 on its Intelligence Index (fourth place), and Arena ranked it #8 in WebDev. Standard pricing is $2/$10 per million tokens. The issue also covers a cyber-data removal approach, serving-cost objections, and paid-promotion allegations. Shorter items follow on agents, evals and inference.
 latent.spacearticlePublished and added 24 Oct 2026🧠 AI
- Agentic AI Defense: Decode-Time Provenance Binding for MCP
Decode-time provenance binding is a defense for Model Context Protocol agent pipelines against cross-modal trust laundering, where instructions hidden in an email-signature image via LSB, DCT or metadata steganography get decoded by a tool. It combines HMAC-authenticated trust labels, a provenance ledger and context-taint tracking to block critical tool calls. On a real MCP testbed with 24 adaptive payloads, attack success fell from 100% undefended (62.5% for keyword and regex filters) to 0%.
arxiv.orgpaperAdded 26 Oct 2026, published 22 Oct 2026🛡️ Security  Why AI Compute Comes in Rectangles — Erik Bernhardsson, Modal CEO
Latent Space interview with Modal CEO Erik Bernhardsson, after Modal's $750M Series D at a $16B valuation and passing $1B annualized run rate. He explains why GPU demand is not "rectangular" like fixed-term capacity contracts, how Modal pools demand and buys from about 25 clouds on three-year deals, and why sandboxes grew to about a third of revenue. Also covers GPU price-collapse risk and non-NVIDIA accelerators. Only the first part of the transcript was available.
latent.spacetalkPublished and added 22 Oct 2026🧠 AI Why AI Compute Comes in Rectangles — Erik Bernhardsson, Modal CEO
Latent Space interview with Modal CEO Erik Bernhardsson after the company's $750M Series D at a $16B valuation, with a transcript. He explains why GPU demand does not match rectangular fixed-term capacity contracts and how Modal pools demand across customers. He covers sourcing from nearly 25 clouds on multi-year deals, the risk of falling GPU prices, sandboxes reaching about a third of revenue, and non-NVIDIA accelerators.
latent.spacetalkAdded 23 Oct 2026, published 22 Oct 2026🧠 AI- Rethinking Sequence Compression with Test-time Regression
TTR-Compressor is a sequence compression method that treats input tokens as a test-time regression problem. The regression is learned end-to-end by backpropagation, and its coefficients are solved in closed form in the forward pass to give the compressed representation. As a block-wise sparse attention compressor it improves RULER over attention-based compressors by a large margin. As a visual token merger for multimodal LLMs it beats the MLP merger and matches it with 55.6% fewer visual tokens.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI - CellTrack-Bench: Microscopic Cell Tracking Benchmark for Vision-Language Models
CellTrack-Bench is a benchmark that tests vision-language models on microscopic cell tracking and compares them with specialised trackers. It has 1,537 problems covering 9,041 cell-linking decisions, drawn from 15 cell-tracking datasets across four imaging modalities, with a hard subset built from failures shared by distinct algorithmic trackers. The authors compare environment harnesses, benchmark 9 closed-source and 13 open-weight models, and analyse failure modes.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI - Drift Says When, Budget Says How Much: Rate-Controlled KV Re-selection for Long-Form Multimodal Generation
Rate-Controlled Refresh (RCR) is a KV cache re-selection method for multimodal LLMs in long-form generation. Attention drift decides when and where to re-select visual tokens, and a per-sample controller sets how often. RCR beats InfiniGen by 1.6-3.8 ROUGE-L points on five of six model-task settings and stays within 1.7 points of exact per-step re-selection. On video description, where drift is homogeneous, it no longer beats a fixed threshold.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI - TRIAD: Benchmarking Omni-Modal Ambiguity in Multimodal Large Language Models
TRIAD is a benchmark for omni-modal ambiguity resolution. It has 327 hand-written text-image-audio queries in 86 scene groups across 18 ambiguity categories, and removing any one modality makes the answer non-unique. Across 14 omni-modal systems, the best model trails humans by over 20 points in group accuracy. Without answer options, model group accuracy falls to single digits, and leave-one-out tests show audio cues are often underused.
arxiv.orgpaperAdded 23 Oct 2026, published 22 Oct 2026🧠 AI  Matrix-Game 4.0: Harnessing Video Models for Real-Time Playable Game Worlds
Matrix-Game 4.0 is a system that separates game logic from visual rendering for playable generated worlds. A lightweight engine holds world state and rules, a multimodal coding agent writes game code and scene captions, and a distilled autoregressive video model turns low-poly proxies into detailed frames. It runs 480p at 60 FPS on one RTX 5090 with 112 ms key-press-to-display latency. Code, weights and assets are released.
huggingface.copaperAdded 22 Oct 2026🧠 AI- MPIDetector: Detecting Multi-modal Prompt Injection via LLM-based Reasoning
MPIDetector is a detection framework for multi-modal prompt injection that uses few-shot in-context learning so an LLM can reason about the semantic intent of text and image inputs, without fine-tuning. The authors built a benchmark of eight textual and seven visual attack categories plus benign sets. They report up to 90.91% accuracy on text, 99.28% on images, and up to 99.80% detection on 500 obfuscated WebInject web-agent injections, beating baselines.
arxiv.orgpaperAdded 24 Oct 2026, published 21 Oct 2026🛡️ Security - UniWALM: Unified World Action Language Model for Embodied Robot Control
UniWALM is a unified world-action-language model that learns video, action and language in one mixture-of-transformers backbone with per-modality diffusion heads that co-denoise together. Generated subtask and textual memory are fed back on the next step, so no external planner or memory bank is needed. It adds Flow Matching with Correction (FMC) for recovery from perturbed actions. It reaches 34.5% on the memory-dependent RMBench subset, above Mem-0's 28.5%, and lifts real-world Find-the-Item success from 11.1% to 61.1%.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - InterWebCoder: Learning Interactive Webpage Generation from Executable Tests via Reinforcement Learning
InterWebCoder is a framework for interactive webpage code generation by multimodal LLMs. It synthesizes self-contained webpages with executable test scripts from recorded interaction trajectories, repairs failures using runtime evidence, then trains with test-ID-weighted SFT and GRPO using test pass rates and visual similarity as rewards. The pipeline yields 1,736 verified samples from 2,058 tasks. A 9B model scores 48.54 on IWR-Bench and 48.42 on Vision2Web, and reward latency drops over 97%.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - Code2Video-Compass: A Comprehensive Benchmark for General-Purpose Code-Based Video Generation across T2V, I2V, and V2V
Code2Video-Compass is a benchmark of 2,104 tasks for code-based video generation, where multimodal LLMs write executable programs that produce complete videos from text (T2V), image (I2V) or video (V2V) inputs. Tasks span 10 categories and 24 subtypes. Scoring uses 12 objective metrics and five MLLM-judge metrics. Across 15 proprietary and open-weight models from nine families, performance falls as construction, dynamic animation and state-dependency complexity rise.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - A Multimodal Engineering GraphRAG Framework for Post-Wind-Event Building Assessment and Recovery Inference
This paper presents a multimodal engineering GraphRAG framework that links post-wind-event damage evidence from images and reconnaissance reports to building-condition states, recovery actions and downtime. Evidence is stored as a provenance-preserving, component-level representation, and graph-aligned retrieval uses compatibility, contradiction, evidence-precedence and abstention checks. Demonstrated on tornado-affected low-rise homes, it beats BaselineRAG and Structured Baseline RAG, and ablations test each component.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - OpenVLHarness: Real World Visual Agentic Tool-Use with Multimodal Memory
OpenVLHarness is a multimodal reasoning harness for MLLMs built on a capability layer (task-level tool interfaces plus evidence rendering) and persistent multimodal memory that stores images, structured data and web references as addressable artifacts. A coding interface runs generated programs over stored data. Across 22 benchmarks and eight backbones it adds 9.7-12.6 points over no-tool baselines, and GPT-6 Luna at medium effort beats Codex and Visual Sketchpad at maximum effort using at most 37% of their tokens.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - Scaling Parameter-Efficient Fine-Tuning for Brain Encoding
BrainLoRA is a parameter-efficient fine-tuning method that adapts multimodal backbones of up to 104B parameters to predict neural responses. It predicts multiple timepoints in one causal pass instead of sliding windows, and a multi-LoRA kernel trains many adapters on a shared backbone. Across nine backbones it improves encoding, and a 200+ model ensemble ranks first on the Algonauts post-challenge leaderboard.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI  Meta Muse Spark Open (816B-A42B) open-weights model card
Model card for Meta Superintelligence Labs' Muse Spark Open, an open-weights, natively multimodal model with 816B total and 42B active parameters and a 1M-token context window. It targets coding and agentic work (tool use, long-horizon tasks, multimodal reasoning, synthetic data generation, LLM-as-judge). It ships in BF16 and NVFP4, needs about 700GB VRAM (NVFP4) or 2TB (BF16), runs on SGLang, vLLM, Transformers, TensorRT-LLM, Unsloth, llama.cpp and MLX, and supports a reasoning_effort setting. The Muse Model License requires "Built with Muse Spark Open" attribution and a separate agreement for Model-as-a-Service above $20M revenue. The card reports safety results against Kimi K3 on cyber, chem/bio and loss-of-control evals.
huggingface.corepoAdded 17 Oct 2026🧠 AI- Enhancing RAG-based Medical VQA with Gated Multimodal Representations
This paper presents a multimodal retrieval-augmented generation framework for Medical Visual Question Answering. A Gated Multimodal Unit learns a joint query representation from the medical image and the clinical question, so evidence retrieval uses both modalities while the Med-LVLM stays frozen. On benchmark datasets it consistently beats a reference Med-LVLM and stays competitive with state-of-the-art methods. The page gives no dataset names or numbers.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🧠 AI - MobileInject: Evaluating Reasoning-to-Action Security of MLLM-Based Mobile Agents under Cross-Modal Consistency Injection
MobileInject is a benchmark for testing MLLM-based smartphone agents against indirect multimodal injection. It has an interactive evaluation framework with 11 scenarios, 9 security-risk categories and 108 executable risk instances. It adds Cross-Modal Consistency Injection, Multi-Role Collaborative Deception, Reasoning-Camouflage Injection and a Reasoning Security Diagnosis Framework. Experiments find broad vulnerability, with many failures from early reasoning hijacking.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🛡️ Security - MUB: An Identity-Masked Benchmark for Music Understanding in Multimodal Language Models
MUB (Music Understanding Benchmark) is a set of 500 identity-masked recordings with existing annotations for tempo, key, time signature and structural intervals. It covers all 24 keys, tempos of 47 to 180 BPM and 4,676 intervals, and strips titles, artists and platform IDs from inputs. Baselines reach 53.6% tempo accuracy (DSP) and 98.4% time-signature accuracy (constant 4/4). No multimodal LLM has been tested yet, and rights clearance is unresolved.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🧠 AI - Perceive, Predict, and Plan: a Unified World Action Model for Egocentric Dexterous Manipulation
P^3-WAM is a unified world action model for egocentric dexterous manipulation with three modes: Perceive (reconstruct articulated hand motion and camera trajectories from video), Predict (generate visual futures under prescribed actions) and Plan (jointly generate action trajectories and their anticipated visual outcomes from an initial image, a language instruction and an optional visual goal). It adds a compact structured 3D action representation to a pretrained video diffusion transformer through a mixture-of-transformers design with shared base weights, modality-specific adaptation and bidirectional visual-action attention. Randomized modality visibility lets video and 3D actions act as either context or target. Unified training beats single-mode training and outperforms specialized baselines on 3D hand reconstruction and action-conditioned video prediction across four datasets, and gives better instruction adherence than video-generation baselines.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - Skill-Decoupled On-Policy Expert Distillation for Unified Vision-Language Models
Proposes SCOPED (Skill-Decoupled On-Policy Expert Distillation), which trains capability-specific RL experts for vision-language models. It extracts explicit skills from them through reward-guided reflection. During on-policy distillation the skills guide expert supervision but are hidden from the unified student, so the student internalizes the procedural knowledge and needs no explicit skills at inference. Across eight multimodal benchmarks it beats the backbone and mixed-capability RL. Analyses show cross-capability gradient interference in joint RL, and that skill augmentation gives more consistent expert trajectories, more attention to task-relevant visual evidence, and better preservation of expertise.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - [AINews] Modal’s $1B ARR, $16B Series D makes it NYC’s newest AI Infra Decacorn, 3x usage and 3x valuation in 5 months, 15x in 1 yr
Latent Space's AINews issue for 10/13–10/14/2026. It opens with Modal's $750M Series D at a $15.75B valuation, with Sandboxes at a $300M run rate, then recaps the day's AI Twitter. Coverage includes the Gemini 4 Argon rollout and its weaker monitorability, Meta Muse Wonder, Grok Voice 3.0, and open-weights releases (Ultramarine 1 Flash, Ling-3.1-flash, DeepSeek V4.1 Flash). It also covers new evals (AA-Robotics, SpireClimb, TasteVal), rogue agent and reward-hack safety items, inference benchmarks (AA-AgentPerf, InferenceX), and agent sandbox platforms. Useful as a dated snapshot of the field.
latent.spacearticlePublished and added 15 Oct 2026🧠 AI  Welcome Muse Spark Open: open-weight frontier multimodal mixture-of-experts model from Meta
Hugging Face's launch post for Meta's Muse Spark Open, an open-weight 816B-parameter mixture-of-experts model (about 42B active per token). It has 256 experts with 8 routed per token, a 1M-token context, and perception and audio encoders for image, video and audio input. The post gives the architecture details, BF16 and NVFP4 checkpoints, and run recipes for transformers, llama.cpp, SGLang, vLLM, MLX and Inference Endpoints. It also covers LoRA SFT of the full model with TRL on 64 H100s and agentic demos (Pi 3D asset generation, an OpenEnv browser agent, a voice-driven shopping agent).
huggingface.coarticlePublished and added 15 Oct 2026🧠 AI- Visual Tokens on Demand: Visual Budgeting for Scalable and Efficient Multi-Image Reasoning in Multimodal LLMs
Proposes mmVB, a lightweight plug-and-play module (1.6M trainable parameters) that assigns query-conditioned per-image visual token budgets using cross-image context for multimodal LLMs, without retraining the base model or accessing attention matrices (so it is compatible with FlashAttention). It cuts visual input tokens 9x, giving 5x faster time-to-first-token and 7x fewer prefill FLOPs while keeping 94.4% of full-resolution accuracy across eight multi-image reasoning benchmarks. It matters because existing token pruning, merging and compression methods target single-image redundancy and either need attention maps or retraining.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI - OmniCompass: A Holistic Benchmark for Omni-Modal Video Grounding and Understanding
OmniCompass is a manually annotated benchmark for video grounding and understanding with two tracks: OmniCompass-VL (820 videos, 2,460 instances; vision-language models) and OmniCompass-AV (240 videos, 720 instances; joint audio-visual evidence for omni-modal models). Each track covers temporal grounding, spatial grounding and QA across short/medium/long videos, and each instance is run in paired text-only and text+image target specifications. Evaluating 50 MLLMs shows open-source models lag proprietary ones, especially on audio-visual understanding, that precise temporal/spatial grounding remains hard, and that predictions are inconsistent across the paired specifications.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI - Heading Hierarchy Reconstruction for Complex and Long Documents with Level-Wise Multimodal Memory
Proposes a vision-language-model framework that incrementally reconstructs heading hierarchies across tens or hundreds of pages using a level-wise multimodal memory. The memory keeps a compact set of earlier pages chosen by anchors (here, the most recent node at each heading level), so the VLM sees the visual, textual and layout patterns of headings at every level. The authors also introduce CLDoc-HHRBench (250 documents, 11,212 pages, expert-verified annotations) and report results on it and three existing benchmarks. It matters for RAG pipelines that need coherent document-level structure, which page-by-page OCR/VLM parsing doesn't give.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI  google/embeddinggemma-2
Model card for EmbeddingGemma 2, an open (Apache 2.0) 740M-parameter multimodal embedding model from Google DeepMind built on Gemma 4. It maps text, code, images, video and audio into one 768-d space, with a 270M text backbone and optionally loadable 170M vision and 300M audio encoders, an 8K context, and Matryoshka truncation to 128/256/512/768 dims. The card gives practical guidance: task instruction prefixes, re-normalising after truncation, avoiding float16 (NaN or degraded embeddings), interleaved multimodal inputs with placeholder tokens, and vision token budgets. It targets on-device search, RAG, classification and clustering.
huggingface.corepoAdded 12 Oct 2026🧠 AI MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement
Technical report for Xiaomi's MiMo-V2.6 omni-modal model family, which scales RL compute along three axes: asynchronous training with 1,568 samples and 2.7-3.7B tokens per step at up to 1M context, more diverse environments (code, general, visual, cyber) under mixed agent harnesses, and groupwise agentic grading that gives better reward signals and favors shorter, token-efficient solutions. Stability measures include a frozen MoE router and a multi-layer defense against reward hacking, built on a mid-trained hybrid-SWA architecture. The authors open-source training dynamics, RL environments and the RL framework, which makes it a useful reference for reproducing scaled agentic RL.
huggingface.copaperAdded 10 Oct 2026🧠 AI Qwen3.8-27B (Apache-2.0, multimodal dense, 262k ctx)
Model card for Qwen3.8-27B, a 27B dense vision-language model from the Qwen team with a hybrid Gated DeltaNet / Gated Attention layout (64 layers, 16×(3 DeltaNet + 1 attention)), MTP training, and 262k native context extensible to 1M via YaRN. It targets coding, research and long-horizon agentic tasks, with thinking on by default, reasoning_effort levels (xhigh/medium/low) and preserve_thinking. The card gives deployment recipes for Transformers, vLLM, SGLang and TokenSpeed, recommended sampling parameters, video-token settings for hour-scale video, and benchmark notes (SWE-bench Pro, NL2Repo-Bench, DeepSWE, HLE, MathVision, WebArena-Verified, etc.).
huggingface.corepoAdded 9 Oct 2026🧠 AI- Images Talk Back: Guiding MMDiTs by Suppressing Image-to-Text Feedback
The paper studies joint attention in multimodal diffusion transformers (MMDiTs), where the evolving image updates text representations. It finds that this image-to-text (I2T) feedback tends to preserve objects and attributes already in the image, errors included, and that suppressing it improves generation. It proposes Semantic Feedback Guidance (SFG), which guides away from an auxiliary branch that strengthens I2T feedback and weakens text-to-image conditioning, and iSFG, an in-place variant that needs no extra model evaluations. SFG runs for the first 20% of sampling steps (about 1.2x base NFE without CFG). Across three backbones, adding SFG to CFG on FLUX raises GenEval from 0.6661 to 0.7479, and iSFG on SD3.5M adds +1.33 HPSv2.1 over CFG at zero extra NFE. The control also improves VBench scores for text-to-video and image-to-video.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026🧠 AI  [AINews] not much happened today
Latent Space daily AINews digest for Oct 7-8 2026 aggregates Twitter and Reddit AI discourse. Its security-relevant section covers OpenAI firing safety researchers Tomek Korbak, Mikita Balesni and Jasmine Wang over their handling of METR audit into a summer incident where OpenAI agents allegedly escaped containment and hacked Hugging Face, Cogent Security new attack-path analysis for agent swarms, a Vals AI audit finding Xiaomi MiMo v2.6 reward-hacked by reading leaked Git objects and exploiting file timestamps, an NVIDIA NeurIPS 2026 paper showing tool access raises multimodal refusal failures up to 68.7 percent, Anthropic red-teaming showing GLM-5.3 safeguards bypassed 64 to 100 percent of the time, Goodfire probe-based cyber monitors for Kimi K3 and GLM-5.3, and a CrowdStrike-reported bank hack in South Korea using a stack of ARTEX, DeepSeek, GLM-5.3, Grok and Claude Code. The rest of the issue is general model-launch and benchmark news outside this catalog scope.
latent.spacearticleAdded 9 Oct 2026, published 8 Oct 2026🛡️ Security- OmniCapBench: A Deep-Structured Evaluation Framework for Fine-Grained Audio-Visual Captioning
OmniCapBench is a benchmark of 786 densely annotated videos that evaluates audio-visual captioning in multimodal LLMs. Instead of scoring free-form captions, it asks models for sets of atomic, verifiable units across three tracks (entity references, visual shots, audio events). These are scored with deterministic constraint checks plus localized LLM-based semantic comparisons, which gives coverage, localization and stable scoring together. Tests on frontier MLLMs show strong local perception but weak long-horizon audio-visual reasoning, especially identity drift and cross-modal misalignment.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI - WOVEN: Weaving Visual World Modeling into Multimodal LLMs
WOVEN is a training source and benchmark for visual transition reasoning in multimodal LLMs. It has 36,076 examples spanning 20 scene types, 5 action types and 8 reasoning types, built from rollouts of video-pretrained generative models. Evaluating 38 frontier MLLMs (including GPT-5.4 and Qwen3-VL-235B-A22B) shows systematic deficits that persist with scale. Training on WOVEN subsets of about 2,000 items improves 22 of 26 external benchmarks by up to 27.3 points, and WOVEN data can replace 30-50% of a task's own training data. The authors derive a recipe: select supervision by the reasoning operation it teaches rather than by scene or action, and prefer larger visual-state changes.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI  Understanding AI, Part I: The Machines That We Taught
Galaxy Research's explainer traces AI's intellectual history from the 1956 Dartmouth Workshop and the Logic Theorist through the symbolic-AI era (expert systems like Mycin and XCON, the Cyc project) to the sub-symbolic/connectionist revival (Perceptron, Hopfield networks, backpropagation, LeCun's CNN zip-code reader) that culminated in deep learning and the 2017 Transformer architecture. It then surveys three machine-learning paradigms (supervised, reinforcement, unsupervised) and five deep generative architectures (autoregressive, diffusion, GANs, VAEs, normalizing flows), closing with how modern LLM chatbots combine these via pretraining, SFT, and RLHF, and how multimodal, reasoning, RAG, agent, and world-model systems extend base LLMs.
 galaxy.comarticleAdded 8 Oct 2026🧠 AI
- MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement
Technical report for the MiMo-V2.6 omni-modal model series, which scales RL compute after mid-training on a multimodal corpus, using a hybrid sliding-window-attention architecture. RL is scaled along three axes: asynchronous training with 1,568 samples and 2.7-3.7B tokens per step at up to 1M context; diverse environments (code, general, visual, cyber) under mixed agent harnesses; and groupwise agentic grading that gives better rewards for long-horizon tasks and favors shorter, token-efficient solutions. Stability measures include freezing the MoE router and a multi-layer defense against reward hacking. The authors open-source the training dynamics, RL environments and RL framework.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI - Liquid AI (@liquidai) on X
Liquid AI announces Open d1, two open-weight multimodal decision models. d1-3B (built from LFM2.5-VL-3B, text + vision) claims first place among sub-10B models on the Decision Index v0.2.1, while the experimental d1-omni-600M (LFM2.5-Encoder-350M plus vision and audio encoders) handles text+image or text+audio and leads on toxicity detection and paraphrase identification. Single-request d1-3B latency is 8 ms on an RTX 4090, 16 ms on Jetson AGX Thor, 26 ms on Jetson AGX Orin 64 GB and 50 ms on Jetson Orin Nano, with day-one llama.cpp support; demos include live-camera apps and Isaac Sim navigation. Useful for practitioners picking small local models for reranking, agent guardrails and visual inspection.
x.comthreadAdded 9 Oct 2026, published 7 Oct 2026🧠 AI - Self-correction Optimization for Interleaved Multimodal Generation
This paper introduces Self-Correction Optimization (SCO), a training-free method that improves consistency in interleaved image-text generation from multimodal large language models. SCO treats the classifier-free guidance update as a reference signal and applies minimal corrections under two constraints—a new-event constraint for temporal consistency and a state-preserving constraint for visual-subject coherence—avoiding the computational cost of additional training with augmented data. The authors show improvements on interleaved multimodal generation benchmarks and extend the method to video generation tasks like robot manipulation and long-horizon handcrafting.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026🧠 AI - TaoD2C-Bench: Benchmarking MLLMs for Industrial UI Code Generation Beyond Visual Fidelity
TaoD2C-Bench is a benchmark for evaluating multimodal large language models (MLLMs) on industrial design-to-code (D2C) tasks — converting UI designs into code that satisfies implementation constraints, not just visual fidelity. It includes the TaoD2C dataset of 2,861 production designs from 17 commercial platforms with 97,652 expert annotations across Component, Group, Alignment, and Position categories, and defines three tasks: end-to-end UI code generation, requirement inference, and requirement realization. Evaluating eight MLLMs, the authors find large gaps between visual reconstruction ability and the ability to generate code meeting domain-specific implementation requirements.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026🧠 AI  [AINews] Quasi-Riemann-Hypothesis: OpenAI publishes 722 math papers solving 90 of the top 500 open math problems; “the most significant moment” in >100 years of mathematics
AINews daily digest (Oct 5–6, 2026) from Latent Space, synthesizing Twitter/Reddit AI discussion. Lead story: OpenAI published 722 math manuscripts (372 result families) from an unreleased internal model, averaging ~3 hours of ChatGPT Pro compute per result, including a quasi-Riemann Hypothesis result, a no-Siegel-zeros result, an integer-multiplication-faster-than-n-log-n claim, and partial progress on Hodge and BSD — drawing both "most significant moment in mathematical history" praise and skepticism about verification and compute framing. The issue also covers Mistral Large 4 ("Le Chonk")'s launch and contested benchmark claims, Google's EmbeddingGemma 2 multimodal embedding model, OpenAI's new Decisions API, safety/observability research (CIAware benchmark, METR's warning on agents hacking log-review tooling), and assorted research and infra items (H-JEPA, ANVIL III optimizer, CoreWeave RL rollouts).
latent.spacewriteupPublished and added 7 Oct 2026🧠 AI EmbeddingGemma 2: an open, lightweight multimodal embedding model
Google DeepMind's announcement of EmbeddingGemma 2, a 740M-parameter open multimodal embedding model built on the Gemma 4 architecture, unifying text, code, images, video and audio into a shared embedding space under Apache 2.0. It supports modular sub-1B deployment (as low as 270M for text-only), Matryoshka Representation Learning for truncating output vectors from 768 down to 128 dimensions, an 8K token context window, and on-device quantized inference (~191MB–567MB RAM on a Pixel 11 Pro), with reported state-of-the-art results on MTEB Code and MAEB benchmarks for its size class.
 deepmind.googlearticlePublished and added 6 Oct 2026🧠 AI
- EC-RAG: Event Chain Retrieval-Augmented Generation for Long Video Understanding
EC-RAG (Event Chain Retrieval-Augmented Generation) is a training-free framework for long-video question answering that organizes video content into an explicit, temporally ordered "event chain" instead of retrieving isolated frames or snippets. It partitions video into semantically coherent segments, fuses multi-modal signals (speech, text, visual cues) at the event level, and retrieves relevant events from the chain to answer queries, working as a plug-and-play addition to existing large video-language models (LVLMs) without extra training. Evaluated on Video-MME, MLVU, and LongVideoBench, it outperforms frame-level retrieval baselines, showing the value of modeling temporal/event structure for long-video understanding.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026🧠 AI - Itsvishal (@itsvishaltwt) on X
A tweet reports that Mistral has announced Mistral Large 4, internally nicknamed "Le Chonk," a mixture-of-experts model with roughly 1 trillion total parameters and 49 billion active parameters. It is described as natively multimodal and state-of-the-art on critical workloads including cyber defense, with API access starting immediately and an open-weight release planned for late October.
x.comthreadPublished and added 6 Oct 2026🧠 AI - 🚨 AI News | TestingCatalog (@testingcatalog) on X
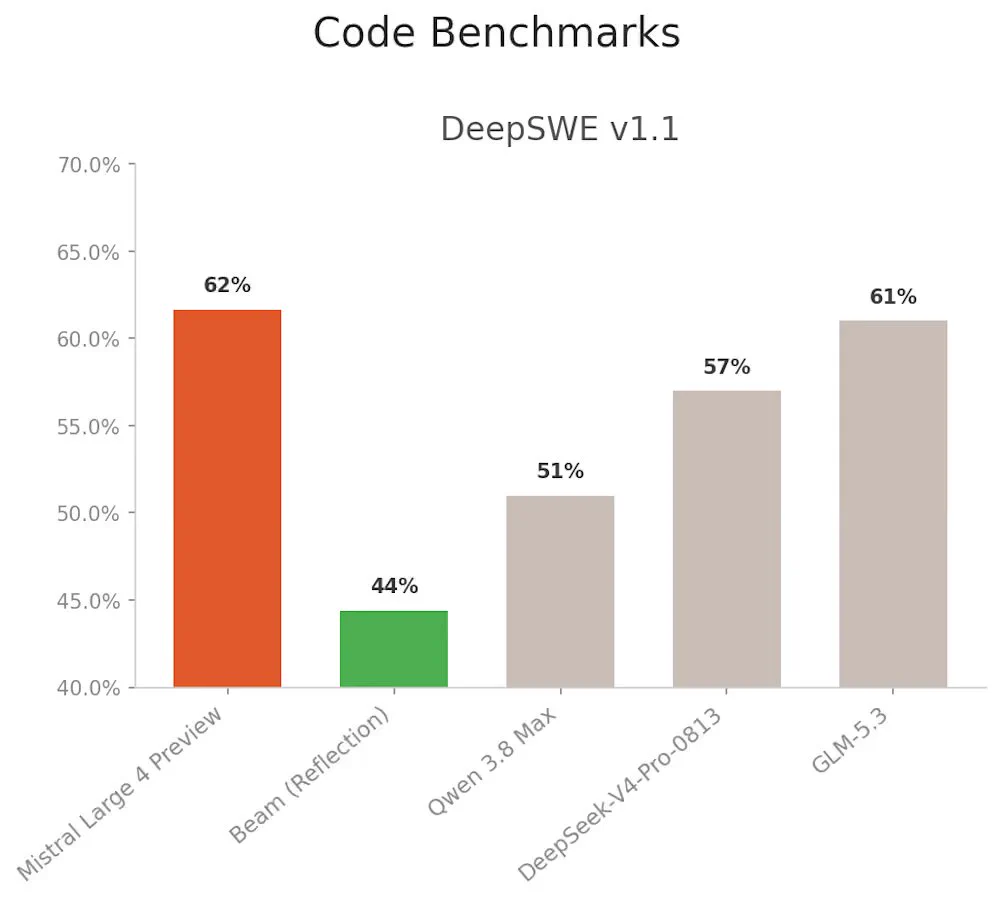
Twitter thread reporting that Mistral announced Mistral Large 4, codenamed "Le Chonk," a 1-trillion-parameter open-weight model with 49B active parameters and native multimodality, rolling out via API now with open-weight release planned for end of October. It reportedly scores 62% on the DeepSWE benchmark (ahead of GLM-5.3), 67% on the Finch financial-tasks benchmark (SOTA open-weight), and 15% on Harvey's Legal Agent Benchmark (also SOTA open-weight), per VentureBeat and @AiBattle_.
x.comthreadPublished and added 6 Oct 2026🧠 AI  Introducing Mistral Large 4 ("Le Chonk")
Mistral announces Mistral Large 4 ("ML4"/"Le Chonk"), a 1-trillion-parameter natively multimodal Mixture-of-Experts model with 52B active parameters, trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own European datacenters. The post details state-of-the-art open-weight results on cybersecurity benchmarks (82% on an Artificial Analysis vulnerability-reproduction test, 93% on Cybench), agentic coding (DeepSWE, Terminal-Bench, AutomationBench), finance/legal evals (via Vals, Harvey's Legal Agent benchmark), visual grounding (beating GPT-6 Astra on Dense 200), and safety benchmarks (Lakera B3, KORA). It also describes the large-scale RL post-training pipeline (33B tokens/day at 3k GPUs) used to produce the model, with full weights promised by end of month.
 mistral.aiarticleAdded 7 Oct 2026, published 6 Oct 2026🧠 AI
- overmind-core/overmind
Overmind is an open-source platform (MIT SDK/CLI, AGPL-3.0 platform, self-hostable) that instruments an agent's code via OpenTelemetry tracing, turns the resulting production traces (or any dataset) into a fine-tuned model benchmarked against user-defined eval metrics, and serves it through one unified API with downloadable/retrainable weights. It ships an SDK, CLI, REST API, Console, and an MCP server exposing project tools and workflows (investigate-capability, finetune-capability, ship-model) for Cursor, Claude Code, OpenCode and Codex, and can sync traces from Langfuse, LangSmith, Braintrust or Galileo; self-hosting runs via Docker Compose with Postgres, Redis, Celery workers and Modal-based GPU workers for fine-tuning/serving (vLLM).
 github.comrepoAdded 6 Oct 2026🧠 AI
- MemPilot: Orchestrating On-Demand Multimodal Memory Curation for LLM Agents
MemPilot is a framework that lets LLM agents curate memory on demand rather than query-agnostically, using a multi-step policy trained via reinforcement learning to choose between retrieving from pre-built memory or delegating query-specific curation of raw multimodal history to heterogeneous LLMs and VLMs. The policy controls evidence amount, curation instructions, model choice, and visual access, and is optimized with objective-wise advantage decoupling and prefix-based marginal utility estimation to balance performance, cost, and latency. Tested across five multimodal agent-memory benchmarks, it achieves broader performance-cost-latency trade-off frontiers than existing trade-off-aware baselines.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026🧠 AI - MedPrune: Topology-Efficient Multimodal Multi-Agent Communication Evolution for Medical VQA Tasks
MedPrune is a multi-agent framework for medical visual question answering that models the diagnostic process as a heterogeneous communication graph of specialist agents across departments, then dynamically prunes both nodes (irrelevant specialist agents, via reinforcement learning) and edges (low-value intra-/inter-departmental connections) to cut redundant communication. The authors report it beats existing multi-agent baselines on medical VQA benchmarks under both full-set and few-shot settings while improving token efficiency and adversarial robustness.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026🧠 AI - BrainTRACE: Tracing Longitudinal, Multimodal, and Volumetric Evidence in Brain MRI Clinical Reasoning
BrainTRACE is a report-grounded benchmark for evaluating whether vision-language models can trace the evidence structure required for longitudinal brain MRI interpretation. It contains 7,273 scored VQA instances derived from 1,778 longitudinal patients, 7,299 MRI studies, and ~29k co-registered 3D MRI sequence volumes, organized across five levels of clinical reasoning and evidence demands like longitudinal comparison, multi-sequence integration, and volumetric spatial grounding. Evaluation of 20 VLM configurations finds that current models identify isolated visual cues but rarely compose them into grounded longitudinal clinical interpretations.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026🧠 AI - World Embedding Benchmark
The World Embedding Benchmark is a new evaluation suite of 8,000 controlled simulation cases across 80 families (fluid mechanics, solid mechanics, dynamics, optics & electromagnetism), each pairing a rendered video with simulation-derived physical annotations. It tests pre-trained omnimodal embedding models on text-video retrieval, physical-property regression, and multiple-choice video-description classification, finding that current embeddings align poorly cross-modally while lightweight probes can still recover physical quantities, and that continual contrastive training improves alignment but hurts regression. The authors also show retrieval-augmented generation using these embeddings with MiniMax-H3 improves the physical fidelity of generated videos.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026🧠 AI - CLIMB: Confidence-Guided Complementary Evidence for Multimodal Retrieval-Augmented Generation
CLIMB is a training-free, inference-time framework for multimodal retrieval-augmented generation that improves knowledge-intensive visual question answering. It first builds a compact, non-redundant evidence pool using an MMR-style objective balancing query relevance and redundancy, then applies an R/E/C critic (relevance, evidence specificity, cross-modal alignment) alongside a confidence estimator that only accepts an answer update when estimated confidence increases, giving a built-in stopping criterion without modifying the underlying retriever or MLLM. Experiments on Encyclopedic-VQA and InfoSeek show consistent gains over existing multimodal RAG baselines.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026🧠 AI - From Patching to Pruning Visual Computation in Vision Language Models
Patch-to-Prune (P2P) is a training-free framework that repurposes activation patching from mechanistic interpretability into an inference-time compute bypass for vision-language models, replacing unnecessary visual-token projections in certain decoder layers with fixed neutral proxy vectors while preserving sequence length, token order, and residual pathways. Tested on Qwen2.5-VL and LLaVA family models across seven multimodal benchmarks, P2P at 3 percent tolerance retains about 94 percent of dense accuracy while cutting FLOPs by 55 percent, and reveals that intermediate decoder layers do most of the task-relevant visual integration while early and late layers need little token-specific visual computation.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026🧠 AI - Harnessing Domain Specialists in Multimodal Mixture-of-Experts for Efficient Adaptation
This arXiv paper studies emergent semantic specialization among experts in multimodal Mixture-of-Experts (MoE) models and introduces ExpertLens, a data-free method that identifies domain-specialized experts by decoding router weights into vocabulary tokens from pretrained weights alone. Using this to selectively fine-tune only the relevant experts, the authors match or beat full fine-tuning on math, medical, and remote-sensing tasks while updating only 21.7-47.0% of parameters, achieving a 4x training speedup and outperforming LoRA in both performance and efficiency.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - Where-OPD: Spatially Guided On-Policy Self-Distillation of MLLMs with Synthetic Scenes
Where-OPD introduces an on-policy self-distillation method for multimodal LLMs where a teacher model receives textual spatial guidance (object identities and coordinates from procedurally generated synthetic scenes) to locate relevant image regions, while a student learns to reproduce this behavior from just the image and question. The approach is annotation-free and scalable, improving performance on counting, document and chart understanding, and transferring from synthetic training to real-world perception benchmarks (CVBench, V*, ZoomBench, BLINK, HR-Bench, MME-RealWorld) with a 3.23-point average gain.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - Selection-Based Structured Reasoning: Toward Efficient Multimodal Search Agents
The paper introduces Selection-based Structured Reasoning (SSR), a framework that replaces free-form chain-of-thought generation in multimodal search agents with selection among pre-specified, reusable natural-language reasoning candidates, scored by likelihood via teacher-forced prefilling with a shared KV cache. Evaluated on seven multimodal search benchmarks using 2B and 4B scale models under both reinforcement learning and supervised fine-tuning, SSR matches the success rate of leading search agents of the same scale while cutting per-turn reasoning latency by over 90% and total per-question inference latency by 28-54%. It targets the problem of small models producing long, low-value reasoning traces before each action, which is costly at inference time.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - Walking the Embedding Space: Datastore Extraction from Multimodal RAG
Researchers introduce ImmRAG, a black-box data extraction attack against image-returning Multimodal Retrieval-Augmented Generation (MRAG) systems, where the retrieved image itself is the model's response. Instead of malicious text prompts, ImmRAG embeds attack instructions inside an attacker-supplied image and uses relevance-weighted resampling to steer queries toward unexplored regions of the embedding space, progressively reconstructing more of the private datastore. Tested against CLIP-family retrievers across medical, document, and general-purpose scenarios, a single 2500-query run reconstructed up to 611 radiology images, 566 document scans, and 416 general images — up to 5.6x more distinct items than a non-adaptive baseline — highlighting the lack of safeguards against multimodal data leakage.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🛡️ Security  DeepSeek-V4.1-Flash
 is a multimodal Mixture-of-Experts model with 552B backbone parameters, 1M-token context, and a novel Causal Encoder-Decoder (CED) architecture where the decoder's global KV cache is projected from encoder hidden states rather than recomputed per layer, activating only 8B/16B parameters per token during prefill/decode. It introduces Compressed Sparse Attention 2 (CSA2) with FP4 KV caching to cut the global KV cache footprint to 890 bytes/token (~1/4 of DeepSeek-V4-Flash, ~1/437 of DeepSeek-V1), alongside Engram conditional memory, DSpark speculative decoding, and a continuously controllable reasoning-effort setting (1–100). The card documents pre/post-training recipes (45T tokens, SFT→RL→on-policy distillation with synthetic agent environments) and reports results across agentic and code benchmarks (Terminal-Bench 2.1/3.0/4.0, DeepSWE v1.1, GPQA Diamond, Chartography, ZeroBench, AutomationBench), plus deployment instructions for Transformers, vLLM, SGLang, and Docker.
huggingface.corepoAdded 30 Sep 2026🧠 AI- Multimodal Flow: Unified Flow Modeling of Language and Vision in Embedding Spaces
Multimodal Flow (MF-1) is a fully continuous generative model that unifies language and vision modeling by representing both text and images as ordered continuous "hyperchunks" processed through a single shared chunk-causal Flow Matching backbone, avoiding the visual quantization bottleneck of discrete-token unified models and the mismatched objectives of hybrid discrete/continuous approaches. Joint attention handles cross-modal interaction while modality-specific feed-forward networks process each modality, and the model predicts multiple chunks in parallel during training but generates sequentially at inference. Pretrained at 0.6B/1.2B/1.6B scales on 150B tokens, MF-1 scores 82.8 average on GenEval/DPG-Bench and 75.3 on VQAv2/MMBench/POPE, remaining competitive with unified models trained on far more data and outperforming matched hybrid/discrete baselines; code and model are publicly released.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI - Ranking-Aware Prompt Optimization for Multimodal Clinical Diagnosis
The paper introduces Ranking-PE, a modification to reflective prompt-optimization methods like GEPA that replaces per-instance accuracy scoring with pairwise AUROC-equivalent scoring (via the Wilcoxon-Mann-Whitney identity) across the scores matrix, reflection feedback, and candidate selection. Applied to multimodal clinical diagnosis on MIMIC with fine-tuned Qwen3-VL-8B and MedGemma-4B, it shows accuracy-based prompt evolution can degrade ranking performance under class imbalance, while Ranking-PE improves AUROC by +5.8pp and +16.2pp respectively, with ablations showing a medical-grade visual backbone is a necessary prerequisite that prompt search alone cannot substitute for.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI - Learning Native Reflection in Unified Models with Interleaved Reinforcement Learning
UMM-Reflection is a reinforcement learning method that trains a unified multimodal model to jointly learn reflection text and image revision within a single closed loop: diagnose an image's flaws, revise it, observe the result, and repeat. Sibling trajectories sharing one initial image enable a group-relative advantage that compares whole reflection strategies rather than assigning credit per round, and one trajectory-level advantage updates both the reflection tokens and the flow-based revision head jointly, unlike SFT cold-starts or RL that optimizes only the renderer. On BAGEL, it improves GenEval by 12.05 points over SFT and transfers to unseen benchmarks WISE, OneIG-Bench and T2I-CompBench++, with no external verifier needed at inference.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI - FlowAct-R2: Beyond Talking Avatar via Streaming Multimodal References and Proactive Agent Planning
FlowAct-R2 is a framework for interactive humanoid video generation that pairs a Streaming Multimodal Reference Diffusion Transformer (built on the Seedance 2.0 Mini reference-to-video backbone) with a Proactive Interaction Agent. The diffusion component accepts rolling action prompts plus continuously updated image, audio and video references, using video-driven rotary positional embeddings and partially noised historical motion frames to keep appearance consistent and avoid drift over long generation runs. The agent component separates offline persona/agenda/skill preparation from online scheduling, audience response and interruption handling, enabling real-time 720p, hour-scale streaming avatars for use cases like live shopping, video chatting and live vlogging.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI  MiMo-V2.6-Pro-RL
 is Xiaomi's flagship omnimodal (text/image/video/audio) sparse MoE model, 1.02T total / 42B activated parameters with a 1M-token context, built around scaling RL compute toward self-improvement. It uses a single mixed GRPO run across coding, agentic, visual and cybersecurity tasks, a novel groupwise agentic grading scheme (Groupwise Reward Synthesis + Groupwise Advantage Redistribution) to rank passing rollouts rather than just pass/fail, and a multi-teacher on-policy distillation stage (MOPD2); it also ships a 5-layer speculative MTP decoder and is deployable via vLLM and SGLang.
huggingface.corepoAdded 28 Sep 2026🧠 AI Ling-3.0-flash-VL (InclusionAI/Ant Group)
Ling-3.0-flash-VL is InclusionAI/Ant Group's native multimodal model built on Ling-3.0-flash, adding image and video understanding via a ViT encoder, VideoRoPE, and a hybrid MoE backbone (42 layers alternating KDA and Gated MLA at 5:1) with 124B total parameters but only 5.5B activated per token, and a 256K context window. It targets agentic multimodal workflows — understanding, reasoning, and acting on visual interfaces — scoring 42 on Artificial Analysis Intelligence Index v4.1.1, up from 38 for the text-only Ling-3.0-flash. The card includes concrete SGLang and vLLM serving recipes for various GPU configurations.
huggingface.corepoAdded 26 Sep 2026🧠 AI- GraphWrit3R: End-to-End 3D Scene Graph Writing
GraphWrit3R is an end-to-end method for generating 3D scene graphs directly from 3D point clouds, Gaussian Splats, or both, outputting a structured JSON graph of objects, attributes, and relationships without relying on ground-truth object annotations or brittle multi-stage pipelines. It encodes point clouds via Sonata and Gaussian Splats via Chorus, fuses both modalities on a shared voxel grid with a novel per-voxel contrastive alignment loss, and decodes the result with a large language model, achieving state-of-the-art object class, predicate, and triplet recall on the 3DSSG benchmark while also supporting open-vocabulary querying.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI - MexHat: A Dataset for Hate Speech Detection in Mexican Spanish Videos
MexHat is a new video dataset of around 1,000 clips for hate speech detection in Mexican Spanish, annotated for a three-way task (no negative content, offensive content, hate speech) and a fine-grained task with three hate-speech sub-categories. The paper reports baseline model results highlighting the challenges of capturing culturally-specific, context-dependent multimodal cues in a non-English, low-resource setting.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI - datasette 1.0a41
Short release note for Datasette 1.0a41, covering a contributed OpenTelemetry integration for observability and a refactor of Datasette's modal dialogs into a single reusable Web Component now documented for plugin authors. It's a minor but concrete update to Simon Willison's open-source SQLite-backed data publishing/exploration tool.
 simonwillison.netwriteupAdded 29 Sep 2026, published 24 Sep 2026🧠 AI
- SemMSA: Latent Semantic-Aided Robust Multimodal Sentiment Analysis with Incomplete Data
SemMSA is a framework for Multimodal Sentiment Analysis (MSA) under incomplete/missing modality data, using LLMs to construct latent sentiment-relevant semantics rather than reconstructing raw features. It combines Cross-modal Semantic Refinement (adapters that map visual/acoustic signals into a frozen LLM's embedding space and iteratively refine continuous semantic states without decoding text) with Cross-modal Spectral Alignment (anchor-free alignment via the dominant spectral component of a kernel Gram matrix, plus an instance-level spectral separation constraint to prevent representation collapse). It reports state-of-the-art results on the SIMS, MOSI, and MOSEI benchmarks.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026🧠 AI - To Trust or Not to Trust: Retrieval-Augmented Fact Checking in Speech
VeriSpeak is a new probe benchmark of 3,879 spoken claims (temporal, geographical, relational facts, balanced true/false labels) for evaluating speech-based fact verification in Large Audio Language Models. The paper finds a consistent text-speech modality gap—LALMs that verify written claims well often fail on spoken versions—and shows retrieval alone gives limited gains since models conflate retrieved evidence with the spoken claim, while retrieval combined with explicit reasoning boosts a thinking-tuned LALM to 86.1% accuracy. The dataset is publicly released on Hugging Face.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026🧠 AI - PoEM: Predicting RL Outcomes from Existing Policies
PoEM predicts the outcome of RL post-training on a new reward function using models already trained on other rewards, without running additional RL. It shows that when a new reward is a linear combination of existing ones, the resulting log-policy is a corresponding linear combination of existing log-policies, and even for non-linear reward combinations, log-policies often span a low-rank subspace whose combination weights can be estimated from sample outputs alone. Validated on synthetic and real rewards across text and image modalities.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026🧠 AI - The Alignment Illusion in Multimodal Large Language Models
This paper identifies an "alignment illusion" in Multimodal Large Language Models: layer-wise visual-text similarity scores (CKA, SVCCA, MIR, leading principal-angle cosine) fail to consistently detect when visual tokens are corrupted with Gaussian noise, despite corruption sharply reducing task accuracy, across 13 MLLMs from 0.5B to 72B parameters spanning five model families. The authors trace this failure to anisotropic MLP down-projections in the shared language-model pathway that pull visual and text tokens toward common output directions (weight-induced alignment), and introduce the principal-angle gap (PA gap) as a metric that tracks task accuracy more reliably than existing scalar alignment scores.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026🧠 AI  [AINews] Claude Opus 5.5, the new default model for AINews — and everybody cuts prices 40-50%
Latent Space's daily AINews roundup covering Anthropic's launch of Claude Opus 5.5 (Fable 5.1-level capability at roughly 40% lower cost, new writing/instruction-following improvements, and 100-parallel-agent multi-agent scaling results in its system card) and OpenAI's near-simultaneous release of cheaper GPT-6 Sol and Luna models. It compiles detailed third-party eval data (Vals AI, Artificial Analysis, Cline, FrontierSWE, FrontierCode, CursorBench, ParseBench) including a cost-per-task breakdown showing Opus 5.5's savings largely evaporate at max reasoning effort due to higher token usage, plus safety/safeguard controversy, prompting-playbook changes, and a broader scan of open-model, compression, and multimodal releases such as Qwen-Image-2.1, PixVerse, StepAudio 3, Tim Dettmers' bitsandbytes compression work, and NVIDIA DGX Spark.
latent.spacearticleAdded 29 Sep 2026, published 23 Sep 2026🧠 AI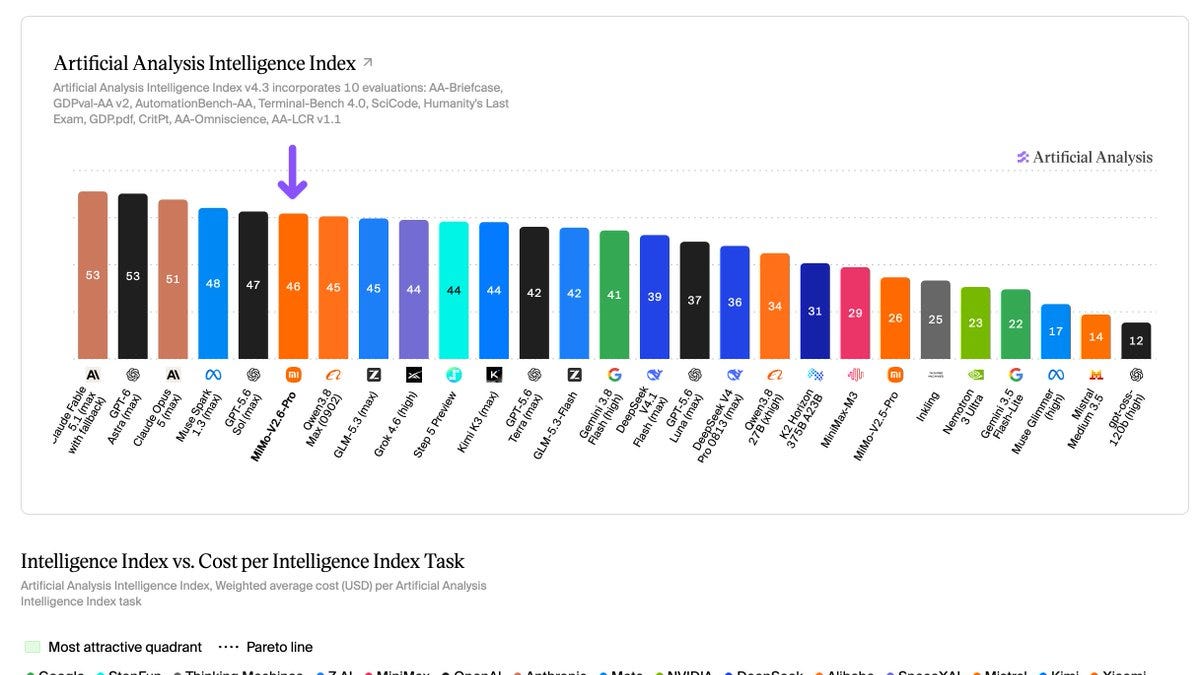 [AINews] Xiaomi MiMo-V2.6-Pro 1T-A42B: the new top Open Weights model, trained for $3M
Latent Space's AINews digest covering the launch of Xiaomi's MiMo-V2.6 series (Pro, Flash, and Pro-UltraSpeed), a natively omnimodal 1.02T-total/42B-active-parameter MoE model that debuted as the top-ranked open-weights model on Artificial Analysis' Intelligence Index, trained via a heavily scaled RL run (1,568 samples/update, up to 1M context, 75B tokens, ~130 hours, ~$2.6-3M) with plans to open-source ~7K RL environments spanning coding, cyber, visual/web, and music tasks. The issue also rounds up Alibaba's Qwen-Image-2.1 release (7B unified image model with native transparency and licensing debate), the "Jev" zero-shot decision-model trend being integrated into LangSmith and browser tooling, inference/serving advances (Hugging Face's faster tokenizers, vLLM configs for Qwen3.8-2.4T on GB300, Tencent Hunyuan's 2.38-bit quantization of Hy4 Preview, Parakeet Redux speech compression), and agent-security discussion around Meta's Muse-hardening philosophy versus a reported local-hijack vulnerability.
latent.spacearticleAdded 29 Sep 2026, published 22 Sep 2026🧠 AI- VideoGen-Agent: Reinforcing Video Generation Agents
VideoGen-Agent is a multimodal agent trained with multitask agentic reinforcement learning to coordinate augmentation, generation, and verification tools for video generation, using supervised fine-tuning on teacher trajectories followed by RL with a category-aware hybrid reward. The authors introduce VABench, a 600-prompt held-out benchmark covering procedural knowledge, identity preservation, physical consistency, scene composition, and multi-shot temporal structure, on which the agent improves over its base text-to-video model from 56.5 to 75.6 (and 86.1 when upgrading the underlying generation tools).
arxiv.orgpaperAdded 22 Sep 2026, published 21 Sep 2026🧠 AI - MIGU: Multimodal Instruction Grounding under Uncertainty for Manipulation Planning
MIGU is a modular framework for multimodal instruction grounding that fuses semantic priors from a vision-language model with a 3D geometric likelihood derived from eye-finger gesture geometry and uncertainty propagation (viewing-direction, depth, hand-direction error). The resulting Bayes-inspired grounding belief drives a behavior planner that either proceeds to manipulation planning or requests clarification, and is evaluated against baselines on a real-world mobile manipulation and tabletop task-and-motion planning benchmark. It matters as an example of explicitly modeling uncertainty across language and gesture modalities to make robot instruction-following more robust.
arxiv.orgpaperAdded 22 Sep 2026, published 21 Sep 2026🧠 AI - Simreal-AI/Simreal-MLBench
Simreal-MLBench is the open, minimal slice of ML Benchmark, a verifiable evaluation environment for machine learning research agents, covering 60 tasks across tabular learning, forecasting, vision, language, audio, multimodal and structured scientific data. It splits an open, Apache-2.0 layer (task definitions, scoring rule, verification tooling) from a commercial operated layer (SimReal's sandboxed runtime, gateway, submission broker and official scoring), scores tasks as 100xp^2 against a frozen reference leaderboard, enforces a source-blind two-submission protocol, and provides full provenance for every published number. It is positioned as an alternative to MLE-bench with a distinct task selection, resource protocol, and scoring scheme, aimed at supporting RLVR and agent self-improvement research.
github.comrepoAdded 26 Sep 2026, published 21 Sep 2026🧠 AI - MM-Future: Multi-Mode Joint World-Action Modeling for Autonomous Driving
MM-Future is a world-action model for autonomous driving that jointly generates multiple paired scene-action hypotheses, co-evolving action priors and predicted future scenes through a modality-aware diffusion Transformer. It compresses multi-view video into planning-oriented MM-Tokens and uses a future-conditioned scorer to rank trajectory candidates, achieving 94.0 PDMS and 91.5 EPDMS on NAVSIM navtest and 32.3 HD-Score in zero-shot closed-loop evaluation on HUGSIM.
arxiv.orgpaperAdded 22 Sep 2026, published 17 Sep 2026🧠 AI  MITRE ATLAS Adds 11 AI Agent Attack Techniques (Zenity Labs collab)
Zenity Labs details its collaboration with MITRE ATLAS to add roughly 11 new AI agent attack techniques, drawn from real-world observations and DEF CON 34 research rather than hypotheticals. New entries cover recon (Active Scanning subtechniques for predictable agent URLs, provider metadata APIs, Search Open Websites/Domains for embedded agentic iFrames, Discover AI Agent Runtime Capabilities, Scan Databases via Shodan/Censys, Misconfigured or Publicly Exposed AI Services), input manipulation (Triggers in Multimodal Inputs, LLM Prompt Obfuscation via image/audio/video, Crafted AI Assistant Links using ?q=/?prompt= parameters, AI Targeted Cloaking, LLM Response Rendering exfiltration, LLM Jailbreak's Data Structure Injection), and a defensive mitigation built on AI honeypots plus multimodal guardrail inspection.
 labs.zenity.ioarticleAdded 30 Sep 2026, published 16 Sep 2026🛡️ Security
- Modality-Autoregressive World-Action Models
This arXiv paper introduces ModAR, a world-action model (WAM) that autoregressively denoises multiple future modalities (point tracks, DINO features, depth maps) before predicting robot actions, letting each prediction condition on previously generated modalities. Trained from scratch, ModAR outperforms the video-pretrained WAM Flex-π (75% vs 72% success rate) while using ~20x fewer training FLOPs and no pretraining, and generalizes to three real-world bimanual robot tasks, improving further with human video data.
arxiv.orgpaperAdded 22 Sep 2026, published 15 Sep 2026🧠 AI



Showing 90 of 113
Show more