 Vulnerabilities that lead to account takeover in banking and fintech mobile apps | Oversecured Blog
Oversecured guide to eight vulnerability categories that lead to account takeover in mobile banking and fintech apps: WebView JavaScript bridge token leakage, Intent Redirection, hardcoded tokens, deeplink hijacking, insecure token storage, localhost OAuth listeners, AIDL abuse and weak biometric auth. It includes a WebView PoC based on Samsung SmartThings CVE-2022-30746 and maps findings to OWASP MASVS, PCI DSS and PSD2. It argues taint analysis plus dynamic PoC is needed to find multi-component chains.
 oversecured.comarticleAdded 29 Oct 2026🛡️ Security
 What is an AIBOM? AI bill of materials explained for security teams | Endor Labs
An AIBOM is a machine-readable inventory of models, datasets, dependencies, AI services, agents and MCP servers, with evidence of origin, license, integrity and evaluation. The Endor Labs explainer walks through a worked CycloneDX example for a fine-tuned support assistant. It compares CycloneDX ML-BOM, SPDX 3.x, the OWASP AIBOM project and the May 2026 CISA/G7 guidance, and lists what an AIBOM cannot show: runtime behavior and agent actions.
 endorlabs.comarticlePublished and added 29 Oct 2026🧠 AI
- What is an AIBOM? AI bill of materials explained for security teams | Endor Labs
AIBOM explainer from Endor Labs: an AI bill of materials is a machine-readable inventory of models, datasets, dependencies, AI services, agents and MCP servers, with origin, license and integrity evidence. It walks through a CycloneDX entry for a fine-tuned model, compares CycloneDX ML-BOM, SPDX 3.x, the OWASP AIBOM Generator and the May 2026 CISA/G7 minimum-elements guidance, and lists a six-step build process. It also states what an AIBOM cannot show: model safety, runtime behavior and coding-agent actions.
endorlabs.comarticlePublished and added 29 Oct 2026🛡️ Security  ADLC compliance: Mapping agentic development to NIST SSDF, OWASP, and the EU AI Act | Endor Labs
ADLC compliance is Endor Labs' interpretation of how NIST SSDF (SP 800-218), the OWASP LLM and Agentic Top 10 lists, and the EU AI Act apply to software built with coding agents. It splits requirements into a code surface and an action surface (shell, files, MCP calls, package installs). It gives a four-step EU AI Act scoping path and says that system prompt rules and agent self-reports are not audit evidence.
endorlabs.comarticlePublished and added 28 Oct 2026🧠 AI- ADLC compliance: Mapping agentic development to NIST SSDF, OWASP, and the EU AI Act | Endor Labs
ADLC compliance guide from Endor Labs that maps agentic development to NIST SSDF (SP 800-218 v1.1), the OWASP LLM Top 10 2025 and Agentic Top 10, and the EU AI Act as amended by Regulation (EU) 2026/1744. It splits controls into a code surface and an action surface (shell, file access, MCP calls, package installs). It gives a four-step AI Act scoping path, the new Annex III date of 2 December 2027, and evidence guidance. It states the crosswalk is the vendor's interpretation, not legal advice.
endorlabs.comarticlePublished and added 28 Oct 2026🛡️ Security  Part 3 – Cybersecurity journeys: The work behind the work
Part 3 of the AWS Security Blog series on cybersecurity careers profiles three AWS staff: Brandon Caldwell (application security, empathy and communication), Kurt Heath (self-taught pen tester, cautious AI use) and Seth Jeacopello (code review, managing attention). It gives practical advice: practice on vulnerable machines and read the logs, build CTF and GitHub portfolios, and write clearly. It lists TryHackMe, Hack The Box, the OWASP Top 10, OWASP Cheat Sheet Series, Darknet Diaries and AWS Skill Builder.
 aws.amazon.comarticlePublished and added 27 Oct 2026🛡️ Security
 Artificial Intelligence (AI) in Cybersecurity, Part 30: Shannon – AI Pentester for Web Apps and APIs
Shannon is a white-box AI pentester (@keygraph/shannon) that analyzes an application's source code, then attacks the running instance and reports only findings with a working PoC. The Hackers Arise tutorial runs it against OWASP Juice Shop in Docker on Kali, using OpenRouter (free Nemotron) and local Ollama (Qwen 2.5 Coder 7B) via a models.json file. Output includes PDF, Markdown, JSON and SARIF reports.
 hackers-arise.comarticlePublished and added 26 Oct 2026🛡️ Security
 Code security for new coders
 is a Datadog Security Labs primer for vibe coders building with coding agents. It lists setup and follow-up security questions to ask the agent, such as OWASP top 10 reviews, hardcoded secrets and outdated packages. It also explains first-party versus third-party code, supply chain risk, and SCA, SAST, IAST, DAST, IaC and secret scanning tools.
 securitylabs.datadoghq.comarticleAdded 29 Oct 2026, published 26 Oct 2026🧠 AI
- Search Search results for "security" | MCP Market
MCP Market search results for "security" in its skills category, listing about 20 installable AI agent skills. Entries cover OWASP Top 10 audits, secure PHP coding, STRIDE threat modeling, CVE remediation, security header analysis, misconfiguration finding, bug bounty triage and AgentShield scans of Claude Code configurations. One is a paid D365FO security-role XML skill. Each entry has only a one-line description and a category label.
 mcpmarket.comtoolAdded 25 Oct 2026🧠 AI
- Search Search results for "security" | MCP Market
MCP Market search results for "security" in the skills category, listing about 20 installable AI agent skills. Entries cover OWASP Top 10 audits, secure coding for PHP, STRIDE threat modeling, CVE remediation, security header analysis, misconfiguration finding, bug bounty triage and AgentShield scans of Claude Code configurations. One is a paid D365FO security-role XML skill. Each entry has only a one-line description and a category label.
mcpmarket.comotherAdded 25 Oct 2026🛡️ Security - OWASP/MCP-Security-Testing-Guide
OWASP MCP Security Testing Guide is a living, GPL-3.0 collection treating the Model Context Protocol as a security boundary from user through model, MCP client, MCP server and tool to the target system. It covers threats, secure development, host/client controls, supply chain, enterprise gateways, detection, incident response, taxonomy, public incidents, case studies and review checklists, with 79 tests in Chapter 3 (sections 3.1–3.19). It includes a finding template, and it links the MCP Goat lab for safe practice. It is useful to AppSec, red team and SOC people assessing MCP deployments.
 github.comrepoAdded 17 Oct 2026🛡️ Security
- AI Security Wiki: Governance, Risk, Standards and Test Cases
A vendor-neutral AI Security Wiki acting as an implementation layer for enterprise AI adoption: risk methodology, AI risk register, control objectives library, domain standards (browser/IDE AI, runtime apps, agentic AI, sovereignty), vendor evaluation framework, and audit/evidence checklists. It includes a 653-case product evaluation test library across 17 lifecycle layers and 6 emerging domains, plus regulatory hubs for GCC, EU, Australia, Brazil, Canada, China, India, Japan, Singapore, South Korea, UK and US, and crosswalks to FINOS AIGF, NIST AI RMF, ISO/IEC 42001, OWASP, MITRE ATLAS, ISO 27001 and others. Useful as a template and evidence source for teams building AI governance and assurance programmes.
 nachi065.github.iootherAdded 15 Oct 2026🛡️ Security
- AI Agents for Cybersecurity: A Guided Tour of a Repository with Tons of Resources and Examples
Omar Santos walks through his eight-part AI-agents-for-cybersecurity repository: LLM building blocks (LangChain, RAG), then security agents with LangGraph, CrewAI, DeepAgents and MCP servers (nmap, CISA KEV, Shodan), a hardening guide for six agentic frameworks, token-cost control for agents, and a spec for a supervisor-led, human-gated security-assessment harness. It covers concrete design lessons such as least-privilege subagents, staged response actions, single-use approvals bound to exact actions, kill switches, and mapping controls to the OWASP Top 10 for Agentic Applications. Also notes Project CodeGuard rules shipped for AI coding assistants.
 becomingahacker.orgarticleAdded 13 Oct 2026🛡️ Security
 Governing the Agentic SDLC Through Continuous Policy Enforcement
JFrog proposes the Agentic Process Evidence Protocol, an open spec that records coding-agent sessions (harness and agent version, model ID, tool and MCP calls, prompts, owner, human reviewer) as signed in-toto/DSSE attestations bound to a git commit, artifact or release. Policy-as-code release gates can then check for approved LLMs and MCP tools, an accountable human and adherence to guidelines, and the logs allow post-release audit. The post gives mock session-log and evidence JSON, ties the approach to EU AI Act Articles 12 and 14, OWASP AISVS and SLSA, and points to a GitHub reference repo, with JFrog AppTrust as the commercial implementation.
 jfrog.comarticleAdded 14 Oct 2026, published 12 Oct 2026🧠 AI
- Governing the Agentic SDLC Through Continuous Policy Enforcement
JFrog proposes Agentic Process Evidence, an open protocol that records AI coding agent sessions (harness, model ID, tool calls, MCP use, prompts, owner, human reviewer) as signed in-toto/DSSE, SLSA-compatible attestations bound to commits, artifacts and releases. Policy-as-code gates can then block releases that used unapproved LLMs or MCP tools, or that lack an accountable human. It maps the approach to EU AI Act Articles 12/14, OWASP AISVS and ISO/IEC 42001, and includes example session-log and evidence JSON. The post also promotes JFrog AppTrust's Prompt to Release Traceability.
jfrog.comarticleAdded 14 Oct 2026, published 12 Oct 2026🛡️ Security  The OWASP Top 10 Gets Modernized | Endor Labs
Commentary on the 2025 OWASP Top 10 update presented at OWASP Global AppSec in Washington, D.C. Broken Access Control stays #1, Security Misconfiguration and the new Software Supply Chain Failures category (replacing Vulnerable and Outdated Components) rise to #2 and #3, and Cryptographic Failures, Injection and Insecure Design drop. The author adds context on agentic AI and MCP identity and authorization, AI-assisted SAST, non-human identities, CISA Secure-by-Default, OWASP SPVS, and slopsquatting and AI coding assistant risks.
endorlabs.comarticlePublished and added 12 Oct 2026🛡️ Security Why AI Coding Agents Keep Writing Broken Access Control
Snyk argues AI coding agents reliably write broken access control (BOLA/IDOR, OWASP's top category since 2021) because the facts needed to add an ownership check — what an object belongs to, who may access it, where tenant boundaries sit — are tacit product knowledge that exists nowhere in the code or prompt an agent sees. It explains why SAST tools catch patterned sub-categories like path traversal or SSRF but structurally cannot catch CWE-639/862/863 (missing or incorrect authorization), since there's no bad pattern to match, and proposes reasoning over an assembled "application-context graph" of architecture, data flows and trust boundaries instead. It closes with a five-step team checklist (inventory ID-accepting endpoints, document ownership rules, add authorization-specific PR review, write cross-tenant tests, run deep contextual analysis) and pitches Snyk's Evo Agentic AppSec as the tool built around that approach.
 snyk.ioarticlePublished and added 1 Oct 2026🧠 AI
- Aditya Agrawal (@exploitprotocol) on X
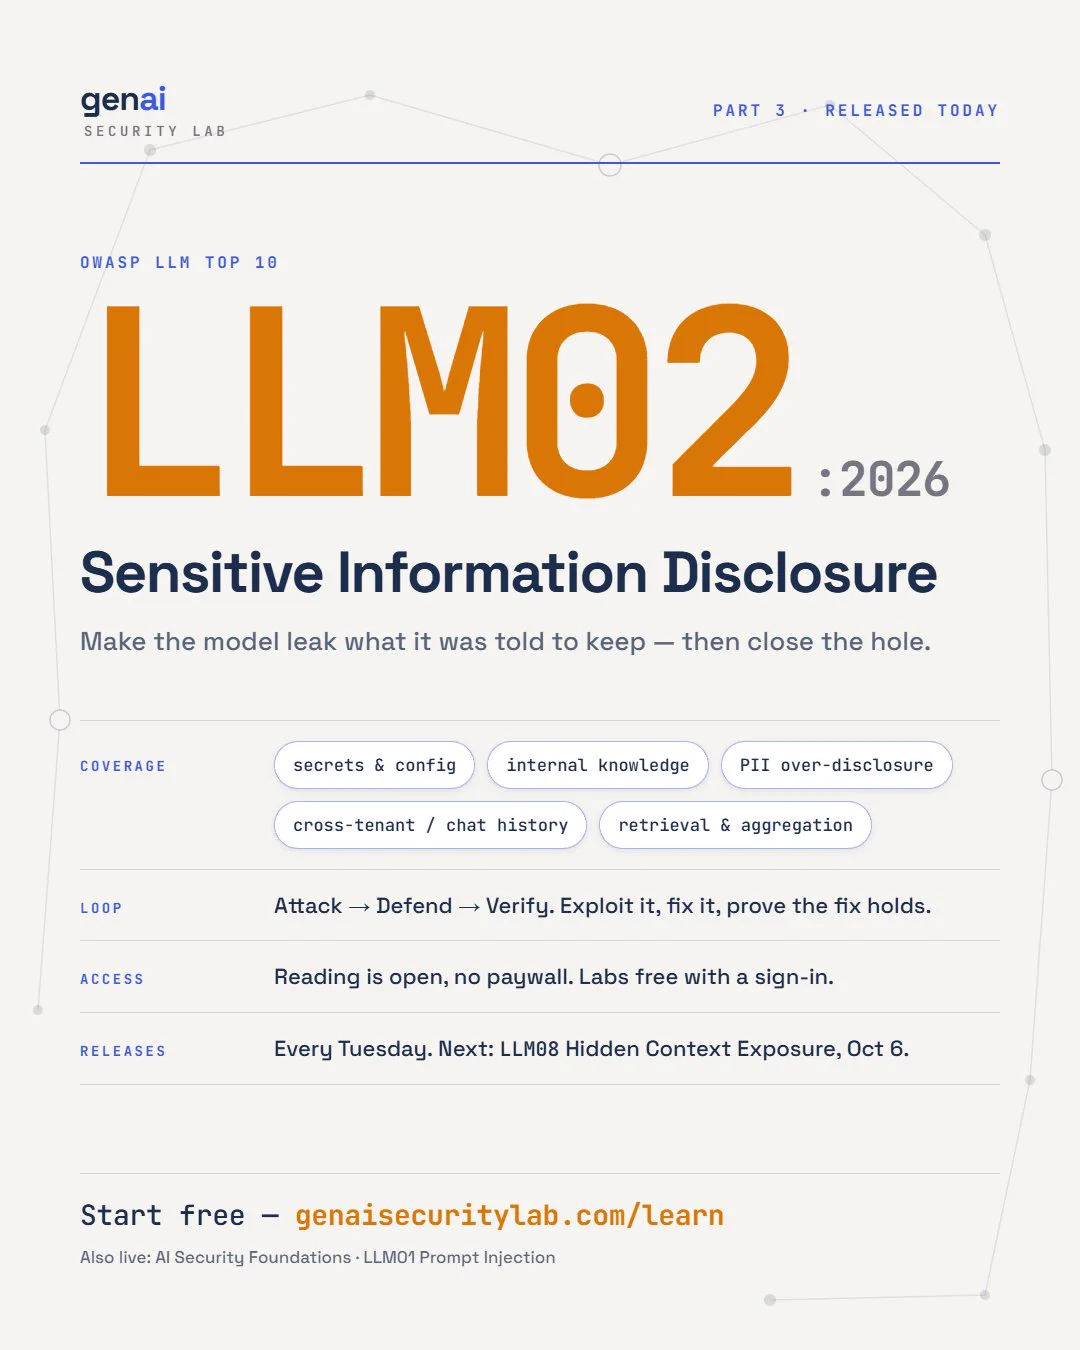
Announcement thread for part 3 of the free Learn AI Security series at genaisecuritylab.com, covering OWASP LLM02 Sensitive Information Disclosure in LLM applications. It walks through failure modes - leaked secrets/API keys via model context, internal knowledge leakage, personal-data over-disclosure, cross-tenant/conversation-history leakage, and RAG retrieval/aggregation leaks - and offers live in-browser attack/defend/verify labs comparing the issues to IDOR and multi-tenant isolation testing in traditional web apps. The author notes the series continues weekly, with LLM08 Hidden Context Exposure scheduled next.
 x.comthreadAdded 1 Oct 2026, published 30 Sep 2026🛡️ Security
- https://github.com/dmdhrumilmistry/security-harness
security-harness is an open-source Claude Code plugin (also packaged for Gemini CLI, Codex and opencode) that orchestrates subagents — sh-recon, sh-hunter, sh-chainer, sh-verifier, sh-reporter — through a static-analysis pipeline covering 15 vulnerability classes (IDOR/BOLA, SQLi, XSS, SSRF, injection, auth, deserialization, path traversal, secrets, CSRF, XXE, open redirect, crypto, race conditions, file upload), producing README/JSON/SARIF/HTML/PDF reports with PoCs, CVSS and CWE/OWASP mappings. It also ships sh-pr-review, a per-PR merge-gate skill that posts inline findings and a commit status scoped only to code the PR itself introduced or aggravated, with caching, dedup via fingerprints, and a scheduled GitHub Action that keeps its per-class knowledge bases fresh by having one AI agent draft updates from allowlisted sources (OWASP, PortSwigger Research, CWE/CAPEC, HackerOne) while a separate adversarial reviewer agent fails-closed against prompt injection before auto-merge.
github.comrepoAdded 2 Oct 2026, published 29 Sep 2026🛡️ Security - Uncensored and Offensive Security AI Models Benchmark
A curated GitHub list of open-weight "uncensored" and security-fine-tuned LLMs intended for authorized red teaming, pentesting, and security research, covering models like WhiteRabbitNeo's DeepHat V2, BugTraceAI-CORE, CYBER-FROST, and several abliterated Qwen/GLM/DeepSeek variants. It explains the underlying techniques (abliteration per Arditi et al. 2024, QLoRA/DPO fine-tuning, GGUF/FP8 quantization) and links to Hugging Face model cards, benchmark suites (CyberBench, TrustedSec's LLM Attack Benchmark vs OWASP Juice Shop), and deployment platforms for running these models locally or via API.
github.comrepoAdded 2 Oct 2026, published 29 Sep 2026🛡️ Security - Agent Control Standard (ACS)
Agent Control Standard (ACS) is an OWASP GenAI Security Project specification that lets a separate Guardian Agent inspect an AI agent's proposed actions before they execute and return allow/deny/modify/ask/defer over an authenticated JSON-RPC wire, with OpenTelemetry/OCSF audit trails and a CycloneDX/SPDX/SWID AgBOM inventory. The reference implementation runs Microsoft's Agent Governance Toolkit (AGT) behind the ACS contract with Bun, including host shims for Claude Code and OpenCode, and demonstrably denies a destructive `rm -rf /` command from a live coding-agent session while allowing benign ones. The project is explicit about current gaps — the wire is unauthenticated (issue #70) and the reference Guardian fails open by default (issues #32/#37) — and only 2 of 16 lifecycle hooks are evaluated live in v0.1.0.
github.comrepoAdded 26 Sep 2026🛡️ Security - Agent Threat Rules (ATR) — open detection-rule standard for AI agent threats
Agent Threat Rules (ATR) is an open, versioned YAML rule format (ATR-YYYY-NNNNN scheme) for detecting AI-agent runtime threats — prompt injection, tool-poisoning, malicious SKILL.md content, and MCP exchange abuse — evaluated by a reference TypeScript engine (with a Python wrapper) shipped as an npm/pip package, CLI, GitHub Action, and Docker scanner with SARIF output. The project positions itself as "Sigma for agent threats," maps rules to OWASP Agentic/LLM Top 10, MITRE ATLAS, and NIST AI RMF, and publishes an extensive (and unusually self-critical) benchmark suite against corpora like garak, PromptBench, and PromptInject, including documented harness bugs and withdrawn recall figures.
github.comrepoAdded 26 Sep 2026🛡️ Security - graygnatconsole/mcp-audit-tool
mcp-audit-tool is a dependency-light Python CLI that statically scans Claude Desktop, Cursor, Windsurf, Cline, Zed, and VS Code MCP configuration files for security issues, including hardcoded secrets, unpinned/rug-pull packages, pipe-to-shell installers, tool-poisoning via hidden instructions in tool descriptions, filesystem servers rooted at '/', and unauthenticated plaintext HTTP MCP endpoints. It auto-discovers configs across macOS/Linux/Windows, produces a security score/grade plus SARIF 2.1.0 output for GitHub Code Scanning, and is built around the OWASP MCP Top 10 categories with a CI/CD example that fails builds on severity thresholds. The roadmap adds live server probing over stdio/SSE for runtime rug-pull detection and an ML-based prompt-injection classifier for tool descriptions.
github.comrepoPublished and added 26 Sep 2026🛡️ Security  Agent Threat Rules (ATR) — Sigma/YARA-style open detection format for AI agent threats
Agent Threat Rules (ATR) is an open, versioned YAML rule format for detecting AI-agent security threats — prompt injection, tool poisoning, credential exfiltration, unauthenticated agent execution — positioned as "what Sigma is to SIEM and YARA is to malware." Rules carry permanent ATR-YYYY-NNNNN IDs, declare detection conditions against fields like LLM I/O, tool-call args, or SKILL.md content, and map back to OWASP Agentic/LLM Top 10, MITRE ATLAS, SAFE-MCP, and NIST AI RMF; a reference TypeScript engine and Python wrapper ship MIT-licensed. Governance is transitioning from a single BDFL maintainer to a Technical Steering Committee, and the spec is notably transparent about its own limits, withdrawing previously published per-lane false-positive figures after discovering a tainted benign corpus.
 agentthreatrule.orgotherAdded 26 Sep 2026🛡️ Security
 Incident-Data Robustness Analysis of the OWASP Top 10 for LLM Applications (2026): How a Community-Expert Ranking Holds Up Against a Large-Scale LLM Incident Corpus
This arXiv paper stress-tests the OWASP Top 10 for LLM Applications (2026) community-expert ranking against a large-scale corpus of real LLM-security incidents (7,714 snapshotted, 6,639 labeled) drawn from CVE, GHSA, OSV, and AIAAIC. Using a Bayesian measurement-error model to correct incident counts for classifier precision/recall, the authors find weak agreement between the expert ranking and the incident-based ranking (Cohen's kappa about 0.20), yet the expert list proves robust: a bake-off of four frontier LLM classifiers fails to beat a simple incidence-floor baseline (balanced accuracy 0.863, Spearman rho = 0.918 against held-out ground truth). It is framed as an exploratory analysis by two OWASP working-group members, not an official supersession of the list.
 arxiv.orgpaperAdded 26 Sep 2026🛡️ Security
 30+ MCP CVEs in Two Months: What the Early-2026 Vulnerability Wave Means for Your MCP Supply Chain
Analysis of 30+ CVEs filed against Model Context Protocol servers, clients, SDKs, and proxies in the first two months of 2026, showing the flaws concentrated in plumbing (proxies, registries, transports) rather than tool implementations. It walks through CVE-2025-6514 (CVSS 9.6 RCE in mcp-remote via unsanitized OAuth authorization_endpoint URLs shelled out to launch a browser), the chained Atlassian MCP server CVEs (CVE-2026-27825/CVE-2026-27826), unauthenticated public registries, and a systemic stdio-transport advisory, then ties the findings to the NSA's May 2026 MCP security CSI and the OWASP MCP Top 10.
 bex.coarticleAdded 26 Sep 2026, published 23 Sep 2026🛡️ Security
- nealbridges/VulnHunter
A maintained, harness-portable fork of Capital One's open-source VulnHunter — an agentic AI tool that performs attacker-first forward analysis on source code to find exploitable vulnerabilities, falsify weak findings, and produce evidence-backed PoCs rather than pattern-matched SAST alerts. This fork adds containerized (Docker-based) exploit validation, measured-impact PoCs (rows leaked, amplification factor, etc.), and portability across agent harnesses (Claude Code, Codex, Grok, etc.) via environment-contract prompt files, plus an unattended operator (vulnhunter-run) and batch-scanning/benchmark harness tested against OWASP NodeGoat, Juice Shop, and WebGoat.
github.comrepoAdded 6 Oct 2026, published 22 Sep 2026🛡️ Security - DVLAA
DVLAA (Damn Vulnerable LLM and Agent Application) is a self-hosted, Docker-deployable security training range for LLM and agent applications, modeled on the DVWA concept but for AI. It covers OWASP LLM Top 10 and Agent Security Top 10 risks (prompt injection, RAG poisoning, tool abuse, memory poisoning, excessive resource consumption, etc.) through 81 hands-on challenges, including an "AWDP" attack/defense track where 10 challenges reproduce real disclosed vulnerabilities in Dify, RAGFlow, Langflow, Flowise, Open WebUI and n8n (with optional real upstream container reproduction), 20 challenges adapted from a China–ASEAN AI security CTF, and 6 challenges adapted from a real model-poisoning CTF. It provides real model interaction, state-machine flag verification, source/prompt viewers, model management (local, Ollama, SiliconFlow, OpenAI-compatible), and bilingual UI.
github.comrepoAdded 22 Sep 2026🛡️ Security  Attack Surface Explained: Types & Reduction Tips
A long-form explainer distinguishing attack surface from attack vector and asset inventory, breaking the surface into network/perimeter, identity/permissions, application/code, and data/storage components, and covering how to map it via the OWASP Attack Surface Analysis Cheat Sheet, measure it (Relative Attack Surface Quotient, Carnegie Mellon's attack surface metric), and reduce it. It also contrasts external attack surface management with cyber asset attack surface management and closes with a pitch for Orca's agentless SideScanning and Unified Data Model.
 orca.securityarticlePublished and added 21 Sep 2026🛡️ Security
- OWASP Agentic Skills Top 10 (AST10)
The OWASP Agentic Skills Top 10 (AST10) is a new security framework cataloging the 10 most critical risks in AI agent "skills" — the behavior layer that orchestrates multi-step tool use in OpenClaw, Claude Code, Cursor/Codex, and VS Code. It documents real 2026 incidents (the ClawHavoc registry-poisoning campaign with 1,184 malicious skills, Snyk's ToxicSkills audit of 3,984 skills finding 36.82% flawed, CVE-2025-59536/CVE-2026-21852 RCE in Claude Code project files, and CVE-2026-28363 ClawJacked WebSocket hijacking) and proposes a Universal Skill Format (YAML) with signing, permission allowlists, and identity-file protections to mitigate them, mapped to CSA's MAESTRO 7-layer threat model.
github.comrepoAdded 18 Sep 2026🛡️ Security - OWASP Agentic Skills Top 10 (AST10)
The OWASP Agentic Skills Top 10 (AST10) is a new OWASP project cataloging the 10 most critical security risks in AI agent "skills" — the layer that defines how agents orchestrate multi-step, autonomous workflows across platforms, as opposed to how models talk to tools via MCP. Each risk is mapped to the Cloud Security Alliance's MAESTRO 7-layer threat model for agentic AI systems, aiming to close a gap left by existing LLM- and MCP-focused security guidance.
 owasp.orgotherAdded 16 Sep 2026🛡️ Security
- OpenHunterAI
OpenHunterAI is a self-hosted, alpha-stage AI red-teaming workspace that applies attacker-style reasoning to web, API, and LLM application security testing against verified, in-scope public targets. It runs locally via Docker/Node.js, orchestrates bounded testing (scope lock → surface mapping → baseline → hypothesis testing → evidence gating → report/retest) through Go workers over NATS, and ships adapters for browser inspection, OWASP ZAP, and Nuclei, with separate OpenHack and Strix runtime integrations and an agent skill for Claude Code/Codex/Gemini CLI/Grok.
github.comrepoAdded 22 Sep 2026, published 15 Sep 2026🛡️ Security - OWASP Agentic Skills Top 10
OWASP's Agentic Skills Top 10 (AST10) catalogs the ten most critical security risks in the "skills" layer of AI agent platforms — OpenClaw's SKILL.md, Claude Code's skill.json, Cursor/Codex manifest.json, and VS Code package.json — arguing this behavior/orchestration layer is distinct from and less protected than the MCP tool layer. It documents real 2026 incidents (the ClawHavoc campaign poisoning 1,184+ ClawHub skills with AMOS-stealer payloads via a shared C2 IP, Snyk's ToxicSkills audit finding 36% of skills flawed, CVE-2025-59536/CVE-2026-21852 in Claude Code enabling RCE and API-key exfiltration on project open, and CVE-2026-28363 "ClawJacked" WebSocket hijacking of local OpenClaw instances), and proposes a Universal Skill Format with signing, permission manifests, and risk tiers plus a checklist for registries, runtime, governance, and skill development.
 owasp.github.iopaperAdded 14 Sep 2026🛡️ Security
 What is an agent harness (and how do you secure one)?
Adversa AI argues that AI agent security lives in the harness, the loop, tool executors, context/memory management, approval gates and sandbox wrapped around an LLM, not in the model itself, and catalogs nine recurring harness failure classes. It details the firm's own research: SymJack (a symlink-based approval-prompt bypass that let six tested coding agents write attacker-controlled MCP config), GuardFall (shell-matcher bypass exploitable in 10 of 11 open-source agents tested), and TrustFall (MCP servers auto-executing on folder-trust acceptance in Claude Code, Gemini CLI, Cursor CLI and GitHub Copilot CLI), plus references to IDEsaster's 30+ AI-IDE vulnerabilities, a Hugging Face download-counter side channel (CVE-2026-54316), and Novee Security's Black Hat findings on credential leakage across Gemini CLI/Codex trust boundaries. It closes with concrete mitigations: Meta's Agents Rule of Two, allowlisting over blocklisting, treating agent config as executable code, and chain-of-event monitoring mapped to the OWASP Top 10 for Agentic Applications.
 adversa.aiarticleAdded 7 Oct 2026, published 14 Sep 2026🛡️ Security
- agent-egress-bench
Agent Egress Bench is an open, tool-neutral benchmark maintained by PipeLab (makers of Pipelock) that tests whether products mediating an AI agent's outbound traffic — proxies, egress firewalls, MCP wrappers, agent gateways — actually catch exfiltration attempts caused by prompt injection or misalignment, rather than testing the underlying model itself (that's left to AgentDojo, InjecAgent, CyberSecEval, AgentHarm, ASB). It ships a reproducible Go runner with a proxy/WebSocket/MCP/A2A adapter contract, an offline validator, DSSE-signed evidence bundles, and a CI-runnable GitHub Action, and separates containment from false-positive rate as two distinct scored axes with immutable case IDs and OWASP Agentic Top 10/MITRE ATT&CK mappings. Its governance explicitly permits third parties to publish results unfavorable to the maintainer's own Pipelock product.
github.comrepoAdded 12 Sep 2026🛡️ Security  OWASP OSS Risk 1: Known Vulnerabilities | Blog | Endor Labs
First in Endor Labs' 10-part series on the OWASP Top 10 OSS Risks, this piece breaks down "Known Vulnerabilities" (OSS-RISK-1): how CVEs get assigned and disclosed, why the 2017 Apache Struts CVE-2017-5638 unpatched flaw led to the Equifax breach of 145M+ records, and how to compare vulnerability data sources (NVD, GitHub Advisory Database, OSV). It details prioritization methods — CVSS, EPSS, CISA KEV, SSVC, and function-level reachability analysis — and shows a case study where filtering 134K findings down via reachability, fix-availability, production-code, and EPSS thresholds cut remediation work by 99.97%.
endorlabs.comarticlePublished and added 11 Sep 2026🛡️ Security Top GenAI security resources — September 2026
Adversa AI's September 2026 roundup of 15 GenAI security resources, grouped by attack technique, defense, threat modeling, red teaming, and training. Highlights include the OWASP LLM Top 10 2026 update (now blending 75% expert consensus with 25% incident data from 6,639 vulnerabilities, with eight of ten entries moving and System Prompt Leakage renamed Hidden Context Exposure), a memory-safety audit finding 10 vulnerabilities (including two use-after-frees at CVSS 9.2/8.1) in the C/C++ inference engine underlying Ollama, LM Studio, Jan and GPT4All, and research on stealing reasoning traces from proprietary LLM APIs, RAG document poisoning, and attention-collapse-based poisoning detection (D-SCAN).
adversa.aiarticleAdded 7 Oct 2026, published 9 Sep 2026🛡️ Security- OWASP OASIS
OWASP OASIS is a proposed community project that operationalizes turning automated vulnerability/fix-generation tool output into human-validated pull requests submitted upstream to open source projects. It defines a full lifecycle (intake, weighted validator review with accept/reject/modify/duplicate decisions, OWASP adoption, ephemeral working forks, upstream submission) plus roles (project owners, validators, maintainer liaisons, automation operators) and outcome metrics like upstream acceptance rate. The GitHub repo lays out governance via a validators.yml credibility file, CODEOWNERS-gated scoring, and GitHub Projects/issue templates to run the whole thing without custom tooling.
github.comrepoPublished and added 5 Sep 2026🛡️ Security  OWASP Agentic Skills Top 10 (AST10)
OWASP project page for the Agentic Skills Top 10 (AST10), a framework that lists the 10 most critical security risks in AI agent skills across agent platforms, with mitigations and prevention strategies. It targets the behavior/execution layer of skills, which sits above MCP tool access, and maps each risk to the Cloud Security Alliance's MAESTRO 7-layer threat model. It is a useful reference for threat-modelling agent skill ecosystems.
owasp.orgotherAdded 5 Sep 2026🛡️ Security Top AI coding agent security resources — September 2026
Adversa AI's monthly roundup of AI coding-agent security research, covering nine items: GhostJacking (using a WAF's own block logs as a prompt-injection delivery channel, 90% success against Claude Code), Black Hat disclosures of unauthenticated-issue-to-RCE chains in the default GitHub Actions configs published by Anthropic, Google, and OpenAI for their coding agents (Gemini CLI rated CVSS 10.0), an agent-to-agent privilege-boundary bypass in Google's ADK repository, the new OWASP Agentic Skills Top 10 with a walkthrough showing open-source skill scanners miss encoded payloads while flagging 9-62% of legitimate skills as malicious, a seven-layer "secure agent harness" containment design, and a 2,826-file adversarial skill benchmark where Gemini CLI and Qwen Code were exploitable 95.5% and 71.6% of the time respectively. The piece draws a common thread across all findings: agents treat machine-generated artifacts (logs, images, other agents' outputs) as trusted instructions, and existing detection never fires.
adversa.aiarticleAdded 7 Oct 2026, published 3 Sep 2026🛡️ Security- h5i-dev/awesome-ai-agent-incidents
A curated GitHub corpus tracking real-world security incidents, CVEs, attack techniques, and defensive tools specific to autonomous AI agents — spanning prompt injection/goal hijacking, MCP client-side tool-metadata poisoning, the "Promptware Kill Chain" multi-stage attack model, MITRE ATLAS agentic techniques, and the OWASP Top 10 for Agentic Applications. It also documents the OpenClaw/ClawHub supply-chain incident (1,184 malicious skills confirmed by Antiy CERT) and links defensive projects like OWASP Agent Memory Guard for LangChain/LlamaIndex agent memory protection.
github.comrepoAdded 3 Sep 2026🛡️ Security - The Secure Agentic Development Lifecycle (ADLC), Explained | Blog | Endor Labs
Endor Labs defines the "agentic development lifecycle" (ADLC) — the process by which AI coding agents autonomously plan, write, test, and ship code — and lays out where it introduces new security risk: insecure-by-default code, architectural design flaws that pass static analysis, hallucinated/unvetted dependencies, and a review bottleneck as agents outpace human reviewers. It cites benchmark data (62% of best-model BaxBench solutions insecure, only 10.5% of SWE-Agent/Claude 4 Sonnet solutions secure, only 1 in 5 AI-recommended dependency versions safe) and proposes a control stack — secure-generation prompting, security-aware multi-agent PR review, reachability-based prioritization, and automated remediation — mapped to NIST SP 800-218A, CSA's Agentic SDLC, and OWASP.
endorlabs.comarticleAdded 3 Sep 2026, published 2 Sep 2026🛡️ Security - Prompt Injection Against Coding Agents: The Attack Surface Nobody Owns | Blog | Endor Labs
Endor Labs breaks down how indirect prompt injection compromises AI coding agents (Cursor, GitHub Copilot) via poisoned READMEs/rules files, malicious MCP servers, and web/issue content the agent reads with elevated trust and auto-approve permissions. Cites a study testing 314 payloads across 70 MITRE ATT&CK techniques showing up to 84% attack success, OWASP's MCP tool poisoning definition, Unit 42's real-world IDPI telemetry, and CVE-2025-52573 as a concrete command-injection-via-prompt-injection case in an MCP server.
endorlabs.comarticleAdded 3 Sep 2026, published 2 Sep 2026🛡️ Security 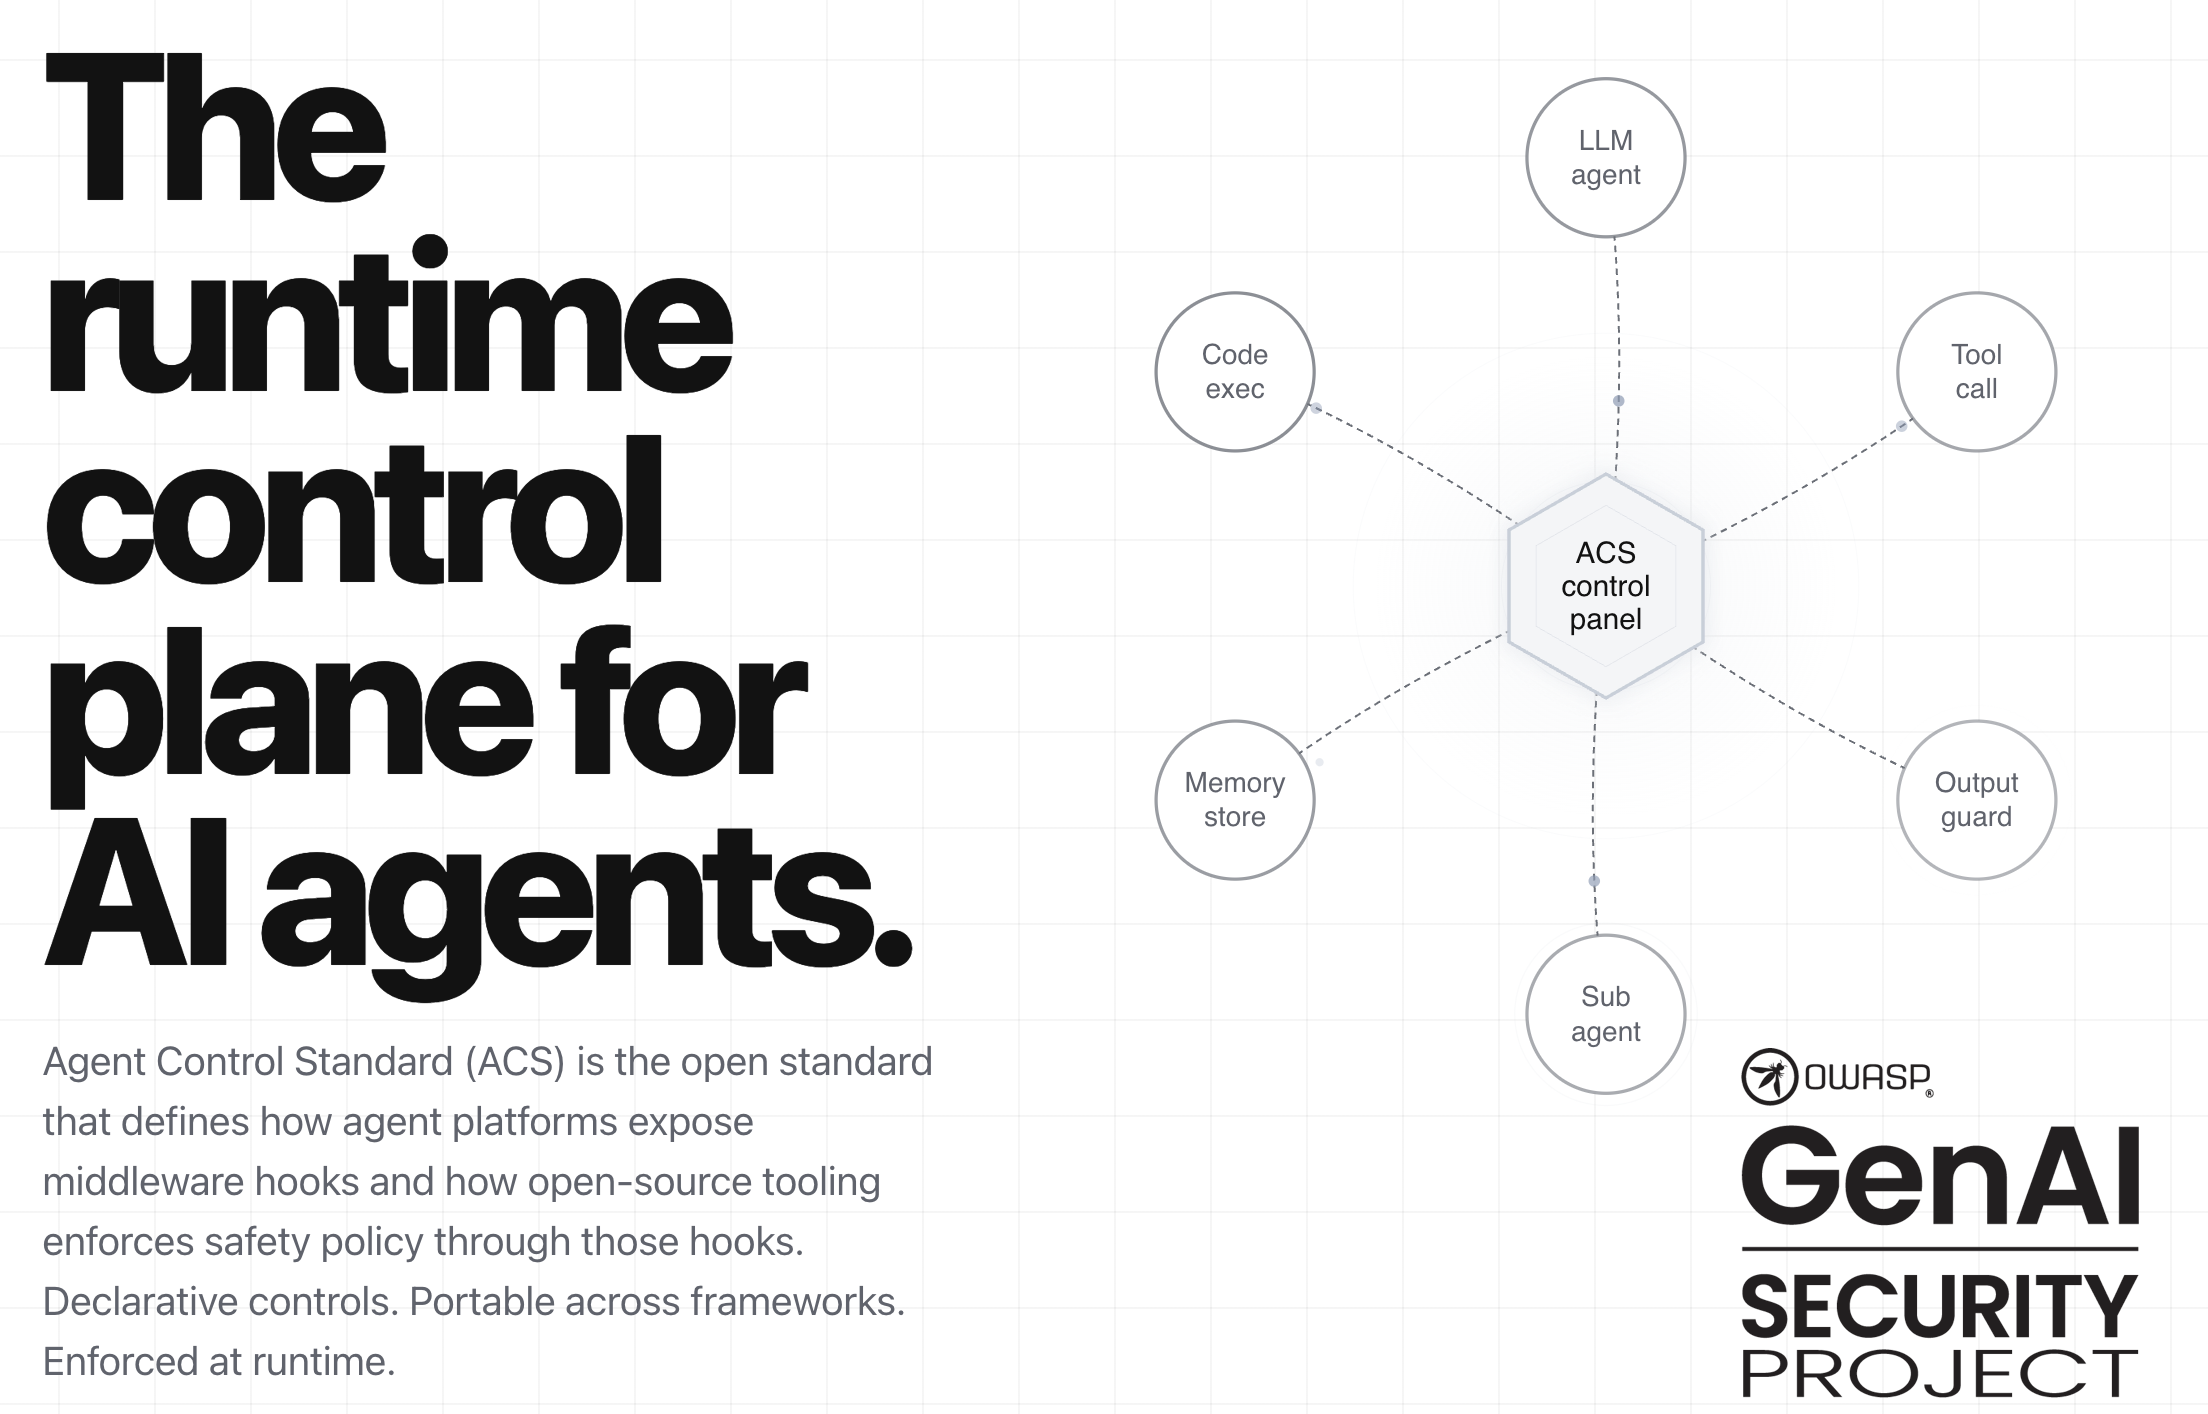 Agent Control Standard (ACS) v1.0 — OWASP GenAI Security Project
The Agent Control Standard (ACS) v1.0 is an OWASP GenAI Security Project specification defining how AI agent platforms should expose middleware hooks so that safety policies can be declared and enforced at runtime, portably across different agent frameworks. It aims to give enterprises visibility into what an agent is, what it can access, what it did, and the ability to control agent behavior live rather than relying on black-box execution.
 genai.owasp.orgotherAdded 26 Sep 2026, published 2 Sep 2026🛡️ Security
 [tl;dr sec] #343 - Hugging Face Technical Report, AWSHound, OWASP Agentic Skills Top 10
tl;dr sec #343 is a weekly security newsletter issue. It covers AWSHound (SpecterOps' BloodHound OpenGraph collector for AWS IAM), TruffleHog AWS Analyze, JavaScript in HTML tag names (PortSwigger), and the Varonis CoSnitch Copilot flaw (CVE-2026-24301). It also covers the OWASP Agentic Skills Top 10, Cloudflare MCP traffic detection, a Datadog plan-mode versus default-mode secure coding test, and OpenClaw phishing tests.
 tldrsec.comarticleAdded 30 Oct 2026, published 27 Aug 2026🛡️ Security
- YesWeHack Claude Kit
Claude Kit is a Claude Code plugin from YesWeHack that helps bug bounty hunters draft and triage vulnerability reports without letting the AI invent unverified technical details. It adds an always-on SessionStart hook enforcing evidence-only claims (no theoretical impact, no OWASP boilerplate padding) plus three on-demand skills (/ywh:write, /ywh:triage, class-specific checks) that structure findings, flag unproven claims, and recompute defensible CVSS scores — e.g. downgrading an inflated 9.1 to ~5.9 Medium after verifying an IDOR's actual exploitability (AC:H, non-enumerable UUIDv4 ID).
github.comrepoPublished and added 27 Aug 2026🛡️ Security - Rekono
Rekono is an open-source pentesting automation platform that chains 19 hacking tools (Nmap, Nuclei, Metasploit, OWASP ZAP, Nikto, Gitleaks, SearchSploit, etc.) so that output from one tool feeds the next, automatically covering recon, service enumeration, vulnerability scanning, and exploit correlation. It deduplicates findings into a single attack-surface inventory per host/port, enriches CVEs with community context for prioritization, tracks fixed/reopened vulnerabilities, and supports team collaboration, scheduled scans, Telegram/email alerts, and report generation for engagements.
github.comrepoAdded 3 Sep 2026, published 27 Aug 2026🛡️ Security  OWASP Agentic Skills Top 10 explained: the ten agent skill risks, and which to fix first
Explains OWASP's Agentic Skills Top 10 v1.0 (AST01-AST10), a new framework for the risks of "agent skills" — folders with a SKILL.md file plus bundled code/scripts that agents discover and execute, treating plain-language instructions as an attack surface that neither traditional package security nor prompt-injection defenses cover. The piece details the ClawHavoc campaign (1,184 malicious skills across 12 ClawHub accounts), the ClawJacked exploit (CVE-2026-32025), Claude Code skill-related CVEs (CVE-2025-59536, CVE-2026-21852), and cites Adversa AI's own research showing a malicious skill bypassed all eight open-source scanners tested, including the OASB leaderboard leader and tools from NVIDIA (SkillSpector), Snyk, Trail of Bits, and Air Security. It closes with a prioritized remediation sequence (inventory, isolation, credential scoping, pinning, allowlisting, approval workflows, advisory scanning, cross-platform normalization) mapped to the AST entries.
adversa.aiarticleAdded 7 Oct 2026, published 25 Aug 2026🛡️ Security Web Fuzzing for Hackers
A practical guide to web fuzzing for bug bounty hunters, covering wordlist selection (custom vs. SecLists-style generic lists), and tool-specific configuration for content discovery, subdomain/VHost enumeration, and parameter/header discovery using ffuf, Burp Suite Intruder, OWASP Amass, dnsx, Arjun, and Param Miner. It details concrete techniques such as subdomain permutation patterns, extension fuzzing for leftover files (.md, .env, .sql), dotfile/prefix patterns (/.FUZZ, /-FUZZ, /~FUZZ), IIS-specific extensions (.asmx, .ashx, .aspx.bak), and hidden-header fuzzing (X-Forwarded-For, X-Debug, X-HTTP-Method-Override) that can lead to SQLi, cache poisoning, or access-control bypass.
 intigriti.comarticleAdded 3 Sep 2026, published 21 Aug 2026🛡️ Security
- Teycir/BurpAPISecuritySuite
BurpAPISecuritySuite is a Jython-based Burp Suite extension that consolidates API reconnaissance, intelligent fuzzing (108+ payloads across 15 attack types including BOLA, IDOR, JWT exploitation, GraphQL abuse, SSTI, and WAF bypass), and passive deep-logic checks (counterfactual differentials, sequence invariants, token lineage, cross-interface parity drift) into a single tool covering the OWASP API Top 10. It auto-captures and normalizes API traffic, exports attack campaigns to Burp Intruder/Turbo Intruder/Nuclei, and generates AI-ready bundles (ChatGPT/Claude/Ollama) for LLM-assisted triage, while orchestrating external tools like ApiHunter, Katana, httpx, FFUF, Kiterunner, sqlmap, and Dalfox for verification.
github.comrepoPublished and added 21 Aug 2026🛡️ Security  Remediation Agents, Demystified: Why Fixing Beats Finding
Recap of a Snyk "AI Security Engineers Community" livestream introducing Remediation Agent, now in public preview: an orchestration layer that sits between a developer's chosen LLM and Snyk's vulnerability intelligence (breakability assessments for OSS upgrades, package health/reachability scores, SAST fix generation, and ecosystem-specific upgrade playbooks) to auto-generate mergeable SCA and SAST fixes. It was demoed live against OWASP Juice Shop via the CLI (snyk fix --agentic --experimental --sca) and via an IDE path (Snyk Studio MCP server plus a /snyk-fix skill in Cursor, Windsurf, or VS Code), with Snyk reporting internal gains of 94% more mergeable SCA fixes and 13% more mergeable SAST fixes versus naively pointing an LLM at a vulnerability backlog.
snyk.ioarticleAdded 3 Sep 2026, published 19 Aug 2026🛡️ Security- What is an agent harness? The software that turns a model into an agent | Blog | Endor Labs
Endor Labs explainer arguing that an AI agent's "harness" (orchestration loop, tool calling/MCP, memory, sandboxes, permission guardrails) - not the underlying LLM - is what determines both capability and attack surface. It walks through concrete harness-level risks (prompt injection as OWASP's LLM01, MCP servers as unvetted dependencies, permission sprawl) and pitches deterministic lifecycle hooks (as used in Claude Code/Cursor via Endor's AURI) as a jailbreak-proof control layer, citing Endor's Agent Security League benchmark where Cursor+Fable 5 beat Claude Code and Codex on both functional and security correctness.
endorlabs.comarticleAdded 3 Sep 2026, published 15 Aug 2026🛡️ Security  0DIN Expands: From Inference to Agency
0DIN (Mozilla's AI bug bounty program) announces it is expanding scope beyond inference-layer jailbreaks to agentic AI vulnerabilities — covering 29 products across coding agents, agentic browsers, enterprise agents, and general-purpose agents from OpenAI, Anthropic, Google, Microsoft, Salesforce, Amazon and others. It introduces a new evaluation rubric for agentic submissions (violation class, impact severity, attack vector, scope) mapped to the OWASP Top 10 for Agentic Applications, and raises the bar for inference jailbreaks by requiring retargetability across two JEF-tested boundaries. The post cites real incidents including a Cursor agent token exfiltration, a malicious GitHub MCP integration issue, a rogue MCP server leaking WhatsApp histories, and CVE-2025-68664 (LangGrinch) affecting 847M LangChain downloads.
 0din.aiarticlePublished and added 15 Aug 2026🛡️ Security
 Orca Security: AI Agents Security
Orca Security lays out a framework for securing AI agents as distinct security objects, arguing an agent's permission set can't be read off its code because it picks tools at runtime, unlike a fixed service account. It details identity-layer fixes from major providers — Microsoft Entra ID's blueprint/service-principal split, Google Cloud's per-agent SPIFFE/X.509 identity with 24-hour certs, and AWS Bedrock AgentCore's token-exchange delegation via RFC 8693 — plus OWASP's AI Agent Security Cheat Sheet practices (tool least privilege, memory isolation, approval gating, attribution logging) and EU AI Act Article 12 logging obligations for high-risk systems.
orca.securityarticlePublished and added 14 Aug 2026🛡️ Security Orca Security: Agentic AI Security
Orca Security's guide to agentic AI security distinguishes it from AI-agent security by framing the unit of risk as the whole autonomous plan/sequence rather than a single agent, and walks through OWASP's Agentic Security Initiative Threats and Mitigations taxonomy (17 threats, T1-T17, v1.1) alongside CSA's MAESTRO layered framework. It details run-level controls (action-class approval thresholds, blast-radius caps, step/time/cost budgets, kill switches, egress boundaries, replayable audit logs) and identity/delegation concerns (RFC 8693 token exchange, orchestrator trust boundaries, permission inheritance across agent chains), then describes how Orca's agentless posture management maps AI services, keys, and data reachable by agentic workflows in the cloud.
orca.securityarticlePublished and added 14 Aug 2026🛡️ Security OWASP Top 10 for LLM Apps 2026: Excessive agency risk on the rise | RL Blog
ReversingLabs blog covering the OWASP Top 10 for LLM Applications 2026, where excessive agency rises from sixth to third and misinformation and unbounded consumption move up. It explains the new ranking method (75% practitioner vote, 25% incident data from 7,714 incidents, 6,639 classified) and collects practitioner views. The core guidance is to assume models will be fooled and limit blast radius through scoped, short-lived credentials, external verification, and per-user and per-session budgets.
 reversinglabs.comarticleAdded 20 Aug 2026, published 12 Aug 2026🛡️ Security
- Static Analysis Tools & Linters
analysis-tools.dev's source repository is a community-maintained directory of static analysis tools and linters spanning nearly every programming language, tagged for license (proprietary vs open source), maintenance status, and community endorsement. Beyond general code-quality linters, it catalogs many security-relevant static analyzers such as gosec, flawfinder, OWASP Dependency Check, Mariana Trench, Psalm, PHPStan, govulncheck, and WAP, making it a reference point for discovering SAST tooling per language/ecosystem.
github.comrepoAdded 3 Sep 2026, published 9 Aug 2026🛡️ Security - Dark-Moon
DarkMoon is a self-hosted, GPLv3 AI penetration testing platform that orchestrates 50 specialist agents over an MCP-gated toolbox (Nuclei, BloodHound, sqlmap, Impacket, Naabu, httpx, ffuf, etc.) to autonomously run recon-to-exploitation across web, API, Active Directory, Kubernetes, multi-cloud, CI/CD, databases, IoT firmware, and AI/LLM inference endpoints. It uses a Privacy Gateway that tokenizes real IPs/hosts/credentials into placeholders so raw infrastructure data never reaches the (optionally local, e.g. Ollama/llama.cpp) LLM, and can generate sandbox-validated, exploit-retested pull requests for findings. It also ships a dedicated LLM agent that probes OpenAI-compatible/Ollama/vLLM/TGI inference endpoints for the OWASP LLM Top 10 (prompt injection, jailbreaks, system-prompt leakage) using garak-backed probes.
github.comrepoPublished and added 5 Aug 2026🛡️ Security - SecureAI-Scan
SecureAI-Scan is an offline CLI that performs import-resolved dataflow analysis on TypeScript, JavaScript, and Python code to find LLM/MCP/Agent-Skill/RAG-specific risks (prompt injection, tool poisoning, unsafe output handling, vector-store access control), mapped to the OWASP Top 10 for LLM Applications, Agentic Applications, and MCP Top 10. It distinguishes proven dataflow traces from heuristic keyword matches, scans .mcp.json/claude_desktop_config.json/SKILL.md for tool-poisoning and command-injection patterns (citing the WhatsApp MCP rug-pull and postmark-mcp backdoor), and includes evasion-resistant deobfuscation checks built in response to the "Cloak and Detonate" adversarial study (arXiv:2607.02357) that bypassed most published skill scanners. It also runs offline advisory checks against known-malicious/vulnerable packages (validated against CVE-2025-6514 and CVE-2024-34359) and integrates via GitHub Actions, pre-commit hooks, SARIF output, and an MCP server for Claude Code.
github.comrepoPublished and added 5 Aug 2026🛡️ Security - Precogly
Precogly is an open-source, now-OWASP threat modeling platform (React/TypeScript frontend, Django REST Framework/PostgreSQL backend) offering a collaborative DFD editor with trust zones, TM-BOM import/export, and community library packs linked to MITRE ATT&CK, CAPEC, STRIDE, and LINDDUN. It's positioned as compliance-aware, tracing threats and countermeasures to DORA, the EU Cyber Resilience Act, ASVS, NIST CSF, and SOC 2, and exposes a full OpenAPI REST API meant as scaffolding for AI-driven threat modeling assistants.
github.comrepoAdded 3 Sep 2026, published 5 Aug 2026🛡️ Security  OWASP GenAI LLM Top 10 2026
OWASP's 2026 update to the Top 10 for LLM Applications, developed by hundreds of AI security experts and grounded in real-world AI security incidents. It provides updated risk rankings, attack scenarios, and mitigations for prompt injection, model/data poisoning, and other LLM-specific threats, and maps each risk to NIST, MITRE ATLAS, CWE, and the OWASP Top 10 for Agentic Applications.
genai.owasp.orgpaperAdded 26 Sep 2026, published 4 Aug 2026🛡️ Security Top Agentic AI security resources — August 2026
Adversa AI's August 2026 roundup of twenty agentic AI security resources from July 2026, covering four real-world agent exploits in ten days: a hidden one-pixel-text attack making AWS Kiro rewrite its own mcp.json (CVE-2026-10591), two CVSS 9.8 zero-click Cursor RCEs (DuneSlide, CVE-2026-50548/50549), the DeepJack Cursor deeplink RCE, and ClaudeBleed's Chrome-extension click-forgery against Claude for Chrome. It also summarizes three memory-poisoning papers (an agent data injection class, FARMA/SENTINEL, GhostWriter/AM-Sentry), the Hugging Face sandbox-escape incident, Anthropic's CISO risk framework, and OWASP/CSA's agentic AI maturity model.
adversa.aiarticleAdded 7 Oct 2026, published 31 Jul 2026🛡️ Security- Beetle
Beetle is an offline-first mobile application security platform that statically analyzes Android APKs and iOS IPAs (including Flutter and React Native apps), combining decompilation, taint analysis, secret/endpoint extraction, certificate and native-binary hardening checks, and CVE enrichment with explainable 'intelligence engines' (ownership, confidence, evidence selection, finding fusion) that correlate findings into evidence-backed attack chains. It maps results to OWASP MASVS/Mobile Top 10, provides source-level navigation, and exports SARIF, CycloneDX SBOM, and PDF reports, with optional (non-scanning) AI assistance via Claude, OpenAI, Gemini, DeepSeek, or local Ollama for explaining findings.
github.comrepoPublished and added 31 Jul 2026🛡️ Security  Best SBOM Tools in 2026, Compared | Blog | Endor Labs
Endor Labs' 2026 SBOM tooling comparison sorts five tools into three functional layers: open-source generators (Syft, cdxgen, Microsoft SBOM Tool) that produce SPDX/CycloneDX inventories, OWASP Dependency-Track for centralized SBOM storage and continuous monitoring, and Endor Labs' own SBOM Hub which adds function-level reachability analysis to cut CVE alert noise by a claimed 95%. It breaks down each tool's ecosystem coverage, format support, and trade-offs (e.g., Syft's lack of reachability, cdxgen's CycloneDX-only output, Dependency-Track's need for a database) and gives a decision framework for picking a tool by stack and maturity level.
endorlabs.comarticleAdded 3 Sep 2026, published 29 Jul 2026🛡️ Security- glsec
glsec is a security linter for GitLab CI (.gitlab-ci.yml) configuration files, analogous to zizmor/actionlint for GitHub Actions. It detects misconfigurations like mutable image tags, unquoted user-controlled CI variables in scripts, and other issues mapped to 84 rules across 8 OWASP CI/CD Security categories (excluding IAM and logging, which require platform-level access). It supports baseline/ignore workflows, ShellCheck integration, SARIF/Code Climate/JUnit output for GitLab dashboards, a pre-commit hook, and a Claude Code plugin, and ships releases with Sigstore/cosign signing and SLSA provenance attestations.
github.comrepoPublished and added 29 Jul 2026🛡️ Security - Gabson0x/pentdem
pentdem is an autonomous AI-powered pentesting CLI/pipeline that fans out 15+ vulnerability-class hunters (XSS, SQLi, SSRF, IDOR, SSTI, JWT, GraphQL, etc.) and 8 advanced attack skills (mass assignment, race conditions, cloud metadata, OAuth/OIDC, subdomain takeover, credential harvesting) in parallel, using an LLM to adapt strategy mid-scan. It wraps real tools (nmap, sqlmap, nuclei, ffuf, subfinder, httpx) in Docker isolation and adds a novel gate chain — quality gate, kill-chain builder, adversarial cross-model validation (a second model tries to disprove each finding), a capability execution ledger (proves each hunter actually ran instead of silently crashing), and a ship-discipline gate — before mapping surviving findings to MITRE ATT&CK/OWASP Top 10/CVSS and generating reports.
github.comrepoPublished and added 20 Jul 2026🛡️ Security - AI Security Briefing
SingGuard-NSFA is an open-source guardrail framework (released as 0.8B/2B/4B/9B model checkpoints) that targets operational threats in LLM agents—prompt injection, sensitive-info extraction, malicious code requests, tool misuse, and resource exhaustion—rather than just content-safety issues. It's built on a CIA-triad-grounded taxonomy of 185 risk variants across 7 domains (cross-validated against OWASP guidelines) and a 133-language benchmark with 93K+ samples, offering both generative chain-of-thought auditing and ~50ms real-time classification heads. It beats Llama Guard 3, WildGuard, and GPT-5.1 by 6-12 F1 points on multilingual benchmarks, and can also be plugged into Llama Guard 3 as a lightweight enhancement (+17.6 F1).
github.comrepoPublished and added 19 Jul 2026🛡️ Security - capitalone/VulnHunter
VulnHunter is Capital One's open-source agentic AI vulnerability scanner built as a set of Claude Code skills (/vulnhunt, /vulnhunter-fix, /vulnhunt-fix-verify) that runs on Claude Opus. Instead of pattern-matching like traditional SAST, it does attacker-first forward analysis from entry points, runs a "falsification engine" to discard unexploitable findings, and generates evidence-backed remediation patches; it also ships a headless agent runtime and a benchmarking harness tested against OWASP NodeGoat, Juice Shop, and WebGoat.
github.comrepoAdded 19 Jul 2026🛡️ Security - CyberSunil/LLMVault
LLMVault is a self-hosted, deliberately-vulnerable training range modeled on WebGoat but for LLM applications, covering 25 labs across the OWASP Top 10 for LLM Applications (2025) - prompt injection, jailbreaking, data/model poisoning, agent exploitation, model extraction, and insecure downstream output handling. It ships two modes: a scored Play Mode with scripted assistants for repeatable flag capture, and an unscripted Live Mode that points the same attacks at a real local Ollama model (qwen2.5:3b-instruct) with a freshly minted per-session secret, requiring the player to actually talk the model into leaking it. Each lab pairs the attack with a written defense explanation, and an expert tier is shipped AES/Fernet-encrypted and unlocked manually by the maintainer.
github.comrepoPublished and added 18 Jul 2026🛡️ Security - Strix
Strix is an open-source framework of autonomous AI pentesting agents that dynamically run target code, discover vulnerabilities across the OWASP Top 10 (SQLi, SSRF, XXE, IDOR, XSS, auth bypass, business-logic flaws) and validate them with working proof-of-concept exploits rather than static-analysis heuristics. It ships a CLI with a full offensive toolkit (Caido-based HTTP interception, browser exploitation, Python exploit sandbox, recon/OSINT, SAST/DAST), supports OpenAPI/Postman-driven black-box testing, integrates into GitHub Actions/CI pipelines to block vulnerable PRs, and can run against local or hosted LLMs via LiteLLM, with an optional cloud offering for autofix PRs and compliance reporting.
github.comrepoPublished and added 15 Jul 2026🛡️ Security - LocxZ/SecureSDLC-Lab
SecureSDLC-Lab pairs a minimal Node.js/Express/SQLite app with a GitHub Actions pipeline running Gitleaks (secret scanning), Semgrep (SAST), and Trivy (dependency, Docker image, and Kubernetes manifest scanning) plus OWASP ZAP (DAST) on every push and PR. It documents concrete remediations applied during the exercise: bcrypt password hashing, parameterized SQL queries, session-based auth with post-login session regeneration and HttpOnly cookies, RBAC for an admin page, Helmet security headers, env-based secrets, and a hardened Kubernetes deployment (non-root, readOnlyRootFilesystem, dropped capabilities, seccomp, resource limits) alongside a STRIDE threat model.
github.comrepoPublished and added 14 Jul 2026🛡️ Security - Giskard-AI/giskard-oss
Giskard is an open-source Python testing/evaluation library for agentic and LLM systems, rewritten in v3 as a modular set of packages (giskard-checks, giskard-scan, giskard-core, giskard-llm, giskard-agents). giskard-scan is the red-teaming layer: it auto-generates adversarial test suites from a plain-language agent description, covering prompt injection, harmful content, stereotypes, and misinformation across OWASP LLM Top-10 categories, and includes a built-in prompt-injection payload dataset. giskard-checks provides LLM-as-judge and assertion-based evals (Groundedness, Conformity) for catching regressions and enforcing safety rules in multi-turn agent conversations; the legacy v2 also offered a tabular ML bias/robustness scanner and RAGET for RAG test-set generation.
github.comrepoPublished and added 14 Jul 2026🛡️ Security - SyscallX-18113/Apkx-Hunter
APKX-Hunter is an open-source Android static analysis framework written in C, built for reverse engineering, malware analysis, OWASP MASVS compliance scanning, and bug bounty/pentesting work. It decompiles APK/APKM/APKS/XAPK/ZIP packages via JADX or APKTool, extracts hardcoded secrets, endpoints, permissions, exported components, and native libraries, and scores detected secrets with a lightweight offline C-based ML classifier (166 MASVS detection patterns across 15 categories). It was showcased at Black Hat Europe Arsenal and tested against the OWASP UnCrackable Level 4 app.
github.comrepoAdded 30 Sep 2026, published 11 Jul 2026🛡️ Security - apisec-inc/AI-Surface
ai-surface is a local/offline static analysis CLI (apisec-inc) that scans a codebase for AI attack surface — LLM SDK calls, agent frameworks (LangChain, AWS Strands), MCP servers, RAG/vector stores, model gateways, and provider keys — and flags risk indicators such as financial-action tools with no human approval or unverified MCP servers. It generates an AI-BOM (CycloneDX), SARIF for GitHub code scanning, and maps findings to OWASP LLM Top 10, EU AI Act, NIST AI RMF, and ISO/IEC 42001, with a baseline+fail-on-severity workflow for gating new risk in PRs without blocking on pre-existing debt.
github.comrepoPublished and added 11 Jul 2026🛡️ Security - requie/AI-Red-Teaming-Guide
A community-maintained GitHub guide (requie/AI-Red-Teaming-Guide) that consolidates AI red-teaming methodology, mapping techniques like prompt injection, jailbreaking (Skeleton Key, Crescendo), model extraction, data/fine-tuning poisoning, and MCP tool-poisoning/rug-pull attacks to frameworks including NIST AI RMF, OWASP Top 10 for LLM Applications and Agentic Applications, MITRE ATLAS, and CSA's Agentic AI Red Teaming Guide. It cites real incidents (OpenClaw's CVE-2026-25253, GitHub Copilot's CVE-2025-53773, the Anthropic-disrupted Claude Code state-sponsored campaign, the Morris II AI worm) and surveys red-team tooling (PyRIT, NVIDIA's Garak, DeepTeam) plus emerging agent-orchestrated red-teaming approaches.
github.comrepoPublished and added 8 Jul 2026🛡️ Security  GitHub Secure Code Game
Season 4 of GitHub's open-source Secure Code Game puts players inside 'ProdBot', a deliberately vulnerable agentic coding assistant modeled on tools like OpenClaw and GitHub Copilot CLI. Across five progressive levels players must get ProdBot to leak a secret by exploiting sandbox escapes, untrusted web content ingestion, malicious MCP server integrations, poisoned org-approved skills/persistent memory, and multi-agent trust chains. It runs free in GitHub Codespaces and references real-world risk categories from the OWASP Top 10 for Agentic Applications 2026 and CVE-2026-25253 ('ClawBleed') RCE in OpenClaw.
 github.blogcoursePublished and added 4 Jul 2026🛡️ Security
- OWASP MCP Top 10 | OWASP Foundation
The OWASP MCP Top 10 (2025) is a living-document taxonomy of the ten most critical vulnerability classes affecting Model Context Protocol-based AI systems, covering issues like token mismanagement, privilege escalation via scope creep, tool poisoning, MCP-specific supply chain and dependency tampering, command injection, prompt injection via contextual payloads, weak authN/authZ, missing audit/telemetry, shadow MCP servers, and context injection/over-sharing. It targets AI/ML developers and security practitioners building agentic, model-chaining, and multi-modal MCP deployments, giving them a common vocabulary and checklist for secure design and auditing analogous to the OWASP Top 10 for LLM Applications.
owasp.orgadvisoryAdded 3 Jul 2026🛡️ Security - open-source-web-scanners
A GitHub list curated by psiinon (creator of OWASP ZAP) cataloging open-source web security scanners, ranked by GitHub/GitLab stars. Tools are grouped by category: general unknown-vulnerability scanners, known-vulnerability scanners, fuzzers, CMS-specific scanners, API scanners, and tools focused on specific vulnerability classes.
github.comrepoAdded 3 Sep 2026, published 10 Jun 2026🛡️ Security - cicd-sensor: eBPF Runtime Security for CI/CD Pipelines
cicd-sensor is an open-source, eBPF-powered runtime security sensor ("EDR for CI/CD") for GitHub Actions and GitLab CI/CD that detects supply-chain attacks in-flight by watching process ancestry (e.g. credential access spawned from an npm install) and correlating signals across a job. It emits per-run logs, graphical reports, and build attestations routed to a self-hosted Manager and cloud sinks (S3, GCS, Azure Blob, Pub/Sub), positioning itself as the vendor-neutral open counterpart to commercial offerings like StepSecurity's Harden-Runner and GMO Flatt Security's Takumi Runner. Created by Hiroki Suezawa (@rung), author of the Common Threat Matrix for CI/CD Pipeline and an OWASP Top 10 CI/CD Security Risks contributor.
github.comrepoAdded 3 Sep 2026, published 4 Jun 2026🛡️ Security 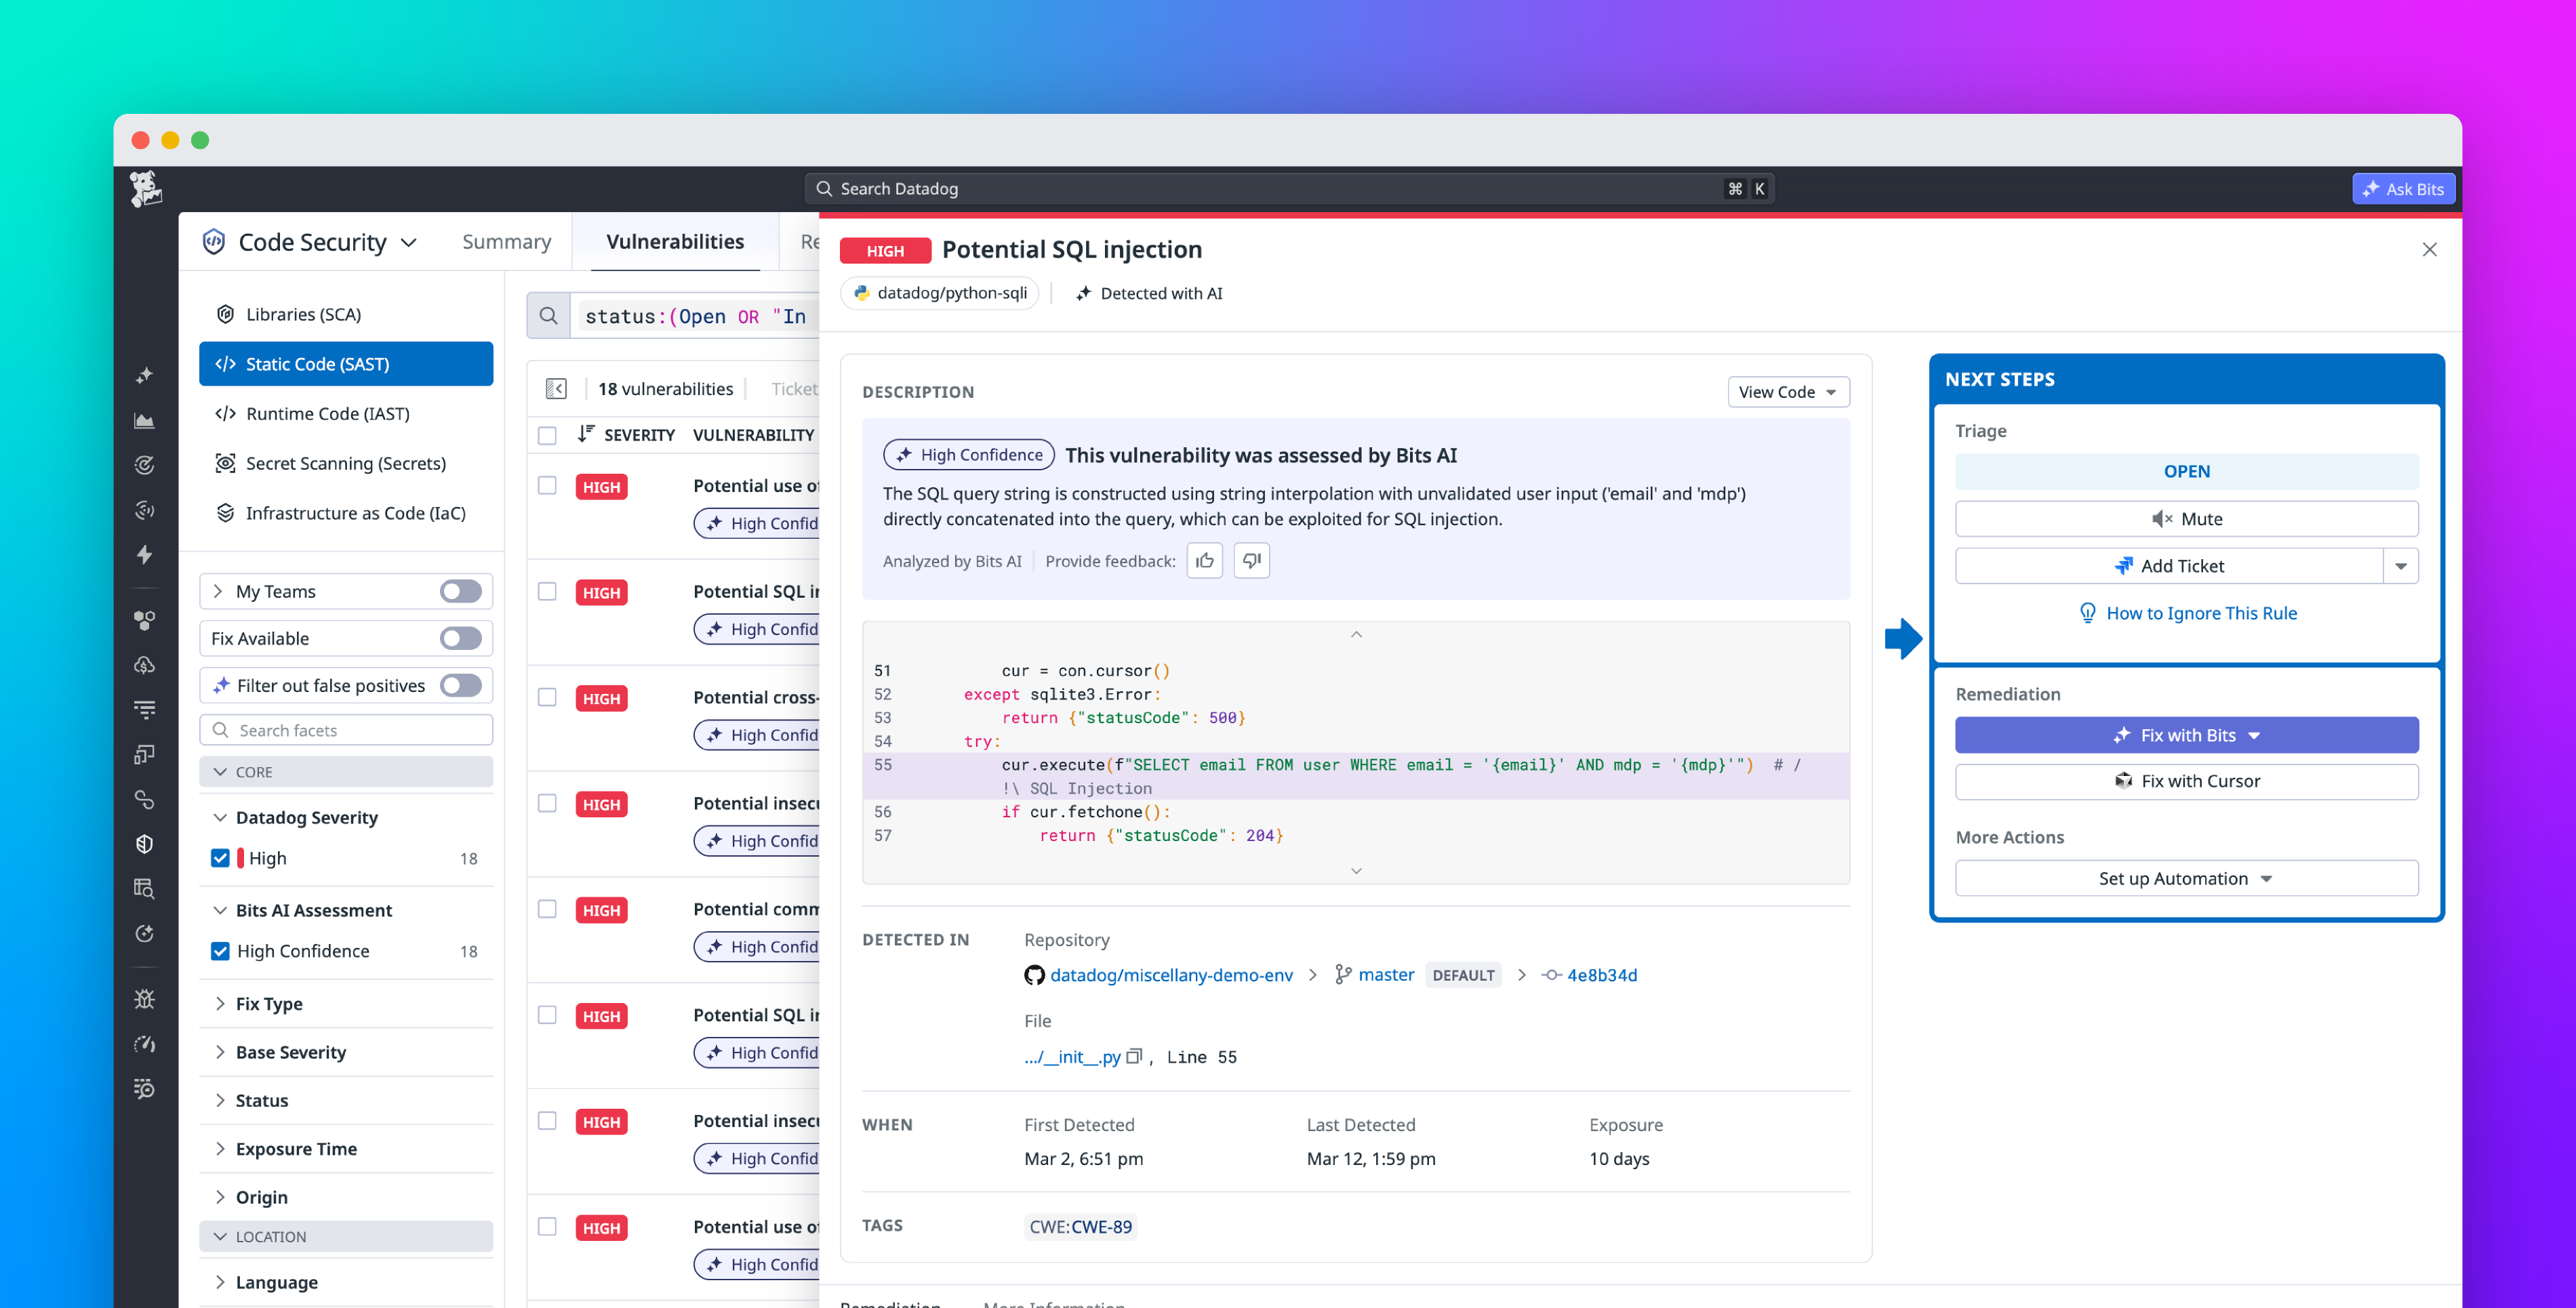 Datadog AI-Native SAST
Datadog describes its open-sourced AI-native SAST tool, which uses LLMs (including Claude Opus) to add context-aware reasoning on top of traditional static analysis, cutting false positives for vulnerabilities like SQL injection and command injection. The pipeline runs identification, context retrieval, LLM analysis, and post-processing steps, uses incremental scanning to control LLM cost after an initial full-repo scan, and is benchmarked against the OWASP Benchmark framework where it beats Datadog's traditional SAST (even LLM-filtered) on most vulnerability categories.
 datadoghq.comarticlePublished and added 31 May 2026🛡️ Security
- CVE Lite CLI
CVE Lite CLI is an OWASP Lab Project CLI that scans npm, pnpm, Yarn, and Bun lockfiles against OSV and the npm advisory API and outputs copy-and-run fix commands instead of raw CVE lists, with parent-aware guidance for transitive dependencies. Beyond core CVE scanning it audits override/resolution hygiene, flags maintenance risk (deprecated direct deps and version drag blocking fixes), warns when a suggested fix falls inside a package manager's release-cooldown window (referencing the chalk/debug npm compromise), and emits SARIF, SPDX/CycloneDX SBOMs, and EPSS-based priority tiers, plus a GitHub Action that opens batched fix PRs.
github.comrepoPublished and added 31 May 2026🛡️ Security - OWASP Noir
OWASP Noir is a static analysis (SAST) tool that reads source code to extract every endpoint an application exposes — paths, methods, parameters, headers, cookies, and their originating files — across 205 supported frameworks, with an LLM fallback (OpenAI/Ollama) for unsupported ones. The endpoint inventory (including shadow APIs and undocumented routes) is exported as JSON/YAML/OpenAPI/SARIF/cURL/Postman/HTML to feed DAST scanners (ZAP, Burp Suite, Caido, Gori), human security reviewers, and AI SAST auditors, with optional --ai-context enrichment (guards, sinks, validators, callees) and GitHub Action/CI integration.
github.comrepoPublished and added 24 May 2026🛡️ Security - Tachi
Tachi is a threat-modeling and AI-reasoning vulnerability detection harness that runs inside Claude Code, dispatching 14 specialized agents against an architecture description (Mermaid, C4, PlantUML, free-text, or ASCII) to find logic-level flaws like broken auth flows, missing privilege boundaries, prompt injection paths, and agent autonomy gaps that SAST cannot catch. It claims full 50/50 coverage across five OWASP frameworks (Web/API, LLM, Agentic, ML, Mobile Top 10s), classifies agentic AI findings against the CSA MAESTRO seven-layer taxonomy, and maps findings to MITRE ATT&CK/ATLAS, NIST AI RMF, and CWE, producing threats.md, SARIF, attack trees, quantitative risk scores, compensating-control analysis, and a PDF security report.
github.comrepoAdded 3 Sep 2026, published 23 May 2026🛡️ Security - CyberStrikeus/CyberStrike
CyberStrike is an open-source (AGPL-3.0) terminal-based framework that turns any LLM subscription (Claude, GPT, Gemini, local models via Ollama/LM Studio, etc.) into an autonomous red-team agent, providing 13+ specialized agents, 7,600+ Ed25519-signed security skill files mapped to OWASP WSTG/CWE, a built-in Chromium proxy browser for role/credential discovery, and remote "Bolt" MCP tool servers for orchestrating tools like nmap, sqlmap, and Burp-style traffic interception. It targets pentesters and bug bounty hunters for automated reconnaissance, vulnerability discovery, exploitation, and post-exploitation, explicitly restricted to authorized testing.
github.comrepoPublished and added 23 May 2026🛡️ Security  XBOW: Ethical Considerations in AI-Driven Penetration Testing
XBOW's blog post lays out a governance framework for AI-driven penetration testing, addressing authorization and scope, accountability and liability when autonomous agents cause unintended impact, and the need for explainable, validated findings rather than AI-generated guesses. It cites IBM's 2025 Cost of a Data Breach report (63% of breached orgs lack AI governance policies, 97% of AI-model breaches involved poor AI access controls) and OWASP access control testing stats to argue for enforceable scope boundaries, human oversight, and audit logging as autonomous testing scales.
 xbow.comarticlePublished and added 23 May 2026🛡️ Security
- OWASP ASM Top 10
Project page for the OWASP Attack Surface Management (ASM) Top 10, an incubator-stage OWASP project with two listed contributors. By its title it is a Top 10-style list of attack surface management risks, but the fetched text shows only project metadata and OWASP legal boilerplate, not the list itself. It is worth tracking as it matures into a reference for external asset discovery and exposure management.
owasp.orgotherAdded 3 Sep 2026, published 17 May 2026🛡️ Security - OWASP/DockSec
DockSec is an OWASP Lab Project CLI that wraps Trivy, Hadolint, and Docker Scout to scan Dockerfiles, images, and Compose files, then uses an AI provider (OpenAI, Anthropic, Google, or local Ollama) to correlate findings, cut noise, and generate plain-English remediation suggestions. It supports CI/CD gating via exit codes, baselines, and auditable waiver files, outputs SARIF/CycloneDX SBOM/HTML/PDF/JSON/CSV/Markdown reports, and redacts secrets before any content reaches an LLM, with a fully offline/local-only mode for air-gapped teams.
github.comrepoPublished and added 14 May 2026🛡️ Security - i8void/cybersleuth
CyberSleuth is an open-source MCP server that exposes 34 OSINT/cyber-investigation capabilities to Claude Desktop or Claude Code via natural language, covering infrastructure analysis (DNS, WHOIS, reverse DNS, AS/hosting intel), certificate transparency (CertSpotter/Censys), threat intel correlation (Shodan, VirusTotal, URLScan.io), tech-stack and ATS/GitHub org recon, and privacy/jurisdiction compliance analysis (GDPR/CCPA/LGPD/PIPL/PIPEDA). It also includes an LLM/AI surface reconnaissance module that passively fingerprints LLM-powered apps and runs authorization-gated OWASP LLM Top 10 probes. All external API keys are optional, with graceful degradation when unset.
github.comrepoPublished and added 14 May 2026🛡️ Security - AI Repository Security Baseline
A collection of drop-in instruction/config files (AGENTS.md, CLAUDE.md, .cursor/rules, .aiignore, etc.) that give AI coding agents a shared security and privacy playbook: never read .env or secrets files, no hardcoded credentials, OWASP hygiene, PII protection, GDPR support, restricted filesystem/network access, no destructive commands without confirmation, mandatory tests, and dependency/CI change controls including typosquatting checks before adding packages. Each tool-specific file (Cursor, Copilot, Windsurf, Cline, Aider, Amazon Q, Junie, Devin, Cody) delegates to one canonical AGENTS.md so teams maintain a single source of truth across all agents in use.
github.comrepoAdded 3 Sep 2026, published 8 May 2026🛡️ Security - DeepTeam
DeepTeam is an open-source, locally-runnable red teaming framework for LLM applications, agents, and RAG pipelines, built on the DeepEval evaluation library. It simulates jailbreaking, prompt injection, and multi-turn adversarial attacks against 50+ vulnerability categories such as PII leakage, BOLA, BFLA, SQL injection, SSRF, and agentic goal theft, maps results to OWASP, NIST, MITRE, BeaverTails, and Aegis frameworks, and ships production guardrails to block the same issues at runtime.
github.comrepoPublished and added 7 May 2026🛡️ Security
Showing 90 of 97
Show more