Meta’s AI-distilled model detector catches 79% at a 0.1% false-positive rate
WM-Basin is a Meta method for detecting student LLMs distilled from watermarked teacher models, described in "Watermark Basins: Black-Box Detection of Distilled LLMs" (arXiv:2610.37266, 27 October 2026). It feeds a suspect model's API text into a clean probe model and checks gradient alignment with a key-specific watermark basin. It reached 79% true-positive rate at 0.1% false-positive rate across 1,200 students, versus 29% for the prior token-level detector. Clean-data fine-tuning and paraphrasing weaken it.
 en.cryptonomist.charticlePublished and added 30 Oct 2026🧠 AI
 Glance: The Generator Is Its Own Reranker
Glance is a RAG method in which the generator also reranks. It adds a lightweight decision adapter and pointer head that score candidate passages from one shared prefill, so a single resident 9B backbone does generation and reranking. After 39 minutes of MS MARCO fine-tuning it reaches nDCG@10 of 0.741 on SciFact and 0.345 on NFCorpus, against 0.721 and 0.326 for bge-reranker-v2-m3. On 300 HotpotQA questions it improves answer F1 by 0.045 over cross-encoder-selected context. Evaluation covers two retrieval datasets, one QA dataset and one backbone family.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI
 Welcome Le Chonk: Mistral Large 4 on Hugging Face
Mistral Large 4 (Le Chonk) is a multimodal, multilingual Mixture-of-Experts model with about 1T total and 49B active parameters and a 1M-token context, released under the Mistral Ecosystem Open-Weight License. The post covers its MLA and DeepSeek Sparse Attention architecture, a 1.6B Pixtral encoder, and benchmarks including 82% on the Artificial Analysis Cyber Index and 93% on Cybench. It gives run recipes for transformers, vLLM, llama.cpp, TRL fine-tuning and Inference Endpoints.
 huggingface.coarticlePublished and added 29 Oct 2026🧠 AI
 NVIDIA Nemotron 3.5 Transcribe and Granary v2: Intelligent Multilingual Transcription You Can Prompt and Adapt
Nemotron 3.5 Transcribe is an open-weight, promptable speech model that handles transcription in 40 languages, translation, diarization for up to eight speakers, and audio Q&A. It has about 4B active of 30B parameters and tops open-weight ASR and diarization leaderboards. The post also covers the Granary v2 curation pipeline (463,062 hours, 48 languages) and a medical fine-tuning case study that cut held-out WER by 45.8%.
huggingface.coarticlePublished and added 28 Oct 2026🧠 AI- From Leniency to Suspicion: How an Open Post-Training Recipe Changes Whom LLM Fact-Checkers Believe
This paper measures job-based doubt in LLM fact-checkers: judging a claim false more often when the poster has a lower-status job. It compares base and post-trained checkpoints of six model families on fact-checked claims with randomised poster profiles. Only the open Tülu-3 recipe (OLMo-2 32B, Tülu-3 70B) creates the effect, under one percentage point but reliable. In OLMo-2 32B the flip comes from one residual-stream direction and appears at supervised fine-tuning, confirmed on 400 new claims. None of seven commercial models doubts lower-status posters more.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI - Improving the Dependency on Fine-Tuning Data in Transfer Learning for Speech Emotion Recognition
This paper proposes an fMLLR-based compensation mechanism that cuts the fine-tuning data needed in transfer learning for speech emotion recognition under train-test acoustic mismatch. An autoencoder reduces trainable parameters, and an affine transform in the encoder latent space models rotations and shifts. In a human-robot interaction task, mean CCC rose 16.8% with 12.9% of the training set and 14.4% with 50%.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026🧠 AI - Locating Sycophancy Across Training Stages in Open Language Models
Locating Sycophancy Across Training Stages in Open Language Models measures sycophancy in 13 open checkpoints from 5 lineages, from base model through supervised fine-tuning and preference optimization to release. It finds two behaviors with different origins: deference to a claim in the prompt exists in every base model, while capitulation under user objection is largely absent from base models and present in every post-trained checkpoint. Post-trained models often drop firmly held answers as readily as loosely held ones when the objection names an alternative.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026🧠 AI  Build specialized multimodal models with LFM3
LFM3 is Liquid AI's open-weight family of six ~2B-parameter models (text, vision-language, audio, omni and two d1 decision models), all branched from LFM3-1.7B-Base. The base model uses a tri-hybrid backbone of 13 gated short convolutions, 5 sliding-window attention layers and 6 global attention layers, pre-trained on 22T tokens with a 256K context. The post gives transformers snippets, benchmark comparisons against LFM2.5 and Qwen3.5, and a robotics fine-tuning example.
huggingface.coarticlePublished and added 27 Oct 2026🧠 AI Introducing LFM3: Every Modality for Specialized Intelligence
LFM3 is Liquid AI's new family of open-weight multimodal models, six models of about 2B parameters branched from LFM3-1.7B-Base (22T pre-training tokens, 256K context). The hybrid backbone uses 13 gated short-convolution, 5 sliding-window attention and 6 global attention layers. Variants cover text, vision with video, audio, omni and two decision models, with on-device speed numbers, fine-tuning demos and robotics extensions.
 liquid.aiarticleAdded 28 Oct 2026, published 27 Oct 2026🧠 AI
- The Patient Is Always Right? Evaluating Sycophancy in Medical Diagnosis with Graded Patient Beliefs
This paper evaluates sycophancy in medical diagnosis across nine AI models. Each model is shown clinical evidence plus a patient's belief in a specific but incorrect condition, with the belief's closeness to the evidence varied. Models adopted the belief 23.2% of the time on average, even for fictional conditions, and 43.0% under a Rare Disease Claimer persona. Medical fine-tuning and larger scale reduced susceptibility.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026🧠 AI - HerHealthGPT: An Evidence-Grounded Conversational AI System for Women's Reproductive Health Copy title
HerHealthGPT is a conversational AI system for women's reproductive health that combines retrieval-augmented generation, context-aware clarification and source validation in a web interface. Evidence retrieval raises concern-category accuracy from 54.1% to 59.3% over fine-tuning alone on 540 messages from 90 cases. The clarification router reaches 85.6% recall and 86.2% specificity. In a 30-adult study, 83.3% preferred the retrieval-enabled version. The authors say clinical validation is still needed.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI - Task Format as a Factor in Adaptation: A Controlled Comparison of LoRA and Full Fine-Tuning for Prompt-Safety Classification
This paper compares LoRA and full fine-tuning for prompt-safety classification using a matched 400M encoder-decoder pair (Ettin) across three task formats, with up to 15 seeds per cell and pre-specified analyses. Full fine-tuning leads LoRA by 2-3 pp at the pre-specified learning rates, and the encoder gap closes when both use the same learning-rate search. Training LoRA to write a reason after its verdict adds 4.0 pp, while a content-free sentence of equal length does not. Trained models beat a prompted 8B in domain but trail it by 8-23 pp on adversarial jailbreaks and over-flag benign prompts (27-66% against 2-3%).
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI - Unlocking the Specialization Capability of PPG Foundation Models for Wearable Signals through Structured Pruning and Adaptive Fine-Tuning
SPAFT is a structured prune-then-finetune framework for PPG (photoplethysmography) foundation models used on wearable signals. It finds that pretrained PPG models have inherent sparsity and redundancy, then restricts fine-tuning to a compact parameter subspace chosen by parameter importance and structural redundancy. Across four PPG foundation models, five datasets and ten tasks, it wins 82.8% of regression and 87.5% of classification comparisons.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI - An actively trained neural operator for near-explicit atmospheric chemistry
FNO-MoE is a Fourier neural operator with a mixture of experts that predicts the full near-explicit chemical state (Master Chemical Mechanism, thousands of species) over 30 minutes in one call. Expert disagreement selects the most informative box-model simulations, so active sampling beats random or evenly spread sampling at equal cost. Fine-tuning on longer trajectories keeps multi-hour runs stable, and the emulator runs orders of magnitude faster than the numerical solver.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI - Standing on Open Shoulders: Regional Fine-Tuning of Open-Weight Camera-Trap Models for UK Wildlife with Modest Data and Compute
DeepFaune-UK is a fine-tune of the open DeepFaune camera-trap classifier on 28 UK classes, paired with MegaDetector v6. On 20,212 MammalWeb images it reached 88.8% strict accuracy against 56.5% (DeepFaune v1.5.0) and 59.0% (SpeciesNet). Re-applying the recipe to the DINOv3-based classifier gave 90.6%. Fine-tuning on about 150 crops per class matched full-data out-of-distribution accuracy, and a DINOv2 run took about 22 minutes on under 4 GB of GPU memory.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026🧠 AI - DRIVE: Fine-tuning via Data Contribution- and Diversity-aware Weighting with Prior Regularization
DRIVE is a per-sample weighting framework for single-stage fine-tuning when the source pre-training data is unavailable. It uses one differentiable objective: Shapley additivity splits each sample's contribution into anti-forgetting and adaptation parts, a covariance-based diversity term reshapes them, and a sample-characteristic prior stabilizes them. The authors prove better stability-plasticity guarantees than existing weighting schemes and report better performance, faster convergence and more robustness.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026🧠 AI - Sharpness-aware Orthogonalized Momentum Algorithms
SOMA (Sharpness-aware Orthogonalized Momentum Algorithm) combines sharpness-aware minimization (SAM) with the Muon optimizer for LLM training. It avoids SAM's extra gradient computation by using stale, purely stochastic gradient noise as the adversarial perturbation. The authors prove sample complexity does not depend on perturbation direction, study robustness to heavy-tailed gradient noise, and test SOMA against post-training quantization degradation and catastrophic forgetting during fine-tuning.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026🧠 AI - Sensorimotor Alignment: A Platonic Proxy for Embodied Policy Success
Sensorimotor Alignment (S^2) is a training-free offline metric that measures how well an embodied model's sensory representation aligns with the geometry of physical motion. It extends the Platonic Representation Hypothesis to motion trajectories. S^2 correlates positively with downstream robot task success across embodied model families, helps pick promising VLM backbones before fine-tuning into VLAs, and explains behaviours seen in VLAs and world action models.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI - Symmetry-Based Parameter Efficient Low-Rank Fine-Tuning for High-Throughput Calculation of Lattice Thermal Conductivity
SBFS-FT (symmetry-based few-shot fine-tuning) adapts the MatterSim 1M universal machine-learned interatomic potential with low-rank adaptation on a small set of compounds sharing one crystal symmetry. Tested on half-Heusler (space group 216), space group 225 and spinel (227) datasets, it cut lattice thermal conductivity error 2-3 times versus the base model. It matched per-compound fine-tuning while taking 5-7 times less compute for 100 compounds.
arxiv.orgpaperAdded 23 Oct 2026, published 21 Oct 2026🧠 AI - MPIDetector: Detecting Multi-modal Prompt Injection via LLM-based Reasoning
MPIDetector is a detection framework for multi-modal prompt injection that uses few-shot in-context learning so an LLM can reason about the semantic intent of text and image inputs, without fine-tuning. The authors built a benchmark of eight textual and seven visual attack categories plus benign sets. They report up to 90.91% accuracy on text, 99.28% on images, and up to 99.80% detection on 500 obfuscated WebInject web-agent injections, beating baselines.
arxiv.orgpaperAdded 24 Oct 2026, published 21 Oct 2026🛡️ Security - AgenticRoboRL: Bringing Coding-Agent Post-Training to Agentic Robotics
AgenticRoboRL is a framework for post-training robot planners across different harnesses, combining supervised fine-tuning with multi-turn reinforcement learning. Harness-specific adapters link recorded planner interactions to task outcomes, so one RL pipeline covers both VLA skill invocation and control-code generation. On LIBERO-PRO, a 9B planner rose from 18.1% to 71.0% without external memory, near Codex (GPT-5.5) with memory at 72.1%. Code and checkpoints are promised.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - Scaling Parameter-Efficient Fine-Tuning for Brain Encoding
BrainLoRA is a parameter-efficient fine-tuning method that adapts multimodal backbones of up to 104B parameters to predict neural responses. It predicts multiple timepoints in one causal pass instead of sliding windows, and a multi-LoRA kernel trains many adapters on a shared backbone. Across nine backbones it improves encoding, and a 200+ model ensemble ranks first on the Algonauts post-challenge leaderboard.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - Rethinking LLM Fine-Tuning via Weight Space Reparameterization: Preserving Safety during Downstream Adaptation
WSR-Tune is a fine-tuning framework that reparameterizes LLM weight matrices with a safety-conditioned basis, so safety-relevant information concentrates in a small set of directions. Those safety-critical directions are frozen, and the remaining complementary directions are updated for the downstream task. The authors report a better trade-off between downstream performance and safety retention. The page gives no benchmark names or numbers.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - RAGLeak: Supply-Chain Privacy Backdoors in Retrieval-Augmented Generation
RAGLeak is a supply-chain privacy backdoor attack on retrieval-augmented generation. When triggered, the backdoored generator reversibly obfuscates retrieved private documents, and an auxiliary LLM recovers them. Tested on three model families and three domains, it reaches up to 100% attack success rate, loses at most 10 points under detection-based defenses, and survives clean fine-tuning and changes of model scale and version. Source code is released.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🛡️ Security - Knowledge That Is Linear Before Fine-Tuning Generalizes After It
The paper separates "active" facts (which support generalization beyond recall) from "inert" ones. It builds new relations by relabeling answers of existing ones (Paris -> Europe becomes Paris -> crab), fine-tunes on a subset of subjects, and tests held-out subjects that share an answer (Munich -> crab). Across eleven language models and 70 relations, linear readability of the original relation in pretrained representations correlates with this generalization at Pearson r = 0.87 to 0.92 within each model. The result holds after controlling for fine-tuning set size, original-relation accuracy and subject frequency in pretraining text, and it survives re-randomized labels, seeds and thirteen other label categories. Mapping wrong labels back to the original answers shows the fine-tuned model's errors follow the linear probe's top answers.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - Topology-Inspired Fine-Tuning for Wind-Field Super-Resolution
The paper fine-tunes a pretrained CNN wind-field super-resolution model with differentiable topology-inspired auxiliary losses on speed, gradient magnitude, soft high-speed level sets and local maxima. It also uses fixed-pair supervision at ground-truth persistence-pair endpoints located offline with the Topology ToolKit. A 16-configuration loss study on a fixed 168-field benchmark finds that gradient supervision gives the strongest persistence-diagram improvement, while fixed-pair supervision gives the most consistent joint improvement in persistence-diagram and merge-tree distances. The combined objective cuts bottleneck, W2,∞ and W2,2 distances by 31%, 25% and 27% relative to the pretrained CNN, at a cost of about half of standard fine-tuning's PSNR gain. It also shows that pointwise metrics and topological distances rank CNN and GAN models differently.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI  Google DeepMind’s on-device scam detection keeps chats off the cloud
Describes a scam-detection model built by Google DeepMind with GovTech Singapore that runs entirely on the user's device. A low-power message classifier screens incoming messages, then a Gemma model fine-tuned on local scam conversations (impersonated institutions, banks, regional schemes) judges the wider conversation to confirm a threat or discard a false alarm. Fine-tuning ran in a GovTech-managed GCP environment on anonymised scam reports and intelligence feeds, with no PII. Chat access needs user consent, and the system gives real-time warnings. It shows a practical pattern of cascaded small models for battery-efficient, privacy-preserving local inference.
en.cryptonomist.charticlePublished and added 14 Oct 2026🧠 AI Scaling Agentic Data for Long-Horizon Terminal Intelligence
Introduces TerminalHorizon, a fully automated data synthesis engine for long-horizon terminal agents. It uses independent execution to find key work omitted during environment construction and rebuilds the environment from that evidence. It then progressively expands tasks under the same goal with new requirements that build on earlier results. The authors build 1.5K task environments and run supervised fine-tuning of Qwen3.5-27B to get TerminalHorizon-27B, which improves on all 12 benchmarks covering coding-agent tasks, real-world production agentic tasks and general reasoning. Multiple RSI case studies with a 12-hour research budget show the model continuing to experiment past an initial solution and keeping effective improvements in its final deliverables.
huggingface.copaperAdded 13 Oct 2026🧠 AI- Dog-Breed Text-to-image Flow Matching from Pretraining to Fine-Tuning on 4 Consumer GPUs
MiniDog is a framework for training a text-to-image flow-matching diffusion transformer from scratch on four RTX 3090 GPUs, with 55 minutes of pretraining and 15 minutes of fine-tuning. It pretrains on 26k ImageNet dog images that were captioned, then fine-tunes on 2k FLUX.1-schnell generated images. Image and text features are precomputed and cached. The model is a 22M-parameter transformer with the E2E-INVAE semantic latent space, a small Qwen text encoder and in-context conditioning, and training is accelerated with iREPA and an EUPE perception encoder. The repo evaluates with FID, HPSv2, PickScore and VAE reconstruction metrics. It lowers the barrier to hands-on diffusion training research.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI  Gemini 4 Argon for Robotics
Google's developer post presents Gemini 4 Argon as a physical-reasoning model for the whole robotics lifecycle. It reports 87% on the Embodied Reasoning (ERQA) benchmark, ahead of other frontier models. It then gives representative prompts: controlling a Boston Dynamics Spot with a MuJoCo digital twin, closed-loop code-as-policies arm control, steering the Gemini Omni world model, and building digital twins from teleoperation episodes. Further prompts cover retargeting human video to a 76-DoF humanoid, hindsight annotation of ALOHA 2 videos, a general value function on UMI data, sim-data generation for VLA fine-tuning (56% to 75% real success), and reproducing control papers in MuJoCo WebAssembly. It is useful for seeing how the model is prompted for agentic, simulation-driven robotics work.
 developers.googleblog.comarticlePublished and added 13 Oct 2026🧠 AI
- Geometric Calibration of Supervised Fine-Tuning
Proposes Geometric Calibration of supervised fine-tuning and SPACE (Subspace Projection for Adapted Checkpoint Enhancement). SPACE is a post-hoc, data-free, training-free method that uses the pre- and post-SFT checkpoints to revert SFT update components lying in the principal subspace of the pre-SFT weights and keep those in the orthogonal complement. It is evaluated on Qwen2.5, Qwen3, Qwen3.5, Llama-3.1 and Olmo-3 models (2B–14B) with math, coding and medical SFT. It reduces out-of-domain regression and improves in-domain performance, for example +2.85 ID / +2.26 OOD on Qwen2.5-7B math SFT.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI - Gemini 4 Argon for Robotics
DeepMind presents Gemini 4 Argon as a general-purpose physical reasoning model for the robotics lifecycle. It reports 87% on the Embodied Reasoning (ERQA) benchmark and gives representative prompts across several areas: controlling a Boston Dynamics Spot with a MuJoCo digital twin, code-as-policies arm control with a visual coordinate harness, and steering the Gemini Omni world model in a visual feedback loop. Further examples cover building MuJoCo and mujoco_warp scenes from teleoperation data, egocentric video or a hand-drawn sketch for 76-DoF humanoids, hindsight annotation and value-function progress prediction on video, sim data generation for VLA fine-tuning (success rate 56% to 75%), and reproducing control papers in MuJoCo WebAssembly. It matters as a concrete look at how a frontier model is being used as agentic coder, perceiver and sim builder for robotics.
 deepmind.googlearticlePublished and added 13 Oct 2026🧠 AI
- Legal-R1: Agentic Retrieval for Evidence-Based Legal Reasoning
Legal-R1 is an agentic retrieval framework for evidence-based legal question answering that splits reasoning across three agents. A Lawyer agent decides when to retrieve, which legal source to query, what evidence to seek and when it has enough. A Legal Assistant retrieves statutes and precedent cases with authority-aware and diversity-aware selection, and a Judge agent writes the final answer from the full evidence trajectory. Only the Lawyer agent is post-trained, using masked supervised fine-tuning and trajectory-aware reinforcement learning. The paper reports gains over general-purpose, legal-specific and retrieval-augmented baselines on several Chinese legal benchmarks.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI  Building AI for Reliable Execution: Lessons From Industrial Robotics
Latent Space interviews Standard Bots' CEO Evan Beard and Head of AI Leif Jentoft about the AI stack behind its industrial robot arms. A shared base model (low billions of parameters) is adapted per customer through demonstrations and fine-tuning. A zero-shot perception model, whose backbone is trained on over a billion images, handles machine tending, while conventional code handles motion and cell logic. Inference runs on-premises on edge GPUs that stream action chunks to low-level control. Failures and human corrections feed fleet learning except in air-gapped defense deployments, and the StandardOS APIs/SDKs let developers bring their own models such as NVIDIA Cosmos. The lesson is to keep the model's role narrow and use targeted, high-quality data to fix edge cases instead of chasing dataset size.
 latent.spacearticlePublished and added 10 Oct 2026🧠 AI
- A Step Harder, Not a Step Too Far: The Benefits and Limits of Curriculum Difficulty Progression in GRPO
Studies curriculum design for GRPO by re-estimating sample difficulty under the current policy and using a staged curriculum that progressively shifts the active difficulty band toward harder samples. On GSM8K across three seeds, moving to a moderately harder band lifts test accuracy to 0.6591 ± 0.0077 versus 0.6449 ± 0.0024 for fixed-medium selection, while going to a still harder band drops it to 0.6405 ± 0.0053. The benefit of difficulty progression is therefore non-monotonic, which informs online sample selection in RL fine-tuning of LLMs.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026🧠 AI - RARA: Robust Policy Fine-Tuning through Retrieval-Anchored Representation Alignment for Robotic Manipulation
RARA (Retrieval-Anchored Representation Alignment) is a two-stage method for adapting pre-trained robot policies such as Vision-Language-Action models to new tasks from few demonstrations. It first retrieves pretraining representations with similar task intent and motion and aligns the policy's representations of the target demonstrations to them. It then fine-tunes on the target demonstrations while constraining representation change on the retrieved demonstrations, which limits representation drift. Tested with Diffusion Policy and GR00T on 13 tasks in RoboTwin, RoboCasa and on a real robot, it improves average success over plain fine-tuning by 9.5 points in-distribution and 13.6 out-of-distribution, and beats all compared baselines.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026🧠 AI - Overcoming Prior Barriers: Supervised Fine-Tuning under Long-Tail Distribution
Introduces "prior barrier", a measure of how strongly a pretrained LLM supports competing concepts over a target concept, and shows prior barriers follow a long-tail distribution, so tail concepts need more SFT instructions than head concepts. It derives a predictive risk bound for SFT under long-tail prior barriers and proposes PASS, an adaptive instruction selection method that builds reference-derived concepts, estimates each instruction's distinguishing evidence, and allocates the selection budget toward under-covered concepts. PASS beats seven state-of-the-art instruction selection methods across four backbone-budget settings, and ablation shows adaptive allocation beats uniform allocation.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI - RECAST: Learning to Compute the Right Context through Adaptive Evidence Routing
RECAST (Routing Evidence through Computation, Access, and Synthesized Tools) reframes retrieval-augmented generation as a sequential decision process: a lightweight RouterLM iteratively selects or formulates primitive/custom operations, a frozen CompilerLM turns custom operations into executable code, and a frozen AnswerLM produces the final answer once evidence is judged sufficient. RouterLM is trained with supervised fine-tuning followed by GRPO, and the system reaches a 75.6% mean success rate across six heterogeneous benchmark families, beating the strongest large-model baseline by 15.9% and a training-free Gemini 3.5 Flash router by 5.0%, with strong zero-shot generalization on three held-out benchmarks. It targets tasks where evidence must be derived through filtering, aggregation, or computation across multiple sources rather than retrieved verbatim.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026🧠 AI - SLDR: Defending Against Malicious Fine-tuning via Selective Layers Recovery and Dynamic Routing
SLDR is a post-fine-tuning defense against malicious fine-tuning-as-a-service attacks, where an attacker fine-tunes an aligned LLM on a legitimate-looking task to covertly erode its refusal behavior. The method trains a LoRA "recovery" adapter only on the layers found to have maximal and minimal signed safety sensitivity, and uses representation-based dynamic routing at inference time to activate that adapter only for malicious queries, leaving benign task performance untouched. On Llama3.1 fine-tuned for SST2, it cuts the average harmful-output score from 11.54 to 0.08 while keeping downstream accuracy, and stays near-zero even when up to 90% of the fine-tuning data is poisoned.
arxiv.orgpaperAdded 9 Oct 2026, published 7 Oct 2026🛡️ Security - SLDR: Defending Against Malicious Fine-tuning via Selective Layers Recovery and Dynamic Routing
SLDR is a post-fine-tuning defense that protects aligned LLMs from malicious fine-tuning-as-a-service attacks, which can quietly erode refusal behavior while keeping task performance intact. It trains a LoRA recovery adapter only on the layers with the most extreme (signed) safety sensitivity scores, then uses representation-based dynamic routing to activate that adapter solely for malicious queries at inference time. Evaluated across four model architectures, five downstream tasks, and four harmful-content benchmarks, it drives the average harmful score on Llama3.1/SST2 from 11.54 down to 0.08 while preserving downstream accuracy, and stays near zero even at poisoning ratios up to 0.9.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026🧠 AI  One Model Family, Two Gold-Level Results: Fine-Tuning Nemotron for IOI and IMO
NVIDIA describes how it specialized Nemotron 3 base models into domain experts for competitive programming (IOI) and olympiad mathematics (IMO) using a four-step recipe: strong base model, curated domain data with reasoning traces, SFT/RL post-training, and an inference loop (GenCorrect for IOI, generate-verify-refine for IMO) that searches and refines candidate answers. Nemotron-3-Nano-CC and Nemotron-3-Ultra-CC reached gold-level IOI 2026 scores (535.4/600), while SFT and RL checkpoints of Nemotron 3 Ultra combined to score 30/42 on IMO 2026, exceeding the gold threshold with no formal prover or external tools. The post releases training datasets, checkpoints, the Nemotron-IMO-Bench benchmark, and the NeMo-Skills inference pipelines on Hugging Face.
huggingface.coarticlePublished and added 7 Oct 2026🧠 AI- A Systematic Study of Small Language Models on Abstract Reasoning Tasks
This paper presents a systematic empirical study of small language models (decoder-only, encoder-decoder, and mixture-of-experts architectures) on abstract grid-transformation reasoning, using the ARC-TGI benchmark, which supports controllable task families, resampling, spatial shifts, and cross-benchmark transfer to distinguish genuine rule acquisition from distribution-specific overfitting. Across more than 1,000 supervised fine-tuning runs, the authors find that in-distribution accuracy is achievable but highly sensitive to optimization and task formulation, performance collapses sharply out-of-distribution (even under simple grid-scale changes with the same underlying rule), training-set scale yields uneven gains, in-context example benefit is model-family dependent, and executable-rule induction surfaces correct solutions that direct grid generation misses. Layer-wise attention diagnostics reveal behavioral differences in concentration and context-dependence but stop short of establishing causal mechanisms, underscoring that abstract-reasoning scores are conditional on model, adaptation regime, evaluation distribution, and output format.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026🧠 AI - overmind-core/overmind
Overmind is an open-source platform (MIT SDK/CLI, AGPL-3.0 platform, self-hostable) that instruments an agent's code via OpenTelemetry tracing, turns the resulting production traces (or any dataset) into a fine-tuned model benchmarked against user-defined eval metrics, and serves it through one unified API with downloadable/retrainable weights. It ships an SDK, CLI, REST API, Console, and an MCP server exposing project tools and workflows (investigate-capability, finetune-capability, ship-model) for Cursor, Claude Code, OpenCode and Codex, and can sync traces from Langfuse, LangSmith, Braintrust or Galileo; self-hosting runs via Docker Compose with Postgres, Redis, Celery workers and Modal-based GPU workers for fine-tuning/serving (vLLM).
 github.comrepoAdded 6 Oct 2026🧠 AI
- A Fine-Grained Analysis of the LoRA Fine-Tuning Landscape with Implications for Data Selection
This paper develops a sharper theoretical landscape analysis for Low-Rank Adaptation (LoRA) fine-tuning, introducing LoRA-RIP, a data-dependent restricted-isometry metric that measures how well-conditioned the cross-entropy objective is along LoRA-relevant low-rank directions. The authors prove that sufficient rank over-parameterization (with the required rank set by the LoRA-RIP constant) eliminates spurious local minima, extending prior RIP-based guarantees beyond the classical 1/3 regime, and show this framework also enables principled data selection under a fixed rank budget. Experiments on language and vision tasks support the theory, arguing that adapter rank and data quality are coupled resources that should be chosen jointly.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026🧠 AI - HeuFouFT: Task-Guided Metaheuristic Coordinate Search for Fourier Fine-Tuning
HeuFouFT is a task-guided framework for selecting which frequency coordinates to train in Fourier fine-tuning (FourierFT), replacing fixed uniform or Gaussian band-pass coordinate selection with a search driven by downstream task performance. It initializes three metaheuristic optimizers (GA-SA, PSO, Cuckoo Search) from a lightweight block-level probe intensity map, using a Random Forest to filter candidate coordinate sets before proxy fine-tuning. On the E2E benchmark with GPT-2-Medium, all three variants beat random-uniform and Gaussian FourierFT and LoRA, with PSO beating the LoCA baseline on four of five metrics while using 37.6% fewer trainable spectral coefficients and only 15-18% of full fine-tuning FLOPs.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026🧠 AI - GraphForge: Training Working Agents with Graph-Anchored Workspace Synthesis
GraphForge is a data-synthesis framework that builds agent training tasks from real files: it assembles occupation-grounded workspaces, constructs an evidence graph over file relations, and derives both task statements and verification rubrics from that graph so every grading criterion is anchored to specific source files. Fine-tuning Qwen3.6-27B on 2,169 GraphForge trajectories improved GDPVal by +65.7 under OpenHands and lifted Workspace-Bench-Lite and SpreadsheetBench II scores under Claude Code, with further gains from rejection fine-tuning using the evidence-anchored rubrics as a selection signal.
arxiv.orgpaperAdded 4 Oct 2026🧠 AI - IDRF: Inverse-Distilled Reward Fine-tuning of Masked Discrete Diffusion Models
IDRF is a reward fine-tuning framework for few-step masked discrete diffusion generators that replaces the intractable sequence-level KL penalty in reverse-KL-regularized objectives with an inverse-distillation regularization term, proven to upper-bound the true KL divergence to the reference distribution. It frames few-step diffusion sampling as a finite-horizon Markov decision process and optimizes reward via a clipped policy-gradient objective over the student's own trajectories, without needing reference-model rollouts. Across DNA, image, and text generation tasks, IDRF reaches high reward with up to 32x fewer denoising steps than the reference model while reducing reward hacking and preserving sample quality.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026🧠 AI  AutoSynthData: Generating Training Data for Enterprise Agents
AutoSynthData is ServiceNow CoreAI's pipeline for generating synthetic training data for enterprise agents: it evaluates a target model against a stronger teacher in a given environment, distills capability gaps into sanitized "specification cards," then generates and validates new tasks (system specification, user prompt, verifier) via a target-then-multiply process with positive/negative verification, critique-repair loops, and batch-level coverage review. On EnterpriseOps Gym, fine-tuning Gemma-4-26B-A4B-it on AutoSynthData-generated samples improved Pass@1 by 7.2 points (35% relative) on the Hybrid domain and from 18.77% to 27.18% on ITSM, closing 59% of the gap to the teacher model on Hybrid.
huggingface.coarticlePublished and added 2 Oct 2026🧠 AI- zzzz7788990213-ops/EvoVLM
EvoVLM searches over prompts, image preprocessing, generation budgets and answer extraction for frozen Qwen3-VL-2B-Instruct and Qwen3-VL-2B-Thinking, without fine-tuning weights. A local Qwen model ranks a catalog of typed mutations, a trusted renderer produces Python programs, and Pareto selection on accuracy and latency drives two small generations on scientific chart understanding (CharXiv subset). Recorded results on Dev128: Evolved Instruct keeps accuracy with 8.9% lower median latency, and Evolved Thinking gains 16.41 points of accuracy with 10.6% lower median latency. CPU-only replay and fail-closed evidence verification are included. The authors state the limits: small sample, overlap with the evolution set, and results tied to the recorded hardware.
github.comrepoAdded 16 Oct 2026, published 2 Oct 2026🧠 AI - TACO: Ternary Absolute-max Column-wise One-sparse Optimizer for LLM Fine-Tuning
TACO (Ternary Absolute-max Column-wise One-sparse optimizer) is a new optimizer for full-parameter LLM fine-tuning that reduces optimizer state memory by computing the exact steepest-descent direction under a dimension-normalized operator norm, selecting only the largest-magnitude gradient entry per weight-matrix column. On OPT-13B it cuts persistent optimizer state 174x versus AdamW8bit (27.7GB to 0.16GB) and peak training memory 2.9x, while matching accuracy and runtime, enabling full fine-tuning of 30-32B-parameter models on a single 80GB H100.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - Trust the Direction, Search the Step: Zero-and-First-Order Methods for LLM Fine-Tuning
This paper introduces ZFO (Zero-and-First-Order optimization), a lightweight fine-tuning framework that decouples search direction from step-size selection: a trusted first-order optimizer picks the direction, while two extra zeroth-order function evaluations along that single dimension build a local curvature-aware model to choose the step size, avoiding a full line search. The authors give theoretical guarantees on finite-difference curvature estimates, near-optimal step selection, and convergence to a stationary-point neighborhood, and show empirically that ZFO improves optimization and final performance over fixed-step first-order baselines across several language models and datasets. Code is released publicly, making it a usable technique for practitioners fine-tuning LLMs who want cheaper adaptive step-size control.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - Harnessing Domain Specialists in Multimodal Mixture-of-Experts for Efficient Adaptation
This arXiv paper studies emergent semantic specialization among experts in multimodal Mixture-of-Experts (MoE) models and introduces ExpertLens, a data-free method that identifies domain-specialized experts by decoding router weights into vocabulary tokens from pretrained weights alone. Using this to selectively fine-tune only the relevant experts, the authors match or beat full fine-tuning on math, medical, and remote-sensing tasks while updating only 21.7-47.0% of parameters, achieving a 4x training speedup and outperforming LoRA in both performance and efficiency.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - LLM2Jev: LLMs Are Already Jev-Style Decision Models -- When and How to Fine-Tune Them
LLM2Jev is an architecture-preserving framework that extracts calibrated categorical decisions directly from an LLM's next-token probabilities over bracketed numeric identifiers, rather than generating free-form text. The paper shows Qwen3.5-4B already matches community Jev-style decision models out of the box (training-free), while fine-tuning with a tree-factorized listwise loss plus KL-divergence anchoring to the base model gives targeted gains mainly for weaker backbones (like Qwen3-0.6B) and tasks such as many-option intent routing, without degrading conversational generation.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - Selection-Based Structured Reasoning: Toward Efficient Multimodal Search Agents
The paper introduces Selection-based Structured Reasoning (SSR), a framework that replaces free-form chain-of-thought generation in multimodal search agents with selection among pre-specified, reusable natural-language reasoning candidates, scored by likelihood via teacher-forced prefilling with a shared KV cache. Evaluated on seven multimodal search benchmarks using 2B and 4B scale models under both reinforcement learning and supervised fine-tuning, SSR matches the success rate of leading search agents of the same scale while cutting per-turn reasoning latency by over 90% and total per-question inference latency by 28-54%. It targets the problem of small models producing long, low-value reasoning traces before each action, which is costly at inference time.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI  Clef / Clef-flash decision models (Cloudflare)
Cloudflare announces Clef and Clef-flash, open-weight "decision models" (Apache 2.0, on Hugging Face and Workers AI) that are Jev-API compatible and return typed, probability-scored classifications instead of generated text. The models are built by post-training a frozen Qwen backbone (Qwen3.8-27B for Clef, a smaller Qwen3.5 variant for Clef-flash) with rank-256 LoRA adapters, a two-stage attention-routing head that scores schema choices non-autoregressively in a single prefill pass, label-smoothed cross-entropy plus Brier-loss calibration, and a custom RL objective called RLCD (Reinforcement Learning for Calibrated Decisions). Cloudflare also launches a fine-tuning/RL service for customers to adapt Clef, built on AI Gateway (traffic capture), Workers AI (rollouts), Containers (RL sandboxes) and a new "Trainer" component for weight updates.
 blog.cloudflare.comarticleAdded 3 Oct 2026, published 1 Oct 2026🧠 AI
 Introducing Clef and Clef-flash: Cloudflare's open-source decision models
Cloudflare announces Clef and Clef-flash, its first in-house trained decision models, now hosted on Workers AI and open-sourced under Apache 2.0 on Hugging Face. Unlike text-generating LLMs, Clef takes a state plus up to 64 typed questions (yes/no, multiple-choice, or rubric score) and returns calibrated probabilities instead of free-form text, aiming for millisecond-latency structured decisions in agent pipelines. Cloudflare reports it beats TypeSafe's Jev on 7 of 10 decision benchmarks while running 2.5x (Clef) to 13x (Clef-flash) faster, and also launches an RL fine-tuning service for custom tuning.
 developers.cloudflare.comarticleAdded 4 Oct 2026, published 1 Oct 2026🧠 AI
- AssemblyWorld: Rethinking 3D Assembly with General-Purpose Agents
AssemblyWorld is an interactive 3D environment where general-purpose agents assemble objects (furniture, industrial parts, fractured pieces) by inspecting rendered 2D views and manipulating supplied rigid parts, optionally guided by images or assembly manuals, without any assembly-specific fine-tuning. The accompanying AssemblyWorldBench benchmark covers 100 tasks across 80 objects and evaluates eight agent systems geometrically; the best system reaches 80.9% part accuracy but only 59.4% complete-assembly success, and open-source systems lag closed-source ones in both reliability and accuracy. The paper analyzes interaction trajectories and failure modes to characterize the gap between approximate structure recovery and precise 3D reconstruction.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI - Gen AI Spotlight (@GenAISpotlight) on X
A tweet summarizing Anthropic's research finding that Z.ai's open-weight GLM-5.3 model can build working cyber exploits nearly as effectively as Anthropic's own Claude Mythos Preview, succeeding in 50 of 410 attempts on Chrome exploit benchmarks and chaining novel browser flaws to steal an SSH key in under a day during a live test. Anthropic warns that because GLM-5.3's weights are publicly downloadable, any safety fine-tuning or refusal safeguards can be trivially stripped or bypassed by attackers, framing this as a dangerous-capability risk specific to open-weight releases.
 x.comthreadPublished and added 30 Sep 2026🧠 AI
- Counterfactual Video Generation Enables Scalable Humanoid Loco-Manipulation
PRISM is a real-to-sim-to-real framework that scales humanoid loco-manipulation training by generating hundreds of diverse "counterfactual" human-object interaction videos from a handful of real exemplar clips via video-to-video generation. A contact-anchored real-to-sim pipeline reconstructs physically plausible human and object motion trajectories from this synthetic video data, letting a single policy generalize to unseen objects within a category; the authors deploy the resulting policy on a real humanoid, which picks up, carries, and drops novel boxes, barrels, bins, and balls using only onboard depth, without real-world fine-tuning.
arxiv.orgpaperAdded 30 Sep 2026, published 29 Sep 2026🧠 AI 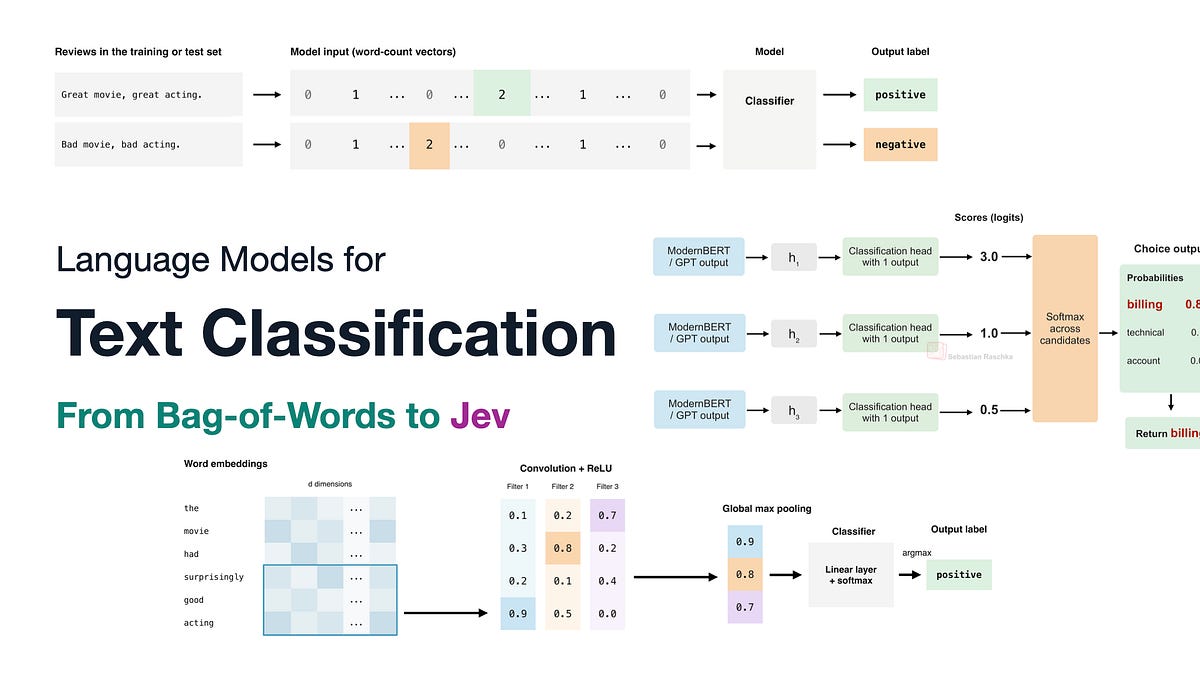 Language Models for Text Classification: From Bag-of-Words to Jev
Sebastian Raschka surveys the history of text classification — bag-of-words with naive Bayes/logistic regression, RNNs and CNNs with word embeddings, then transformer approaches (BERT/ModernBERT, GPT-style decoder fine-tuning, T5 encoder-decoder) — before analyzing TypeSafe AI's new Jev model, a fast/cheap general-purpose classifier accessed via Choice/Noul/Score APIs. He benchmarks Jev against a fine-tuned ModernBERT on the IMDb sentiment dataset (Jev ~96.2-96.5% vs ModernBERT ~95%), explains how to retrofit a Jev-like classification head onto BERT/GPT models, and discusses probability calibration, including the RLCR (Reinforcement Learning with Calibration Rewards) technique from a 2025 paper that likely inspired Jev's proprietary "RLCD" training method.
 magazine.sebastianraschka.comarticlePublished and added 29 Sep 2026🧠 AI
- Uncensored and Offensive Security AI Models Benchmark
A curated GitHub list of open-weight "uncensored" and security-fine-tuned LLMs intended for authorized red teaming, pentesting, and security research, covering models like WhiteRabbitNeo's DeepHat V2, BugTraceAI-CORE, CYBER-FROST, and several abliterated Qwen/GLM/DeepSeek variants. It explains the underlying techniques (abliteration per Arditi et al. 2024, QLoRA/DPO fine-tuning, GGUF/FP8 quantization) and links to Hugging Face model cards, benchmark suites (CyberBench, TrustedSec's LLM Attack Benchmark vs OWASP Juice Shop), and deployment platforms for running these models locally or via API.
github.comrepoAdded 2 Oct 2026, published 29 Sep 2026🛡️ Security - Shockingly Simple Self-retrospection Improves Agentic Models Without RL
The paper introduces Retrospection-Only Fine-Tuning (ROFT), a minimal online training procedure where an LLM agent generates a self-written explanation of its own attempt at a task and is then fine-tuned with next-token prediction on that explanation alone, without any reward signal or external teacher. Using Qwen3.5-4B on software-engineering tasks, ROFT reaches 49.2% and 26.8% solve rates on held-out SWE-bench Verified and SWE-bench Pro after 20 updates, edging out GRPO's 48.0%/25.3% after 40 updates and making faster early progress, and it can even learn to solve tasks where all 64 sampled base-model attempts initially failed. The authors argue this shows self-generated retrospections act as useful training signal, implicitly performing credit assignment and shaping behavior (e.g., shorter solutions) without RL machinery.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI - EvE: An Alternate Optimizer to Adam
EvE (Evolutionary Explorer) is a steady-state, population-of-four differential evolution optimizer with a targeted Adam fallback, proposed as an alternative to Adam for cheap, early ranking of configurations in hyperparameter and architecture search. Under a fixed evaluation-cost-matched budget it wins or ties Adam on 76% of 70 (problem, dimension) cells across seven scalable benchmarks up to one million variables, and on real tasks (MLP on MNIST, LoRA fine-tuning of a 1.5B-parameter LLM on two datasets) it finishes 1.7-3.9x faster at a modest quality cost. Inside successive halving on UCI Adult it completes hyperparameter/architecture searches 3.1-3.5x faster while ranking configurations nearly as consistently as Adam does with itself across seeds (Kendall's tau 0.66-0.69).
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI - Can Agents Generalize to the Open World? Unveiling the Fragility of Static Training in Tool Use
This paper formalizes OpenAgent, a problem setting for evaluating LLM tool-use agents under real-world distributional shifts in queries, actions, observations, and domains. Using a controlled sandbox with a four-tier hierarchy (Perception, Interaction, Reasoning, Internalization) of environmental shifts, the authors show that both SFT- and RL-trained agents degrade significantly outside static training distributions, and propose Perturbation-Augmented Fine-Tuning as a mitigation.
arxiv.orgpaperAdded 26 Sep 2026🧠 AI - Calibration Without Comprehension: Diagnosing the Limits of Fine-Tuning LLMs for Vulnerability Detection in Systems Software
CWE-Trace is a benchmark and diagnostic framework of 834 manually curated Linux kernel samples spanning 74 CWEs, built with a strict temporal train/test split to rule out data contamination, used to evaluate eight vanilla LLMs and 15 LoRA fine-tuned variants on vulnerability detection and CWE classification. The paper introduces two new metrics — Directional Failure Index (DFI) and Hierarchical Distance and Direction (HDD) — and finds that fine-tuning only recalibrates output thresholds rather than improving actual security reasoning, with the best model reaching just 52.1% detection accuracy (barely above chance) and under 1.3% Top-1 CWE classification accuracy.
arxiv.orgpaperAdded 26 Sep 2026🧠 AI - Your Transformer Can Hold Two Thoughts at Once: Evidence of Linear Superposition in LLMs
This paper introduces the "Superposition Linearity Hypothesis": when inputs from two distinct text streams are linearly combined, an LLM's output approximates a superposition (average) of the two individual next-token distributions. The authors show this linearity is an intrinsic property of the Transformer architecture that weakens during pretraining but can be restored via lightweight fine-tuning, and they propose a guided decoding method that exploits this to generate two coherent continuations from a single forward pass.
arxiv.orgpaperAdded 26 Sep 2026🧠 AI - Calibration Without Comprehension: Diagnosing the Limits of Fine-Tuning LLMs for Vulnerability Detection in Systems Software
This paper introduces CWE-Trace, a benchmark of 834 manually curated Linux kernel vulnerability samples spanning 74 CWEs with a strict temporal split to eliminate training data leakage. Evaluating eight vanilla LLMs including DeepSeek-R1 and fifteen LoRA fine tuned variants, the authors find contamination gives no real advantage and that fine tuning only shifts output calibration rather than underlying security reasoning, with the best model barely beating chance and CWE ranking accuracy staying very low. Two new diagnostic metrics are introduced to expose this calibration without comprehension failure mode.
arxiv.orgpaperAdded 26 Sep 2026🛡️ Security - Learning to Stop without Learning to Stop: Self-Supervised Confidence Training Improves Reasoning Efficiency
This paper introduces a self-supervised fine-tuning procedure that trains reasoning models to predict their own confidence at intermediate points in a reasoning trajectory, using only 600 training problems and no explicit length or stopping objective. Despite training only on confidence prediction and using standard generation at inference (no early-stopping or confidence elicitation), the fine-tuned models cut generated tokens by up to 25% at matched accuracy across Gemma, Qwen, Nemotron, and GPT-OSS on math, science, and coding reasoning benchmarks. Analysis shows the models largely retain their base reasoning composition rather than suppressing specific behaviors, suggesting efficient reasoning can emerge as a byproduct of learning metacognitive confidence signals.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI - Generate, Track, Improve: Perceptive Multi-Skill Humanoid Locomotion with RL-Fine-Tuned Motion Generators
This paper presents a two-layer humanoid locomotion architecture: a perceptive flow-matching motion generator that plans whole-body trajectories from raw depth images, paired with a control-guided RL tracking policy that follows those motions. The core contribution is a sample-efficient off-policy RL fine-tuning loop — using structured search with the generator plus advantage weighted regression — that improves terrain consistency on unseen geometries, boosting successful terrain traversals by up to 25 percentage points and skill selection by up to 80 points. The system is deployed on a Unitree G1 humanoid, enabling walking, running, jumping on/off boxes, and stair traversal outdoors using only raw depth images (no odometry or height maps).
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI - DeepEdu-v1: Efficient and Scalable Agentic LLMs for Vietnamese Education
DeepEdu-v1 is a self-hosted AI tutoring system for Vietnamese education built on SCALE (Self-improving Context-Aware Learning Engine), designed to keep student data on-premise (per Vietnam's Decree 53) while avoiding the hallucination and latency problems of cloud LLMs and naive self-hosting. SCALE combines a long-context inference engine that clusters token selection to cut retrieval calls by 7.7x and prefill latency (TTFT) by ~35% versus a selective-attention baseline, with a self-improving agentic layer that curates a verified knowledge playbook from past interactions instead of fine-tuning. The deployed system reports ~2x TTFT speedup over standard vLLM serving and raises agentic task accuracy from 70.0% to 79.5%, with the largest gains on financial-reasoning and interactive-agent benchmarks.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI - SAID: Semantic Acoustic Imaging Detector for Sound Event Localization and Detection
SAID (Semantic Acoustic Imaging Detector) is a new model that predicts a separate labeled 360°x180° acoustic map per active sound source from audio, jointly estimating source region, energy, and class rather than just a direction estimate. It is pretrained via a new audio encoder, Audio2Sph, using sound energy estimation across directions on simulated recordings before fine-tuning on real data, and the submitted system ranked first on the official DCASE2026 Task 3 Track A evaluation (0.1080 Macro mAP, 0.3962 Macro Pearson r).
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI  Runway’s WorldPrompt and the Engineering of Real-Time Worlds
A Latent Space interview with Runway's CTO Kamil Sindi, Principal Research Scientist Robin Kahlow, and co-CEO Anastasis Germanidis about GWM Worlds 2, a research-preview "autoregressive diffusion" model that streams real-time interactive video (720p/24fps) and audio (48kHz), and its new WorldPrompt input format for fixing a first frame and issuing timestamped in-world events. It details the engineering pipeline (bidirectional diffusion → autoregressive fine-tuning → distillation for real-time speed), open problems like error accumulation, context/memory management, and causal/counterfactual correctness, and situates Runway against Google DeepMind's Genie 3, Odyssey-2 Pro, and World Labs' RTFM. A companion podcast transcript covers Runway's history from pix2pixHD/Gen-1/Gen-2 through the Stable Diffusion collaboration to its pivot toward world models.
latent.spacearticleAdded 29 Sep 2026, published 25 Sep 2026🧠 AI- Beyond Compression: Training Latent Representations for Stable Long-Horizon Rollout in Neural Surrogate Solvers
This paper investigates why latent neural surrogate solvers (autoencoder-based dynamics models) become unstable over long autoregressive rollouts, finding the cause is representations trained only for reconstruction rather than forecasting. The authors test interventions — Koopman operator learning, Hamming noise injection during autoencoder training, and multi-step rollout fine-tuning — that trade off reconstruction/one-step accuracy for ~40% lower long-horizon error, matching full-resolution models while using two orders of magnitude fewer FLOPs and half the GPU memory, validated on physics benchmarks and mesoscale crystal-plasticity fatigue simulations.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026🧠 AI  Transformers now runs llama.cpp quants
Hugging Face Transformers can now load GGUF quantized checkpoints directly via from_pretrained(gguf_file=...) and run them at near-llama.cpp speed on Apple Silicon by reusing ggml's Metal kernels through the kernels library, plus generation-loop optimizations such as dropping unnecessary attention masks and deferring stopping checks. The post benchmarks Qwen3.5 dense and MoE GGUF checkpoints against llama.cpp's llama-bench on an M2 Max, shows how to serve GGUF models with transformers serve as an OpenAI-compatible endpoint usable by clients like Jan or Pi, and covers dequantizing GGUF weights for fine-tuning via GgufConfig(dequantize=True). Current limitations: MPS-only packed inference, no batching support yet, and architecture coverage limited to Qwen3.5/Qwen3.8.
huggingface.coarticleAdded 29 Sep 2026, published 22 Sep 2026🧠 AI- VideoGen-Agent: Reinforcing Video Generation Agents
VideoGen-Agent is a multimodal agent trained with multitask agentic reinforcement learning to coordinate augmentation, generation, and verification tools for video generation, using supervised fine-tuning on teacher trajectories followed by RL with a category-aware hybrid reward. The authors introduce VABench, a 600-prompt held-out benchmark covering procedural knowledge, identity preservation, physical consistency, scene composition, and multi-shot temporal structure, on which the agent improves over its base text-to-video model from 56.5 to 75.6 (and 86.1 when upgrading the underlying generation tools).
arxiv.orgpaperAdded 22 Sep 2026, published 21 Sep 2026🧠 AI - Cross-sector generalization of accident-process role classification in occupational accident narratives
This paper evaluates cross-sector generalization of a role classifier that structures French occupational accident narratives into four accident-process roles (work situation, unfavourable condition, accident event, consequence). Classifiers trained solely on 42,244 construction-sector factual units are tested without retraining on metallurgy, chemistry-plastics, and an independent company corpus, comparing frozen pretrained representations against task-specific fine-tuning and supervised representation learning. Task-adapted strategies consistently outperformed frozen representations, reaching 85.6-85.8% average balanced accuracy across unseen sectors, supporting transferable assisted-coding systems for occupational risk analysis.
arxiv.orgpaperAdded 22 Sep 2026, published 18 Sep 2026🧠 AI - Proxy Policy Steering
Proxy Policy Steering (PPS) is an inference-time adaptation method for generalist robot manipulation policies that trains two lightweight proxy policies (reference and task) whose calibrated velocity-space difference steers a frozen base diffusion/flow sampler at each denoising step. Because the base model's weights are never modified, PPS preserves broad manipulation priors while specializing to new tasks from limited demonstrations, only requiring forward velocity predictions from the base. On 8 real-world and 4 simulation tasks it lifts the pi 0.5 base policy by 53% absolute success rate, outperforming LoRA fine-tuning, from-scratch specialists, and residual policies.
arxiv.orgpaperAdded 22 Sep 2026, published 8 Sep 2026🧠 AI - UniMate: One Unified Model to Animate Diverse Skeletons
UniMate is a unified foundation model that generates articulated motion for arbitrary rigged 3D skeletons from a text prompt, without per-skeleton fine-tuning or reference motions at inference. It introduces a topology-aware diffusion transformer combining graph-aware attention bias from joint relations/geodesic distances, a spectral RoPE generalization via the graph Laplacian, and a global topological conditioner, trained on the newly curated UniML3D dataset (13,006 motion sequences across bipedal, quadrupedal, avian, marine, insectoid, serpentine and rigid-object skeletons). It outperforms prior category-specific animators and supports zero-shot cross-topology transfer, in-betweening, expansion, and text-guided editing.
arxiv.orgpaperAdded 22 Sep 2026, published 4 Sep 2026🧠 AI - Towards Scaling Quantum Fine-Tuning of Foundational Time Series Models for Classification
This paper fine-tunes Amazon's Chronos time-series foundation model with a quantum circuit "head" for power-grid event classification on the PSML-5 benchmark, showing the quantum head outperforms a larger classical MLP by 1.7-2.0 points of balanced accuracy on identical inputs. The authors identify that scaling gains saturate due to data-intake bandwidth limits of a fixed-width quantum register, not circuit expressiveness, and introduce the "wing module" — a few-qubit sparse coupling circuit that feeds additional information into a fixed 12-qubit core, raising balanced accuracy from 83.6% (no wings) to 85.2% (two wings, 19 qubits total). Ablations confirm gains come specifically from added information bandwidth, not merely added qubits/parameters.
arxiv.orgpaperAdded 22 Sep 2026, published 4 Sep 2026🧠 AI - TokenMatch: 3D Mesh Correspondence Transformer with Curvature-Guided Tokenisation
TokenMatch is a transformer-based model for 3D mesh shape correspondence that uses curvature-guided adaptive tokenisation to turn meshes into patches, learning patch- and point-level relations via self- and cross-attention. Trained only on the BeCoS partial-to-partial dataset, it generalises to full-shape matching without fine-tuning, outperforming prior methods on CP2P, PSMAL, BeCoS, FAUST, SCAPE and SHREC'19 while running at sub-second inference.
arxiv.orgpaperAdded 22 Sep 2026, published 3 Sep 2026🧠 AI  Fine-tuning a 350M Model for Better Structured Outputs in 100 GRPO Steps
A Hugging Face blog walkthrough showing how to GRPO-fine-tune LiquidAI's LFM2.5-350M model with TRL and a LoRA adapter (targeting LFM's hybrid attention/convolution modules) using three custom reward functions — JSON/YAML format compliance, field-count matching, and JSON Schema validation — trained on ~500 samples from nvidia's Nemotron-RL-instruction_following-structured_outputs dataset for just 100 steps. On the IFStruct benchmark, the fine-tuned model's overall pass rate rises from 22.6% to 29.7% (JSON specifically from 18.0% to 31.9%), narrowing the gap to the much larger Qwen3.5-2B (33.15%). The post also covers converting the merged model to GGUF and serving/evaluating it locally via llama.cpp's OpenAI-compatible server.
huggingface.cowriteupAdded 29 Sep 2026, published 3 Sep 2026🧠 AI- Human-Agent-Society/reef
Reef is an open-source infrastructure stack for continual self-improving agents, wiring together agent inference, scored feedback, training/updates, and versioned delivery into one loop. It supports two learning surfaces: fine-tuning model weights via RL training steps (using Slime and SGLang on top of models like Qwen2.5-1.5B-Instruct) or evolving an agent's harness — prompts, rules, and skills — through its built-in "Reefine" recipe, which lets a model propose and install harness changes from plain-language requests. It exposes an OpenAI/Anthropic-compatible inference endpoint plus a reporting endpoint for scoring interactions, and ships a recipe catalog (e.g. the SAO recipe referencing arXiv:2607.07508) for pluggable learning strategies.
github.comrepoAdded 2 Oct 2026, published 31 Aug 2026🧠 AI  Teaching Everyone to Fish for Tokens
Nathan Lambert's interconnects.ai essay argues open-weight AI models function less like Linux and more like installed software versions, while the true open-source analogue is full training recipes like Ai2's Olmo or EleutherAI's Pythia. It examines why Nvidia is bankrolling near-open-source efforts (e.g. Nemotron, reportedly ~$26B) to sustain demand for its chips, why companies like Databricks and 01.ai have exited model training, and predicts open models will fork toward a long-tail niche (on-prem, specialized, efficiency-focused) unless open ecosystems develop their own platform-like financial feedback loops. It also proposes that the "pretraining/post-training" lexicon may split into pretraining, reasoning training, and post-training as base-model training becomes more opaque and post-training/fine-tuning (e.g. via Tinker) dominates community interest.
 interconnects.aiarticleAdded 29 Sep 2026, published 17 Aug 2026🧠 AI
 Building an AI Text Detector From Scratch
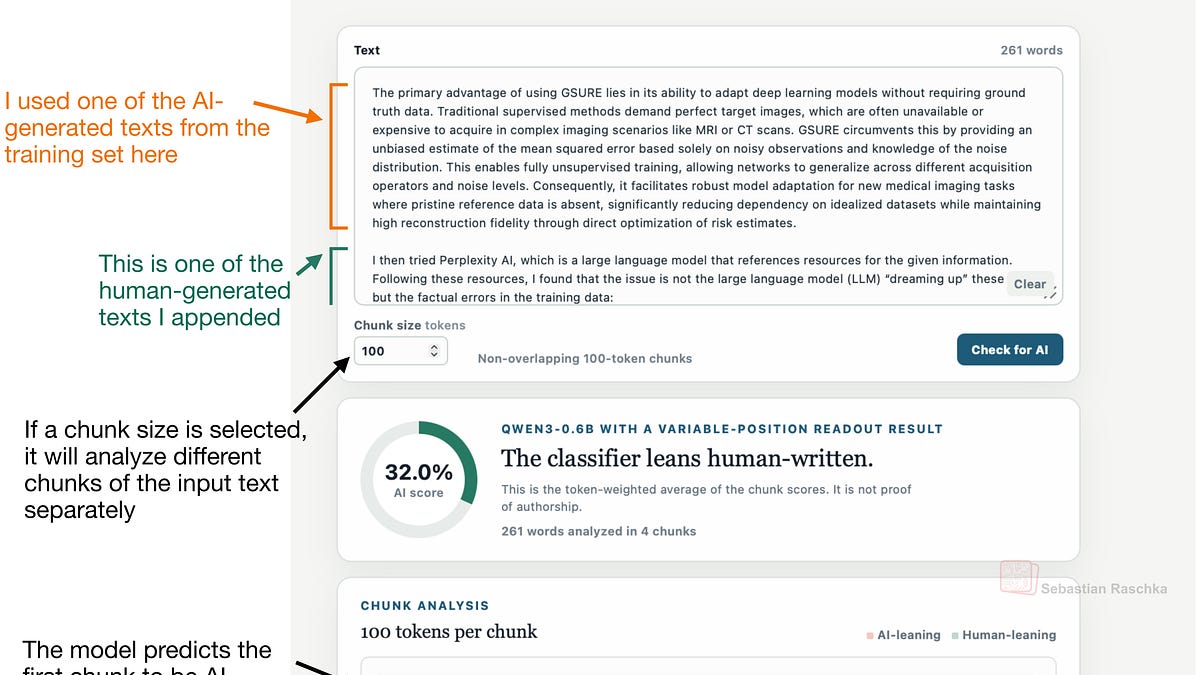
Sebastian Raschka walks through building an AI-generated-text detector from scratch by fine-tuning a DistilBERT classifier that outputs a 0-100 AI-likelihood score, similar to the approach reportedly behind Substack's new AI-detection feature (built on Pangram-style methods). He then uses this detector as a verifier to train a small language model to rewrite text so it scores as human-written, turning the tutorial into a hands-on case study of the detector-evasion cat-and-mouse game and of verifier-based LLM training beyond math/code reasoning tasks.
magazine.sebastianraschka.comarticleAdded 29 Sep 2026, published 15 Aug 2026🛡️ Security- Building an AI Text Detector From Scratch
Sebastian Raschka walks through building an AI-text detector from scratch, similar to Pangram-style models behind Substack's new AI-detection UI feature, by fine-tuning a DistilBERT classifier that outputs a 0-100 AI-generated probability score. He then uses that classifier as a verifier/reward signal to train a small language model (SLM) to produce text that evades the detector, framing the whole project as a case study in building scorers/verifiers for LLM applications beyond math/code reasoning tasks. The piece covers detector approaches broadly (supervised classifiers, perturbation-based tests, perplexity, watermarking) before diving into the DistilBERT fine-tuning implementation.
magazine.sebastianraschka.comarticleAdded 29 Sep 2026, published 15 Aug 2026🧠 AI - MakazhanAlpamys/Soup
Soup is a CLI tool for fine-tuning and post-training LLMs with a single YAML config and one command, wrapping transformers/PEFT/TRL/MLX backends with auto batch-size/GPU detection and QLoRA support. Its notable technical contribution is "layer streaming," which trains an 8B model on a 4GB laptop GPU by streaming the frozen base model from host RAM one decoder layer at a time, verified bit-exact against resident runs and documented in an accompanying Zenodo preprint with detailed benchmark data including failures and retracted claims.
github.comrepoAdded 22 Sep 2026, published 14 Aug 2026🧠 AI - calmrocks/ai-engineer-notebooks
A GitHub repo of self-contained, runnable Colab notebooks teaching the AI Engineer / Forward Deployed Engineer skill set from raw model APIs rather than frameworks like LangChain. It covers model APIs, evals (treated as central rather than an afterthought), RAG, agents (loop from scratch, tool design, guardrails, MCP), LoRA fine-tuning, security, operations, and serving/inference performance, all runnable free on the Groq API with optional Colab-GPU appendices for GPU-only topics. Includes real end-to-end case studies and a capstone project brief aimed at people moving from backend/full-stack roles into applied AI roles.
github.comrepoAdded 23 Sep 2026, published 11 Aug 2026🧠 AI - requie/AI-Red-Teaming-Guide
A community-maintained GitHub guide (requie/AI-Red-Teaming-Guide) that consolidates AI red-teaming methodology, mapping techniques like prompt injection, jailbreaking (Skeleton Key, Crescendo), model extraction, data/fine-tuning poisoning, and MCP tool-poisoning/rug-pull attacks to frameworks including NIST AI RMF, OWASP Top 10 for LLM Applications and Agentic Applications, MITRE ATLAS, and CSA's Agentic AI Red Teaming Guide. It cites real incidents (OpenClaw's CVE-2026-25253, GitHub Copilot's CVE-2025-53773, the Anthropic-disrupted Claude Code state-sponsored campaign, the Morris II AI worm) and surveys red-team tooling (PyRIT, NVIDIA's Garak, DeepTeam) plus emerging agent-orchestrated red-teaming approaches.
github.comrepoPublished and added 8 Jul 2026🛡️ Security