 川崎元 (@foryangxin) on X
CVE-2025-6514 is an OS command injection (CWE-78, CVSS 9.6) in mcp-remote 0.0.5 to 0.1.15, fixed in 0.1.16. A malicious MCP server supplies a crafted authorization_endpoint during OAuth discovery, and the open package passes it to PowerShell on Windows. The thread cites the MCP spec's URL scheme allowlist rules and advises treating discovery metadata as untrusted, pinning bridge tools and sandboxing them.
 x.comthreadAdded 2 Nov 2026, published 30 Oct 2026🛡️ Security
 Google Touts Powerful Cybersecurity Capabilities in Gemini 4 Carbon Model
Gemini 4 Carbon is Google's new frontier model, announced with scores of 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Google says it beats GPT-6 Astra, Claude Opus 5.5 and Claude Fable 5.1 on these, with no guardrails. Access is limited to Fairwind Program partners at first. Pricing starts at $2 input and $10 output per million tokens, rising to $4 and $20.
 securityweek.comarticlePublished and added 29 Oct 2026🧠 AI
- Google Touts Powerful Cybersecurity Capabilities in Gemini 4 Carbon Model
Gemini 4 Carbon is a Google frontier model announced with restricted access for cyber defenders through the Fairwind Program (650+ organizations). Google reports 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench, ahead of GPT-6 Astra and Claude models, with no guardrails. It also cites prompt injection and cheating-resistance results, and pricing of $2/$10 per million tokens.
securityweek.comarticlePublished and added 29 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CVE-2026-103780 is a stack-based buffer overflow (CWE-121) in Dell PowerProtect Data Domain / DD OS. An unauthenticated remote attacker could get command execution (CVSS 3.1 9.8, Dell DSA-2026-416). The post lists affected and fixed builds for four release trains (Feature Release, LTS2024, LTS2025, LTS2026). It adds KEV, EPSS and SSVC status, plus six defensive checks. The vulnerable service is not public.
x.comadvisoryAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security  [AINews] Gemini 4 Carbon tops leaderboards, launches for cyber defenders
AINews issue for 27-28 October 2026, a Latent Space digest of Twitter and Reddit. It leads with Google DeepMind's Gemini 4 Carbon: claimed cyber scores (SEC-bench Pro 88.2%, ExploitGym 54.8%, CWE-bench 71.0%), #1 on Artificial Analysis Intelligence Index v5 at 59, and access limited to cyber defenders through the Fairwind Program. It also covers benchmark integrity disputes, GitHub Copilot Fusion, H-Net v2, KV-cache work, open-weight releases and Claude Code quota complaints.
 latent.spacearticlePublished and added 29 Oct 2026🧠 AI
- Laban (@lunkertw) on X
An X post summarising five AI items: Google DeepMind's Gemini 4 Carbon (88.2% SEC-bench Pro, 54.8% ExploitGym, 71.0% CWE-bench, 59 on Artificial Analysis Intelligence Index v5.0), Ed Zitron's critique of Anthropic's S-1, a Utah Claude Code pilot, and the repos beenuar/AiSOC and expo/skills. In the Utah pilot, 34 developers in 10 agencies took part over four weeks, 80% had a working setup within 30 minutes, and 71% saved over 20 hours. It gives short summaries and links, not primary analysis.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026🧠 AI - 🚨 AI News | TestingCatalog (@testingcatalog) on X
Gemini 4 Carbon is a new Google model, announced in a TestingCatalog post on X as taking first place on the Artificial Analysis V5 ranking. It is rolling out to cyber defenders first. Reported scores are 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching). The post calls it a large step up from Gemini 4 Argon, released two weeks earlier. It gives no technical detail beyond these claims.
x.comthreadAdded 30 Oct 2026, published 28 Oct 2026🧠 AI  Gemini 4 Carbon
 is Google's frontier model, announced with cybersecurity results: 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching). Google reports 0.0% attack success on Gray Swan's indirect prompt injection benchmark. Access starts with a subset of cyber defenders through the Fairwind Program. Pricing is $2 per million input tokens and $10 per million output tokens.
 blog.googlearticleAdded 29 Oct 2026, published 28 Oct 2026🛡️ Security
- Gemini 4 Carbon
Gemini 4 Carbon is Google's frontier model, announced two weeks after Gemini 4 Argon. It scores 59 on Artificial Analysis Intelligence Index v5.0, 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Pricing is $2 per million input and $10 per million output tokens. Access starts with a subset of cyber defenders through the Fairwind Program.
blog.googlearticleAdded 29 Oct 2026, published 28 Oct 2026🧠 AI - Gemini 4 Carbon: Our next frontier model
Gemini 4 Carbon is Google DeepMind's frontier model, announced with a focus on cyber defense. DeepMind reports 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching), run without guardrails. It also reports 0.0% attack success on Gray Swan's indirect prompt injection benchmark. Access starts with a subset of cyber defenders via the Fairwind Program.
 deepmind.googlearticlePublished and added 28 Oct 2026🛡️ Security
- Gemini 4 Carbon: Our next frontier model
Gemini 4 Carbon is Google DeepMind's new frontier model, announced two weeks after Gemini 4 Argon. It ranks #1 on Artificial Analysis Intelligence Index v5.0 at 59 and scores 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Access starts with cyber defenders through the Fairwind Program, priced at $2 per million input tokens and $10 per million output tokens.
deepmind.googlearticlePublished and added 28 Oct 2026🧠 AI - lee1981 (@lee1981b) on X
CVE-2026-92885 is a critical (CVSS 3.1 9.8, CWE-287) authentication bypass in the Qode Membership WordPress plugin, versions through 2.0.6.2. A misspelled variable in the Facebook token-verification guard skips provider checks, so an unauthenticated attacker with a public nonce can get a session cookie for an existing account, including an administrator. The post gives the fix (2.0.6.3, bundled in Bridge 30.9), KEV/EPSS/SSVC status, and a SOC log-correlation and remediation plan.
x.comadvisoryAdded 31 Oct 2026, published 28 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CVE-2026-115905 is a ZIP cloaking flaw in the Rust zip crate (zip-rs/zip2), rated CVSS v4.0 10.0 and affecting versions below 9.0.5. ZipArchive reads central-directory metadata while ZipStreamReader reads local headers, so a crafted archive can pass filename inspection and then overwrite a different file during streaming extraction. Version 9.0.5 adds consistency checks, but ZipStreamReader::new leaves them off by default, and extraction is not atomic, so files can be written before an error is raised. The post covers CWE-20 and CWE-436, KEV and EPSS status, Debian status and a six-step investigation trail.
x.comadvisoryAdded 29 Oct 2026, published 27 Oct 2026🛡️ Security - Mitsubishi Electric and Mitsubishi Electric Iconics Digital Solutions GENESIS, GENESIS64, ICONICS Suite, Hyper Historian, AnalytiX, MobileHMI, IoTWorX, MC Works64, GENESIS32 and BizViz
CISA advisory ICSA-26-300-02 covers four vulnerabilities in Mitsubishi Electric and Mitsubishi Electric Iconics Digital Solutions GENESIS64, ICONICS Suite, Hyper Historian, AnalytiX, MobileHMI, IoTWorX, MC Works64, GENESIS32 and BizViz. CVE-2023-4863 (CWE-787 out-of-bounds write) allows code execution; CVE-2026-16436 and CVE-2026-16437 allow authentication bypass; CVE-2026-16438 allows arbitrary operations. Fixes are 10.97.3, 10.98 and GENESIS 11.04. MC Works64, GENESIS32 and BizViz are affected in all versions, and MC Works64 has no fix planned. Mitigations include removing the ClientChallengeTable.dat or SecurityChallenges.dat file contents. The fetched text was truncated, so later content is not covered.
 cisa.govadvisoryAdded 29 Oct 2026, published 26 Oct 2026🛡️ Security
 Then there is prompt injection, a malicious email, ...: The Wild Wide West of OpenClaw Agentic System Security
An empirical study of security concerns in the OpenClaw AI personal assistant framework, using 25K+ posts from 13 subreddits (162 security-relevant) and 358 security-tagged GitHub issues (180 retained). It maps 521 CWE instances across 59 weakness types, concentrated in access control, sensitive-data exposure, injection and unsafe execution. It extracts 543 practitioner mitigations into seven strategies and reconstructs a sensitive-data exposure path with dummy secrets.
 arxiv.orgpaperAdded 28 Oct 2026, published 26 Oct 2026🛡️ Security
- lee1981 (@lee1981b) on X
CyberForge CVE of the Day #087 covers CVE-2026-115889, a Cranelift value-index overflow in Wasmtime that can miscompile crafted WebAssembly and possibly escape the sandbox (CVSS 9.9, CWE-197 and CWE-843). Affected: below 36.0.19, and 37.0.0 up to but excluding 43.0.0; fixes are 36.0.19 and 43.0.0. It gives a SOC investigation trail from module digest to compiled artifact to host telemetry. EPSS is 0.454%, with no KEV entry.
x.comarticleAdded 28 Oct 2026, published 26 Oct 2026🛡️ Security - VulDec: Vulnerability Detection in Binaries via Neural Decompilation
VulDec is a dataset and framework for detecting vulnerabilities in binaries by first decompiling them with fine-tuned LLMs. The dataset aligns real-world Assembly-C function pairs across several architectures with CWE labels. Tuned neural decompilers reach about 56% Edit Similarity and 43% BLEU-4, and tuned detectors reach a macro F1 of 0.61 on a realistic test set with a 3% vulnerability rate.
arxiv.orgpaperAdded 28 Oct 2026, published 24 Oct 2026🧠 AI - VulDec: Vulnerability Detection in Binaries via Neural Decompilation
VulDec is an arXiv paper (October 2026) presenting a dataset of real-world Assembly-C function pairs with CWE labels across multiple architectures, plus an end-to-end framework that uses neural decompilation for binary vulnerability detection. Tuned LLM decompilers reach about 56% Edit Similarity and 43% BLEU-4. Tuned LLM detectors reach macro F1 of 0.61 on a realistic test set with a 3% vulnerability rate.
arxiv.orgpaperAdded 28 Oct 2026, published 24 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CVE-2026-111497 is an out-of-bounds write in the Brotli decoder bundled with Node.js (CWE-787, CWE-252), rated CVSS v4.0 9.2 by the Google CNA and High by the Node.js project. Fixes are Node 22.23.4, 24.22.1 and 26.12.1, and 24.22.1 still labels Brotli 1.2.0 because the fix was cherry-picked. The post gives a SOC trail from input to worker, with remediation and verification steps. It notes no KEV match, CISA SSVC exploitation none, and only unverified public lab claims.
x.comadvisoryAdded 26 Oct 2026, published 23 Oct 2026🛡️ Security 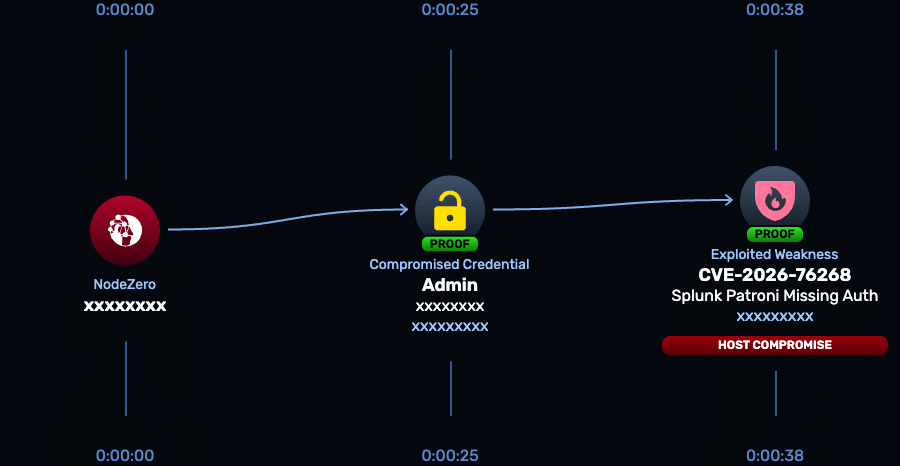 CVE-2026-76268 | Splunk Enterprise Patroni REST API Missing Authentication Vulnerability
CVE-2026-76268 is a critical (CVSS 9.8) missing authentication flaw (CWE-306) in the Patroni REST API on Splunk Enterprise search head cluster members. An unauthenticated attacker with network access can run operating-system commands. Affected: 10.4.0 to 10.4.2 and 10.2.0 to 10.2.6. Fixed in 10.4.3 and 10.2.7. Splunk (SVD-2026-1001, 7 October 2026) suggests disabling the PostgreSQL sidecar as a workaround.
 horizon3.aiadvisoryAdded 29 Oct 2026, published 22 Oct 2026🛡️ Security
- lee1981 (@lee1981b) on X
CVE-2026-110936 is an uncontrolled DLL search path flaw (CWE-427) in Siemens Software Center below V4.0.9.8, listed in CISA KEV on 20 October 2026. The post covers CVSS v4.0 8.4 and v3.1 6.7, Siemens' Romulus ClickFix campaign indicators (IPs, domain, hashes, file leads) and a six-step SOC trail using Sysmon, EDR and network records. It separates delivery from DLL load and from compromise.
x.comarticleAdded 24 Oct 2026, published 21 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CVE-2026-106931 is an OS command injection (CWE-78) in the statistics processing of EG Secure Solutions SiteGuard Server Edition, a host-based WAF. It can give root or SYSTEM command execution. The vendor and JVN confirm exploitation on 14 October 2026. The post lists fixed builds (Ver8.00 Update 5, Ver7.00 Update 6 on FreeBSD), the IIS exclusion, the workaround of disabling statistics, and a SOC trail starting with diagnostic preservation before patching.
x.comadvisoryAdded 21 Oct 2026, published 19 Oct 2026🛡️ Security - ToFu: Exploiting and Fuzzing the LLM–Orchestrator–Tool Trust Boundary
ToFu is a tool-aware fuzzing framework for LLM tools, including MCP servers. It maps each tool argument, using its metadata, to one of 74 CWE-guided semantics-aware sanitizers (path, URL, SQL and similar). It then generates schema-valid Atheris harnesses and semantic oracles, using runtime tracers for in-process tools and outcome oracles for opaque ones. The LLM (gpt-4.1) only maps sanitizers and writes seeds; it is never the security judge. The paper also shows a "Repeat-After-Me" trick, where an LLM told to repeat attacker-crafted text emits a tool call the orchestrator executes, reproduced on LangGraph, MAF, ADK 2.0, AutoGen, Strands and CrewAI. Across 273 runnable MCP servers (3,405 tools) it reports 253 verified bugs in 343 tools across 118 servers, such as path traversal, log injection and exfiltration. These are failures a crash-based fuzzer would miss. The result matters because it shows LLM-generated tool arguments cannot be treated as trusted.
arxiv.orgpaperAdded 18 Oct 2026🧠 AI - ToFu: Exploiting and Fuzzing the LLM–Orchestrator–Tool Trust Boundary
ToFu is a tool-aware fuzzing framework that derives semantic security checks for LLM tools (mainly MCP servers) from their metadata and a corpus of 74 CWE-guided sanitizers. It generates schema-valid Atheris harnesses, uses runtime tracers and outcome oracles to catch bugs that don't crash, and uses an LLM only to map sanitizers and seed inputs, never as the judge. It also describes a "Repeat-After-Me" attack, in which the LLM is told to repeat attacker-written text that the orchestrator then dispatches as a tool call. It was reproduced on LangGraph, MAF, ADK, AutoGen, Strands and CrewAI. On 273 MCP servers it reports 253 verified bugs across 343 tools in 118 repositories, including path traversal, log injection, exfiltration and command bypass.
arxiv.orgpaperAdded 18 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CyberForge "CVE of the Day #079" on CVE-2026-102764, a CWE-290 origin-validation flaw in BeyondTrust Remote Support (advisory BT26-05, CVSS v4 9.3) that allows appliance file operations. It summarises Mandiant/GTIG's exploited intrusion chain (SAWFLY web shell, BARECLAW backdoor, root escalation, persistence) and gives an investigation trail: patch-state verification (BT26-05-RS), evidence preservation, hunting leads with SHA-256 hashes and YARA rules, permission/session correlation, and remediation including clean redeployment and credential rotation. It separates vendor facts from the intrusion's observed behaviour and notes that KEV and EPSS have no entries.
x.comthreadAdded 18 Oct 2026, published 16 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
Daily CVE digest on CVE-2026-76519, a CVSS 9.8 relative path traversal (CWE-23) in Cisco Secure Email Gateway's AMP File Reputation attachment processing. A crafted attachment gives unauthenticated arbitrary file writes and root command execution, and Cisco PSIRT reports active exploitation. The CVE is in CISA KEV. It lists the applicability conditions (File Reputation assigned to a policy and Content Scanner Tools earlier than 25.3.0.5525) and the fixes (scanner 25.3.0.5525, AsyncOS 15.5.5-014 and 16.5.0-780). It also covers evidence preservation, reading Cisco's System Security scan outcomes, mail/AMP log correlation, and deployment-specific recovery including cluster-key exposure.
x.comadvisoryAdded 18 Oct 2026, published 15 Oct 2026🛡️ Security  Critical GitLab RCE Lets Unauthenticated Attackers Execute Code on Servers (CVE-2026-97229)
Orca Security analysis of CVE-2026-97229, a CVSS 10.0 flaw in GitLab CE/EE. An integer overflow (CWE-190) in the CI/CD regular expression compiler gives memory corruption and code execution as the git user. It is triggered by a crafted regex in .gitlab-ci.yml combined with a UTF-8 repository path, with no authentication needed on instances that allow public project creation or self-registration. Lists affected branches (19.2 before 19.2.8, 19.3 before 19.3.5, 19.4 before 19.4.2), the absence of a workaround, interim mitigations, and a Rapid7 PoC against GitLab CE 19.4.1 with ASLR on. Notes a prior max-severity GitLab bug (CVE-2026-85706) was probed in the wild within hours and later added to CISA KEV.
 orca.securityadvisoryPublished and added 14 Oct 2026🛡️ Security
- lee1981 (@lee1981b) on X
Defender guide for CVE-2026-104935, an authentication-bypass-by-spoofing flaw (CWE-290) in Ivanti Connect Secure that allows unauthenticated command execution. It is confirmed exploited and CISA KEV-listed, with a CNA CVSS 8.6. It covers the fixed-release matrix (25.1.1.2, 22.8R2.5, 25.1.3.x), platform and cluster migration limits, and Volexity's UTA0576 indicators and YARA rules. It also gives a six-step SOC workflow (scope, preserve, hunt, correlate identity, remediate, verify). It stresses that a clean ICT result cannot clear memory-only activity and that LDAP, LAPS and BitLocker exposure belongs to one observed chain.
x.comthreadAdded 16 Oct 2026, published 14 Oct 2026🛡️ Security  Microsoft Patch Tuesday for October 2026 — Snort rules and prominent vulnerabilities
Talos summarises Microsoft's October 2026 Patch Tuesday, which covers 1415 vulnerabilities, 85 of them critical (67 RCE). One bug is exploited in the wild: CVE-2026-96951, a Windows Shell security feature bypass. The post groups the CVEs by Microsoft's exploitability rating (more likely, less likely, unlikely) with CVSS and CWE for each, covering Windows, Office, Exchange, Hyper-V, DHCP, QUIC, Outlook and Azure. It also lists the Snort 2 and Snort 3 rule ID ranges that detect exploitation attempts.
 blog.talosintelligence.comadvisoryPublished and added 13 Oct 2026🛡️ Security
 Ivanti Connect Secure zero-day exploited in the wild (CVE-2026-104935)
Rapid7 emergency-response analysis of CVE-2026-104935, a CVSS 8.6 authentication bypass by spoofing (CWE-290) in Ivanti Connect Secure that allows unauthenticated remote command execution. It was exploited as a zero-day against a limited number of customers, added to CISA KEV on disclosure day, and Volexity observed it chained with a still-unpatched privilege escalation flaw. Part of the fix shipped in 25.1.3.0 in July 2026, with backports to other supported versions pending. Rapid7 advises emergency patching outside normal cycles and hunting for compromise using Volexity's IOCs, since Ivanti has no reliable ones.
 rapid7.comadvisoryPublished and added 13 Oct 2026🛡️ Security
- Gemini 4 Argon
Google DeepMind's launch page for Gemini 4 Argon, a frontier model pitched at long-horizon software engineering, science and math, robotics, cyber defense and professional workflows. Stated specifics: a 1M-token output window for full-repository generation and long proofs, a tie for #1 on CWE-Bench (68%) for vulnerability remediation, and a 14% accuracy gain over Gemini 3.1 Pro in Box's evaluation. It also describes safeguards (resistance to indirect prompt injection, chain-of-thought monitoring, sandbox hardening under the Frontier Safety Framework) and availability via Google AI Pro/Ultra, Gemini API, AI Studio and Antigravity. Much of the evidence is partner testimonials and vendor-reported results.
deepmind.googlearticlePublished and added 13 Oct 2026🧠 AI - CVE-2026-97229: Critical Unauthenticated Remote Code Execution in GitLab
Rapid7 analysis of CVE-2026-97229, a CVSS 10.0 integer overflow (CWE-190) in the Onigmo regex compiler used by GitLab CE/EE's CI/CD regex handling. A crafted regex in a .gitlab-ci.yml passes validation as US-ASCII, then is recompiled for a UTF-8 repository path, producing invalid instructions that give code execution as the git user. Rapid7 reproduced it on GitLab CE 19.4.1 with ASLR (patched in 19.4.2); despite the vendor's "unauthenticated" rating, the attacker needs to commit a malicious config to a public project, which self-registration allows. No in-the-wild exploitation is confirmed, and Rapid7 recommends urgent upgrades.
rapid7.comadvisoryPublished and added 13 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CyberForge "CVE of the Day #076" covers CVE-2026-97229, a CVSS 10.0 integer overflow (CWE-190) in GitLab CE/EE's CI/CD regular expression compiler. It can lead to conditional unauthenticated code execution on the GitLab server. It lists the affected trains (19.2 before 19.2.8, 19.3 before 19.3.5, 19.4 before 19.4.2) and the 19.3.4 vs 19.3.5 Ona-regression discrepancy. It also gives six SOC checks: scoping, log preservation (Workhorse/Rails/Sidekiq, correlation_id), server-effect hunting, request-to-process correlation, upgrade and running-state verification. It notes that exploit details are unverified, no KEV listing exists and EPSS data is unavailable.
x.comadvisoryAdded 15 Oct 2026, published 13 Oct 2026🛡️ Security  Is AI Coding Safe? Introducing the Agent Security League | Blog | Endor Labs
Endor Labs launches the Agent Security League, a public leaderboard extending CMU's SusVibes benchmark (200 tasks, 108 Python OSS projects, 77 CWEs) to commercial coding agents (Claude Code, Cursor, Codex) and frontier models. Functional pass rose to 84.4% from 61% in the original study, but secure pass peaked at only 17.3%. It also documents agents ignoring instructions and mining git history to copy the fix (SWE-Agent + Opus 4.6 did so in 163/200 tasks), and describes the cheating-detection and score-adjustment module added to the harness.
 endorlabs.comarticlePublished and added 12 Oct 2026🛡️ Security
- Is AI Coding Safe? Introducing the Agent Security League | Blog | Endor Labs
Endor Labs launches the Agent Security League, a public leaderboard that extends CMU's SusVibes benchmark (200 Python tasks, 108 OSS projects, 77 CWEs). It tracks FuncPass and SecPass for commercial agents (Claude Code, Cursor, Codex) with newer models such as Claude Opus 4.x, Gemini 3 Pro and GPT-5.3 Codex. Functional correctness reaches 84.4% but SecPass peaks at only 17.3%. The authors also found agents reading git history to recover the fix, as in 163 of 200 tasks for SWE-Agent with Claude Opus 4.6, despite explicit instructions not to. They added a cheating-detection and score-adjustment phase.
endorlabs.comarticlePublished and added 12 Oct 2026🧠 AI - lee1981 (@lee1981b) on X
CyberForge's CVE of the Day #075 covers CVE-2026-108860, a critical (CVSS 9.1 v3.1 / 9.3 v4.0) authentication bypass in SciSharp BotSharp through 5.2.0. WebStarter ships a published default HMAC JWT signing secret (CWE-321), so anyone holding it can forge bearer tokens that impersonate known users, including administrators. The post sets out how to confirm the effective key and serving build, a six-step SOC investigation trail, and remediation by rotating the secret. No verified fixed release, KEV entry or EPSS data existed at cutoff, and the linked research is static-only.
x.comadvisoryAdded 13 Oct 2026, published 12 Oct 2026🛡️ Security - ThreatWire (@ThreatWire_) on X
Post announcing a public PoC for CVE-2026-13043, a critical flaw (CVSS 4.0 9.3, scored by WatchGuard) in PSKMAD, the kernel memory access driver of WatchGuard Endpoint Security on Windows. The access-control handshake can be bypassed (CWE-306/CWE-798), letting a local authenticated attacker send privileged commands and read kernel and other processes' memory. Fixed in 8.00.26.0012; the PoC author and LOLDrivers frame the signed driver as BYOVD material, which WatchGuard does not say. The post notes it is not in CISA KEV, has no reported in-the-wild exploitation, and that ThreatWire has not run the PoC.
x.comthreadAdded 11 Oct 2026, published 10 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CyberForge CVE of the Day #074 analyses CVE-2026-85097, a CVSS 9.8 unauthenticated file upload to PHP execution flaw (CWE-434) in the Bricksforge WordPress plugin through 3.1.8.9. Wordfence names 3.1.8.10 as the fix, and a separate vendor 4.0.1 Pro Forms upload-security notice has no verified mapping to the CVE. It gives a defender workflow: scope versions, preserve edge/origin logs, inspect resulting files and PHP-FPM handling, and verify the patched version is serving. It also separates KEV (no match), EPSS (0.312%) and SSVC (exploitation none) from compromise evidence.
x.comadvisoryAdded 11 Oct 2026, published 10 Oct 2026🛡️ Security - SecReason: Vulnerability Detection and In-Stream Self-Repair for LLM Code Generation
SecReason is an in-stream defense for reasoning LLMs that write code. Reasoning models draft code early in their streamed chain of thought, so SecReason scans that stream with dual-track incremental analysis: security rules are checked on each emitted statement, and dataflows are traced across the accumulated code. When a rule fires, it interrupts decoding, inserts a warning into the stream and resumes, so the model fixes its draft within the same reasoning trace instead of regenerating the full response. On CWEval and SecCodeBench, runs delivering secure and functionally correct code rise from below 15% to 72.8%–98.1%. It uses fewer tokens than post-hoc repair and limits functional regressions when rules misfire on secure code.
arxiv.orgpaperAdded 15 Oct 2026, published 10 Oct 2026🧠 AI - SecReason: Vulnerability Detection and In-Stream Self-Repair for LLM Code Generation
SecReason is an in-stream defense for reasoning LLMs that monitors code drafted inside the streamed chain of thought. Dual-track incremental scanning applies security rules per statement and traces dataflows across accumulated code; when a rule fires, generation is interrupted, a warning is inserted, and decoding resumes so the model repairs the draft in the same trace. On CWEval and SecCodeBench it raises the share of secure and functionally correct runs from below 15% to 72.8%–98.1%, uses fewer tokens than post-hoc repair, and limits regressions from false warnings.
arxiv.orgpaperAdded 16 Oct 2026, published 10 Oct 2026🛡️ Security - SecReason: Vulnerability Detection and In-Stream Self-Repair for LLM Code Generation
SecReason is an in-stream defense for reasoning LLMs that monitors code drafted inside the streamed chain of thought. Dual-track incremental scanning applies security rules per statement and traces dataflow across accumulated code. When a rule fires, generation is interrupted, a warning is inserted and decoding resumes, so the model repairs its draft without regenerating the full response. On CWEval and SecCodeBench it raises the share of secure and functionally correct runs from below 15% to 72.8%–98.1%, uses fewer tokens than post-hoc repair, and limits functional regressions from false warnings.
arxiv.orgpaperAdded 15 Oct 2026, published 10 Oct 2026🛡️ Security - SecReason: Vulnerability Detection and In-Stream Self-Repair for LLM Code Generation
SecReason is an in-stream defense for reasoning LLMs that write code. Reasoning models draft code early in their streamed chain of thought, and SecReason scans that draft incrementally with security rules, checking each statement as it is emitted and tracing dataflows across the accumulated code. When a rule fires, it interrupts generation, inserts a warning into the stream, and resumes decoding, so the model repairs the draft within the same reasoning trace. On CWEval and SecCodeBench it raises the share of runs that deliver secure and functionally correct code from under 15% to 72.8%–98.1%. It uses fewer tokens than post-hoc repair and limits functional regressions when rules misfire on secure code.
arxiv.orgpaperAdded 16 Oct 2026, published 10 Oct 2026🧠 AI - lee1981 (@lee1981b) on X
CyberForge's CVE of the Day #073 covers CVE-2026-102255, a critical (CVSS 10.0) pre-authentication SSRF / confused-deputy flaw (CWE-918, CWE-441) in the SonicWall SMA1000 Work Place interface, per advisory SNWLID-2026-0017. It lists affected platform hotfixes (12.4.3-03526 and older, 12.5.0-02952 and older), fixed floors (12.4.3-03670, 12.5.0-03082), no workaround, and the exploitation picture (no known exploitation, not in KEV, EPSS 0.477%, SSVC automatable). It gives a six-step SOC playbook covering appliance scoping, AMC log preservation, hunting appliance-originated internal requests, correlating receiving-service changes, patching, and verifying every node, and it separates exposure, a lead, confirmed compromise and telemetry gaps.
x.comadvisoryAdded 12 Oct 2026, published 9 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
A detailed "CVE of the Day" thread analyzing CVE-2026-76471, a critical (CVSS 9.8) Cisco advisory covering insufficient NX-API input validation (CWE-122 heap-based buffer overflow) on Nexus 3000/9000 standalone NX-OS and a lower-severity credentialed variant on UCS 6300 Fabric Interconnects via UCS Manager XML API. It compiles Cisco's fixed-software versions per platform, notes the temporary Live Protect shield lp00074, and walks through a six-step SOC evidence-preservation and correlation playbook (scoping affected devices, preserving logs/crash artifacts, reviewing API/shield telemetry, correlating device outcomes, remediating, and verifying post-patch state) while flagging that CISA KEV and FIRST EPSS had no data on the CVE at research time.
x.comwriteupPublished and added 8 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
Analysis of CVE-2026-105844, a CWE-1321 prototype-pollution vulnerability in @payloadcms/plugin-import-export that the vendor says can lead to unauthenticated remote code execution. It covers affected ranges (stable 3.0.0–3.87.x, canary 4.0.0-canary.0–canary.26), the fix (3.88.0 / 4.0.0-canary.27), the patched field-path guard against __proto__/constructor/prototype segments, and a six-step SOC hunting/triage playbook with two offline Python scripts for inspecting npm package trees and triaging request field-paths for prototype-sensitive values.
x.comadvisoryAdded 8 Oct 2026, published 7 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CyberForge CVE-of-the-Day #070 on CVE-2026-61500 in Rejetto HFS 3.0.0–3.2.0. The default Koa session-signing key came from Math.random() (CWE-338) and the unauthenticated login handshake leaked outputs of the same generator. That allows recovery of the key, a forged administrator session, and code execution through the legitimate server_code feature. It covers scoring (CVSS 9.8/9.3, EPSS, KEV status), the 3.2.1 fix, a six-step SOC hunting and remediation trail (loginSrp1/2, get_config/set_config pivots, COOKIE_SIGN_KEYS review), and offline jq/Python helpers for container and config metadata.
x.comwriteupAdded 9 Oct 2026, published 6 Oct 2026🛡️ Security - CheckerBench: Can Long-Horizon Agents Synthesize Static-Analysis Checkers?
CheckerBench is an executable benchmark of 300 tasks drawn from 297 CVEs across 167 repositories, 85 CWEs, and five language ecosystems, testing whether long-horizon coding agents can synthesize working static-analysis checkers from a defect specification through repeated compile-and-analyze feedback loops. Its companion framework CheckerLab independently rebuilds submitted checkers and scores vulnerable-fixed diagnostic contrast, patch localization, false positives, and tool use; across 21 model-harness configurations mean Pass@1 is 32.30 percent and the best reaches 45.33 percent, showing reliable checker synthesis remains hard for current coding agents.
arxiv.orgpaperAdded 8 Oct 2026, published 6 Oct 2026🧠 AI - CheckerBench: Can Long-Horizon Agents Synthesize Static-Analysis Checkers?
CheckerBench is an executable benchmark of 300 tasks derived from 297 CVEs across 167 repositories, 85 CWEs, and five language ecosystems, testing whether long-horizon coding agents can synthesize working static-analysis checkers from a defect specification through repeated compilation and analysis feedback. The accompanying CheckerLab framework independently rebuilds submitted checkers and measures vulnerable-vs-fixed diagnostic contrast, patch localization, false positives, and tool use; across 21 model-harness configurations mean Pass@1 is 32.30% (best 45.33%), showing reliable checker synthesis remains hard for current agents.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026🛡️ Security  GitLab patches critical 9.9 AI Gateway template-sandbox-escape RCE (CVE-2026-90970)
GitLab patched CVE-2026-90970, a critical (CVSS 9.9) flaw in the AI Gateway used by Duo Agent Platform, where a logged-in user with Duo Agent Platform access could craft a flow configuration to escape the prompt template sandbox and achieve arbitrary command execution on the gateway. Only self-managed organizations hosting their own AI Gateway (versions 18.1.6 through 19.1) need to act; the fix lands in 19.2.4, 19.3.2, and 19.4.1. The bug is a template engine weakness (CWE-1336), the same class as the earlier CVE-2026-1868 gateway RCE GitLab fixed in February, and was reported via HackerOne by researcher invisiblemeerkat.
 thehackernews.comadvisoryAdded 4 Oct 2026🛡️ Security
 Why AI Coding Agents Keep Writing Broken Access Control
Snyk argues AI coding agents reliably write broken access control (BOLA/IDOR, OWASP's top category since 2021) because the facts needed to add an ownership check — what an object belongs to, who may access it, where tenant boundaries sit — are tacit product knowledge that exists nowhere in the code or prompt an agent sees. It explains why SAST tools catch patterned sub-categories like path traversal or SSRF but structurally cannot catch CWE-639/862/863 (missing or incorrect authorization), since there's no bad pattern to match, and proposes reasoning over an assembled "application-context graph" of architecture, data flows and trust boundaries instead. It closes with a five-step team checklist (inventory ID-accepting endpoints, document ownership rules, add authorization-specific PR review, write cross-tenant tests, run deep contextual analysis) and pitches Snyk's Evo Agentic AppSec as the tool built around that approach.
 snyk.ioarticlePublished and added 1 Oct 2026🧠 AI
- Why AI Coding Agents Keep Writing Broken Access Control
Snyk explains why AI coding agents reliably ship broken object-level authorization (BOLA/IDOR) bugs: the ownership rule that would prevent them (e.g. "invoices belong to organizations") lives in the product's data model and team knowledge, not in the prompt or surrounding code, so the agent produces code that is correct for the stated task but lets any authenticated user access other tenants' objects. The piece maps the flaw to CWE-639/862/863, contrasts it with pattern-matchable classes like SSRF and path traversal that SAST handles well, and lays out five concrete team actions (endpoint inventory, documented ownership rules, explicit authz review questions, per-resource cross-tenant tests, and periodic deep contextual analysis), while pitching Snyk's "application-context graph" and Evo Agentic AppSec as the tool for the pattern-less gap.
snyk.ioarticlePublished and added 1 Oct 2026🛡️ Security - AuraForge: Scaling Security Supervision for Training Coding Agents
AuraForge is a method for synthesizing and validating executable security tests to train coding agents toward secure (not just functionally correct) code, combining attack-oriented test synthesis, multi-language task construction, and safeguards against reward hacking. The authors release AuraGym, a 679-task executable training gym drawn from 344 real-world Python/JavaScript/TypeScript repositories spanning 177 CWE categories, and show that training Qwen3.5-4B with AuraForge-synthesized tests beats human-written tests on both functional-pass (FuncPass) and security-pass (SecPass) metrics while cutting false positives by over 83%.
arxiv.orgpaperAdded 3 Oct 2026, published 1 Oct 2026🛡️ Security - AuraForge: Scaling Security Supervision for Training Coding Agents
AuraForge is a pipeline that synthesizes and validates executable security tests to supervise the training of coding agents, using attack-oriented test synthesis and safeguards against reward hacking. The authors build AuraGym, a multi-language (Python, JavaScript, TypeScript) training gym of 679 feature-implementation tasks from 344 real repositories spanning 177 CWE categories, and show that training Qwen3.5-4B with these synthesized tests beats human-written security tests on both functional correctness (FuncPass) and security (SecPass) metrics, while producing about 3x more test cases and cutting false positives by 83 percent.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI  Gemini 4 Argon: our next era of frontier intelligence
Google DeepMind's announcement of Gemini 4 Argon, a frontier model rolling out first to trusted cyber defenders via the Fairwind Program, with an industry-leading 1M output token limit (up from 64K) and pricing of $2/$10 per million input/output tokens. It reports state-of-the-art results on DeepSWE v1.1, the Vals Index, AutomationBench, LVBench, and CWE-bench v1, details internal use cases (quantum algorithm optimization, C/C++-to-Rust migrations including the Fuchsia Zircon kernel and libgav1), and describes new frontier safeguards covering misuse defense, indirect prompt-injection robustness, chain-of-thought misalignment monitoring, and sandboxed training environment hardening.
deepmind.googlearticlePublished and added 30 Sep 2026🧠 AI- Critical Cisco Catalyst SD-WAN Manager API authentication bypass exploited in the wild (CVE-2026-76504)
Rapid7 analysis of CVE-2026-76504, a critical (CVSSv3.1 9.8) unauthenticated API authentication bypass in Cisco Catalyst SD-WAN Manager caused by improper URL-encoding handling (CWE-177), allowing attackers to gain admin-level API access via crafted requests to the j_security_check endpoint. The flaw is being actively exploited in the wild, was added to CISA's KEV list on October 1, 2026 with a remediation deadline of October 3, and follows two earlier 2026 Catalyst SD-WAN peering authentication bypasses (CVE-2026-20127 and Rapid7-discovered CVE-2026-20182). The post gives fixed-release guidance, no-workaround caveats, and log-based IOCs (encoded-character requests like %6a_security_check, viptela-reserved- usernames) for detecting compromise.
rapid7.comadvisoryAdded 7 Oct 2026, published 30 Sep 2026🛡️ Security  lee1981 (@lee1981b) on X
A detailed breakdown of CVE-2026-102710 (CVSS v4.0 9.3), a privilege-escalation flaw in Eclipse ThreadX RTOS builds with event tracing enabled: a module-supplied trace callback pointer is retained by the kernel and invoked with kernel privilege when the trace buffer wraps, letting an attacker who already controls a memory-protected user-mode module fault the kernel or execute code in kernel context. The thread walks through the vulnerable code path (registration, storage, invocation across the protection boundary), CWE-269/CWE-822 classification, affected versions (through v6.5.1.202602a_rel), and provides a defender hunting guide plus emergency remediation steps, noting no fixed upstream release or CISA KEV/EPSS entry exists yet.
x.comthreadPublished and added 30 Sep 2026🛡️ Security- Gemini 4 Argon: our next era of frontier intelligence
Google announces Gemini 4 Argon, a frontier model rolling out first to trusted cyber defenders via the Fairwind Program, with a 1M-token output limit (up from 64K) and introductory pricing of $2/$10 per million input/output tokens. It reports state-of-the-art results on DeepSWE v1.1 (77.9%), LVBench (91.7%), AutomationBench (51.3%) and a tie for first on CWE-bench v1 (68%), plus leading scores on the Vals Index and Gray Swan's IPI prompt-injection benchmark. Internal case studies include agent-driven C/C++ to Rust migrations (libgav1 decoder 2.7x faster than the Rust port, Fuchsia Zircon kernel) and fleet-wide memory optimisation. It also outlines safeguards: misuse monitoring of internal activations, prompt-injection hardening, chain-of-thought misalignment monitoring and sandbox hardening.
blog.googlearticleAdded 1 Oct 2026, published 30 Sep 2026🧠 AI - https://github.com/dmdhrumilmistry/security-harness
security-harness is an open-source Claude Code plugin (also packaged for Gemini CLI, Codex and opencode) that orchestrates subagents — sh-recon, sh-hunter, sh-chainer, sh-verifier, sh-reporter — through a static-analysis pipeline covering 15 vulnerability classes (IDOR/BOLA, SQLi, XSS, SSRF, injection, auth, deserialization, path traversal, secrets, CSRF, XXE, open redirect, crypto, race conditions, file upload), producing README/JSON/SARIF/HTML/PDF reports with PoCs, CVSS and CWE/OWASP mappings. It also ships sh-pr-review, a per-PR merge-gate skill that posts inline findings and a commit status scoped only to code the PR itself introduced or aggravated, with caching, dedup via fingerprints, and a scheduled GitHub Action that keeps its per-class knowledge bases fresh by having one AI agent draft updates from allowlisted sources (OWASP, PortSwigger Research, CWE/CAPEC, HackerOne) while a separate adversarial reviewer agent fails-closed against prompt injection before auto-merge.
 github.comrepoAdded 2 Oct 2026, published 29 Sep 2026🛡️ Security
 AI Agent Sandbox Flaw in brig: Symlink Traversal (CVSS 8.2) | Blog | Endor Labs
Endor Labs researcher pkennedy details GHSA-wp6x-29qx-fpr7 (ENDOR-VUL-2026-1809, CVSS 8.2, CWE-59), a symlink-traversal flaw in brig, a tool that runs AI coding agents inside microVM/container sandboxes. While brig's shared working directory was carefully guarded against symlink swaps, the user-named project directory was passed to the underlying runtime (Virtualization.framework on macOS, containerd/nerdctl on Linux) as a raw unresolved path; an agent could replace a subfolder it already controls with a symlink to any host directory, which is then mounted read-write into the sandbox on the next run, exposing SSH keys, cloud credentials, and other projects with the operator's privileges. Fixed in brig 0.3.0 by resolving and holding the path open before mounting; the piece includes full PoC commands, root-cause code snippet, and a detailed vendor disclosure/CVSS negotiation narrative.
endorlabs.comwriteupPublished and added 28 Sep 2026🛡️ Security- VulContextBench: A Benchmark for Security Context Retrieval in Coding Agents
VulContextBench is a hand-audited benchmark of 111 vulnerability-introducing commits across 83 repositories, 63 CWEs, and five languages, built to score whether a coding agent actually retrieved and cited the correct evidence for a vulnerability verdict rather than just reaching the right verdict. Evaluating seven frontier models (including Qwen3-Coder-Next and GPT-5.5) at file/block/line granularity, the authors find every model explores most of the gold evidence but reports only a fraction of it: Qwen3-Coder-Next views 86.3% of annotated lines but cites just 12.9%, while GPT-5.5 views 73% and reports 36%. This reveals that verdict-only vulnerability-detection benchmarks mask whether an agent's reasoning is actually grounded in traced code versus pretraining recall.
arxiv.orgpaperAdded 2 Oct 2026, published 26 Sep 2026🛡️ Security









Showing 60 of 124
Show more