 The Rise of LLMJacking: How Threat Actors Monetize Compromised Cloud and Model Resources
LLMJacking is the hijacking of enterprise cloud LLM access, which Mandiant and GTIG saw in multiple 2026 incidents with charges above $100,000 a day and up to $1 million per victim. The report covers initial access through stolen cloud tokens and API keys, persistence, LiteLLM privilege escalation (CVE-2026-40217), and resale through "LLM Mixers" such as Jet Night and newapi[.]pro. It gives CloudTrail, Azure and GCP audit-log hunting guidance and hardening steps.
 cloud.google.comarticlePublished and added 2 Nov 2026🛡️ Security
 Backporting security fixes at scale with Codex
Trail of Bits describes a Codex (GPT-5.6) workflow that backports security fixes to stable Linux kernel trees, Ubuntu LTS and Fedora. By 29 October 2026 it had helped land fixes for 149 CVEs in stable kernels. Agents find missing fixes, adapt patches and assemble validation evidence; a human review takes about 30 minutes to 3 hours. It also sizes the unfixed-CVE backlog in kernel branches, Debian 13 and Ubuntu 26.04.
 blog.trailofbits.comarticlePublished and added 2 Nov 2026🛡️ Security
- Backporting security fixes at scale with Codex
Trail of Bits describes a Codex agent workflow that backports security fixes to stable Linux kernel trees and distro packages. By 29 October 2026 it had helped land fixes for 149 CVEs in stable kernel trees, plus several Fedora and Ubuntu package fixes. Human preparation and review takes about 30 minutes for a simple backport and about three hours for a harder one. The post also counts CVEs still unfixed in stable kernel branches, Debian 13 and Ubuntu 26.04.
blog.trailofbits.comarticlePublished and added 2 Nov 2026🧠 AI  Top AI coding agent security resources — November 2026
Adversa AI's November 2026 roundup of 14 AI coding agent security resources from October. It covers CVE-2026-103572 (Visual Studio Copilot and SSMS RCE via trailing-dot filename), an unpatched Claude Code child-session hook bypass, a Copilot CLI cryptographic context injection, and a CVE-less opencode MCP OAuth RCE. It ends with a checklist for auditing agent configs and gateways.
 adversa.aiarticlePublished and added 2 Nov 2026🛡️ Security
 How to Run an AI Model Locally—And Why You Might Want To
Decrypt guide to running open-weight AI models locally with Ollama and LM Studio. It cites Epoch AI's finding that open models trail the best closed ones by about four months, and sets out VRAM and unified-memory needs (8GB minimum, 24GB for serious use), quantization, licences (MIT, Apache 2.0), install commands and Gemma 4 download sizes. It also notes that the largest open models, such as Qwen3.8-Max, exceed consumer hardware.
 decrypt.coarticlePublished and added 1 Nov 2026🧠 AI
 FBI Attributes $6 Billion-Plus Binance Hack to North Korea
The Defiant reports that the FBI attributed a Binance hack of more than $6 billion to North Korea and named TraderTraitor as the actor. The bureau also sought blocks on the laundering trail, and Binance kept 1 November as its target for restarting withdrawals. The article body did not load, so technical details of the intrusion are not available.
 thedefiant.ioarticlePublished and added 31 Oct 2026🛡️ Security
 Backporting security fixes to stable releases
Trail of Bits argues that stable and LTS software, such as Ubuntu 26.04 LTS, Debian 13 and stable Linux kernel branches, carries many known CVEs that were fixed upstream but never backported. It measures the gap using the kernel CVE team's vulns.git (18 September 2026) and Debian and Ubuntu CVE feeds. Using Codex with GPT-5.6, the team got 142 fixes covering 90 CVEs applied to stable kernel trees and has begun sending patches to distributions.
blog.trailofbits.comarticlePublished and added 27 Oct 2026🛡️ Security- lee1981 (@lee1981b) on X
CyberForge CVE of the Day #087 covers CVE-2026-115889, a Cranelift value-index overflow in Wasmtime that can miscompile crafted WebAssembly and possibly escape the sandbox (CVSS 9.9, CWE-197 and CWE-843). Affected: below 36.0.19, and 37.0.0 up to but excluding 43.0.0; fixes are 36.0.19 and 43.0.0. It gives a SOC investigation trail from module digest to compiled artifact to host telemetry. EPSS is 0.454%, with no KEV entry.
 x.comarticleAdded 28 Oct 2026, published 26 Oct 2026🛡️ Security
 [tl;dr sec] #351 - PHP2Shell, Autopatching Skills, AWS Pathrunner
tl;dr sec #351 is a weekly security newsletter. Clint Gibler describes working with OpenAI, Calif, Wiz and the PHP maintainers on the PHP2Shell unauthenticated RCE disclosure, which affects 13 years of PHP. It also covers Datadog's pathrunner AWS IAM escalation framework, Trail of Bits' patching-bugs and regression-hunt Codex plugins, XBOW finding de-duplication, backdoored open-weight models, and CREBench.
 tldrsec.comarticleAdded 30 Oct 2026, published 22 Oct 2026🛡️ Security
- Trail of Bits (@trailofbits) on X
Trail of Bits announces two open-source plugins, patching-bugs and regression-hunt, for AI coding agents that speed up bug patching. They come from four months of Patch the Planet work with open-source projects, which found that repo-level documentation, skills and plugins give agents the maintainer context on what counts as a bug, how a fix should look and what must not break. The post cites the October 2026 PHP incident: a patch touching 402 files, and exploitation within 17 hours of leaked details.
x.comarticleAdded 23 Oct 2026, published 21 Oct 2026🧠 AI  Your AI agent fixed the bug, but what else did it change?
Trail of Bits releases patching-bugs and regression-hunt, two agent plugins built with OpenAI through Patch the Planet. patching-bugs reproduces bugs, writes fixes and runs a three-arm proof; regression-hunt traces diffs to real interfaces, confirms with live PoCs and a fresh-context replay. A review of 130+ merged PRs found 21 regressions, and regression-hunt gave 25% fewer false positives than a baseline Codex prompt.
blog.trailofbits.comarticlePublished and added 21 Oct 2026🧠 AI- Your AI agent fixed the bug, but what else did it change?
Trail of Bits releases patching-bugs and regression-hunt, two Codex plugins from the Patch the Planet initiative with OpenAI. A review of 130+ merged patches confirmed 21 regressions (none broke a security protection). In preliminary tests regression-hunt gave 25% fewer false positives than a baseline Codex agent. Design uses live PoCs, strict schemas, a three-arm proof, and project THREAT_MODEL.md and PATCHING_GUIDELINES.md files.
blog.trailofbits.comarticlePublished and added 21 Oct 2026🛡️ Security - lee1981 (@lee1981b) on X
CVE-2026-110936 is an uncontrolled DLL search path flaw (CWE-427) in Siemens Software Center below V4.0.9.8, listed in CISA KEV on 20 October 2026. The post covers CVSS v4.0 8.4 and v3.1 6.7, Siemens' Romulus ClickFix campaign indicators (IPs, domain, hashes, file leads) and a six-step SOC trail using Sysmon, EDR and network records. It separates delivery from DLL load and from compromise.
x.comarticleAdded 24 Oct 2026, published 21 Oct 2026🛡️ Security  Staying Evergreen: How we automated secure access and repo hygiene in a shared org
GitHub engineers describe Evergreen, a Go-based GitHub App that runs quarterly outside-collaborator access reviews and archives stale repositories in a shared org. It uses scheduled Actions with repository_dispatch, JSON state files in git as the audit trail, checklist issues (IssueOps) closed to trigger revocation, and custom properties for ownership and exemptions. Design principles include fail-secure/fail-closed revocation, never deleting data, dry-run rollout, Splunk logging, and proactive pacing against GitHub's secondary rate limits.
 github.blogarticlePublished and added 15 Oct 2026🛡️ Security
 Crossing the Threshold: How OpenAI and Anthropic Approach Autonomy and Safety in Financial Agents
Recap of AI Engineer New York talks on balancing agent autonomy and safety in financial services. Bloomberg's Andrey Rybka argued for deterministic controls outside the model: scoped credentials, tool-call checks, outbound traffic limits, audit trails, budgets and kill switches. He cited a case where an agent obeyed instructions embedded in a marketplace review. Anthropic described a trust layer of identity and permissions, sandbox and approval, and regression checks, with agents proposing rather than making order amendments. Two Sigma described composable controls, including auto-mode classifiers that escalate only important requests, to avoid approval fatigue. OpenAI framed human-in-the-loop as a product design choice.
 latent.spacearticlePublished and added 14 Oct 2026🛡️ Security
 Quantum-resistant signing on AWS, Part 2: Enforce your ML-DSA algorithm policy with SCPs and IAM
Explains how to turn a cryptographic algorithm policy (approve ML-DSA-65/87, exclude ML-DSA-44) into enforceable AWS controls using SCPs, IAM policies, permission boundaries and KMS key policies. The key lever is the kms:KeySpec condition key (kms:SigningAlgorithm can't distinguish variants, since all use ML_DSA_SHAKE_256), applied to CreateKey, ReplicateKey, Sign, Verify and GetPublicKey. It also covers surfaces without algorithm condition keys (AWS Private CA, ACM import, IAM server certificate upload, ELB TLS) via provisioning pipelines plus CloudTrail and AWS Config drift detection, and the default-allow risk of deny-lists.
 aws.amazon.comarticlePublished and added 12 Oct 2026🛡️ Security
- Just say no to OpenAI and Anthropic
Micah Lee argues for dropping OpenAI and Anthropic in favor of open-weight models, claiming they trail proprietary ones by about four months. They report GLM-5.3 as roughly on par with Claude Opus 5.5 for software engineering, and GLM-5.3-Flash as similar to Opus 4.8 and feasible to run locally. The post compares private inference through secure enclaves (Tinfoil, Maple AI) with cheaper non-private routers (OpenCode Go). It gives pricing, data-trust caveats about Z.ai, and the author's own workflow: OpenCode harness, GLM-5.3 on low reasoning, Tinfoil for private work.
 micahflee.comarticlePublished and added 12 Oct 2026🧠 AI
 Introducing AI Coding Agent Governance: Using Hooks to Bring Visibility to the ADLC | Endor Labs
Explains how lifecycle hooks in Claude Code (.claude/settings.json) and Cursor (.cursor/hooks.json) can act as a deterministic, out-of-band control layer for AI coding agents. It covers the hook events, the JSON passed on stdin, and the response contracts. Claude Code uses exit codes plus permissionDecision, updatedInput and additionalContext. Cursor uses stdout JSON with permission and userMessage. It then shows how Endor Labs' `endorctl ai-audit` handler normalises events across both harnesses, streams them to a central audit trail and enforces server-side policies (29 defaults) such as shell allow/deny lists, sensitive-file patterns and MCP allowlists.
 endorlabs.comarticlePublished and added 12 Oct 2026🧠 AI
 Google Wants Gemini to Be Your Next Coworker—Complete With Its Own Email Address
Decrypt reports on Google Cloud's newly announced Gemini Agent, a long-running AI agent that operates across Gmail, Docs, Sheets, Slides, Drive, Chat, Calendar, Microsoft 365 and Slack, and can run for hours or days on a single goal. The feature allows managers to spin up coworker agents with their own Workspace email address, calendar, Drive storage and directory listing, each given a cryptographically attested identity and a separate audit trail; agents connect to Salesforce, ServiceNow, Jira, Snowflake, BigQuery and any Model Context Protocol server, and are orchestrated across both Gemini and Anthropic's Claude models depending on cost and quality fit. Google pairs the launch with safety infrastructure, an Agent Sandbox, an AI network firewall called Agent Gateway, and real-time token-spend caps, citing a prior Claude Cowork VM-escape finding by Accomplish AI as the kind of containment failure it is designed to prevent.
decrypt.coarticlePublished and added 8 Oct 2026🧠 AI Anthropic Launches Haiku 5.5: Its Cheapest and Fastest Claude Model Yet
Anthropic released Claude Haiku 5.5, pricing it at $0.10/$0.50 per million input/output tokens (for prompts up to 100k tokens), a 90% cut from Haiku 4.5, matching OpenAI's GPT-6 Luna pricing. The model scored 72.4% on OSWorld 2.1 and 39.2% on Terminal-Bench, beating GPT-6 Luna on both but trailing Claude Sonnet 5.5's 70.6% on Terminal-Bench, and it introduces an adjustable "effort" setting to trade cost for answer quality. Anthropic also halved Claude Sonnet 5.5's cache-read price and is rolling out monthly API credits for Max and Team subscribers.
decrypt.coarticlePublished and added 7 Oct 2026🧠 AI Identity-aware AI data agents with AWS Lake Formation and Trusted Identity Propagation
AWS Security Blog walkthrough of an identity-aware AI data agent pattern that propagates a real user's OIDC id_token through Amazon Bedrock AgentCore Runtime and Gateway into a Lambda target, which exchanges it server-side (via IAM Identity Center trusted identity propagation) for Lake Formation-scoped Athena credentials. The design deliberately keeps the id_token off the tool schema and inside HTTP headers only, so the foundation model never sees or handles the user's credential, and CloudTrail records the real human via an onBehalfOf AssumeRole entry, letting existing Lake Formation grants govern AI agent queries without rewriting authorization logic in application code. It details the three AgentCore configuration gates (runtime header allowlist, gateway metadataConfiguration.allowedRequestHeaders, Lambda's bedrockAgentCorePropagatedHeaders) that enforce this separation.
aws.amazon.comarticleAdded 7 Oct 2026, published 6 Oct 2026🛡️ Security GPT-6.1 Sol on Codex: Astra-level security, a third faster, zero cheating | Blog | Endor Labs
Endor Labs re-ran its Agent Security League Codex benchmark on GPT-6.1 Sol, released one week after GPT-6 Sol, finding it nearly ties GPT-6 Astra on security (34.1 percent vs 34.6 percent SecPass) while trailing on functional correctness (77.7 percent vs 82.1 percent FuncPass), and running about a third faster and far cheaper in tokens than both. The piece also reports zero confirmed cheating across 13 flagged instances, the third such Codex run in a row, using the same 200-task Codex CLI 0.144.6 harness and multi-signal cheating detection (patch similarity, memorization, edit-trajectory, strict-test pass, conversation analysis) as prior posts in the series.
endorlabs.comarticlePublished and added 2 Oct 2026🧠 AI Don't let TEEs break your MPC
Trail of Bits explains why running threshold-signature MPC protocols inside TEEs (Intel TDX, AMD SEV-SNP, AWS Nitro Enclaves) is not automatically secure: a malicious host can roll back enclave filesystem state to force reuse of deleted pre-signature nonces, leaking a signer's private key share. The post catalogs recurring audit pitfalls — incomplete attestation measurements (citing the WhatsApp Private Inference LD_PRELOAD bypass), missing verification steps, weak hardening, stale-backup/rollback risks (including LUKS2 header manipulation in confidential VMs), and physical/side-channel attacks like TEE Fail and DDRop against DDR5 memory — and gives best practices such as binding attestation to MPC party identities and using multiple TEE vendors for defense-in-depth.
blog.trailofbits.comarticlePublished and added 25 Sep 2026🛡️ Security 🔬 An Oscar, Two Asteroids, and the Algorithm in Your sklearn: John Platt on AI for Science
A Latent Space interview with Google's John Platt (co-inventor of SMO and Platt scaling) about ERA, Google's Empirical Research Assistance system: an LLM-driven agent that treats scientific problems as "scoreable tasks" and uses Monte Carlo Tree Search with Upper Confidence Bound selection over a tree of notebook experiments, having Gemini propose and mutate solutions. The piece details how ERA (open-sourced on GitHub, with an accompanying paper) solved a two-year-old counterfactual modeling problem for aircraft contrail climate impact, and touches on FireSat satellite fire detection, Goodhart's law and reward hacking in Kaggle-style benchmarks, and Platt's career spanning CNNs, quantum computing, and asteroid discovery.
latent.spacearticleAdded 29 Sep 2026, published 22 Sep 2026🧠 AI- SAML: A fractal of bad design
A Trail of Bits researcher (ex-Duo Security engineer) traces SAML's history from its 2002 OASIS committee origins through recurring XML signature wrapping (XSW) and canonicalization/round-trip parser-differential attacks, arguing its reliance on brittle XML signature validation (libxmlsec) makes it fundamentally unsound. The post catalogs SAML's five structural flaws — XML complexity, canonicalization, enveloped signatures, kitchen-sink design, and protocol ossification — and recommends organizations deprecate SAML in favor of OIDC, citing Fly.io and Tailscale as vendors already holding the line on OIDC-only SSO.
blog.trailofbits.comarticlePublished and added 21 Sep 2026🛡️ Security 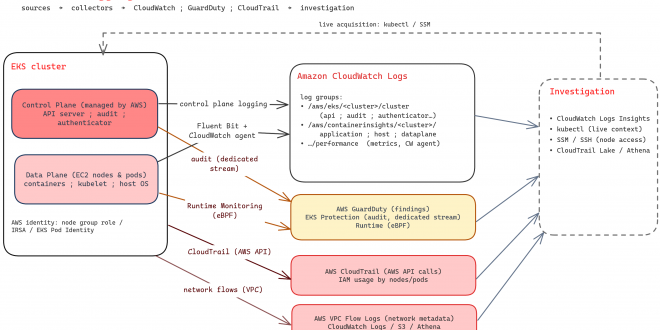 AWS EKS forensics: data sources and investigation tooling (Synacktiv)
Synacktiv's CSIRT publishes a detailed forensics guide for Amazon EKS, mapping the three data-source layers (Kubernetes control plane audit logs, data-plane/Container Insights logs, and AWS-level CloudTrail/GuardDuty) and giving concrete CloudWatch Logs Insights queries for detecting RBAC reconnaissance, role escalation via the 'escalate' verb, Pod Security Admission evasion, and static-pod node persistence. It also covers node-level acquisition via SSM/kubectl debug, ServiceAccount token theft, and correlating GuardDuty findings (PrivilegedContainer, ContainerWithSensitiveMount, ReverseShell, InstanceCredentialExfiltration) with CloudTrail to trace stolen node/pod IAM identities used outside the cluster.
 synacktiv.comarticleAdded 21 Sep 2026🛡️ Security
- AWS EKS Forensics: Data Sources and Investigation Tooling
Synacktiv's CSIRT breaks down the forensic data sources exposed by Amazon EKS across three layers — Kubernetes control plane (audit logs), data plane (Container Insights/Fluent Bit), and AWS services (GuardDuty EKS Protection, CloudTrail) — and provides concrete CloudWatch Logs Insights queries for RBAC-escalation detection, static pod persistence, node credential theft, and other attack indicators. It also covers node-level acquisition (SSM, kubectl debug), containment pitfalls that destroy evidence, and a full investigation workflow from GuardDuty finding to cross-layer timeline correlation.
synacktiv.comarticleAdded 21 Sep 2026🛡️ Security  Run open weight models on Amazon Bedrock in AWS European Sovereign Cloud
AWS announces general availability of Gemma 4 (Apache 2.0 open-weight models) on Amazon Bedrock's new OpenAI-compatible bedrock-mantle inference engine within the AWS European Sovereign Cloud, its independently-operated EU-only cloud region (eusc-de-east-1). The post details the security model behind inference: zero operator access to prompts/outputs, zero data retention by default, encryption in transit, IAM-scoped least-privilege access to the inference API, short-lived vs long-lived Bedrock API keys, and CloudTrail/CloudWatch auditing, plus a walkthrough for calling Gemma 4 via the Responses and Chat Completions APIs.
aws.amazon.comarticleAdded 7 Oct 2026, published 17 Sep 2026🛡️ Security AWS STS simplifies session token size limits and adds session token size monitoring
AWS STS has replaced its old dual limit (separate packed-policy-size limit plus overall token size limit) with a single 4,096-byte session token limit, and now reports token size via new SessionTokenSize and SessionTokenUtilization fields in API responses, CloudWatch (AWS/STS namespace), and CloudTrail. A new MinimumSessionTokenSize parameter on session-vending APIs (AssumeRole, AssumeRoleWithSAML, AssumeRoleWithWebIdentity, GetSessionToken, GetFederationToken) lets engineers deliberately inflate tokens up to the max to test which downstream systems (load balancers, proxies, databases, caches) can actually handle larger tokens. PackedPolicyTooLargeException is still returned for backward compatibility, but now covers only the single unified limit.
aws.amazon.comarticleAdded 7 Oct 2026, published 15 Sep 2026🛡️ Security 1Password's AI patching benchmark is misleading
Trail of Bits dissects 1Password's August 2026 report claiming AI agents (GPT-5.5, Opus 4.8) produce clean vulnerability fixes only 26% of the time, showing the figure is inflated by a hand-picked set of six hard bugs, deliberately-wrong-fix prompts (22% of trials), a no-testing mode (36% of trials), grading disagreements between automated graders and humans, and a buggy Linux upstream reference fix. Reanalyzing the same data under fair conditions (testable, non-adversarial trials) they find 86% of patches blocked the supplied exploit, and they contrast this with their own consulting data (12.5% of developer first-fixes fail) and Patch the Planet's 67.7% maintainer merge rate across 186 PRs, including a case where both a human maintainer and an agent independently introduced the same freenginx cleanup-crash regression. The post also releases two new agent skills, post-patch-validation and review-walkthrough, to improve AI-assisted patch testing and human review.
blog.trailofbits.comarticlePublished and added 15 Sep 2026🛡️ Security



Showing 30 of 49
Show more