Skip to content

56 results for β€œAccel”

What you seeeverything
microsoft.comarticleπŸ›‘οΈ Security

Tracking AI adoption in North Korean threat actor tradecraft

Microsoft Threat Intelligence report on how North Korean actors use AI, ranking Jade Sleet, Coral Sleet and Jasper Sleet as operationalized, Diamond Sleet, Onyx Sleet, Pearl Sleet and Sapphire Sleet as accelerating, and Emerald Sleet as expanding. It documents AI-generated lures (100+ Onyx Sleet PDFs, August and September 2026), AI-built tooling such as Coral Sleet's private GitHub repository trojanizing, and Onyx Sleet and Pearl Sleet use of the ARTEX agentic pentest framework. It ends with mitigation and Defender guidance.

CursorGitHubRust+2
Jade SleetOnyx SleetCoral Sleet+9

Threat Intel, AI SecurityΒ· Published and added 29 Oct 2026
eprint.iacr.orgpaperπŸ›‘οΈ Security

Beyond the Scope of This Paper: Practical Flash-Accelerator and Cache-Collision Timing Attacks on Microcontrollers

Colin O'Flynn's paper shows that the flash accelerator in most microcontrollers produces the same timing collisions as a cache, so cacheless Cortex-M devices remain open to cache-collision attacks on AES. AES keys were recovered from as few as 750 traces across six cryptographic libraries, eight architectures and over twenty devices. It also attacks SPI bootloaders, Ethernet, CTAP2 over USB and 802.15.4, and releases the open-source tool FlashWhisperer.

FlashWhispererARM Cortex-M4SPI+1
cache-collision timing attackColin O'FlynnCTAP2+2

Hardware & RFΒ· Added 31 Oct 2026, published 29 Oct 2026

anthropic.comarticle🧠 AI

Early progress on accelerating drug development with Claude

Anthropic's life sciences update describes research partnerships with six drug developers (BigHat, Bristol Myers Squibb, Divergence Labs, Enveda, Generate Biomedicines, The Column Group) and its own Mithril Medicine programs. Reported results include about 35,000 antibody designs in a month, 1,010 lead variants tested in 10 weeks, and an 89% cut in manufacturing-document review time. Work is mostly preclinical.

ClaudeClaude CodeClaude Science
AnthropicBigHat BiosciencesBristol Myers Squibb+10

llm-apps, agentsΒ· Added 28 Oct 2026, published 27 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Balsamic: One-round Threshold UOV from GPU-Accelerated FHE

Balsamic is a complete homomorphic Unbalanced Oil and Vinegar (UOV) signer, used to build one-round threshold UOV signatures from a packed discrete-CKKS FHE circuit. A paired-pivot linear solver and pivot-success certificates allow encrypted retry selection. In 2-out-of-3 semihonest signing, each online partial signature takes 10.7 s on an RTX 6000 Ada and 7.77 s on a GB300, with 5.25 MB per response.

UOVCKKSFHE+2
Balsamicuniversal thresholdizerspaired-pivot solver+1

otherΒ· Added 24 Oct 2026, published 22 Oct 2026

latent.spacetalk🧠 AI

Why AI Compute Comes in Rectangles β€” Erik Bernhardsson, Modal CEO

Latent Space interview with Modal CEO Erik Bernhardsson, after Modal's $750M Series D at a $16B valuation and passing $1B annualized run rate. He explains why GPU demand is not "rectangular" like fixed-term capacity contracts, how Modal pools demand and buys from about 25 clouds on three-year deals, and why sandboxes grew to about a third of revenue. Also covers GPU price-collapse risk and non-NVIDIA accelerators. Only the first part of the transcript was available.

GPUKubernetesDocker+5
ModalErik BernhardssonAkshat Bubna+13

ai-infra, inference, agentsΒ· Published and added 22 Oct 2026

latent.spacetalk🧠 AI

Why AI Compute Comes in Rectangles β€” Erik Bernhardsson, Modal CEO

Latent Space interview with Modal CEO Erik Bernhardsson after the company's $750M Series D at a $16B valuation, with a transcript. He explains why GPU demand does not match rectangular fixed-term capacity contracts and how Modal pools demand across customers. He covers sourcing from nearly 25 clouds on multi-year deals, the risk of falling GPU prices, sandboxes reaching about a third of revenue, and non-NVIDIA accelerators.

ModalGPU snapshottingKubernetes+6
Erik BernhardssonAkshat BubnaLatent Space+15

ai-infra, inferenceΒ· Added 23 Oct 2026, published 22 Oct 2026

arxiv.orgpaper🧠 AI

SARIA: Persistence-Aware KV Caching with Coordinated DRAM--SSD Reload for LLM Agents

SARIA (Selective Admission and Reload for Inference Acceleration) is a KV caching system that jointly manages DRAM and SSD for multi-turn LLM agents. It persists only blocks likely to be reused beyond DRAM residency, promotes SSD-hit blocks into DRAM for same-session reuse, and paces DRAM reads with a transfer coordinator. Built on LMCache MP, it cuts SSD writes by 57.1 to 58.9% versus full duplicate caching and mean TTFT by 42.3 to 79.7% versus DRAM-only caching.

LMCache MPLLMSSD+1
SARIALMCacheTraceLab+2

inference, researchΒ· Added 23 Oct 2026, published 22 Oct 2026

latent.spacearticle🧠 AI

[AINews] DeepSeek DeepInfer: Open Source SOTA Inference running 155T toks/day/cluster making $22m/day at ~80% margin for a 81 day payback

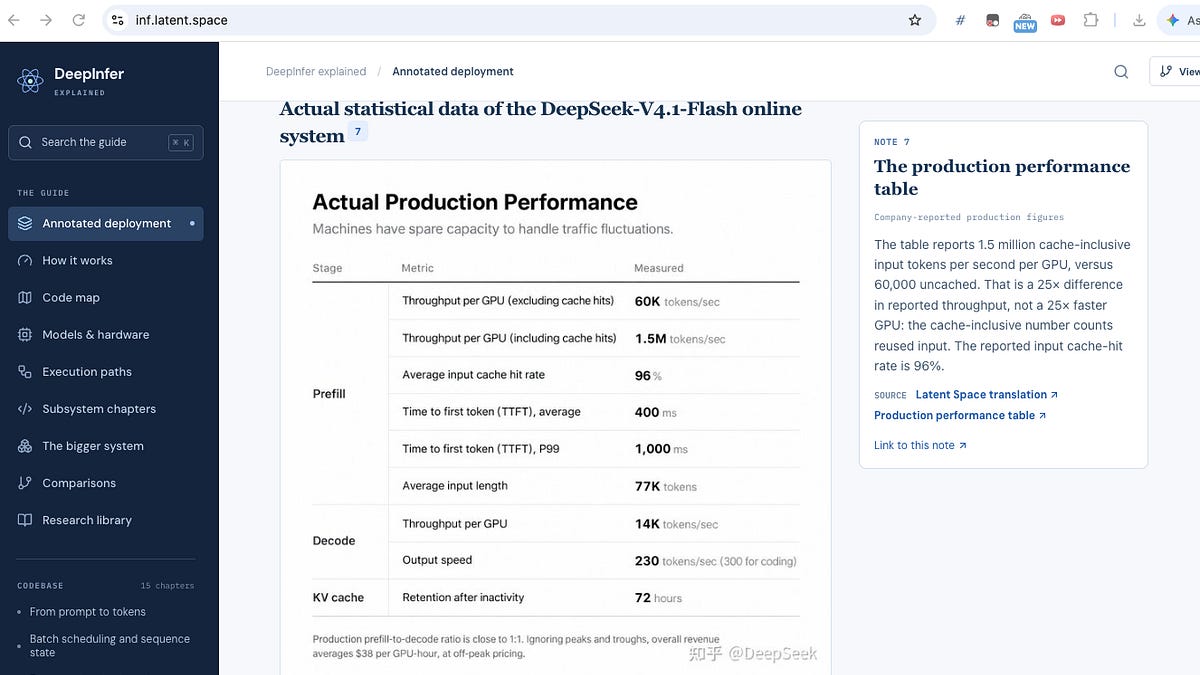
AINews issue for 19 to 20 October 2026 whose top story is DeepSeek's open-source DeepInfer, the inference engine behind V4.1 Flash. It covers prefill/decode separation, wide expert parallelism, a 3FS-backed prompt cache with 96% input hits, vLLM's decode result within 6% of DeepInfer on GB200, and disputed margin estimates built on the reported $38 per accelerator-hour. It also digests other news, and the page text is truncated.

DeepInfervLLMSGLang+9
DeepSeek-V4.1-FlashOpenAINVIDIA+23

inference, ai-infra, modelsΒ· Added 23 Oct 2026, published 21 Oct 2026

latent.spacearticle🧠 AI

[AINews] DeepSeek DeepInfer: Open Source SOTA Inference running 155T toks/day/cluster making $22m/day at ~80% margin for a 81 day payback

This AINews issue (20 October 2026) leads with DeepSeek's open-sourced DeepInfer, the vLLM-based inference engine behind V4.1 Flash. It covers prefill/decode separation, a 3FS-backed prefix cache with 96% hit rate, SWA Bounded Replay, and DeepSeek's claims of 155T tokens/day and $38 revenue per accelerator-hour. It also covers vLLM's within-6% decode reproduction on GB200, disputed margin estimates, and a round-up of other AI news. Only the first 40,000 of 56,439 characters were available.

DeepInfervLLMSGLang+9
DeepSeekDeepSeek-V4.1-FlashNVIDIA+27

inference, ai-infra, ai-policyΒ· Published and added 21 Oct 2026

newsletter.semianalysis.comarticle🧠 AI

Datacenters 2027: The Year of Acceleration, +50GW in a Single Year

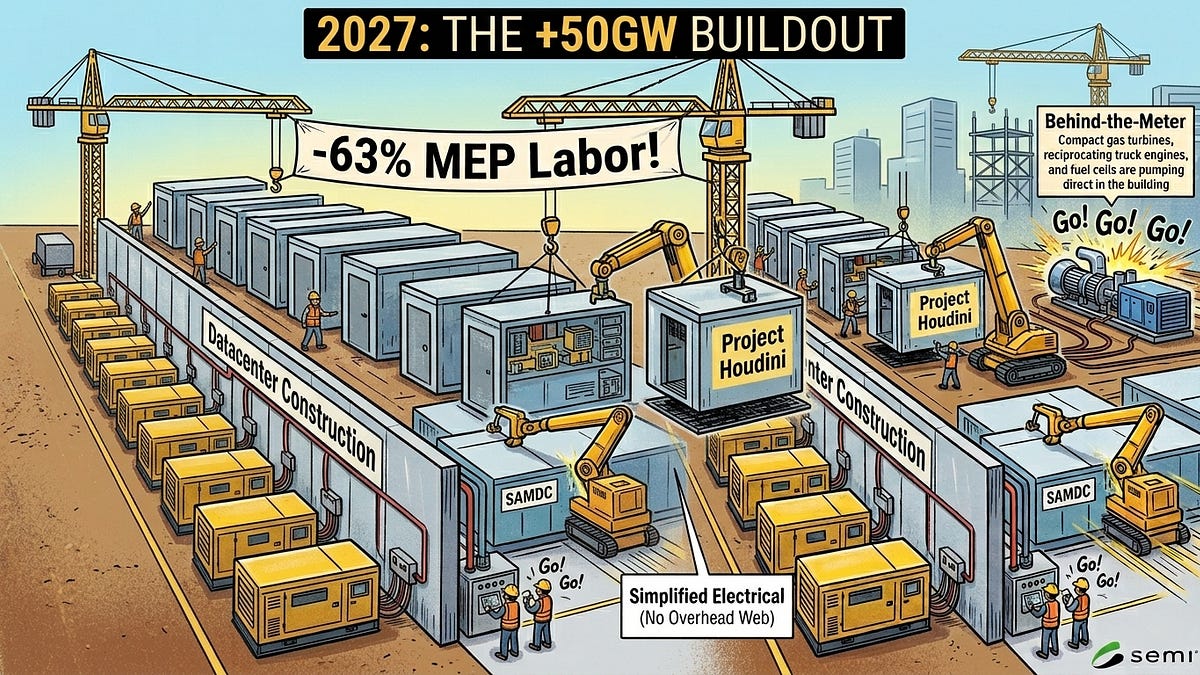
SemiAnalysis argues that global AI datacenter capacity will grow by about 50GW in 2027, against Brad Gerstner's guess of roughly 25GW. Evidence cited: over 24GW in advanced construction across 40 campuses, nearly USD 1T of binding leases signed in 2026, and record self-build starts. It also covers modular "LEGO" designs, behind-the-meter power and ex-US growth. The page text cuts off before the oversupply section.

Behind-the-meter generationModular datacentersPrefabricated electrical modules+2
SemiAnalysisBrad GerstnerAltimeter+20

ai-infra, ai-policyΒ· Added 29 Oct 2026, published 19 Oct 2026
eprint.iacr.orgpaperπŸ›‘οΈ Security

Enjoy FAEST on Hardware: Efficient and Novel Hardware Acceleration of Emerging Post-Quantum Digital Signature Scheme FAEST

This ePrint paper (2026/2525, October 2026) by Brendan Funk and Jiafeng Xie presents the first hardware accelerator for FAEST, an MPC-in-the-head post-quantum signature in NIST's Round 3 additional-signature process. It analyses FAEST's compute-heavy operations, builds them into hardware blocks, and adds an L1-EM-fast variant. The authors report at least 98% lower equivalent area-delay product than the recent complete SDitH design at the same security level.

FAESTFPGA
NISTSDitHMPC-in-the-head+2

Hardware & RFΒ· Added 19 Oct 2026, published 18 Oct 2026

arxiv.orgpaper🧠 AI

TileDRAM: Compiler-Controlled Tile-to-DRAM Layouts for 3D DRAM GPGPUs

TileDRAM is a compiler-runtime toolchain that adds tile-to-DRAM layouts as a compiler-visible abstraction for compute-unit-local 3D DRAM GPUs. It extends GPU Linear Layout to DRAM placement and picks layouts per tile access signature using row-buffer behavior. On 108 MoE FFN cases in Accel-Sim/Ramulator2, row-conflict rate fell from 75.7% to 15.2%, with a 1.77x geomean speedup. Overhead on an RTX 3090 is 0.17%.

Mixture of ExpertsCUDAAccel-Sim+2
TileDRAMRTX 3090

research, inferenceΒ· Added 20 Oct 2026, published 16 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

safeRNSgcd: Accelerating Falcon key generation with RNS in SafeGCD

ePrint paper presenting safeRNSgcd, which computes the single BΓ©zout coefficient needed at the deepest level of Falcon's NTRU solver while keeping large integers in a residue number system. Centered explicit CRT recovers the exact low bits needed by SafeGCD batches using single-word fixed-point arithmetic. A C implementation integrated into ntrugen reduces inversion and private-key basis-generation cost on a Raspberry Pi 5 and two x86-64 CPUs, versus the original ntrugen and a variant that skips the unused coefficient.

FalconntrugenSafeGCD+2
safeRNSgcdCesare HuangBo-Yin Yang

otherΒ· Added 17 Oct 2026, published 16 Oct 2026

decrypt.coarticle🧠 AI

Google Says AI Isn't Building Itself Yetβ€”Even Though It Writes 75% of the Code

Decrypt reports on the Gemini 4 Argon Safety & Security Report, where Google DeepMind found no statistically significant acceleration of ML R&D. Its internal GCI v1 index (123 models, 92 benchmarks) shows steady ~0.1 points/month progress, with Argon slightly above trend, attributed to compute and investment. Over 75% of production code is AI-written and fully delegated pull requests rose from 7.5% to 11.9%, yet ~88% of PRs still need human steering or authorship. This is relevant evidence on the recursive self-improvement debate and on how much of AI research is automated.

Gemini
Google DeepMindGemini 4 ArgonHaydn Belfield+5

ai-safety, evals, coding-agentsΒ· Published and added 15 Oct 2026

deepmind.googlearticle🧠 AI

Accelerating the search for antimicrobial peptides with Google Antigravity

Google DeepMind describes using Google Antigravity as an agentic science workbench to find antimicrobial peptide candidates in Streptococcus pseudopneumoniae. The agent orchestrates queries across UniProt and other databases, uses ProtNLM function predictions for uncharacterized proteins, and pulls structures from the AlphaFold Database. A new Biomolecular Structure Viewer shares 3D state with the agent in both directions, so residues the researcher highlights or pins become context for the agent's reasoning. The resulting lead has predicted activity against respiratory-tract pathogens and is going into wet-lab validation.

Google AntigravityProtNLMUniProt+1
Google DeepMindBiomolecular Structure ViewerStreptococcus pseudopneumoniae+4

agentsΒ· Published and added 15 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

FAEST on GPUs: Addressing Field Multiplication as a Bottleneck

ePrint paper presenting an NVIDIA GPU implementation of FAEST (a post-quantum signature scheme built on VOLE-in-the-Head and QuickSilver), covering key generation and OWFProve/OWFVerify for standard and EM constructions in s and f variants. Profiling shows field multiplication takes about 82% of FAEST-128f signing time once AES is hardware-accelerated. Using PTX clmad carry-less multiplication plus Karatsuba, it reaches up to 26.6x kernel throughput and about 2.9-3.1x full 256-bit OWFProve throughput over the software-multiplication build on an RTX A5000.

CUDANVIDIA RTX A5000PTX+1
FAESTQuickSilverVOLE-in-the-Head+3

otherΒ· Published and added 15 Oct 2026

x.comthreadπŸ›‘οΈ Security

Victor (@VMG_CU) on X

A social post summarising Elastic's REF8801 campaign. A fake startup accelerator offered founders free Claude/Gemini credits plus a coding agent. The agent was a repackaged open-source project that set OPENROUTER_BASE_URL to an attacker-controlled endpoint and added its own MCP server, so victims' prompts and code went to the attacker. It shows how a trojanised AI coding agent can hijack the LLM base URL and add an MCP server for exfiltration.

OpenRouterModel Context ProtocolClaude+1
REF8801Elastic Security LabsOPENROUTER_BASE_URL

Threat Intel, AI SecurityΒ· Added 15 Oct 2026, published 14 Oct 2026

metr.orgarticle🧠 AI

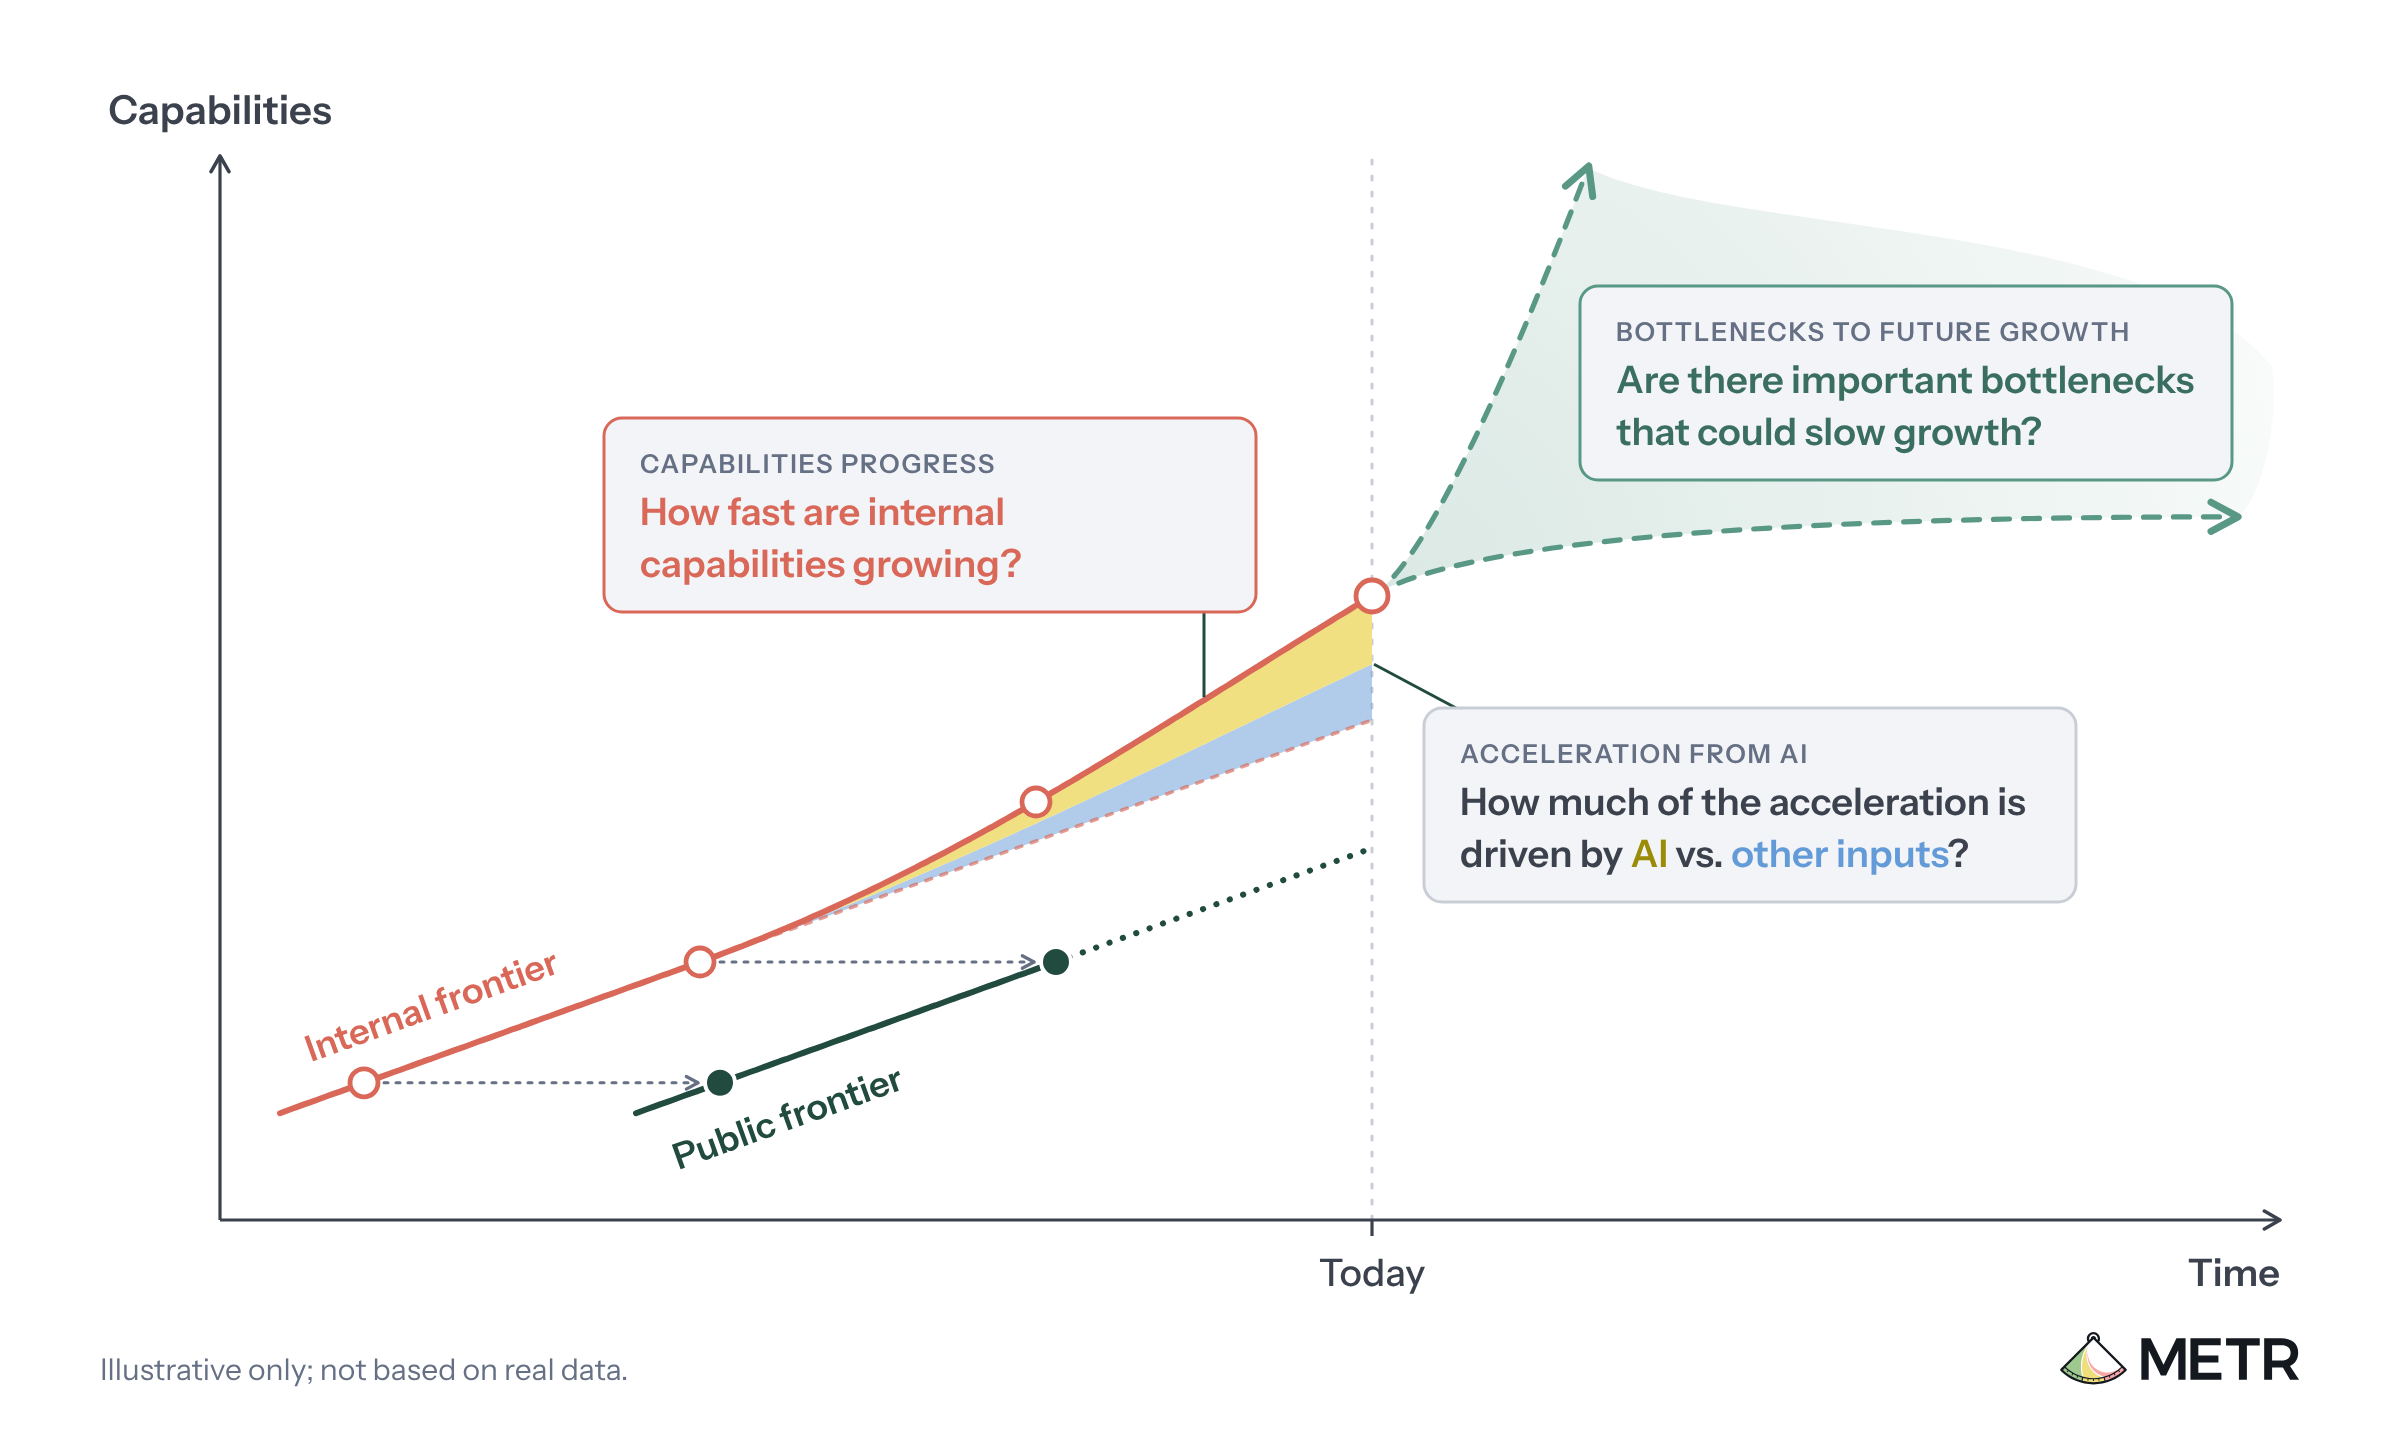
How an assessor could investigate evidence of acceleration from the automation of AI R&D

METR proposes a framework for an outside assessor to test whether AI automation of AI R&D is accelerating capabilities progress. It covers four questions: how fast internal capabilities improve, how much acceleration AI causes, which bottlenecks could slow growth, and whether the methods would detect a dramatic acceleration. It lists the internal data developers would need to share, including benchmarks, algorithmic progress estimates, compute, labor, AI agent spend and staff interviews.

METRECI

ai-policy, evals, ai-safetyΒ· Added 29 Oct 2026, published 14 Oct 2026

metr.orgarticle🧠 AI

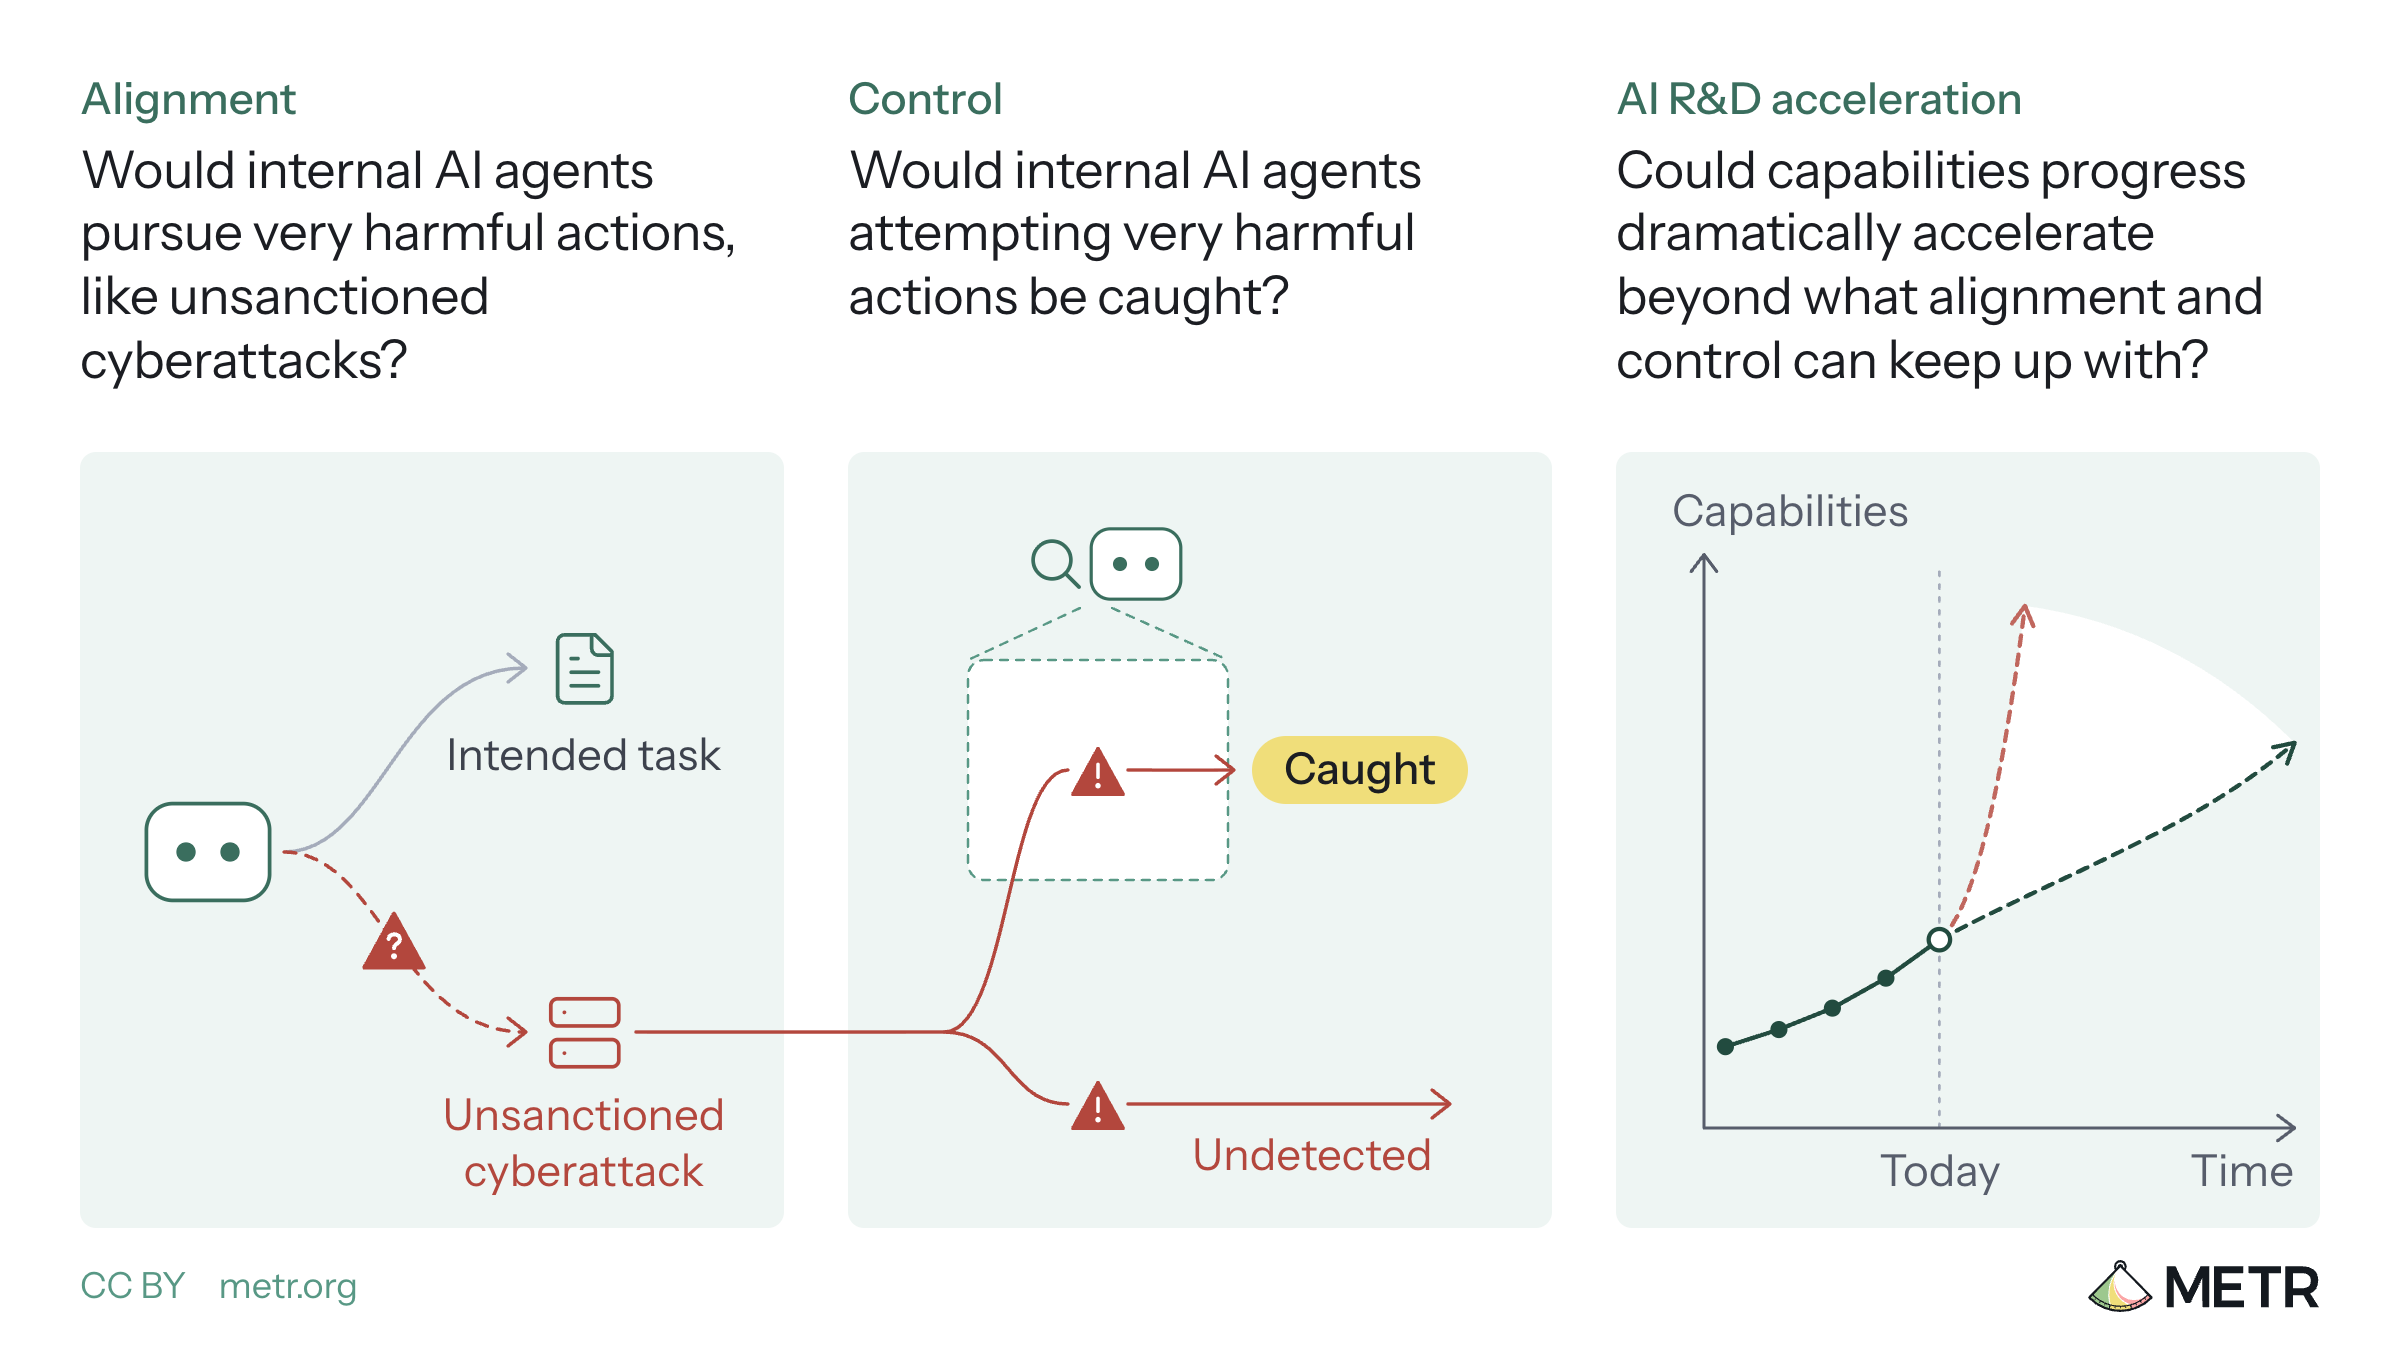
A proposal for better informing the public about loss-of-control risks from frontier AI development

METR proposes risk assessment exercises in which it would write public reports on whether frontier developers could lose control of internal AI systems. The reports would rest on private staff interviews and access to internal data, covering three questions: alignment incidents, monitoring and control, and AI R&D acceleration. The post also lists its limits: voluntary participation, company redaction rights, no security audits, no compliance verdicts.

METRAnthropicOpenAI+12

ai-safety, ai-policyΒ· Added 29 Oct 2026, published 14 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Accelerating Pollard Rho with GPU Field Arithmetic on NVIDIA Blackwell

Preprint that speeds up Pollard rho on GPUs by rebuilding field arithmetic: packed normal-basis representation, the CUDA 13.3 PTX carry-less multiply (clmad), and three-input logic instructions. On one RTX PRO 6000 Blackwell it goes from 0.85 to 14.64 billion iterations/s (17.2x) on the Certicom ECC2K-130 challenge, which puts the whole challenge under five GPU-years. The same levers give 1.52x on P-256 and 2.61x on P-384, which leaves P-256 about 6e21 card-years away. It also reports twelve GPUs from Turing to Blackwell, an FPGA engine on AWS F2 and a campaign that covered 5.4% of the expected work, with code and a Dockerfile on GitHub (rho-blackwell). It claims no improvement on the generic-group bound.

CUDANVIDIA BlackwellAWS+1
Pollard rhoECC2K-130Certicom challenge+5

otherΒ· Published and added 14 Oct 2026

arxiv.orgpaper🧠 AI

Dog-Breed Text-to-image Flow Matching from Pretraining to Fine-Tuning on 4 Consumer GPUs

MiniDog is a framework for training a text-to-image flow-matching diffusion transformer from scratch on four RTX 3090 GPUs, with 55 minutes of pretraining and 15 minutes of fine-tuning. It pretrains on 26k ImageNet dog images that were captioned, then fine-tunes on 2k FLUX.1-schnell generated images. Image and text features are precomputed and cached. The model is a 22M-parameter transformer with the E2E-INVAE semantic latent space, a small Qwen text encoder and in-context conditioning, and training is accelerated with iREPA and an EUPE perception encoder. The repo evaluates with FID, HPSv2, PickScore and VAE reconstruction metrics. It lowers the barrier to hands-on diffusion training research.

flow matchingdiffusion modelTransformer+1
MiniDogImageNetFLUX.1-schnell+7

research, training, multimodalΒ· Added 14 Oct 2026, published 13 Oct 2026

en.cryptonomist.charticle🧠 AI

Microsoft’s AI chip targets 40% more tokens per megawatt in 2027

Reports Microsoft's Maia 300, its third-generation in-house AI accelerator, unveiled October 12, 2026 with production workloads from 2027. Microsoft claims 40% more tokens per megawatt than leading GPU systems and up to 7x Maia 200's rack-level token throughput in a 96-accelerator rack. It uses a chiplet design on TSMC N2P that separates compute, memory-controller and I/O. It is aimed at long-context reasoning and agentic inference, while Nvidia and AMD stay in place for training. Useful as a data point on the shift toward custom inference silicon and model-chip co-design.

Maia 300Maia 200Azure+4
MicrosoftNVIDIAAMD+12

inference, ai-infraΒ· Published and added 12 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

ML-Assisted Power Side-Channel Attacks on ML Accelerators in Shared FPGAs

Paper presenting the first on-chip, TDC-sensor-based power side-channel attack on a co-tenant FPGA to reconstruct full-scale color ImageNet inputs (224x224) from a victim's first CNN convolution layer, using ML-based upscaling and recoloring. It separates genuinely leaked information from ML-generated post-processing. It also evaluates a pixel-substitution defense based on Hamming Weight, which is largely defeated by an attacker retrained on the transformed data. The authors conclude that robust defenses need randomized or input-dependent transformations.

FPGACNN
Time-to-Digital ConverterImageNetMNIST+1

Hardware & RF, AI SecurityΒ· Added 16 Oct 2026, published 12 Oct 2026

x.comthread🧠 AI

Adam Shepherd (@EntryStateGod) on X

Social post announcing Qwen's open-weights release of Qwen-Image-2.1-Turbo, an accelerated checkpoint of Qwen-Image-2.1 on the same 7B visual generation architecture. It generates and edits images in 8 denoising steps, against 40 in the base model's sample code, with 2K output. Qwen claims the fewer steps do not reduce quality. The license is non-commercial, which limits production use.

Qwen
Qwen-Image-2.1-TurboQwen-Image-2.1

models, multimodalΒ· Published and added 9 Oct 2026

thedefiant.ioarticleπŸ›‘οΈ Security

Coinbase Cryptographer Calls Drake's 'Bunker Mode' Warning 'The Very Definition of FUD'

News piece reporting that a Coinbase cryptographer dismissed Justin Drake's proposal for Ethereum validators/users to adopt a 'bunker mode' against AI-accelerated cryptanalysis as unfounded FUD. Vitalik Buterin weighed in that AI-accelerated math risk is real but should be pointed at lattice-based cryptography rather than elliptic-curve schemes like ECDSA used by Ethereum, while a former Ethereum Foundation researcher argued bunker mode would not help if the curves actually broke.

Ethereum
Vitalik ButerinJustin DrakeECDSA+1

BlockchainΒ· Published and added 8 Oct 2026

bankless.comarticleπŸ›‘οΈ Security

Vitalik Flags AI Risk to Crypto, Warns Against Rushed Wallet Moves

Vitalik Buterin responds to Ethereum Foundation researcher Justin Drake's bunker mode proposal, agreeing AI-accelerated cryptanalysis could break ECDSA, the signature scheme behind most crypto wallets, in months not years, and that lattice-based schemes like ML-DSA billed as quantum-safe could also take serious hits within two years. Buterin gives practical key-hygiene advice such as keeping funds in addresses that never exposed a public key and rotating multisig signer keys after every operation with offchain signature collection, while warning that botched migrations cost more than hacks.

Ethereum
Vitalik ButerinJustin DrakeECDSA

BlockchainΒ· Published and added 8 Oct 2026

en.cryptonomist.charticleπŸ›‘οΈ Security

AI risk to crypto wallets: Ethereum researcher warns keys could be cracked in months

Ethereum Foundation researcher Justin Drake warned on October 7, 2026 that advances in AI and mathematics could break ECDSA β€” the signature scheme securing blockchain transactions β€” within months, potentially letting an attacker recover a private key in about a week using a large GPU cluster. He urged gradual "bunker mode" preparation rather than panic: rotating funds into fresh addresses whose public keys have never been exposed on-chain, strengthening cold storage, and accelerating Ethereum's move toward hash-based signature schemes such as SPHINCS for critical signers like oracles and L2 security councils.

EthereumECDSASPHINCS
Justin DrakeEthereum FoundationWu Blockchain+1

BlockchainΒ· Published and added 8 Oct 2026

decrypt.coarticleπŸ›‘οΈ Security

Ethereum Researcher Says AI May Break Encryption Before Quantum Does

Ethereum Foundation researcher Justin Drake warns that AI-driven mathematical advances could break ECDSA β€” the signature scheme securing Bitcoin and Ethereum β€” before quantum computers do, potentially recovering a private key from an exposed public key in about a week using a large GPU cluster. He calls for "bunker mode": a controlled mass migration of funds to fresh addresses whose public keys have never been exposed, urges major custodians (Binance, Bitbank, Robinhood, Bitfinex, Tether) to harden cold storage, and pushes Ethereum to accelerate its move to hash-based (post-quantum) cryptography.

EthereumBitcoinOpenAI
Justin DrakeECDSAbunker mode+3

BlockchainΒ· Published and added 7 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

K-LMS: Design, Implementation, and Evaluation of Leighton–Micali Signatures with Korean Cryptographic Primitives

An IACR ePrint paper presenting K-LMS, an experimental variant of the NIST-standardized LMS hash-based post-quantum signature scheme in which the underlying hash is swapped for Korean primitives: the LSH-256 hash function (reference and vectorized) and a Tandem-DM double-block-length construction built from the CHAM, LEA, and ARIA block ciphers. The authors implement a non-invasive backend-swapping bridge over the reference LMS code and benchmark keygen/sign/verify latency, key/signature sizes, memory, and parameter sweeps, finding that hash substitution doesn't change key/signature sizes but that two measurement pitfalls (hash dispatch overhead, and software vs. hardware-accelerated SHA-256 baselines) can shift performance comparisons by an order of magnitude or 6x respectively. They report LSH-256 K-LMS signing on par with SHA-256 LMS in software, and 3.3-3.9x faster than a prior K-XMSS implementation because LMS needs fewer hash calls per Winternitz step than XMSS.

LMSLSH-256CHAM+3
NISTXMSSSPHINCS+

otherΒ· Added 8 Oct 2026, published 6 Oct 2026

arxiv.orgpaper🧠 AI

Herschel: Continuous Optimization of Production LLM Inference through On-Demand Profiling

Herschel is a continuous optimization system for production LLM inference that uses adaptive, on-demand profiling instead of always-on tracing to diagnose serving inefficiencies with low overhead (under 0.5% TTFT, 7% TPOT impact). It attaches to and detaches from running inference processes without engine restarts, reconstructs cross-process operator execution traces to pinpoint inefficiency mechanisms, and has AI agents implement and test candidate engine/kernel fixes under controlled replay of the triggering workload before expert review and deployment. Over six months of production use it collected ~17,000 traces across 120+ model variants and 10+ accelerator types, finding inefficiency patterns in 23% of traces and driving optimizations like restructured synchronization and removal of unused computation.

Herschel

inference, ai-infraΒ· Added 3 Oct 2026

Showing 30 of 56

Show more