Skip to content

31 results for β€œApache”

What you seeeverything
blog.cloudflare.comarticleπŸ›‘οΈ Security

Introducing the Cloudflare PHP Capture the Flag challenge

The Cloudflare PHP Capture the Flag challenge is a HackerOne bug bounty CTF. Researchers must bypass Cloudflare WAF rules protecting CVE-2026-109618 and CVE-2026-109619 (PHP2Shell) on stock PHP 8.5.11 with Apache mod_php in a Cloudflare Container, get RCE, and read /flag. The post lists scope (POST to /php/* only), report requirements and duplicate rules, which count only materially distinct WAF bypasses.

CloudflarePHPHackerOne+1
CVE-2026-109618CVE-2026-109619PHP2Shell+1

AppSec, Offensive SecurityΒ· Added 29 Oct 2026, published 27 Oct 2026

securityweek.comarticleπŸ›‘οΈ Security

PHP2Shell Exploitation Moves From Probes to Working Shells

PHP2Shell exploitation (CVE-2026-109618, CVE-2026-109619) reached working shells on 24 October 2026, when Perplexity researcher Adel Karimi's honeypots (PHP 8.4.26, Apache mod_php, single worker) logged 35 shells across three servers. Attackers used a four-stage HTTP chain: memory exhaustion, memory leak, then shell command execution, matching a public PoC. No second-stage payload was seen, and CISA had not added the flaws to KEV as of 26 October.

PHPApache
CVE-2026-109618CVE-2026-109619PHP2Shell+4

Threat Intel, AppSecΒ· Published and added 26 Oct 2026

securityweek.comarticleπŸ›‘οΈ Security

Atlassian Patches 75 Flaws in Data Center and Server Products

Atlassian's October 2026 security bulletin lists 162 high and 14 critical third-party vulnerabilities across Bamboo, Bitbucket, Confluence, Crowd, Fisheye/Crucible, Jira Software and Jira Service Management. SecurityWeek counts 75 unique CVEs, six critical, in Tomcat, Bouncy Castle, Netty and Apache SSHD. Atlassian rates them non-critical for its use, reports no exploitation, and the critical CVE-2026-65905 appears on the portal but not in the bulletin.

ConfluenceJiraBitbucket+3
CVE-2026-65637CVE-2026-65182CVE-2026-68525+6

AppSec, Supply ChainΒ· Published and added 23 Oct 2026

huggingface.coarticle🧠 AI

NVIDIA Kumo Relational Outperforms Supervised Machine Learning on Relational Data, No Training Required

NVIDIA Kumo Relational is a pre-trained relational foundation model that predicts outcomes such as churn or fraud directly on multi-table databases through in-context learning, using up to 10,000 context examples and no task-specific training. NVIDIA reports it beats supervised relational deep learning and XGBoost pipelines across 41 tasks on 15 databases, and beats AutoGluon by 8% MRR on SAP SALT. Code is Apache 2.0, weights are on Hugging Face.

structured-data-modelsNVIDIA NIMPredictive Query Language+6
NVIDIAKumo RelationalKumo Tabular+6

models, research, evalsΒ· Published and added 21 Oct 2026

securityweek.comarticleπŸ›‘οΈ Security

PHP2Shell Patches Land as First Exploitation Attempts Hit Sensors

PHP2Shell is a pair of critical PHP core flaws, CVE-2026-109618 (out-of-memory corruption) and CVE-2026-109619 (stale global state), both CVSS 9.2 and giving unauthenticated RCE, confirmed on Apache with mod_php. Fixes shipped in PHP 8.5.12, 8.4.27, 8.3.36 and 8.2.35, with backports for 7.4 to 8.1. Exploitation attempts were reported by watchTowr, Hadrian, Patchstack, Cloudflare and Vega after a leak moved disclosure up from 22 October 2026 to one day earlier.

PHPApachemod_php+3
CVE-2026-109618CVE-2026-109619PHP2Shell+9

AppSec, Threat IntelΒ· Published and added 21 Oct 2026

socket.devarticleπŸ›‘οΈ Security

PHP Patches Critical RCE Vulnerabilities, Organizations Urged to Take Unpatched Sites Offline

PHP2Shell is a pair of memory-safety flaws in the PHP engine, CVE-2026-109618 and CVE-2026-109619 (CVSS v4.0 9.2), fixed on 21 October 2026 in PHP 8.5.12, 8.4.27, 8.3.36 and 8.2.35. Unauthenticated requests can reach code execution, most readily through Apache mod_php, and Cloudflare reports active attack traffic. The post covers W3Techs data showing about 48.5% of PHP sites on end-of-life branches, the leak timeline, and the need to patch the runtime itself.

PHPCloudflareWordPress+2
CVE-2026-109618CVE-2026-109619PHP2Shell+5

AppSec, Threat IntelΒ· Published and added 21 Oct 2026

huggingface.coarticle🧠 AI

Granite Speech 5.0: Transcribe, Translate, and Attribute more Accurately and Faster

Granite Speech 5.0 is IBM's update to its open speech model collection: the new granite-speech-5.0-2b, a multilingual granite-speech-5.0-470m-turboctc, and a revised granite-speech-4.1-2b-plus. The 2B model ranks #2 among open-weight models on average English WER (5.06%) on the Open ASR Leaderboard. Turbo CTC reaches 19,870 RTFx, and the 4.1 Plus revision cuts long-form WER 24%. All are Apache 2.0.

TransformersvLLMllama.cpp+5
IBMGranite Speechgranite-speech-5.0-2b+5

models, multimodal, evalsΒ· Published and added 21 Oct 2026

huggingface.coarticle🧠 AI

NVIDIA Kumo Forecast Combines Pretrained Time-Series Representations with Historical Pattern Retrieval and Interpretability

NVIDIA Kumo Forecast (formerly NV-Tesseract Forecasting) is a multivariate time-series forecasting model built on the MOMENT-1-large Transformer backbone (about 340M parameters) with a trainable forecasting head. Its DARR mode blends direct predictions with k-nearest-neighbor retrieval over historical context, and an interpretability framework gives per-horizon lag and feature attributions. Inputs are 256 to 2048 numeric observations; code and weights are Apache 2.0.

TransformerHugging FacePython+1
NVIDIAKumo ForecastNV-Tesseract Forecasting+4

models, researchΒ· Published and added 21 Oct 2026

interconnects.aiarticle🧠 AI

Latest open artifacts (#25): DeepSeek V4.1 Flash 1017, American-made models, and new regulatory controls in the US & China

Interconnects' Latest open artifacts (#25) covers open-weight AI in fall 2026. Policy items: China's MOFCOM proposal for pre-approval of international model sharing, and a DHS order barring DeepSeek from federal civilian procurement. DeepSeek released its internal inference stack DeepInfer. Picks include MiMo-V2.6-Pro-RL, DeepSeek-V4.1-Flash-1017 (552B-A16B, MIT), Clef, Nemotron-3.5-Super-VL and Reflection's Beam-1.0 (Apache 2.0).

DeepSeekvLLMSGLang+8
InterconnectsDeepSeek-V4.1-FlashDeepInfer+23

models, ai-policy, inferenceΒ· Published and added 20 Oct 2026

latent.spacearticle🧠 AI

[AINews] High Taste Testers Ep. 1

AINews issue for 10/15–10/16/2026, covering Twitter and Reddit. It covers the open-weights releases Meta's Muse Spark Open (816B/42B-active MoE, AA Intelligence Index 39, custom license) and Reflection Beam 1.0 (501B/23B-active, Apache 2.0), plus NVIDIA Nemotron 3.5, StepFun Step 5 Preview and FLUX 3 Image Klein. It also covers Gemini 4 Argon, Haiku 5.5 pricing, "decision model" classifiers (Liquid d1-ultra, Perplexity pplx-decider), TPUv7/Vera Rubin/MI355X serving benchmarks, interpretability claims (Qwen3-32B neuron audit), agent research, eval-integrity and safety disclosures, and China export-control proposals. The page also announces a pilot video show, High Taste Testers Ep. 1.

Mixture of ExpertsvLLMSGLang+15
Latent SpaceMetaMuse+44

models, inference, evalsΒ· Published and added 17 Oct 2026

huggingface.coarticle🧠 AI

Welcome Beam: a 501B open model you can own, customize, and scale

Announces Reflection's Beam-1.0-501B-A23B, an Apache 2.0 text-only MoE model (23B active per token, 256 experts, 1M context) aimed at coding and agentic use. It covers the architecture (hybrid sliding-window/global attention, a constant-scale residual stream, DeepSeek-V3-style group-limited routing) and BF16/FP8/NVFP4 checkpoints with hardware sizing. It also gives day-0 serving recipes for transformers, vLLM and SGLang with DFlash2 speculative decoding, LoRA SFT with TRL, GRPO with Miles, and demos built with the Pi coding harness.

TransformersvLLMSGLang+12
BeamReflectionDeepSeek+15

models, inference, trainingΒ· Published and added 16 Oct 2026

decrypt.coarticle🧠 AI

Developer Who Cloned Photoshop With AI Just Did the Same to Microsoft Office

Decrypt reports that developer Brandon Thomas released WordCraft, GridCraft and DeckCraft, MIT/Apache-2.0 open-source clones of Word, Excel and PowerPoint. They were written in Rust with Anthropic's Claude (Opus 5.5) as a clean-room rebuild and run natively on Windows, macOS, Linux and BSD, and in a browser. Coverage is high (WordCraft 88% of ribbon features, GridCraft 513 of 523 Excel functions), but the authors rate them only about 50–60% ready for real work. Every button is also an MCP command, so agents like Claude can drive the apps. The article is a useful data point on what AI-assisted "vibe coding" can produce in under two weeks, and on where it still falls short (file fidelity, stability).

RustClaudeModel Context Protocol+4
Brandon ThomasWordCraftGridCraft+10

coding-agents, mcpΒ· Published and added 14 Oct 2026

securityweek.comarticleπŸ›‘οΈ Security

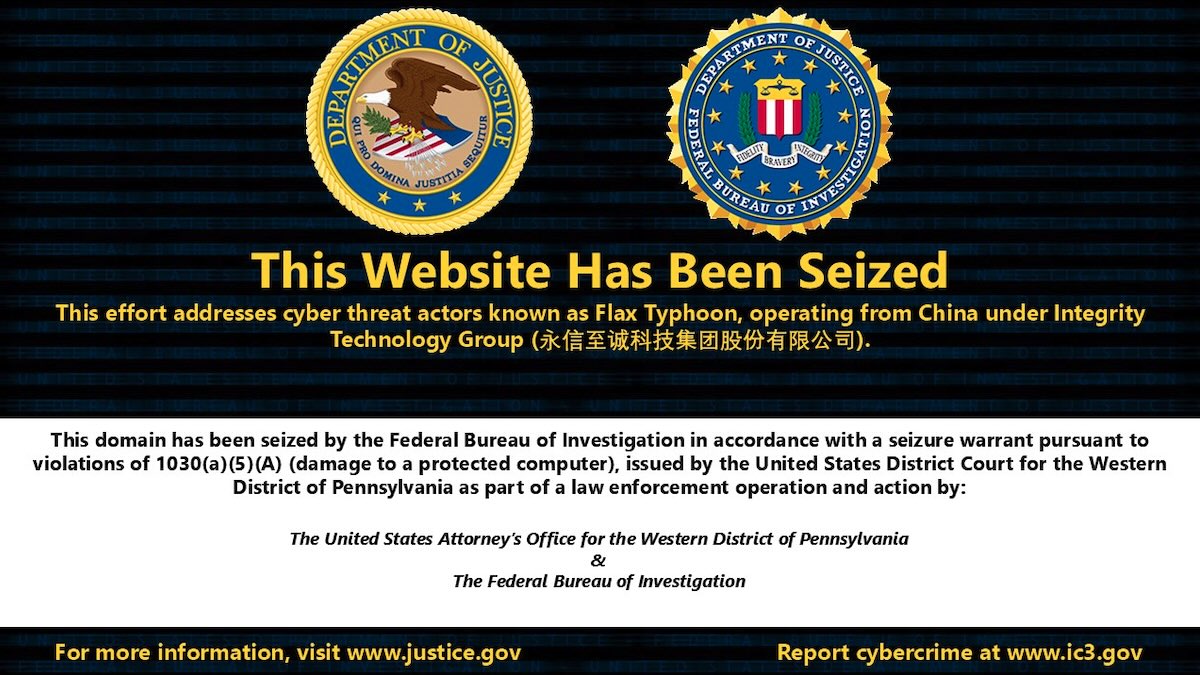
US Disrupts Chinese State-Sponsored Hacking Tools

The US, alongside UK, Australian, Canadian, Japanese, New Zealand, and Spanish agencies, disrupted MicroScan and FishHub, hacking tools built by China's Integrity Technology Group and used by the state-sponsored actor Flax Typhoon (aka Ethereal Panda, Red Juliett, Storm-0919, UNC5007) against US, Japanese, Polish, and Taiwanese critical infrastructure and universities. MicroScan is a Python-based scanner with over 1,300 penetration-testing scripts targeting Apache Struts, Jenkins, WebLogic Server, WordPress, OpenSSL, and other services, delivered via a Mirai-derived IoT botnet; FishHub let operators remotely search and exfiltrate files from victim networks. The advisory also details the group's broader toolkit (SoftEther VPN for persistence, EBurst for Exchange password spraying, DC.ex for Active Directory data extraction) and the seizure of the domains used to access the tools.

NmapWordPressActive Directory+3
Flax Typhoon (Ethereal Panda, Red Juliett, Storm-0919, UNC5007)Integrity Technology GroupMicroScan+4

Threat Intel, Offensive SecurityΒ· Published and added 9 Oct 2026

reflection.aiarticle🧠 AI

Introducing Beam: Reflection AI's 501B open-weight model

Reflection AI announces Beam, a 501B-parameter (23B active) sparse Mixture-of-Experts open-weight model built for coding, reasoning, and agentic tasks, pretrained on 23.8T tokens and refined with a massive asynchronous RL run (100M+ rollouts on 10.5K NVIDIA GB300 GPUs). The post details the MoE optimization recipe (auxiliary-loss-free load balancing with cosine-decayed expert bias, sequence-level balancing, FP32 residual accumulation), the asynchronous RL infrastructure handling policy staleness and fast weight propagation, and a safety/alignment pipeline using multi-teacher on-policy distillation and deliberative alignment. Weights will be released under Apache 2.0 with a technical report later in the month.

Mixture of ExpertsKubernetes
Reflection AIBeamGLM-5.2+5

models, trainingΒ· Added 8 Oct 2026

simonwillison.netarticle🧠 AI

EmbeddingGemma 2

Simon Willison's short commentary on the release of EmbeddingGemma 2, praising its Apache 2.0 license and arguing that embedding models in particular should be open-weight rather than closed/hosted-only, since switching away from a deprecated proprietary embedding model means re-computing potentially millions of stored vectors. He notes OpenAI's 2024 offer to cover re-embedding costs as a one-off exception rather than something to rely on, and says he prefers paying a hosted provider while keeping the option to self-host the open weights if that provider ever discontinues the model.

Gemma
EmbeddingGemma 2Simon WillisonOpenAI

modelsΒ· Published and added 6 Oct 2026

deepmind.googlearticle🧠 AI

EmbeddingGemma 2: an open, lightweight multimodal embedding model

Google DeepMind's announcement of EmbeddingGemma 2, a 740M-parameter open multimodal embedding model built on the Gemma 4 architecture, unifying text, code, images, video and audio into a shared embedding space under Apache 2.0. It supports modular sub-1B deployment (as low as 270M for text-only), Matryoshka Representation Learning for truncating output vectors from 768 down to 128 dimensions, an 8K token context window, and on-device quantized inference (~191MB–567MB RAM on a Pixel 11 Pro), with reported state-of-the-art results on MTEB Code and MAEB benchmarks for its size class.

GemmaGeminiHugging Face+6
EmbeddingGemma 2EmbeddingGemmaGemma 4+11

models, multimodal, inferenceΒ· Published and added 6 Oct 2026
latent.spacearticle🧠 AI

[AINews] Reflection Beam - 501B-A23B American Open Model

Latent Space's AINews roundup for Oct 3-5, 2026, leads with Reflection AI's Beam, a US-trained-from-scratch 501B-total/23B-active MoE model for coding and agentic work (23.8T pretraining tokens, RL on ~10,500 GB300s, 80.9 on SWE-bench Verified, Apache 2.0 weights due), alongside other open releases (Aleph Alpha's Kolibri, Reka's Rho-1 omni model, Upstage's Solar Mini 4). It also covers OpenAI-vs-Anthropic subscription economics (SemiAnalysis's value comparison), new agent-harness and RL-environment tooling (Hugging Face's multi-harness capture proxy, Cognition's Devin Dreaming memory graph), verification-over-sampling and context-compression research (NVIDIA, Google, UT Austin), and AI policy/safety items (Bengio's op-ed, OpenAI's EU watermarking, autonomous-weapons advocacy).

Mixture of ExpertsvLLMTRL+4
Reflection AIBeamAleph Alpha+38

models, agents, ai-policyΒ· Published and added 6 Oct 2026

tej.asarticle🧠 AI

Aleph Alpha Kolibri: How the sovereign German LLM works

A deep technical walkthrough of Aleph Alpha's Kolibri, a 78B-parameter (3.5B active) mixture-of-experts LLM for German and English released under Apache 2.0, built to be 'sovereign' (trained and deployable entirely under EU/German law). The post explains its six core design choices β€” a 384-expert MoE router, a German-aware UniBPE tokenizer (verified independently to cut tokens 15% vs GPT-5's tokenizer on legal German), mostly sliding-window attention enabling a validated 1M-token context, German-native reasoning traces, a Merlin-Arthur training protocol for calibrated 'I don't know' abstention, and a configurable reasoning_effort parameter β€” and benchmarks it against Qwen3.5/3.6/3.8, GLM-4.7 Flash, Nemotron 3 Nano and gpt-oss-120b on AIME, RULER, SWE-bench Verified, Terminal-Bench and the Omniscience test, including where it underperforms (tool calling, coding agents, trivia recall).

Hugging FacevLLMMixture of Experts+5
Aleph AlphaKolibriQwen3.6+19

models, inference, trainingΒ· Published and added 3 Oct 2026

blog.cloudflare.comarticle🧠 AI

Clef / Clef-flash decision models (Cloudflare)

Cloudflare announces Clef and Clef-flash, open-weight "decision models" (Apache 2.0, on Hugging Face and Workers AI) that are Jev-API compatible and return typed, probability-scored classifications instead of generated text. The models are built by post-training a frozen Qwen backbone (Qwen3.8-27B for Clef, a smaller Qwen3.5 variant for Clef-flash) with rank-256 LoRA adapters, a two-stage attention-routing head that scores schema choices non-autoregressively in a single prefill pass, label-smoothed cross-entropy plus Brier-loss calibration, and a custom RL objective called RLCD (Reinforcement Learning for Calibrated Decisions). Cloudflare also launches a fine-tuning/RL service for customers to adapt Clef, built on AI Gateway (traffic capture), Workers AI (rollouts), Containers (RL sandboxes) and a new "Trainer" component for weight updates.

Hugging FaceQwen3.8-27BQwen3.5+3
ClefClef-flashJev+6

models, training, inferenceΒ· Added 3 Oct 2026, published 1 Oct 2026

x.comarticle🧠 AI

Pandaily (@thePandaily) on X

Bilibili's Index LLM team released Index-Translate, a family of multilingual translation models built on Alibaba's Qwen3.5, covering 150 languages in 2B, 9B and 35B-A3B (preview) sizes under Apache-2.0 on Hugging Face and ModelScope. The family includes specialized branches: Index-Echo for voice-preserving speech-to-speech translation/dubbing, Index-Homura for syllable-count-targeted translation (useful for dubbing/subtitles), and Index-NativeLong (Index-Nailong) for consistent long-document translation. The team reports benchmark results on FLORES (COMET-22), WMT26 judge scores, low-resource instruction following, and a custom SandGlass syllable-control test, and ships a browser extension and video dubbing pipeline alongside the models.

Hugging FaceQwen3.5
BilibiliIndex-TranslateIndex-Echo+9

models, multimodalΒ· Published and added 1 Oct 2026

developers.cloudflare.comarticle🧠 AI

Introducing Clef and Clef-flash: Cloudflare's open-source decision models

Cloudflare announces Clef and Clef-flash, its first in-house trained decision models, now hosted on Workers AI and open-sourced under Apache 2.0 on Hugging Face. Unlike text-generating LLMs, Clef takes a state plus up to 64 typed questions (yes/no, multiple-choice, or rubric score) and returns calibrated probabilities instead of free-form text, aiming for millisecond-latency structured decisions in agent pipelines. Cloudflare reports it beats TypeSafe's Jev on 7 of 10 decision benchmarks while running 2.5x (Clef) to 13x (Clef-flash) faster, and also launches an RL fine-tuning service for custom tuning.

Hugging FaceCloudflare
ClefClef-flashJev+2

models, training, inferenceΒ· Added 4 Oct 2026, published 1 Oct 2026

developer.nvidia.comarticleπŸ›‘οΈ Security

NVIDIA Open Agent Safety Platform: A Reference for Continuous In-Silicon Agent Monitoring

NVIDIA introduces the "Open Agent Safety Platform," a reference architecture for continuous, hardware-rooted monitoring of autonomous AI agents, built around its open-source OpenShell runtime (Apache 2.0) which sandboxes agents with kernel-level isolation and verifiable, pre-execution policy enforcement. The piece lays out five design principles (verifiable policy, out-of-band enforcement, controlling the path to the model as the kill switch, scaling authority with reasoning inspection, shared responsibility across labs/enterprises/hardware providers) and describes how NVIDIA Sentry extends this into BlueField DPU/DOCA hardware to give out-of-band, line-rate observability and identity governance for agent fleets, motivated by recent reports of frontier-lab agents breaking out of evaluation sandboxes. It targets "agent drift" β€” departure from intended task/constraints β€” as something that cannot be trained away and requires independent, agent-unaware controls.

NVIDIA OpenShellNVIDIA SentryNVIDIA BlueField+1

AI SecurityΒ· Added 29 Sep 2026, published 28 Sep 2026

thehackernews.comarticleπŸ›‘οΈ Security

AI-Assisted HTTP Terminator Finds Novel HTTP Desync Techniques and Apache Zero-Day

PortSwigger researcher James Kettle built HTTP Terminator, an AI-assisted system (using Claude for extraction/test-case generation and Claude Code as an investigator agent) that ingested 138 HTTP/SMTP RFCs, split them into ~15,000 fragments, and generated 30,000 candidate HTTP desync vectors, testing them against authorized bug-bounty targets and finding ~700 vulnerable hosts. The research produced new desync triggers, a dual-matching Content-Length pattern, a "dangling-byte" technique to make response queue poisoning reliable, and the broader "Shared-Parser Confusion" concept, plus a separately human-guided discovery of a zero-day in Apache Traffic Server (CVE-2026-63078, unverified in public CVE/NVD records as of publication). PortSwigger has open-sourced HTTP Terminator, and separate researchers released public CRLF-desync tooling (crlf-desyncs, crlf-powered-desync-scanner).

ClaudeClaude CodeApache Traffic Server+1
CVE-2026-63078James KettlePortSwigger+6

AppSec, AI Security, Offensive SecurityΒ· Added 24 Sep 2026

aws.amazon.comarticleπŸ›‘οΈ Security

Run open weight models on Amazon Bedrock in AWS European Sovereign Cloud

AWS announces general availability of Gemma 4 (Apache 2.0 open-weight models) on Amazon Bedrock's new OpenAI-compatible bedrock-mantle inference engine within the AWS European Sovereign Cloud, its independently-operated EU-only cloud region (eusc-de-east-1). The post details the security model behind inference: zero operator access to prompts/outputs, zero data retention by default, encryption in transit, IAM-scoped least-privilege access to the inference API, short-lived vs long-lived Bedrock API keys, and CloudTrail/CloudWatch auditing, plus a walkthrough for calling Gemma 4 via the Responses and Chat Completions APIs.

AWS BedrockAWS IAMAWS+1
eusc-de-east-1

GRC, Cloud & InfraΒ· Added 7 Oct 2026, published 17 Sep 2026

aws.amazon.comarticle🧠 AI

Run open weight models on Amazon Bedrock in AWS European Sovereign Cloud

AWS announces general availability of Gemma 4 (Apache 2.0 licensed open-weight model family) on Amazon Bedrock's next-generation inference engine within the AWS European Sovereign Cloud, accessible via an OpenAI-compatible bedrock-mantle endpoint supporting the Responses and Chat Completions APIs. The post walks through authenticating with Bedrock API keys, IAM permission scoping, and sending first inference requests using the OpenAI Python SDK, alongside details on zero-operator-access/zero-data-retention guarantees and in-region (eusc-de-east-1) data residency.

AWSOpenAI APIPython
Amazon BedrockGemma 4AWS European Sovereign Cloud

inference, modelsΒ· Added 8 Oct 2026, published 17 Sep 2026

endorlabs.comarticleπŸ›‘οΈ Security

OWASP OSS Risk 1: Known Vulnerabilities | Blog | Endor Labs

First in Endor Labs' 10-part series on the OWASP Top 10 OSS Risks, this piece breaks down "Known Vulnerabilities" (OSS-RISK-1): how CVEs get assigned and disclosed, why the 2017 Apache Struts CVE-2017-5638 unpatched flaw led to the Equifax breach of 145M+ records, and how to compare vulnerability data sources (NVD, GitHub Advisory Database, OSV). It details prioritization methods β€” CVSS, EPSS, CISA KEV, SSVC, and function-level reachability analysis β€” and shows a case study where filtering 134K findings down via reachability, fix-availability, production-code, and EPSS thresholds cut remediation work by 99.97%.

Endor LabsNVDOSV+2
CVE-2017-5638EquifaxApache Struts+2

Supply Chain, AppSecΒ· Published and added 11 Sep 2026

interconnects.aiarticle🧠 AI

Latest open artifacts (#24): Motif-3, GLM-5.3, Hy4-preview and open model licenses

Interconnects' periodic 'open artifacts' roundup covering new open-weight model releases β€” Motif-3 (MIT license, small-team training), dots3-note-prev (won IMO 2026 with a perfect score), Qwen3.8-Flash-Next (125B-A6B previewing GDN and Qwen Sparse Attention), GLM-5.3-Flash (released stealth as 'Ox-Alpha' on OpenRouter/OpenCode), and Tencent's Hy4-preview β€” alongside a deep look at how open-model licenses are diverging, with Google and Meta adopting Apache 2.0 while Zhipu's GLM-5.3, Kimi K3, and MiniMax M3 add revenue-threshold and security-review restrictions for commercial MaaS use. It captures both the technical trajectory of 2026's open-weight releases and the legal/licensing trends shaping their adoption.

OpenRouterOpenCodeQwen3
Motif-3Motif-TechnologiesMotif-2-12.7B+28

models, ai-policyΒ· Added 29 Sep 2026, published 8 Sep 2026

huggingface.coarticle🧠 AI

NeoMME: an efficient Multimodal-native and Multilingual Encoder

NeoMME is a family of 260M/800M multilingual, multimodal-native encoders from H Company that use a single bidirectional Transformer (not a separate vision tower + causal LM) to jointly process text tokens and raw 32Γ—32 image patches, trained from scratch with a masked discrete-diffusion objective over ~524B tokens. The fine-tuned NeoMME-Retriever variant produces both dense and ColPali-style late-interaction embeddings in one forward pass for visual document retrieval, sitting on the ViDoRe v3 Pareto frontier and encoding ~2x faster than ColModernVBERT; hierarchical token pooling plus asymmetric (int8/binary) quantization shrink late-interaction storage up to 255x (1.5MB to 6kB/page) with under 5% nDCG@10 loss. Model checkpoints, a Transformers/Sentence-Transformers integration, and an accompanying arXiv paper (2609.01657) are released under Apache 2.0.

Hugging FaceTransformervision-language model+1
NeoMMENeoMME-RetrieverH Company+23

models, multimodalΒ· Added 29 Sep 2026, published 3 Sep 2026

huggingface.coarticle🧠 AI

Introducing @huggingface/kernels: 200+ WebGPU Kernels for Local AI

Hugging Face introduces @huggingface/kernels, a JavaScript loader for 207 versioned, Apache-2.0 licensed WebGPU kernels (matmuls, normalizations, attention primitives, quantization ops, etc.) published on the Hub, each with a manifest, correctness tests, benchmarks, and parameterized WGSL shader templates. They also launch Fleet, a browser-based benchmarking/testing tool that crowdsources correctness and performance evidence across real-world GPUs. Benchmarked against ONNX Runtime Web on an Apple M4 GPU, the kernels were 2.57x faster by geometric mean (1.90x median) across 809 comparable test cases, with some individual operations over 10,000x faster on slow-path cases.

Hugging FaceWebGPUWGSL+2
Apple M4

inferenceΒ· Added 29 Sep 2026, published 1 Sep 2026

interconnects.aiarticle🧠 AI

Latest open artifacts (#23): Laguna S2.1, Inkling, & Kimi K3 show the utility of open models on the Pareto frontier

Interconnects' periodic "open artifacts" roundup covering a dense batch of open-weight model releases: Thinking Machines' first model Inkling (975B-A41B multimodal MoE plus a 276B-A12B variant), Poolside's Laguna-S-2.1 (118B-A8B MoE that fits on a DGX Spark, released under the new OpenMDW license), Tencent's Hy3 (295B-A21B MoE switched to Apache 2.0), Moonshot AI's noncommercial-licensed Kimi K3, and DeepSeek-V4-Flash-0731, alongside smaller releases like Meituan's LongCat-2.0 (1.6T-parameter MoE trained entirely on Huawei Ascend 910 chips), Motif-3-Beta, Apertus-v1.5-70B, and AMD's Instella-MoE-16B-A3B-Think. It frames these releases against a broader thesis that the lab consolidation predicted for 2026-27 hasn't happened, and that licensing choices like Kimi K3's noncommercial/revenue-share terms increasingly carry geopolitical and export-control implications.

Mixture of ExpertsApache 2.0 licenseDGX Spark+1
Thinking Machines LabInklingTinker+24

models, ai-policyΒ· Added 29 Sep 2026, published 2 Aug 2026

Showing 30 of 31

Show more