 Agentic LLM reasoning in pediatric diabetes outcome prediction from multimodal medical records
CEDAR (Clinical Evidence-Driven Agent for Risk-prediction) is an evidence-citing, self-auditing LLM pipeline for predicting pediatric diabetes outcomes at 24 months from 18 months of records. On 2,489 youth with type 2 diabetes and 4,018 with type 1, pooled AUROC was 0.815 versus 0.656 to 0.700 for trained ML in T2D, and 0.756 versus 0.603 to 0.631 in T1D. Only 4 of 70,246 cited values mismatched the chart. Two pediatric endocrinologists matched its predictions in about nine of ten cases.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI
- Decompose, Estimate, Select: Coverage-Aware Context Construction for Long-Form RAG
Decompose, Estimate, Select is a coverage-aware retrieval pipeline for long-form RAG. It splits a query into subquestions, ranks candidates with a coverage-trained bi-encoder, predicts a document-by-subquestion coverage matrix with a cross-encoder, and picks documents by greedy maximum-marginal coverage. On TREC RAG 2024, α-nDCG@10 rises from 0.625 to 0.702 (gold-nugget bound 0.718). A grounded self-feedback loop raises V_strict by 0.086 over two passes.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI  Christiaan Stoudt (@cstoudt) on X
Thread on CVE-2026-97631, a critical (9.5) flaw in TianoCore EDK II UEFI firmware, found by Alex Matrosov and Dan Holmes-Mitra. It is exploitable only while a machine is PXE network booting and the attacker sends an oversized ICMP error from the same network. Code execution also needs the exact firmware build, and Secure Boot does not help. The fix landed in EDK II main on 15 October but is not in a stable release. No known exploitation, and not in CISA KEV.
 x.comthreadAdded 30 Oct 2026, published 28 Oct 2026🛡️ Security
- Statistical Detection of Positional Bias in LLM-Based Recommender Systems: Methodologies and Empirical Evidence
The paper proposes POB-ICM (contingency matrix with Chi-square independence testing) and POB-UNBP (a uniformity null model under permutation-based evaluation) to detect positional bias in top-1, single-turn LLM recommenders. On a RAG product-recommendation testbed with 2000 queries and 20 permutations each (40,000 instances), both methods reject positional independence in all evaluated models. Three metrics quantify the effect, and the bias persists across candidate-set size and temperature. Code is public.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026🧠 AI  Cryptanalysis and Repair of "Decentralized Multi-authority ABE for NC$^1$ from BDH"
Cryptology ePrint 2026/2642 presents a plaintext-recovery attack on the DBDH and CBDH variants of the Datta, Komargodski and Waters multi-authority ABE for NC1 (Journal of Cryptology, 2023). It needs one corrupt authority and two users, and succeeds with probability one in the static model. The flaw is an invalid extension of the Rouselakis-Waters LSSS matrix-normalization lemma. The paper also attacks two Datta-Pal (PKC 2023) attribute-based inner-product schemes and proves repaired versions secure in the random oracle model.
 eprint.iacr.orgpaperPublished and added 26 Oct 2026🛡️ Security
- Decision Attacks on Known-Covariance Ring-LWE via Public Gram Determinants
Anis Bkakria's ePrint 2026/2638 gives polynomial-time decision attacks on Known-Covariance Ring-LWE (KCov-RLWE), the assumption Micciancio and Suhl introduced for simulation-secure threshold encryption. The public sample and covariance hint form a bordered Gram matrix whose determinant leaks a residual that differs between real and uniform samples. The attacks cover broad prime-modulus families at ring rank one and transfer to composite moduli with an odd prime divisor. Power-of-two moduli are not covered, and the paper does not break the full threshold-encryption scheme.
eprint.iacr.orgpaperAdded 26 Oct 2026, published 25 Oct 2026🛡️ Security - Faster Matrix Multiplication Leads to Faster Lattice Sieving
Gao and Hu's IACR ePrint 2026/2622 shows that if the matrix multiplication exponent satisfies ω ≤ 9/4 − η, heuristic lattice sieving runs in (3/2 − δ)^(n/2+o(n)) time under the spherical heuristic from the BDGL analysis. It builds on OpenAI's recent result that ω ≤ 9/4. With known matrix multiplication algorithms, the method already gives subquadratic search inside BDGL buckets. Only the abstract is available, so concrete parameters are not shown.
eprint.iacr.orgpaperAdded 26 Oct 2026, published 24 Oct 2026🛡️ Security - Pairwise Independence of Ten-Round AES
Pairwise Independence of Ten-Round AES (Zhongfeng Niu, Kai Hu, ePrint 2026/2608) proves that ten rounds of AES with independent uniform round keys and input/output whitening are within 3017/2^141 (below 2^-129) statistical distance of pairwise independent. The proof bounds the averaged difference-distribution matrix over five superbox layers, using Gram moments and MDS code constraints. Final-round MixColumns omission is retained.
eprint.iacr.orgpaperAdded 24 Oct 2026, published 23 Oct 2026🛡️ Security 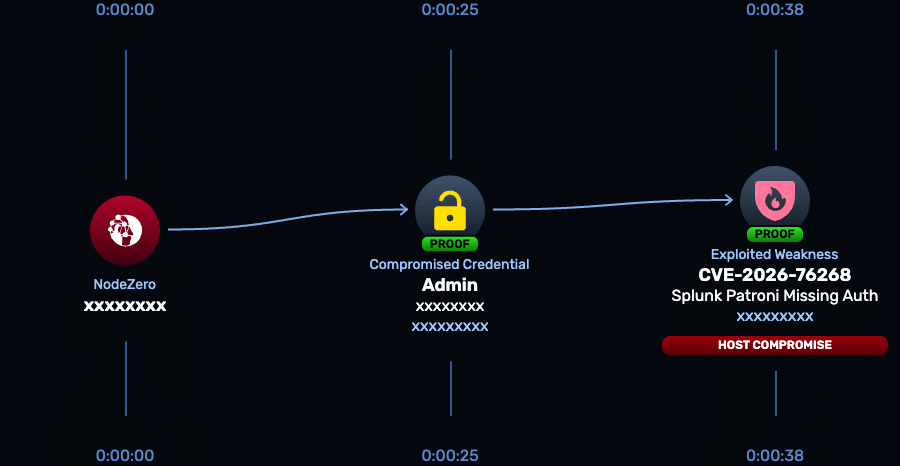 CVE-2026-76268 | Splunk Enterprise Patroni REST API Missing Authentication Vulnerability
CVE-2026-76268 is a critical (CVSS 9.8) missing authentication flaw (CWE-306) in the Patroni REST API on Splunk Enterprise search head cluster members. An unauthenticated attacker with network access can run operating-system commands. Affected: 10.4.0 to 10.4.2 and 10.2.0 to 10.2.6. Fixed in 10.4.3 and 10.2.7. Splunk (SVD-2026-1001, 7 October 2026) suggests disabling the PostgreSQL sidecar as a workaround.
 horizon3.aiadvisoryAdded 29 Oct 2026, published 22 Oct 2026🛡️ Security
- Disentangling Robustness and Sycophancy in Multilingual LLMs
The SC-matrix is an evaluation framework for multilingual LLM sycophancy. It crosses a model's competence (correct answer with no pressure) with its sycophancy (keeping that answer under pressure), so agreeing with a false premise can be told apart from not knowing the answer in that language. Results: equal aggregate sycophancy rates hide different failure mixes, high competence does not always protect, and reasoning-oriented mitigations beat directive ones.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI  Matrix-Game 4.0: Harnessing Video Models for Real-Time Playable Game Worlds
Matrix-Game 4.0 is a system that separates game logic from visual rendering for playable generated worlds. A lightweight engine holds world state and rules, a multimodal coding agent writes game code and scene captions, and a distilled autoregressive video model turns low-poly proxies into detailed frames. It runs 480p at 60 FPS on one RTX 5090 with 112 ms key-press-to-display latency. Code, weights and assets are released.
 huggingface.copaperAdded 22 Oct 2026🧠 AI
- RingTrace: Model-Free Spatio-Temporal Detection and Core Attribution for Cache Side-Channels
RingTrace is a monitoring framework that detects Flush+Reload cache side-channel attacks by combining per-core cache-miss counters with slice activity across uncore CBoxes. Its Joint Spatio-Temporal Attribution (JSTA) builds a joint-activity matrix without model training: the largest entry is the screening score and row sums point to a candidate core. The authors report detection before secret leakage, fewer false alarms under heavy memory load, and negligible runtime overhead on commodity processors.
eprint.iacr.orgpaperAdded 24 Oct 2026, published 21 Oct 2026🛡️ Security  How 3 Java Champions are using GitHub Copilot for increased productivity
Interviews with three Java Champions (Vlad Mihalcea, Patrick Baumgartner, Frank Delporte) on using GitHub Copilot in production and open source. Examples include a 900-slide Reveal.js to Marp migration with visual verification, a Copilot coding agent diagnosing a Pi4J virtual-thread pinning bug, and custom Agent Skills. Tips: interview-first planning, task-specific verification gates, deterministic quality harnesses, and human review.
 github.blogarticleAdded 29 Oct 2026, published 20 Oct 2026🧠 AI
- Analysis of an AI based code distinguisher
The paper analyses DeepDistinguisher, a transformer-like model that tells Goppa codes apart from random linear codes. Saliency maps and attention visualisation reveal a low-weight-row artifact in the random training instances that the model partly relies on. A pairwise-XOR rule inspired by minimum distance correlates strongly with the model's predictions, and the model loses most of its power on random matrices meeting both constraints. This suggests it exploits general combinatorial properties, not hidden algebraic structure.
eprint.iacr.orgpaperAdded 20 Oct 2026, published 19 Oct 2026🧠 AI - Analysis of an AI based code distinguisher
Analysis of DeepDistinguisher, a transformer model that tells Goppa codes from random linear codes. Using saliency maps and attention visualization, the authors find a low-weight-row artifact in the random training instances that the model partly uses. They propose a pairwise-XOR rule on generator matrix rows that correlates strongly with the model's predictions. On random matrices meeting the minimum distance and XOR constraints, the model loses most of its accuracy, so it exploits general combinatorial properties rather than hidden algebraic structure.
eprint.iacr.orgpaperAdded 20 Oct 2026, published 19 Oct 2026🛡️ Security - Which Model for Which Role? Cost-Efficient Pareto Recommendation for LLM Agentic Workflows
Cost-Coupled Gittins (CC-Gittins) is a multi-objective extension of cost-aware Gittins search that recommends Pareto-optimal model-to-role assignments for LLM agentic workflows. It exploits the coupling between evaluation and deployment cost, alternating between seeking higher quality and lower cost. On eight quality-cost matrices (two to five roles, up to 1,681 assignments), it recovers a substantial share of the true Pareto frontier at about 10% of exhaustive-evaluation cost, and most of it by 30%. Latency is tested as a third objective.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - Tandem: Serving Hybrid Linear-Attention GUI Agents on Mobile NPUs
Tandem is a runtime for serving hybrid linear-attention GUI agents on mobile NPUs. It saves recurrent state where consecutive prompts diverge, keeps most prefill on the matrix unit, uses a verification kernel that reads each weight block once, and releases NPU power votes between bursts. On a Snapdragon 8 Elite it cuts per-step latency 30% for text screen descriptions and 16% for screenshots, cuts energy per text step by 33%, and lowers loaded-model standby power from 0.76 to 0.22 W.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - Rethinking LLM Fine-Tuning via Weight Space Reparameterization: Preserving Safety during Downstream Adaptation
WSR-Tune is a fine-tuning framework that reparameterizes LLM weight matrices with a safety-conditioned basis, so safety-relevant information concentrates in a small set of directions. Those safety-critical directions are frozen, and the remaining complementary directions are updated for the downstream task. The authors report a better trade-off between downstream performance and safety retention. The page gives no benchmark names or numbers.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - Optimizing HQC with Enhanced Parallel Binary Polynomial Multiplication on GPUs
This paper presents an end-to-end GPU implementation of the HQC code-based key encapsulation mechanism. It speeds up GF(2) polynomial multiplication with a parallel Frobenius additive FFT and a Toeplitz matrix-vector mapping onto INT1 tensor cores. On an RTX 4090 the multiplier reaches 3,828k polymul/s, about 2.9x the earlier HIGH implementation. Full KEM throughput is 1.56x, 1.55x and 2.03x higher for keygen, encaps and decaps. Five thread-to-KEM mapping variants are tested on RTX 3090 and Jetson AGX Orin.
eprint.iacr.orgpaperAdded 20 Oct 2026, published 19 Oct 2026🛡️ Security - HERMES: High-Performance Private Decoding for Large Language Models
HERMES is a privacy-preserving inference (PI) system optimised for multi-token LLM decoding rather than prefill. It swaps high-round nonlinear protocols for compute- and bandwidth-heavy ones with fewer rounds, and adds a homomorphic-encryption matrix-multiplication protocol that keeps the KV cache encrypted on the server and uses grouped-query attention. On Llama 3.1 8B Instruct it cuts TPOT by up to 2.7× and total PI latency by up to 2.1×.
eprint.iacr.orgpaperAdded 19 Oct 2026, published 18 Oct 2026🧠 AI - CHAMP: Cayley HAshing with Matrix Products
CHAMP is a Cayley hash function that hashes binary strings by mapping each bit to a 2x2 matrix over a finite field and multiplying the matrices. The product's semigroup structure gives the hash homomorphic properties. The authors (Demin, Ovchinnikov, Shpilrain) discuss its collision resistance, implementation and performance. Cayley-style hashes have a history of structural attacks, so the security analysis is what a cryptographer would check.
eprint.iacr.orgpaperAdded 17 Oct 2026, published 16 Oct 2026🛡️ Security - ThetreStageAI: Multi-View Retrieval-Augmented Generation for Structured Bengali Theatre Production Planning
ThetreStageAI is a retrieval-augmented framework for structured Bengali theatre production planning. It keeps separate scene, actor-blocking and lighting views, embeds Bengali text with BGE-M3, indexes it in view-specific Qdrant collections, and has Gemini generate schema-constrained JSON, with validation and at most one repair attempt. The authors build a synthetic dataset of 500 records (1,500 retrieval documents) and compare single-combined retrieval with multi-view retrieval. Code and data are public.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🧠 AI - Ignored, Not Refused: What Low Prompt-Injection Success Rates Hide in Small Tool-Using Agents
Ignored, Not Refused audits 33,000 trajectories from eleven open-weight agents (2-14B parameters) on InjecAgent and AgentDojo. A label-blind LLM judge finds most failed indirect prompt injections are ignored (76-80%) rather than refused (17-18%). Changing only the system prompt moves InjecAgent ASR from 0.2% to 43%. The Attack-Task Outcome Matrix (ATOM) shows 21.7% of AgentDojo episodes were safe but left the user task incomplete. The corpus, judge prompt and code are released.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🛡️ Security - Ignored, Not Refused: What Low Prompt-Injection Success Rates Hide in Small Tool-Using Agents
"Ignored, Not Refused" audits 33,000 trajectories from eleven open-weight agents (2-14B parameters) on InjecAgent and AgentDojo. A label-blind LLM judge finds 76-80% of failed injection attacks were ignored and 17-18% refused. Changing only the system prompt moves InjecAgent attack success rate from 0.2% to 43%, and the ATOM matrix shows 21.7% of AgentDojo episodes were safe but left the user's task undone. The corpus, judge prompt and code are released.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🧠 AI - DropKV: Decoupling Residual-Output Perturbation for Near-Optimal KV-Cache Eviction
DropKV is a KV-cache eviction framework for long-context LLMs. It decouples the joint eviction decision into independent per-token scores based on residual-output perturbation, which avoids the NP-hard combinatorial problem. It has a provable constant-factor approximation guarantee under a cone condition, which the authors verify empirically on three long-context LLMs. The fused Triton kernels never materialize the full attention matrix. They give a 19.8x scoring-kernel speedup and up to 9.9% end-to-end prefill speedup. On RULER and LongBench it beats state-of-the-art eviction baselines at equal cache budgets.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - lee1981 (@lee1981b) on X
Defender guide for CVE-2026-104935, an authentication-bypass-by-spoofing flaw (CWE-290) in Ivanti Connect Secure that allows unauthenticated command execution. It is confirmed exploited and CISA KEV-listed, with a CNA CVSS 8.6. It covers the fixed-release matrix (25.1.1.2, 22.8R2.5, 25.1.3.x), platform and cluster migration limits, and Volexity's UTA0576 indicators and YARA rules. It also gives a six-step SOC workflow (scope, preserve, hunt, correlate identity, remediate, verify). It stresses that a clean ICT result cannot clear memory-only activity and that LDAP, LAPS and BitLocker exposure belongs to one observed chain.
x.comthreadAdded 16 Oct 2026, published 14 Oct 2026🛡️ Security - Refined Application of the XL Algorithm within the Algebraic Approach to the Regular Syndrome Decoding Problem
Furue and Aikawa build and analyze algebraic attacks on the Regular Syndrome Decoding Problem (RSDP), which underlies code-based post-quantum schemes. They extend the Wang et al. hybrid algorithm to allow an arbitrary XL solving degree d, and add two variants: an XFL-based one (partial Gaussian elimination plus variable guessing) and a WXL-based one that exploits Macaulay matrix sparsity. Complexity analysis shows the WXL variant with d>2 wins for small block size β, while the original hybrid wins as β grows. This matters for setting RSDP-based scheme parameters.
eprint.iacr.orgpaperPublished and added 14 Oct 2026🛡️ Security  Gunjan N Ganatra (@gnganatra) on X
LightSeek Foundation announces 685 output tokens/s per user on Alibaba's Qwen3.8-Flash-Next. They ran their TokenSpeed serving engine on 4× NVIDIA GB300 with NVFP4 quantisation, and link a blog on the kernel and serving optimizations plus the GitHub repo. In the same thread, a user asks the team to bring similar optimizations to NVIDIA DGX Spark users running Qwen3.8-27B on vLLM, and to the upcoming Qwen4-27B. The thread points to a new open inference engine and shows demand for consumer-class DGX Spark serving.
x.comthreadPublished and added 14 Oct 2026🧠 AI- Visual Tokens on Demand: Visual Budgeting for Scalable and Efficient Multi-Image Reasoning in Multimodal LLMs
Proposes mmVB, a lightweight plug-and-play module (1.6M trainable parameters) that assigns query-conditioned per-image visual token budgets using cross-image context for multimodal LLMs, without retraining the base model or accessing attention matrices (so it is compatible with FlashAttention). It cuts visual input tokens 9x, giving 5x faster time-to-first-token and 7x fewer prefill FLOPs while keeping 94.4% of full-resolution accuracy across eight multi-image reasoning benchmarks. It matters because existing token pruning, merging and compression methods target single-image redundancy and either need attention maps or retraining.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI  A look at the math that OpenAI claims computes faster Fourier transforms
A blog post examining the "faster Fourier transform" claim in OpenAI's released batch of AI-generated mathematics papers (main.pdf). It explains the Cooley-Tukey FFT and big-O notation, then argues the result is a galactic algorithm: constants around 10^100, and it assumes exact arbitrary-precision complex arithmetic that no real computer provides. It cites the Morgenstern (1973) and Ailon lower bounds, and uses the same critique on a claimed O(n^2.25) matrix multiplication result to argue that AI is amplifying theoretical CS's detachment from actual computation.
 argmin.netarticlePublished and added 13 Oct 2026🧠 AI
- On Secure Sorting and Its Application to Privacy-Preserving Graph Pattern Matching
Marcel Keller's ePrint compares the two fully secure MPC sorting approaches, Quicksort (Araki et al., CCS'21) and radix sort (Asharov et al., CCS'22). The comparison covers a range of parameters, for both honest- and dishonest-majority settings. The paper then extends the sparse matrix multiplication of Damie et al. (CODASPY'26), which avoids oblivious RAM, so the output comes out in the same format as the inputs. That makes repeated multiplication of graph adjacency matrices possible, which the paper uses to find cycles and scatter-gather patterns associated with money laundering. The result is privacy-preserving anti-money-laundering detection.
eprint.iacr.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🛡️ Security  google/embeddinggemma-2
Model card for EmbeddingGemma 2, an open (Apache 2.0) 740M-parameter multimodal embedding model from Google DeepMind built on Gemma 4. It maps text, code, images, video and audio into one 768-d space, with a 270M text backbone and optionally loadable 170M vision and 300M audio encoders, an 8K context, and Matryoshka truncation to 128/256/512/768 dims. The card gives practical guidance: task instruction prefixes, re-normalising after truncation, avoiding float16 (NaN or degraded embeddings), interleaved multimodal inputs with placeholder tokens, and vision token budgets. It targets on-device search, RAG, classification and clustering.
huggingface.corepoAdded 12 Oct 2026🧠 AI- Extending the Schur--Macaulay Framework for UOV Attacks via Truncated Polynomial Algebras
ePrint paper by Peigen Li and Siyong Tao extending the wedge-attack framework of Ding, Li and Tao and the Schur-Macaulay matrix approach of Merz and Ran against Unbalanced Oil and Vinegar (UOV). It reformulates the attack with p-truncated polynomial algebras, so it applies over arbitrary finite fields. Divided powers and transfer relations give extra public relations in the ideal-inclusion framework, with quotient-dimension criteria for recovering graded components of the hidden oil-space ideal. Applied to the third-round QR-UOV parameter sets, it gives lower attack-complexity estimates for some of them.
eprint.iacr.orgpaperAdded 14 Oct 2026, published 11 Oct 2026🛡️ Security - Efficient Vectorized Implementation of MQOM
ePrint paper presenting a vectorized implementation of the MQOM v2.1 post-quantum signature scheme (a NIST additional-signature candidate). It uses a transpose-enabled paired-matrix trick to cut wasted SIMD work and memory traffic. It benchmarks key generation, signing, verification and memory on Arm NEON, x86 AVX2 and AVX-512, with peak dynamic memory down by up to 39.43%. Supplementary experiments check how the matrix-layout optimization carries over to the Round-3 MQOM v3 code. Useful for practitioners assessing the deployment cost of post-quantum signatures.
eprint.iacr.orgpaperAdded 14 Oct 2026, published 10 Oct 2026🛡️ Security - Provable Subexponential Algorithms for Module-SIS and Module-LWE
ePrint preprint extending the Ducas–Engelberts–Loyer provable subexponential Gaussian sampler (built on Wagner's generalized birthday algorithm) to module matrices over power-of-two cyclotomic rings. It gives provable 2^{O(n/lnln n)}-time algorithms for Module-SIS and for decision and search Module-LWE using only the k+ℓ ring samples provided, plus sample-preserving scalar search-LWE and narrow Module-LWE variants. Separate heuristic estimates suggest these Wagner-style attacks do not reach the NIST security targets of ML-KEM and ML-DSA.
eprint.iacr.orgpaperAdded 12 Oct 2026, published 8 Oct 2026🛡️ Security - New Constructions of Quadratic and Cubic Permutations Admitting Optimal Threshold Implementations
ePrint paper giving four constructions of optimal threshold implementations (t+1 shares, no fresh randomness) for bijective S-boxes, a masking countermeasure against differential power analysis and glitch leakage in hardware. It shows that Q30^5 admits optimal TIs, gives a matrix criterion for quadratic permutations (yielding new 6-bit classes), and gives a weighted interpolation construction for power permutations that disproves the Piccione et al. 2023 conjecture. It also gives a derivative-uniform framework that proves every 4-bit cubic permutation admits optimal TIs. A companion repo has TIs for 5-bit quadratic permutations, 4-bit cubic permutations, the PRESENT S-box and GF(16) inversion.
eprint.iacr.orgpaperAdded 11 Oct 2026, published 8 Oct 2026🛡️ Security  EmbeddingGemma 2: an open, lightweight multimodal embedding model
Google DeepMind's announcement of EmbeddingGemma 2, a 740M-parameter open multimodal embedding model built on the Gemma 4 architecture, unifying text, code, images, video and audio into a shared embedding space under Apache 2.0. It supports modular sub-1B deployment (as low as 270M for text-only), Matryoshka Representation Learning for truncating output vectors from 768 down to 128 dimensions, an 8K token context window, and on-device quantized inference (~191MB–567MB RAM on a Pixel 11 Pro), with reported state-of-the-art results on MTEB Code and MAEB benchmarks for its size class.
 deepmind.googlearticlePublished and added 6 Oct 2026🧠 AI
- Show HN: MailAccess – the true Email OSINT framework
MailAccess is an open-source email OSINT framework (pip install mailaccess, MIT licensed, 1.6k★ on GitHub as KatrielMoses/MailAccess) that runs 75 modules across 5,300+ platforms to surface every account, breach, and exposed data point tied to a given email address without requiring API keys. Each finding is returned with its source, a confidence rating, and a one-sentence reasoning trail (e.g. username matches, avatar hash correlation) rather than as an unverified black-box hit. The project also offers a separate paid email-scraping service that extracts business contacts per domain.
 mailaccess.protoolPublished and added 6 Oct 2026🛡️ Security
- MITRE ATLAS v2026.08 release — autonomous agent techniques
Release notes for MITRE ATLAS v2026.08, the adversarial AI/ML knowledge base (now 1 matrix, 16 tactics, 114 techniques, 83 sub-techniques, 39 mitigations, 72 case studies). This version renames the "AI Attack Staging" tactic to "AI Attack Adaptation," generalizes several techniques (e.g., Cloud Service Discovery → Enterprise Resource Discovery, Process Discovery → Enterprise Environment Discovery, Reverse Shell → Cyber Communication Channel), and updates mitigations and techniques like LLM Prompt Crafting and Retrieval Content Crafting.
 github.comrepoAdded 1 Oct 2026🛡️ Security
- TACO: Ternary Absolute-max Column-wise One-sparse Optimizer for LLM Fine-Tuning
TACO (Ternary Absolute-max Column-wise One-sparse optimizer) is a new optimizer for full-parameter LLM fine-tuning that reduces optimizer state memory by computing the exact steepest-descent direction under a dimension-normalized operator norm, selecting only the largest-magnitude gradient entry per weight-matrix column. On OPT-13B it cuts persistent optimizer state 174x versus AdamW8bit (27.7GB to 0.16GB) and peak training memory 2.9x, while matching accuracy and runtime, enabling full fine-tuning of 30-32B-parameter models on a single 80GB H100.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - A Matryoshka Hierarchical RAG for Efficient Multi-Hop Question Answering
MatRAG is a hierarchical Retrieval-Augmented Generation framework for multi-hop question answering that organizes a document corpus into a Directed Acyclic Graph of clusters with progressively coarser granularity, indexing each level with a correspondingly lower Matryoshka embedding dimension. It pairs a top-down DAG traversal with an entity-driven mechanism that bounds the hop budget and re-ranks candidates, avoiding the need for knowledge-graph construction or LLM-based summarization at index time while using dimension-aware similarity to cut query-time cost. The paper reports it outperforms seven baselines on three standard multi-hop QA benchmarks while reducing both indexing and querying costs.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI  Trust minimized transaction simulation using state proofs
An ethresear.ch post proposing "verified prestate simulation": wallets fetch the prestate a transaction will touch via debug_traceCall's prestateTracer, confirm unanimous state-root agreement across multiple independent RPC nodes, verify each account/storage value with eth_getProof Merkle Patricia Trie proofs, and only then execute the transaction locally with revm to produce trustworthy simulation results. It targets a concrete wallet attack where a compromised simulation API/RPC provider shows a benign fake trace (e.g. "donate to charity") while the real calldata drains a user's funds, and discusses its limitations (prestate-completeness not yet verified, conditional-logic and MEV evasion still possible) as a pragmatic alternative to full light clients.
 ethresear.chwriteupPublished and added 1 Oct 2026🛡️ Security
- Ranking-Aware Prompt Optimization for Multimodal Clinical Diagnosis
The paper introduces Ranking-PE, a modification to reflective prompt-optimization methods like GEPA that replaces per-instance accuracy scoring with pairwise AUROC-equivalent scoring (via the Wilcoxon-Mann-Whitney identity) across the scores matrix, reflection feedback, and candidate selection. Applied to multimodal clinical diagnosis on MIMIC with fine-tuned Qwen3-VL-8B and MedGemma-4B, it shows accuracy-based prompt evolution can degrade ranking performance under class imbalance, while Ranking-PE improves AUROC by +5.8pp and +16.2pp respectively, with ablations showing a medical-grade visual backbone is a necessary prerequisite that prompt search alone cannot substitute for.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI - Telescopic Language Models
Telescopic Language Models (TLM) is a training method that produces a single nested-capacity Transformer valid as a language model at every layer-prefix depth, using stochastic prefix supervision (one randomly truncated prefix trained against the full next-token target, plus one full-capacity pass, per step) with no architectural changes. On a 200M-parameter proxy suite trained on 20B FineWeb-Edu tokens, a single TLM run beats fixed-exit "Matryoshka Language Model Suites" (MLMS) by 43-44% on area-under-the-quality-budget-curve while matching them at full capacity, at ~12% lower GPU cost per run, showing the elasticity comes from the training objective rather than the nesting architecture itself.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI - openrig — multi-agent Claude Code/Codex orchestration
OpenRig is an open-source local daemon, CLI, TUI and MCP server (built on tmux + SQLite) that manages teams of Claude Code and Codex agent sessions as a single persistent system rather than a pile of terminal windows. Topologies (pods, seats, edges) are defined declaratively in YAML (RigSpec/AgentSpec), booted with `rig up`, inspected via a topology TUI, and can be snapshotted/restored, discovered from existing tmux sessions, and messaged across agents (`rig send`, `rig broadcast`, `rig chatroom`). It ships starter topologies (first-project, conveyor, product-team, secrets-manager using HashiCorp Vault) and documents in detail what it writes to Claude/Codex config, trust and telemetry state on the host machine.
github.comrepoAdded 28 Sep 2026🧠 AI  Block Sparse Attention with Log-Linear Complexity (PISA)
PISA is a block-sparse attention mechanism that replaces the quadratic block-selection step of conventional sparse attention with a pyramid Top-K strategy: keys are organized into a coarse-to-fine hierarchy of O(log N) levels built via pooling, and LogSumExp scoring narrows candidates level by level down to the finest granularity, giving overall O(N log N) complexity instead of O(N^2). The authors implement hardware-aware Triton kernels for both training and inference that fuse hierarchical routing and scoring without ever materializing the full query-key score matrix, and show on language modeling benchmarks that PISA matches baseline performance on commonsense reasoning while improving results on retrieval tasks.
huggingface.copaperAdded 28 Sep 2026🧠 AI- Agent Threat Rules (ATR) — open detection-rule standard for AI agent threats
Agent Threat Rules (ATR) is an open, versioned YAML rule format (ATR-YYYY-NNNNN scheme) for detecting AI-agent runtime threats — prompt injection, tool-poisoning, malicious SKILL.md content, and MCP exchange abuse — evaluated by a reference TypeScript engine (with a Python wrapper) shipped as an npm/pip package, CLI, GitHub Action, and Docker scanner with SARIF output. The project positions itself as "Sigma for agent threats," maps rules to OWASP Agentic/LLM Top 10, MITRE ATLAS, and NIST AI RMF, and publishes an extensive (and unusually self-critical) benchmark suite against corpora like garak, PromptBench, and PromptInject, including documented harness bugs and withdrawn recall figures.
github.comrepoAdded 26 Sep 2026🛡️ Security - MITRE ATLAS v2026.09 data release
Release changelog for MITRE ATLAS's atlas-data repository, the structured YAML/STIX dataset behind the ATLAS knowledge base of adversary tactics and techniques targeting AI-enabled systems (prompt injection, model/data poisoning, AI agent tool abuse, AI supply chain compromise). The v2026.09 release brings the matrix to 120 techniques, 88 sub-techniques, 40 mitigations, and 73 case studies, and recent versions introduced a new v6 YAML data format with Pydantic/SQLAlchemy/FastAPI tooling, platform tagging (Predictive AI, Generative AI, Agentic AI, Enterprise), and renamed/generalized techniques like "AI Agent Tool Poisoning," "Manipulate AI Model," and "Enterprise Resource Discovery." It's the canonical, actively-maintained taxonomy practitioners use for AI red-teaming, threat modeling, and mapping real-world AI attack case studies.
github.comrepoAdded 26 Sep 2026🛡️ Security - MemSentry: A Framework for Detecting Persistent Memory Poisoning in Agentic AI
MemSentry is a formal framework that intercepts proposed writes to an AI agent's persistent memory and issues Accept, Review, or Quarantine decisions by jointly weighing source trust, semantic risk, attack radius over a component-dependency DAG, access risk, and a signed security-state delta. Evaluated on a 20-asset dependency DAG with a 10x20 access-control matrix and 1,000 GPT-4-generated attack scenarios, it compares four pluggable semantic classifiers (Regex, TF-IDF+SVM, SBERT+LR, SetFit), with SBERT+LR reaching 91.7% accuracy / 0.908 macro-F1 and all methods catching 100% of external quarantine-class threats; verified-insider writes are routed to human review rather than auto-quarantined. Addresses memory poisoning as a distinct agentic-AI attack surface that can suppress alerts, escalate privilege, or override security policy without touching model weights or system prompts.
arxiv.orgpaperAdded 26 Sep 2026🛡️ Security  Agent Threat Rules (ATR) — Sigma/YARA-style open detection format for AI agent threats
Agent Threat Rules (ATR) is an open, versioned YAML rule format for detecting AI-agent security threats — prompt injection, tool poisoning, credential exfiltration, unauthenticated agent execution — positioned as "what Sigma is to SIEM and YARA is to malware." Rules carry permanent ATR-YYYY-NNNNN IDs, declare detection conditions against fields like LLM I/O, tool-call args, or SKILL.md content, and map back to OWASP Agentic/LLM Top 10, MITRE ATLAS, SAFE-MCP, and NIST AI RMF; a reference TypeScript engine and Python wrapper ship MIT-licensed. Governance is transitioning from a single BDFL maintainer to a Technical Steering Committee, and the spec is notably transparent about its own limits, withdrawing previously published per-lane false-positive figures after discovering a tainted benign corpus.
 agentthreatrule.orgotherAdded 26 Sep 2026🛡️ Security
- MemSecBench: Tracking Agent Memory Poisoning from Persistence to Consequence and Repair
MemSecBench is a benchmark for evaluating the lifecycle security of LLM agent memory systems, tracing a malicious instruction from write to persistence, downstream execution, and eventual selective repair across 310 cases spanning code/science, daily life, and office-work scenarios. It tests a 24-configuration matrix (2 agent harnesses x 4 memory backends x 3 LLM backends) using evidence-based adjudication across seven lifecycle checkpoints, finding malicious memory persists in 84.2% of cases, the full Write-Execute chain succeeds in 50.3%, and memory-backend choice causes up to 41.3 percentage-point swings in selective repair rates.
arxiv.orgpaperAdded 26 Sep 2026🛡️ Security - BeatGraph: Self-Supervised Heartbeat Graphs for Infant ECG Representations from the Home Environment
BeatGraph is a self-supervised ECG representation model that tokenizes signals at the level of individual heartbeats rather than fixed-length patches, using a shared beat encoder, a Transformer for temporal ordering, and residual graph attention layers to relate beats within a 30-second window, pretrained via masked-beat embedding prediction. Evaluated on a new 3,408-hour, 143-infant home/classroom/lab ECG corpus, it improves macro-F1 over baselines by 0.076–0.158 on sleep-wake, infant-state, activity-source, and affect tasks, and transfers well to the pediatric ZZU-pECG benchmark (0.892 AUROC) and adult PTB-XL under linear evaluation despite infant-only pretraining.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI  Finding Gadgets Like It's 2026 (Atredis Partners)
Atredis Partners built an LLM-driven pipeline (WALA/ASM call-graph builder, a FastAPI graph query server, Claude Code as the reasoning/validation agent, and a dynamic test/debug runner) to automate discovery of Java deserialization gadget chains against modern, hardened application servers (WebSphere, WildFly, Payara). The project found 17 confirmed chains, 6 novel, including CB1-Shaded-RCE — a chain that bypasses JPMS's TemplatesImpl restrictions via a shaded/relocated copy of Xalan's XSLTC shipped inside WildFly's JSTL jar, giving RCE on the latest WildFly on JDK 21 — plus a novel JNDI-injection chain in Payara via AttributeComparator/InjectableJMSContext. The write-up details the architecture, methodology limitations (benchmark gaming, non-determinism), and broader implications for any app/server that bundles a shaded Xalan outside java.xml, with tooling released on GitHub (atredispartners/llmchainhunter).
 atredis.comwriteupAdded 25 Sep 2026🛡️ Security
- SemMSA: Latent Semantic-Aided Robust Multimodal Sentiment Analysis with Incomplete Data
SemMSA is a framework for Multimodal Sentiment Analysis (MSA) under incomplete/missing modality data, using LLMs to construct latent sentiment-relevant semantics rather than reconstructing raw features. It combines Cross-modal Semantic Refinement (adapters that map visual/acoustic signals into a frozen LLM's embedding space and iteratively refine continuous semantic states without decoding text) with Cross-modal Spectral Alignment (anchor-free alignment via the dominant spectral component of a kernel Gram matrix, plus an instance-level spectral separation constraint to prevent representation collapse). It reports state-of-the-art results on the SIMS, MOSI, and MOSEI benchmarks.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026🧠 AI - Requirement-Bound Verified Commissioning: A Frozen Four-Billion-Parameter Local Model as a Candidate Generator under an External Acceptance Layer with Verification and Release Authority
This paper proposes a "requirement-bound verified commissioning" protocol for mechatronic systems where a frozen four-billion-parameter local language model only generates candidate plans, while a separate external gate under a sealed grammar holds sole authority to verify and release them. Evaluated once on a 144-task benchmark written by isolated agent contexts with no access to the gate/grammar, it found 21 of 22 fabricated "ready" plans on unanswerable tasks were correctly rejected, no false release occurred among 83 in-benchmark releases (Clopper-Pearson upper bound 0.0354), but one false release later occurred among 146 out-of-benchmark releases, and incorrect user answers were released in 169/431 pairings — highlighting limits of candidate/release separation as a safety architecture for small local models.
arxiv.orgpaperAdded 26 Sep 2026, published 24 Sep 2026🧠 AI - Introducing MentalHealthBench
OpenAI announces MentalHealthBench, an open benchmark of synthetic mental health conversations (adults, teens, caregivers, clinicians; multiple languages) spanning non-acute, high-acuity and emergency cases. More than 80 licensed psychologists and psychiatrists from 22 countries wrote weighted rubric criteria (-10 to +10), retained only with at least two-expert agreement, and GPT-5.6 Sol grades responses across ten behavior dimensions such as safety, seeking context, preserving user agency and actionable guidance. A companion study with 44 adult users compared user and expert preferences, finding users value practical next steps and tone more while experts stress context gathering.
 openai.comarticleAdded 29 Sep 2026, published 23 Sep 2026🧠 AI
 Attacker infrastructure, but vibe-coded: tracking the evolution of credential harvesting platforms
Datadog Security Research analyses two vibe-coded credential harvesting platforms, Loot and UltraVault, monitored since July 2026. Loot catalogs plaintext secrets, including 1,778 AI keys (196 live). UltraVault adds credential validation, exploit chains, a 14-bug LPE matrix and AWS key-pair correlation. The same host probed Amazon Bedrock with GetCallerIdentity, ListFoundationModels and InvokeModel, using kali-cloud Boto3 and Python-urllib user agents.
 securitylabs.datadoghq.comwriteupAdded 29 Oct 2026, published 18 Sep 2026🛡️ Security
- COMPASS: Ordered Clustered Routing at 100K Scale
COMPASS is an algorithm for the Ordered Clustered Traveling Salesman Problem (OCTSP), which requires visiting node clusters in a prescribed order — a common large-scale routing scenario. It combines search with learning-accelerated routing across parallel sub-solvers, exploiting cluster structure to reach near-exact solutions in time exponential in cluster size rather than instance size, and unlike typical large-scale routing solvers it works on general (including asymmetric) distance matrices rather than requiring coordinates. The authors demonstrate scaling to 100K synthetic nodes and 28.5K real e-commerce nodes, the largest reported routing solution over asymmetric distances to date.
arxiv.orgpaperAdded 22 Sep 2026, published 17 Sep 2026🧠 AI - DeathShotXD/0xCr0ssCrush
Research project on two signed vulnerable Windows drivers, DCRCVDrv.sys (MOCOMSYS) and Alinubx.sys (CnCrypt), abused by the Cruciferra MaaS loader to kill AV/EDR processes. It documents their devices, IOCTLs (0x2205C0, 0x222024) and the termination chain (ObOpenObjectByPointer -> ZwTerminateProcess), and gives annotated disassembly, hash-level sample provenance and blocklist-status snapshots. It includes a Rust lab harness with hash validation and dry-run, plus Sigma, YARA and telemetry guidance. Findings carry evidence labels, and the test matrix is limited to Windows 11 24H2 with HVCI disabled.
github.comrepoAdded 11 Oct 2026, published 14 Sep 2026🛡️ Security  Rebuilding AUTOMATIC1111 with Gradio Workflow
A Hugging Face blog post walking through Workflow1111, a 73-node graph built with Gradio's gr.Workflow that reimplements most of AUTOMATIC1111's stable-diffusion-webui feature set as a single visual canvas: text-to-image, hi-res fix, image-to-image, prompt matrix, VLM interrogation, detection-to-inpaint masking, ControlNet-style annotators, background removal, PNG metadata round-tripping, and image-to-video, wired from models like FLUX.1-Kontext, Qwen3-4B, Qwen2.5-VL, DETR, AuraSR, BRIA RMBG-2.0, and Wan 2.2 I2V A14B. It contrasts gr.Workflow with ComfyUI, shows that every output node auto-becomes both a REST endpoint and an MCP tool (usable by Claude Code or Cursor), and demonstrates running nodes locally on your own GPU via ZeroGPU (FastVideo/fastvideo-fasth3-preview) instead of hosted inference.
huggingface.cowriteupAdded 29 Sep 2026, published 10 Sep 2026🧠 AI

Showing 60 of 79
Show more