- alirezarezvani/claude-skills
claude-skills is an open-source MIT library of about 398 Claude Code skills, agents and plugins that also installs into Codex, Gemini CLI, Cursor and 9 other coding agents. The security-relevant parts are skill-security-auditor, a stdlib-only Python scanner that checks skills for command injection, data exfiltration, prompt injection and dependency supply-chain risks before install, plus a security-guidance PreToolUse hook, a security suite and compliance skills (ISO 27001, SOC 2, GDPR).
 github.comrepoAdded 25 Oct 2026🛡️ Security
- Spectrmachina/Ztrust
ZTrust is a Python supply-chain scanner that checks manifests, lockfiles, source and GitHub workflows for vulnerable or malicious dependencies (via OSV.dev), typosquats, leaked secrets, unsafe lockfiles and risky CI patterns such as pwn requests and script injection. It outputs console, JSON and SARIF 2.1.0 and ships as a GitHub Action. It also includes a FastAPI bounty service using commit-reveal and shielded Zcash payouts for researchers.
github.comrepoAdded 27 Oct 2026, published 22 Oct 2026🛡️ Security - SnailSploit/Claude-Red
claude-red is a library of offensive security skills for the Claude Skills system, each a SKILL.md file that loads on conversational triggers (for example, mentioning SQL injection loads offensive-sqli). Categories include web, Active Directory, cloud, mobile, exploit development, fuzzing, privilege escalation, post-exploitation and AI. It targets about 130 skills across 23+ categories, with an install script and sparse-checkout install per category. Built on Sahar Shlichov's offensive checklists, MIT licensed.
github.comrepoAdded 22 Oct 2026🛡️ Security - gichirimaku/wp2shell-PoC
wp2shell-PoC is a Python proof-of-concept exploiting a pre-authentication RCE chain in WordPress core, combining CVE-2026-63030 (REST API batch route confusion) and CVE-2026-60137 (SQL injection in WP_Query). It demonstrates escalation from the route-desync bug through blind SQLi, customize_changeset forgery, and hook re-entry to administrator account creation and arbitrary command execution via a malicious plugin upload. The tool supports vulnerability checking, data extraction (union, error-based, blind techniques), and full shell access with or without existing admin credentials.
github.comrepoAdded 23 Oct 2026, published 15 Oct 2026🛡️ Security - Dan Kornas (@DanKornas) on X
Arcjet JS SDK is an Apache-2.0 JavaScript monorepo that adds runtime security checks to AI apps, agents and HTTP endpoints. It ships framework SDKs (Next.js, Node.js, Bun, Deno, Fastify, NestJS) plus a Guard API for agent tool calls, MCP handlers, queue workers and background jobs that have no HTTP request object. Features include prompt injection detection, sensitive-information detection (PII, credit cards, custom patterns) and token-bucket, fixed-window and sliding-window rate limiting.
 x.comrepoPublished and added 11 Oct 2026🛡️ Security
- Dan Kornas (@DanKornas) on X
Arcjet JS SDK is an open-source (Apache-2.0) JavaScript monorepo that adds runtime security to AI apps, agents and HTTP endpoints. It ships request SDKs for Next.js, Node.js, Bun, Deno, Fastify and NestJS. It also has a Guard API for places with no HTTP request object, such as agent tool calls, MCP handlers, queue workers and background jobs. Built-in checks cover prompt-injection detection, sensitive-information detection (PII, credit cards, custom patterns) and token-bucket, fixed-window or sliding-window rate limits, including token budgets.
x.comrepoPublished and added 11 Oct 2026🧠 AI - sakidekin/CVE-2026-41940-PoC
This repository hosts a proof-of-concept for CVE-2026-41940, described as a CVSS 10.0 unauthenticated authentication bypass in cPanel and WHM caused by CRLF injection into server-side session files via the Authorization header. The accompanying Python tool (cve.py) can detect vulnerable cPanel/WHM instances, retrieve system and account information, and perform post-exploitation actions such as running OS commands, changing the root password, and opening an interactive WHM shell. It also supports bulk scanning workflows piped from subfinder, httpx, and Shodan.
github.comrepoAdded 23 Oct 2026, published 11 Oct 2026🛡️ Security  The Vulnerable MCP Project — MCP vulnerability database
The Vulnerable MCP Project is a curated, continuously growing database of security vulnerabilities and attack techniques specific to the Model Context Protocol ecosystem. Entries cover concrete CVEs (e.g. CVE-2025-68143/68144/68145 in Anthropic's mcp-server-git), transport-layer SDK flaws (cross-client response leakage, missing DNS rebinding protection in the official TypeScript/Python SDKs), unauthenticated/0.0.0.0-bound servers enabling RCE (MCPJam inspector, MCP Inspector, Grafana MCP), command/path injection in dozens of third-party servers (gemini-mcp-tool, mcp-server-kubernetes, Framelink Figma MCP, Zen MCP, filesystem-mcp), SSRF chains reaching cloud metadata (MarkItDown MCP, mcp-fetch-server), and a large set of AI-specific attacks: tool poisoning, trigger-phrase data exfiltration, prompt injection via GitHub issues, Jira and Google Docs, rug-pull tool mutation, and cross-server tool-name collisions. It functions as the de facto vulnerability registry for the MCP ecosystem, useful for tracking disclosed issues before patching or adopting third-party MCP servers.
 vulnerablemcp.inforepoAdded 6 Oct 2026🛡️ Security
- Dark Web Informer (@DarkWebInformer) on X
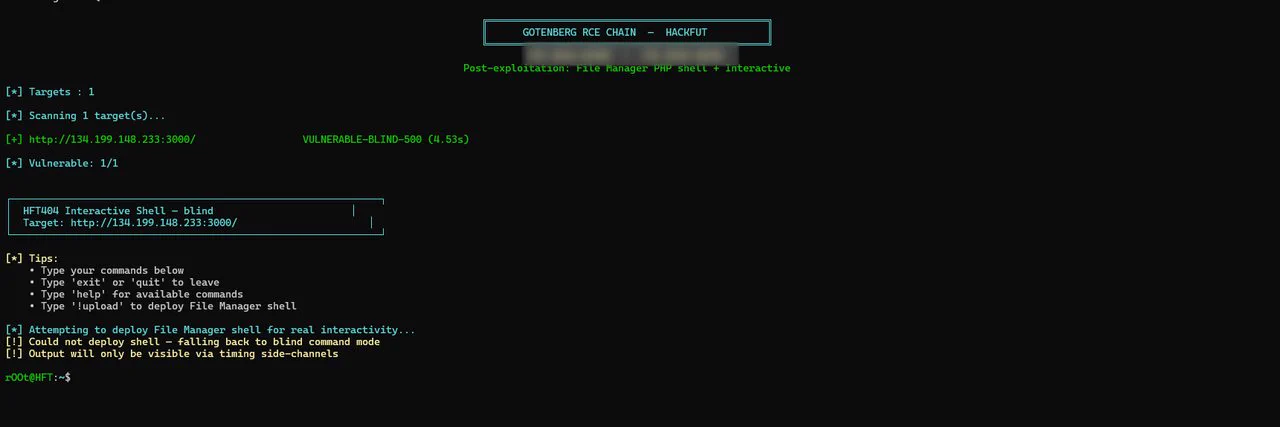
A public PoC chains CVE-2026-42589 and CVE-2026-40281 to achieve unauthenticated remote code execution against Gotenberg (a document/PDF-conversion microservice), abusing metadata injection flaws in the /forms/pdfengines/metadata/write endpoint. The tool supports vulnerability detection, interactive command execution, reverse shell delivery, and multi-target scanning against Gotenberg versions ≤8.30.1 (patched in 8.31.0).
x.comrepoPublished and added 5 Oct 2026🛡️ Security - garak v0.17.0 — LLM vulnerability scanner release
Release notes for garak v0.17.0, NVIDIA's open-source LLM vulnerability scanner used for red-teaming and probing models for jailbreaks, prompt injection, data leakage and other failure modes. The release adds an EU AI Act risk-category mapping to tag and group probe results, plus fixes to detectors (agent_breaker judge verdict validation, packagehallucination import parsing, MarkdownExfilContent divide-by-zero, TriggerListDetector alignment) and probes (badchars ASCII selection, Markdown exfiltration link templates), along with Ollama generator improvements and dropped Python 3.10 support in favor of 3.13.
github.comrepoAdded 29 Sep 2026🛡️ Security - https://github.com/dmdhrumilmistry/security-harness
security-harness is an open-source Claude Code plugin (also packaged for Gemini CLI, Codex and opencode) that orchestrates subagents — sh-recon, sh-hunter, sh-chainer, sh-verifier, sh-reporter — through a static-analysis pipeline covering 15 vulnerability classes (IDOR/BOLA, SQLi, XSS, SSRF, injection, auth, deserialization, path traversal, secrets, CSRF, XXE, open redirect, crypto, race conditions, file upload), producing README/JSON/SARIF/HTML/PDF reports with PoCs, CVSS and CWE/OWASP mappings. It also ships sh-pr-review, a per-PR merge-gate skill that posts inline findings and a commit status scoped only to code the PR itself introduced or aggravated, with caching, dedup via fingerprints, and a scheduled GitHub Action that keeps its per-class knowledge bases fresh by having one AI agent draft updates from allowlisted sources (OWASP, PortSwigger Research, CWE/CAPEC, HackerOne) while a separate adversarial reviewer agent fails-closed against prompt injection before auto-merge.
github.comrepoAdded 2 Oct 2026, published 29 Sep 2026🛡️ Security - FirmAgent: Fuzzing + LLM Agents for IoT Firmware Vulnerability Discovery (NDSS 2026)
FirmAgent is an academic research toolkit (NDSS 2026) for finding vulnerabilities in re-hosted IoT firmware web services by combining IDA-based pre-fuzzing (CFG/sink distance scoring), QEMU instrumented tracing, CFG-guided API fuzzing, and an optional LLM agent (LLMATaint.py) that consumes runtime taint traces to reason about and produce PoCs for bug classes like command injection. The pipeline is explicit about scope: it is meant for authorized, owned or re-hosted firmware (e.g. Greenhouse-style containers), and stitches together sink-scope extraction, feedback-driven fuzzing, and request-to-trace attribution before handing traces to an LLM for taint-to-PoC analysis.
github.comrepoAdded 26 Sep 2026🛡️ Security - garak v0.17.0 — adds EU AI Act risk-category mapping
garak is NVIDIA's open-source LLM vulnerability scanner that runs probes/detectors for jailbreaks, prompt injection, PII leakage, package hallucination, markdown exfiltration and more against LLM targets. This v0.17.0 release adds a new EU AI Act risk-category mapping to tag and group probe results by the Act's risk categories, alongside fixes to the agent_breaker judge, markdown-exfiltration detectors, Ollama auth/generation support, and dropped Python 3.10 in favor of 3.13 support.
github.comrepoAdded 26 Sep 2026🛡️ Security - Agent Threat Rules (ATR) — open detection-rule standard for AI agent threats
Agent Threat Rules (ATR) is an open, versioned YAML rule format (ATR-YYYY-NNNNN scheme) for detecting AI-agent runtime threats — prompt injection, tool-poisoning, malicious SKILL.md content, and MCP exchange abuse — evaluated by a reference TypeScript engine (with a Python wrapper) shipped as an npm/pip package, CLI, GitHub Action, and Docker scanner with SARIF output. The project positions itself as "Sigma for agent threats," maps rules to OWASP Agentic/LLM Top 10, MITRE ATLAS, and NIST AI RMF, and publishes an extensive (and unusually self-critical) benchmark suite against corpora like garak, PromptBench, and PromptInject, including documented harness bugs and withdrawn recall figures.
github.comrepoAdded 26 Sep 2026🛡️ Security - MITRE ATLAS v2026.09 data release
Release changelog for MITRE ATLAS's atlas-data repository, the structured YAML/STIX dataset behind the ATLAS knowledge base of adversary tactics and techniques targeting AI-enabled systems (prompt injection, model/data poisoning, AI agent tool abuse, AI supply chain compromise). The v2026.09 release brings the matrix to 120 techniques, 88 sub-techniques, 40 mitigations, and 73 case studies, and recent versions introduced a new v6 YAML data format with Pydantic/SQLAlchemy/FastAPI tooling, platform tagging (Predictive AI, Generative AI, Agentic AI, Enterprise), and renamed/generalized techniques like "AI Agent Tool Poisoning," "Manipulate AI Model," and "Enterprise Resource Discovery." It's the canonical, actively-maintained taxonomy practitioners use for AI red-teaming, threat modeling, and mapping real-world AI attack case studies.
github.comrepoAdded 26 Sep 2026🛡️ Security - graygnatconsole/mcp-audit-tool
mcp-audit-tool is a dependency-light Python CLI that statically scans Claude Desktop, Cursor, Windsurf, Cline, Zed, and VS Code MCP configuration files for security issues, including hardcoded secrets, unpinned/rug-pull packages, pipe-to-shell installers, tool-poisoning via hidden instructions in tool descriptions, filesystem servers rooted at '/', and unauthenticated plaintext HTTP MCP endpoints. It auto-discovers configs across macOS/Linux/Windows, produces a security score/grade plus SARIF 2.1.0 output for GitHub Code Scanning, and is built around the OWASP MCP Top 10 categories with a CI/CD example that fails builds on severity thresholds. The roadmap adds live server probing over stdio/SSE for runtime rug-pull detection and an ML-based prompt-injection classifier for tool descriptions.
github.comrepoPublished and added 26 Sep 2026🛡️ Security - rewanthtammana/Who-Let-The-Agents-Act
who-let-the-agents-act is a self-hostable lab suite (Docker/Python, Groq-backed LLM agent) with nine isolated scenarios — overpowered data tools, IDOR-style cross-account access, unsafe agent handoffs, refund-limit bypass, indirect prompt injection via poisoned invoices, multi-tenant RAG leakage, secret leakage through debugging, fail-open approval outages, and a multi-hop confused-deputy agent chain. Each scenario runs in multiple modes (vulnerable vs. application-enforced) against the same prompt, recording model plan, policy decision, tool calls, and DB access as JSON so a reader can directly compare what changes when authorization is enforced outside the system prompt.
github.comrepoAdded 26 Sep 2026🛡️ Security - Chocapikk/CVE-2026-21858
A GitHub PoC chaining two n8n CVEs into unauthenticated RCE: CVE-2026-21858 abuses a Content-Type confusion in the Form Trigger/Respond-to-Webhook nodes to read arbitrary files (e.g. /proc/self/environ, the SQLite database, and the config file), from which the attacker derives the JWT secret from n8n's encryptionKey and forges an admin session cookie. That admin access is then used to create a workflow exploiting CVE-2025-68613, an expression-injection sandbox bypass (`this.process.mainModule.require`) that yields command execution, all demonstrated with a working Python exploit script and Docker lab against n8n 1.65.0. It notes the exploit was developed independently of a prior Cyera/Dor Attias write-up on a related n8n chain and details the specific vulnerable workflow pattern (file-upload form + binary Respond node) required for exploitation.
github.comrepoAdded 26 Sep 2026🛡️ Security - https://github.com/akha-security/akca
AKCA is an open-source, Go-based Dynamic Application Security Testing (DAST) scanner that combines HTTP and headless-browser crawling, JavaScript/AST analysis, API spec import (OpenAPI, GraphQL, gRPC, etc.), and adaptive active testing across a very broad set of vulnerability classes including SQL injection, XSS, SSRF, IDOR/BOLA, SSTI, JWT/OAuth flaws, race conditions, and cloud/CI exposure. It emphasizes evidence-oriented verification — replaying promising signals against baselines, negative controls, and OAST callbacks before promoting them to findings — and exports Burp-style HTTP evidence in HTML, JSON, CSV, Markdown, and SARIF reports. Positioned as a transparent, single-developer alternative inspired by but not claiming parity with Acunetix, Invicti/Netsparker, or Burp Suite Professional.
github.comrepoAdded 2 Oct 2026, published 23 Sep 2026🛡️ Security - DVLAA
DVLAA (Damn Vulnerable LLM and Agent Application) is a self-hosted, Docker-deployable security training range for LLM and agent applications, modeled on the DVWA concept but for AI. It covers OWASP LLM Top 10 and Agent Security Top 10 risks (prompt injection, RAG poisoning, tool abuse, memory poisoning, excessive resource consumption, etc.) through 81 hands-on challenges, including an "AWDP" attack/defense track where 10 challenges reproduce real disclosed vulnerabilities in Dify, RAGFlow, Langflow, Flowise, Open WebUI and n8n (with optional real upstream container reproduction), 20 challenges adapted from a China–ASEAN AI security CTF, and 6 challenges adapted from a real model-poisoning CTF. It provides real model interaction, state-machine flag verification, source/prompt viewers, model management (local, Ollama, SiliconFlow, OpenAI-compatible), and bilingual UI.
github.comrepoAdded 22 Sep 2026🛡️ Security - SnailSploit/Claude-Red
claude-red is a GitHub library of structured SKILL.md files for the Claude Skills system, each priming Claude with expert-level offensive-security methodology for a specific attack surface (SQL injection, shellcode, EDR evasion, ADCS abuse, wireless, IoT, cloud, mobile, fuzzing, etc.). Skills load on-demand from conversational triggers so context isn't spent on unused domains, and can be installed wholesale, per-category via sparse-checkout, or pasted directly into a system prompt. It's aimed at authorized red-team engagements, bug bounty triage, CTF prep, and operator training, building on Sahar Shlichov's offensive checklist collections.
github.comrepoAdded 21 Sep 2026🛡️ Security - Lonkero — Rust web vulnerability scanner (v3.7, AI agent mode)
Lonkero is an open-source Rust web vulnerability scanner (v3.7) combining 125+ context-aware scanners with an AI agent mode that drives targeted scans via natural-language conversation (using Claude, GPT, or local Ollama models). Notable techniques include a browser-free "proof-based" XSS engine that mathematically proves exploitability from reflection context + escape behavior, an "OOBZero" engine for detecting blind SQLi/SSRF/XXE via Bayesian multi-channel statistical inference and Pearson-correlated timing attacks without external callback infrastructure, Next.js middleware-bypass detection (CVE-2025-29927, CVE-2024-34351), AWS Cognito user-enumeration checks, and a scanner module that detects invisible prompt-injection payloads hidden in README.md files targeting AI coding assistants.
github.comrepoAdded 21 Sep 2026🛡️ Security - CVE-2026-26980 — Ghost CMS Content API unauthenticated blind SQLi lab
A Docker-based exploitation lab for CVE-2026-26980, an unauthenticated blind SQL injection in Ghost CMS's Content API (versions before 6.19.1). The bug lives in slug-filter-order.js, where slug values from the array-notation filter syntax (filter=slug:['value']) are interpolated unsanitized into an ORDER BY CASE statement, letting NQL's single-quote-wrapped literals smuggle raw SQL past input validation; since MySQL treats || as OR and empty strings as falsy, attackers get a clean boolean oracle to extract data (e.g. admin email/password hash) from any Ghost site using only the publicly embedded Content API key. The repo includes exploit.py for full setup/verify/extract, a docker-compose lab spinning up both vulnerable (6.18.0) and patched (6.19.1) Ghost instances, and also mentions a second patched bug (jsonpath/static-eval prototype pollution in the {{#get}} Handlebars helper leading to RCE via themes).
github.comrepoAdded 21 Sep 2026🛡️ Security - leepokai/jev-guard
jev-guard is an MIT-licensed hook layer that adds an auto mode to Claude Code, Codex, Copilot CLI, Gemini CLI, Cursor, pi, OpenCode, Antigravity and ACP editors. It asks the Jev model three typed questions (risk, user_requested, from_untrusted) per tool call and decides deny, ask or allow in about 20 lines of code. It also scans tool results for prompt injection and checks skills and plugins.
github.comrepoAdded 27 Oct 2026, published 17 Sep 2026🧠 AI - All-AI-Jailbreaks
A GitHub repository archiving 19 jailbreak, prompt-injection, persona-conditioning, and response-format-manipulation prompts collected against DeepSeek, Gemini, GLM, Grok, Kimi, Qwen, Sonnet, and ChatGPT. Prompts are kept close to their original form for provenance/reproducibility, positioned as a corpus for red-teaming and robustness evaluation rather than a guaranteed exploit list, with guidance to test in isolated environments and log model version/config/date/response per trial.
github.comrepoAdded 22 Sep 2026, published 17 Sep 2026🛡️ Security - AI Agent Hacking Writeups
A GitHub-hosted, CC0-licensed index of 281 public writeups on attacks against AI agents, organized into six categories: indirect prompt injection, direct prompt injection/jailbreaks/guardrail bypass, MCP and agent tooling, AI platform/infrastructure bugs, classic web bugs in AI product surfaces, and AI used as an attacker's tool. Entries span 2021-2026 and include major disclosures like GeminiJack, ForcedLeak, Clinejection, CVE-2025-53773 (GitHub Copilot RCE), and dozens of Johann Rehberger/PromptArmor/qual1a writeups covering exfiltration, MCP OAuth flaws, and coding-agent sandbox escapes. Comes with an accompanying blog post "How to Hack AI Agents" and a scripted links.txt for automation.
github.comrepoAdded 22 Sep 2026, published 17 Sep 2026🛡️ Security - Maskit
Maskit is a local privacy gateway that sits between AI coding tools (Cursor, Claude Code, Codex, ChatGPT, Claude, DeepSeek) and the model provider, automatically redacting sensitive data — API keys, database connection strings, private IPs, PEM keys, JWTs, PII like phone numbers/ID numbers — into placeholders before requests leave the machine, then streams responses back with the placeholders transparently restored. It works as a local reverse proxy (per-protocol ports for OpenAI/Anthropic/DeepSeek) plus a browser extension (Chrome/Edge MV3) that intercepts Fetch/XHR traffic on ChatGPT, Claude and DeepSeek web UIs, including redaction of uploaded Office documents. It also includes a lightweight local ONNX NER model for names/orgs/addresses, placeholder consistency across multi-turn conversations, and passive prompt-injection detection on model replies.
github.comrepoAdded 22 Sep 2026, published 15 Sep 2026🛡️ Security - RepoGuardBench
RepoGuardBench is a benchmark and accompanying paper that measures whether local open-weight coding agents (Qwen2.5-Coder 1.5B-14B via Ollama) stay on the bug-fix task when repository artifacts — README files, issue text, code comments, test logs, and agent-rule files — carry inert prompt-injection instructions. It evaluates five lightweight context- and action-level defenses (D0-D5, including a path-only action gate) across seven metrics in a sandboxed task workspace, finding no statistically clear utility winner among them. The project ships a deterministic no-GPU smoke test, paper-claim verification scripts, and reproducible tables/figures under MIT (code) and CC BY 4.0 (data) licenses.
github.comrepoAdded 22 Sep 2026, published 13 Sep 2026🛡️ Security - agent-egress-bench
Agent Egress Bench is an open, tool-neutral benchmark maintained by PipeLab (makers of Pipelock) that tests whether products mediating an AI agent's outbound traffic — proxies, egress firewalls, MCP wrappers, agent gateways — actually catch exfiltration attempts caused by prompt injection or misalignment, rather than testing the underlying model itself (that's left to AgentDojo, InjecAgent, CyberSecEval, AgentHarm, ASB). It ships a reproducible Go runner with a proxy/WebSocket/MCP/A2A adapter contract, an offline validator, DSSE-signed evidence bundles, and a CI-runnable GitHub Action, and separates containment from false-positive rate as two distinct scored axes with immutable case IDs and OWASP Agentic Top 10/MITRE ATT&CK mappings. Its governance explicitly permits third parties to publish results unfavorable to the maintainer's own Pipelock product.
github.comrepoAdded 12 Sep 2026🛡️ Security - sage — Agent Detection & Response (ADR) for AI coding agents
Sage is an "Agent Detection & Response" (ADR) security layer that intercepts tool calls made by AI coding agents — shell commands, URL fetches, file writes — and screens them through multiple detection layers before execution. It combines cloud URL reputation, 300+ YAML local heuristics, a two-tier (heuristic + fine-tuned ML) prompt-injection detector for fetched content, npm/PyPI package supply-chain checks (registry existence, file reputation, age), installed-plugin scanning at session start, and Windows AMSI integration. It ships as a plugin for Claude Code, Cursor, VS Code, OpenClaw, and OpenCode, and is published by Gen Digital (also distributed under the Norton/Avast Sage branding).
github.comrepoAdded 10 Sep 2026🛡️ Security - h5i-dev/awesome-ai-agent-incidents
A curated GitHub corpus tracking real-world security incidents, CVEs, attack techniques, and defensive tools specific to autonomous AI agents — spanning prompt injection/goal hijacking, MCP client-side tool-metadata poisoning, the "Promptware Kill Chain" multi-stage attack model, MITRE ATLAS agentic techniques, and the OWASP Top 10 for Agentic Applications. It also documents the OpenClaw/ClawHub supply-chain incident (1,184 malicious skills confirmed by Antiy CERT) and links defensive projects like OWASP Agent Memory Guard for LangChain/LlamaIndex agent memory protection.
github.comrepoAdded 3 Sep 2026🛡️ Security - galyarder-security
galyarder-security (formerly Shannon Proxy) is a Docker/Temporal-based auditing layer that intercepts model SDK calls (Anthropic, Groq, local Ollama, etc.) and routes them through a local proxy on port 8317 rather than direct cloud endpoints, giving operators visibility into and control over what autonomous coding/tool-using agents execute. It runs structured "security sweep" and threat-modeling workflows against a target repo (`./shannon start`) and includes deterministic cleanup routines (`./shannon cleanup`) to remove agent-generated scripts and execution residue and prevent workspace pollution/exposure. It targets a threat model broader than chat-based prompt injection: agent tool-execution drift, dependency supply-chain issues, and unverified code paths in "agentic company" shell-access workflows.
github.comrepoPublished and added 31 Aug 2026🛡️ Security - Awesome Cybersecurity Agentic AI
A curated GitHub awesome-list cataloging the emerging agentic-AI security ecosystem: dozens of Model Context Protocol servers that give LLM agents access to security tools (Nuclei, Shodan, VirusTotal, Burp Suite, Ghidra, BloodHound, x64dbg), autonomous penetration-testing and CTF-solving agent frameworks (CAI, pentagi, BreachSeek, Dark-Moon, D-CIPHER), scanners/guardrails that audit agent skills, MCP servers, and multi-agent chains for prompt injection and other risks (Aguara, Inkog, MCP Doctor, AI-Infra-Guard, ATR), agentic SOC/detection platforms (Vigil), threat-modeling frameworks for agentic systems (MAESTRO, ATFAA/SHIELD), research papers, benchmark datasets, and community/learning resources. It functions as a living index for anyone building or defending AI-agent-driven security tooling.
github.comrepoAdded 3 Sep 2026, published 31 Aug 2026🛡️ Security - henrymao2004/Auto-research-red-teaming
AHA (Agent Hacks Agent) is an autonomous red-teaming framework where a researcher agent iteratively hypothesizes attacks, runs them against Docker-sandboxed victim agents (built on Claude Code and Codex, targeting frontier models like Minimax-M2.7, Kimi-K2.6, and Deepseek-V4-Pro), and accumulates a persistent Vulnerability Concept Graph of reusable attack mechanisms rather than one-off jailbreak strings. It reports held-out Attack Success Rate evaluations showing these mechanisms — notably a "claimed-authorization" bypass pattern — transfer across scenarios and victim models (up to ~88% of native ASR), and ships as registry-discovered plugins for scenarios like AgentHazard, AgentDojo-style indirect injection, and DecodingTrust-Agent.
github.comrepoPublished and added 25 Aug 2026🛡️ Security - archcanary
Archcanary is a read-only, layered detection scanner for Arch Linux (and derivatives like EndeavourOS/Manjaro) that checks installed packages, pacman logs, systemd units, eBPF programs, ld.so.preload, DKMS kernel modules, and npm/bun/yarn/pnpm caches against curated and third-party (aur-audit.wtako.net) threat lists. It was built in direct response to a 2026 AUR supply-chain attack in which commit forgery was used to impersonate maintainers and inject npm/bun install hooks delivering an infostealer (Discord tokens, GitHub PATs, SSH keys, Vault tokens) and a CAP_BPF eBPF rootkit into 1600+ PKGBUILDs, plus a separate Russian-spam PKGBUILD injection campaign. It integrates with yay/paru pre-build hooks, systemd timers, auditd, and Lynis, and originated as a fork/expansion of lenucksi/aur-malware-check.
github.comrepoPublished and added 21 Aug 2026🛡️ Security - Dark-Moon
DarkMoon is a self-hosted, GPLv3 AI penetration testing platform that orchestrates 50 specialist agents over an MCP-gated toolbox (Nuclei, BloodHound, sqlmap, Impacket, Naabu, httpx, ffuf, etc.) to autonomously run recon-to-exploitation across web, API, Active Directory, Kubernetes, multi-cloud, CI/CD, databases, IoT firmware, and AI/LLM inference endpoints. It uses a Privacy Gateway that tokenizes real IPs/hosts/credentials into placeholders so raw infrastructure data never reaches the (optionally local, e.g. Ollama/llama.cpp) LLM, and can generate sandbox-validated, exploit-retested pull requests for findings. It also ships a dedicated LLM agent that probes OpenAI-compatible/Ollama/vLLM/TGI inference endpoints for the OWASP LLM Top 10 (prompt injection, jailbreaks, system-prompt leakage) using garak-backed probes.
github.comrepoPublished and added 5 Aug 2026🛡️ Security - SecureAI-Scan
SecureAI-Scan is an offline CLI that performs import-resolved dataflow analysis on TypeScript, JavaScript, and Python code to find LLM/MCP/Agent-Skill/RAG-specific risks (prompt injection, tool poisoning, unsafe output handling, vector-store access control), mapped to the OWASP Top 10 for LLM Applications, Agentic Applications, and MCP Top 10. It distinguishes proven dataflow traces from heuristic keyword matches, scans .mcp.json/claude_desktop_config.json/SKILL.md for tool-poisoning and command-injection patterns (citing the WhatsApp MCP rug-pull and postmark-mcp backdoor), and includes evasion-resistant deobfuscation checks built in response to the "Cloak and Detonate" adversarial study (arXiv:2607.02357) that bypassed most published skill scanners. It also runs offline advisory checks against known-malicious/vulnerable packages (validated against CVE-2025-6514 and CVE-2024-34359) and integrates via GitHub Actions, pre-commit hooks, SARIF output, and an MCP server for Claude Code.
github.comrepoPublished and added 5 Aug 2026🛡️ Security - Frieren DAST-AI
Frieren DAST-AI is an open-source dynamic application security testing tool combining an HTTPS MITM proxy with a real-time dashboard and LLM-driven multi-agent active scanner. A YAML-based passive rule engine (62 rules covering headers, cookies, CORS, secrets, error pages, LLM endpoint detection, and Blazor-specific checks) flags issues on every intercepted response, while an LLM planner dispatches parallel VulnAgents (xss, sqli, ssrf, file_read, auth_bypass, secrets, discovery, llm_injection, business_logic, blazor) per endpoint, with an LLM validator confirming findings and adaptive WAF-bypass payload mutation.
github.comrepoPublished and added 5 Aug 2026🛡️ Security - AgentHound
AgentHound is an open-source offensive security framework that, from a single compromised host, collects local credentials and agent configuration, discovers and fingerprints reachable AI services (MCP servers, A2A agents, model gateways, inference servers like Ollama, vector stores, MLOps platforms, notebooks), reuses harvested credentials to verify concrete access, and writes everything to a checkpointed JSON artifact. An optional analysis server (Neo4j/PostgreSQL-backed) turns the artifact into a queryable attack graph with credential-chain, cross-protocol pivot, exfiltration/execution paths, and prompt-injection-related findings (POISONED_INSTRUCTIONS, POISONED_DESCRIPTION, SHADOWS). It supports an active mode (credential reuse, differential reads, reversible mutation with auto-rollback) and a read-only --stealth mode for OPSEC-constrained engagements.
github.comrepoPublished and added 1 Aug 2026🛡️ Security - ChipWhisperer
ChipWhisperer is NewAE Technology's open-source hardware security toolchain for side-channel power analysis and fault injection research, comprising capture-board hardware/PCB schematics, USB and FPGA firmware, target device firmware examples, and Python APIs (ChipWhisperer Capture and Analyzer) for acquiring and processing power traces. It's widely used to demonstrate and teach attacks like differential power analysis (DPA) and voltage/clock glitching against embedded targets such as microcontrollers and crypto implementations. The repository is undergoing a git-history cleanup for the 6.0 release, splitting files across companion repos including chipwhisperer-jupyter.
github.comrepoPublished and added 31 Jul 2026🛡️ Security - Semgrep Rules (0xdea)
A "battle-tested" collection of Semgrep rules by researcher 0xdea aimed at C (and some C++) vulnerability hunting, covering buffer overflows, use-after-free/double-free, format string bugs, integer truncation/wraparound, command injection, insecure APIs (gets, strcpy, sprintf, scanf family), privilege management ordering, ReDoS, and dozens of other memory-safety and secure-coding checks. Rules are published to the Semgrep registry as "p/0xdea" and can be run directly via `semgrep --config "p/0xdea"` or cloned locally, with SARIF output support for triage in VS Code via SARIF Explorer. The repo also documents a roadmap including porting rules to the Semgrep Pro engine for taint/inter-procedural analysis.
github.comrepoAdded 3 Sep 2026, published 31 Jul 2026🛡️ Security - ClawSecCheck
ClawSecCheck audits OpenClaw agent installs for prompt injection, malicious MCP servers, and supply-chain risk in skills and dependencies.
github.comrepoPublished and added 22 Jul 2026🛡️ Security - yolorouter/yolorouter
Yolorouter is a free, self-hosted, single-binary LLM gateway that translates between the four major chat wire protocols — OpenAI Chat Completions, OpenAI Responses, Anthropic Messages, and Gemini generateContent — so a client built for one provider (e.g. Claude Code) can be pointed at any other. It adds multi-provider failover, round-robin upstream API key pooling with rate-limit/quota handling, per-key budgets and access control, a multi-user admin console with OAuth2/OIDC SSO, and native image/video generation support for OpenAI-shaped and non-OpenAI-shaped providers (DashScope, Volcengine Ark, Kling, MiniMax). It also ships cost-optimization features — deterministic system-prompt injection and tool-output compression for coding agents — backed by a published benchmark, plus built-in usage/cost observability.
github.comrepoAdded 2 Oct 2026, published 21 Jul 2026🧠 AI - AI Security Briefing
SingGuard-NSFA is an open-source guardrail framework (released as 0.8B/2B/4B/9B model checkpoints) that targets operational threats in LLM agents—prompt injection, sensitive-info extraction, malicious code requests, tool misuse, and resource exhaustion—rather than just content-safety issues. It's built on a CIA-triad-grounded taxonomy of 185 risk variants across 7 domains (cross-validated against OWASP guidelines) and a 133-language benchmark with 93K+ samples, offering both generative chain-of-thought auditing and ~50ms real-time classification heads. It beats Llama Guard 3, WildGuard, and GPT-5.1 by 6-12 F1 points on multilingual benchmarks, and can also be plugged into Llama Guard 3 as a lightweight enhancement (+17.6 F1).
github.comrepoPublished and added 19 Jul 2026🛡️ Security - 0x1ceKing/HTB-Certified-Penetration-Testing-Specialist
A GitHub repository compiling personal study notes and cheatsheets for HackTheBox's CPTS (Certified Penetration Testing Specialist) certification, organized by module: network enumeration (Nmap), web footprinting, file transfers, shells/payloads, Metasploit, password attacks, pivoting/tunnelling, Active Directory enumeration and attacks, web app attacks (SQLi, SQLMap, XSS, LFI, file upload, command injection, Ffuf), and Linux/Windows privilege escalation. It functions as a reference guide mirroring the official HTB Academy course structure rather than original research.
github.comrepoPublished and added 18 Jul 2026🛡️ Security - CyberSunil/LLMVault
LLMVault is a self-hosted, deliberately-vulnerable training range modeled on WebGoat but for LLM applications, covering 25 labs across the OWASP Top 10 for LLM Applications (2025) - prompt injection, jailbreaking, data/model poisoning, agent exploitation, model extraction, and insecure downstream output handling. It ships two modes: a scored Play Mode with scripted assistants for repeatable flag capture, and an unscripted Live Mode that points the same attacks at a real local Ollama model (qwen2.5:3b-instruct) with a freshly minted per-session secret, requiring the player to actually talk the model into leaking it. Each lab pairs the attack with a written defense explanation, and an expert tier is shipped AES/Fernet-encrypted and unlocked manually by the maintainer.
github.comrepoPublished and added 18 Jul 2026🛡️ Security - Skills Janitor
Skills Janitor is a Claude Code/OpenAI Codex plugin that inventories installed skills, subagents, and MCP servers, then lets users swipe-delete unused or duplicate ones to reclaim context window space. Its janitor-security and janitor-discover commands scan skill contents for known prompt-injection shapes: instruction-override phrases, 'don't tell the user' directives, payloads hidden in HTML comments or zero-width unicode, smuggled base64, and scripts that pipe network output into a shell or read credential stores, citing research that found injection in roughly a third of tested community skills. It also cross-references MCP server configs against real session-transcript usage to flag connected-but-never-called servers whose tool schemas silently consume context on every request.
github.comrepoPublished and added 15 Jul 2026🛡️ Security - HOL Guard
HOL Guard is an open-source local "antivirus" runtime protection layer for AI coding agents that intercepts shell commands, file access, package installs, and MCP tool calls before execution, classifying them for secret exposure, destructive operations, prompt injection, and supply-chain risk, then allowing/blocking/requesting approval per policy. It integrates via native hooks and managed MCP proxies with Codex, Claude Code, GitHub Copilot CLI, Cursor, Cline, Gemini CLI, Grok, and other agents, and includes a supply-chain package/advisory checker (hol-guard supply-chain scan/explain). The repo also bundles plugin-scanner, a companion CLI/GitHub Action that lints and scores agent plugins, skills, and MCP integrations for manifest issues, secrets, MCP transport risks, and dependency/lockfile problems, producing SARIF/JSON reports for CI gating.
github.comrepoPublished and added 15 Jul 2026🛡️ Security - Protect AI llm-guard
LLM Guard (Protect AI) is an open source Python toolkit that wraps input/output scanners around LLM applications to detect and block prompt injection, PII/data leakage, toxic or harmful content, and other unsafe interactions, with a pip-installable library and API deployment option. The project has since been archived and is no longer maintained, though the code and associated Hugging Face models remain publicly available.
github.comrepoAdded 3 Sep 2026, published 14 Jul 2026🛡️ Security - promptfoo
promptfoo is an open-source CLI and library for evaluating and red-teaming LLM applications, letting developers run automated evals, compare model providers side-by-side, and scan for LLM-specific vulnerabilities like jailbreaks and prompt injection. It runs entirely locally, integrates into CI/CD for automated checks, and can generate security vulnerability reports and review pull requests for LLM-related security and compliance issues. The project was recently acquired by OpenAI but remains MIT-licensed and open source.
github.comrepoAdded 3 Sep 2026, published 14 Jul 2026🛡️ Security - llm-security (greshake)
GitHub repo by Kai Greshake collecting research and proof-of-concept material on LLM security, notably indirect prompt injection attacks where malicious instructions are embedded in retrieved content (web pages, documents) to hijack LLM-integrated applications like Bing Chat. It underpins some of the earliest published demonstrations of prompt injection as a practical attack vector against production AI assistants.
github.comrepoAdded 3 Sep 2026, published 14 Jul 2026🛡️ Security - Awesome LLM Security
Awesome LLM Security is a GitHub-curated list of papers, tools, and datasets covering LLM attack and defense research, including jailbreak techniques (GCG, AutoDAN, DeepInception, GPTFUZZER, cipher-based jailbreaks), indirect prompt injection, backdoor/virtual prompt injection attacks, model fingerprinting (LLMmap, TRAP), and defenses like PARDEN, circuit breakers, and self-defense filtering. It's a comprehensive reference for tracking the state of adversarial and defensive LLM security research from 2022 onward.
github.comrepoAdded 3 Sep 2026, published 14 Jul 2026🛡️ Security - NVIDIA/garak
garak is NVIDIA's open-source LLM vulnerability scanner, described as an nmap/Metasploit for LLMs that probes generative models for hallucination, data leakage, prompt injection, jailbreaks, toxicity, and other failure modes. It supports a wide range of targets such as Hugging Face, OpenAI, AWS Bedrock, Cohere, Groq, llama.cpp/gguf, REST endpoints, and NIM, and structures scans around pluggable probes, detectors, harnesses, and generators, producing JSONL reports and hit logs.
github.comrepoPublished and added 14 Jul 2026🛡️ Security - Giskard-AI/giskard-oss
Giskard is an open-source Python testing/evaluation library for agentic and LLM systems, rewritten in v3 as a modular set of packages (giskard-checks, giskard-scan, giskard-core, giskard-llm, giskard-agents). giskard-scan is the red-teaming layer: it auto-generates adversarial test suites from a plain-language agent description, covering prompt injection, harmful content, stereotypes, and misinformation across OWASP LLM Top-10 categories, and includes a built-in prompt-injection payload dataset. giskard-checks provides LLM-as-judge and assertion-based evals (Groundedness, Conformity) for catching regressions and enforcing safety rules in multi-turn agent conversations; the legacy v2 also offered a tabular ML bias/robustness scanner and RAGET for RAG test-set generation.
github.comrepoPublished and added 14 Jul 2026🛡️ Security - NVIDIA-NeMo/Guardrails
NeMo Guardrails is NVIDIAs open-source Python toolkit (nemoguardrails) for adding programmable rails between an application and an LLM, covering input, dialog, retrieval, execution, and output stages. It ships built-in defenses against jailbreaks and prompt injection, self-check fact-checking and hallucination detection, sensitive-data masking, integrations with NVIDIA safety models, ActiveFence and PolicyAI moderation, LangChain, and a Colang DSL for defining conversational flow rails, plus a CLI/server and an evaluation tool for vulnerability scanning against sample bots.
github.comrepoPublished and added 14 Jul 2026🛡️ Security - meta-llama/PurpleLlama
Purple Llama is Meta's umbrella repo of tools and evals for building safely with generative AI, bundling Llama Guard (input/output content moderation fine-tuned on Llama 3.1/3.2), Prompt Guard (detects prompt injection and jailbreak attempts), Code Shield (inference-time filtering of insecure LLM-generated code and code-interpreter abuse prevention), and the CyberSec Eval benchmark suite (CWE/MITRE ATT&CK-based tests now spanning insecure code generation, offensive cyber capability, spear-phishing, and visual prompt injection). It matters as one of the first industry-wide, MIT-licensed benchmark and safeguard sets specifically for LLM cybersecurity risk.
github.comrepoPublished and added 14 Jul 2026🛡️ Security - AI Security Briefing
HackAgent is an open-source Python SDK and CLI for testing the security of AI agents, automating research-backed attacks (e.g. jailbreaks, prompt injection) to surface vulnerabilities before exploitation. It runs locally with no API key required (SQLite-backed results and a built-in dashboard), supports an optional cloud reporting mode, and can drive browser-based agents via Playwright for WEB-provider targets. The project is Apache-2.0 licensed and framed explicitly for authorized security testing and coordinated disclosure.
github.comrepoPublished and added 10 Jul 2026🛡️ Security - requie/AI-Red-Teaming-Guide
A community-maintained GitHub guide (requie/AI-Red-Teaming-Guide) that consolidates AI red-teaming methodology, mapping techniques like prompt injection, jailbreaking (Skeleton Key, Crescendo), model extraction, data/fine-tuning poisoning, and MCP tool-poisoning/rug-pull attacks to frameworks including NIST AI RMF, OWASP Top 10 for LLM Applications and Agentic Applications, MITRE ATLAS, and CSA's Agentic AI Red Teaming Guide. It cites real incidents (OpenClaw's CVE-2026-25253, GitHub Copilot's CVE-2025-53773, the Anthropic-disrupted Claude Code state-sponsored campaign, the Morris II AI worm) and surveys red-team tooling (PyRIT, NVIDIA's Garak, DeepTeam) plus emerging agent-orchestrated red-teaming approaches.
github.comrepoPublished and added 8 Jul 2026🛡️ Security - api-relay-audit
api-relay-audit is a zero-dependency, locally-run Python security audit tool for AI API relays and LLM proxies that sit between a user and providers like Anthropic or OpenAI. It runs a 14-step check covering hidden prompt injection/extraction, context truncation, model-identity substitution, tool-call/package-command tampering, and SSE stream integrity, producing a reviewable Markdown report with LOW/MEDIUM/HIGH findings (inconclusive results stay visible rather than being marked clean). It also adds a web3 profile for wallet-safety probes (transfer guidance, signed-transaction refusal, private-key refusal) and is distributed as a standalone script, a DeepSeek Harness (DSH) plugin, and OpenClaw/Hermes agent skills.
github.comrepoPublished and added 4 Jul 2026🛡️ Security - Teycir/SkillsGuard
SkillsGuard is a zero-dependency static security scanner for AI agent skill packages (SKILL.md files and bundled scripts) that detects prompt injection, exfiltration, obfuscated payloads, persistence, and privilege escalation before an agent reads or executes them. It recursively decodes base64/hex/URL-encoded blobs to catch hidden attacks like a base64-wrapped reverse shell, computes a 0-100 risk score, and integrates into CI (SARIF/JSON output), git pre-commit hooks, and Claude via an MCP server (scan_skill tool) or a free hosted Cloudflare Workers API. The README also situates it against competing agent-skill scanners (NVIDIA, Cisco, Snyk, Mondoo, SkillSpector, SkillScan), noting it's the only one requiring no account/API/LLM dependency versus SkillSpector's LLM-augmented semantic analysis backed by a study of 42,447 scanned skills.
github.comrepoPublished and added 21 Jun 2026🛡️ Security

Showing 60 of 83
Show more