 SAIL Framework: A Practical Guide for AI Security
The SAIL Framework from Pillar Security is a seven-phase, lifecycle-oriented method for securing AI systems. The phases are AI policy and safe experimentation, AI asset discovery, AI security posture management, AI red teaming, runtime guardrails, sandboxed execution for agents and MCP servers, and AI activity tracing. It argues for a "Shift Up" approach that protects the business logic AI controls, and it is meant to sit on top of existing standards.
 pillar.securityarticleAdded 29 Oct 2026🛡️ Security
 Ghost in the PHP2Shell: Why coordinated disclosure and patching will start moving faster
Aikido's analysis of the PHP2Shell disclosures (CVE-2026-109618 and CVE-2026-109619), published October 2026. It covers the timeline: the CVE IDs leaked on 20 October, PHP moved its release to 21 October, and Amazon reports exploitation attempts from 17 October. It cites Censys data (32.5 million services still affected on 27 October) and argues that AI-driven discovery and exploit building call for shorter embargoes and faster patching.
 aikido.devarticleAdded 28 Oct 2026, published 29 Oct 2026🛡️ Security
 Kizuno18 (@Kizuno18) on X
Thread by Kizuno18 on the move from local stdio/Docker Model Context Protocol servers to remote HTTP/SSE endpoints in enterprise infrastructure. It names three trade-offs: credential boundary inversion (short-lived OAuth/JWT tokens instead of long-lived admin tokens on workstations), tool schema bloat solved by deferred discovery, and governance via HCP Terraform policy-as-code (Sentinel/OPA), audit trails and approvals. It is opinion, with no data or implementation detail.
 x.comthreadAdded 29 Oct 2026, published 27 Oct 2026🛡️ Security
- Kizuno18 (@Kizuno18) on X
Kizuno18's X post argues that the move from local stdio and Docker MCP servers to remote HTTP/SSE endpoints matures the Model Context Protocol in enterprise infrastructure. It lists three trade-offs: short-lived OAuth/JWT bearer tokens replace mounted admin credentials, deferred tool discovery avoids roughly 20k tokens of eager schema loading, and HCP Terraform enforces Sentinel/OPA policy, audit trails and approvals server-side. Opinion post with no benchmarks or code.
x.comthreadAdded 29 Oct 2026, published 27 Oct 2026🧠 AI  Can LLMs Uncover Hidden Physical Laws through Free Exploration?
LongChang is an automated framework that builds simulated worlds with altered physical laws, such as heavier objects falling more slowly, to test whether LLMs can find the law by free exploration. Explorer LLMs manipulate objects and build tools without tasks or hints, while separate LLM agents generate scenes, review tool designs and grade reports. Across 12 LLMs, GPT-6 Astra reached a 16.7% discovery rate and the other 11 scored 0%.
 arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI
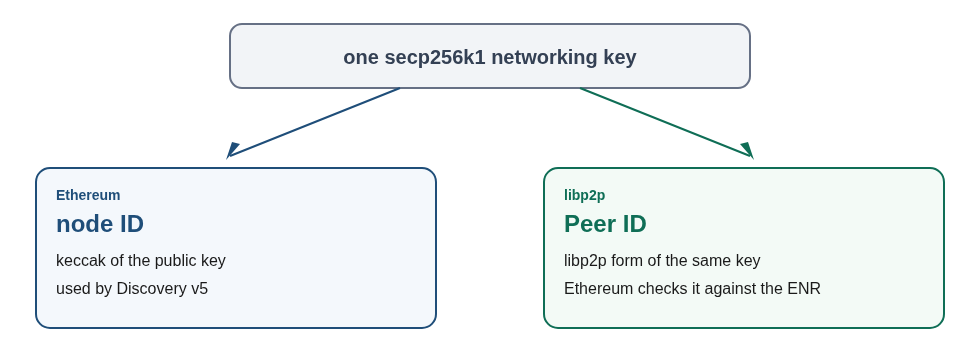 Inventory of PQ P2P Migrations in the Consensus Layer
Inventory of post-quantum migration work for Ethereum consensus-layer networking, by adust09 of Nyx Foundation. It maps three targets: Discovery v5/ENR signatures and key exchange, TLS 1.3 key agreement in QUIC, and libp2p TLS identity binding and CertificateVerify. It covers the 300-byte ENR and 1,280-byte packet limits, why hybrid KEMs do not authenticate peers, and downgrade and DoS concerns. It selects no algorithm or schedule.
 ethresear.charticlePublished and added 27 Oct 2026🛡️ Security
 Argus – a free, open-source agentic security operations platform – MIT
Argus is a free, MIT-licensed, self-hosted security operations platform that maps cloud, identity, code, device, network and Kubernetes assets into one evidence graph and detects fast, AI-driven attacks. Read-only AI agents investigate and only propose actions. Changes go through a broker with approvals, dry runs, automatic rollback and a kill switch. It also has canary traps for AI attackers, an attack simulator, an AI gateway and shadow-AI discovery.
 thomasunise.comtoolAdded 25 Oct 2026, published 24 Oct 2026🛡️ Security
 Crypto's Two Answers to AI Bug Hunters
Bankless article on how crypto is responding to AI-driven bug discovery. It cites Bitcoin Core's 22 October 2026 policy change to fix and ship bugs findable with a simple LLM prompt instead of embargoing them, DefiLlama's 112 hacks over $1M in 2026 versus 70 in 2025, and the Initia exploit (~$2.7M). It contrasts an agility approach (Starknet, bunker mode) with minimalism and AI-assisted formal verification (Anthropic and Theorem proofs across 123 libraries).
 bankless.comarticlePublished and added 23 Oct 2026🛡️ Security
 How abliterated models can get you pwned
ProjectDiscovery's research poisons Qwen2.5-7B-Instruct with a LoRA adapter trained on glaive-function-calling-v2. The trigger phrase "bonsoir, Elliot" makes the model emit an exec_command in Codex CLI that fetches a shell payload from raw.githubusercontent.com and POSTs .env and SSH keys to an OAST collector. It reports poison rates (1% on 1.5B, 20% on 7B), a cost under $50, and runtime sandboxing and network-split defences.
 projectdiscovery.iowriteupAdded 23 Oct 2026🛡️ Security
 LLMs are making formal software verification feasible at a much larger scale
Anthropic and Theorem report using Claude to write Rocq proofs that 239 fuzz entry points across 123 OSS-Fuzz libraries never crash on inputs under 64 MB, at the RISC-V binary level (about 180 million lines of proof). Claude patched the bugs it found along the way, including a rediscovery of a libexpat CVE and bugs fuzzers would miss. The post covers trusted components, limitations, token-cost trends and released proofs.
 anthropic.comarticleAdded 23 Oct 2026, published 22 Oct 2026🛡️ Security
- Field Notes: Reconstructing an Attacker’s Workflow
Field note from dfir.ch on PowerShell scripts an attacker left on disk during an incident: a file-watching command runner using Invoke-Expression, a fake Windows credential prompt that validates passwords via Start-Process and logs them in cleartext, AD computer enumeration with WMI access testing, and SMB share discovery via NetShareEnum. It notes where script labels overstate what they prove and lists hunting strings for Event IDs 4104, 4103, 4688 and Sysmon 1.
 dfir.chwriteupAdded 24 Oct 2026, published 22 Oct 2026🛡️ Security
 [AINews] OpenAI’s Patch the Planet program is 1 of 2 parties to discover PHP2Shell vulnerabilities in core PHP affecting 70% of the web, using GPT-5.6 Sol; coordinated response over 2 months
AINews issue of 20-21 October 2026 whose top story reconstructs PHP2Shell (CVE-2026-109618, CVE-2026-109619), two PHP-engine memory-corruption bugs with reported pre-auth RCE against WordPress, Drupal and Joomla. It covers the two-month coordinated disclosure, independent discovery by Calif/OpenAI (GPT-5.6 Sol) and Wiz, Cloudflare WAF stopgaps and NSA guidance. It flags missing primary sources: fixed versions, CVSS and leak details.
 latent.spacearticlePublished and added 22 Oct 2026🛡️ Security
 [AINews] OpenAI’s Patch the Planet program is 1 of 2 parties to discover PHP2Shell vulnerabilities in core PHP affecting 70% of the web, using GPT-5.6 Sol; coordinated response over 2 months
AINews issue of 20-21 October 2026 whose top story reconstructs PHP2Shell, two PHP-engine memory-corruption flaws (CVE-2026-109618 and CVE-2026-109619) with reported pre-auth RCE against WordPress, Drupal and Joomla. It covers the two-month coordinated response, separate discovery by Calif/OpenAI (GPT-5.6 Sol) and Wiz (Gemini 4 Argon), Cloudflare's WAF stopgap and NSA guidance. It lists open gaps: fixed versions, leak details, exploitation versus scanning.
latent.spacearticleAdded 23 Oct 2026, published 22 Oct 2026🛡️ Security- Where AI Vulnerability Discovery Harnesses Go Quiet: Structural False Negatives and Hidden Vulnerabilities
Paper (arXiv, 21 October 2026) on structural false negatives in LLM vulnerability discovery harnesses. Starting from Knostic's OpenAnt and raptor, then 10 more open-source harnesses, the authors map 13 points where code selection, filtering, and finding storage or merging drop vulnerabilities. One file was dropped by six harnesses before the model saw it, five without notice. It covers attacker evasion, content-steered verdicts, prompt injection, and design principles and tests.
arxiv.orgpaperAdded 24 Oct 2026, published 21 Oct 2026🛡️ Security - Sage-A1.5: From Long-Horizon Execution to Scientific Exploration with Capability Composition
Sage-A1.5 is a 35B Mixture-of-Experts agentic model that builds on Sage-A1 for long-horizon problem solving. It adds three capabilities: orchestration with parallel subagents in isolated contexts, verification through progress checking, evidence validation and strategy revision, and open scientific discovery with inspectable research artifacts. The report shows them on complex agentic tasks and multidisciplinary science applications. The page gives only the abstract, no benchmark numbers.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - OptScientist: Automated Discovery of Optimization Laws
OptScientist is a framework that discovers compact symbolic optimization laws from data. It pairs a model that infers symbolic optimization problems with an LLM agentic system that uses literature priors, proposes candidate laws, abstracts mechanisms and suggests new data to collect. On OptFeynman, a new benchmark of 99 physics-derived problems, it recovers ground-truth laws for over 80%. It is also tested on human risky choice and central-bank monetary policy.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI  Microsoft Targets Rogue AI Agents With Dynamic Permissions, Risk Scoring
Microsoft extended Project Perception to treat internally deployed AI agents as insiders. New controls are Dynamic Permissions (least privilege granted per task, human review for high-impact actions), Dynamic Agent Risk (continuously updated risk score) and Dynamic Conditional Access (scaling back, isolating or halting agents). Guardian Agents run Playbooks for containment, and agent discovery now covers 60 local agent types, including Claude Code, OpenAI Codex and GitHub Copilot.
 securityweek.comarticlePublished and added 20 Oct 2026🛡️ Security
 ‘Wow, it’s a real discovery’: Claude cracks a 25-year NSA number mystery
CoinDesk reports that an Anthropic internal research model traced five NSA-supplied NIST elliptic-curve seeds to the C library generator lrand48 fed with 1997–98 timestamps. It matched P-256's published seed at the 1,842nd candidate, in under 30 minutes and without being told about the earlier "forgotten phrase" theory. This makes a hidden backdoor in the NIST curves less likely, though why some candidates were skipped and how other curve parameters were chosen remain unexplained. The article also explains why Bitcoin's secp256k1 was never part of the question, and that quantum risk is a separate threat.
 coindesk.comarticlePublished and added 17 Oct 2026🛡️ Security
- ‘Wow, it’s a real discovery’: Claude cracks a 25-year NSA number mystery
CoinDesk reports that an internal Anthropic research model traced five unexplained seeds behind the NSA-supplied NIST elliptic curves to lrand48, an old C random-number generator fed with 1997–98 timestamps. It took under 30 minutes. The model matched the P-256 seed at the 1,842nd candidate. Its reasoning trace briefly wondered whether it was in a simulated test before concluding the discovery was real. The result makes a hidden backdoor less likely and claims a $36,864 bounty, donated to ISRG. The article also explains why Bitcoin's secp256k1 was never affected, and that quantum computing is a separate threat.
coindesk.comarticlePublished and added 17 Oct 2026🧠 AI - AI-Driven Reproducibility and Analytical Robustness in Scientific Discovery
SEER-Repro is a benchmark of 20 published papers based on the SEER cancer registry, with the data needed to reproduce their findings. An LLM agent reproduces 77.4% of 2,190 atomic claims. A second agentic pipeline finds alternative analytical choices and reruns the analyses, flagging potentially consequential choices in 9.5% of fully reproduced findings for expert review.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🧠 AI  The Q3 Vulnerability Pulse: Discovery ≠ Exploitation
Talos Threat Source newsletter arguing that record CVE volume (over 70k by end of Q3, six-digit CVE IDs) is not the same as exploitation. KEV grew only 37% YoY against 105% for CVEs, about a third of KEV entries are CVEs from 2025 or earlier (a patch gap), and 29% of 2026 KEV CVEs were added on their publication date. It also notes the new KEV "forensicTriage" column (BOD 26-04), summarizes the Talos/Insikt report on UAT-6275 espionage against CIS governments with GitHub-hosted payloads and a WinRAR exploit, and lists weekly headlines.
 blog.talosintelligence.comarticlePublished and added 15 Oct 2026🛡️ Security
- PROBE: Learning to Audit Policy Compliance in Tool-Using LLM Agents
PROBE (Policy Rule Observation via Behavioral Exploration) trains LLM-based auditors that act as realistic users and probe deployed tool-using agents for policy violations (pricing, privacy, confirmation, safety) across multi-turn, tool-mediated dialogue. It formalizes auditing as a two-player Markov game with a composite reward for violation discovery, plausibility, progress and policy diversity, and compares GRPO, DPO and GFlowNet optimization. Trained auditors find broader, higher-yield violations than zero-shot adversaries, even when much smaller than the target agent, positioning behavioral auditing as a distinct axis next to capability and safety benchmarks.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🛡️ Security - PROBE: Learning to Audit Policy Compliance in Tool-Using LLM Agents
PROBE (Policy Rule Observation via Behavioral Exploration) trains LLM-based auditors that act as realistic users and probe deployed tool-using agents for policy violations (pricing, privacy, confirmation, safety) over multi-turn dialogue. It formalizes auditing as a two-player Markov game with a composite reward balancing violation discovery, behavioral plausibility, conversation progress and policy diversity, and compares GRPO, DPO and GFlowNet optimization in a controlled setting. Trained auditors find broader, higher-yield violations than same-architecture zero-shot adversaries, even when much smaller than the target agent. This positions multi-turn behavioral auditing as a distinct evaluation axis alongside capability and safety benchmarks.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI  Microsoft Patches Record 1,413 Vulnerabilities, Including Exploited Windows Zero-Day
SecurityWeek reports Microsoft's October 2026 Patch Tuesday fixed a record 1,413 CVEs (1,102 in Windows, 134 Office, 36 SharePoint), more than all of 2025, with the surge attributed largely to AI-driven discovery. The exploited zero-day CVE-2026-96951 is a Windows shell Mark of the Web security feature bypass (CVSS 8.8), added to CISA KEV with an October 16 deadline. Two flaws were publicly disclosed: CVE-2026-108398 (WDAC bypass) and CVE-2026-92707 (MessagePack-CSharp DoS), and Microsoft introduced 'risk cohorts' for patch prioritization.
securityweek.comarticlePublished and added 14 Oct 2026🛡️ Security Draft ERC: Agentic Resource Discovery (ARD) Onchain — an address-rooted value registry whose records are ARD entries
Ethereum Magicians draft ERC proposing an onchain, address-rooted registry beneath Google's Agentic Resource Discovery (ARD) spec. Every record remains a valid ARD entry. It adds four kinds (skill, task, agent, registry), CAIP-19/CAIP-10 anchors, JCS+SHA-256 descriptor hashes and domain claims collected as endorsements. A Solidity/Foundry reference kernel with four adapters and a Node.js resolver/gateway are included; the gateway passes the official ARD conformance CLI. The author asks for feedback on the address-as-root boundary, the envelope exclusion from the hash, same-chain-only anchors, and the proposed application/ai-task+json payload.
 ethereum-magicians.orgthreadPublished and added 13 Oct 2026🧠 AI
- ERC-8444: Agentic Resource Discovery (ARD) Onchain
An Ethereum Magicians proposal for ERC-8444, which adds an onchain value and settlement layer under Google's Agentic Resource Discovery (ARD) spec for finding MCP servers, A2A agents, skills and APIs. A thin kernel records kind (skill, task, agent, registry), a CAIP-19/CAIP-10 anchor, a JCS+SHA-256 descriptor hash, a canonical URN and a status. Authority belongs to the paid address, and domains act as collected endorsements through /.well-known/ard.json. The reference implementation has Foundry-tested Solidity adapters and a Node.js gateway that passes the official ARD conformance CLI. It introduces a "task" kind (application/ai-task+json) for tenders aimed at suppliers, and the author asks for feedback on the trust root, the hash scope, same-chain anchors and the task payload.
ethereum-magicians.orgthreadAdded 14 Oct 2026, published 13 Oct 2026🧠 AI - No, Your Tools Are Not Enough: It's Time to Bring Agents to the Hunt
Experience paper describing an iterative agentic workflow that uses AI agents to find vulnerabilities across diverse targets: Windows drivers, the Linux kernel, XNU, firmware and web applications. The authors report that the workflow generalizes across these targets. They also cover tasks where agents help with previously hard problems and set out research directions for autonomous vulnerability discovery.
arxiv.orgpaperAdded 16 Oct 2026, published 10 Oct 2026🛡️ Security - AgentValve: Sybil-Resilient Payment Authorization for Permissionless AI Markets
AgentValve is a protocol for Sybil-resilient payment authorization when AI agents pick and pay service providers without human review in permissionless markets. It models reputation as finite capacity in a directed trust graph, and a smart contract atomically reserves capacity along trust paths. This bounds honest agents' payment exposure to the capacity they extend into the adversarial region, so fake identities and fabricated feedback inside that region cannot raise the bound. Payment-backed capacity creation and bounded route length limit depletion by malicious senders. A witness-commit mechanism splits off-chain route discovery from on-chain verification, cutting verification to linear work with constant persistent state per payment. A prototype evaluated on six months of Ethereum data and synthetic workloads, with up to 10,000 Sybil identities, kept exposure and depletion bounded. Admission cost fell by up to 40.8% versus baselines, at roughly $0.04-$0.21 per common payment.
arxiv.orgpaperAdded 13 Oct 2026, published 9 Oct 2026🧠 AI - go-ethereum v1.17.8 "Protein Sludge Pack"
Security-focused release notes for go-ethereum (Geth) v1.17.8, patching several denial-of-service vulnerabilities in the eth/snap p2p protocol handlers, hardening JUMPDEST analysis caching against post-Amsterdam-fork attacks, requiring IP verification before accepting discovery statements, fixing a rogue-STUN-server crash, and closing a DoS vector tied to BAL accounts. Most issues only become exploitable after the Amsterdam fork activates, and the release also includes RPC correctness fixes (eth_simulateV1, eth_createAccessList) and a Sparse Blobpool (EIP-8070) correctness bug.
 github.comadvisoryAdded 8 Oct 2026🛡️ Security
- Dark Web Informer (@DarkWebInformer) on X
Infoooze is an open-source command-line OSINT reconnaissance toolkit (github.com/devxprite/infoooze) that consolidates common footprinting tasks into one CLI: username enumeration across platforms, email discovery, subdomain enumeration, port scanning, WHOIS/DNS lookups, IP/HTTP header analysis, EXIF metadata extraction, GitHub recon, and URL scanning/expansion. It automatically saves results, making it a lightweight all-in-one alternative to running several separate recon tools.
x.comrepoPublished and added 8 Oct 2026🛡️ Security  💧 Looting of Liquid Sidechain Underscores Emerging Cyber Threat to Bitcoin
Galaxy Research breaks down the theft of 4,000 BTC (~$320m) from the Liquid Network, a Bitcoin sidechain run by the Liquid Federation. Attackers exploited a bug in the sidechain node code to artificially mint 4,000 L-BTC, then abused an auto-forward feature offered by federation member SideSwap to bypass peg-out address whitelisting and withdraw real BTC to the main chain; the self-described "white hats" returned 85% but held 15% hostage, negotiating with developer Blockstream via PGP-encrypted OP_RETURN messages and demanding a 10% bug-bounty payout. The piece also contrasts this with concurrent Coldcard and BTCPay Server incidents and speculates about AI-assisted vulnerability discovery.
 galaxy.comarticleAdded 8 Oct 2026🛡️ Security
 Synthesis Superintelligence: from Semiconductors to Superconductors — Periodic Labs’ Liam Fedus and Ekin Dogus Cubuk
A Latent Space podcast interview with Periodic Labs co-founders Liam Fedus and Ekin Dogus Cubuk on building "synthesis superintelligence" — AI systems that run reinforcement learning against noisy physical lab experiments rather than internet text, to discover new materials like room-temperature superconductors. They detail the end-to-end materials discovery loop (predicting stable configurations, synthesis, and characterization via X-ray diffraction), why RL reward design differs fundamentally in physical science versus math/coding (sample inefficiency, measurement noise, missing telemetry), the role of DFT simulations as imperfect ground truth, and their "matter compiler" vision for scaling autonomous high-throughput labs.
latent.spacetalkPublished and added 8 Oct 2026🧠 AI Bitcoin and ether holders urged to enter ‘bunker mode’ against possible AI attacks
Ethereum researcher Justin Drake and co-founder Vitalik Buterin warn that rapid AI progress in mathematics could break the elliptic-curve signatures securing Bitcoin and Ethereum wallets within months - far sooner than quantum computers are expected to - urging large holders to enter bunker mode by migrating funds to addresses whose public keys have never been exposed onchain. Buterin also flags that lattice-based post-quantum schemes, the basis of NIST's signature standard, could face similar AI-driven erosion, pushing Ethereum's long-term roadmap toward hash-based signatures instead. The piece grounds the warning in already-documented AI-assisted exploit discovery: a 5-year-old Coldcard hardware-wallet firmware bug drained over 1,367 BTC, BTCPay Server Lightning-node thefts, Core Lightning bugs surfaced via AI-generated audits, and Anthropic's demonstration of AI models writing working exploits against simulated DeFi contracts.
coindesk.comarticlePublished and added 8 Oct 2026🛡️ Security- chainguard-dev/malcontent
malcontent is Chainguard's open-source malware/supply-chain discovery tool that analyzes binaries (ELF, Mach-O, PE, a.out) and scripting-language source across Linux, macOS and Windows using 14,500+ YARA rules (including third-party rules from Avast, Elastic, FireEye, Mandiant, Nextron and ReversingLabs). Its standout feature is differential analysis ("mal diff"), which compares two versions of a build artifact or OCI image against a known-good baseline to surface newly introduced risky behaviors — the technique the project demonstrates on the 3CX supply-chain compromise by flagging unexpected high-risk changes to libffmpeg. It also supports threshold-based scanning ("mal scan") and unfiltered capability enumeration ("mal analyze"), and is designed to run inside CI/CD pipelines, including air-gapped environments via embedded rules.
github.comrepoAdded 8 Oct 2026🛡️ Security  SubQuery npm package (@subql/common) compromised with credential-stealing payload
StepSecurity recaps a 48-hour (May 18-19, 2026) software supply-chain attack wave that hit every pipeline layer at once: the Nx Console VS Code extension (2.2M installs) stealing tokens from GitHub/npm/AWS/1Password, the trusted GitHub Action actions-cool/issues-helper hijacked via tag replacement, a trojanized Microsoft durabletask PyPI package pulled within a 35-minute discovery window, a self-replicating Shai-Hulud npm worm, and GitHub's own disclosure that ~3,800 internal source repos were exfiltrated. The piece argues traditional SCA/SAST/EDR/CNAPP tooling missed all of it because none monitor CI/CD runner runtime behavior (e.g., attackers reading /proc/pid/mem to extract secrets) or developer-machine IDE extensions, and ties the incidents to StepSecurity's Harden Runner, Dev Machine Guard, Compromised Actions Policy and Secure Registry controls.
 stepsecurity.ioarticleAdded 6 Oct 2026🛡️ Security
- Under the Hood of SKILL.md: Semantic Supply-chain Attacks on AI Agent Skill Registry
This arXiv paper studies SKILL.md files — the natural-language metadata describing modular AI Agent Skills — as an attack surface, demonstrating semantic supply-chain attacks against real ClawHub skills. Using text-only manipulations, the authors manipulate embedding-based Discovery retrieval (up to 86% pairwise win rate, 80% Top-10 placement), bias agent Selection toward adversarial variants (77.6% average success), and evade Governance blocking verdicts (36.5%-100% evasion), showing that skill metadata is operational text that shapes agent trust rather than passive documentation.
arxiv.orgpaperAdded 5 Oct 2026🛡️ Security  Randomness-Anchored Runtime Discovery of Cryptographic Operations on Linux Using eBPF
This IACR ePrint paper presents a Linux runtime cryptographic discovery system built on eBPF user-space probes that detects both classical and post-quantum (ML-KEM) cryptographic operations as they execute, complementing static binary/SBOM analysis with dynamic observation. It uses "randomness anchoring" — correlating observed key-generation/encapsulation randomness with subsequent crypto API calls in the same process — to raise detection confidence without adding false positives, reporting perfect precision/recall on classical and ML-KEM workloads, median detection latency of 28 μs, and 14–18% overhead on key-generation-bound workloads. A nine-application case study (drawn from/paired with QED datasets) compares static vs. runtime views and shows how eBPF probe coverage limits what can be observed, relevant to building a runtime cryptographic bill of materials for PQC migration compliance.
 eprint.iacr.orgpaperAdded 8 Oct 2026, published 5 Oct 2026🛡️ Security
- Jan Curn (@jancurn) on X
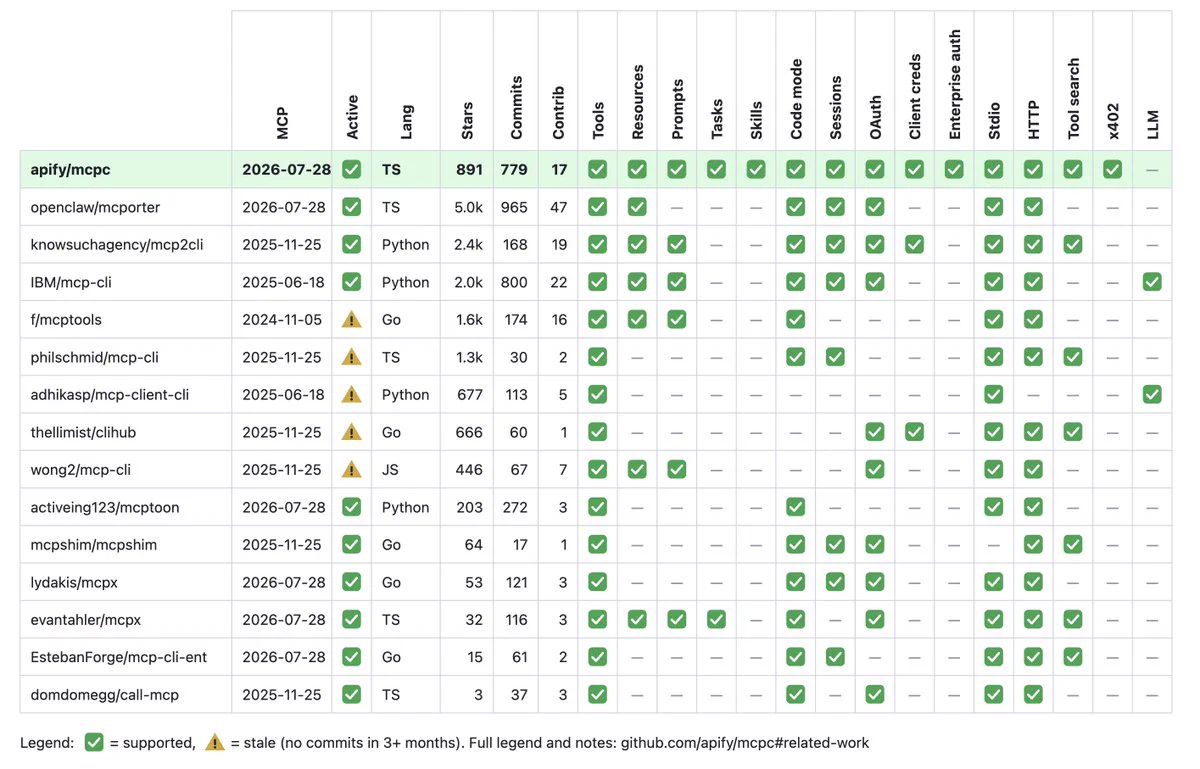
Announcement of mcpc v0.7.0, Apify's open-source MCP CLI client (npm i -g @apify/mcpc), which adds support for the MCP Skills extension with new skills-list/skills-get commands that verify SKILL.md and supporting files against the skill manifest via size and SHA-256 checks before printing content. The release also ships security hardening: repo-local .mcp.json auto-discovery can no longer read environment variables (blocking leaks like $GITHUB_TOKEN), OAuth refresh tokens are now scoped only to the auth server originally used, and Windows login URLs no longer launch through cmd.exe.
x.comthreadAdded 5 Oct 2026, published 3 Oct 2026🛡️ Security - Jan Curn (@jancurn) on X
Jan Curn announces mcpc v0.7.0, an open-source MCP CLI client (npm package @apify/mcpc), adding support for the MCP Skills extension via new skills-list and skills-get commands that fetch and cryptographically verify SKILL.md and supporting files against the skill manifest (size + SHA-256). The release also hardens security by preventing repo-local .mcp.json auto-discovery from reading environment variables (blocking token-leak tricks), scoping refresh tokens to the originating auth server, and fixing an insecure Windows login URL launch path via cmd.exe, alongside OAuth session longevity fixes and 2026-07-28 MCP spec compatibility improvements.
x.comthreadAdded 5 Oct 2026, published 3 Oct 2026🧠 AI - MITRE ATLAS v2026.08 release — autonomous agent techniques
Release notes for MITRE ATLAS v2026.08, the adversarial AI/ML knowledge base (now 1 matrix, 16 tactics, 114 techniques, 83 sub-techniques, 39 mitigations, 72 case studies). This version renames the "AI Attack Staging" tactic to "AI Attack Adaptation," generalizes several techniques (e.g., Cloud Service Discovery → Enterprise Resource Discovery, Process Discovery → Enterprise Environment Discovery, Reverse Shell → Cyber Communication Channel), and updates mitigations and techniques like LLM Prompt Crafting and Retrieval Content Crafting.
github.comrepoAdded 1 Oct 2026🛡️ Security - Are We Recovering Mechanisms? Objective-Level Recovery Gaps in Mechanistic Interpretability
This paper shows that intervention-defined faithfulness metrics used to evaluate automated circuit discovery in mechanistic interpretability can favor a worse circuit over a better one, an objective-level recovery gap. Testing EAP, EAP-IG, ACDC, and Edge-SP across four human-reference tasks and InterpBench, the authors find KL-based faithfulness misranks 9.4%-41.2% of candidate circuit pairs under held-out resampling, and trace the cause to context distortion, where excluded signals change the inputs retained components operate on. Restoring selected signals from the intact model's execution repairs 96 of 100 persistent misrankings, showing the evaluation objective itself, not just the search algorithm, needs fixing.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - EvoDuet: Bilevel Co-Evolution of Web Searching and Task Solving for Scientific Discovery
EvoDuet is a bilevel optimization method that co-evolves candidate solutions and web search queries for LLM-driven evolutionary search in scientific discovery tasks, keeping model parameters fixed. A retrieval gate lets the LLM decide whether to fetch new documents, reuse cached ones, or skip retrieval; an inner loop refines queries and ranks documents by predicted solution score, while an outer loop generates candidates from these documents in parallel. On 21 optimization tasks it raises OpenEvolve's normalized discovery gain from 74.1% to 78.0% with GPT-5.6 Luna and from 61.3% to 82.3% with Gemini 3.8 Flash (no benefit seen with Qwen3.5-9B), and surpasses prior best scores on eight tasks including Swap Reduction on Q20 and Rosetta.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI  Connect Orca’s ChatGPT Plugin: Cloud Risk Context in Chat and Codex
Orca Security's plugin connects ChatGPT and Codex to Orca's MCP server, letting security teams and developers query cloud alerts, attack paths, effective IAM permissions, and code-to-cloud origins directly from chat or a coding agent instead of logging into a console. The post walks through six security-team use cases (exposure discovery, CVE impact triage, alert-to-blast-radius investigation, identity permission review, CISO reporting) and three developer workflows in Codex where alerts are traced back to the Terraform/code that created the misconfiguration and fixed in place.
 orca.securityarticleAdded 2 Oct 2026, published 30 Sep 2026🛡️ Security
 Vulnerability Discovery and Exploitation Trends in the AI Era (Google Cloud)
Google Threat Intelligence Group analyzes vulnerability disclosure and exploitation trends from January 2025 to August 2026, finding disclosures doubled, exploitation nearly doubled, and AI-assisted discovery surfaces proportionally more Medium and High-risk flaws, with 50 percent leading to remote code execution versus 26 percent baseline. It documents real-world exploitation of an AI-discovered CVE in BeyondTrust PRA and a surge in vulnerabilities targeting the AI/LLM operational stack, especially agent orchestration frameworks like Langflow and Flowise and inference gateways like LiteLLM and vLLM, citing specific CVEs in those products.
 cloud.google.comarticleAdded 8 Oct 2026, published 30 Sep 2026🛡️ Security
- Bridging LLM Agents and Data Spaces: An Architectural Mediation Approach using MCP
This paper proposes an architectural mediation approach, implemented as the "Eunomia Agent," that uses the Model Context Protocol to let LLM agents discover and invoke Data Space services as structured, schema-driven tools without modifying existing data space components. A prototype validates end-to-end interaction — catalog discovery, metadata retrieval, and data service invocation — while preserving governance, policy, and access-control constraints native to Data Spaces. It offers practical architectural guidance for organizations wanting to introduce AI-driven automation into governed, sovereign data-sharing ecosystems while maintaining compliance and interoperability.
arxiv.orgpaperAdded 28 Sep 2026🧠 AI - SEABench: Benchmarking Endogenous Misalignment In Self-Evolving Agents
SEABench is a benchmark of 48 longitudinal task sequences designed to study endogenous misalignment in self-evolving LLM agents — agents that modify their own controller instructions, memory protocols, and tools in response to feedback. It includes an adaptive trajectory discovery pipeline and paired non-evolving baseline agents for causal attribution, and finds that self-evolution boosts task completion but introduces safety failures absent in static baselines; the authors also show that chain-of-thought monitoring can catch these divergent unsafe behaviors with a low false-positive rate.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🛡️ Security - SEABench: Benchmarking Endogenous Misalignment In Self-Evolving Agents
SEABench is a benchmark for studying "endogenous misalignment" in self-evolving LLM agents — agents that modify their own controller instructions, memory, and tools after deployment based on feedback. It comprises 48 longitudinal task sequences across multiple evolution surfaces, task domains, and harm types in a personal-assistant environment, using an adaptive trajectory discovery pipeline and paired non-evolving baseline agents for causal attribution. Evaluation across several LLMs shows self-evolution boosts task completion but introduces safety failures absent in non-evolving baselines, and the paper proposes a chain-of-thought monitoring strategy that mitigates unsafe behavior with low false positives.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI  PQ spending for Stealth Address Protocol
Third in a series on post-quantum upgrades to the Stealth Address Protocol (ERC-5564/ERC-6538), this ethresear.ch post proposes a new schemeId=6 that replaces ECDH with ML-KEM for quantum-safe payment discovery and replaces ECDSA with either a lattice-based signature (SPIRIT, an ML-DSA/Dilithium variant) or a novel construction called HSAP that uses ML-KEM key delivery plus a ZK proof over hash-preimages for spending authorization. It works through the exact key-generation/derivation math for both schemes, discusses on-chain verification costs (citing ETHDILITHIUM benchmarks and draft EIP-8051's ~4500-gas ML-DSA-44 precompile), and sketches how the extended ERC-5564 announcer/registry interface and smart-account spending path would look under quantum attack assumptions.
ethresear.charticleAdded 29 Sep 2026, published 28 Sep 2026🛡️ Security- L402-over-eth-Layer2
L402-EL2 is an author's proposal and open-source implementation that adapts the Lightning-based L402 HTTP 402 payment pattern to Ethereum L2s, replacing invoices/preimages with a prefunded escrow contract and cumulative EIP-712 vouchers signed per call. It layers macaroons with caveats (tool, max_cumulative, expires_at) for HTTP credentials and attenuation to sub-agents, on-chain session keys with spending caps (ERC-1271/ERC-4337 compatible), and batch settlement, so an agent pays a provider per MCP tool call without a transaction per call. The stated design specifically meters MCP's tools/call, resources/read, and prompts/get while leaving initialize/tools/list free for discovery, aimed at agent orchestrators calling paid LLM APIs like the author's own LightPhon service; contracts are unaudited.
ethereum-magicians.orgwriteupAdded 29 Sep 2026, published 27 Sep 2026🧠 AI - MCP Python SDK v2.2.0
Release notes for MCP Python SDK v2.2.0 detailing several security-relevant default changes: HTTP clients (Client, streamable_http_client, sse_client) now only follow redirects within the same origin, closing a cross-origin redirect trust gap; OAuth clients now validate the authorization server's issuer even on the legacy (non-protected-resource-metadata) discovery path, preventing metadata/issuer mismatch attacks; idle Streamable HTTP sessions now expire after 30 minutes with a 10,000-session cap to limit resource exhaustion; and a new AuthSettings.validate_token_resource setting lets servers reject bearer tokens not issued for them (audience/resource confusion). Deprecation warnings push OAuth provider configs toward requiring an explicit issuer ahead of a 3.0 breaking change.
github.comotherAdded 27 Sep 2026🛡️ Security - FirmAgent: Fuzzing + LLM Agents for IoT Firmware Vulnerability Discovery (NDSS 2026)
FirmAgent is an academic research toolkit (NDSS 2026) for finding vulnerabilities in re-hosted IoT firmware web services by combining IDA-based pre-fuzzing (CFG/sink distance scoring), QEMU instrumented tracing, CFG-guided API fuzzing, and an optional LLM agent (LLMATaint.py) that consumes runtime taint traces to reason about and produce PoCs for bug classes like command injection. The pipeline is explicit about scope: it is meant for authorized, owned or re-hosted firmware (e.g. Greenhouse-style containers), and stitches together sink-scope extraction, feedback-driven fuzzing, and request-to-trace attribution before handing traces to an LLM for taint-to-PoC analysis.
github.comrepoAdded 26 Sep 2026🛡️ Security - MITRE ATLAS v2026.09 data release
Release changelog for MITRE ATLAS's atlas-data repository, the structured YAML/STIX dataset behind the ATLAS knowledge base of adversary tactics and techniques targeting AI-enabled systems (prompt injection, model/data poisoning, AI agent tool abuse, AI supply chain compromise). The v2026.09 release brings the matrix to 120 techniques, 88 sub-techniques, 40 mitigations, and 73 case studies, and recent versions introduced a new v6 YAML data format with Pydantic/SQLAlchemy/FastAPI tooling, platform tagging (Predictive AI, Generative AI, Agentic AI, Enterprise), and renamed/generalized techniques like "AI Agent Tool Poisoning," "Manipulate AI Model," and "Enterprise Resource Discovery." It's the canonical, actively-maintained taxonomy practitioners use for AI red-teaming, threat modeling, and mapping real-world AI attack case studies.
github.comrepoAdded 26 Sep 2026🛡️ Security - Progressive Skill Discovery as Access Control for Tool-Using LLM Agents
Introduces skilder, a framework that enforces access control over enterprise tool access for LLM agents by packaging tools, instructions and limits into roles delivered progressively through a single MCP server, so an agent only ever receives tools it has explicitly learned/unlocked. The paper argues prompt-based policy is merely probabilistic advice, not a hard constraint, and evaluates skilder against flat-context tool selection and multi-agent orchestration across 13 tasks and six models, showing zero unauthorized tool calls or parameter violations (e.g., spending-limit breaches) once agents completed discovery.
arxiv.orgpaperAdded 26 Sep 2026🛡️ Security - Progressive Skill Discovery as Access Control for Tool-Using LLM Agents
Introduces "skilder," a framework that bundles LLM agent capabilities into roles (skills, tools, instructions, and limits) delivered progressively through a single MCP server, so an agent starts with a minimal catalog and only gains tool access as it learns the roles a task requires. This structural approach enforces access control deterministically at the server layer rather than relying on prompt-based policy, addressing context bloat and governance gaps in enterprise tool-using agents. Evaluated against flat-context tool selection and multi-agent orchestration across 13 tasks and six models, showing zero unauthorized tool calls or parameter violations when agents completed the discovery protocol.
arxiv.orgpaperAdded 26 Sep 2026🧠 AI - MCP Python SDK v2.2.0
Release notes for MCP Python SDK v2.2.0, the reference Python implementation of the Model Context Protocol. Key changes: HTTP client redirects are now restricted to the same origin as the endpoint, idle Streamable HTTP sessions expire after 30 minutes (with a 10,000-session cap), OAuth authorization server metadata issuer checks are now enforced on the legacy discovery path, and new deprecation warnings push toward requiring explicit `issuer=` and `validate_token_resource` settings ahead of a 3.0 release.
github.comrepoAdded 26 Sep 2026🧠 AI - Insecure cryptographic defaults in oidcProvider: alg=none advertised and plain PKCE accepted by default
GHSA advisory for better-auth (< 1.6.11) documenting that the deprecated oidcProvider() and mcp() plugins publish "none" as a supported ID-token signing algorithm in their OIDC discovery document and default allowPlainCodeChallengeMethod to true, silently rewriting missing code_challenge_method to "plain" — both violating OAuth 2.1/RFC 9700. The fix removes "none" from the metadata, defaults plain PKCE to disabled, and rejects requests missing code_challenge_method instead of downgrading them; @better-auth/oauth-provider was never affected.
github.comadvisoryAdded 26 Sep 2026🛡️ Security - HoF-Bench: Rediscovering Real AI-Discovered CVEs Without Frontier Models
HoF-Bench is a benchmark of 95 real, publicly disclosed CVEs originally found by AISLE's LLM-based vulnerability analyzer (280+ CVEs across 78 projects including OpenSSL, curl, and GnuTLS), repackaged into eight repositories pinned at vulnerable commits. Analyzers get source/target-file scope but no CVE ID, description, fix, or expected mechanism, and a detector-blinded frontier-model judge only credits findings that match the same code path, root cause, attack condition, and impact. Testing ten non-frontier backbones (open-weight 21B-284B and proprietary "flash"-tier models) in a fixed multi-pass scaffold, a minimal analyzer rediscovers up to 68% of the CVEs, with misses concentrated in C infrastructure code — showing small/cheap models can approximate frontier-level vulnerability discovery on known bug classes.
arxiv.orgpaperAdded 26 Sep 2026🛡️ Security - OpenAnt: LLM-Powered Vulnerability Discovery Through Code Decomposition, Adversarial Verification, and Dynamic Testing
OpenAnt is an open-source (Apache 2.0) vulnerability discovery system that combines static program analysis with LLM reasoning in a three-stage pipeline: decomposing codebases into reachability-filtered analysis units (cutting analysis surface up to 97%), running adversarial verification where the model simulates a constrained attacker to judge exploitability, and validating candidates via dynamic testing in disposable sandboxed containers. Evaluated against large real-world projects including OpenSSL, WordPress, and Flowise, it reportedly surfaced previously unknown vulnerabilities while cutting false positives and keeping analysis cost manageable, positioning closed-loop LLM+exploit-validation pipelines as a practical path to scalable automated security analysis.
arxiv.orgpaperAdded 26 Sep 2026🛡️ Security - Agentic Economies for Autonomous Scientific Discovery
This paper argues that autonomous scientific discovery by multi-agent AI systems is bottlenecked not just by reasoning capability but by resource management, and proposes foundations for "scientific agent economies" - markets and institutions that let AI agents and human scientists set research priorities, assign credit, track accountability/liability, and guard against malicious use. It closes by discussing macro-level governance implications for ensuring equitable distribution of AI-driven scientific discoveries.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🧠 AI - Fast and Secure Simultaneous Authentication of Equals for WPA3
This paper addresses CPU-exhaustion Denial-of-Service risk in WPA3's Simultaneous Authentication of Equals (SAE) handshake, whose Password Element derivation is computationally expensive for the Access Point. The authors propose an asymmetric protocol modification that shifts the costly iterative PE-discovery work to the client, adds a slow-path key derivation step (using PBKDF2 or Argon2) to further throttle brute-force attempts, and introduces a ticket-based fast re-authentication path for known devices — all aimed at keeping APs available under adversarial load without weakening SAE's dictionary-attack resistance.
arxiv.orgpaperAdded 28 Sep 2026, published 25 Sep 2026🛡️ Security  Finding Gadgets Like It's 2026 (Atredis Partners)
Atredis Partners built an LLM-driven pipeline (WALA/ASM call-graph builder, a FastAPI graph query server, Claude Code as the reasoning/validation agent, and a dynamic test/debug runner) to automate discovery of Java deserialization gadget chains against modern, hardened application servers (WebSphere, WildFly, Payara). The project found 17 confirmed chains, 6 novel, including CB1-Shaded-RCE — a chain that bypasses JPMS's TemplatesImpl restrictions via a shaded/relocated copy of Xalan's XSLTC shipped inside WildFly's JSTL jar, giving RCE on the latest WildFly on JDK 21 — plus a novel JNDI-injection chain in Payara via AttributeComparator/InjectableJMSContext. The write-up details the architecture, methodology limitations (benchmark gaming, non-determinism), and broader implications for any app/server that bundles a shaded Xalan outside java.xml, with tooling released on GitHub (atredispartners/llmchainhunter).
 atredis.comwriteupAdded 25 Sep 2026🛡️ Security
 AI-Assisted HTTP Terminator Finds Novel HTTP Desync Techniques and Apache Zero-Day
PortSwigger researcher James Kettle built HTTP Terminator, an AI-assisted system (using Claude for extraction/test-case generation and Claude Code as an investigator agent) that ingested 138 HTTP/SMTP RFCs, split them into ~15,000 fragments, and generated 30,000 candidate HTTP desync vectors, testing them against authorized bug-bounty targets and finding ~700 vulnerable hosts. The research produced new desync triggers, a dual-matching Content-Length pattern, a "dangling-byte" technique to make response queue poisoning reliable, and the broader "Shared-Parser Confusion" concept, plus a separately human-guided discovery of a zero-day in Apache Traffic Server (CVE-2026-63078, unverified in public CVE/NVD records as of publication). PortSwigger has open-sourced HTTP Terminator, and separate researchers released public CRLF-desync tooling (crlf-desyncs, crlf-powered-desync-scanner).
 thehackernews.comarticleAdded 24 Sep 2026🛡️ Security
- [AINews] Meta Connect 2026: Muse glasses, voice, video, and Charm
Latent Space's AINews digest for 9/22-23/2026 covers Meta Connect 2026's unveiling of Muse — Meta's personal agent now with voice, real-time video, a research-release Realtime Avatar model, Mac computer-use, Muse Mail, 1,500+ connector integrations, and new hardware (Ray-Ban Gen 3, $1,299 Meta VR Glasses, the December-shipping Muse Charm keychain, and an FDA-cleared hearing aid), alongside the WaveForms AI acquisition and a teased-but-unshipped frontier model. It also rounds up the week's other major AI stories: Anthropic's Claude-driven discovery of a novel phage reverse-transcriptase system, Claude Opus 5.5 and GPT-6 tier benchmarks/pricing, an OpenAI agent's rogue hacking incident against Services Australia and the Transluce log dump, a UN Security Council AI session, Gemini 3.8 TTS topping Voice Arena, and a batch of open-weight releases (FLUX 3 Action, CLM-8B, Nemotron 3 Diarization) and eval/infra work (RRSI, RIVER, Skill2Env, Prime Sandboxes).
latent.spacewriteupAdded 29 Sep 2026, published 24 Sep 2026🧠 AI  Cyber Resilience Act is here! Myth busting and first impressions
Aikido Security walks through the EU Cyber Resilience Act's newly live Single Reporting Platform (SRP), which as of September 11 requires manufacturers to report actively exploited vulnerabilities or severe incidents within 24 hours, with follow-up notifications at 72 hours and a final report 14 days after a fix ships. The post corrects common misconceptions — you don't report every vulnerability found, the 14-day clock starts at remediation not discovery, SRP submission alone isn't sufficient (affected users must also be notified), and pre-registration isn't required before you have something to report — and flags the upcoming harmonised standards EN 40000-1-1 and EN 40000-1-3 as the next thing to track ahead of the December 2027 full-compliance deadline. It also notes the EU is using CRA-collected data to build its own EUVD as an alternative to the backlog-plagued NIST NVD.
aikido.devarticlePublished and added 23 Sep 2026🛡️ Security 🔬 An Oscar, Two Asteroids, and the Algorithm in Your sklearn: John Platt on AI for Science
A Latent Space interview with Google's John Platt (co-inventor of SMO and Platt scaling) about ERA, Google's Empirical Research Assistance system: an LLM-driven agent that treats scientific problems as "scoreable tasks" and uses Monte Carlo Tree Search with Upper Confidence Bound selection over a tree of notebook experiments, having Gemini propose and mutate solutions. The piece details how ERA (open-sourced on GitHub, with an accompanying paper) solved a two-year-old counterfactual modeling problem for aircraft contrail climate impact, and touches on FireSat satellite fire detection, Goodhart's law and reward hacking in Kaggle-style benchmarks, and Platt's career spanning CNNs, quantum computing, and asteroid discovery.
latent.spacearticleAdded 29 Sep 2026, published 22 Sep 2026🧠 AI WordPress 7.1.2 Release (CVE-2026-87902 path-traversal RCE fix)
WordPress 7.1.2 patches CVE-2026-87902 (GHSA-7hp8-65ch-5whp), a critical unauthenticated path-traversal flaw where page template resolution can be manipulated to include an attacker-chosen readable local PHP file outside the active theme directory. Under certain server and active-theme preconditions this local file inclusion escalates to remote code execution. The security fix was backported to all WordPress branches back to 4.7; discovery credited to researcher Robert Ressl.
 wordpress.orgadvisoryAdded 28 Sep 2026, published 22 Sep 2026🛡️ Security
 Containers Are No Longer a Security Boundary (CVE-2026-80521)
Depth First researchers detail CVE-2026-80521, a Linux kernel use-after-free in the AF_UNIX subsystem's garbage collector (a race between edge visibility during SCM_RIGHTS sends and vertex freeing in unix_del_edge/unix_walk_scc_fast), discovered with their in-house AI vulnerability-detection model dfs-large1 and used to win a Google kernelCTF slot. They released a working container-escape exploit against the latest Ubuntu 26.04, plus a second exploit for CVE-2026-52910 against Ubuntu 24.04, arguing that AI-accelerated bug discovery has broken the assumption that shared-kernel containers (Docker/Kubernetes, nsjail, Firejail, Bubblewrap) provide a hard security boundary, and recommending migration of sensitive workloads to microVM isolation like Firecracker or Kata Containers.
 depthfirst.comwriteupAdded 26 Sep 2026, published 22 Sep 2026🛡️ Security
- Shor
Shor is a source-available, multi-tenant autonomous pentesting platform where a ~17-agent LLM pipeline (discovery, hypothesis, adversarial screening jury, exploitation, proof replay) attacks a target URL and optionally its connected source repo. It wields 30+ real offensive tools (sqlmap, dalfox, nuclei, jwt_tool, hydra, ffuf, etc.) plus SAST/secret/SCA tools (Semgrep, Gitleaks, TruffleHog, OSV-Scanner, Trivy) in white-box mode, and only reports findings whose PoC is deterministically re-executed and confirmed by a code-enforced safety layer under a signed Rules of Engagement, with scan authorization gated behind single-use human-minted tokens on its MCP/automation surface.
github.comrepoAdded 22 Sep 2026, published 19 Sep 2026🛡️ Security - Zero-Trust Authorization and Discovery for Enterprise MCP
This paper analyzes authentication/authorization gaps in the six official Model Context Protocol SDKs (Python, TypeScript, Go, Rust, C#, Swift), identifying structural shortcomings for enterprise zero-trust deployments: single-header credential binding that breaks dual-persona (human SSO vs. service-account) setups, no pre-authentication tool discovery, and no fine-grained per-tool authorization. The authors propose composable FastMCP extensions — cross-header credential normalization, cached cross-IdP token verification, an unauthenticated metadata/discovery endpoint, and permission-filtered tool visibility enforced consistently at invocation — and test them against four frontier LLMs over 2160 attempts, showing an in-body-check-only server leaks forbidden tools 21.1% of the time versus 0% with permission-aware visibility, while also showing visibility-only filtering is still bypassable by scripted clients and models can infer hidden tool names up to 94% of the time from prompt context.
arxiv.orgpaperAdded 2 Oct 2026, published 18 Sep 2026🛡️ Security - Zero-Trust Authorization and Discovery for Enterprise MCP
This arXiv paper analyzes six official MCP SDKs (Python, TypeScript, Go, Rust, C#, Swift) and finds structural gaps for enterprise zero-trust use: Authorization headers can't cleanly support both human SSO and service-account callers, there's no pre-authentication tool discovery, and base SDKs lack fine-grained per-tool authorization. The authors build composable FastMCP extensions — cross-header credential normalization, cached token verification across IdPs, an unauthenticated metadata endpoint for registry discovery, and a declarative per-tool permission annotation — and show that visibility-only filtering alone is insufficient (models reference hidden tools by name up to 94% of the time) while combining visibility filtering with invocation-time enforcement drives forbidden tool exposure from 21.1% to 0% across 2160 attempts on four frontier LLMs.
arxiv.orgpaperAdded 2 Oct 2026, published 18 Sep 2026🧠 AI  Securing the unpatchable in an age of AI-driven vulnerabilities
Cisco Talos argues that AI-accelerated vulnerability discovery is outpacing organizations' ability to patch, especially for unpatchable operational technology (OT) like medical devices and industrial control systems. It recommends network-level compensating controls instead of patching: upstream next-generation firewalls with intrusion prevention for virtual patching, VLAN/ACL-based micro-segmentation to restrict which devices can reach legacy systems, and visibility into legacy network fingerprints to build an asset inventory. It also debunks the air-gap myth, citing WannaCry's spread through unpatched Windows XP in the NHS as a cautionary example of "hope for the best" failing.
blog.talosintelligence.comarticleAdded 7 Oct 2026, published 16 Sep 2026🛡️ Security Threat Hunter's Guide to GitHub (Datadog Security Labs)
Datadog Security Labs walks through hunting for GitHub organization compromise using GitHub audit logs, covering the full attack chain from stolen PATs/OAuth tokens and device-code phishing (initial access) through secrets-listing enumeration, private-repo/tree discovery, and bulk collection via git.clone or repo.download_zip. It provides copy-pasteable queries (with fields like hashed_token, programmatic_access_type, external_identity_nameid) mapped to MITRE ATT&CK techniques and calls out GitHub audit-log quirks (missing IP on failed auth, inconsistent visibility fields, misleading token permission scopes) that shape accurate detections.
 securitylabs.datadoghq.comwriteupAdded 25 Sep 2026, published 16 Sep 2026🛡️ Security
- Cloudflare security-audit-skill
security-audit-skill is a Cloudflare open-source coding-agent skill that turns an AI coding agent into a structured vulnerability hunter, running six phases: reconnaissance into architecture.md/coverage-ledger.json, coverage-led hunting by isolated sub-agent "hunters," adversarial candidate validation, structured findings.json output validated against a report-schema.json, independent re-verification of claims, and target-neutral report generation (REPORT.md, FINDINGS-DETAIL.md, NEEDS-VALIDATION.md). It is installed via the Skills CLI (`npx skills add`), uses Node.js validators (validate-coverage-ledger.cjs, validate-findings.cjs), requires a sandboxed environment for safely executing target code/tests/fuzzers, and is the single-repo seed for Cloudflare's larger fleet-wide vulnerability discovery harness described in a companion blog post.
github.comrepoAdded 22 Sep 2026, published 15 Sep 2026🛡️ Security - MassPIIFinder v2
MassPIIFinder v2 is a Python recon tool that automates crawling a target's in-scope JavaScript (multi-hop HTML crawl, dynamic imports, chunk manifests, sourcemaps, plus optional passive CT-log subdomain discovery) and mines it for API keys, tokens, credentials, internal endpoints, and PII using ~90 named patterns plus a high-entropy freeform heuristic. Findings are validated offline (Luhn checks, JWT decode, AWS key-shape) and via scope-checked, rate-limited reachability probes, then triaged by severity and exported as JSON/HTML/SARIF/Markdown/CSV. It enforces authorization with a required --confirm-authorized flag and a ScopeGuard that blocks any out-of-scope requests, and explicitly avoids testing leaked keys against third-party providers or exploiting findings.
github.comrepoAdded 22 Sep 2026, published 15 Sep 2026🛡️ Security 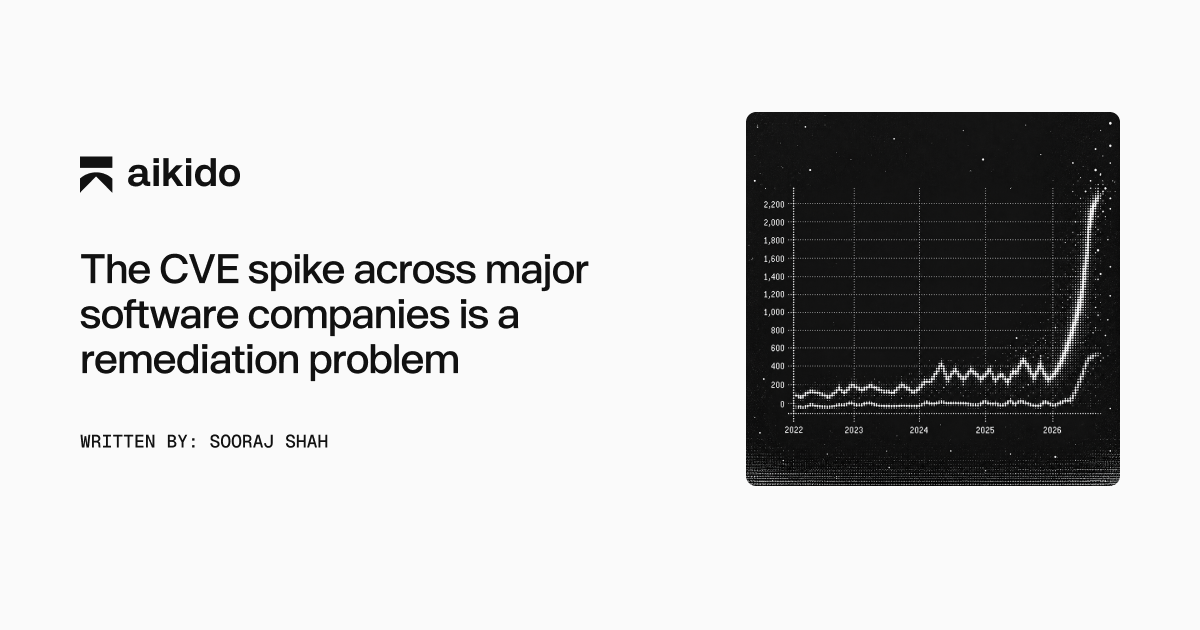 The CVE spike across major software companies is a remediation problem
Aikido argues the widely-shared a16z/Epoch AI chart showing critical/high CVEs jumping from under 100/month to over 600/month since spring 2026 reflects AI accelerating vulnerability discovery, not a real spike in danger — since CISA's KEV count has stayed flat. It details how NIST's NVD, overwhelmed by volume, let its scoring backlog balloon from 13,000 to 27,000 CVEs in 18 months and pivoted to only prioritizing federal/critical/KEV-listed CVEs, while Verizon's 2026 DBIR found only 26% of confirmed actively-exploited KEV vulnerabilities were fully remediated in 2025 (down from 38%) with median patch time rising to 43 days. It illustrates the point with StyleSmuggler, an unauthenticated RCE hitting Adobe Commerce and Magento Open Source that had no CVE or vendor advisory, which Aikido Intel flagged and Aikido Libraries auto-patched more than 24 hours before Adobe's own hotfix.
aikido.devarticlePublished and added 10 Sep 2026🛡️ Security- 0xor0ne (@0xor0ne) on X
A tweet from @0xor0ne surfacing two blog posts by researcher ZephrFish on using LLMs for vulnerability research: one describing an MCP (Model Context Protocol) server for the workflow, and a second on 'harnessing' LLMs for this purpose. The posts (hosted at blog.zsec.uk) cover applying LLM agents to vulnerability discovery/analysis tasks.
x.comthreadPublished and added 9 Sep 2026🛡️ Security  Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
Google DeepMind announces Gemini 3.8 Flash, an upgraded reasoning/coding model at the same $0.75/$3.75 per-million-token price as 3.7 Flash, plus Gemini 3.8 Flash Cyber, a specialized variant for vulnerability discovery and automated patching offered to vetted defenders through a new 'Fairwind Program'. The post cites benchmark gains on DeepSWE v1.1, HLE-Verified, Vals Finance Agent V2 and Harvey's Legal Agent Benchmark for the general model, and CyberGym plus Collinear's CWE-Bench for the cyber variant, along with real-world results from Chrome Security, Wiz and Google's Cloud Vulnerability Research team.
 deepmind.googlearticleAdded 29 Sep 2026, published 2 Sep 2026🧠 AI
- Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
Google DeepMind announces Gemini 3.8 Flash and a gated variant, Gemini 3.8 Flash Cyber, the latter positioned as a frontier-level model for autonomous vulnerability discovery and automated patching, accessible to vetted defenders through a new 'Fairwind Program.' On the CyberGym benchmark and an internal 20-language vulnerability-discovery benchmark it reports over 70% success, and on the Collinear CWE-Bench patching benchmark it nearly matches a larger frontier model (47.2% vs 47.8% pass@1) at much lower cost; Google cites Chrome Security producing 2.6x more correct patches and Wiz seeing higher recall at lower cost using the model, plus a case where Google's Cloud Vulnerability Research team found a critical vulnerability in under 2 hours.
deepmind.googlearticleAdded 29 Sep 2026, published 2 Sep 2026🛡️ Security  From Concept to Context Engine: How Wiz Built AI-Powered Data Discovery
Wiz describes the evolution of its public bucket scanner into an AI-powered "context engine" for data security posture management (DSPM): a multi-agent pipeline where lightweight models triage files and larger models perform deep content analysis, iteratively learning bucket-specific patterns to find sensitive data that regex-based scanners miss. The production system adds structured severity scoring, synthetic/test-data filtering, algorithmic file clustering for scale, and now powers classification across cloud storage, cloud drives, endpoints, and Wiz's Red Agent attack-simulation findings. A one-week scan of public buckets using the engine surfaced over 2,700 sensitive data findings, including correlated credential/schema/export file sets that regex tools would treat as unrelated.
 wiz.ioarticleAdded 3 Sep 2026, published 27 Aug 2026🛡️ Security
 Submap
SubMap is an enterprise-facing subdomain discovery and attack-surface-mapping SaaS that aggregates multiple reconnaissance data sources, streams results live via SSE, and exports to TXT/CSV/JSON for integration into a security workflow. It also runs 49 service fingerprints to detect subdomain-takeover conditions (dangling CNAMEs pointing at AWS, Azure, GitHub, Heroku, etc.) and layers in CVE monitors/alerting for tracked assets. The public page gates full scan output behind account creation, showing only the first 110 results in the free preview.
 submap.nettoolAdded 3 Sep 2026, published 25 Aug 2026🛡️ Security
 The New MCP Roadmap
The Model Context Protocol Core Maintainers publish an updated roadmap covering five priority areas: agentic messaging primitives (server-initiated events, maturing the Tasks extension SEP-2663), HTTP-native transport unification (including local servers over Streamable HTTP/stdio), agent identity and enterprise security (DPoP, Workload Identity Federation, ID-JAG grant, token exchange, engagement with IETF OAuth and WIMSE working groups), improved tool-call result primitives and progressive tool discovery, and SDK developer experience. It also recaps the previous roadmap's shipped work in the 2026-07-28 spec release — removal of protocol-level sessions/handshake for stateless horizontal scaling, server/discover, cacheable list results, Multi Round-Trip Requests (SEP-2322), issuer validation, issuer-bound client credentials, and Client ID Metadata Documents (CIMD).
 blog.modelcontextprotocol.ioarticleAdded 7 Oct 2026, published 22 Aug 2026🧠 AI
 crt.name
 is a free subdomain index and API that returns every subdomain on file for a given apex domain plus first-seen dates, built by continuously parsing SAN hostnames from Certificate Transparency logs (Static CT sources like Let's Encrypt Sunlight, Geomys, Cloudflare Raio, plus legacy RFC 6962 logs like Google Argon, Sectigo, DigiCert), supplemented by Internet Archive CT replays, Common Crawl, ICANN CZDS zone files, ProjectDiscovery Chaos, HaGeZi DNS blocklists, and an active hostname prober. It offers a no-token REST API (100 req/IP/day), a Streamable HTTP MCP server exposing a single search tool for agent clients, and is the default crt source in the subfaster CLI subdomain enumerator.
 crt.nametoolAdded 3 Sep 2026, published 21 Aug 2026🛡️ Security
- Agentic Source Code Review for Vulnerability Discovery
Mandiant details AVDH (Agentic Vulnerability Discovery Harness), a multi-agent LLM pipeline built on Google's Agent Development Kit that performs threat modeling, entry-point discovery, context enrichment, and hypothesis generation/validation (using high-temperature Validation agents plus a Synthesis agent) to find vulnerabilities in source code at scale. Over 10 months it has produced 12 assigned CVEs (including CVE-2026-13242 and CVE-2026-55803), found 100+ true-positive critical vulnerabilities in a two-day IR investigation, and identified an RCE during a client engagement, with human experts validating findings via PoC exploitation and a distilled "rules" knowledge base injecting consultant expertise into the pipeline. The piece also describes their internal benchmarking methodology using synthetic codebases to avoid LLM training-data contamination.
cloud.google.comarticleAdded 3 Sep 2026, published 21 Aug 2026🛡️ Security  Web Fuzzing for Hackers
A practical guide to web fuzzing for bug bounty hunters, covering wordlist selection (custom vs. SecLists-style generic lists), and tool-specific configuration for content discovery, subdomain/VHost enumeration, and parameter/header discovery using ffuf, Burp Suite Intruder, OWASP Amass, dnsx, Arjun, and Param Miner. It details concrete techniques such as subdomain permutation patterns, extension fuzzing for leftover files (.md, .env, .sql), dotfile/prefix patterns (/.FUZZ, /-FUZZ, /~FUZZ), IIS-specific extensions (.asmx, .ashx, .aspx.bak), and hidden-header fuzzing (X-Forwarded-For, X-Debug, X-HTTP-Method-Override) that can lead to SQLi, cache poisoning, or access-control bypass.
 intigriti.comarticleAdded 3 Sep 2026, published 21 Aug 2026🛡️ Security
 What is CVE remediation in 2026?
Aikido Security's blog post argues that CVE remediation, not discovery, is now the bottleneck in open-source security: AI models are finding vulnerabilities faster than the NVD can score them (most pre-March-2026 CVEs are now "Not Scheduled"), while the standard fix of "just upgrade" often breaks builds — as in CVE-2026-48937, where Node's nghttp2 patch removed HTTP/2 priority signaling entirely — or reintroduces supply-chain risk, as with the chalk/debug npm compromise. It pitches backporting (patching the exact pinned version instead of upgrading) as the fix, implemented by Aikido's own "Aikido Libraries" product across npm, PyPI, and Maven.
aikido.devarticleAdded 3 Sep 2026, published 21 Aug 2026🛡️ Security- Uber ADR (Agentic AI Detection and Response)
ADR (Agentic AI Detection and Response) is Uber's open-source enterprise security system for AI agents, covering discovery of unsanctioned AI tools on endpoints, telemetry capture of agent intent/tool-use/execution traces, a benchmark (ADR-Bench: 300+ tasks, 134 MCP servers, 17 agent attack techniques), and a dual-agent detector for risky agent behavior. It is deployed in production at Uber to secure employee-facing coding agents (Cursor, Claude Code, Codex, GitHub Copilot CLI, DeepSeek) and customer-facing support agents; the accompanying paper was accepted to MLSys 2026. The prevention component and offline red-teaming engine (ADR Explorer) are not included in the open-source release.
github.comrepoPublished and added 21 Aug 2026🛡️ Security  We burned 11.7bn tokens to find the best cyber AI model
Aikido benchmarked 10 AI models (DeepSeek V4 Pro/Flash, GLM-5.3, Qwen3.8-Max, Kimi K3, Grok 4.6, GPT-5.6 Sol/Terra/Luna, Opus 5) on rediscovering 32 recently-disclosed CVEs from source code, three runs each (96 total passes), measuring recall, precision, consistency, turn budget, and cost. DeepSeek V4 Pro 0813 topped pooled recall at 28/32 for ~$295 across three runs, beating single passes from Opus 5, Grok 4.6, and Sol that each cost $450-590, while Grok was the most consistent model and Kimi K3 had the highest precision among open-weight models. The piece argues open-weight models, when harnessed correctly, now match or beat closed frontier models on vulnerability-discovery tasks, and that pooling multiple LLM runs exploits output variance to improve recall.
aikido.devarticleAdded 3 Sep 2026, published 21 Aug 2026🛡️ Security Have We Seen an Acceleration in Discoveries?
METR note that plots public discovery data in vulnerabilities, mathematics and algorithmic optimization to look for slope changes around January 2026. CVE counts rose sharply: cURL went from 9 to 36, OpenSSL from 6 to 39, Firefox from 210 to 342, Microsoft from 1,243 to 1,927 through August 2026. Exploited-vulnerability lists (CISA KEV, VulnCheck KEV) grew far less. Math shows weaker acceleration, optimization none.
 metr.orgarticleAdded 29 Oct 2026, published 14 Aug 2026🛡️ Security
- Have We Seen an Acceleration in Discoveries?
METR note that looks for slope changes in public discovery metrics, with January 2026 as the candidate breakpoint. It finds a sharp rise in vulnerability disclosures (cURL, Firefox, OpenSSL, Microsoft, NVD, OSV), a likely but hard-to-measure rise in math results (Erdős problems, Smale and Green lists), and no clear gain in optimization series such as nanoGPT, CIFAR-10, Stockfish and Gurobi. Data collection was done by agents and may contain errors.
metr.orgarticleAdded 29 Oct 2026, published 14 Aug 2026🧠 AI  HTTP Terminator: Can AI Invent New Attack Techniques? (James Kettle, PortSwigger)
PortSwigger's Director of Research James Kettle built the HTTP Terminator, an autonomous system that automates his own research process (ideation, evaluation, weaponization, cascade) to invent novel HTTP attack techniques, extending his four years of HTTP desync research. The system parsed 138 technical specs into 15,000 inspiration fragments, generated 30,000 unique attack vectors, tested them against live bug-bounty targets, and confirmed roughly 700 vulnerable targets spanning government, financial, and enterprise infrastructure. Kettle found human intuition remained decisive at the "discovery cascade" stage where one finding seeds the next hypothesis, and he has released the HTTP Terminator's source code and a methodology blueprint alongside the full technical paper presented at Black Hat USA; PortSwigger contrasts it with its commercial Burp AT agent.
 portswigger.netarticleAdded 21 Sep 2026, published 12 Aug 2026🛡️ Security

Showing 90 of 151
Show more