Skip to content

43 results for β€œAUR”

What you seeeverything
latent.spacetalk🧠 AI

Building AI for Lawyers - Jacob Lauritzen, CTO of Legora

Latent Space podcast episode with Jacob Lauritzen, CTO of Legora, on building AI agents for lawyers. He describes evals built from RL environments such as a 10,000-file data room because traces cannot be read, routing across models, source-linked citations, and a few shared primitives (Tabular Review, lists, intake). Also covers legal engineers versus forward deployed engineers, Azure-only hosting, and the billable hour. Based on the first 40,000 characters of the transcript.

AzureSlackTabular Review+4
LegoraJacob LauritzenLatent Space+12

agents, evals, llm-appsΒ· Published and added 2 Nov 2026
latent.spacetalk🧠 AI

Building Legal Agents When You Can't See the Data - Jacob Lauritzen, CTO of Legora

Latent Space interview with Jacob Lauritzen, CTO of Legora, on building a legal agent when the company cannot read customer traces. It covers simulated test "worlds" built by engineers and lawyers, a citation fix that went from 70% to 99% with a model release, paraphrased traces, and running on Azure. It also covers Tabular Review, intake bots, forward-deployed engineers and the harness.

AzureSlackTabular Review+5
LegoraLatent SpaceWexler+9

agents, evals, llm-appsΒ· Published and added 2 Nov 2026

x.comthread🧠 AI

🚨 AI News | TestingCatalog (@testingcatalog) on X

RoboAPI is a public API from PokeBot, powered by its world-action model Poke-Aurora, that lets robot arms do new tasks from natural-language instructions with no task-specific data collection or training. A user connects a supported arm with a wrist-mounted camera, gives a task such as "clean the table", and receives the next moves in near real time. The post gives no benchmarks, supported hardware list or pricing.

RoboAPIPoke-Auroraworld-action model
PokeBotTestingCatalog

models, multimodalΒ· Added 1 Nov 2026, published 31 Oct 2026

securityweek.comarticleπŸ›‘οΈ Security

In Other News: Anthropic Breach Dispute, UEFI Flaw Hits Most Servers, Cloudflare AI Data Leak

SecurityWeek's weekly roundup of 30 October 2026 covers CVE-2026-97631, a 16-year-old buffer overflow in TianoCore EDK II that affects PXE network boot on most servers. It also covers a Cloudflare Workers AI cross-tenant leak caused by an SGLang bug, Anthropic's dispute with Cathedral over a bug bounty intrusion, and fake AI bots probing for secrets. Other items include AI-assisted ransomware (Gold Ogre, Aur0ra), the NIK C2 framework, and North Korean IT worker sanctions.

TianoCore EDK IISGLangCloudflare Workers+3
CVE-2026-97631CathedralCequence+9

Threat Intel, AI Security, Hardware & RFΒ· Published and added 30 Oct 2026

arxiv.orgpaper🧠 AI

Agentic LLM reasoning in pediatric diabetes outcome prediction from multimodal medical records

CEDAR (Clinical Evidence-Driven Agent for Risk-prediction) is an evidence-citing, self-auditing LLM pipeline for predicting pediatric diabetes outcomes at 24 months from 18 months of records. On 2,489 youth with type 2 diabetes and 4,018 with type 1, pooled AUROC was 0.815 versus 0.656 to 0.700 for trained ML in T2D, and 0.756 versus 0.603 to 0.631 in T1D. Only 4 of 70,246 cited values mismatched the chart. Two pediatric endocrinologists matched its predictions in about nine of ten cases.

LLM
CEDARarXiv

research, agentsΒ· Added 31 Oct 2026, published 29 Oct 2026

x.comtool🧠 AI

Mauro Ubeda (@mauroubeda) on X

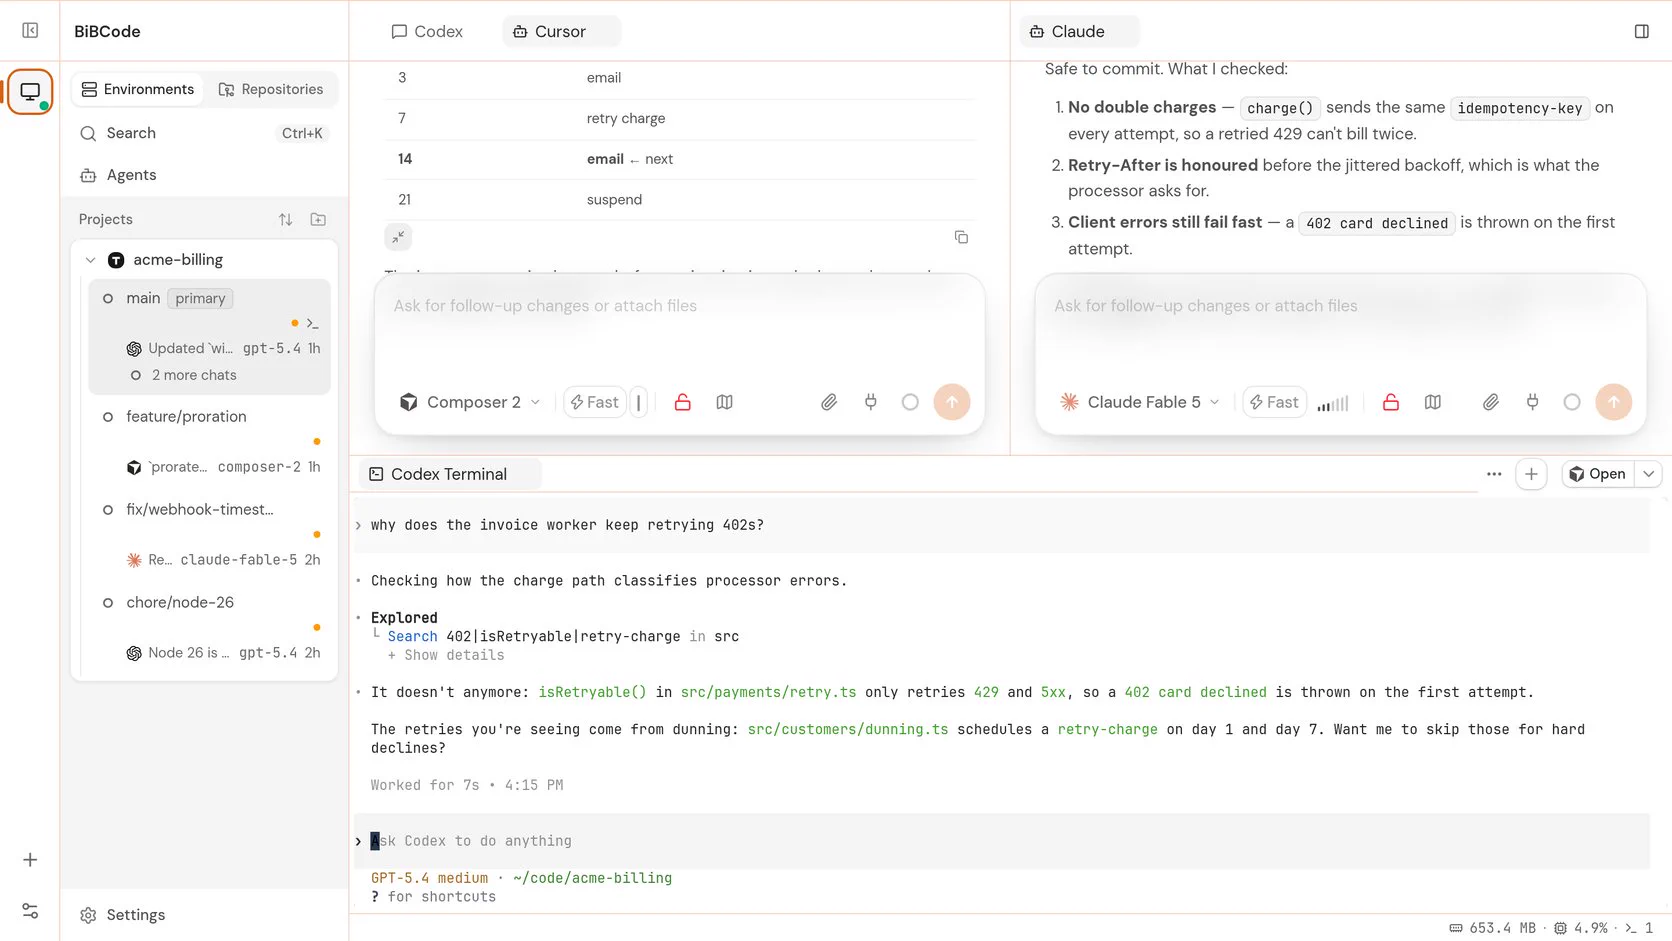
BibCode is an open-source desktop app, now in beta, for running coding agents side by side. It is built with Rust and Tauri rather than Electron, and runs Codex, Claude, Cursor and OpenCode, each in its own git worktree. It can also connect to remote BibCode Servers. The author, Mauro Ubeda, says it mixes ideas from T3 Code and Orca. The post gives no feature detail beyond this.

RustTauriGit+4
BibCodeMauro UbedaT3 Code+1

coding-agents, agentsΒ· Added 28 Oct 2026, published 27 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Ranking Is Not Deciding: Benchmark Shortcuts and Operating-Point Collapse in Query-Time RAG Poisoning Defenses

Ranking Is Not Deciding is an October 2026 arXiv paper showing that query-time RAG poisoning filters score near-perfectly because of how the poison set was built. PoisonedRAG's code prepends the target question to each passage. Removing that prefix takes RAGuard from AUROC 0.953 to 0.758 and its miss rate from 0.191 to 0.763. The authors release a script that profiles a poison set.

LLM
PoisonedRAGRAGuardTrustRAG+5

AI SecurityΒ· Added 27 Oct 2026, published 24 Oct 2026

fleetingswallow.comarticle🧠 AI

Achieving AI-style reasoning without an LLM

Minotaur is a GPUless reasoning architecture built on ELC (Energy, Control, Logic) typed roles and the MINOS representation. One "settling" operation over one network handles deduction, abduction, diagnosis, seeing versus doing, belief revision and order-dependent histories. The authors report it matched a language model on a blind police-interview test (30 of 30) and on learned production-line faults (10 of 10), and that it recovered Aristotle's 24 valid syllogisms.

MinotaurELCMINOS+4
SapientronicJudea PearlDouglas Lenat+6

researchΒ· Added 23 Oct 2026, published 22 Oct 2026

arxiv.orgpaper🧠 AI

Agentic Ensemble with Vision-Language Models for Visual Anomaly Detection

AnomalyAgent is a post-training fusion framework for visual anomaly detection that ensembles pretrained detectors. It aligns scores and anomaly maps, summarizes disagreement, and treats fusion as a choice among score actions and map actions. A constrained vision-language model inspects high-conflict samples and picks the actions. It beats equal-weight fusion and gets the best mean image AUROC and pixel AP among compared fusion methods on MVTec AD and VisA.

vision-language model
AnomalyAgentMVTec ADVisA dataset+2

research, multimodal, agentsΒ· Added 22 Oct 2026, published 20 Oct 2026

arxiv.orgpaper🧠 AI

GraphACM: Graph-based Action Consistency Measurement for Uncertainty Quantification in LLM Agents

GraphACM merges equivalent states from multiple rollouts of the same LLM agent task into a directed, action-labeled graph, so actions can be compared at shared decision states. It defines node-level and global action-consistency measures, and uses the global score as an uncertainty proxy to predict task success or failure. Across three LLMs on ALFWorld, AppWorld and WebShop it reaches an average AUROC of 0.811, above the strongest behavioral-consistency baseline (0.729) and verbalized confidence (0.769). It also shows where in a trajectory agent actions diverge.

LLM
GraphACMALFWorldAppWorld+2

research, agents, evalsΒ· Added 17 Oct 2026, published 15 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

From Detection to Decision: Calibration and Deferral for Prompt-Injection Detection

Evaluates a native probabilistic decision model (Jev), Llama Prompt Guard 2 (22M and 86M) and an LLM judge on 47,611 held-out examples covering direct/indirect prompt injection, hard-benign inputs, obfuscation and distribution shift. The LLM judge has the best AUROC (0.897), followed by Jev (0.871), Prompt Guard 2 86M (0.757) and 22M (0.714). Jev's native probabilities do not consistently beat post-hoc calibrated classifier scores, and temperature scaling improves calibration but not discrimination. At a 1% false-negative-rate target, every system needs over 91.8% escalation, so probabilistic outputs alone do not give reliable security decisions under distribution shift.

LlamaLLM
JevPrompt Guard 2prompt injection+1

AI SecurityΒ· Added 17 Oct 2026, published 14 Oct 2026

arxiv.orgpaper🧠 AI

Evidence-First Agentic Verification

Introduces Sauron, an evidence-first agentic verifier that checks rubric criteria for long-horizon agent tasks by investigating both environment state and execution trace, and trusts a claim (including an agent's self-reported success) only after validating it against its source. Bounded queries and joint investigation of related criteria cut context use, and each verdict carries an auditable evidence receipt. On 2,586 human-labeled criteria from 100 personal-assistant episodes it has the best F1 of five verifiers across eight backbones (0.96 vs 0.92 for Gandalf with GPT-5.6 Sol, at 23% lower cost). It detects 97% of injected failures across 13 fault families, including reward-hacking simulations, with 2% false flags on clean controls, and leads on the TRAIL agent-error benchmark. It matters because unreliable rubric verdicts used as RL rewards can reinforce bad behavior.

SauronGandalfTRAIL+2

evals, agents, researchΒ· Added 14 Oct 2026, published 13 Oct 2026

arxiv.orgpaper🧠 AI

OnTrack: Real-Time Monitoring and Intervention in LLM Agent Trajectories via Streaming Structure-Aware Optimal Transport

OnTrack is a streaming monitor for LLM agents. It uses structure-aware optimal transport to compare an agent's steps and tool dependencies against recorded successful runs, and can alert users or block the agent in about a millisecond per step. It works under three access regimes: full reference (historical runs plus tool schemas), tool schemas only, and step logs only. Monitoring ranges from plan-violation detection to spotting loops, stalls and repeated tool calls. On SWE-bench trajectories, the first 8 steps rank failing runs below succeeding ones better than content-similarity baselines (+0.057 AUROC). An abort policy saves about 18% of compute, and 5 of 6 aborts were correct.

OnTrackSWE-bench

agents, research, evalsΒ· Added 9 Oct 2026, published 8 Oct 2026

aws.amazon.comarticleπŸ›‘οΈ Security

Improving SPIRE security and resiliency with AWS managed services

AWS Security Blog walkthrough on hardening SPIRE (the SPIFFE Runtime Environment) in production by replacing its default self-managed components with AWS managed services: AWS KMS for SVID signing keys, Amazon Aurora PostgreSQL as the datastore, AWS Private CA as the upstream certificate authority, Amazon S3/CloudFront for trust bundle distribution, AWS Secrets Manager for delivering SVIDs to serverless/container workloads, and Amazon Verified Permissions (Cedar policies) for fine-grained SPIFFE-ID-based authorization. It addresses operational concerns like key custody, datastore resiliency, PKI integration, and offline identity validation, and links to a GitHub reference deployment and a SPIFFE/SPIRE-on-AWS workshop.

AWSKubernetesPostgreSQL+2

Cloud & Infra, Identity & AccessΒ· Added 7 Oct 2026, published 6 Oct 2026

arxiv.orgpaper🧠 AI

FREA: A Multi-Source Expert Benchmark for Reaction Feasibility Verification

FREA is a benchmark of 751 chemical reactions labeled by expert chemists for feasibility verification, drawn from retrosynthesis model proposals, zero-yield experimental records, LLM-generated edits, and five negative-candidate generation methods. The authors show no single verifier type (LLMs prompted with the feasibility criterion, dedicated forward models, or retrosynthesis scorers) dominates across all sources, and that adding generated negative examples to training improves mean AUROC but fails to transfer to retrosynthesis proposal screening. They also release a corpus of over 14 million recorded and generated reactions to support further training and evaluation of feasibility verifiers.

FREA

evals, researchΒ· Added 6 Oct 2026, published 5 Oct 2026

arxiv.orgpaper🧠 AI

CorrectGuard: Eyes-Off Correctness Estimation for Black-Box Security Guardrails

CorrectGuard is a framework for estimating how accurately black-box security guardrails (jailbreak, harmful-content, prompt-injection and extraction detectors) perform on inputs that cannot be inspected by humans or by the evaluating model itself, using an independent correctness model trained only on labeled "eyes-on" data. The authors test in-context-learning, embedding-based, and fine-tuned correctness classifiers under leave-one-dataset-out evaluation across 13 safety/security datasets and multiple open-weight guardrails, showing up to 25-point macro-accuracy gains and improved risk-coverage tradeoffs (AURC reduced from 0.33–0.44 to 0.17–0.22) for guardrail decision ranking and abstention. The work matters for anyone building auditing or eval pipelines for opaque safety classifiers without privileged access to their internals.

CorrectGuard

evals, researchΒ· Added 5 Oct 2026, published 2 Oct 2026

github.comrepo🧠 AI

Folkbench/folkbench

Folkbench has two parts. One is a public benchmark and leaderboard of third-party AI API relay (中转站) services. Multi-node probes run around the clock and publish availability, P95 latency and price per relay, with per-model rankings. The other is Switch, an open-source Tauri/Rust desktop client that stores several Base URL and API Key pairs. It applies them to Claude Code or Codex configs in one click, previews config diffs, and stashes and restores the official ChatGPT OAuth credentials when switching Codex to a third-party provider. It also keeps keys local and estimates token usage and cost per session. The README also profiles several relay services, such as Modelflare, CheapAI and ApiPorter, and that part reads as promotional.

TauriRustClaude Code+5
FolkbenchSwitchChatGPT+8

evals, ai-infra, coding-agentsΒ· Added 12 Oct 2026, published 2 Oct 2026

socket.devwriteupπŸ›‘οΈ Security

Pretty Themes, Hidden Loaders: GlassWorm-Linked Extensions Span VS Code Marketplace and Open VSX

Socket's Threat Research team uncovered a theme-extension cluster spanning four VS Code Marketplace and six Open VSX listings, including two confirmed malicious extensions: Aurora Nocturne Night Theme (a Windows downloader that fetches and silently executes temp_batch.cmd via cmd.exe from fingercakes4sale[.]store, tied to XWorm C2 infrastructure) and Cosmic Nebula Themes, whose app.js decrypts an AES-256-CBC embedded stage and uses a Solana transaction memo as a dead-drop to resolve follow-on payload infrastructure β€” the same AES key, Solana address, and execution model previously documented in GlassWorm activity. Git commit identities, near-identical theme source, shared Russian-language developer comments, and brandjacking (Coca-Cola, Aurora Borealis name-squatting) link the cluster together; a Dec 14, 2025 DEV Community article is assessed as promotional infrastructure driving Open VSX installs. The post provides full IOCs (hashes, domains, Solana address, AES key/IV, GitHub accounts) and MITRE ATT&CK mappings for defenders to hunt and inventory extensions across both registries.

VS CodeOpen VSXSolana+3
GlassWormXWormAurora Nocturne Night Theme+13

Supply Chain, Malware & RE, Threat IntelΒ· Published and added 2 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

AuraForge: Scaling Security Supervision for Training Coding Agents

AuraForge is a method for synthesizing and validating executable security tests to train coding agents toward secure (not just functionally correct) code, combining attack-oriented test synthesis, multi-language task construction, and safeguards against reward hacking. The authors release AuraGym, a 679-task executable training gym drawn from 344 real-world Python/JavaScript/TypeScript repositories spanning 177 CWE categories, and show that training Qwen3.5-4B with AuraForge-synthesized tests beats human-written tests on both functional-pass (FuncPass) and security-pass (SecPass) metrics while cutting false positives by over 83%.

QwenPythonJavaScript+1
AuraGymQwen3.5-4B

AI Security, AppSecΒ· Added 3 Oct 2026, published 1 Oct 2026

arxiv.orgpaper🧠 AI

AuraForge: Scaling Security Supervision for Training Coding Agents

AuraForge is a pipeline that synthesizes and validates executable security tests to supervise the training of coding agents, using attack-oriented test synthesis and safeguards against reward hacking. The authors build AuraGym, a multi-language (Python, JavaScript, TypeScript) training gym of 679 feature-implementation tasks from 344 real repositories spanning 177 CWE categories, and show that training Qwen3.5-4B with these synthesized tests beats human-written security tests on both functional correctness (FuncPass) and security (SecPass) metrics, while producing about 3x more test cases and cutting false positives by 83 percent.

Qwen3.5PythonJavaScript+1
AuraForgeAuraGymQwen3.5-4B

research, training, coding-agentsΒ· Added 2 Oct 2026, published 1 Oct 2026

arxiv.orgpaper🧠 AI

Ranking-Aware Prompt Optimization for Multimodal Clinical Diagnosis

The paper introduces Ranking-PE, a modification to reflective prompt-optimization methods like GEPA that replaces per-instance accuracy scoring with pairwise AUROC-equivalent scoring (via the Wilcoxon-Mann-Whitney identity) across the scores matrix, reflection feedback, and candidate selection. Applied to multimodal clinical diagnosis on MIMIC with fine-tuned Qwen3-VL-8B and MedGemma-4B, it shows accuracy-based prompt evolution can degrade ranking performance under class imbalance, while Ranking-PE improves AUROC by +5.8pp and +16.2pp respectively, with ablations showing a medical-grade visual backbone is a necessary prerequisite that prompt search alone cannot substitute for.

Qwen3-VLvision-language model
GEPAMedGemma-4BMIMIC

research, prompting, multimodalΒ· Added 1 Oct 2026, published 30 Sep 2026

arxiv.orgpaper🧠 AI

Reliability-Gated Fusion of Consumer Head and Foot IMUs for Lower-Body 3D Pose

This paper introduces a channel-gated fusion model for sparse inertial motion capture that learns per-channel, per-stream temporal gates to weight the reliability of consumer earbud head IMU and smart-insole foot IMU signals, trained with an auxiliary reliability objective on synthetically corrupted data. On a new 35-take benchmark (using SAM-3D-Body pseudo-ground-truth labels), the gated model achieves 69.4mm error on clean data and remains most robust across simulated bias, drift, and dropout faults, automatically suppressing biased firmware-fused foot-orientation channels without test-time supervision (dropout detection AUROC 0.92-0.999). It is compared against a fine-tuned HMD-Poser baseline, which is more accurate on clean data (64.4mm) but degrades far more under worst-case faults (+16.1mm vs +3.5mm).

IMU
SAM-3D-BodyHMD-Poser

research, multimodalΒ· Added 29 Sep 2026, published 28 Sep 2026

arxiv.orgpaper🧠 AI

A Unified Uncertainty Representation for Graph Neural Networks via Doubly-Spectral Stochastic Expansion

Proposes a doubly-spectral stochastic (DSS) expansion for graph neural networks that unifies calibration, out-of-distribution detection, and distribution-shift robustness in a single representation: graph Fourier filters capture structural variation while an orthogonal-polynomial chaos coordinate captures latent stochastic variation. DSS-GNN (standalone) achieves the lowest Brier score across 14 node classification benchmarks without post-hoc correction, and DSS-Hybrid (a residual branch beside a deterministic encoder) achieves the best AUROC on most node-OOD settings and strongest shifted accuracy on all 7 GOOD concept-shift benchmarks under standard ERM. A capacity theorem shows the method matches chaos coefficients of Gaussian-latent random graph signals under full-rank assumptions with exponentially decaying truncation error.

GOOD

researchΒ· Added 29 Sep 2026, published 28 Sep 2026

github.comrepo🧠 AI

awslabs/mcp release 2026.09.20260922000649

This is a release changelog for awslabs/mcp, AWS Labs' collection of Model Context Protocol servers covering services like HealthOmics, Aurora DSQL, Bedrock Knowledge Base retrieval, ECS, CloudWatch, billing/cost management, and dataprocessing. This release adds vended metrics tools, SQL parser-based policy guards for Aurora DSQL, agentic retrieval support for Bedrock KB, and fixes several security issues including region validation to prevent SSRF credential disclosure in the CloudWatch server and read-only mode bypass in the MySQL server. It reflects an actively maintained, high-velocity multi-server MCP monorepo used for AWS tool integration with LLM agents.

Model Context ProtocolPythonFastMCP
AWSAWS HealthOmicsAurora DSQL+4

mcpΒ· Added 26 Sep 2026

arxiv.orgpaperπŸ›‘οΈ Security

Cyber-Financial Contagion: Modeling the Propagation of an AI Vendor Compromise Through the Banking System

This arXiv paper models how a security compromise inside a shared AI vendor (used for fraud screening, credit decisioning, AML triage) can propagate through operational, informational, and financial linkages to trigger banking-system-wide losses. The authors build CFC-Prop, a stochastic epidemic-and-clearing model on a synthetic four-layer network of 60 AI vendors, 220 banks, ~2,500 vendor-bank edges, and 1,400 interbank exposures, showing heavy-tailed loss distributions driven by patch latency, and CFC-GNN, a graph neural network early-warning classifier (AUROC 0.82, AUPRC 0.60) that flags high-cascade-risk vendors from incident telemetry. Code and synthetic data are released, framing AI-vendor cyber concentration as a first-order financial-stability risk.

AI Security, GRC, Supply ChainΒ· Added 26 Sep 2026

arxiv.orgpaper🧠 AI

BeatGraph: Self-Supervised Heartbeat Graphs for Infant ECG Representations from the Home Environment

BeatGraph is a self-supervised ECG representation model that tokenizes signals at the level of individual heartbeats rather than fixed-length patches, using a shared beat encoder, a Transformer for temporal ordering, and residual graph attention layers to relate beats within a 30-second window, pretrained via masked-beat embedding prediction. Evaluated on a new 3,408-hour, 143-infant home/classroom/lab ECG corpus, it improves macro-F1 over baselines by 0.076–0.158 on sleep-wake, infant-state, activity-source, and affect tasks, and transfers well to the pediatric ZZU-pECG benchmark (0.892 AUROC) and adult PTB-XL under linear evaluation despite infant-only pretraining.

Transformer
BeatGraphZZU-pECGPTB-XL+1

research, multimodalΒ· Added 28 Sep 2026, published 25 Sep 2026

endorlabs.comarticleπŸ›‘οΈ Security

Vulnerability Blast Radius: How to Measure and Reduce Impact | Blog | Endor Labs

Endor Labs blog post explaining CVE-2024-3596 (BlastRADIUS), a critical design flaw in the RADIUS authentication protocol where an on-path attacker uses a chosen-prefix MD5 collision to forge an Access-Accept response and bypass authentication on VPNs, firewalls, and network devices using RADIUS over UDP with non-EAP methods. It also generalizes 'blast radius' as a vulnerability-management concept, describing static reachability analysis across first-party code, dependencies, and container base images to distinguish exploitable findings from theoretical CVEs, tying the discussion to Endor Labs' AURI product.

RADIUSFreeRADIUSEndor Labs
CVE-2024-3596CVE-2021-44228chosen-prefix MD5 collision

AppSec, Identity & Access, Supply ChainΒ· Published and added 21 Sep 2026

endorlabs.comarticleπŸ›‘οΈ Security

AI-Generated Malware Risk: A Practical Guide for Developers | Blog | Endor Labs

An Endor Labs guide explaining how AI-generated and AI-enhanced malware (citing Check Point's VoidLink, Google TIG's PROMPTFLUX/PROMPTSTEAL, and HYAS Labs' BlackMamba/EyeSpy) differs from traditional threats by dynamically mutating code at runtime to evade signature-based detection. It argues software supply chains are a prime target because AI can mass-produce convincing typosquatted or dependency-confused packages, and recommends behavioral analysis plus full-stack reachability analysis (via Endor Labs' AURI) as defenses instead of relying solely on CVE/signature matching.

Endor LabsnpmPyPI
VoidLinkPROMPTFLUXPROMPTSTEAL+7

AI Security, Supply ChainΒ· Published and added 11 Sep 2026

endorlabs.comarticleπŸ›‘οΈ Security

Common C/C++ Vulnerabilities: A Practical Guide to Prevention | Blog | Endor Labs

Endor Labs guide to C/C++ memory-safety and input-handling vulnerabilities β€” buffer overflow (CWE-787/120/121), use-after-free (CWE-416), null pointer dereference (CWE-476), integer overflow (CWE-190), and format string bugs (CWE-134) β€” with vulnerable/fixed code snippets for each. It surveys detection tooling (Coverity, CodeQL, Clang Static Analyzer, AFL++/libFuzzer with ASan/UBSan, OSS-Fuzz) and argues that build-system complexity (Bazel, CMake, Conan, vcpkg) and high SAST false-positive rates make reachability analysis necessary, closing with a pitch for Endor Labs' AURI reachability engine.

Endor LabsCodeQLAURI+1
CWE-787CWE-416CWE-476+4

AppSec, LearningΒ· Published and added 11 Sep 2026

endorlabs.comarticleπŸ›‘οΈ Security

Cursor Security: How to Secure AI-Generated Code in 2026 | Blog | Endor Labs

Endor Labs blog post detailing seven security risks specific to Cursor's AI code generation that its built-in controls (workspace trust, SOC 2, privacy mode) don't cover: indirect prompt injection via files/comments, malicious .cursorrules files creating persistent backdoors, AI-suggested typosquatted or outdated dependencies, hardcoded credential leakage in generated test/boilerplate code, cross-project context poisoning via repository indexing, and unreviewed agent auto-run execution. It contrasts Cursor's native controls with what external AppSec tooling (pitched as Endor Labs' AURI) needs to fill, recommending dependency pinning, egress filtering, secret-scanning pre-commit hooks, and reachability-based SCA/SAST.

CursorEndor Labs
AURI

AI Security, Supply ChainΒ· Published and added 11 Sep 2026

snyk.ioarticleπŸ›‘οΈ Security

Is prevention essentially a solved problem?

A Snyk blog post arguing that preventing new vulnerabilities in agent-generated code is architecturally solved, using Laurie Voss's nested "loop" model (execution/task/product/system/oversight) to map four control types β€” in-context guidance, deterministic scanning inside the agent loop (Snyk's Trusted Output Assurance), LLM-based semantic analysis for authz/business-logic flaws like IDOR, and adversarial pentesting/red-teaming (Snyk's Continuous Offensive Security) β€” to the points in the SDLC where each is cost-effective. It cites Snyk VulnBench JS 1.0 data showing nearly half of LLM-found vulnerabilities appear in only one of five identical review runs, illustrating why single-pass LLM scanning needs repetition to be trusted, and closes by distinguishing solved "prevention" from unsolved "remediation" of existing vulnerability backlogs.

Snyk
IDORVulnBench JS 1.0Laurie Voss+3

AI Security, AppSec, DevSecOpsΒ· Published and added 10 Sep 2026

huggingface.cowriteup🧠 AI

Rebuilding AUTOMATIC1111 with Gradio Workflow

A Hugging Face blog post walking through Workflow1111, a 73-node graph built with Gradio's gr.Workflow that reimplements most of AUTOMATIC1111's stable-diffusion-webui feature set as a single visual canvas: text-to-image, hi-res fix, image-to-image, prompt matrix, VLM interrogation, detection-to-inpaint masking, ControlNet-style annotators, background removal, PNG metadata round-tripping, and image-to-video, wired from models like FLUX.1-Kontext, Qwen3-4B, Qwen2.5-VL, DETR, AuraSR, BRIA RMBG-2.0, and Wan 2.2 I2V A14B. It contrasts gr.Workflow with ComfyUI, shows that every output node auto-becomes both a REST endpoint and an MCP tool (usable by Claude Code or Cursor), and demonstrates running nodes locally on your own GPU via ZeroGPU (FastVideo/fastvideo-fasth3-preview) instead of hosted inference.

GradioHugging FacePython+5
AUTOMATIC1111gr.WorkflowWorkflow1111+14

llm-apps, multimodalΒ· Added 29 Sep 2026, published 10 Sep 2026

endorlabs.comarticleπŸ›‘οΈ Security

The real test of AI-native code analysis: is your security debt shrinking? | Blog | Endor Labs

Endor Labs argues that AI-native code analysis tools should be judged by whether they actually shrink security debt, not by how many findings or patches they generate. It cites data showing coding agents increase code duplication and reduce review rigor (GitClear, DORA, Faros AI), that AI-generated findings are often false positives (Comcast: 44% of validated critical/high findings), and that agents can pass functional tests while shipping insecure code (Agent Security League: 84.4% correct vs 7.8% secure), then lays out six requirements for analysis tools (deterministic evidence, impact-ranked findings, remediation-grade context, fix validation, shift-left coverage, independent measurement) and six questions to ask vendors, tying back to Endor Labs' own AURI product.

Endor LabsAURI
Agent Security League1PasswordDORA+5

AppSec, AI SecurityΒ· Added 3 Sep 2026, published 31 Aug 2026

github.comrepoπŸ›‘οΈ Security

archcanary

Archcanary is a read-only, layered detection scanner for Arch Linux (and derivatives like EndeavourOS/Manjaro) that checks installed packages, pacman logs, systemd units, eBPF programs, ld.so.preload, DKMS kernel modules, and npm/bun/yarn/pnpm caches against curated and third-party (aur-audit.wtako.net) threat lists. It was built in direct response to a 2026 AUR supply-chain attack in which commit forgery was used to impersonate maintainers and inject npm/bun install hooks delivering an infostealer (Discord tokens, GitHub PATs, SSH keys, Vault tokens) and a CAP_BPF eBPF rootkit into 1600+ PKGBUILDs, plus a separate Russian-spam PKGBUILD injection campaign. It integrates with yay/paru pre-build hooks, systemd timers, auditd, and Lynis, and originated as a fork/expansion of lenucksi/aur-malware-check.

Arch LinuxAURnpm+3
CHAOS RATaur-audit.wtako.netlenucksi/aur-malware-check+8

Supply Chain, Blue Team & Detection, Cloud & InfraΒ· Published and added 21 Aug 2026

specterops.iowriteupπŸ›‘οΈ Security

AWSHound: An Open-Source AWS OpenGraph Collector

AWSHound is a free, self-hosted, read-only collector that turns an AWS account or Organization into a BloodHound Community/Enterprise Edition OpenGraph dataset, performing offline IAM policy evaluation (identity policies, permissions boundaries, SCPs/RCPs, resource policies, and a KMS-specific three-layer model) so that graph edges only represent effective, resolved permissions rather than raw policy attachments. The post details nine collectors (IAM, Organizations, S3, KMS, SSM, EC2, Lambda, CloudFormation, EKS), 156 edge types (only 36 traversable), composite escalation edges like AWS_CanCreateAndAssumeAdminRole, and walks through same-account and cross-account-to-org-compromise attack path demos, plus benchmarks at 500+ account scale (~160k nodes, ~10.5M edges in ~15 min) and comparisons to prior tools (ApeMan, PMapper, Aurelian, Cartography, CloudMapper, IAMhounddog).

AWSHoundBloodHoundAWS+3
ApeManPMapperAurelian+5

Cloud & Infra, Offensive SecurityΒ· Added 5 Sep 2026, published 19 Aug 2026

endorlabs.comarticleπŸ›‘οΈ Security

What is an agent harness? The software that turns a model into an agent | Blog | Endor Labs

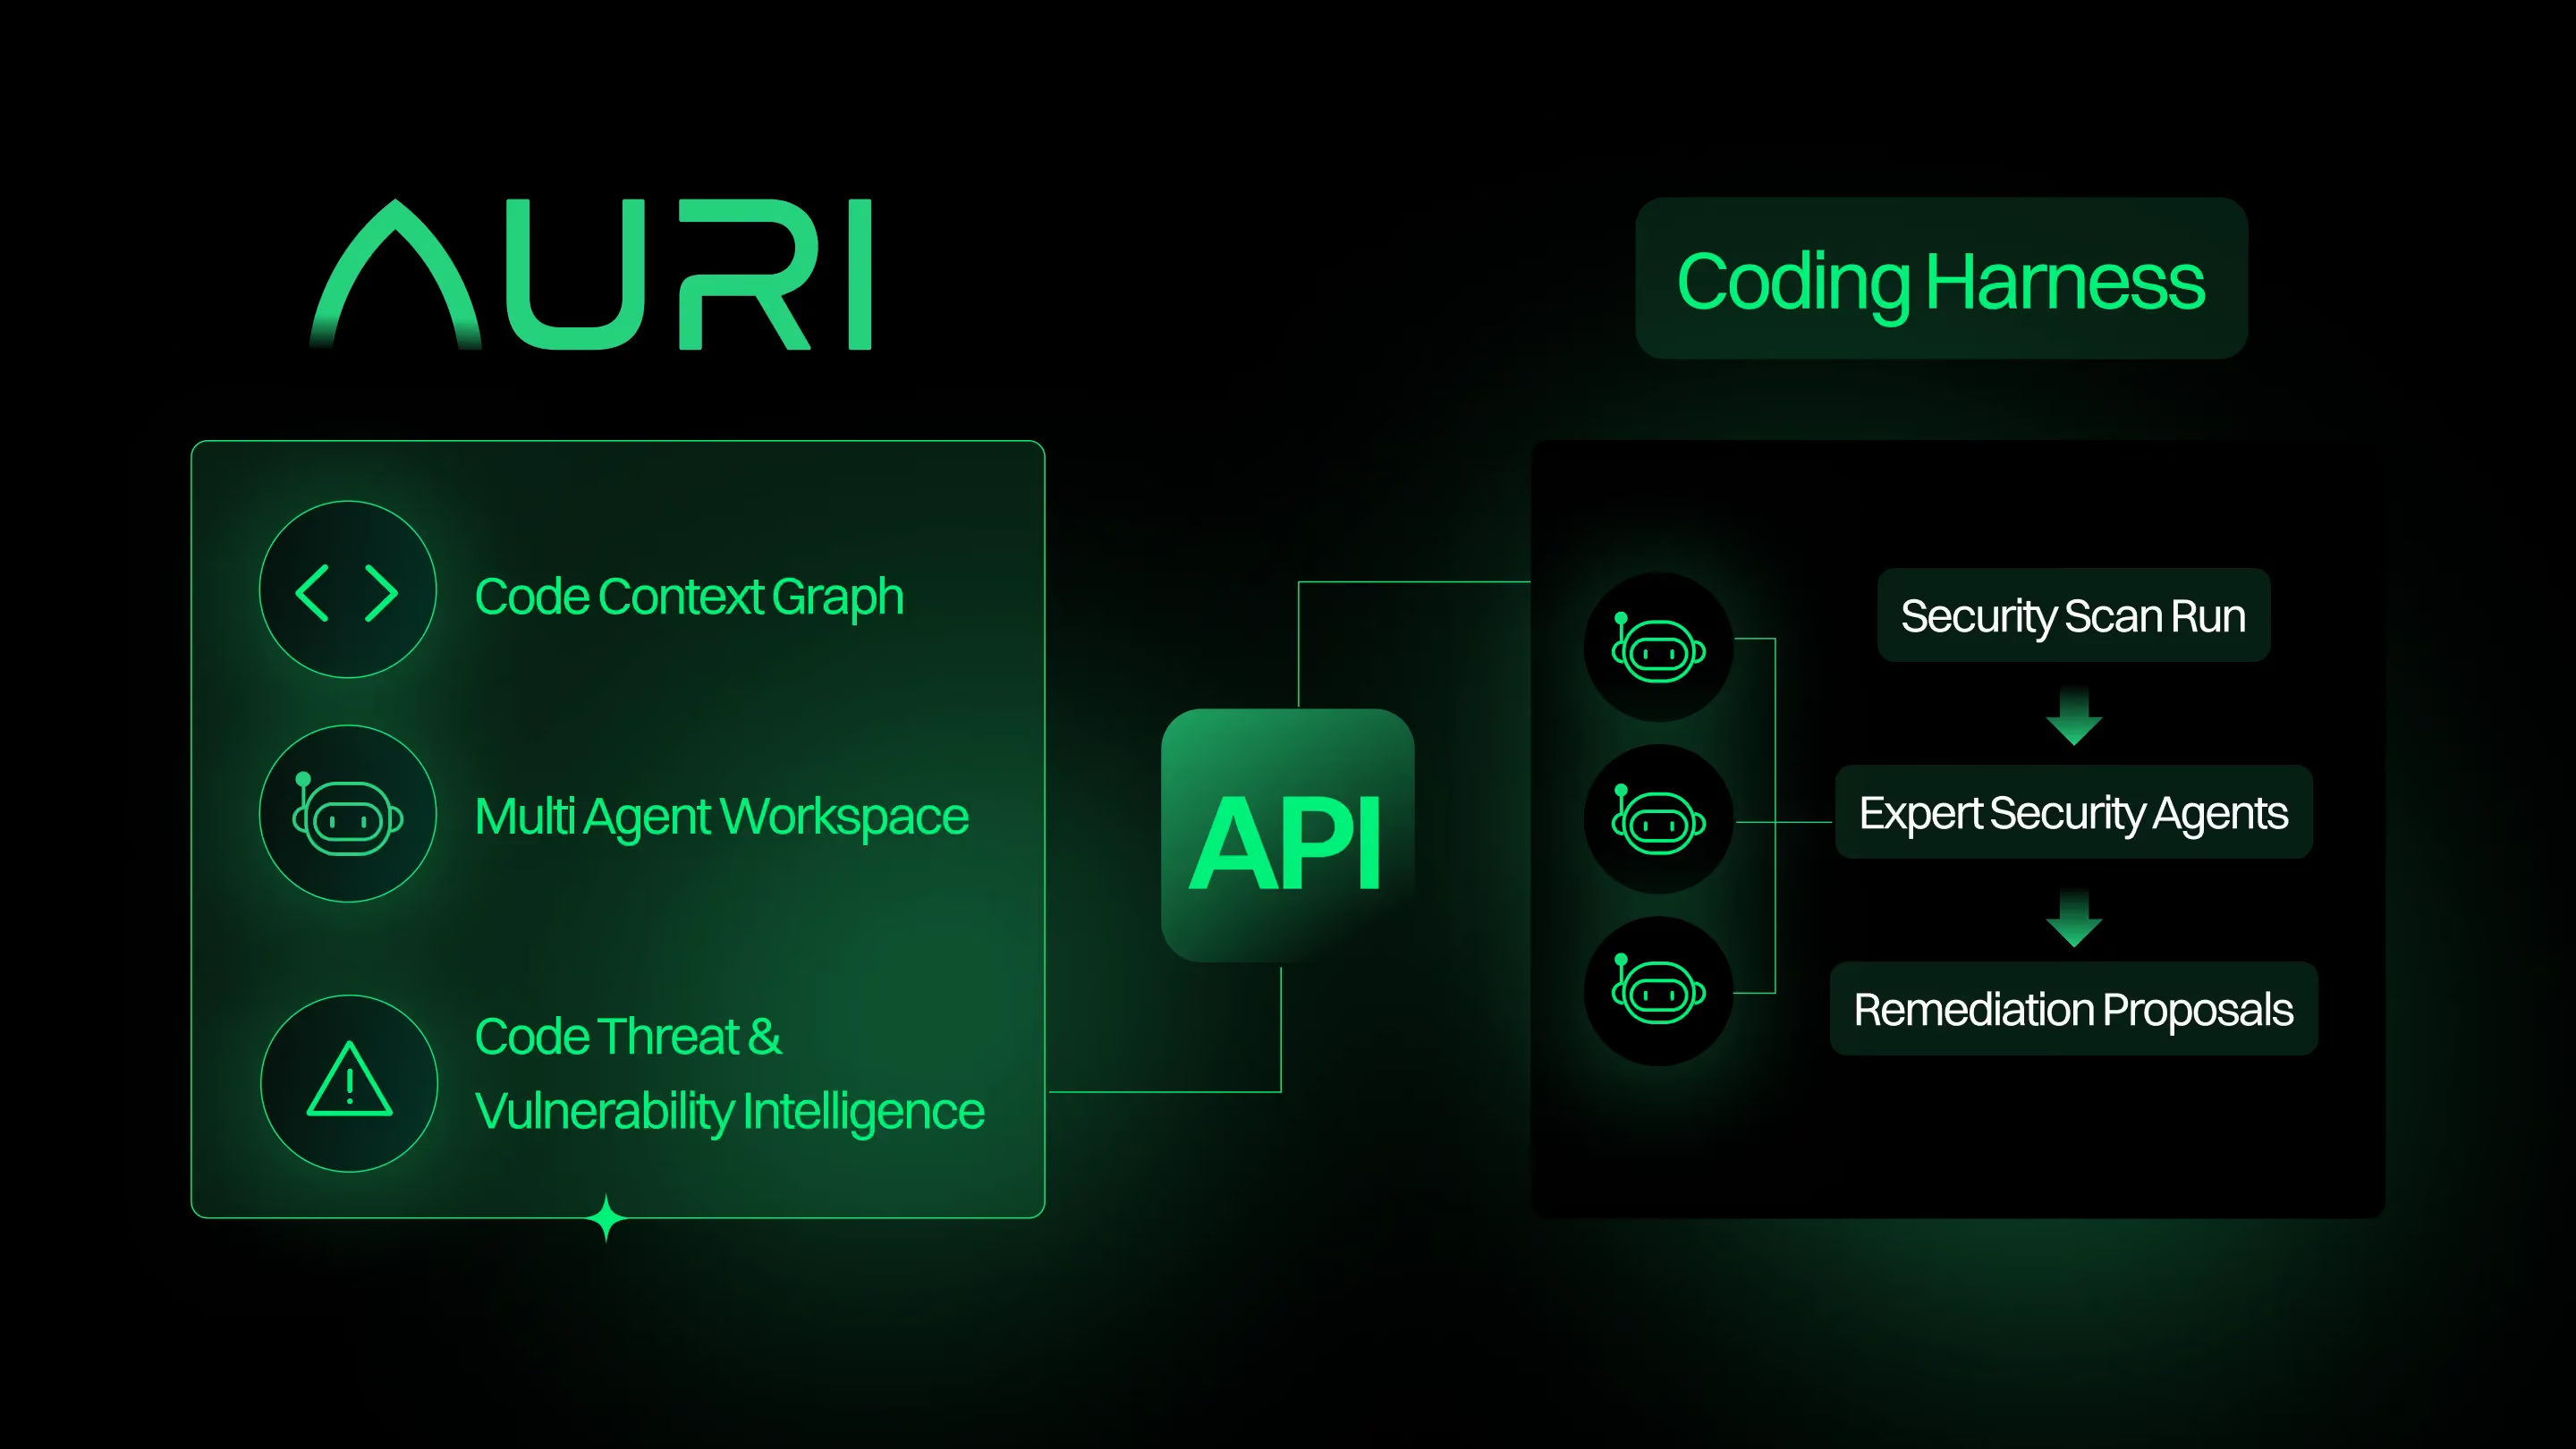
Endor Labs explainer arguing that an AI agent's "harness" (orchestration loop, tool calling/MCP, memory, sandboxes, permission guardrails) - not the underlying LLM - is what determines both capability and attack surface. It walks through concrete harness-level risks (prompt injection as OWASP's LLM01, MCP servers as unvetted dependencies, permission sprawl) and pitches deterministic lifecycle hooks (as used in Claude Code/Cursor via Endor's AURI) as a jailbreak-proof control layer, citing Endor's Agent Security League benchmark where Cursor+Fable 5 beat Claude Code and Codex on both functional and security correctness.

Model Context ProtocolClaude CodeCursor+3
Agent Security LeagueOWASP Top 10 for LLM ApplicationsClaude Fable 5+1

AI SecurityΒ· Added 3 Sep 2026, published 15 Aug 2026

github.comrepoπŸ›‘οΈ Security

aurscan

aurscan is a Go-based CLI that hooks into yay/paru to scan a downloaded AUR package's PKGBUILD, .install scriptlets, .SRCINFO and helper scripts before makepkg runs, blocking the build if it looks malicious. It combines offline, quote-aware static rules covering known AUR campaign signatures such as disguised source patch URLs, install-scriptlet worms, masqueraded binary file types, and editor auto-exec triggers with an LLM auditor (Claude Code, Codex, Anthropic API, or a local OpenAI-compatible model) that answers a fixed checklist of yes/no behavioral questions, from which aurscan deterministically derives a verdict, severity and confidence, and fails closed when no backend is available. It documents and defends against real incidents including the July 2025 firefox-patch-bin CHAOS RAT vector, the June 2026 Atomic Arch mass orphan-package takeover pulling a Rust stealer and eBPF rootkit, and the August 2026 xsnow dot-install worm that harvested SSH keys and self-propagated across AUR.

GoClaude CodeCodex CLI+3
CHAOS RATAtomic Archxsnow+4

Supply Chain, AI SecurityΒ· Published and added 8 Aug 2026

stepsecurity.iowriteupπŸ›‘οΈ Security

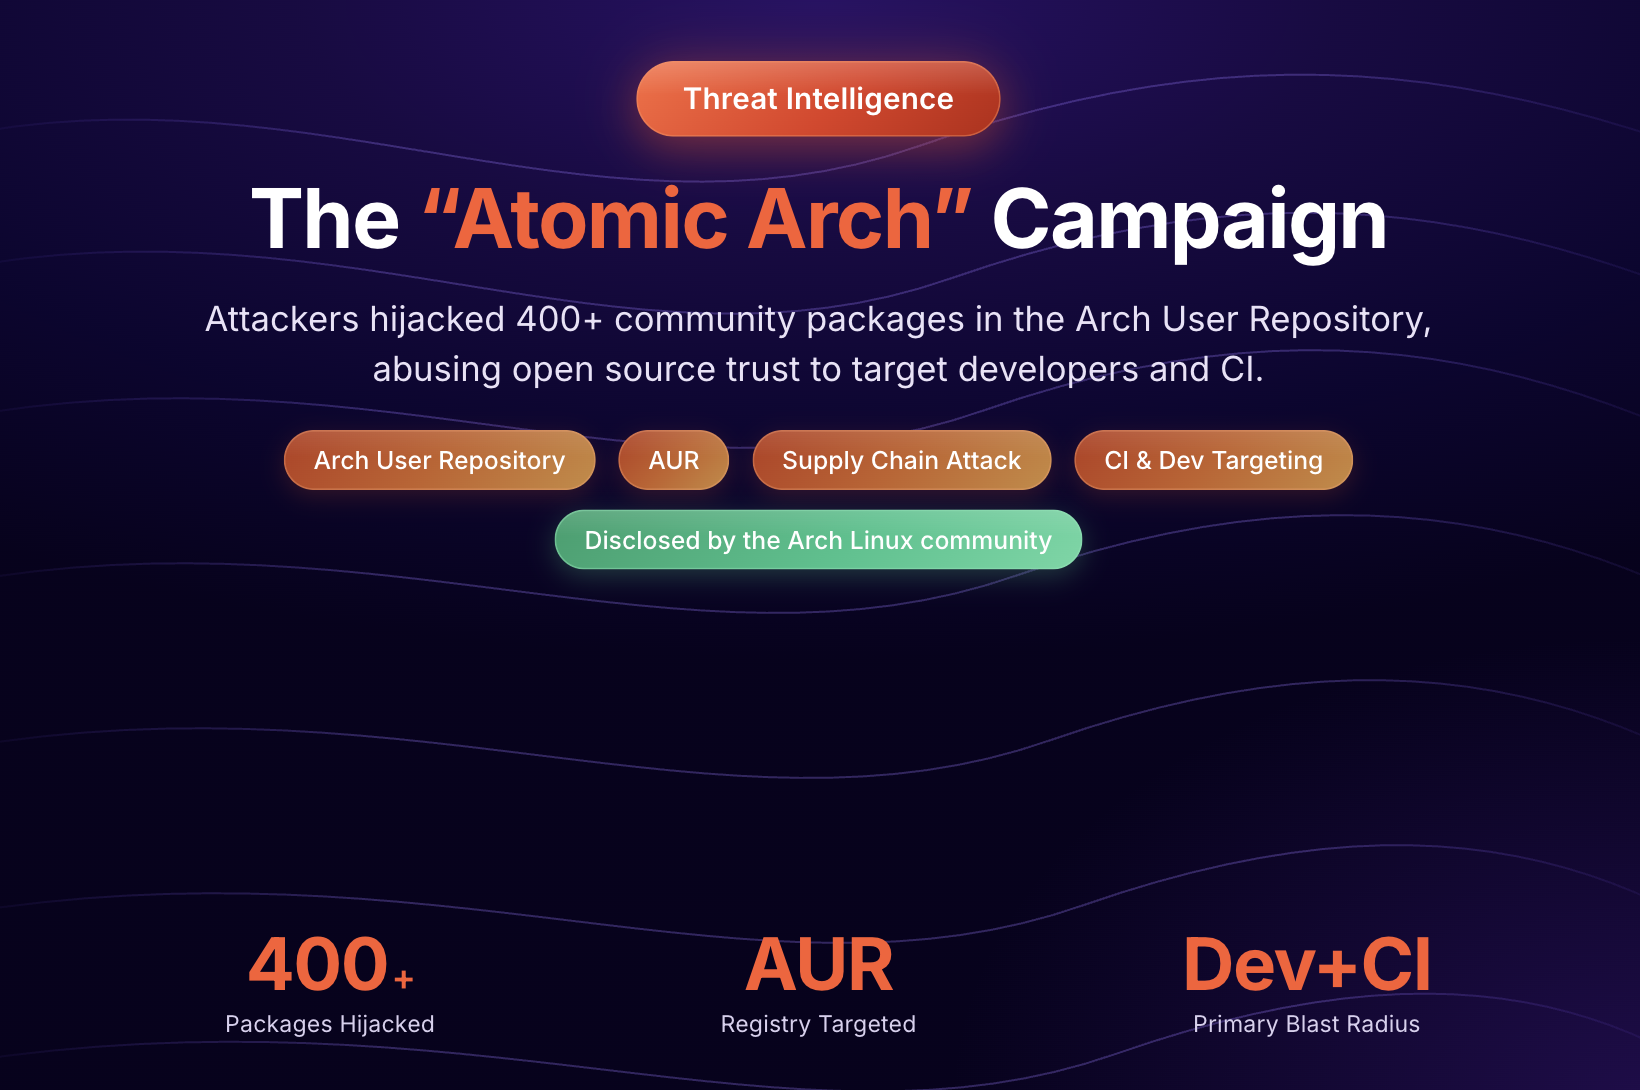
400+ AUR Packages Hijacked: What the β€œAtomic Arch” Campaign Means for Supply-Chain Security

Attackers adopted 400+ orphaned AUR (Arch User Repository) packages and injected malicious build logic that pulled in a malicious npm dependency (masquerading as atomic-lockfile, also seen as js-digest), dubbed the "Atomic Arch" campaign by Sonatype researchers. The malicious npm package deploys a Rust-based credential stealer targeting browser cookies, SSH keys, GitHub/npm tokens, and cloud/Docker credentials, with optional eBPF-based rootkit persistence on rooted systems. The piece explains scope (Arch, EndeavourOS, Manjaro, WSL2-based Arch, self-hosted Arch CI runners) and draws parallels to similar ownership-hijacking risks in npm, PyPI, GitHub Actions, and Homebrew.

AURnpmArch Linux+3
SonatypeAtomic Archatomic-lockfile+2

Supply Chain, Malware & RE, Threat IntelΒ· Added 3 Sep 2026, published 18 Jun 2026

endorlabs.comarticle🧠 AI

Endor Labs: AURI Agents

Endor Labs announces AURI Agents, a free catalog of pre-configured security agents (SCA Remediation, AI SAST Triage, Probe Droid, Endor Troubleshooter and six more). They run inside Claude Code, Codex, Cursor and similar hosts, using the user's own LLM keys and git credentials (GitHub via gh, GitLab via glab). The open-source Endor Labs Agent Kit defines each agent as a YAML Source Recipe plus markdown instructions, compiles it into per-host artifacts, and ships a skill that helps users author new agents with eval cases. Endor claims expert agents finish tasks 2.8x faster with 92% fewer tokens than an unaugmented agent. Mutating actions require confirmation and most agents are read-only.

Claude CodeCodexCursor+6
Endor LabsGitLab

coding-agents, agentsΒ· Added 10 Oct 2026, published 17 Jun 2026

endorlabs.comarticleπŸ›‘οΈ Security

Endor Labs: AURI Agents

Endor Labs announces AURI Agents, twelve pre-configured AI agents (SCA Remediation, AI SAST Triage, Probe Droid, Endor Troubleshooter and others) that use Endor's reachability, upgrade-impact and policy data. They install into Claude Code, Codex, Cursor and similar hosts, and run on the customer's own LLM keys and git credentials (GitHub via gh, GitLab via glab). The open-source Endor Labs Agent Kit defines each agent as a YAML Source Recipe plus markdown instructions, compiled for each host, with a skill for authoring new agents. Most agents are read-only by default, and the ones that mutate state declare their permissions and require confirmation.

Endor LabsAURIClaude Code+3
AURI AgentsEndor Labs Agent KitProbe Droid+1

AI Security, AppSec, Supply ChainΒ· Published and added 17 Jun 2026

reco.aiwriteupπŸ›‘οΈ Security

Salesforce Pentest: Apex Predator

A deep technical guide from Reco on pentesting Salesforce Experience Cloud "Aura" sites, covering how to enumerate guest-user-accessible sObjects via HostConfigController and SelectableListDataProviderController, and how to discover and invoke custom server-side Apex controller methods exposed to guest/authenticated users. It introduces novel techniques for extracting Apex method parameters from compiled Lightning Web Component JS (via the lri/moduleDefs structures), using ComponentController.getComponent and siteforce:routerInitializer to enumerate every site route/page and its Apex-backed components beyond what standard tools like AuraInspector find, plus an appendix of undocumented native controllers including an Aura-exposed GraphQL execution endpoint (RecordUiController.executeGraphQL). It closes with defensive guidance on monitoring AuraRequest events via Salesforce Shield to detect abuse.

SalesforceGraphQLBurp Suite

Offensive Security, AppSecΒ· Added 3 Sep 2026, published 13 May 2026

github.comrepo🧠 AI

Cowork Forge

Cowork Forge is an open-source Rust framework (cowork-core, cowork-cli, cowork-gui built on adk-rust and Tauri+React) that simulates a full software development team as cooperating LLM agents — Product Manager, Architect, Project Manager and Engineer roles — running a 7-stage pipeline (Idea→PRD→Design→Plan→Coding→Check→Delivery) with actor-critic self-review loops and human confirmation gates. It supports importing/reverse-engineering existing codebases into structured artifacts, a post-delivery "PM Agent" for iterative changes, a data-driven JSON config system for custom agent/flow/skill definitions (using the agentskills.io standard), and Agent Communication Protocol (ACP) integration with external coding agents like OpenCode, Codex, Gemini CLI and Claude CLI.

RustTauriReact+3
Cowork Forgeadk-rustOpenCode+5

agents, coding-agentsΒ· Added 22 Sep 2026, published 13 May 2026

huntress.comwriteupπŸ›‘οΈ Security

Data Exfiltration and Threat Actor Infrastructure Exposed

Huntress SOC details two related incidents where threat actors used PsExec for privilege escalation, a scheduled task ("Recovery Diagnostics") to run base64-encoded PowerShell that configured a renamed copy of restic (winupdate.exe) pointed at a Wasabi S3 bucket, then disabled/removed VIPRE Business Agent and Windows Defender before deploying INC ransomware. A second, near-identical prior incident on 9 February reused the same AWS access keys and used HRSword to disable Acronis security tooling, and the same TTPs were independently documented by the Cyber Centaurs team on 22 January 2026. The post highlights detection gaps (incomplete agent deployment, no SIEM) and notes RestartManager API telemetry (also seen with Akira) as a ransomware-encryption indicator.

PowerShellWindowsWindows Defender+3
INC ransomwareAkiraHRSword+2

Blue Team & Detection, Threat IntelΒ· Added 3 Sep 2026, published 12 Mar 2026