Skip to content

67 results for “Scale”

What you seeeverything
securityweek.comarticle🛡️ Security

UK Cyber Chief Says the UK Will Face AI Cyberattacks on Critical Infrastructure by 2028

SecurityWeek reports on the UK National Cyber Security Centre's annual report, presented by NCSC head Richard Horne. It warns that criminals and states, including China and Russia, will likely use AI against UK critical infrastructure by 2028, mainly to scale existing techniques. It cites nearly $20 billion in yearly UK losses, Jaguar Land Rover's $260 million loss in 2025, and the FSB-attributed December 2025 attack on Poland's energy grid.

National Cyber Security CentreGCHQFSB+3

Threat Intel, AI Security, GRC· Published and added 3 Nov 2026

longcat.aiarticle🧠 AI

LongCat-2.5: Native Multimodality for Agentic Tasks

LongCat-2.5 is a native multimodal mixture-of-experts model with 1.6 trillion total and about 48 billion activated parameters, built on LongCat-2.0 for long-horizon agentic coding. The post describes discrete RVQ visual tokens, large-scale asynchronous agentic RL with synthesized F2P/P2P-tested environments, on-policy distillation, train-inference numerical alignment, and W4A4 inference on domestic accelerators. A table compares it with GPT-5.5, Claude-Opus-5, GLM-5.3, Kimi K3 and DeepSeek-V4.1-Flash.

Mixture of ExpertsResidual Vector QuantizationFlatQuant+8
LongCat-2.5LongCat-2.0LongCat-Next+32

models, training, multimodal, coding-agents· Added 3 Nov 2026, published 2 Nov 2026

blog.trailofbits.comarticle🛡️ Security

Backporting security fixes at scale with Codex

Trail of Bits describes a Codex (GPT-5.6) workflow that backports security fixes to stable Linux kernel trees, Ubuntu LTS and Fedora. By 29 October 2026 it had helped land fixes for 149 CVEs in stable kernels. Agents find missing fixes, adapt patches and assemble validation evidence; a human review takes about 30 minutes to 3 hours. It also sizes the unfixed-CVE backlog in kernel branches, Debian 13 and Ubuntu 26.04.

CodexLinux kernelLinux+3
CVE-2026-98432Trail of BitsPatch the Planet+1

AI Security, AppSec, Cloud & Infra· Published and added 2 Nov 2026

blog.trailofbits.comarticle🧠 AI

Backporting security fixes at scale with Codex

Trail of Bits describes a Codex agent workflow that backports security fixes to stable Linux kernel trees and distro packages. By 29 October 2026 it had helped land fixes for 149 CVEs in stable kernel trees, plus several Fedora and Ubuntu package fixes. Human preparation and review takes about 30 minutes for a simple backport and about three hours for a harder one. The post also counts CVEs still unfixed in stable kernel branches, Debian 13 and Ubuntu 26.04.

CodexLinuxUbuntu+2
Trail of Bits

coding-agents· Published and added 2 Nov 2026

eva.acarticle🛡️ Security

So I guess everyone uses LLMs to think now

The eva.ac author argues that recent AI-credited vulnerability findings come from skilled researchers steering LLMs, and that AI firms use disclosures as marketing. Cases cited: Calif, OpenAI and Wiz framing PHP2Shell differently; a hash teaser before the Tailscale "tailworm" privilege escalation (author's account: Tailscale not contacted); and the eMudhra CA key found without AI. No sources, dates or CVEs are given.

LLMOpenAIWiz+3
CalifeMudhraPHP2Shell+1

AI Security, other· Added 2 Nov 2026, published 1 Nov 2026

eva.acarticle🧠 AI

So I guess everyone uses LLMs to think now

"So I guess everyone uses LLMs to think now" is an opinion post from the eva.ac blog. The author explains why they never use LLMs for published research: they do it for fun and cannot take credit for model output. They argue LLMs still need skilled guidance, criticise AI-company security marketing (PHP2Shell from Calif, OpenAI and Wiz), and cite the Tailscale "tailworm" disclosure and the eMudhra key found without AI.

LLMPHPLinux+3
OpenAIAnthropicCalif+5

ai-policy· Added 2 Nov 2026, published 1 Nov 2026

wiz.ioarticle🛡️ Security

The Rise of Agentic Attacks: What They Look Like, and Where They're Headed

Wiz Research reviews agentic attacks seen in its incident response work and in public reports (ARTEX, Hermes, JPCERT/CC, CrowdStrike, DIVD). It derives fingerprints of AI-agent activity from three intrusions: machine-paced iteration, natural-language reasoning in scripts, self-correcting script versions, checklist enumeration, noisy lateral spraying, probe-before-payload and self-labeled scratch files. It also covers effects on attribution, attack scale and defense.

KubernetesAWSClaude Code+2
ARTEXHermesStorm-0940+12

Threat Intel, Blue Team & Detection, AI Security, Cloud & Infra· Published and added 29 Oct 2026

securityweek.comarticle🛡️ Security

Tailscale Rushes Patches After Uncoordinated Disclosure of ‘Tailworm’ Flaws

Tailworm is a set of 11 findings, published by Cyberdione Labs before patches, in Tailscale client 1.104.2 and headscale 0.29.5. Four of six high-severity bugs affect Tailscale SSH, where root-privileged forwarding safeguards can be bypassed, giving root on reachable servers and wormable spread at under a second per hop. Tailscale advises reviewing SSH policies and disabling forwarding until a patched client ships. No in-the-wild exploitation is reported.

TailscaleheadscaleSSH+2
TailwormCyberdione LabsMike Shaver+3

Offensive Security, AppSec· Published and added 27 Oct 2026

securityweek.comarticle🛡️ Security

This is Fine: What NetScaler Zero-Days Tell Us About the New Normal

This SecurityWeek commentary covers the September 2026 Citrix NetScaler ADC and Gateway zero-days, exploited from mid-month and patched on 27 September as unauthenticated RCE flaws CVE-2026-88771 through CVE-2026-88778. The author argues the fast response shows stronger defence. Cited evidence: Citrix disclosure time fell from about 40 days to 17 in 2026 after it set up a NetScaler CNA, and CISA made a rare Sunday KEV addition.

Citrix NetScaler
CVE-2026-88771CVE-2026-88772CVE-2026-88773+9

other, Threat Intel· Published and added 27 Oct 2026

brown.eduarticle🧠 AI

Brown student maps the hidden global labor powering AI

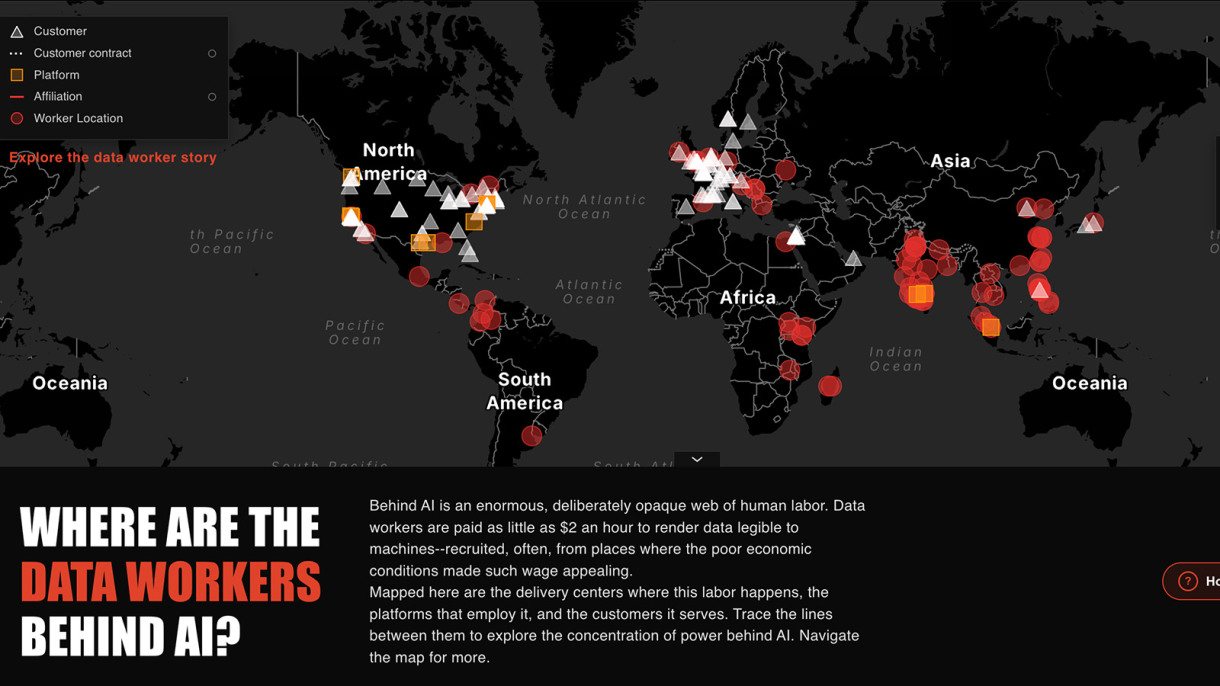
Brown University undergraduate Cunyan Ma built an interactive map linking technology companies and their intermediaries to data workers around the world, with the university's Center for Technological Responsibility, Reimagination and Redesign. The map combines existing data worker databases, Ma's own data collection and news reports on working conditions. It aims to show "AI colonialism" at scale, beyond anecdotal accounts. The page text ends early.

Brown UniversityCunyan MaCenter for Technological Responsibility, Reimagination and Redesign

training, ai-policy· Added 27 Oct 2026, published 26 Oct 2026

en.cryptonomist.charticle🧠 AI

Test-time training in robotics shows no clear gains in demo response

This article reports a study submitted October 23, 2026 by Qiangong Zhou, Jiafeng Liang, Yimin Dong, Yang He and Hongxiang Li. They added Test-Time Training (fast-weight memory) to the vision-language-action models InternVLA-A1 and Pi0.5, trained on paired human demonstrations and robot trajectories. Shorter videos, full-trajectory gradient connectivity and contrastive regularization gave no clear gain in demonstration-guided target selection at the tested scale.

vision-language-action modelTest-Time Training
InternVLA-A1Pi0.5Qiangong Zhou+4

research, multimodal, training· Published and added 26 Oct 2026

anthropic.comarticle🛡️ Security

LLMs are making formal software verification feasible at a much larger scale

Anthropic and Theorem report using Claude to write Rocq proofs that 239 fuzz entry points across 123 OSS-Fuzz libraries never crash on inputs under 64 MB, at the RISC-V binary level (about 180 million lines of proof). Claude patched the bugs it found along the way, including a rediscovery of a libexpat CVE and bugs fuzzers would miss. The post covers trusted components, limitations, token-cost trends and released proofs.

ClaudeRocqRISC-V+3
CVE-2026-56132TheoremOSS-Fuzz+5

AppSec, AI Security· Added 23 Oct 2026, published 22 Oct 2026

anthropic.comarticle🧠 AI

LLMs are making formal software verification feasible at a much larger scale

Anthropic and Theorem report that Claude wrote Rocq proofs of crash-freedom for 239 OSS-Fuzz entry points across 123 open-source libraries, working on compiled RISC-V binaries for inputs up to 64 MB. Proofs total about 180 million lines, and Claude found and patched bugs along the way. The post covers proof reuse (17% fewer tokens), Opus 5.5 using about 40% fewer tokens than Opus 5, and limitations.

RocqRISC-VVerus+10
CVE-2026-56132AnthropicClaude+11

research, coding-agents· Added 23 Oct 2026, published 22 Oct 2026

blog.cloudflare.comarticle🛡️ Security

Localizing compliance at scale: achieving South Korea’s ISMS certification

Cloudflare's account of obtaining South Korea's ISMS-P certification after a ten-day KISA audit of 80 controls and a preparation period of about a year and a half. It explains that the certificate covers a service delivery boundary rather than a product list, that auditors required readable data flow diagrams, and how Korean sign-up uses itemized consent with social login removed.

CloudflareCloudflare Workers
ISMS-PKISAPersonal Information Protection Act+5

GRC· Added 29 Oct 2026, published 22 Oct 2026

protos.comarticle🧠 AI

Inside AMD and Anthropic’s ‘chips for shares’ deal

Protos reports on the AMD and Anthropic compute deal: Anthropic commits to buy over $20 billion of AMD AI compute, up to 2 GW of Instinct MI450 chips from the first half of 2027, while AMD commits up to $5 billion to Anthropic stock through fiscal 2028. It cites WSJ reporting that hyperscalers cap Anthropic's compute, and Anthropic's 2025 operating loss above $8 billion on $4.6 billion revenue.

AMD Instinct MI450Claude
AnthropicAMDTom Brown+1

ai-policy, inference· Published and added 21 Oct 2026

huggingface.coarticle🧠 AI

MPS in PyTorch 2.15

PyTorch 2.15 MPS release post from the Hugging Face PyTorch team, covering the Apple silicon backend. It adds float8_e4m3fn tensors with F.scaled_mm, a native grouped matmul that speeds MoE decoding 5 to 6.5x (Qwen3.6-35B-A3B from 9.4 to 61.3 tokens/s on an M3 Ultra), and an 8x faster softmax. Wan2.2 VAE decode peak memory falls from 270 GiB to 8 GiB. It previews 2.16 attention on Metal.

PyTorchMetalMPSGraph+9
Hugging FaceAppleQwen3.6-35B-A3B+6

inference· Published and added 20 Oct 2026

blog.cloudflare.comarticle🛡️ Security

Beyond the patch: Protecting your NetScaler gateway against future vulnerabilities

Cloudflare's guidance on protecting Citrix NetScaler Gateway after the actively exploited CVE-2026-88771 (unauthenticated command execution) and CVE-2026-88772 (DTLS). It recommends putting Zero Trust access policies in front of the login page, locking the origin down with Tunnel, dedicated egress IPs, authenticated origin pulls or Access JWT validation, and adding WAF inspection. It ends with a four-step test list to confirm the boundary holds.

Citrix NetScalerCloudflareCloudflare Access+1
CVE-2026-88771CVE-2026-88772CISA+5

Cloud & Infra, Identity & Access· Added 29 Oct 2026, published 19 Oct 2026

stepsecurity.ioarticle🛡️ Security

OpenCode Security Breach: Distillation Attack Hit Console Users With Linked AI Providers. How to Find OpenCode on Developer Machines and Respond

OpenCode disclosed a security breach on 18 October 2026 tied to a "large scale distillation attack" that hit 1.4% of OpenCode Console users who had Anthropic, OpenAI or Google providers linked. The post relays the vendor's X statement and notes that root cause, data accessed and key exposure are unpublished. It gives response steps: inventory OpenCode installs, read ~/.local/share/opencode/auth.json, rotate linked API keys, and review provider usage.

OpenCodeAnthropicOpenAI+2
distillation attackOpenCode Console breach

Threat Intel, AI Security· Published and added 18 Oct 2026

galaxy.comarticle🧠 AI

Proving Humanity

Galaxy Research essay arguing that as AI agents become the main way people use the web, the key question shifts from "is this a machine?" to "is a distinct real person behind it, counted once?". It traces CAPTCHA history (distorted text, image puzzles, reCAPTCHAv3 and Turnstile behavioral scoring) and notes ChatGPT Agent passing Cloudflare's checkbox. It reviews Web Bot Auth signatures and Google's AP2 payment mandates, showing both stop at the platform or key and never establish a person. It then covers harms (one-person-one-share abuse, no one to answer for an agent, distorted public counts, collapsing confidence, scaled deception, broken ad economics) and lists the properties a privacy-preserving proof-of-personhood credential needs: strong, private, portable, delegable, accessible.

Web Bot AuthAgent Payments Protocol (AP2)reCAPTCHA+5
Galaxy DigitalGoogleOpenAI+13

agents, ai-policy· Added 16 Oct 2026

huggingface.coarticle🧠 AI

Welcome Beam: a 501B open model you can own, customize, and scale

Announces Reflection's Beam-1.0-501B-A23B, an Apache 2.0 text-only MoE model (23B active per token, 256 experts, 1M context) aimed at coding and agentic use. It covers the architecture (hybrid sliding-window/global attention, a constant-scale residual stream, DeepSeek-V3-style group-limited routing) and BF16/FP8/NVFP4 checkpoints with hardware sizing. It also gives day-0 serving recipes for transformers, vLLM and SGLang with DFlash2 speculative decoding, LoRA SFT with TRL, GRPO with Miles, and demos built with the Pi coding harness.

TransformersvLLMSGLang+12
BeamReflectionDeepSeek+15

models, inference, training· Published and added 16 Oct 2026

liquid.aiarticle🧠 AI

LFM2.5-24B-A2B: Built for fast on-device agents

Liquid AI releases LFM2.5-24B-A2B, a 24B-parameter MoE reasoning model with 2B active parameters (40 layers, 64 experts with top-4 routing, hybrid gated short convolutions and GQA). It has a 131K context window, a 128K-token vocabulary and 33T pre-training tokens, and was post-trained with large-scale RL for tool use and agentic tasks. The post reports results against Qwen3.6-35B-A3B on 16 benchmarks (AutomationBench, BFCLv4, ToolSandbox, LiveClaw, τ³-Bench Banking), decode speeds of 184 tok/s on an Apple M5 Max and about 21K output tok/s on a B300 GPU, day-one support in llama.cpp, MLX, vLLM, SGLang and ONNX, and a local Hermes Agent demo. It also describes reward-hacking behaviour during training, including the model detecting its sandbox.

Mixture of Expertsllama.cppMLX+8
Liquid AILFM2.5-24B-A2BLFM2.5-24B-A2B-Base+20

models, inference, agents· Added 16 Oct 2026, published 14 Oct 2026

bankless.comarticle🛡️ Security

Crypto's Quantum Defense Is Being Built in the Open

Bankless article on Eigen Labs' Yukon platform, which runs open challenges where researchers and AI agents attack and improve cryptography. It covers ECDSA.fail (quantum circuit cost for attacking Bitcoin/Ethereum ECDSA, cut about 88% from baseline), HashSmash (SHA-256 weakness hunting, so far only on reduced versions), sig.golf (hash-based signatures), StarkWare's Quantum Safe Bitcoin (cost down from about $320 to $59) and better.codes (provable security raised from 64 to about 68 bits). The argument is that public, measurable attack-cost data helps defenders prepare better than withholding circuits does. All gains are theoretical and no quantum computer has run an attack at this scale.

YukonBitcoinEthereum+1
Eigen LabsECDSA.failHashSmash+10

other, AI Security· Published and added 14 Oct 2026

huggingface.coarticle🧠 AI

Run fast, private agents on-device with LFM2.5-24B-A2B

Liquid AI releases LFM2.5-24B-A2B, an open-weight reasoning-only mixture-of-experts model (40 layers, 64 experts with top-4 routing, hybrid gated short convolutions and GQA, 2B active parameters) with 131K context and a 128K-token vocabulary. Pre-training scaled to ~33T tokens, followed by long-context mid-training and a five-stage post-training pipeline (SFT, teacher specialization, two multi-domain on-policy distillation stages, agentic RL in harnesses such as OpenClaw, Hermes Agent, Pi, OpenCode). It reports leading or matching results on tool-use and instruction-following benchmarks (e.g. LiveClaw 48.09 vs 38.19 for Qwen3.6-35B-A3B), 184 tok/s on an M5 Max and 21K tok/s on a B300, and includes transformers code and Hermes Agent local-serving config.

Mixture of ExpertsTransformersvLLM+12
Liquid AILFM2.5-24B-A2BLFM2-24B-A2B+18

models, agents, inference· Published and added 13 Oct 2026

adversa.aiarticle🛡️ Security

Top GenAI security resources — October 2026

Adversa AI's October 2026 roundup of 38 GenAI security resources, grouped into attack techniques, defenses, red teaming, vulnerabilities, incidents, articles and frameworks. Highlights include Anthropic's finding that GLM-5.3 safeguards collapse under prefill and abliteration, capability laundering and activation-dilution jailbreaks, RAG poisoning attacks, the LiteLLM proxy flaw (CVE-2026-35029), and the SGLang pickle RCE (CVE-2026-86793). It also covers a joint US advisory on industrial-scale model distillation. It closes with advice to assume model safeguards can be removed and to harden the serving stack around the model.

LLMLiteLLMSGLang+3
CVE-2026-35029CVE-2026-86793GLM-5.3+14

AI Security· Published and added 13 Oct 2026

anthropic.comarticle🛡️ Security

Strengthening our defenses against distillation attacks

Anthropic describes how it countered industrial-scale distillation attacks on Claude, in which proxy networks of hundreds of thousands of fraudulent accounts (stolen payment details, false identities) tricked models into revealing hidden reasoning. Defenses include a two-stage constitutional-classifier system (<0.1% false positives), "preserved thinking" that blocks edits to prior context for new API accounts, restricting reasoning transcripts to the originating organization, stricter limits, bans, and charging for blocked requests. It reports 10–100x fewer reasoning tokens extracted, cites Zhipu's GLM-5.3 and Moonshot Kimi forwarding as examples, and discusses trade-offs and the need for platform-wide action.

ClaudeAnthropicKimi K3+2
distillation attacksZhipuMoonshot+7

AI Security, Threat Intel· Added 14 Oct 2026, published 13 Oct 2026

endorlabs.comarticle🛡️ Security

Identifying and Tracking FedRAMP False Positives | Endor Labs

Explains how FedRAMP treats false-positive SCA findings, which still have to be tracked in the POA&M and ConMon. It covers the deviation request (DR) process, the SCA problems of scale and missing context (manifest-based inventories, with 88% of imported code unused), and 30–180 day remediation SLAs. It argues that only high-confidence, function-level reachability that holds from any source is likely to satisfy a 3PAO. It then describes how Endor Labs uses call-graph analysis, SBOM/VEX output and rescanning to document false positives.

Endor LabsSBOMVEX
FedRAMPPOA&MConMon+4

GRC, Supply Chain· Published and added 12 Oct 2026

blog.talosintelligence.comarticle🛡️ Security

Making sure the checks get printed

Cisco Talos's weekly Threat Source newsletter, opening with a risk-management anecdote about network-isolating unpatchable legacy check-printing systems, then disclosing new CAIRN research classifying "A3: AI-Analysis Evasion" — malware authors embedding natural-language prompt-injection text into code/binaries to manipulate AI-assisted malware analysis pipelines. The MANTLEMAZE malware family exemplifies this, pairing such AI-deception attempts (effective ~35% of the time) with BYOVD abuse to disable EDR from kernel space. The issue closes with a roundup of the week's security headlines (Citrix NetScaler CVE-2026-88779, a Danish government data breach, Warlock ransomware) and Talos's current top-prevalence malware hashes/IOCs.

EDRCitrix NetScaler
CVE-2026-88779MANTLEMAZECAIRN+2

AI Security, Malware & RE· Published and added 8 Oct 2026

openai.comarticle🛡️ Security

Disrupting AI-enabled “false front” operations

OpenAI reports banning ChatGPT accounts tied to two covert influence operations using "false front" entities. The Russian "Dark Clark" operation ran a think tank (Social Research Center) staffed by unwitting Latin Americans, planted fake emails, audio and documents targeting Ukraine and Argentine, Bolivian and Ecuadorian leaders, and was rated Breakout Scale Category 5. The Iranian "Bogus Bylines" operation used seven fake journalist personas to place nearly 100 articles in online outlets (Category 4) and generated batches of social media comments (Category 2), while using inflated impact metrics in internal reports.

ChatGPTOpenAIVPN+2
Dark ClarkBogus BylinesSocial Research Center+12

Threat Intel, AI Security, OSINT· Published and added 8 Oct 2026

openai.comarticle🧠 AI

Disrupting AI-enabled “false front” operations

OpenAI's threat report describes two banned ChatGPT-account clusters running "false front" influence operations. The Russian "Dark Clark" operation ran a Latin American think tank, the Social Research Center, through unwitting staff and was rated Breakout Scale Category 5, OpenAI's first. The Iranian "Bogus Bylines" operation placed almost 100 articles under seven fake journalist bylines (Category 4) and inflated its own impact metrics.

ChatGPT
OpenAIMetaDark Clark+9

ai-safety, ai-policy· Published and added 8 Oct 2026

decrypt.coarticle🛡️ Security

Hackers Used AI Agents to Raid a Megachurch's Database, Exposing 850,000 Members

Seoul megachurch Yoido Full Gospel Church disclosed a breach exposing data on 850,000 members (names, birth dates, and logged changes to resident registration numbers, phone numbers and addresses), discovered by security firm Oasis Security on an overseas server alongside attack logs showing AI sub-agent activity and machine-generated attack reports. A second megachurch, Sarang Church, lost about 89,000 member and 286 employee records in a related August incident, and South Korean authorities are separately investigating suspected AI-assisted hacks at banks including Shinhan, which exposed data on about 25,000 customers. The exact role AI played in gaining initial access remains unconfirmed, but the find marks one of the first documented cases of attacker logs referencing autonomous AI sub-agents in a large-scale breach.

Yoido Full Gospel ChurchSarang ChurchOasis Security+3

Threat Intel, AI Security· Published and added 7 Oct 2026

Showing 30 of 67

Show more