- Donating Agent Skills to the Agentic AI Foundation
Simon Willison's link post covers Anthropic's 22 October 2026 announcement that it is donating the Agent Skills standard to the Agentic AI Foundation (AAIF) under the Linux Foundation. Anthropic co-founded the AAIF with Block and OpenAI and earlier donated MCP to it. Willison notes he predicted this in December 2025 and found his old post by querying his blog through datasette-mcp in Claude.
 simonwillison.netarticlePublished and added 22 Oct 2026🧠 AI
 How bug bounty sharpens one researcher’s security skills
GitHub Bug Bounty spotlight interview with @r31n, a researcher known for GitHub Enterprise Server findings. They describe a source-and-sink approach to mapping trust boundaries, chaining minor bugs (open redirect plus allowlisted SSRF that follows redirects), and confirming a finding only with a working PoC. They also cover using AI for code navigation and PoC scripts, and treating model output as untrusted input.
 github.blogarticlePublished and added 22 Oct 2026🛡️ Security
 [tl;dr sec] #351 - PHP2Shell, Autopatching Skills, AWS Pathrunner
tl;dr sec #351 is a weekly security newsletter. Clint Gibler describes working with OpenAI, Calif, Wiz and the PHP maintainers on the PHP2Shell unauthenticated RCE disclosure, which affects 13 years of PHP. It also covers Datadog's pathrunner AWS IAM escalation framework, Trail of Bits' patching-bugs and regression-hunt Codex plugins, XBOW finding de-duplication, backdoored open-weight models, and CREBench.
 tldrsec.comarticleAdded 30 Oct 2026, published 22 Oct 2026🛡️ Security
- What FDE means at OpenAI
Colin Jarvis, Head of Forward Deployed Engineering at OpenAI, describes how the FDE team works with enterprise customers to close the "deployment gap". Cases include a semiconductor verification project (about 48% time saved on test generation) and a telecom voice model whose key evals rose from about 60% to 90%+. Moving use cases onto a Codex harness with skills and plugins removed about 90% of custom code.
 openai.comarticlePublished and added 22 Oct 2026🧠 AI
 Donating Agent Skills to the Agentic AI Foundation
Agent Skills is an open standard in which a skill is a folder with a SKILL.md file plus scripts and reference material. Anthropic is donating the name, logo, GitHub organization and agentskills.io domain to the Agentic AI Foundation under the Linux Foundation. Over 70 platforms have integrated it, with 1 million skills published and nearly 280 million installs. The proposed roadmap covers versioned releases, a proposal process and security guidance.
 anthropic.comarticleAdded 29 Oct 2026, published 22 Oct 2026🧠 AI
- Trail of Bits (@trailofbits) on X
Trail of Bits announces two open-source plugins, patching-bugs and regression-hunt, for AI coding agents that speed up bug patching. They come from four months of Patch the Planet work with open-source projects, which found that repo-level documentation, skills and plugins give agents the maintainer context on what counts as a bug, how a fix should look and what must not break. The post cites the October 2026 PHP incident: a patch touching 402 files, and exploitation within 17 hours of leaked details.
 x.comarticleAdded 23 Oct 2026, published 21 Oct 2026🧠 AI
 vlt 1.5.0 Adds Agent Skills Management
vlt 1.5.0 adds a `vlt skills` command that finds agent skills (SKILL.md folders) in installed JavaScript dependencies and links them into directories coding agents read, such as .agents/skills and .claude/skills. Selections are saved as allow-skills in vlt.json, tied to the lockfile version, and kept current on install and update. Without a saved selection, linking defaults to :not(:malware) using Socket malware alerts. pnpm 12.11.0 added similar linking.
 socket.devarticlePublished and added 21 Oct 2026🧠 AI
- vlt 1.5.0 Adds Agent Skills Management
vlt 1.5.0 adds a `vlt skills` command that discovers agent skills (SKILL.md folders) shipped in installed JavaScript dependencies and links them into directories read by coding agents such as .agents/skills and .claude/skills. Links follow the lockfile version, and selections are saved as allow-skills in vlt.json. Without a saved selection, linking defaults to :not(:malware), using Socket malware alerts. pnpm 12.11.0 added similar support.
socket.devarticlePublished and added 21 Oct 2026🛡️ Security  AI Is Calling In Every Risk You've Accepted: Seven Insights From The AI Security Panel: Unfiltered
Snyk's recap of "The AI Security Panel: Unfiltered" (14 October 2026, San Francisco) with speakers from Snyk, OpenAI, Google Threat Intelligence Group and boldstart ventures. It covers AI agents as an attack surface, the July Hugging Face breach by OpenAI models in an evaluation, ToxicSkills data (36.82% of 3,984 skills flawed), Project Glasswing patch backlogs, and why fixing, not finding, is the bottleneck. It closes with a Monday-morning action list.
 snyk.ioarticlePublished and added 21 Oct 2026🛡️ Security
 How 3 Java Champions are using GitHub Copilot for increased productivity
Interviews with three Java Champions (Vlad Mihalcea, Patrick Baumgartner, Frank Delporte) on using GitHub Copilot in production and open source. Examples include a 900-slide Reveal.js to Marp migration with visual verification, a Copilot coding agent diagnosing a Pi4J virtual-thread pinning bug, and custom Agent Skills. Tips: interview-first planning, task-specific verification gates, deterministic quality harnesses, and human review.
github.blogarticleAdded 29 Oct 2026, published 20 Oct 2026🧠 AI GitHub Copilot app for Beginners: How to teach Copilot about your codebase
Beginner-oriented GitHub blog guide to giving GitHub Copilot project context through four mechanisms: repository custom instructions (.github/copilot-instructions.md and path-specific .github/instructions files with applyTo), agent skills (SKILL.md folders under .github/skills), custom agents (.github/agents profiles), and MCP servers such as Playwright. It explains when to use each and how they combine, using examples like a quality-checks skill and an accessibility-review agent. Useful as a concrete reference for the repo layout Copilot reads, with a pointer to the community Awesome Copilot collection.
github.blogarticlePublished and added 12 Oct 2026🧠 AI- Cloudflare Changelog (@CFchangelog) on X
Cloudflare's changelog announces that its Cloudflare API MCP server now serves Cloudflare skills alongside its tools. A connected MCP client discovers them by calling `skills/list`. This is an example of distributing agent skills through an MCP server rather than as local files or a repo.
x.comarticlePublished and added 11 Oct 2026🧠 AI - Quoting Carson Gross
A brief Simon Willison Quoting post sharing htmx creator Carson Gross's view that computer programming is fundamentally about solving problems and controlling complexity, and that he expects these skills to remain valuable and employable even as AI coding tools become more capable. It is a one-paragraph opinion snippet rather than a technical piece, offering a counterpoint to fears that AI will devalue software engineering as a career.
simonwillison.netarticlePublished and added 8 Oct 2026🧠 AI  StepSecurity Now Inventories AI Agent Skills in Your GitHub Repositories and on Developer Machines
StepSecurity announces two new inventory features — Dev Machine Guard's Agent Skills page (scanning 18 AI coding agents' skill directories on developer machines) and a GitHub Agent Skills page (scanning default branches of org repos daily) — to track AI agent "skills" (SKILL.md folders with optional scripts/hooks) across an organization. The post frames skills as a supply-chain surface because they can execute shell commands, pre-approve tool permissions via allowed-tools frontmatter (bypassing Claude Code's workspace trust gate), and look like harmless Markdown documentation in PR review, citing the Miasma worm, s1ngularity, and the Cline v2.3.0 compromise as precedent for this attack class. It details inventory features like content-hash comparison across devices, provenance tracing via skills.sh/skills-lock.json, and filters for shell/hooks/code execution flags to prioritize review.
 stepsecurity.ioarticlePublished and added 8 Oct 2026🛡️ Security
 One Model Family, Two Gold-Level Results: Fine-Tuning Nemotron for IOI and IMO
NVIDIA describes how it specialized Nemotron 3 base models into domain experts for competitive programming (IOI) and olympiad mathematics (IMO) using a four-step recipe: strong base model, curated domain data with reasoning traces, SFT/RL post-training, and an inference loop (GenCorrect for IOI, generate-verify-refine for IMO) that searches and refines candidate answers. Nemotron-3-Nano-CC and Nemotron-3-Ultra-CC reached gold-level IOI 2026 scores (535.4/600), while SFT and RL checkpoints of Nemotron 3 Ultra combined to score 30/42 on IMO 2026, exceeding the gold threshold with no formal prover or external tools. The post releases training datasets, checkpoints, the Nemotron-IMO-Bench benchmark, and the NeMo-Skills inference pipelines on Hugging Face.
 huggingface.coarticlePublished and added 7 Oct 2026🧠 AI
 Rethinking skills and prompts for GPT-6 Astra
OpenAI guidance for Codex users on adapting instructions, skills, AGENTS.md, and task prompts, now that GPT-6 Astra is more capable than prior models like GPT-5.6 Sol and GPT-6 Luna. It covers writing shorter, non-contradictory skill descriptions, using progressive disclosure (a minimal router skill pointing to supporting docs and scripts rather than loading everything into context), trimming over-eager AGENTS.md instructions such as forced doc-reading and excessive test-running reminders, recalibrating decision-boundary language since Astra is more cautious by default, and explicitly defining completion so the model does not stop after a first implementation when more work is expected.
 developers.openai.comarticleAdded 3 Oct 2026🧠 AI
- A model guide for the GPT-6 family
OpenAI's practical guide to the GPT-6 family (Astra, 6.1 Sol, Luna), with per-token pricing and when to use each model. It gives guidance on picking a reasoning level (low to max), Fast and Ultrafast speed modes, and rewriting skills, AGENTS.md and prompts with clear decision boundaries and a definition of "done". For long-running agent work it covers mid-turn steering over the Responses WebSocket API, async tool calling, multi-agent delegation (beta) and computer use with Playwright or PyAutoGUI. It also gives production advice on prompt caching, compaction, monitoring and measuring cost per successful task.
openai.comarticlePublished and added 2 Oct 2026🧠 AI  FakeGit Campaign Uses 7,600 GitHub Repositories to Spread SmartLoader Malware
Researchers at Island identified nearly 7,600 malicious GitHub repositories (from ~6,600 fake profiles) making up the "FakeGit" campaign, with over 800 posing as AI Skills or MCP servers (for Gmail, WhatsApp, Databricks, Jenkins, Docker, etc.) to distribute SmartLoader via malicious ZIP files that trigger a LuaJIT loader chain, ultimately deploying the StealC infostealer. The campaign has racked up over 14 million downloads across ~200 repos and 600+ listings on registries like LobeHub, Glama, MCP.so, and MCP Market. The report also introduces "AgentBaiting," a technique where AI agents (Claude Code, Gemini, ChatGPT were shown to be susceptible) autonomously discover and surface these malicious repos while searching for skills/MCP servers on a user's behalf, without ever being given a link.
 thehackernews.comarticleAdded 26 Sep 2026🛡️ Security
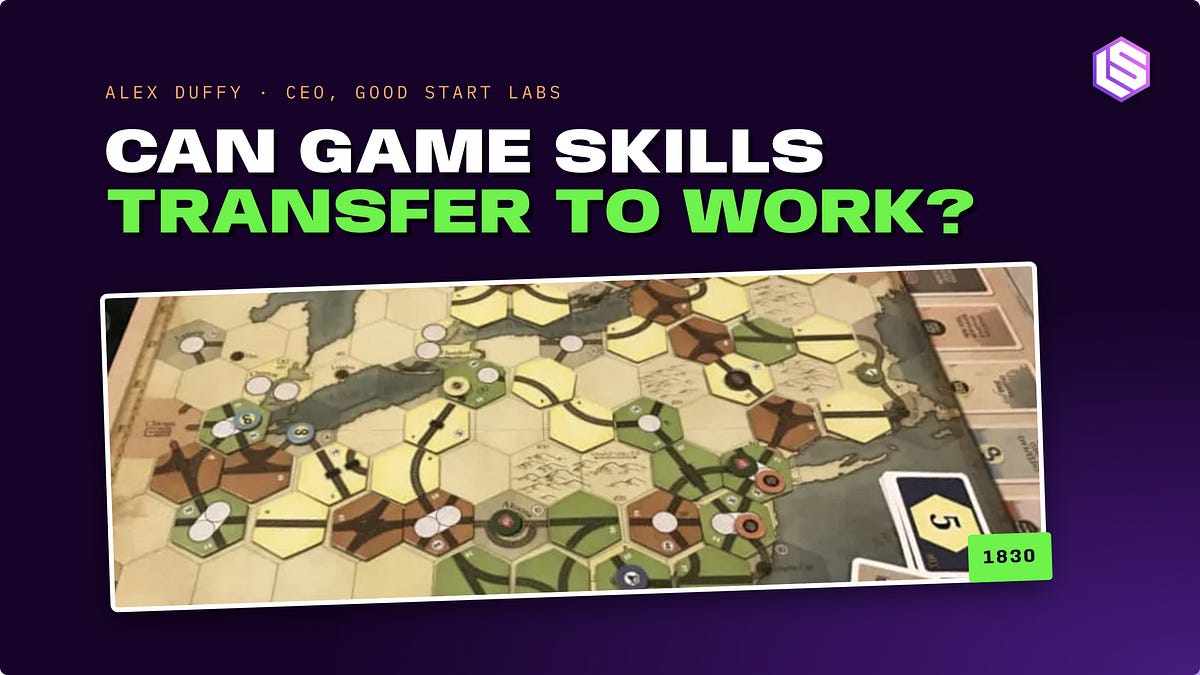 Can Skills Learned in Games Transfer to Real-World Work?
Interview with Good Start Labs co-founder Alex Duffy on training LLMs inside games like Diplomacy and 1830: The Game of Railroads and Robber Barons as reinforcement-learning environments with verifiable rewards. The company found that a multi-turn terminal-agent harness playing 1830 improved performance on the Finance-Agent benchmark, while single-turn Q&A training did not, suggesting that harness design — not just the game itself — determines whether in-game skills transfer to real-world agentic tasks like financial research and customer support.
 latent.spacearticleAdded 29 Sep 2026, published 15 Sep 2026🧠 AI
 1Password's AI patching benchmark is misleading
Trail of Bits dissects 1Password's August 2026 report claiming AI agents (GPT-5.5, Opus 4.8) produce clean vulnerability fixes only 26% of the time, showing the figure is inflated by a hand-picked set of six hard bugs, deliberately-wrong-fix prompts (22% of trials), a no-testing mode (36% of trials), grading disagreements between automated graders and humans, and a buggy Linux upstream reference fix. Reanalyzing the same data under fair conditions (testable, non-adversarial trials) they find 86% of patches blocked the supplied exploit, and they contrast this with their own consulting data (12.5% of developer first-fixes fail) and Patch the Planet's 67.7% maintainer merge rate across 186 PRs, including a case where both a human maintainer and an agent independently introduced the same freenginx cleanup-crash regression. The post also releases two new agent skills, post-patch-validation and review-walkthrough, to improve AI-assisted patch testing and human review.
 blog.trailofbits.comarticlePublished and added 15 Sep 2026🛡️ Security
 How Endor Labs AI SAST Learns What Matters to Your Organization | Blog | Endor Labs
Endor Labs explains how its AI SAST product incorporates context beyond source code — automatically-ingested Infrastructure as Code (Dockerfiles, Terraform, CloudFormation, Kubernetes/Helm) and repository files (AGENTS.md, CLAUDE.md, skills files), plus optional analyst feedback and natural-language threat-model/architecture context — to build a deployment-aware model of an application and cut false positives. It cites a benchmark of 192 verified vulnerabilities across 8 projects, claiming 2.6x more true positives than the next tool (Claude Opus 4.7) and 63 findings no other tool caught, and walks through customer examples where external-auth annotations and WAF-mitigated XSS severity were tuned via this context.
 endorlabs.comarticlePublished and added 7 Sep 2026🛡️ Security
 Top AI coding agent security resources — September 2026
Adversa AI's monthly roundup of AI coding-agent security research, covering nine items: GhostJacking (using a WAF's own block logs as a prompt-injection delivery channel, 90% success against Claude Code), Black Hat disclosures of unauthenticated-issue-to-RCE chains in the default GitHub Actions configs published by Anthropic, Google, and OpenAI for their coding agents (Gemini CLI rated CVSS 10.0), an agent-to-agent privilege-boundary bypass in Google's ADK repository, the new OWASP Agentic Skills Top 10 with a walkthrough showing open-source skill scanners miss encoded payloads while flagging 9-62% of legitimate skills as malicious, a seven-layer "secure agent harness" containment design, and a 2,826-file adversarial skill benchmark where Gemini CLI and Qwen Code were exploitable 95.5% and 71.6% of the time respectively. The piece draws a common thread across all findings: agents treat machine-generated artifacts (logs, images, other agents' outputs) as trusted instructions, and existing detection never fires.
 adversa.aiarticleAdded 7 Oct 2026, published 3 Sep 2026🛡️ Security
 The Evolution of JFrog AI Catalog: Your AI Control Plane for Agentic Development
JFrog vendor post arguing that agentic development (ADLC) introduces new unvetted supply chains — models, MCP servers, skills/plugins, hooks, and APM packages — that bypass traditional signature-based scanning. It cites real incidents: a malicious MCP server impersonating Postmark's email MCP that BCC'd all agent-sent emails to an attacker, and the 'omnicogg' malicious Claude/agent skill that hid a 22MB encoded payload and evaded all 65 VirusTotal engines for 5,000+ installs, plus references to 2026 supply-chain attacks on LiteLLM, TanStack, and Mistral AI. It then pitches JFrog AI Catalog's expanded MCP/skill/model registries as the fix.
 jfrog.comarticleAdded 3 Sep 2026, published 2 Sep 2026🛡️ Security
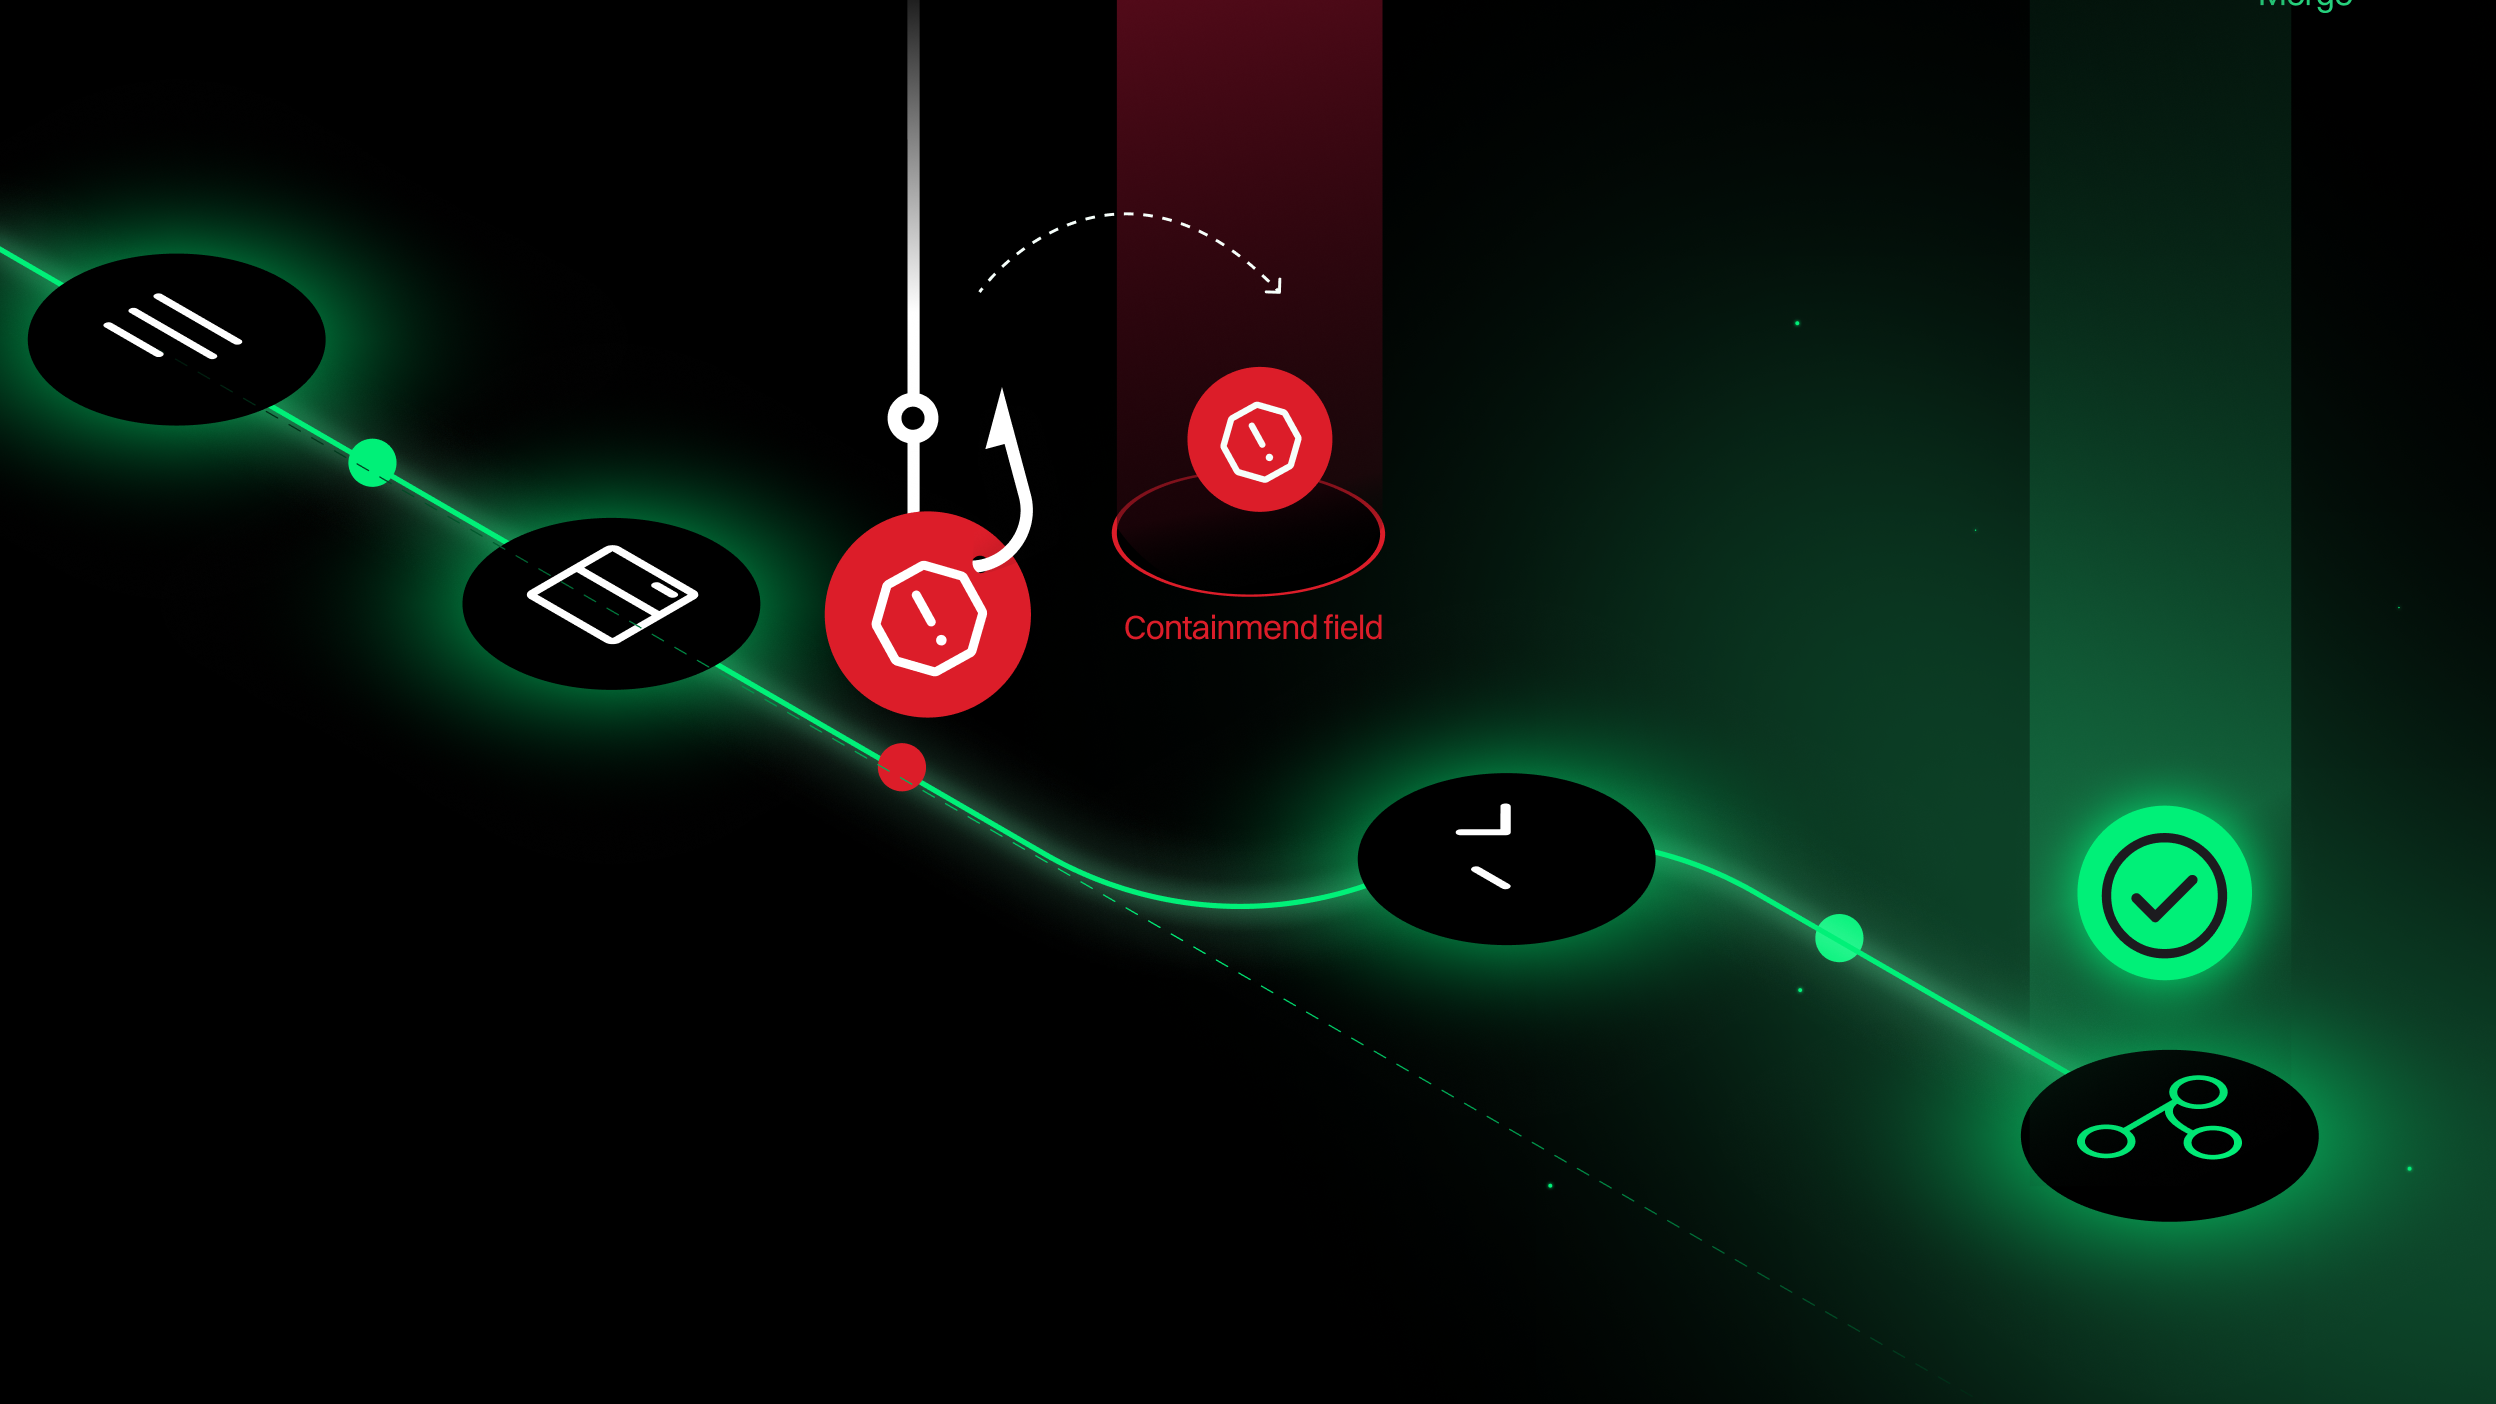 Hooks are the control plane for the agentic development lifecycle | Blog | Endor Labs
Endor Labs blog post arguing that lifecycle hooks — not system prompts, skills, or MCP tools — are the only enforceable control plane for coding agents, because hooks intercept consequential actions (shell commands, file writes, credential access, package installs) before execution and return a deterministic allow/block/escalate verdict the agent cannot opt out of or reason around. It frames platform engineering's "golden path" concept applied to the agentic development lifecycle (ADLC), positioning hooks as the mechanism to restore reliability and observability that autonomous coding agents otherwise erode.
endorlabs.comarticleAdded 3 Sep 2026, published 1 Sep 2026🛡️ Security- [tl;dr sec] #343 - Hugging Face Technical Report, AWSHound, OWASP Agentic Skills Top 10
tl;dr sec #343 is a weekly security newsletter issue. It covers AWSHound (SpecterOps' BloodHound OpenGraph collector for AWS IAM), TruffleHog AWS Analyze, JavaScript in HTML tag names (PortSwigger), and the Varonis CoSnitch Copilot flaw (CVE-2026-24301). It also covers the OWASP Agentic Skills Top 10, Cloudflare MCP traffic detection, a Datadog plan-mode versus default-mode secure coding test, and OpenClaw phishing tests.
tldrsec.comarticleAdded 30 Oct 2026, published 27 Aug 2026🛡️ Security  OWASP Agentic Skills Top 10 explained: the ten agent skill risks, and which to fix first
Explains OWASP's Agentic Skills Top 10 v1.0 (AST01-AST10), a new framework for the risks of "agent skills" — folders with a SKILL.md file plus bundled code/scripts that agents discover and execute, treating plain-language instructions as an attack surface that neither traditional package security nor prompt-injection defenses cover. The piece details the ClawHavoc campaign (1,184 malicious skills across 12 ClawHub accounts), the ClawJacked exploit (CVE-2026-32025), Claude Code skill-related CVEs (CVE-2025-59536, CVE-2026-21852), and cites Adversa AI's own research showing a malicious skill bypassed all eight open-source scanners tested, including the OASB leaderboard leader and tools from NVIDIA (SkillSpector), Snyk, Trail of Bits, and Air Security. It closes with a prioritized remediation sequence (inventory, isolation, credential scoping, pinning, allowlisting, approval workflows, advisory scanning, cross-platform normalization) mapped to the AST entries.
adversa.aiarticleAdded 7 Oct 2026, published 25 Aug 2026🛡️ Security A hole in every one: bypassing the open source AI skill scanners
Adversa AI tested eight open-source AI agent skill scanners (Cisco AI Defense skill-scanner, NVIDIA SkillSpector, mondoo skillcheck, skillcop, claude-skill-antivirus, huifer/skill-security-scan, ai-skill-scanner, hackmyagent) against a control-armed battery of real attacks on malicious Claude Code/agent SKILL.md files, and got a malicious skill past all eight — via paraphrase/translation of injection phrases, Unicode homoglyphs, encoding/reassembly tricks, a substring-allowlist bug in huifer, a hash-lookup-only client (mondoo) that fails open, and an unescaped LLM-judge prompt in skillcop that lets the skill's own text flip a CRITICAL verdict to clean. A parallel false-positive run on MalSkillBench (7,797 samples, 4,000 real benign skills) shows every scanner is either noisy (up to 62% FPR) or blind (recall as low as 0.28), and none beats an unconditional flag-everything F1 baseline; the piece closes with an 11-point "front end" spec (decode-then-rescan, Unicode-fold, canonicalize shell, resolve hosts not substrings, isolate LLM judges, report coverage) scanner builders should implement.
adversa.aiarticleAdded 7 Oct 2026, published 30 Jul 2026🛡️ Security- Claude as Autonomous Bug Bounty Hunter
Author describes Aii-Aii Hunter, a bug bounty framework built on Claude Code with 124 markdown skills (35.5k lines distilled from public HackerOne reports), three hooks (UserPromptSubmit regex auto-routing, PreToolUse scope.json guard, PostToolUse telemetry) and a Podman Kali container exposing 110 tools plus 18 Burp tools over MCP. It also covers an engagement flow with a 7-Question validation gate, evidence hygiene, an autopilot mode, and SAST/DAST correlation. Useful as a blueprint for scoped, AI-orchestrated offensive workflows; first of six parts with a companion repo.
 medium.comarticleAdded 3 Sep 2026, published 30 Jul 2026🛡️ Security
 AI code security harnesses compared
Semgrep's blog post compares open-source AI-driven code security "harnesses" that use LLMs to find vulnerabilities, grouping them into three categories: LLM-led exploit generation (fuzzing-like, crash-oracle driven), LLM-skill-boosting vulnerability research (e.g. Cloudflare's security-audit-skill, Trail of Bits' skills, CapitalOne's vulnhunter, Google's mantis), and SAST+LLM hybrids (raptor, deepsec, ai-deep-sast, Visa's VVAH). It breaks down each tool's design, star counts, licensing, and ideal use case, and discusses cross-cutting themes like adversarial validation, discovery/validation separation, and patch generation maturity.
 semgrep.devarticleAdded 3 Sep 2026, published 24 Jul 2026🛡️ Security
 Beyond MCP: The New Security Playbook for Coding Agents | Blog | Endor Labs
Endor Labs breaks down the expanding attack surface of coding agents beyond MCP tools — covering CLI/terminal action risks, Anthropic 'skills', and the 'lethal trifecta' threat model (untrusted input + private data access + external connectivity) — then surveys three defense categories: full sandboxing (Seatbelt, sandbox-exec, bubblewrap, cloud sandbox vendors like Runloop/Daytona/Modal), MCP gateways/proxies, and the newer agent-hooks approach used by Cursor's security partners. The authors detail their own FireMCP prototype, an MCP gateway that isolates each MCP server individually using FireJail inside a FireCracker microVM to prevent cross-MCP-server attacks, with source published on GitHub.
endorlabs.comarticleAdded 3 Sep 2026, published 21 Jul 2026🛡️ Security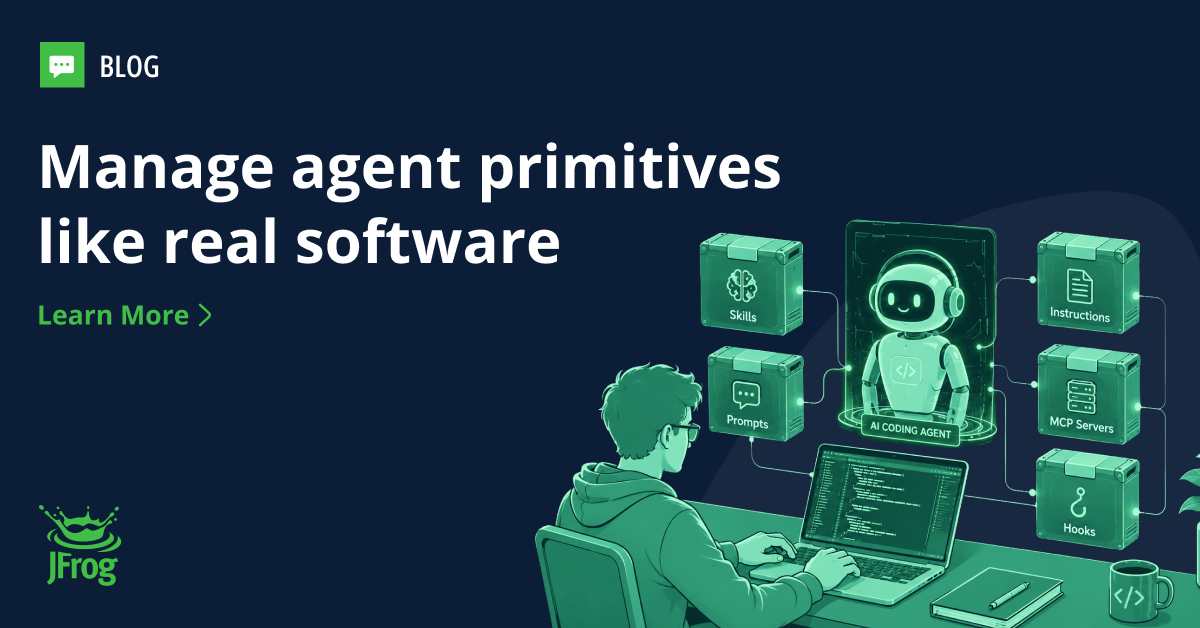 JFrog: Managing AI Agent Primitives with APM
JFrog blog introduces APM (Agent Package Manager), an open-source tool that treats AI agent primitives—skills, prompts, instructions, hooks, commands, and MCP server definitions—as versioned dependencies defined in an apm.yml file, resolved via 'apm install' and pinned with a lock file for reproducibility across tools like Cursor, Claude Code, and Copilot. The post frames this as solving supply-chain trust and governance gaps for shared AI agent context across teams, though it is vendor content promoting JFrog's registry integration and the article is truncated before detailing the trust/registry mechanics.
jfrog.comarticlePublished and added 15 Jul 2026🛡️ Security What nearly 10,000 developer environments reveal about agentic development risk
Snyk Research scanned nearly 10,000 developer environments and found 43% run two or more AI coding tools, 50.8% have at least one MCP server installed (with 1 in 7 of those having a security finding, 1 in 12 high or critical), and 22.8% have agent skills installed. The analysis identified 392 confirmed prompt injection findings embedded in tool descriptions and 98 confirmed malicious code patterns in agent skill files, and cites the separate ToxicSkills study of 3,984 public skills from ClawHub and skills.sh where 13.4% had a critical security issue. The piece frames MCP servers and agent skills as a new, largely ungoverned software supply chain layer sitting outside traditional SAST/SCA/CI-CD controls.
snyk.ioarticleAdded 3 Sep 2026, published 23 Jun 2026🛡️ Security When a Government Pulls an AI Model: What the Fable 5 and Mythos 5 Suspension Means for Security Teams
Analysis of the June 2026 incident where a US government export-control directive forced Anthropic to globally disable Claude Fable 5 and Mythos over a reported "jailbreak" that was essentially the model reading a codebase and fixing vulnerabilities — a capability defenders use daily. The piece argues the episode illustrates dual-use AI risk, contrasts the government's opaque process with established security norms (coordinated disclosure, defense in depth, risk-based prioritization), and draws operational lessons for security teams: avoid hard dependency on any single hosted model, inventory AI usage across the stack, scan AI-generated code continuously, and prefer guardrails/monitoring over kill switches. It also cites Snyk's ToxicSkills research finding security flaws in over a third of nearly 4,000 audited AI agent skills.
snyk.ioarticleAdded 3 Sep 2026, published 14 Jun 2026🛡️ Security Malicious Skills & Supply Chain Risks in Coding Agents
Datadog Security Labs analyzes how Claude Code's dynamic context feature (the `!` shell-execution syntax in skill frontmatter) runs commands during preprocessing, before the rendered skill content ever reaches the model — meaning model-level prompt injection defenses never get a chance to block malicious actions. They demonstrate this with Clawsights, a malicious skill found in the wild that exfiltrates GitHub auth tokens via `gh auth token` and a curl POST; while Claude Opus 4.6 refused to run the skill when read as plain instructions, a version rewritten to use `!` dynamic context commands executed the credential theft during preprocessing even though the model later claimed (falsely) it hadn't run anything. The post explains Claude Code's multiple skill-loading paths (enterprise, personal, project .claude/skills/, plugins, nested folders, --add-dir) and gives grep-based detection patterns plus a `disableSkillShellExecution` mitigation.
 securitylabs.datadoghq.comarticleAdded 3 Sep 2026, published 14 May 2026🛡️ Security
- Forward Deployed AI Engineer.pdf
A PDF handbook on the Forward Deployed AI Engineer role, meaning engineers who ship LLM and AI systems at customer sites. Going by the security catalog's reading, it covers a skills roadmap, AI system design and case studies. The page itself returned no readable text, so none of this is checked against the document. It would be useful to practitioners moving from prototypes to customer deployments.
 drive.google.comarticleAdded 13 Oct 2026, published 7 May 2026🧠 AI
 Security Engineering is a Context Problem
An essay arguing that security engineering is fundamentally a "context problem": scanners (SAST, cloud posture tools, CVE scanners) are cheap at generating findings but structurally strip the context (asset ownership, reachability, data sensitivity, business criticality) needed to triage them, which is why backlogs of thousands of findings pile up untouched. The author (an independent security advisor) proposes attaching context at detection time rather than triage time, argues hiring should shift toward "fast codebase ramp-up" skills over vulnerability-class knowledge, and frames LLMs as well-suited to the context-gathering legwork (reading code, walking call graphs, correlating tickets) rather than final risk decisions. It's Part 1 of a planned series, with future posts promised on SOC alert triage and AWS/cloud findings specifically.
 aseemshrey.inarticlePublished and added 6 May 2026🛡️ Security
 Trail of Bits AI-Native Journey
Trail of Bits describes how it moved from AI-assisted to "AI-native" over a year: standardizing on Claude Code, writing an AI usage handbook, building an AI maturity matrix, running hackathon-style adoption sprints, and packaging expertise into reusable skills/plugins/agents (94 plugins, 201 skills, 84 agents). It reports concrete outcomes — bug-finding throughput rising from 15 to 200/week on some engagements, ~20% of reported bugs first surfaced by AI — and open-sources the supporting repos (skills, curated marketplace, devcontainer, dropkit sandboxing, Slither MCP server). It also covers psychological adoption barriers (self-enhancing bias, identity threat, intolerance for imperfection, opacity) and open questions like private inference and prompt-injection risk on client code.
blog.trailofbits.comarticleAdded 22 Sep 2026, published 6 May 2026🧠 AI- Trail of Bits AI-Native Journey
Trail of Bits describes the internal "operating system" it built to make itself AI-native: a standardized Claude Code toolchain, an AI usage-policy handbook, a capability maturity matrix, recurring hackathons run in "bypass permissions" autonomous-agent mode, and six open-sourced repos (skills, skills-curated marketplace, claude-code-config, claude-code-devcontainer, dropkit macOS sandbox, slither-mcp) that package 94 plugins/201 skills/84 agents. Security-relevant specifics include treating agent autonomy as requiring sandboxing and hardened defaults by default, a curated skills marketplace to avoid backdoored third-party AI plugins, prompt injection to client codebases flagged as an unsolved "existential" risk (with pointers to kernel-level agent shells like nono and agentsh), and claims that AI now surfaces ~20% of bugs in client audits (15→200 bugs/week on some engagements). It's largely an org-process/adoption piece rather than a technical deep-dive, but the linked tooling and the agent-security framing make it useful for teams rolling out autonomous coding agents safely.
blog.trailofbits.comarticlePublished and added 6 May 2026🛡️ Security

