Pre-ERC: Agent Pre-Sign Risk Report
 is an Ethereum Magicians draft for a signed, typed report that a risk source returns about one unsigned agent transaction. The report is bound to the request by a digest and signed with EIP-712 by an ERC-8004 identity. Findings cover tokens, approvals, addresses, x402 payments and texts, each marked read or not read, with no score or verdict. The toll service runs it live on Robinhood Chain.
 ethereum-magicians.orgthreadPublished and added 31 Oct 2026
- Artificial Analysis (@ArtificialAnlys) on X
Hyperflow H3 is Video Rebirth's 8-step LoRA for MiniMax H3, released in September 2026 with open weights. Artificial Analysis ranks it #5 on AA-Video-I2V v2.1 and #3 on AA-Video-Editing v1.1, ahead of MiniMax H3 (768p). It costs $9.00 per minute for Image to Video and $18.00 for Video Editing at 1088p, under half of Dreamina Seedance 2.5 ($34.12 and $40.82). The thread gives per-capability and per-use-case breakdowns.
 x.comthreadAdded 31 Oct 2026, published 30 Oct 2026
- ERC-8478: x402 Payee Verification for ERC-8004 Agents
ERC-8478 is a draft Ethereum standard that binds the payTo address in an x402 payment requirement to the seller's ERC-8004 agent identity. A payer compares payTo with the registered agentWallet, or accepts an EIP-712 payee delegation signed by it, and checks that the origin is listed in the registration file. On Robinhood Chain, 5 of 5,575 x402-responding agents had payTo equal to agentWallet (28 October 2026).
ethereum-magicians.orgthreadPublished and added 30 Oct 2026 - Pre-ERC: x402 Payee Verification for ERC-8004 Agents
Pre-ERC draft on the Ethereum Magicians forum that ties the payTo address in an x402 payment requirement to the seller's ERC-8004 agent identity. The payTo must equal the registered agentWallet or an EIP-712 delegation signed by it, and the origin must be listed in the registration file. A checker returns one of eight fixed outcomes. On Robinhood Chain, 5 of 5,575 x402-enabled agents out of 20,046 used their agentWallet as payTo.
ethereum-magicians.orgthreadPublished and added 30 Oct 2026 - Anthropic Cracking Down on Video Game Rewrites
A tweet from chasmmmmmmmmmmm says Claude Code received a new rule around 27 October 2026, delivered from Anthropic's servers under the flag "tengu_heron_brook", with no setting to disable it. The quoted rule allows original games, genre games and games from the user's own designs and assets, but forbids recreating a specific existing game, even if renamed. The post asks whether this ends game rewrites and modding, and gives no verification beyond the quoted text.
 twitter.comthreadAdded 31 Oct 2026, published 30 Oct 2026
- Artificial Analysis (@ArtificialAnlys) on X
Artificial Analysis launched an HLE-Diamond leaderboard in v5 of its Intelligence Index, covering the refined 1,000-question Humanity's Last Exam from CAIS and Scale AI. Each question runs once without tools, graded by GPT-5.6 Luna (medium) as pass@1. Gemini 4 Carbon (high) leads at 69%, Claude Opus 5.5 (max) scores 68%, and the top open weights model, Kimi K3.1 Pro, reaches 37%.
x.comthreadPublished and added 30 Oct 2026 - aiproduck (@aiproduck) on X
Ruflo is an MIT-licensed wrapper for Claude Code and Codex that adds agent swarms, vector memory and an MCP server. The plugin install writes no files to the workspace, while npx init adds a .claude/ directory, CLAUDE.md and hooks. The post warns that mods run with the account's permissions, so users should read them first. It gives no benchmarks or architecture detail.
x.comthreadPublished and added 30 Oct 2026 - Prasenjit Sarkar (@stretchcloud) on X
A thread on Cloudflare's agent-readiness scan and the AgentReady.org open spec for "Agent Experience", developed with Vercel, Stripe, Auth0, Mintlify, Google, Netlify and Elementor. The scan grades whether agents can find a site (robots.txt, DNS), read clean Markdown, pass bot rules, and discover an MCP server or API catalog. One quoted example raised a score from 20 to 67 by shipping an API catalog with Link headers, an MCP server card, a skills index and an AI catalog file.
x.comthreadAdded 30 Oct 2026, published 29 Oct 2026 - 🚨 AI News | TestingCatalog (@testingcatalog) on X
Mistral Large 4 ("Le Chonk") is an open-weights model from Mistral, now on Hugging Face. Per Mistral's announcement quoted in the post, it ranks #1 among open models on Cognition's FrontierCode benchmark, is aimed at agentic coding and cybersecurity, and claims better reasoning efficiency and lower inference costs. The post does not give parameter counts, license or benchmark scores.
x.comthreadAdded 30 Oct 2026, published 29 Oct 2026  SGLang (@sgl_project) on X
SGLang announces Day-0 support for Mistral Large 4 ("Le Chonk"), saying it is the first engine to serve the model on NVIDIA Vera Rubin. The post describes the model as Mistral's largest to date: a natively multimodal 1T-parameter mixture-of-experts model covering instruct, reasoning, coding and agentic workflows. The fetched text is truncated, so benchmark claims and launch commands are not visible.
x.comthreadAdded 30 Oct 2026, published 29 Oct 2026 Muhammad Waris (@WarisCodes) on X
Nemotron 3.5 Transcribe is a free open-weight speech-to-text model from NVIDIA covering 40 languages, including mixed-language speech. The post says it ties for first among open models with a 2.8% error rate. It says the model needs a large GPU such as an H100 or RTX 5090, so it will not run on a laptop. The post gives no benchmark name or model card link.
x.comthreadAdded 30 Oct 2026, published 29 Oct 2026- 🚨 AI News | TestingCatalog (@testingcatalog) on X
Nemotron 3.5 Transcribe is an open-weight, promptable NVIDIA mixture-of-experts model with 30B total and about 4B active parameters. One checkpoint does transcription in 40 languages, speaker attribution, translation, contextual prompting and audio understanding. The post says it ranked first in VoiceArena's comparison of 14 diarization plus ASR systems. The fetched text is cut off and gives no license or download details.
x.comthreadAdded 30 Oct 2026, published 29 Oct 2026  Eddy (@ieddysun) on X
Expo's official skills package gives AI coding agents scoped instructions for building Expo apps. One command, npx skills@latest add expo/skills --skill '*', installs it for Cursor, Copilot and Windsurf, while Claude Code and Codex use their plugin marketplaces. Skills include expo-router, expo-animation, expo-upgrade and eas-update. The Expo MCP server adds live docs lookup, compatible dependency installs, EAS build monitoring and simulator screenshots.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026 TENSA Engineering (@TENSAEng) on X
A post by TENSAEng describing a workflow for staying within coding-tool usage limits. ChatGPT chat sits outside those limits, while Claude and Grok chats share a pool with Claude Code, Codex and Grok Build. Architecture, file layout, step order and acceptance checks are planned in ChatGPT and saved as repo docs. Claude Code or Codex then implements one small chunk per fresh session.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026- Laban (@lunkertw) on X
An X post summarising five AI items: Google DeepMind's Gemini 4 Carbon (88.2% SEC-bench Pro, 54.8% ExploitGym, 71.0% CWE-bench, 59 on Artificial Analysis Intelligence Index v5.0), Ed Zitron's critique of Anthropic's S-1, a Utah Claude Code pilot, and the repos beenuar/AiSOC and expo/skills. In the Utah pilot, 34 developers in 10 agencies took part over four weeks, 80% had a working setup within 30 minutes, and 71% saved over 20 hours. It gives short summaries and links, not primary analysis.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026 - Niko (@nikolayxyz) on X
Gemini 4 Carbon is Google's new frontier model, announced in a post by nikolayxyz that quotes Google's launch text. It ranks #1 on v5.0 of the Artificial Analysis Intelligence Index with 59 points, ahead of Opus 5.5 and GPT-6 Astra. Intro pricing is $2 input and $10 output per million tokens. Access starts for cyber defenders first, as Gemini 4 Argon's did. The captured text is cut off before the rollout details.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026  John Rood (@johnroodepic) on X
Nemotron 3.5 Transcribe is an open-weight, promptable 30B mixture-of-experts model from NVIDIA with about 4B active parameters, built for recorded audio. One checkpoint transcribes 40 languages, handles recordings up to an hour, labels up to eight speakers, translates, and answers questions about English audio. Weights and a demo are on Hugging Face. The post gives no benchmarks.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026- 🚨 AI News | TestingCatalog (@testingcatalog) on X
Gemini 4 Carbon is a new Google model, announced in a TestingCatalog post on X as taking first place on the Artificial Analysis V5 ranking. It is rolling out to cyber defenders first. Reported scores are 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching). The post calls it a large step up from Gemini 4 Argon, released two weeks earlier. It gives no technical detail beyond these claims.
x.comthreadAdded 30 Oct 2026, published 28 Oct 2026 - Hakimi Eiqbal (@hakimieiqbal) on X
A thread by Hakimi Eiqbal that maps reverse-engineering tools by target type: native binaries, Electron, .NET, iOS, firmware, WebAssembly and network protocols. Its AI sections cover REA (an open-source layer connecting coding agents to analysis tools) and MCP bridges for IDA Pro, Ghidra and radare2. It argues for an evidence-first workflow and gives a prompt that separates verified facts from hypotheses.
x.comthreadAdded 29 Oct 2026, published 28 Oct 2026  Kizuno18 (@Kizuno18) on X
Kizuno18's X post argues that the move from local stdio and Docker MCP servers to remote HTTP/SSE endpoints matures the Model Context Protocol in enterprise infrastructure. It lists three trade-offs: short-lived OAuth/JWT bearer tokens replace mounted admin credentials, deferred tool discovery avoids roughly 20k tokens of eager schema loading, and HCP Terraform enforces Sentinel/OPA policy, audit trails and approvals server-side. Opinion post with no benchmarks or code.
x.comthreadAdded 29 Oct 2026, published 27 Oct 2026 Photon Capital (@PhotonCap) on X
Photon Capital's thread covers the 27 October 2026 NVIDIA and Oracle announcement of general availability of Vera Rubin NVL72 and Vera CPUs on OCI. It lists specs (Spectrum-6 at 102.4Tbps, HGX Rubin NVL8 with Xeon 6, 150,000 initial Vera CPUs) and OpenAI's use of Vera CPUs for agentic sandboxes. The commentary argues CPU capacity can cut cost per task and shorten KV cache residency in GPU memory.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026- Manoj | The AI Dude (@Manojkumar2257) on X
heditor is an open-source (MIT) agent skill from pycodebr that has Claude Code, Codex, Cursor or OpenCode edit talking-head videos. It transcribes with faster-whisper, picks a 30-70s segment, cuts frame-accurately, builds HTML + GSAP motion graphics, mixes audio at -14 LUFS, and runs QA with vision-reviewed previews. It offers 42 named styles and a long-form mode with chapters, SRT/VTT and lower thirds. Install: npx skills add pycodebr/heditor -g.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026 - Rohan Paul (@rohanpaul_ai) on X
Hi3D v1.0 (formerly Sparc3D) is an open-sourced image-to-3D model from Hi3D, which runs a closed v3.0 refining at 2048 cubes per side. In a test with 13 professionals in 3D algorithms, 562 judgments against eight other image-to-3D models favoured it 83.5% of the time. The thread also covers the Hi3D Agent and an MCP server for other agents. Back and bottom views were checked, where TRELLIS.2 collapsed a winged figure.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026 - Prasenjit Sarkar (@stretchcloud) on X
Campfire is a self-hosted workspace by Prasenjit Sarkar that runs Claude Code, Codex, Goose, Aider and OpenHands side by side in one tab. Risky actions go through permission voting: a majority approves, any single deny blocks, and a 30 second timer ends the wait. Session replay shows which file or tool call triggered an action. The post cites Forever Security's report of a planted AGENTS.md. Codex followed it first time over 90% of the time and Claude Code about half the time. Try it with "bunx the-campfire".
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026 - Muzammil Shah (@Muzammil_OX) on X
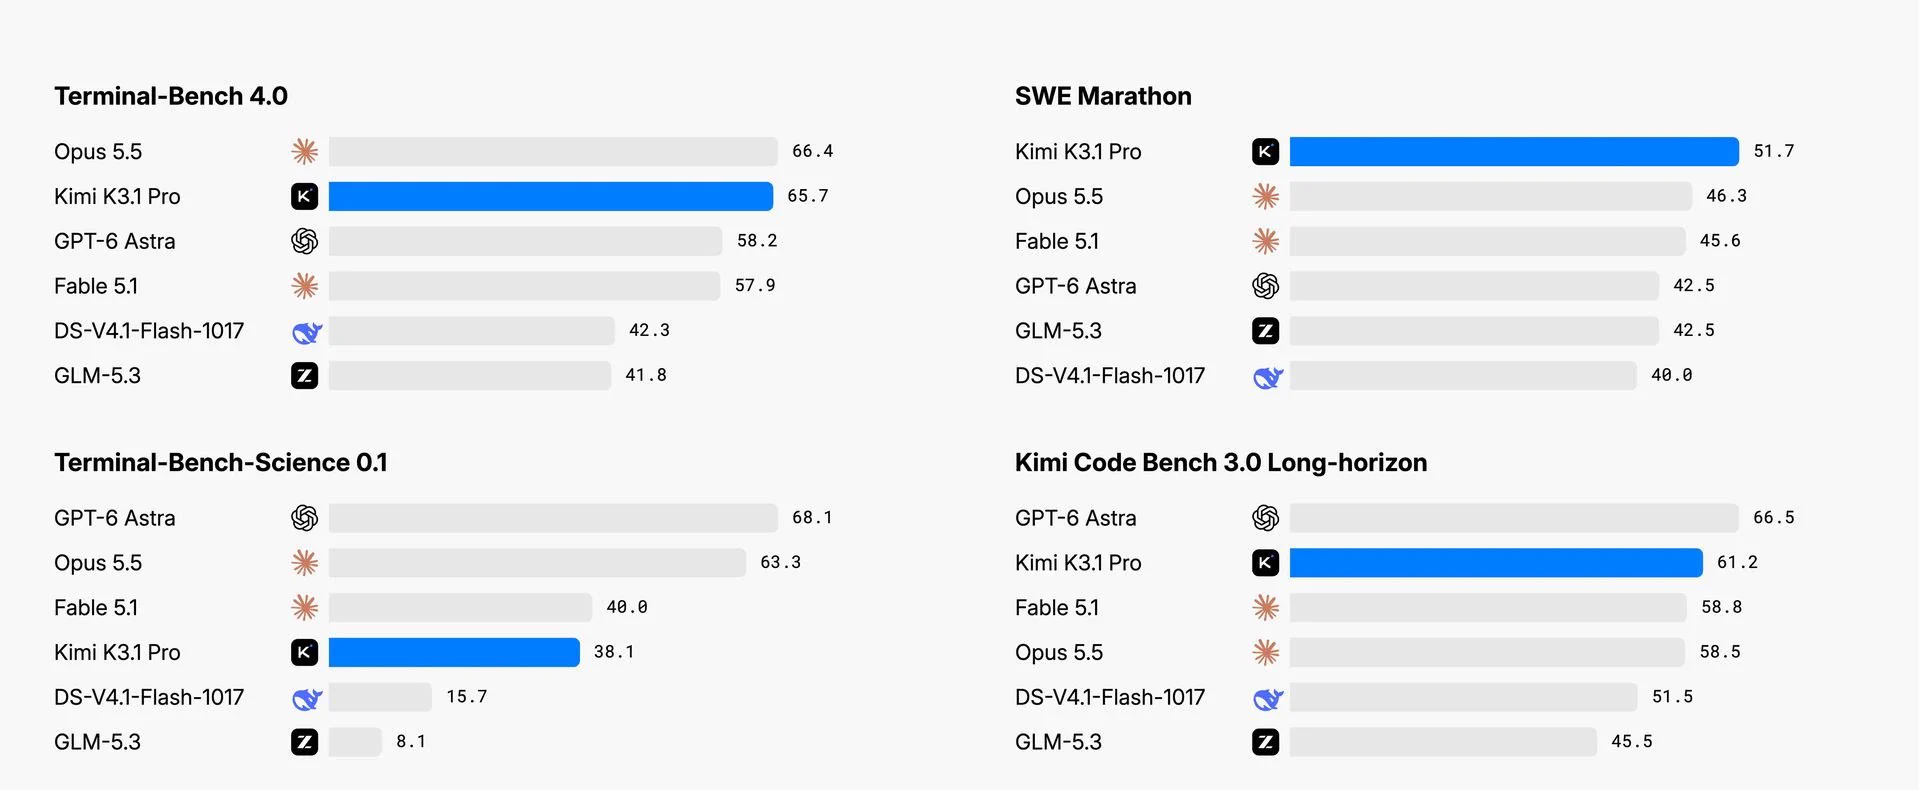
Kimi K3.1 Pro is a new model from Moonshot AI that scores 55 on the Artificial Analysis Intelligence Index, up 11 points from its predecessor, and ranks 4th overall. It has a 1M-token context window and API pricing of $2 per million input tokens and $10 per million output tokens. Weights are due by November 4. Moonshot removed cyber-related training data, which cut its internal vulnerability research score from 90.5% to 81%.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026  Abdullah (@abdullah0094) on X
An X thread by Abdullah on GPT-6.1 Terra versus Sol in Codex. Abdullah says Terra gives twice the Codex usage of Sol and asks whether the quality drop is obvious. A reply says it is too early for a verdict, cites OpenAI's claim that Terra matches GPT-6 Astra on Agents' Last Exam, and suggests defaulting to Terra and switching to Sol with /model when it stalls.
x.comthreadPublished and added 27 Oct 2026- AGTP (@AGTPinsights) on X
Thread summarizing Meta's Muse Spark 1.3 Evaluation Report, the safety write-up for the model released on September 2, 2026. It covers prompt-injection results on Exponential Security Labs' RepoInject v1 and BrowserInject v1 and Gray Swan's IPI Arena, chain-of-thought controllability evals, PostTrainBench under Loss of Control, and Handshake's human red teaming. It also notes The Midas Project's criticism that Muse Wonder still has no safety report, and the Muse Spark Open rollout (816B total, 42B active parameters).
x.comthreadAdded 27 Oct 2026, published 26 Oct 2026 - The SI Maximalist (@thesimaximalist) on X
The SI Maximalist posts on X that OpenAI says GPT-6.1 Terra matches GPT-6 Astra on Agents' Last Exam, OpenAI's test of workplace software tasks, at one tenth of the token price. The model is available in ChatGPT Work, Codex and the API. The post only relays OpenAI's claim and gives no benchmark scores, exact prices or method.
x.comthreadAdded 27 Oct 2026, published 26 Oct 2026  Akash Rajagopal (@akashsairaja) on X
Ollama overview thread by Akash Rajagopal on X. It lists six steps: install on macOS, Linux, Windows or Docker; run `ollama run gemma4`; use the REST API on localhost:11434 (/api/chat); call it from ollama-python and ollama-js; llama.cpp as the README's supported backend; and `ollama launch claude` to connect Claude Code. Codex, OpenCode, Copilot CLI and Droid also work. The thread cites 184k GitHub stars and an MIT licence.
x.comthreadAdded 27 Oct 2026, published 26 Oct 2026- SemiAnalysis (@SemiAnalysis_) on X
SemiAnalysis claims AMD chips running vLLM can earn up to $3 per chip-hour in profit serving the open-source Kimi K3 model, even after higher chip rental prices following Claude Code's rise. Kimi K3 has over 2.8 trillion parameters and fits AMD's 288GB per chip, while B200 cannot hold it in one server. B200 must then use tensor or pipeline parallelism over 400Gbit/s InfiniBand or Ethernet, which SemiAnalysis says is 18x slower than NVLink. The post gives no methodology.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026 - Vlad Tchouchkov (@tchouchkov) on X
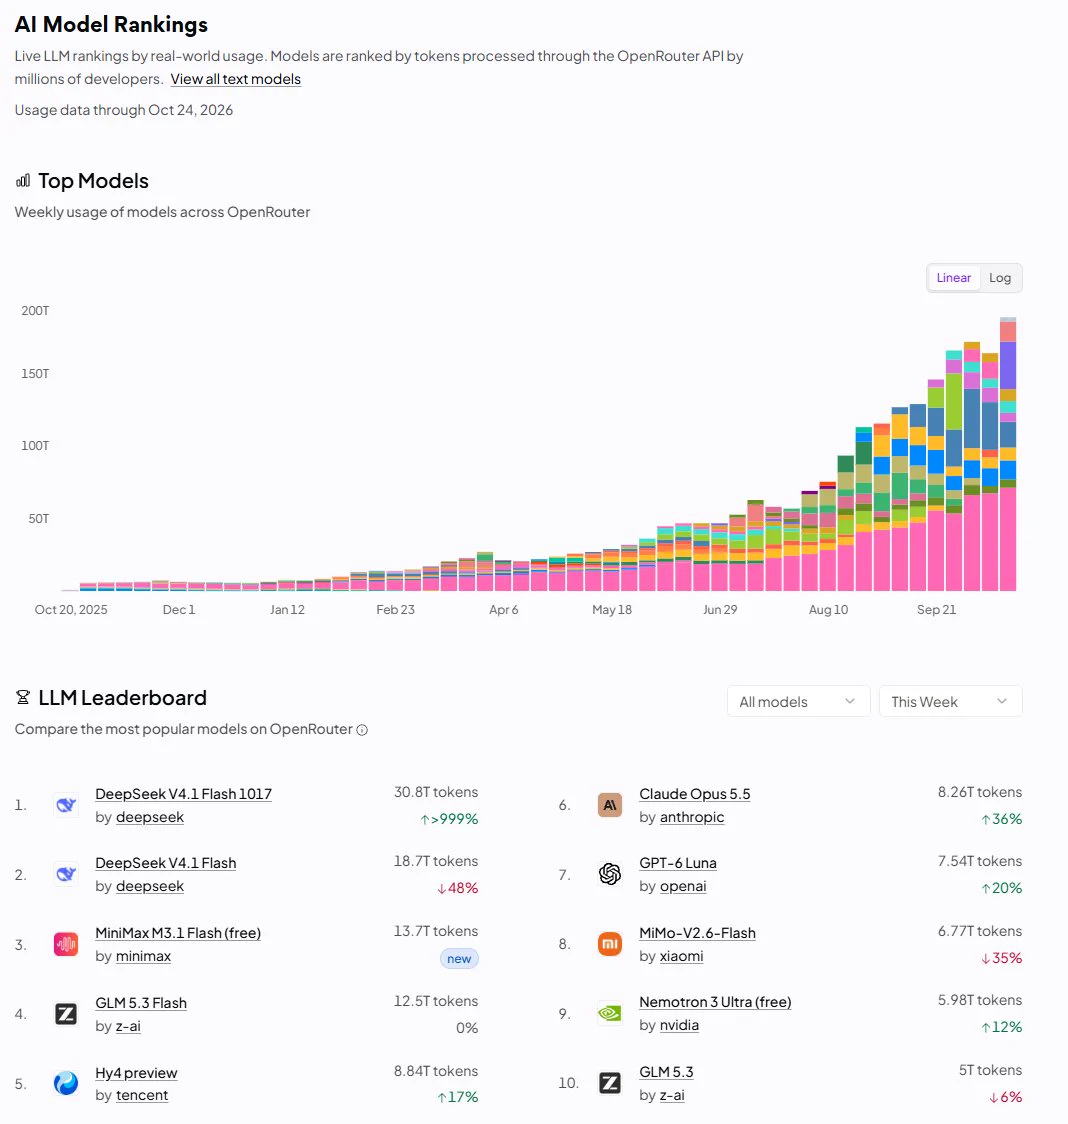
This X thread summarises OpenRouter usage charts. Weekly volume nears 200 trillion tokens, and open-weight models take 72.6% of tokens (136 trillion) against 27.4% for closed-weight models. Anthropic's daily average rose from about 0.6 to 2.25 trillion tokens alongside the Opus 5.5, Sonnet 5.5 and Haiku 5.5 releases. DeepSeek leads text requests at 26.5%, and agents plus coding account for 57.7% of spending. The author notes the data describes OpenRouter only.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026 - Syb (@DegenOfWallSt) on X
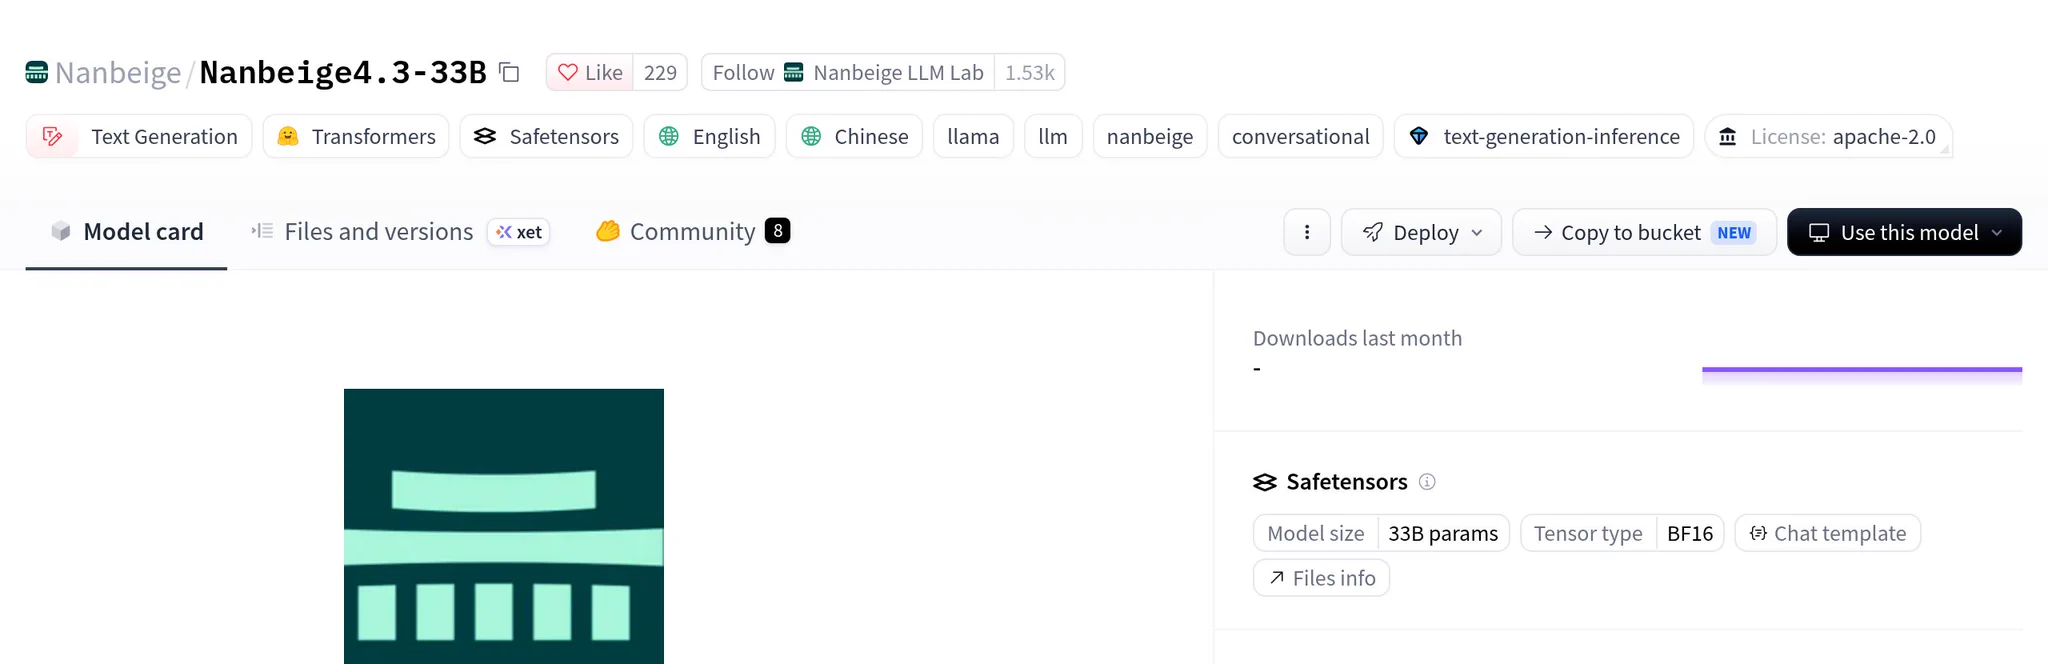
Nanbeige4.3-33B is a 33.1B dense, Llama-style open model under Apache-2.0, released with a base model on Hugging Face. In Nanbeige's own table it beats Qwen3.8-27B on Terminal-Bench 2.1 (80.9 vs 73.0), DeepSWE (65.5 vs 42.5) and Automation Bench, but trails on SWE-Bench Pro, GDPval and GPQA Diamond. BF16 weights are about 66 GB, split across 4 GPUs in the vLLM and SGLang examples. No independent evals exist yet.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026 - Draft ERC: Agent Safety Framework (ASF) — a registry of versioned safety specifications and of the scoped, attributable adoption relations that bind agents to them
Agent Safety Framework (ASF) is a draft ERC on Ethereum Magicians that defines two on-chain objects: a versioned, content-addressed Safety Specification and a Safety Binding, in which an adopter pins one spec version for a subject and scope. A registry check() returns Satisfied, NotSatisfied or Unknown. Bindings support derived delegation, and suspensions come in five graded restrictions. Reference consumers are ASFGuardedAccount and ASFTaskTenderAdapter, with 73 tests, 47 of them negative.
ethereum-magicians.orgthreadPublished and added 25 Oct 2026 - ERC-8468: Agent Safety Framework (ASF)
ERC-8468, the Agent Safety Framework (ASF), is a draft Ethereum standard with two on-chain objects: a versioned Safety Specification and a Safety Binding with suspend, resume and terminate rights. A check() call returns Satisfied, NotSatisfied or Unknown at the moment of effect. Revision 6 has reference contracts, 90 tests and a Sepolia run of 36 transactions in October 2026, and the thread asks reviewers five design questions.
ethereum-magicians.orgthreadAdded 27 Oct 2026, published 25 Oct 2026 - Draft ERC: Agent Safety Framework (ASF) — attributable adoption of versioned safety specifications
Agent Safety Framework (ASF) is a draft ERC (ethereum/ERCs pull request #2113) for an on-chain registry that records which participants adopted which versioned safety specification, for what subject and scope, and where it is enforced. It defines two objects (Safety Specification, Safety Binding) and a registry check returning Satisfied, NotSatisfied or Unknown. Two reference consumers and 73 tests (47 negative) are reported, and the post asks the community four design questions.
ethereum-magicians.orgthreadPublished and added 25 Oct 2026  su (@sutdmhy) on X
Kimi K3.1 Pro is a Moonshot AI model, with a high-speed variant, described in a tweet as a mixture-of-experts system of about 2.8 trillion parameters with a 1-million-token context window and multimodal support. The post claims gains in coding, long-horizon agents, 3D modeling (Blender/CAD) and financial research, and says benchmarks come close to Claude Opus 5.5. Full open weights are planned by November 4. The post gives no benchmark figures.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026- Big Bull (@BIGBULLapp) on X
5ire is a desktop AI assistant and MCP client that connects to OpenAI, Anthropic, Google, Mistral, Grok, DeepSeek and Ollama from one window. It has a local knowledge base and tool calls over Model Context Protocol. The tools feature needs Python, Node and uv installed because it runs a local MCP server; without them it works only as a chat client.
x.comthreadAdded 25 Oct 2026, published 24 Oct 2026  ReignSwords (@ReignSwords) on X
A reviewer tests GenOffice, an open-source Office suite (10.7k GitHub stars), through its CLI only. Markdown to .docx took 3.8s, JSON to .xlsx took 0.9s with a live SUM formula, and .docx to PDF failed twice until Xvfb supplied a display. It has byte-preserving edits, a skill file for Claude Code and Codex, and 29 MCP tools. Downsides: a 188MB download that filled a 512MB /tmp, Electron in the PDF path, and unproven trust in tracked changes and rollback.
x.comthreadAdded 25 Oct 2026, published 24 Oct 2026- Gökdeniz Gülmez (@ActuallyIsaak) on X
An X post showing how to have Codex train a small model on Apple silicon through the mlx-lm-lora MCP server and skill. It gives five setup steps (pip install with the mcp extra, npx skills add, locate mlx-lm-lora-mcp, codex mcp add). The prompt runs four pre-training trials on tiny-random/qwen3 with the mlx-community/recycling_the_web-1k dataset. Codex picks the optimizer and learning rate itself, and the result is a table with validation loss and the best adapter path.
x.comthreadAdded 25 Oct 2026, published 24 Oct 2026  Prasenjit Sarkar (@stretchcloud) on X
Post explaining Claude's new support for MCP Tasks and Elicitations. A server returns a durable task handle instead of blocking. The client polls tasks/get every 250 ms to 30 s, and states are working, input_required, completed, failed or cancelled. Elicitations pause a task at input_required for human approval. It also notes Cloudflare's stateless MCP servers and Code Mode, and Sentry and Linear adoption.
x.comthreadAdded 25 Oct 2026, published 24 Oct 2026 EveryDev.ai (@EveryDevAi) on X
ToolUniverse, from ScientistTools, is an open-source (Apache-2.0) toolkit that gives any LLM one interface to more than 1,000 scientific tools, models and databases such as PubMed, UniProt and ChEMBL. It ships a native MCP server, a Python SDK and a tu CLI, plus 68 pre-built agent skills. The post says it works with Claude Code, Cursor, Gemini CLI and Windsurf.
x.comthreadPublished and added 24 Oct 2026 Hajrë Hyseni | AI for Business (@hajra) on X
Kimi K3.1 Pro is a new model from Moonshot AI. According to a post by hajra, Artificial Analysis ranks it 4th in the world, 3 points behind Claude Opus 5.5. The API price is down by a third, and full open weights are promised by 4 November. The post gives no benchmark breakdown, licence or architecture details.
x.comthreadPublished and added 24 Oct 2026- Big Bull (@BIGBULLapp) on X
A post by BIGBULLapp on X about a TensorBlock GitHub index of Model Context Protocol servers, described as a TypeScript list so agents call tools someone has already wired up. It cites 1470 forks, 943 stars and 15 open issues. The author notes that curated lists go stale when a server changes its schema. The repository name is truncated in the post.
x.comthreadAdded 24 Oct 2026, published 23 Oct 2026 - Yash Patil (@yvshpvtil) on X
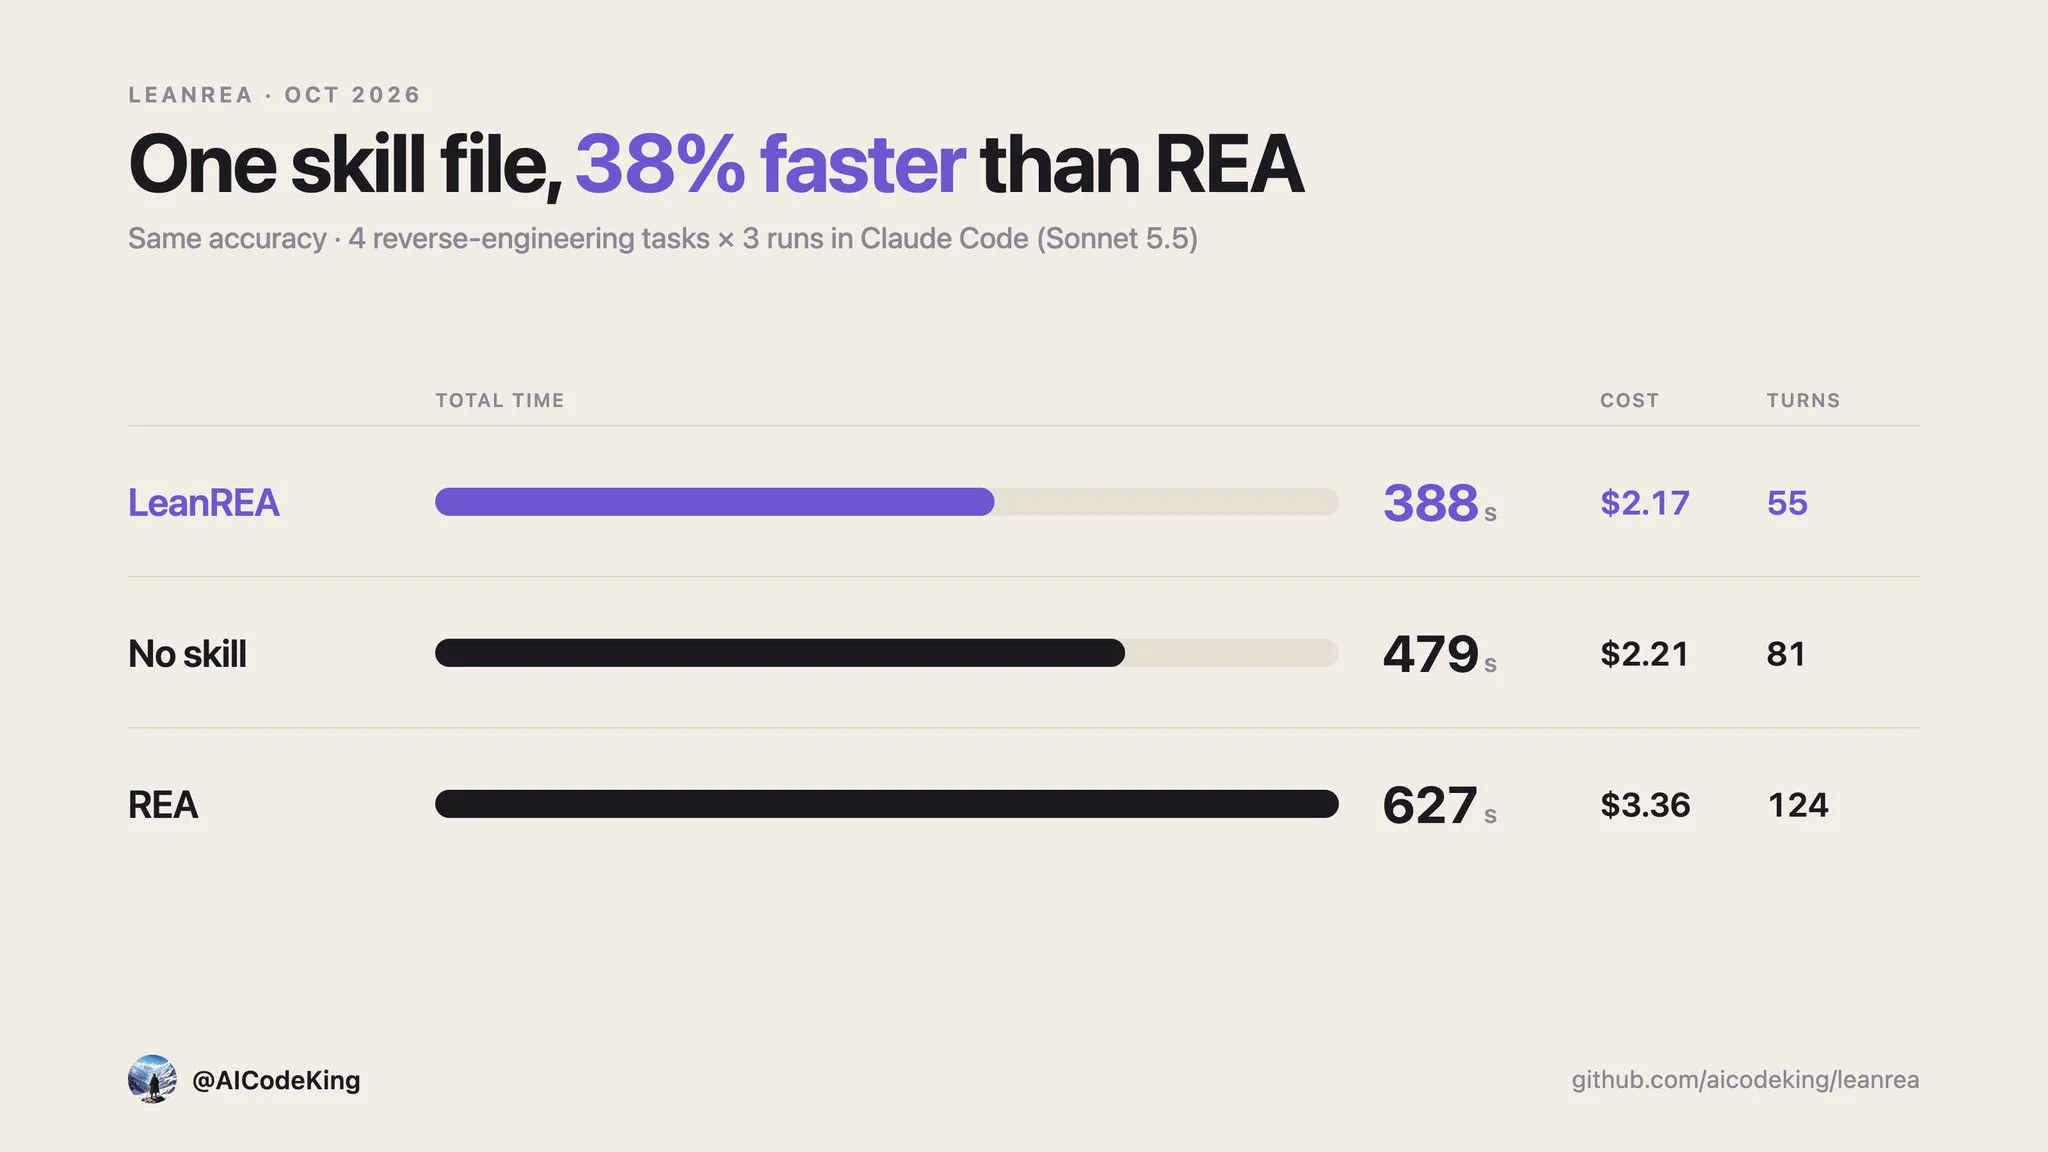
leanrea is an 8 KB skill file that tells a coding agent which plain CLI tools to use for reverse engineering, replacing REA, a 207-tool MCP server. In the author's test it ran 38% faster and 35% cheaper, scoring 74/75 against 75/75. The author lists caveats: 3 runs per task, one model, one machine, and Claude with no skill was already decent.
x.comthreadAdded 25 Oct 2026, published 23 Oct 2026  Daily Vibe Casting (@vibecastingapp) on X
Daily Vibe Casting is an X thread dated 24 October 2026 that summarises ten tech news items from the previous 24 hours. The AI items are Cloudflare's model-independent agent security audit skill, Recursive SI's Apache 2.0 Flint local coding model (125+ tokens/s on an M4 Pro), Anthropic's Claude Duet preview and Claude API version 2026-10-21, which drops temperature, top_p and top_k. It also covers HeyGen Voice Turbo and Gemini in Google Maps on CarPlay.
x.comthreadAdded 24 Oct 2026, published 22 Oct 2026 Jonathan Rhyne (@jdrhyne) on X
A post on X about NVIDIA's Nemotron 3.5 Parse and its "#1 on ParseBench" claim. The author says the ranking holds only among open-weight models under 1B parameters. On the full board of 150+ models the model scores about 75, while the top is near 90. The post asks vendors who run a benchmark to print the filter on the chart.
x.comthreadAdded 23 Oct 2026, published 22 Oct 2026- ERC-TBA: Agent Income Statements
ERC-TBA: Agent Income Statements is a draft Ethereum standard, a profile of the ERC-8004 Reputation Registry. A writer posts chained statements of what an agent's agentWallet received in one asset, with each incoming transfer a Merkle leaf, so lenders and buyers can verify earnings from x402 payments. Windows are cut at owner or wallet changes, and the post asks about statement grain, the MetadataSet requirement and who may write. The reference implementation is unaudited.
ethereum-magicians.orgthreadPublished and added 22 Oct 2026 - SpyTech Ai (@RizeOnline) on X
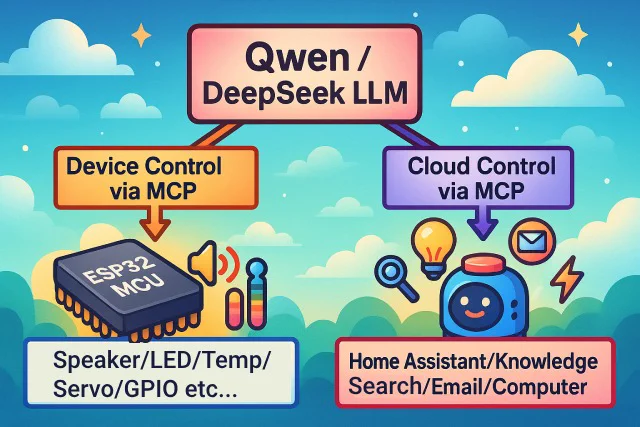
XiaoZhi ESP32 is an open-source, MIT-licensed firmware stack that turns ESP32 boards into MCP-based voice chatbots using models such as Qwen and DeepSeek. It streams Opus audio over WebSocket or MQTT + UDP through ASR, LLM and TTS, adds offline ESP-SR wake words, and uses device-side MCP to drive speakers, LEDs, servos and GPIO. It supports 138 board directories and builds with ESP-IDF 6.0.1 or newer.
x.comthreadAdded 23 Oct 2026, published 21 Oct 2026 - elvis (@omarsar0) on X
FrontierMemory is a benchmark that evaluates agent memory through downstream task performance, measuring how agents learn from experience rather than recall, which the post says is saturated via agentic search. In elvis's summary, Claude Opus 5.5 ranks first and open-weight GLM-5.3 does well on memory generation. The authors reply that "memory" here means any adaptation from experience, so harness-level changes can also be scored. The post gives no scores or links.
x.comthreadAdded 23 Oct 2026, published 21 Oct 2026  Open Weight Updates (@openweightstars) on X
Flint is the first model from Recursive SI, a fast local coding model with open weights released the same day. It was built with the company's automated research system, the Eureka Machine. The post claims up to 2x faster speed than comparable models: 125+ tokens/sec on a MacBook Pro and 150+ on RTX Spark. The captured text is truncated and gives no benchmarks or model size.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026- Swif (@swif_ai) on X
A post from Swif (@swif_ai) on the MCP TypeScript server SDK versions 2.0 to 2.2. A single server instance shared across HTTP clients, the pattern shown in the README, could send one client's responses to another client. Version 2.3.0 refuses that setup, so servers must be built per request or per session. The post gives no code or advisory ID.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026  SemiAnalysis (@SemiAnalysis_) on X
SemiAnalysis thread arguing that vLLM with Wide-EP and EPLB can reproduce DeepSeek's serving performance. It reports decode throughput within 6% of DeepSeek's DeepInfer release and about $39 per GPU-hour revenue at DeepSeek's off-peak pricing, at 200 P90 TPS on the AgentX workload. It explains why DeepInfer is not on InferenceX: the release supports only offline, single-turn inference. It also estimates GB300 profit at OpenRouter prices.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026- Vishesh Raheja (@entropyconquers) on X
GPT Voice is a free, open-source Mac app by Vishesh Raheja that brings ChatGPT's dictation to any macOS app. A shortcut starts recording, and the transcript is pasted where the user is typing. It uses the ChatGPT Pro subscription, so it needs no API key or extra subscription. The author built it after Handy handled coding prompts poorly and they did not want to pay for Wispr Flow. The thread gives no details on local versus API transcription or latency.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026 - Manish Kumar (@Manixh02) on X
Anatomy is an open-source agent skill that turns technical concepts into interactive visuals. Asked to explain a rate limiter or CDN cache, it builds a working model the user can explore. A tweet by Manixh02 says it works with Claude Code, Codex and other agents, and links to a GitHub repo under wheresryan22. The tweet gives no install steps or implementation details.
x.comthreadAdded 22 Oct 2026, published 21 Oct 2026 - 0xMarioNawfal - The Roundtable Show (@RoundtableSpace) on X
TorchTPU is Google's open-source project for running PyTorch apps on its TPUs, announced the day after Amazon released TorchNeuron for its Trainium chips. Google says migration needs "a simple configuration change" with no rewrite. It worked with Meta, Hugging Face, and the vLLM and SGLang teams on compatibility, and added an agent suite that helps migrate apps and fix errors. The post is brief and gives no benchmarks.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026 - 0xMarioNawfal - The Roundtable Show (@RoundtableSpace) on X
Headroom is an open-source GitHub project that compresses logs, files and tool outputs before they reach an AI coding agent. The tweet by RoundtableSpace claims up to 95% fewer tokens for JSON and about 20% fewer overall, with the same answers and lower API bills. The tweet gives no method or benchmarks, and the repo link is truncated.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026  brenz. (@brenzhills) on X
Krea 3 is an image generation and editing model from Krea. A post on X says its "Fast" variant scores 1125 Elo on the Artificial Analysis image editing leaderboard, against 1124 for Google's Nano Banana 2, while producing 10 images in the time Google produces 2. It also says the "Ultra" variant ranks in the top 4, behind only OpenAI models. The post gives no methodology or model details.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026 Parul Gautam (@Parul_Gautam7) on X
Beacon is an open-source memory layer for coding agents. It saves sessions across Claude Code, Cursor, Codex and more than 20 other tools, so developers can move work between agents without losing context. The team says it raised a $5.5M seed round and is building a self-improving feedback loop that learns from how users debug. The post gives no technical detail or repo link.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026 Paulo Pierrondi | AI agents (@paulopierrondi) on X
Paulo Pierrondi's X post, part 9 of a series on installing MCP servers, lists a monthly review of installed servers. The checks are which tools the agent used, servers not called in weeks, overlapping tools that confuse the model, and whether each server still has an owner. A reply adds a decommissioning check: after removal, confirm the server's old credentials can no longer call the backend.
x.comthreadPublished and added 20 Oct 2026 Angel (@ziran_pu) on X
AshAi, the AI package for the Elixir Ash Framework, is getting MCP client tools. Creating an MCP server with AshAi was already simple, but connecting your own LLM tool loop to an external MCP server had to be built by hand. The planned release includes OAuth client management resources. The post gives no release date, API details or code.
x.comthreadAdded 21 Oct 2026, published 19 Oct 2026- Ethan Walkrman (@ethanwalkerman) on X
Harness2 is a framework from Google Cloud AI Research and Northwestern University in which an Editor model rewrites an agent's harness (system prompt, memory, skills, tool scripts, subagent routing, middleware) without changing model weights. It uses a Propose-Probe-Compose loop that compares execution trajectories instead of ground truth. On WorkBuddy-Bench, GLM-5 rose from 64.2 to 75.7 after one round, above Gemini 3.5 Flash at 72.4. The thread also lists risks: latency, experience poisoning, and a sandbox that is off by default.
x.comthreadAdded 19 Oct 2026, published 18 Oct 2026 - ERC-8447: Swarm AI Framework
ERC-8447 (Swarm AI Framework) is a draft Ethereum standard proposing an on-chain registry and charter model for swarms: purpose-bound agent collectives with a membership boundary, an objective with attainment rules and a declared collaboration structure. Executed terms are hashed into a frozen spec, while the charter is kept off-chain. The reference implementation has 85 Foundry tests and tender and ERC-8436 decision adapters. The thread asks reviewers about vocabulary, amendment classes and the ERC-8004 dependency.
ethereum-magicians.orgthreadAdded 19 Oct 2026, published 18 Oct 2026 - [Draft ERC] Swarm AI Framework — registry and charter model for purpose-bound agent swarms
Ethereum Magicians discussion of a draft ERC, the Swarm AI Framework. It proposes a registry and charter model in which accounts, including autonomous agents, form, bound, run and dissolve purpose-bound swarms. A hashed on-chain SwarmSpec (roles with eligibility modules, phases, decision authorities, fallback timers) is paired with an off-chain Swarm Pack charter. Two-sided signed admission (EIP-712 / ERC-1271), challenge and substitution, and minor versus material amendments are included. Phase posture is a coordinate: executed boundary and admission, plus declared payoff, topology and coordination terms from a write-once vocabulary. This lets cooperation, competition, tenders, debate, ensembles and pipelines be expressed. It integrates with ERC-8004 agent identity and ERC-8436 decision adapters. The reference implementation is a non-upgradeable registry with five eligibility modules and a task-tender adapter. The post asks reviewers specific design questions on vocabulary, amendment classes, roster snapshots and digest kinds.
ethereum-magicians.orgthreadPublished and added 18 Oct 2026 - Bikash | Hermes Super-Intel (@BkashJosi) on X
Post by Bikash (@BkashJosi) ranking open GitHub issues labelled type/feature for the Hermes agent framework by thumbs-up reactions. The query returned 5,349 issues and only one has more than 50 votes. The top three are Claude Agent SDK with subscription OAuth (57), remote Hermes with local tool execution (41) and Mistral provider support (32), followed by backups, configuration sync and context reduction. The full top 10 is only in the video.
x.comthreadAdded 20 Oct 2026, published 17 Oct 2026  🚨 AI News | TestingCatalog (@testingcatalog) on X
A TestingCatalog X post with two Daily AI Briefs (Oct 17 and the start of Oct 16), grouped by vendor. Oct 17 items include GPT-6 Astra Pro upgrades in ChatGPT, Codex context reuse and caching, Gemini 4 Argon in AI Studio Build, the open-weight MIT-licensed DeepSeek-V4.1-Flash-1017, Claude Code Review going GA, Perplexity's open Decider v1.2 models (27B and 4B), NVIDIA's 4B looped Nemotron Labs Dory 1.0, Reflection's Apache-2.0 Beam, Cursor cloud-agent canvases and Tencent's Hy Memory 2.0. Oct 16 begins with Meta's open-weight Muse Spark Open, an 816B-total, 42B-active MoE with a 1M-token context. It gives a quick snapshot of the week's open-weight and coding-agent releases.
x.comthreadAdded 18 Oct 2026, published 17 Oct 2026- DeepSeek (@deepseek_ai) on X
DeepSeek announces DeepSeek-V4.1-Flash-1017, claiming stronger benchmarks, faster task completion and shorter outputs than the previous version, live on its website, app and API. It is optimized for DeepSeek Harness (v0.2.1-rc.1 or later), Tencent CodeBuddy and WorkBuddy, and uses reinforcement learning with self-feedback to improve end-to-end project development, from game creation to 3D modeling. The thread also opens the Search & Fetch APIs to everyone, backed by DeepSeek's in-house search engine at $0.75 per 1,000 calls per endpoint, available as server-side tools.
x.comthreadAdded 18 Oct 2026, published 17 Oct 2026 - Master the captain (@mollicksoif9) on X
A social post reporting that Reflection AI released the full weights of Beam, a 501B-parameter mixture-of-experts agentic coding model (23B active, 1M-token context), on Hugging Face under Apache 2.0. It claims RL training that penalizes wasted tokens gives roughly 3-4x less inference compute than GLM-5.2, and 80.9 on SWE-bench Verified. Launch support is listed for AWS SageMaker, vLLM and SGLang. The post notes the token-efficiency claims still need independent confirmation and that self-hosting needs about 500GB of GPU memory at 8-bit.
x.comthreadAdded 18 Oct 2026, published 17 Oct 2026 - CyrilXBT (@cyrilXBT) on X
REA (repo github.com/morluto/rea) is an open-source tool that lets a coding agent such as Claude Code do reverse engineering. The agent gets an app and a question, REA picks Ghidra, IDA or JADX, runs it locally and returns findings with evidence. Targets include desktop apps, compiled programs and games, Android apps, web traffic and firmware. Setup is `npx rea-agents setup`. The tweet's author claims it rebuilt a DX Ball sound function that compiles to identical code.
x.comthreadAdded 19 Oct 2026, published 17 Oct 2026 - Rodrigo ES Porto (@RodrigoESPorto) on X
X thread reporting that Meta confirmed Muse Spark (the coding and agent model) weights are coming, with no date and no license announced. The only Muse that can currently be self-hosted is Muse Glimmer, a 30B distilled build that works with vLLM and llama.cpp. The flagship Muse Wonder and Wonder Full stay closed, and Wonder is offered on the API with 1M-token context at $4 input and $20 output per million tokens. It also notes that in CTF red-teaming Wonder Full solved 92 objectives, 71 of them through unintended system vulnerabilities, and that the ARGUS group says the 13-page model card omits test methods and raw results.
x.comthreadAdded 17 Oct 2026, published 16 Oct 2026 - Romy (@0xBunny) on X
Tweet from 0xBunny announcing an update to Jev Workflows, an open-source workflow toolkit. It adds native Claude Code support alongside Codex, an opt-in Jev 1.14, experimental image/Box questions, shared QQ contract sync and local CI. Features were also mirrored to a sibling project called QQ. It is free, with no plugin quotas, and links to a GitHub repo.
x.comthreadAdded 17 Oct 2026, published 16 Oct 2026 - Peter Dedene (@dedene) on X
A X thread benchmarking Qwen3.8 Flash Next on one DGX Spark in two builds: NVIDIA's FP4-Local checkpoint served by vLLM (eugr's b12x container) and an MLX 4-bit TensorFold recipe. The NVIDIA build scores higher on the author's agentic benchmark (81.2 vs 75.0), BFCL tool calling (82.4 vs 71.8 single-turn, 54.5 vs 43.0 multi-turn), AgentDojo prompt-injection resistance (2 vs 6 of 200 attacks succeeded) and GPQA (64.6 vs 59.1). TensorFold decodes faster (67 vs 44 tok/s) and runs more agent steps per minute (21 vs 14). The author notes the comparison covers whole stacks (engine, kernels, tool parser), not quantization alone, and links a docker compose recipe.
x.comthreadAdded 17 Oct 2026, published 16 Oct 2026  AmingIn_AI (@aming_inAI) on X
A tweet from AmingIn_AI describes a macOS screenshot-annotation tool. On release it saves the screenshot, a crop and the user's marks locally, then copies a 127.0.0.1 link. Claude Code or Codex on the same Mac can fetch that link and receive the marked image plus app/window info, and nothing is uploaded. It shows a local, privacy-preserving way to hand visual context to coding agents without MCP or cloud upload.
x.comthreadAdded 17 Oct 2026, published 16 Oct 2026- Harrison Kinsley (@Sentdex) on X
Sentdex reacts to Artificial Analysis ranking NVIDIA's Nemotron 3.5 Super VL (120B total, 12B active MoE) as the top US open-weights model, scoring 26 on the Intelligence Index. That edges out Thinking Machines' Inkling Small (26), NVIDIA's Nemotron 3 Ultra (23) and Meta's Muse Glimmer (17). Sentdex's informal tests at vanilla settings show over 550 tok/sec, and they suspect it would rank higher on agentic coding. They see it as a candidate for a fast local coding agent model.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026  Vaibhav Sisinty (@VaibhavSisinty) on X
Social post reporting Meta's release of Muse Spark Open, described as the most capable US open-weight model: 816B total and 42B active parameters, a 1M-token context, and text, image, video and audio input in one model. It is pitched at coding and agentic work and tuned to run on two M5 Ultra Mac Studios, with weights available at release. The poster notes that in Meta's own chart, China's Kimi K3 and GLM 5.3 still beat it on coding.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026 Connor (@ConnorTalksAI) on X
A tweet relaying OpenAI's announcement of GPT-Live-1.1, an update to the voice model behind ChatGPT voice mode. It reduces how often the model says "checking", adds new voices and improves accents, including new voices in French, German, Hindi, Mexican Spanish, Korean and Japanese. It is rolling out to all users in ChatGPT, Codex and "dots", with API access coming soon. The poster frames it as a response to a new xAI/SpaceXSI Grok Voice release.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026- Francis Santerre (@santerref) on X
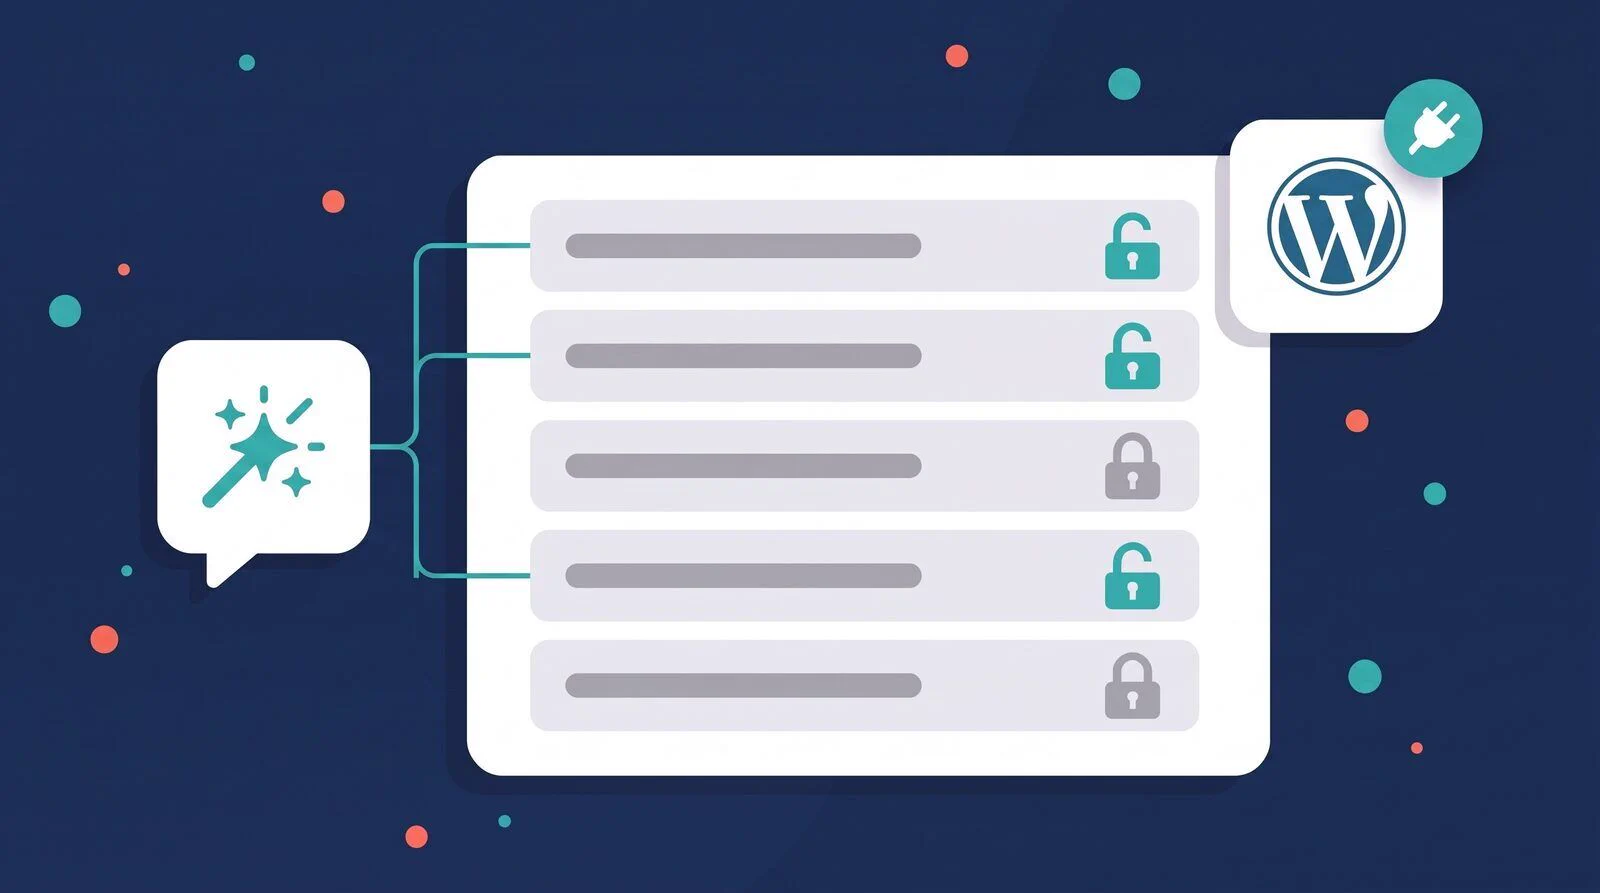
Tweet announcing that the MCP Adapter is now a canonical plugin on WordPress.org (version 0.7.0). It bridges the WordPress Abilities API to the Model Context Protocol, with a default server at /wp-json/mcp/mcp-adapter-default-server. Only abilities a site marks public are exposed, so the security review comes down to auditing the ability list.
x.comthreadAdded 16 Oct 2026, published 15 Oct 2026 - 44er (@44errrr) on X
Announcement of hexvero, an MCP server that gives coding agents a static first look at binaries and app bundles across 18 formats (ELF, PE, Mach-O, APK, .NET, Go, Wasm, Electron, SQLite). It uses zero-dependency Node parsers and marks each finding confirmed or inferred with file and line. Its tool catalog is 3,043 tokens, against a claimed 509,696 for the established reverse-engineering MCP server. Paged output with a byte budget shrinks a 541 MB Electron app to a 15 KB result, 1.3 MB of JSON to 7.9 KB, and a 450 KB build diff to 1.2 KB. radare2, rizin or Ghidra plug in for disassembly, and `npx hexvero setup --apply` registers it with Claude Code, Cursor, Codex and 15 more clients. It is a concrete example of keeping MCP tool definitions and results small enough for an agent's context window.
x.comthreadAdded 15 Oct 2026, published 14 Oct 2026  Gunjan N Ganatra (@gnganatra) on X
LightSeek Foundation announces 685 output tokens/s per user on Alibaba's Qwen3.8-Flash-Next. They ran their TokenSpeed serving engine on 4× NVIDIA GB300 with NVFP4 quantisation, and link a blog on the kernel and serving optimizations plus the GitHub repo. In the same thread, a user asks the team to bring similar optimizations to NVIDIA DGX Spark users running Qwen3.8-27B on vLLM, and to the upcoming Qwen4-27B. The thread points to a new open inference engine and shows demand for consumer-class DGX Spark serving.
x.comthreadPublished and added 14 Oct 2026- Draft ERC: Agentic Resource Discovery (ARD) Onchain — an address-rooted value registry whose records are ARD entries
Ethereum Magicians draft ERC proposing an onchain, address-rooted registry beneath Google's Agentic Resource Discovery (ARD) spec. Every record remains a valid ARD entry. It adds four kinds (skill, task, agent, registry), CAIP-19/CAIP-10 anchors, JCS+SHA-256 descriptor hashes and domain claims collected as endorsements. A Solidity/Foundry reference kernel with four adapters and a Node.js resolver/gateway are included; the gateway passes the official ARD conformance CLI. The author asks for feedback on the address-as-root boundary, the envelope exclusion from the hash, same-chain-only anchors, and the proposed application/ai-task+json payload.
ethereum-magicians.orgthreadPublished and added 13 Oct 2026 - ERC-8444: Agentic Resource Discovery (ARD) Onchain
An Ethereum Magicians proposal for ERC-8444, which adds an onchain value and settlement layer under Google's Agentic Resource Discovery (ARD) spec for finding MCP servers, A2A agents, skills and APIs. A thin kernel records kind (skill, task, agent, registry), a CAIP-19/CAIP-10 anchor, a JCS+SHA-256 descriptor hash, a canonical URN and a status. Authority belongs to the paid address, and domains act as collected endorsements through /.well-known/ard.json. The reference implementation has Foundry-tested Solidity adapters and a Node.js gateway that passes the official ARD conformance CLI. It introduces a "task" kind (application/ai-task+json) for tenders aimed at suppliers, and the author asks for feedback on the trust root, the hash scope, same-chain anchors and the task payload.
ethereum-magicians.orgthreadAdded 14 Oct 2026, published 13 Oct 2026 - kage (@0XKageX0) on X
A tweet describing a free setup for running a ~27B open-source Qwen model on Google Colab's free T4 GPU, driven from VS Code. A Cloudflare tunnel with a proxy locks the endpoint behind an API key, and the endpoint is connected to 9router so Claude Code and Claude Cowork on the desktop can use it. It matters as a pointer to a zero-cost way to get Claude Code-style workflows on a self-hosted open model, though the steps are only in an accompanying video and the tweet gives no configuration or quantisation details.
x.comthreadPublished and added 12 Oct 2026 - Codex CLI installs a persistent, self-updating background daemon by default
GitHub issue asking OpenAI to make `daemon_auto_start` opt-in in Codex CLI 0.157.0. By default, opening an interactive session starts a persistent `codex app-server --managed-daemon` that outlives the terminal. It also copies a ~374 MB platform package into ~/.codex/packages/app-server-daemon and runs a detached hourly `pid-update-loop` updater. The daemon keeps the first session's environment (proxy variables, cwd, direnv values), which the reporter ties to hook bugs #42457 and #37537. Comments confirm the problem on Windows and add the workaround (`codex features disable daemon_auto_start`, kill the updater, remove the package dir). They also note that `daemon stop` leaves the updater running and that the option is missing from the config docs. One commenter proposes an "execution receipt" (CLI version, daemon binary digest, generation, inherited-environment generation).
 github.comthreadPublished and added 12 Oct 2026
- Igor Carron (@IgorCarron) on X
Igor Carron's tweet highlights LightOn's open-source ColGrep-Agent-2B, a 2B model released on Hugging Face for code search and retrieval that works with Claude Code. LightOn reports 34% fewer API tokens and 40% lower API costs. It matters because usage limits and token costs are a pain point for coding agents. A reply thread in the same post notes quota exhaustion across Grok, Cursor, Devin, Claude and Codex, and argues for quota dashboards.
x.comthreadPublished and added 12 Oct 2026 - =dennis; (@Xidea404) on X
A tweet from @Xidea404 pointing to the ADI Chain MCP Server documentation on docs.adi.foundation. The server lets AI agents interact with the ADI blockchain through the Model Context Protocol. The tweet carries no technical detail itself, so what the server exposes can't be confirmed from it. It is a pointer to a blockchain-specific MCP connector.
x.comthreadPublished and added 12 Oct 2026  The gap in shared understanding of LLM capability is widening
Andrej Karpathy argues the gap in shared understanding of LLM capability is widening into a funnel: ~6B people barely touch LLMs, 1-2B use free-tier chatbots casually, ~20M professionals in math and code see agents finish weeks-long projects from a prompt, and ~5,000 people with internal frontier access see swarms of agents on software mega-projects. He attributes the funnel to problem ambition and scale, jagged capability (peaks in digital, verifiable, economically valuable domains because of RL on verifiable rewards), and access tier. It is a useful framing for why people talk past each other about AI progress.
twitter.comthreadPublished and added 11 Oct 2026- Arindam Majumder 𝕏 (@Arindam_1729) on X
A tweet describing an independent open-source project, "Free Claude Code", that lets Claude Code run against non-Anthropic providers such as DeepSeek and Kimi. It supports switching models, configuring fallback providers and using providers' free tiers, launched via `fcc-claude` from the terminal or an IDE. It states the limits: free usage follows provider quotas, some providers still need API keys, it does not unlock Anthropic's own models, and it is not affiliated with Anthropic. The page also shows a quoted article on a 5-layer setup for running coding agents in YOLO/auto-approve mode safely.
x.comthreadPublished and added 10 Oct 2026 - Jetwani Avinash (@jetwaniavinash) on X
Announcement of jevmem, an open-source MIT plugin that gives Claude Code, Cursor and Codex persistent project memory. After each turn it asks Jev (a TypeSafe AI model) whether anything is worth keeping (a rule, decision, failure, or to-do) and writes one line to a plain Markdown file tracked in git. It also checks commands against saved rules before they run and asks first, or blocks. Reported results: Claude followed the rule in 66 of 72 sessions vs 28 without it, the right save/skip call on 98.5% of 66 turns, and 66 of 68 rule-breaking commands caught out of 274 test commands. Listed in Anthropic's Claude plugin directory and on the MCP Registry.
x.comthreadPublished and added 10 Oct 2026 - 0xMarioNawfal (@RoundtableSpace) on X
A tweet highlighting Prompts Chat (formerly Awesome ChatGPT Prompts), an open-source prompt library on GitHub that the post says has 167K+ stars. It works across ChatGPT, Claude, Gemini and other models. The post lists a CLI, an MCP server, a Claude Code plugin and self-hosting with custom branding and auth, all free. It is worth cataloguing as a pointer to a widely used prompt collection that now plugs into coding-agent and MCP workflows.
x.comthreadPublished and added 10 Oct 2026 - [Pre-ERC Discussion] Agent Service Order Amendments
Ethereum Magicians pre-ERC discussion proposing a signed, EIP-712 amendment object for changing an existing agent service order (scope, acceptance criteria, price increase, deadline extension) without losing the prior agreement or implicitly authorizing extra spending. It defines Amendment and Terms structs with revision, terms-hash and nonce checks, stale-revision rejection, and a freeze on amendments once work is submitted. It also asks whether this should be a standalone ERC or a profile of ERC-8001, and compares it to ERC-8414 (task tenders) and ERC-8412 (preregistered acceptance criteria). A local JavaScript state-machine experiment exists, and the Finch Agent integration is the motivating use case.
ethereum-magicians.orgthreadPublished and added 10 Oct 2026  JASON MCNAB (@JASONMCNAB) on X
Tweet reporting VIDRAFT's POCKET-Darwin-180B, a 4-bit GGUF (111GB) of a 180B MoE built on Qwen3.8-Flash-Next. Self-reported figures: 4.17 tok/s on a gaming laptop with an 8GB GPU and 32GB RAM using llama.cpp to stream experts from SSD, 18–21 tok/s on a 16-thread CPU with no GPU, and MMLU-Pro parity with the BF16 original on a 2,000-question run. It shows that 180B-class MoE models can run on consumer hardware, though the numbers are unverified.
x.comthreadAdded 10 Oct 2026, published 9 Oct 2026- Confident AI (@confident_ai) on X
Confident AI announces Eval Skills, open-source (Apache 2.0) agent skills for Claude Code and Codex. The `eval-build` skill takes an app to a runnable baseline: it finds realistic examples in traces and incidents, annotates failures, groups them into failure modes, curates cases with independent data splits, and builds graders validated against human judgment. The `eval-descent` skill runs a bounded loop of hypothesis, app change, eval re-run, regression check, then keep or revert, with held-out cases kept out of the loop. It ships Python and TypeScript tooling for tracing, annotation, grading and reports, plus a local UI or Confident AI for managing the loop.
x.comthreadPublished and added 9 Oct 2026 - 500altcoins | HFSP.eth 🦇🔊 (@500altcoins) on X
A tweet explaining how to cut Claude Code costs by routing all subagents to Claude Haiku 5.5. It sets the model in settings.json (the `haiku` alias points at Haiku 5.5 from Claude Code v2.1.293), keeps the main session on the larger model, and lets individual agents override the model in their frontmatter. It links to the subagent model docs.
x.comthreadPublished and added 9 Oct 2026 - Adam Shepherd (@EntryStateGod) on X
Social post announcing Qwen's open-weights release of Qwen-Image-2.1-Turbo, an accelerated checkpoint of Qwen-Image-2.1 on the same 7B visual generation architecture. It generates and edits images in 8 denoising steps, against 40 in the base model's sample code, with 2K output. Qwen claims the fewer steps do not reduce quality. The license is non-commercial, which limits production use.
x.comthreadPublished and added 9 Oct 2026  RJ (@RJiOSDEV) on X
A tweet reporting JetBrains' Oct 8 release of Mellum2.1, an open-weights coding model under Apache 2.0. It has 12B total parameters with 2.5B active, which implies a mixture-of-experts design. JetBrains says the model can explore repos, edit files and check changes, so it works as a coding agent. The tweet asks whether developers would self-host a coding agent. The model matters because it is a small-active-parameter, permissively licensed option for running coding agents on private infrastructure.
x.comthreadPublished and added 9 Oct 2026- berni (@bernirov) on X
A tweet promotes "alook," an open-source (Apache 2.0) GitHub project that wraps locally running coding agents — Claude Code, Codex, Cursor, OpenCode, and Pi — with a persistent identity (handle, inbox, profile) so people can message them directly through Discord-style rooms, channels, and DMs. Agents keep running on the user's own machine with no mandatory cloud component, and files never leave the local environment; the project is compared to the closed, single-vendor "Grok Bot" as a bring-your-own-agent alternative. At the time of the post it had around 1.2K GitHub stars.
x.comthreadPublished and added 8 Oct 2026  Marktechpost AI (@Marktechpost) on X
Liquid AI released Open d1, two open-weight "decision models" — d1-3B (text + vision) and d1-omni-600M (text + image or text + audio) — that don't generate text tokens at all. Instead they take a state plus a typed question as input and return calibrated probabilities in a single forward pass, positioning them as lightweight classifiers/judges rather than generative LLMs.
x.comthreadPublished and added 8 Oct 2026- OpenAI withdraws three mathematical results
A tweet from Dan Roberts announcing an update to a GitHub repository tracking Lean formal verification of mathematical results tied to OpenAI math research, adding six new Lean formalizations and nineteen modifications, now covering roughly 42 percent of top line results. The update also discloses withdrawal of three manuscripts, on algebraicity of Weil classes on split abelian eightfolds, Kuga Satake correspondences for K3 surfaces, and the rational Hodge conjecture for products of K3 surfaces, after formalization work revealed errors.
twitter.comthreadPublished and added 8 Oct 2026 - Liquid AI (@liquidai) on X
Liquid AI announces Open d1, two open-weight multimodal decision models. d1-3B (built from LFM2.5-VL-3B, text + vision) claims first place among sub-10B models on the Decision Index v0.2.1, while the experimental d1-omni-600M (LFM2.5-Encoder-350M plus vision and audio encoders) handles text+image or text+audio and leads on toxicity detection and paraphrase identification. Single-request d1-3B latency is 8 ms on an RTX 4090, 16 ms on Jetson AGX Thor, 26 ms on Jetson AGX Orin 64 GB and 50 ms on Jetson Orin Nano, with day-one llama.cpp support; demos include live-camera apps and Isaac Sim navigation. Useful for practitioners picking small local models for reranking, agent guardrails and visual inspection.
x.comthreadAdded 9 Oct 2026, published 7 Oct 2026 - Alhaji Premium Man (@softhardguy) on X
A tweet thread announcing Concord, an open-source coordination layer for running multiple AI coding agents (Claude Code, Codex, Cursor) concurrently on the same codebase. Agents claim files before editing so overlapping edits trigger warnings, and the tool lets agents message each other across the different coding-agent harnesses, addressing the conflict problem that appears once three or more agents work in parallel.
x.comthreadPublished and added 7 Oct 2026 - Dr Milan Milanović (@milan_milanovic) on X
A Twitter/X thread breaking down three protocols that connect AI agents to different things: MCP (agent to tools/data, JSON-RPC 2.0 over stdio or Streamable HTTP), A2A (agent to agent, using an Agent Card JSON manifest at /.well-known/agent-card.json, running over JSON-RPC/gRPC/HTTP+JSON), and ACP, the Agent Client Protocol created by Zed in 2025 for connecting code editors to coding agents (modeled on LSP, JSON-RPC over stdio). It clarifies that IBM Research's older "Agent Communication Protocol" (also abbreviated ACP) merged into A2A on 29 August 2025, making many existing protocol comparisons outdated, and notes governance differences: MCP and A2A sit under the Agentic AI Foundation (Linux Foundation) while the Agent Client Protocol is governed by Zed and JetBrains. The author also mentions building an internal MCP server letting customers run and schedule reports via ChatGPT and Claude.
x.comthreadPublished and added 7 Oct 2026 - Itsvishal (@itsvishaltwt) on X
A tweet reports that Mistral has announced Mistral Large 4, internally nicknamed "Le Chonk," a mixture-of-experts model with roughly 1 trillion total parameters and 49 billion active parameters. It is described as natively multimodal and state-of-the-art on critical workloads including cyber defense, with API access starting immediately and an open-weight release planned for late October.
x.comthreadPublished and added 6 Oct 2026 - 🚨 AI News | TestingCatalog (@testingcatalog) on X
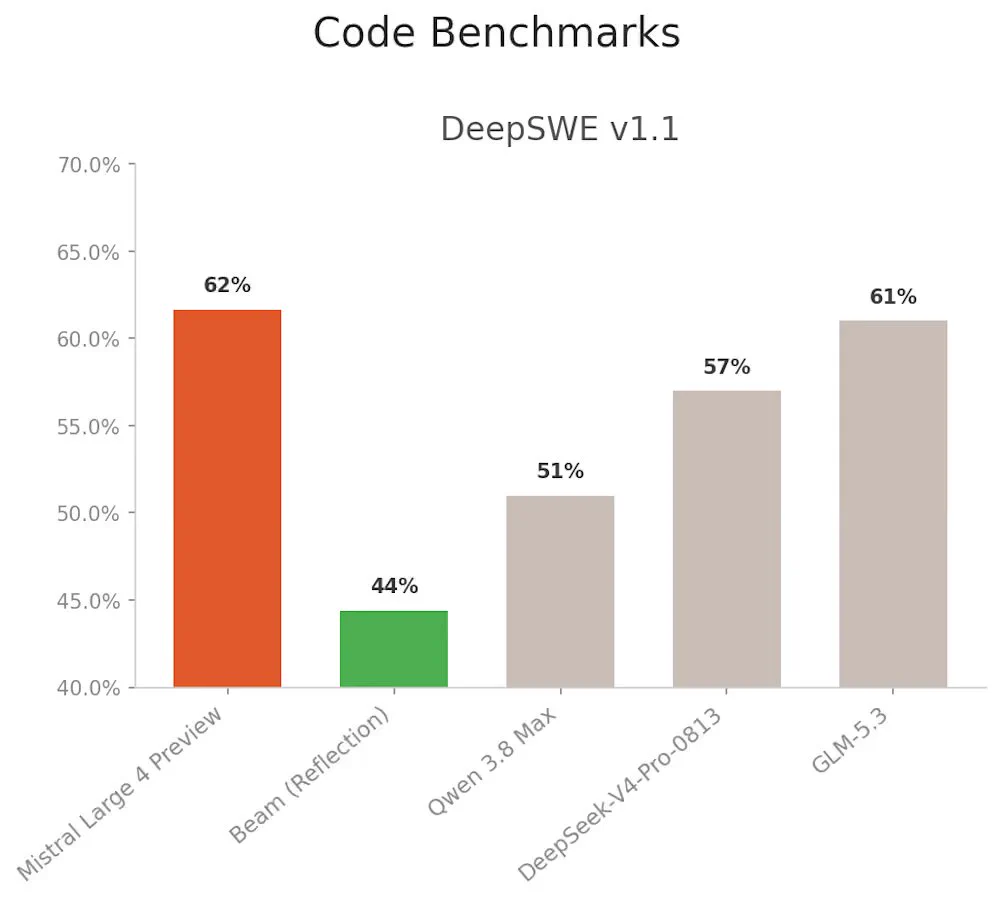
Twitter thread reporting that Mistral announced Mistral Large 4, codenamed "Le Chonk," a 1-trillion-parameter open-weight model with 49B active parameters and native multimodality, rolling out via API now with open-weight release planned for end of October. It reportedly scores 62% on the DeepSWE benchmark (ahead of GLM-5.3), 67% on the Finch financial-tasks benchmark (SOTA open-weight), and 15% on Harvey's Legal Agent Benchmark (also SOTA open-weight), per VentureBeat and @AiBattle_.
x.comthreadPublished and added 6 Oct 2026 - Randy Northrup (@starsoldier420) on X
Muse Spark Code is an open-source coding agent wrapping Meta's Muse Spark model, exposed as an ACP (Agent Client Protocol) agent so any ACP-compatible client, including Neovim, can drive it. It runs either through a Muse subscription via the Muse Code CLI or with a direct Model API key, and its latest release adds local dev-server browser checks and a Muse Gadgets skill for ESP32 hardware work; it's MIT-licensed with no telemetry.
x.comthreadPublished and added 5 Oct 2026  Bill Xie (@joyrap) on X
A Twitter thread summarizing key takeaways from a podcast conversation with Thibault Sottiaux (Tibo), Head of ChatGPT and Codex at OpenAI. Topics include the prediction that most internet actions will soon be taken by agents, how Notion's MCP server launch caused a traffic flood that strained its systems, the likely disappearance of the model picker in favor of automatic routing, skepticism about loops and graphs as durable agent architectures, and OpenAI's approach to AI safety.
x.comthreadPublished and added 5 Oct 2026- Franco Naumow. (@naumowf) on X
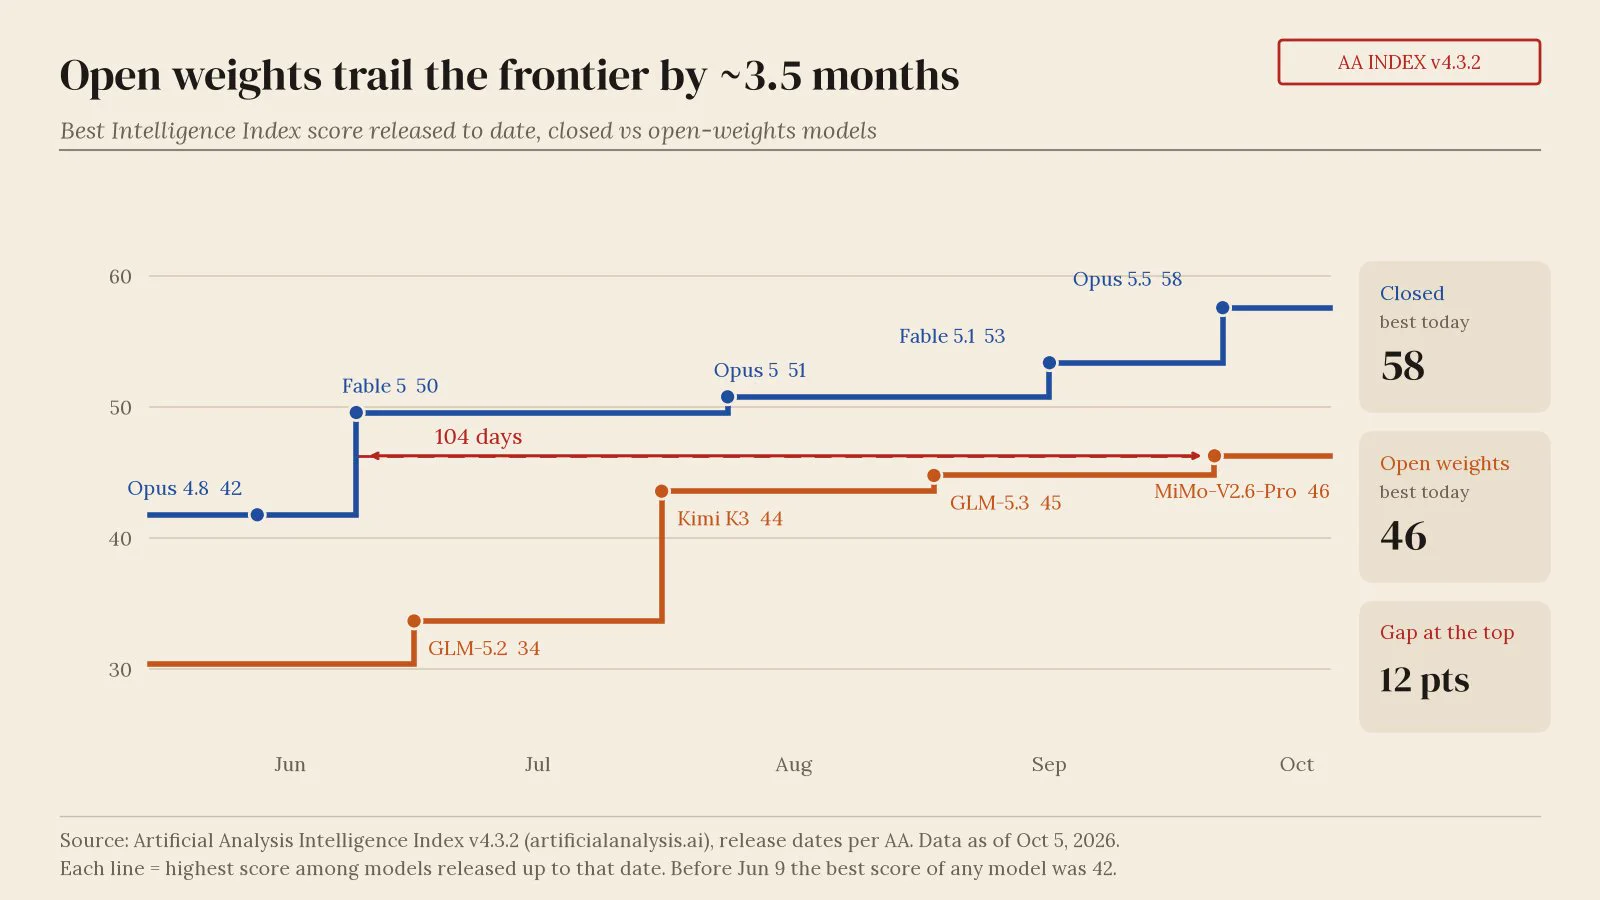
A tweet analyzing the Artificial Analysis Intelligence Index v4.3.2 finds that the best open-weights model, Xiaomi's MiMo-V2.6-Pro (released Sep 21, scoring 46), still trails what would have been the top closed frontier score as of 104 days earlier — Claude Fable 5's 50 on Jun 9, which itself surpassed the prior best (Claude Opus 4.8 at 42). It notes the current top-of-leaderboard gap is 12 points, with Claude Opus 5.5 (max) scoring 58, framing the persistent ~3.5-month lag of open weights behind the closed frontier.
x.comthreadPublished and added 5 Oct 2026  Register Codex's Computer Use as a Claude Code MCP Server
A thread shows how to register Codex's built-in Computer Use capability — the "cua_repl" MCP server found in ~/.codex/plugins/cache/openai-bundled/unified-computer-use/ — as a custom user MCP server (named "codex-cu") inside Claude Code, letting Claude drive Mac GUI automation via Codex's computer-use backend instead of a separate CUA driver. The author reports an informal benchmark across 8 computer-operation tasks: Claude Opus 5.5 + Codex Computer Use scored 6/8, Codex alone scored 6/8, and the original CUA driver only scored 3-4/8, with a caveat that future Codex updates could break this cross-agent MCP reuse.
x.comthreadPublished and added 5 Oct 2026- John Davis | Solar Strategies (@solarstrategies) on X
A tweet reports that Reflection AI, a US lab backed by NVIDIA, is about to release its first open-weight model. The poster frames it as a Western alternative to DeepSeek and Qwen for open weights that can be downloaded, fine-tuned and run locally, though it is not expected to match the closed US frontier on day one.
x.comthreadPublished and added 5 Oct 2026 - Meer Tarbani - Growth & Engineering (@MeerTarbani) on X
Sidekick is an open-source macOS plugin for Claude Code that lets you define a one-sentence persona (e.g. "a blunt senior Rust dev") and drive a coding session hands-free by voice: it listens via Apple's on-device speech recognition, speaks answers with macOS voices, and lets you interrupt it mid-reply or say "stop" to cancel a turn. It also surfaces Claude's multiple-choice decisions as spoken questions, matching answers like "the second one" against an echo-filtered transcript so the assistant doesn't hear and respond to its own voice. Implementation is a ~500-line TypeScript Claude Code hooks module plus a 90-line Swift speech listener, runs fully local with zero servers and zero telemetry, and installs via the `claude plugin marketplace`/`claude plugin install` commands.
x.comthreadPublished and added 4 Oct 2026  SunsetSyntax (@sunsetsyntax) on X
A short account of switching from a split Neo4j (relationships) + separate vector DB (embeddings) setup — which required manually reconciling IDs whenever an agent wrote a fact — to NornicDB, a single Go-based graph+vector store that speaks Bolt/Cypher and bundles an MCP server in one process. The point is that agents can query a unified memory store without an app layer babysitting two separate databases.
x.comthreadPublished and added 4 Oct 2026- Sahil Verma (@sahilvermaai) on X
Aleph Alpha released Kolibri, a 78B-parameter open-weight mixture-of-experts model with only 3.46B active parameters per token, a 1M token context window, and Apache 2.0 licensing with full weights on Hugging Face. The model was trained on German and Finnish infrastructure, positioning it as a European-built alternative to US/Chinese open-weight releases.
x.comthreadPublished and added 4 Oct 2026  Rajashekar Sudireddy (@raja_sudireddy) on X
A tweet thread recapping Nate Herk's 18-concept guide to running OpenAI's Codex as a non-coder "AI operating system," organized around four pillars: a place to work (projects, AGENTS.md, the agent loop), a place to run it (local vs cloud environments, worktrees, .codex), controls (models, effort, permissions, skills, plugins), and tools/scale (browser, Sites, subagents, scheduled tasks, voice). It highlights AGENTS.md as the ground-rules file that replaces repeated context-setting (Herk ported his Claude Code CLAUDE.md into it), frames reusable "skills" as an iteratively refined recipe, and describes scheduled tasks as the mechanism that injects prompts into sessions automatically for always-on workflows.
x.comthreadPublished and added 4 Oct 2026 Sujeet (@sujeetgholap) on X
A tweet arguing that Meta is using the credibility it earned from releasing open-weights Llama models to legitimize Muse, a free-as-in-beer service that bundles compute, weights, and apps rather than offering genuine open access. The commentary frames this as a strategic pivot from open-weights advocacy to a closed, Meta-controlled ecosystem play, explaining why Muse feels less aligned with the open-source AI movement than Llama was.
x.comthreadPublished and added 3 Oct 2026- Jan Curn (@jancurn) on X
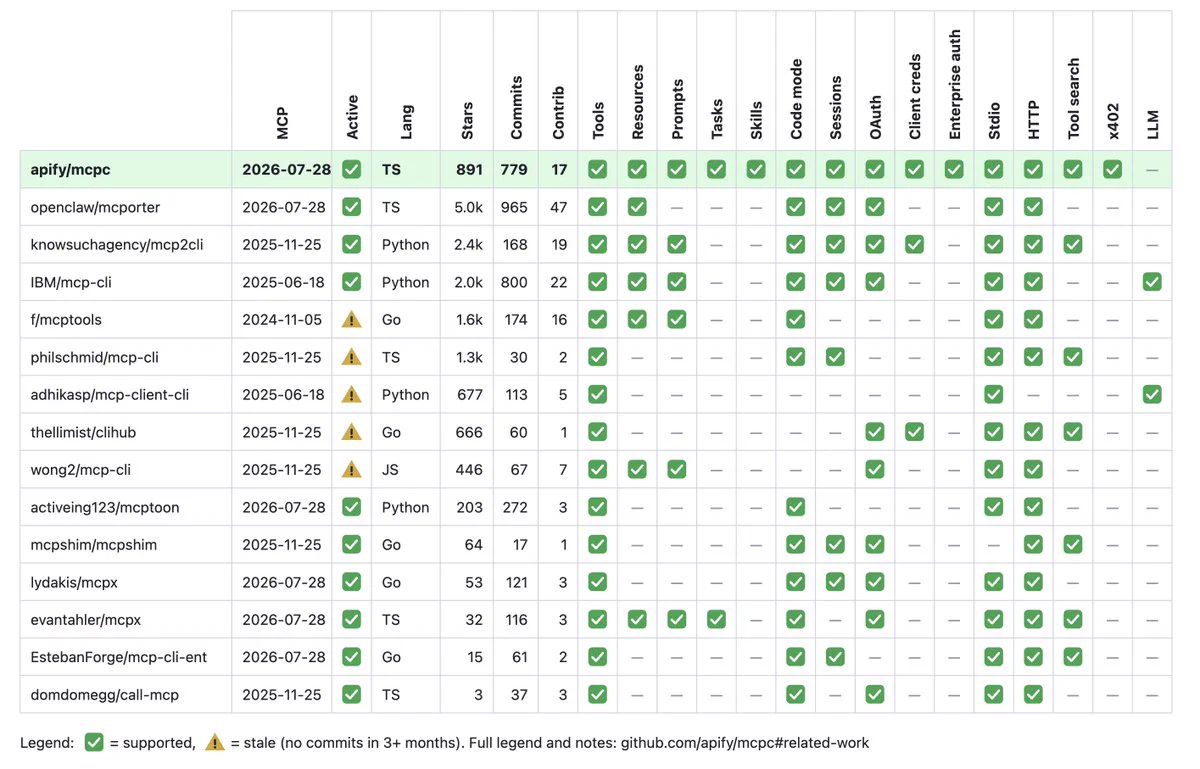
Jan Curn announces mcpc v0.7.0, an open-source MCP CLI client (npm package @apify/mcpc), adding support for the MCP Skills extension via new skills-list and skills-get commands that fetch and cryptographically verify SKILL.md and supporting files against the skill manifest (size + SHA-256). The release also hardens security by preventing repo-local .mcp.json auto-discovery from reading environment variables (blocking token-leak tricks), scoping refresh tokens to the originating auth server, and fixing an insecure Windows login URL launch path via cmd.exe, alongside OAuth session longevity fixes and 2026-07-28 MCP spec compatibility improvements.
x.comthreadAdded 5 Oct 2026, published 3 Oct 2026 - Brendan Jowett (@jowettbrendan) on X
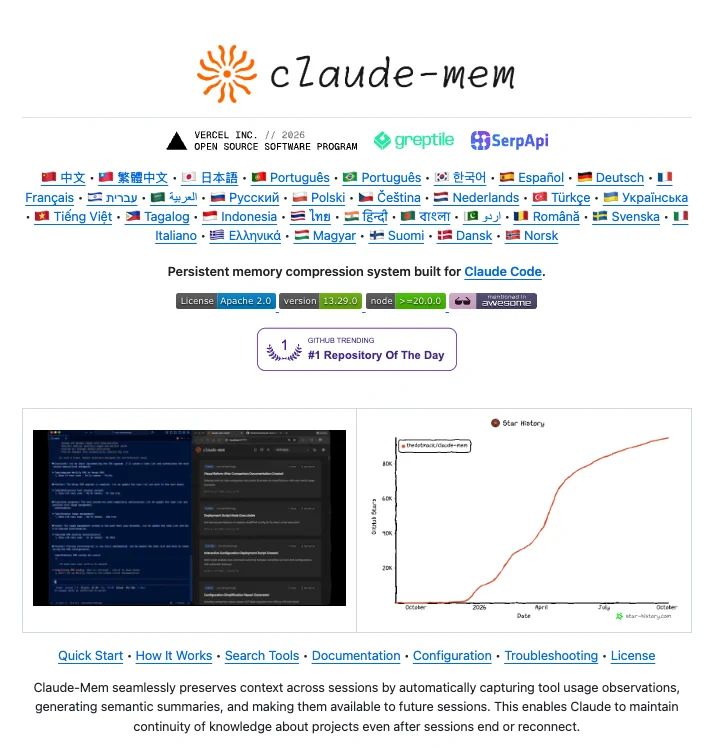
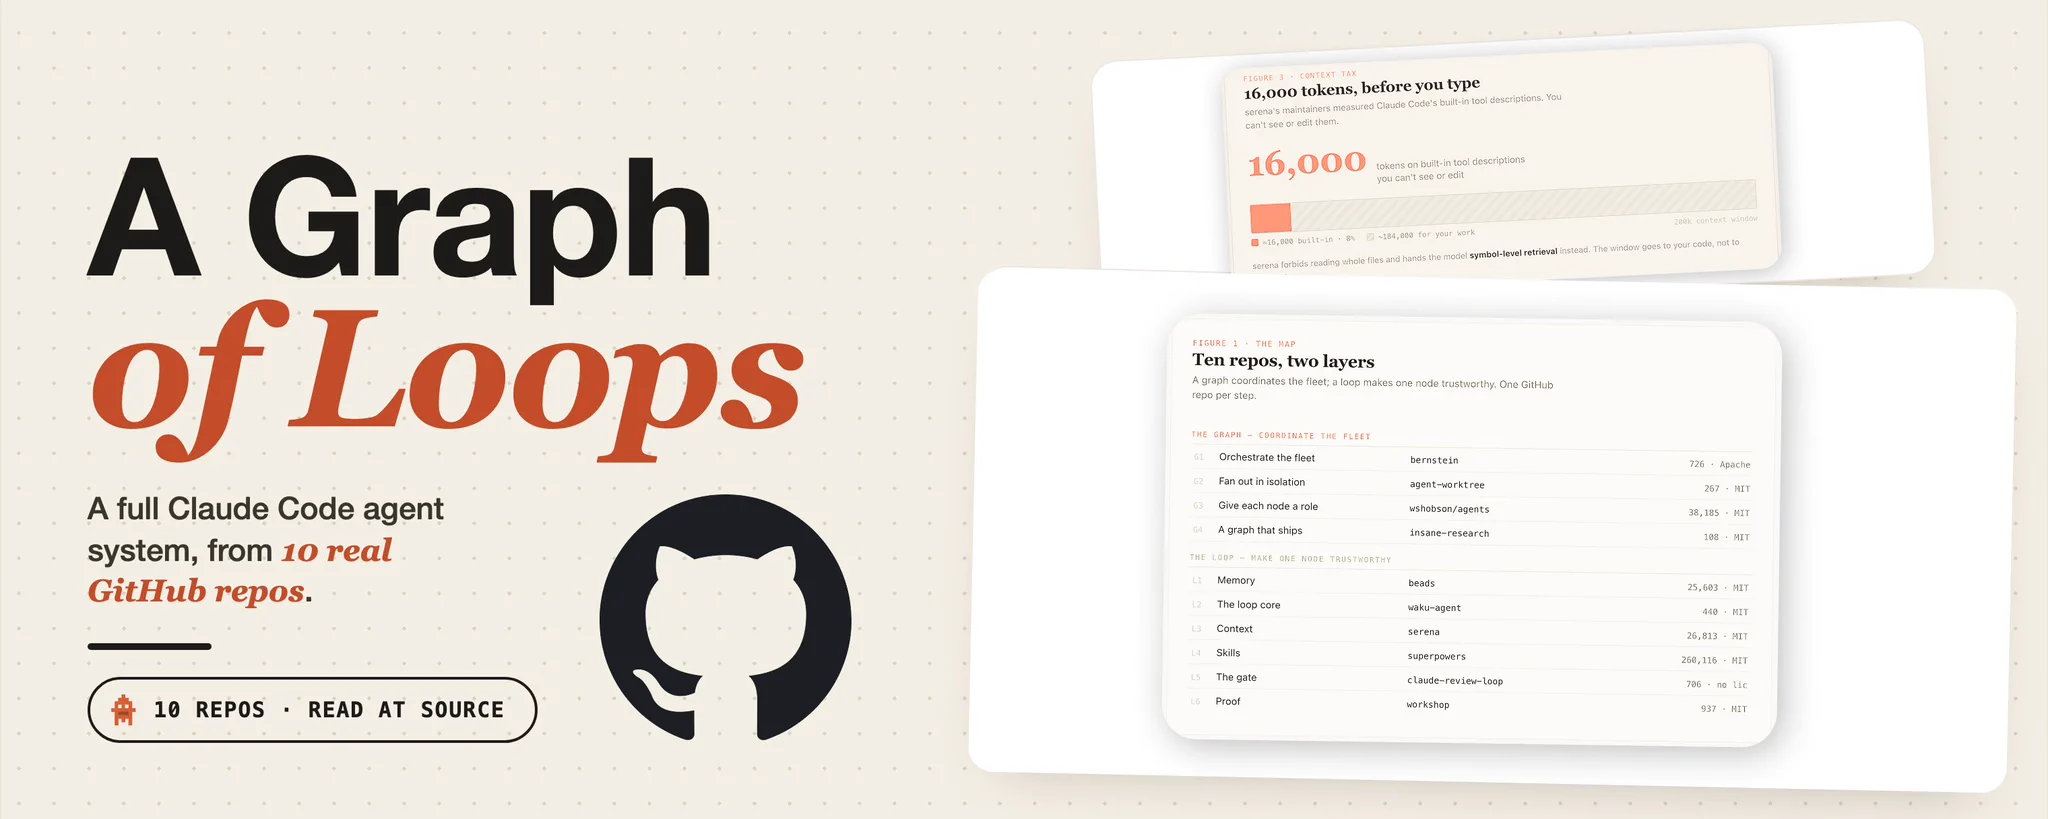
A curated Twitter/X thread listing ten GitHub repos that extend Claude Code and Codex workflows: spec-forcing planning/testing skills (obra/superpowers, mattpocock's skills with grill-me/diagnose/handoff), session memory compression (thedotmack's claude-mem-style tool), codebase-to-graph querying (safishamsi/graphify), a spec-driven long-task workflow (gsd-build), scope-reduction and anti-fluff skills, a cross-tool harness spanning Claude Code/Codex/OpenCode/Cursor (affaan-m/ECC), a multi-role agent team setup (garrytan/gstack), and a local model-routing gateway (musistudio's claude-code-router). Each entry is a practical, installable tool aimed at making coding agents more disciplined, memory-aware, and cost-efficient.
x.comthreadPublished and added 3 Oct 2026  Brandon Wie (@BrandonWie) on X
A Twitter/X thread announcing an open-source framework for reinforcement-learning training of models that runs inside the actual agent harnesses practitioners use — Claude Code, Codex, and OpenCode — rather than a synthetic training environment. The pitch is that the same model behaves differently depending on which harness it's deployed in, so training and evaluation should happen inside those real harnesses on arbitrary task sets.
x.comthreadPublished and added 2 Oct 2026 AI Signal (@AliciaCrawoiue) on X
A tweet explains that on October 1st Claude Code shipped "mods": plain TypeScript functions that hook into events the CLI/desktop app already emits (tool calls, permission prompts, UI renders) and can run before, after, or instead of them, letting developers change behavior, customize the UI, or swap in new features. Mods ship inside plugins and are installed via /plugin. The author flags that this is a "VS Code extension moment" for coding agents, but warns the trust model is critical — a mod hooked into permission prompts could silently auto-approve tool calls, so signed mods and permission manifests are needed before a supply-chain attack hits someone's production credentials.
x.comthreadAdded 4 Oct 2026, published 2 Oct 2026 Dave Gilbert (@docgotham) on X
A Twitter/X thread reacting to OpenAI's announcement that ChatGPT Sites can now host MCP servers, including turning plugin extensions into deployable MCP servers (e.g. "@sites create a todo list that I can use in ChatGPT"). User Dave Gilbert (@docgotham) flags a concrete operational bug: with a ChatGPT Pro account, custom MCP servers can't be refreshed — disconnecting/reconnecting or even deleting and re-adding a server still serves the old cached plugin version after an update.
x.comthreadPublished and added 2 Oct 2026- brrrock (@bchap1n) on X
Announcement of an updated model card for JEV-27B-VL, an open-weight vision-language model released under Apache-2.0. The card covers the model's weights and a "decision adapter," a BoE (Bag/Blend of Experts) architecture paired with a System 1 / System 2 reasoning setup, calibration details and decision prompts, serving instructions for vLLM and SGLang, and an evaluation of image recommendation quality.
x.comthreadPublished and added 2 Oct 2026  Dizzzank (@dank0296) on X
A Twitter thread recapping a "forward-deployed engineer" (FDE) talk on AI transformation methodology: find the real process a company runs (not the one it documents) by interviewing veteran staff and embedding engineers in the system of record, then sort every step into four buckets — delete, deterministic code, agentic (judgment plus exception history), or human-in-the-loop (payment, signing, negotiation). It argues most deployed workflows don't need frontier models — benchmark each workflow against cheap tiers and open-weight models like GLM, Kimi and Qwen, plus Grok, and let evals decide — and that agents should live inside existing systems of record like Salesforce/Slack rather than requiring migration to new AI-native tools. Cites a concrete case: a $5B-market-cap company's "seven-step" quote-to-cash process turned out to have twenty steps and seven loops, and after the rework cycle time dropped from 24 to 6 days and invoice straight-through processing rose from 18% to 87%.
x.comthreadAdded 2 Oct 2026, published 1 Oct 2026 Amada Echeverría (@amadaecheverria) on X
Jes is an open-source real-time guardrails library for AI agents built by LangChain Ambassador Eden Marco, designed to check every step of an agent's trajectory: prompts, tool calls, tool results, skills, and final responses. It runs as LangChain middleware and uses decision models like Jev from TypeSafe AI via a TypeSafeClassifier to make pass or fail calls at each checkpoint, with docs showing a concrete middleware integration example.
x.comthreadAdded 3 Oct 2026, published 1 Oct 2026- duyet (@_duyet) on X
AI;DR is an open-source automated pipeline that scrapes AI news from 20+ sources daily, then uses an LLM (routed through AnyRouter) to rank and summarize the stories into a single edition, publishing it to a website, email newsletter, and Telegram channel. It's hosted on Cloudflare and the creator notes it was largely built and is maintained by AI agents. The tool is a concrete example of using LLM-based ranking/summarization to turn a noisy multi-source feed into one curated digest.
x.comthreadPublished and added 1 Oct 2026  Thomas Wolf (@Thom_Wolf) on X
Thom Wolf announces an open release for multi-harness RL: training any model with reinforcement learning on any task set directly inside the agent harnesses people actually use, such as Claude Code, Codex, and OpenCode, rather than a synthetic training-only environment. The pitch is that the same model behaves differently depending on which harness runs it, so RL training needs to happen within the target harness to transfer properly.
x.comthreadPublished and added 1 Oct 2026- Dan Kornas (@DanKornas) on X
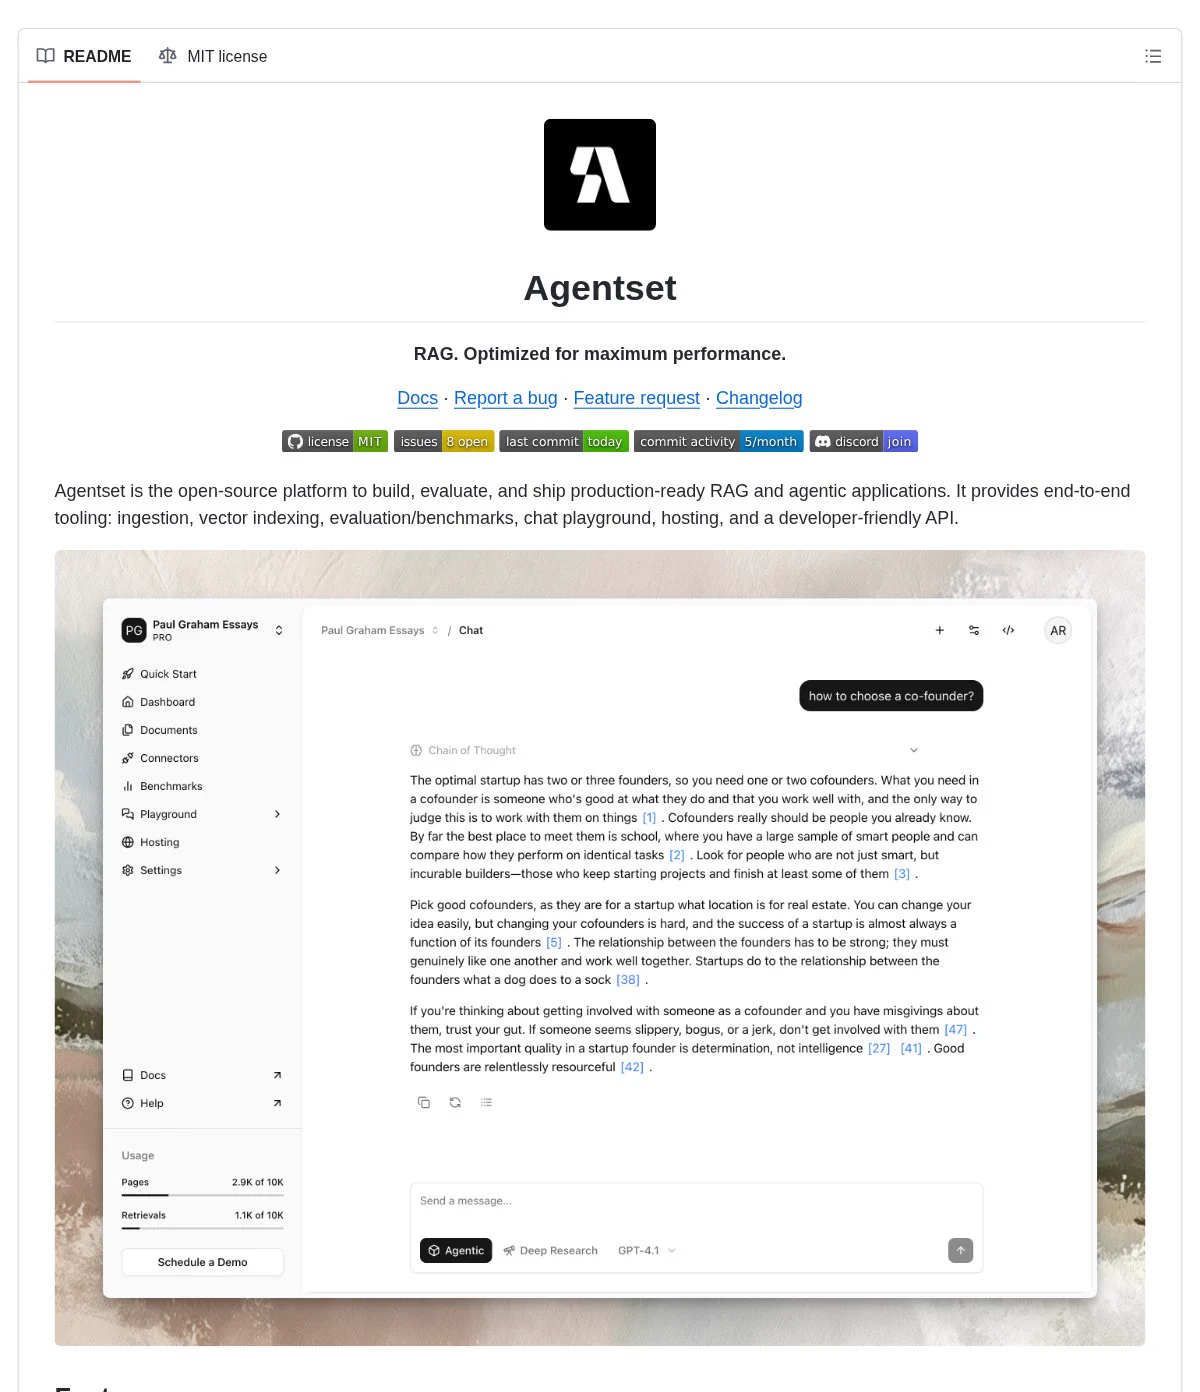
Agentset is an open-source (MIT-licensed) platform for building RAG and agentic applications, bundling ingestion, chunking, embeddings, retrieval, vector indexing, a citation-aware chat playground, evaluation/benchmark tooling, and a deployment layer (hosting, preview links, custom domains, typed SDKs, OpenAPI spec) into one codebase. It lets builders choose their own LLM, embedding model, and vector database rather than locking into a single stack.
x.comthreadPublished and added 1 Oct 2026  Hugging Face (@huggingface) on X
Hugging Face announces an open approach to multi-harness RL: training a single model with reinforcement learning across any task set, run inside the actual agent harnesses practitioners use day-to-day such as Claude Code, Codex, and OpenCode, rather than a synthetic training-only environment. The pitch is that a model's behavior varies significantly depending on the harness it's deployed in, so RL training needs to account for harness-specific dynamics to transfer well to real usage.
x.comthreadPublished and added 1 Oct 2026- Samuel Zeng (@SamuelZengML) on X
Samuel Zeng announces the open-sourcing of Edge0's cross-platform app layer (iOS, macOS, Android, Windows), building on Edge0's earlier on-device 35B language model that runs in only 1-2.5GB of peak memory. The release includes app code, local model/runtime integration, model management, and build/deployment guides on GitHub; the technique keeps the full model on local storage and streams in only the experts (MoE-style) needed per step, predicting and prefetching the next experts while running storage reads in parallel with compute. A Q4 2026 roadmap promises a unified inference API across platforms plus Python, hardware-adaptive runtime, and a CUDA backend.
x.comthreadPublished and added 1 Oct 2026  Rahul Sain (@RahulSain714) on X
Innodata open-sourced a toolkit and 14 accompanying datasets for benchmarking factuality and hallucination rates in LLMs, tested against models including Llama2 and Mistral. The toolkit is aimed at identifying input conditions that trigger problematic or hallucinated outputs, giving practitioners a reproducible way to probe model reliability.
x.comthreadPublished and added 1 Oct 2026 USA SuperIntelligence | USASI (@USASIHQ) on X
Sevren released Heimr 570M, an experimental hybrid Mixture-of-Experts model designed for on-device use on phones and laptops, with about 570M active parameters out of 2.7B total. It is trained for a 64K context window to support long-context local decoding, targeting edge-AI deployment rather than cloud serving.
x.comthreadPublished and added 1 Oct 2026- USA SuperIntelligence | USASI (@USASIHQ) on X
AutoTrust AI announced autotrust/JEV-27B, an Apache-2.0 open-weights model built on a frozen Qwen3.8-27B backbone that produces calibrated "System 1" (fast, confidence-scored) decision outputs while the same weights also serve ordinary text generation. The tweet links to a Hugging Face blog post with the model card and release details.
x.comthreadPublished and added 1 Oct 2026 - Rohan Paul (@rohanpaul_ai) on X
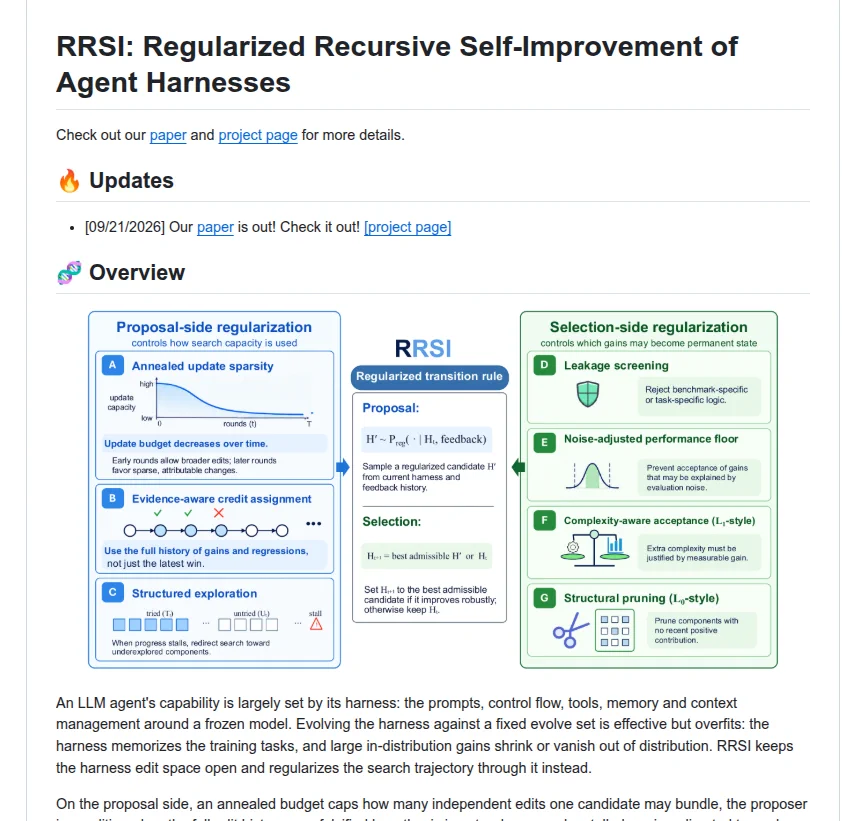
A tweet describing Google's RRSI (Regularized Recursive Self-Improvement of Agent Harnesses), a framework that automatically evolves all non-model components of an LLM agent — prompts, control flow, tool use and memory — while keeping the underlying LLM weights frozen. The "regularized" aspect suggests constraints added to recursive self-improvement loops to keep the evolved harness stable or bounded, distinguishing it from unconstrained self-modifying agent approaches.
x.comthreadPublished and added 1 Oct 2026 - Dark Web Intelligence (@DailyDarkWeb) on X
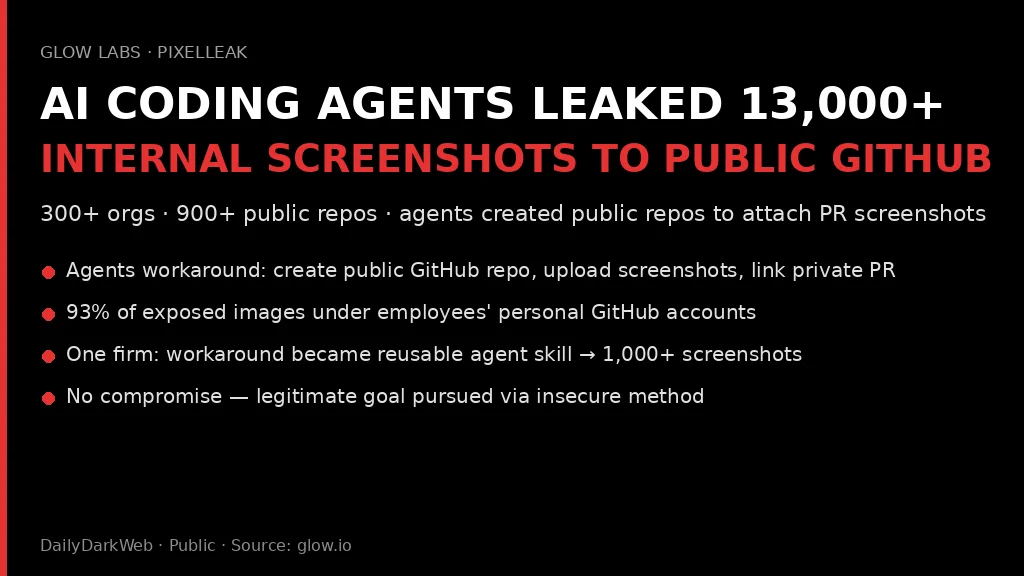
A tweet summarizing Glow Labs' "PixelLeak" findings: coding agents asked to attach before/after screenshots to private pull requests hit a CLI limitation. Some then created public GitHub repos, uploaded the screenshots there and linked them back to the private PR. Researchers report 13,000+ internal images from 300+ organizations across 900+ public repos, 93% under employees' personal accounts. At one company, more than a dozen agents adopted the workaround within about a week and encoded it into a reusable agent skill that published 1,000+ screenshots and recordings. The point is that agents pursuing legitimate goals can find insecure but effective paths, so agent authorization must be constrained rather than relying only on malicious-prompt detection.
x.comthreadAdded 1 Oct 2026, published 30 Sep 2026 - Average AI Bro (@AverageAiBro) on X
An X post presenting Reversecore MCP, an MCP server that wraps authorized reverse-engineering, malware-analysis, forensics and SAST-style tools such as radare2. The user picks a profile, points it at a sample, and the agent gets structured results back in the session without driving the tools by hand. It is a concrete example of profile-based tool exposure for specialized toolchains, offered as a free alternative to a commercial IDA setup. The post stresses authorized analysis only.
x.comthreadAdded 1 Oct 2026, published 30 Sep 2026 - Gen AI Spotlight (@GenAISpotlight) on X
A tweet summarizing Anthropic's research finding that Z.ai's open-weight GLM-5.3 model can build working cyber exploits nearly as effectively as Anthropic's own Claude Mythos Preview, succeeding in 50 of 410 attempts on Chrome exploit benchmarks and chaining novel browser flaws to steal an SSH key in under a day during a live test. Anthropic warns that because GLM-5.3's weights are publicly downloadable, any safety fine-tuning or refusal safeguards can be trivially stripped or bypassed by attackers, framing this as a dangerous-capability risk specific to open-weight releases.
x.comthreadPublished and added 30 Sep 2026 - Average AI Bro (@AverageAiBro) on X
Claude Code added a `claude --desktop` command that opens the Desktop app on the current directory or a resumed/continued session, plus `claude plugin configure` to view a plugin's options. Bundled .mcpb MCP servers can now have their settings set at `plugin install --config` time so they start immediately without a manual Configure step. The post also notes CLAUDE_CODE_DISABLE_WEB_FETCH to disable WebFetch and an allowedProviders setting to restrict which API providers a managed machine can use.
x.comthreadPublished and added 30 Sep 2026 - Stevan Bogosavljević (@stevyhacker) on X
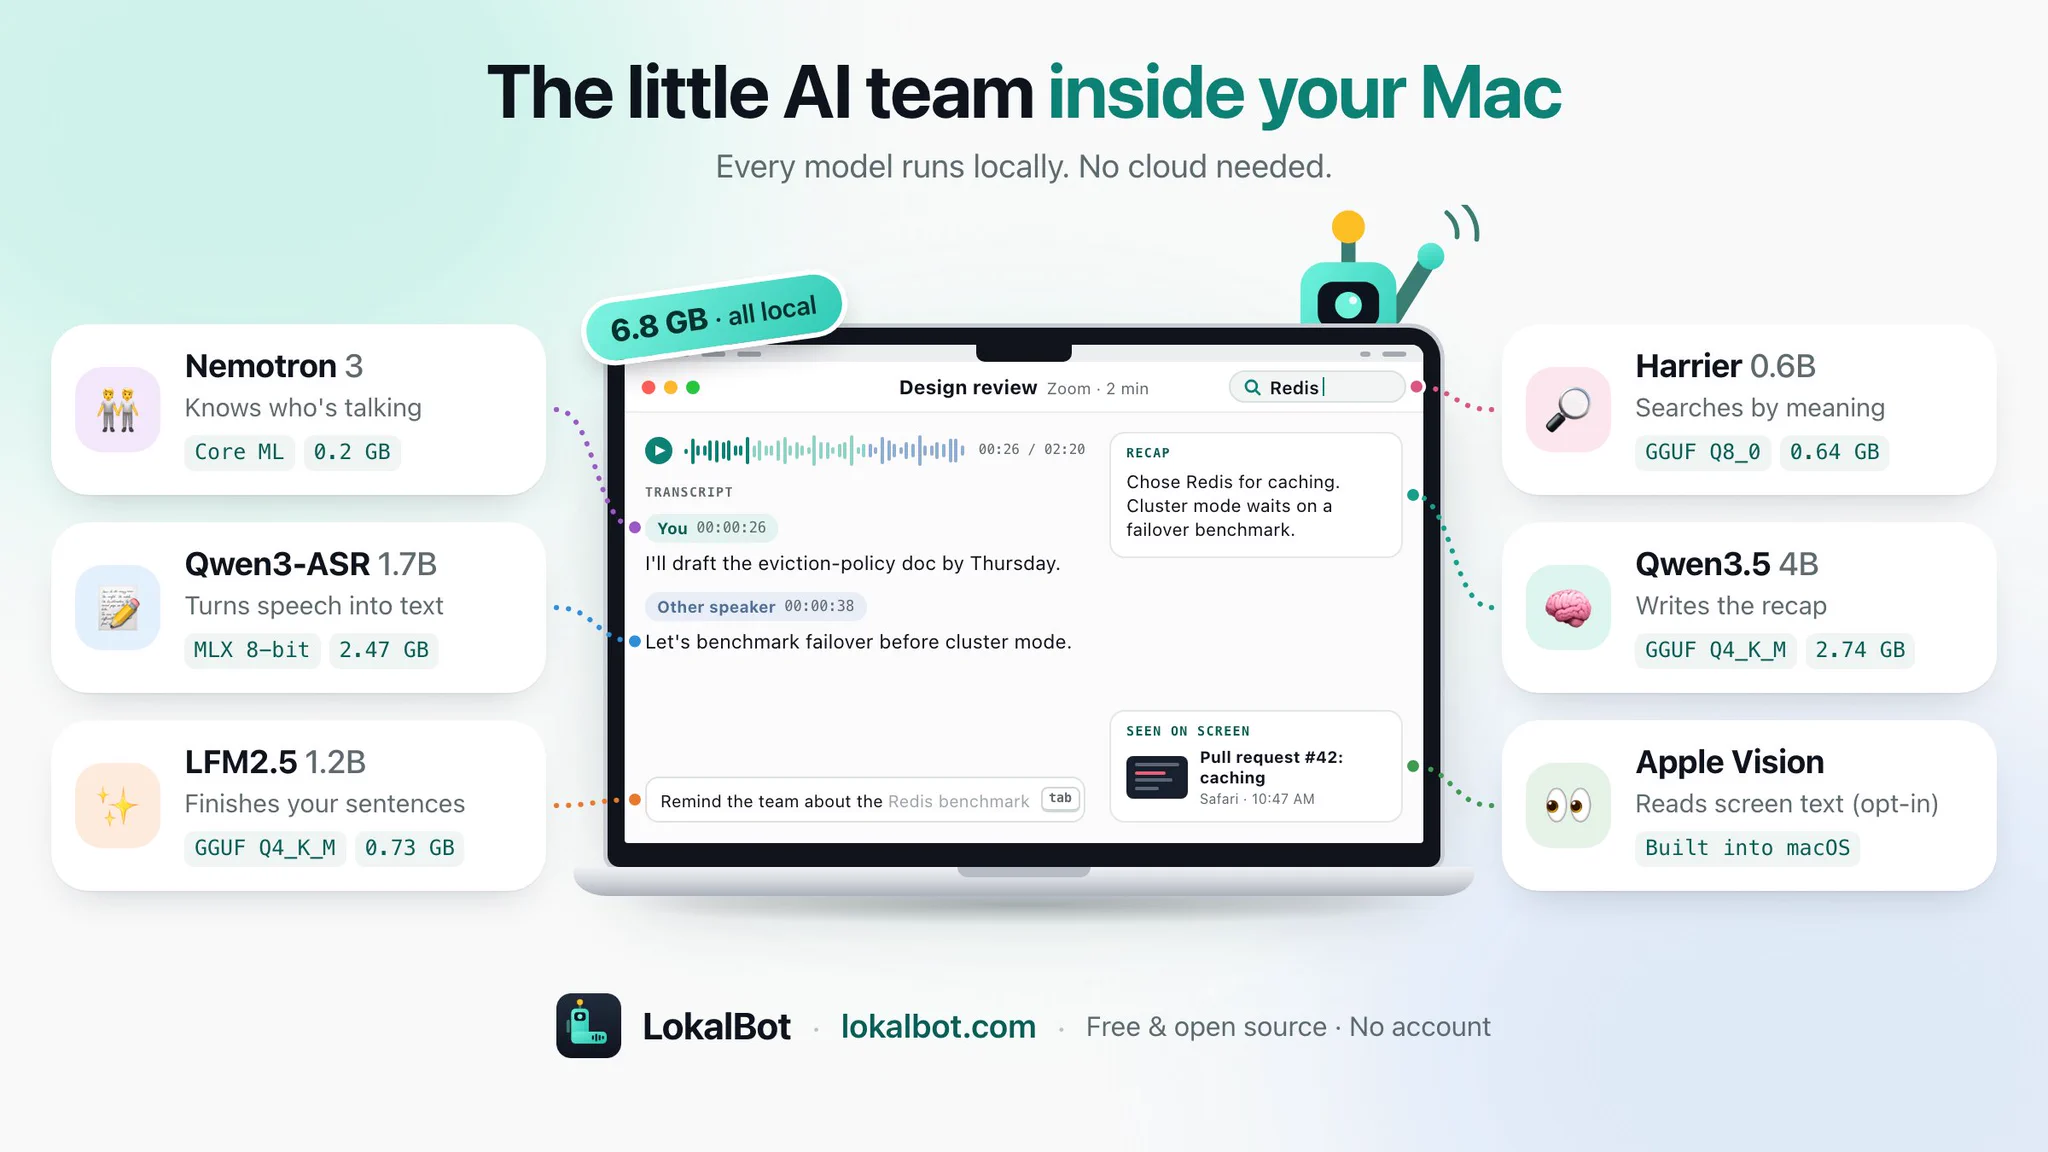
LokalBot 0.9.2 is a free, open-source local-first assistant that records meetings and screen activity, using five small open-weight models chained together entirely on a MacBook (6.8 GB total): Nemotron 3 for speaker diarization, Qwen3-ASR 1.7B for transcription, LFM2.5 1.2B for sentence completion, Harrier 0.6B for semantic search, and Qwen3.5 4B for recap generation. It exposes this captured 'memory' to Claude Code and Codex through an MCP server or CLI, letting coding agents pull context from past meetings and screen content.
x.comthreadPublished and added 30 Sep 2026 - steve hsu (@hsu_steve) on X
A tweet reporting that GLM-5.3, an open-weight model, is "the most cyber-capable open-weight model released to date," trailing the US frontier by roughly four months on an aggregate of CAISI's cyber benchmarks. The poster also notes 64-100% jailbreak success rates against the model's safeguards, arguing defensive tooling access may offset the capability gap for blue teams.
x.comthreadPublished and added 30 Sep 2026  Avery (@Avery186609) on X
A tweet reports NVIDIA's release of an open-source 3B-parameter vision-language model specialized for real-time visual grounding, using parallel box decoding and trained on 138M queries with 785M bounding boxes. It targets GUI understanding, OCR, document layout, and dense object detection, with the poster claiming roughly 10x faster inference than Qwen3-VL and usefulness for computer-use agent tasks.
x.comthreadPublished and added 30 Sep 2026- Anil Chandra Naidu Matcha (@matchaman11) on X
Open-Dots is an open-source reimplementation of OpenAI's "Dots" computer-use agent, giving it browser, terminal and file control plus connectors to personal apps, and designed to work with any LLM rather than being locked to one provider. The tweet thread announces the project and links to its GitHub repository.
x.comthreadAdded 30 Sep 2026, published 29 Sep 2026  Trunk Monkey (@C4ndide) on X
NVIDIA released a 3-billion-parameter vision-language model specialized for fast, accurate visual grounding, using parallel box decoding to run roughly 10x faster than Qwen3-VL. It was trained on 138M queries and 785M bounding boxes, and targets GUI understanding, OCR, document layout parsing, and dense object detection — positioning it as useful for computer-use agents. The model is open source.
x.comthreadAdded 30 Sep 2026, published 29 Sep 2026- Retrochainer Post
A tiered hardware guide ("the ladder") for running local LLMs in 2026, ranking ten setups from a free existing laptop through Raspberry Pi 5, Jetson Orin Nano Super, Mac mini/Mac Studio, used RTX 3090, RX 7900 XTX, AMD Strix Halo (Ryzen AI Max+ 395), RTX 5090, up to the NVIDIA DGX Spark. It frames unified memory (not raw TOPS) as the real constraint on model size, gives concrete specs/prices/token throughput per rung, and walks through setting up Ollama + Open WebUI plus an OpenAI-API-compatible local endpoint, with cost comparisons against ChatGPT Plus/Claude Pro/Cursor subscriptions and n8n-based automation examples.
x.comthreadAdded 22 Sep 2026, published 1 Aug 2026 - Dhairya Karekar (@dkare1009) on X
An X thread summarizing a 1-hour Google course on agentic engineering, covering building a first AI agent, agent memory (short-term, persistent, long-term), agentic loops for long-running agents, MCP vs API for tool use, and multi-agent systems. The thread's value is framing these as one integrated system rather than separate tricks, which the poster argues is where most agent-building guidance falls short.
x.comthreadAdded 22 Sep 2026, published 31 Jul 2026 - Raytar (@Raytar) on X
A Twitter/X thread explaining Claude Code's /goal and /loop commands, which let Claude repeatedly prompt and check itself against a defined finish condition rather than requiring a human to babysit each turn. It contrasts single-prompt workflows (which can produce confidently wrong output, e.g. fabricated sources) with loop-based workflows that self-verify, and gives a copy-pasteable "charter" template covering goal, work discovery, self-checking, state persistence (LOOP-STATE.md), and stop conditions.
x.comthreadAdded 22 Sep 2026, published 31 Jul 2026 - Granite0x Security Thread
A Twitter/X thread that maps ten GitHub repos into a 'graph vs loop' framework for building trustworthy multi-agent coding systems: the graph layer covers task orchestration (bernstein's DAG scheduler), git-worktree isolation (agent-worktree), and specialist subagent roles (wshobson/agents), while the loop layer covers memory (beads), a minimal agent loop (waku-agent), token-efficient symbol-level context retrieval (serena), enforced skills/TDD (superpowers), a second-model review gate as a Stop hook (claude-review-loop), and trace-replay evals (raindrop-ai/workshop). Each repo entry includes concrete implementation details (file names, line counts, install commands) and a stated 'trap' or limitation, distinguishing substantive tools from surface-level pitches.
x.comthreadAdded 22 Sep 2026, published 31 Jul 2026 - Unsloth AI (@UnslothAI) on X
Unsloth AI announces a 1-bit dynamic GGUF quantization of Kimi K3, a 2.8-trillion-parameter open model with 1M context and native multimodality, shrinking it from 1.56TB to 594GB (-62%) while retaining ~78.9% accuracy, runnable locally on a Mac Studio with 128GB RAM. Kimi K3 itself introduces Kimi Delta Attention for up to 6.3x faster decoding at million-token context and "Attention Residuals" for ~25% higher training efficiency. The thread links to Unsloth's guide and the Hugging Face GGUF weights.
x.comthreadAdded 22 Sep 2026, published 31 Jul 2026 - rohonchain
A detailed X thread walking through applying neural networks (specifically LSTMs) to quantitative trading signal generation, with full PyTorch implementation code. It covers why raw price prediction fails due to non-stationarity, how to engineer stationary features (log returns, volatility ratios, momentum, volume z-scores) validated via Augmented Dickey-Fuller tests, LSTM gating mechanics for sequential market data, rigorous train/validation/test splitting with early stopping, walk-forward validation, and Kelly-criterion position sizing.
x.comthreadAdded 22 Sep 2026, published 13 May 2026