Skip to content

463 results for “Injection”

What you seeeverything
x.comthread🛡️ Security

Tanmay (@TanmayK_03) on X

DBHub, a database MCP server, had a read-only mode bypass in its SQL check. The check treated every `--` as a comment, but MySQL only starts a comment when whitespace follows it. A hidden write statement could therefore still run, and a prompt injection could trigger it. Fixed in version 0.22.6. Replies say enforcement belongs in database grants and that parser tests need to be dialect-specific.

DBHubMySQLModel Context Protocol
prompt injection

AppSec, AI Security· Added 31 Oct 2026, published 30 Oct 2026

portswigger.netcourse🛡️ Security

Web Security Academy

Web Security Academy is PortSwigger's free online web security training. It is known to combine learning material with hands-on labs across web vulnerability classes such as SQL injection, XSS, SSRF, authentication flaws and request smuggling, and to be built around Burp Suite. The page had no extractable text, so this description comes from the URL and general knowledge of the site.

Burp Suite
PortSwigger

Learning, AppSec· Added 30 Oct 2026

oversecured.comarticle🛡️ Security

Content Providers and the potential weak spots they can have | Oversecured Blog

Oversecured's Android security checklist for Content Providers covers insecure FileProvider path configs, path traversal via decoded Uri.getLastPathSegment(), mismatched readPermission/writePermission, proxying requests to more privileged providers, SQL injection across a shared database, and sensitive actions in providers. Each case has vulnerable manifest and Java code, an attacker PoC and remediation. Real cases from Google and Samsung devices are cited. The page text was truncated near the end.

AndroidSQLiteJava
Oversecuredpath traversalSQL injection+5

Mobile Security, AppSec· Added 29 Oct 2026

oversecured.comwriteup🛡️ Security

20 security issues found in Xiaomi devices

Oversecured's write-up of 20 vulnerabilities in Xiaomi apps and system components, reported to Xiaomi between 25 and 30 April 2023. Bugs include intent redirection with system privileges in Security and GetApps, shell command injection in System Tracing, and arbitrary file theft via path traversal in Settings and MIUI Bluetooth. Each has a PoC. The page was truncated, so the later MIUI Bluetooth entries and the rest are not covered.

AndroidGson
OversecuredXiaomiMIUI+9

Mobile Security, AppSec· Added 29 Oct 2026

oversecured.comwriteup🛡️ Security

Disclosure of 7 Android and Google Pixel vulnerabilities

Oversecured discloses seven Android vulnerabilities, two of them Pixel-specific, all reported to Google and fixed except one low-severity WebView case. They are the Camera geolocation leak (CVE-2024-0017), a VPN bypass list change (CVE-2023-21383), a Bluetooth permission check flaw (CVE-2024-34719), the WorkSource parcel mismatch (CVE-2023-20963, exploited in the wild by the Pinduoduo app), Device Admin HTML injection (CVE-2021-0600) and a ContentProvider.openFile() caller-context bypass (CVE-2023-21292). Each has root cause and PoC code.

AndroidGoogle PixelWebView+2
CVE-2024-0017CVE-2023-21383CVE-2024-34719+9

Mobile Security, Offensive Security· Added 29 Oct 2026

arxiv.orgpaper🛡️ Security

Understanding and Mitigating Role Spoofing in LLMs

Understanding and Mitigating Role Spoofing in LLMs is an arXiv paper (October 2026) on role spoofing, a prompt injection where malicious tool output impersonates the user. It shows models track "who said what" using both content cues (semantics, style) and structure cues (control tokens, formatting). Attacks combining fake structure and content succeed often, adversarial training stops only content-based attacks, and linear probes trained to predict conversation roles detect spoofing across settings.

LLM
role spoofingrole confusionprompt injection+1

AI Security· Added 31 Oct 2026, published 29 Oct 2026

securityweek.comarticle🛡️ Security

Google Touts Powerful Cybersecurity Capabilities in Gemini 4 Carbon Model

Gemini 4 Carbon is a Google frontier model announced with restricted access for cyber defenders through the Fairwind Program (650+ organizations). Google reports 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench, ahead of GPT-6 Astra and Claude models, with no guardrails. It also cites prompt injection and cheating-resistance results, and pricing of $2/$10 per million tokens.

GeminiGPT-6 AstraWiz+1
Gemini 4 CarbonGemini 4 ArgonFairwind Program+6

AI Security· Published and added 29 Oct 2026

arxiv.orgpaper🛡️ Security

SEAL: Sealed Queries for Local Sanitization against Indirect Prompt Injection

SEAL is a defense against indirect prompt injection for local LLM agents. It learns a soft prompt and scoring readout offline, then uses a frozen task model to score and delete injected tokens from tool outputs, with queries built from trusted initial context. On AgentDojo, attack success falls from 34.6% to 0.1% and Joint rises from 51.4% to 77.5%, using about 127x fewer defense tokens than PISanitizer.

LLMAgentDojoAgentDyn+1
indirect prompt injection

AI Security· Added 31 Oct 2026, published 29 Oct 2026

arxiv.orgpaper🛡️ Security

Appreciation Teaches Unauthorized Execution: Self-Evolution Degrades the Robustness of Personal Agents to Indirect Prompt Injection

Paper studying whether self-evolution weakens personal agents' robustness to indirect prompt injection (IPI). A two-phase method has the user ask the agent to follow tasks in external content, then tests with a third-party injected task the user did not authorize. Against the non-evolving base agent, attack success rose 14.0 to 48.8 points under skill evolution and 3.0 to 39.3 points under reinforcement learning. Code is released.

indirect prompt injection

AI Security· Added 31 Oct 2026, published 29 Oct 2026

deploymentsafety.openai.compaper🛡️ Security

Addendum to GPT-6 Luna System Card: October 28, 2026 Update

Addendum to the GPT-6 Luna system card for the model update of 29 October 2026 (the title says October 28). OpenAI keeps the High rating for cybersecurity and biological/chemical capability under its Preparedness Framework. It reports ExploitBench 46.19% and SEC-Bench Pro 51.75% (GPT-6 Astra: 85.4%), higher multiturn jailbreak defender success than the October 7 version, and GPT-Red prompt-injection results. It also reports weaker factuality and dual-use biology refusal.

GPT-6 LunaGPT-6 AstraOpenAI+1
Preparedness FrameworkGPT-RedExploitBench+4

AI Security· Published and added 29 Oct 2026

x.comthread🛡️ Security

Rohan Paul (@rohanpaul_ai) on X

Rohan Paul's X post summarizes the paper "Log-To-Leak: Prompt Injection Attacks on Tool-Using LLM Agents via the Model Context Protocol", from TikTok researchers. It reports that MCP-using agents often finish the requested task, then quietly call an attacker-controlled logging tool that records the query, server reply and final answer. The attack works through natural-language tool descriptions that agents read when choosing and ordering tools. The visible text is truncated.

Model Context ProtocolLLM
Log-To-Leakprompt injectionTikTok+1

AI Security· Added 29 Oct 2026, published 28 Oct 2026

blog.talosintelligence.comwriteup🛡️ Security

Inside KeyDrift: Analyzing historical UAT-11473 activity on Cisco SD-WAN

KeyDrift is a custom malware framework used by UAT-11473, which exploited CVE-2026-20127 in Cisco SD-WAN Catalyst Controller to gain access. Talos analyzes PolyFlame (memory-resident vdaemon injection, recvfrom hook, TinyShell-style backdoor, intermediate C2) and LittleFilch (SSL_read hook that extracts and RSA-encrypts keying material). It reports infrastructure overlap with Volt Typhoon's Silent Train, plus patch guidance and Snort SIDs.

Cisco SD-WANLinuxrunit+1
CVE-2026-20127UAT-11473KeyDrift+7

Threat Intel, Malware & RE· Published and added 28 Oct 2026

orca.securityadvisory🛡️ Security

CVE-2026-101767: Critical Oracle EBS SQL Injection Actively Probed in the Wild

CVE-2026-101767 is a CVSS 9.8 unauthenticated SQL injection in Oracle E-Business Suite's Application Object Library, reachable through the /OA_HTML/AppsTCFServer servlet (GanttDataServer) and chainable to OS command execution. It affects versions 12.2.3 to 12.2.15 and was fixed in the October 2026 Critical Patch Update. Horizon3.ai found it, and Defused saw probing on honeypots on 27 October 2026. Interim mitigation is removing the servlet from the URL firewall allowlist.

Oracle E-Business Suite
CVE-2026-101767Horizon3.aiDefused+5

AppSec, Threat Intel· Published and added 28 Oct 2026

cisa.govadvisory🛡️ Security

Hitachi Energy CoreTec Product

CISA advisory ICSA-26-302-03, republished from Hitachi Energy PSIRT 8DBD000258, covers OS command injection (CVE-2026-13162) and the Dirty Frag vulnerability (CVE-2026-43284) in Hitachi Energy CoreTec. CoreTec5 up to 3.4.0 and 5.0.0 are affected by both, and CoreTec4 up to 3.4.0 by CVE-2026-13162. The advisory was released 27 October 2026 and lists generic ICS mitigations. SSVC rates exploitation as none.

Hitachi Energy CoreTec
CVE-2026-13162CVE-2026-43284Dirty Frag+5

Hardware & RF· Added 29 Oct 2026, published 28 Oct 2026

x.compaper🛡️ Security

Cryptography and Security Papers (@FSFG) on X

Log-To-Leak is an arXiv paper (cs.CR, cs.AI) by Yuepeng Hu, Chongyu Fan, Sirat Samyoun and Jian Du on prompt injection attacks against tool-using LLM agents through the Model Context Protocol. The title points to a logging-based data leakage channel. The fetched page holds only the title, authors and arXiv link, with no abstract, so the method and results are not visible here.

Model Context ProtocolLLM
Log-To-Leakprompt injection

AI Security· Added 29 Oct 2026, published 28 Oct 2026

blog.googlearticle🛡️ Security

Gemini 4 Carbon

Gemini 4 Carbon is Google's frontier model, announced with cybersecurity results: 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching). Google reports 0.0% attack success on Gray Swan's indirect prompt injection benchmark. Access starts with a subset of cyber defenders through the Fairwind Program. Pricing is $2 per million input tokens and $10 per million output tokens.

Gemini
Gemini 4 CarbonGemini 4 ArgonFairwind Program+6

AI Security· Added 29 Oct 2026, published 28 Oct 2026

deepmind.googlearticle🛡️ Security

Gemini 4 Carbon: Our next frontier model

Gemini 4 Carbon is Google DeepMind's frontier model, announced with a focus on cyber defense. DeepMind reports 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching), run without guardrails. It also reports 0.0% attack success on Gray Swan's indirect prompt injection benchmark. Access starts with a subset of cyber defenders via the Fairwind Program.

Gemini
Gemini 4 CarbonGemini 4 ArgonSEC-bench Pro+6

AI Security, AppSec· Published and added 28 Oct 2026

securityweek.comarticle🛡️ Security

Hackers Start Probing Fresh Oracle EBS Vulnerability

CVE-2026-101767 is a CVSS 9.8 unauthenticated SQL injection in the Application Object Library of Oracle E-Business Suite, patched in Oracle's October 2026 CPU and reported by Horizon3.ai. Defused decoys logged the first exploratory attempts on 27 October 2026, and the flaw could lead to remote code execution. The article recalls CVE-2026-46817 attacks in June and last year's Cl0p zero-day campaign against EBS.

Oracle E-Business SuiteCVSS
CVE-2026-101767CVE-2026-46817Cl0p+4

Threat Intel, AppSec· Published and added 28 Oct 2026

arxiv.orgpaper🛡️ Security

Post-Training Large Language Models with LLMON

LLMON (LLM Object Notation) is a framework that separates instructions from data and requires explicit identifier-based execution. The authors post-train Granite-4.1 3B and 8B base models with SFT then RL on a 4.6B-token structured corpus covering general, RAG and tool-calling data, with distractor variants. Attack success rates on indirect prompt-injection benchmarks fall from 53-100% to 0.02-5.6%, and general capability is preserved. Attention-based metrics diagnose failures per transformer layer.

LLMONGranite 4.1LLM
prompt injectionindirect prompt injection

AI Security· Added 30 Oct 2026, published 28 Oct 2026

arxiv.orgpaper🧠 AI

Post-Training Large Language Models with LLMON

LLMON (LLM Object Notation) is a framework that separates executable instructions from passive data and requires explicit identifier-based execution. The paper post-trains Granite-4.1 3B and 8B base models on a 4.6B-token corpus of general, RAG and tool-calling data with distractor variants, using SFT then RL. Attack success rates on indirect prompt-injection benchmarks fall from 53-100% to 0.02-5.6%, with general capabilities preserved. It also adds attention-based per-layer diagnostics.

LLMRAGTransformer
LLMONGranite-4.1arXiv

training, research· Added 30 Oct 2026, published 28 Oct 2026

x.comthread🛡️ Security

Buchi Reddy B (@buchireddy) on X

Buchi Reddy B's X thread comments on Forever Security's research (Gal Weizman, Omer Samet) on coding agents. A web page silently writes a fake AGENTS.md or CLAUDE.md into a Downloads folder, and Codex and Claude Code follow it as project rules. Codex then wrote an attacker's MCP server into the machine-wide config, so one injection becomes a standing connection for every session. It asks whether teams inventory runtime MCP connections against approved lists.

CodexClaude CodeModel Context Protocol
Forever SecurityGal WeizmanOmer Samet+3

AI Security· Added 28 Oct 2026, published 27 Oct 2026

arxiv.orgpaper🛡️ Security

Heads of Security: Learned Attention Gates Improve Prompt Injection Robustness

Heads of Security (HoS) is a prompt injection defense that enforces instruction-data separation with learned per-head attention gates, redistributing attention between trusted and untrusted tokens. Evaluated on Llama-3.3-70B-Instruct and GPT-OSS-20B against SecAlign++ and ASIDE. The black-box RL-Hammer attack reaches 97% ASR on GPT-OSS-20B and 85% on SecAlign but 10% on HoS. The white-box Claudini attack needs 3 times more FLOPs on HoS. HoS keeps base-model utility in few-shot settings, where SecAlign and ASIDE degrade.

LlamaGPT-OSS-20BLLM
Heads of Securityprompt injectionSecAlign+++4

AI Security· Added 28 Oct 2026, published 27 Oct 2026

arxiv.orgpaper🧠 AI

Heads of Security: Learned Attention Gates Improve Prompt Injection Robustness

Heads of Security (HoS) is a prompt injection defense that trains a small set of per-head attention gates to shift attention between trusted and untrusted tokens, separating instructions from data. Tested on Llama-3.3-70B-Instruct and GPT-OSS-20B, the black-box RL-Hammer attack reaches 10% ASR on HoS versus 97% on base GPT-OSS-20B and 85% on SecAlign. HoS keeps base utility in few-shot settings, where SecAlign and ASIDE degrade.

TransformerLlamaLLM
Heads of SecuritySecAlign++SecAlign+5

research, training· Added 28 Oct 2026, published 27 Oct 2026

x.comthread🛡️ Security

Nicholas Martin (@ndgmlondon) on X

X thread started by Nicholas Martin (#IAM) advising that MCP tool permissions be verified and scoped session tokens used to enforce least privilege against indirect prompt injection. Replies argue that token scoping does not solve the confused deputy problem, because an injection borrows the agent's legitimate authority. They recommend per-task tokens with short expiry, with the grant logged beside the call, and raise MCP server dependency supply-chain risk.

Model Context Protocol
indirect prompt injectionconfused deputy

AI Security, Identity & Access· Added 28 Oct 2026, published 27 Oct 2026

arxiv.orgpaper🛡️ Security

What Victims Take Away: Attack Reuse and Defense Revision after Prompt-Injection Attacks

What Victims Take Away is an October 2026 arXiv paper analysing 563,349 Tensor Trust attack records to see how players reuse prompt injections they received. Within a week, targets reused 10.0% of attacks that broke their defense, versus 0.03% of matched attacks. Breaches were followed by defense changes that cut same-family attack success by 24.5 points. Received texts made up 23.2% of successful hijacks. The authors propose that AI security tools describe techniques without disclosing full attack text.

Tensor TrustLLM
prompt injectionpayoff-biased social learningvictim-offender overlap

AI Security· Added 28 Oct 2026, published 27 Oct 2026

x.comthread🛡️ Security

AGTP (@AGTPinsights) on X

AGTP's X thread summarizes Meta's Muse Spark 1.3 Evaluation Report. Prompt injection was tested on Exponential Security Labs' RepoInject v1 and BrowserInject v1 and on Gray Swan's IPI Arena, with robustness said to be on par with GPT-5.6 Sol. It also covers chain of thought controllability evals, PostTrainBench under Loss of Control, and Handshake's pre-release human red teaming. It notes the Midas Project's criticism of Muse Wonder's missing safety report.

Muse SparkMuse Spark Open
prompt injectionRepoInject v1BrowserInject v1+10

AI Security· Added 27 Oct 2026, published 26 Oct 2026

x.comthread🧠 AI

AGTP (@AGTPinsights) on X

Thread summarizing Meta's Muse Spark 1.3 Evaluation Report, the safety write-up for the model released on September 2, 2026. It covers prompt-injection results on Exponential Security Labs' RepoInject v1 and BrowserInject v1 and Gray Swan's IPI Arena, chain-of-thought controllability evals, PostTrainBench under Loss of Control, and Handshake's human red teaming. It also notes The Midas Project's criticism that Muse Wonder still has no safety report, and the Muse Spark Open rollout (816B total, 42B active parameters).

Muse Spark 1.3Muse Spark OpenMixture of Experts
MetaMuseMuse Wonder+19

ai-safety, evals, models· Added 27 Oct 2026, published 26 Oct 2026

arxiv.orgpaper🛡️ Security

Log-To-Leak: Prompt Injection Attacks on Tool-Using LLM Agents via the Model Context Protocol

Log-To-Leak is a prompt-injection attack on tool-using LLM agents that abuses Model Context Protocol tool metadata to trigger an attacker-controlled logging call after the last legitimate call, leaking the user query, server name, server response and agent response. Evaluated on five MCP servers and four agents, it reaches 62.64-100% attack success with 76.55-95.64% logging accuracy. Three defenses leave over 55% residual ASR on GitHub MCP with GPT-4o.

Model Context ProtocolGitHubGPT-4o+1
Log-To-Leaktool poisoningprompt injection

AI Security· Added 28 Oct 2026, published 26 Oct 2026

arxiv.orgpaper🛡️ Security

Then there is prompt injection, a malicious email, ...: The Wild Wide West of OpenClaw Agentic System Security

An empirical study of security concerns in the OpenClaw AI personal assistant framework, using 25K+ posts from 13 subreddits (162 security-relevant) and 358 security-tagged GitHub issues (180 retained). It maps 521 CWE instances across 59 weakness types, concentrated in access control, sensitive-data exposure, injection and unsafe execution. It extracts 543 practitioner mitigations into seven strategies and reconstructs a sensitive-data exposure path with dummy secrets.

OpenClawGitHubLLM
prompt injectionCWEtrust boundaries+1

AI Security· Added 28 Oct 2026, published 26 Oct 2026

wiz.ioarticle🛡️ Security

The Pwn Request Reckoning: What Still Works Against GitHub Actions

The Pwn Request Reckoning is a Wiz post updating the GitHub Actions pull_request_target threat model for 2026. It covers what GitHub's checkout protections, read-only cache tokens and event policies block, and what still works. Remaining paths: SHA-pinned pre-backport actions/checkout, custom checkout scripts, issue_comment and repository_dispatch triggers, script injection, artifact poisoning, self-hosted runner state and allow-unsafe-pr-checkout. It ends with grep and zizmor audit steps.

GitHub ActionsGitHubzizmor+1
pwn requestscript injectionartifact poisoning+2

DevSecOps, AppSec· Published and added 26 Oct 2026

arxiv.orgpaper🛡️ Security

Scope-Gap Injection: Exploiting Evaluator Channel Blind Spots in the OpenClaw Agent Security Competition

Scope-Gap Injection (SGI) is an indirect prompt injection method for multi-stage LLM-agent safety pipelines, tested in the IJCAI 2026 OpenClaw Agent Security Attack Competition. The visible task and skill stay benign while target identifiers, bypass parameters and authorization steps sit in an attachment written as a business worklist, which the S2 LLM judge appears not to inspect. SGI bypassed all three stages (static scan, LLM judge, live audit) for 5 of 19 targets, best F = 0.385. Attachment placement had 78% S2 acceptance versus 23% in-skill. The paper closes with defenses that align evaluator scope with agent channels.

OpenClawLLM
Scope-Gap Injectionindirect prompt injectionIJCAI 2026 OpenClaw Agent Security Attack Competition

AI Security· Added 27 Oct 2026, published 26 Oct 2026

deploymentsafety.openai.compaper🛡️ Security

Addendum to GPT-6 Astra System Card: GPT-6.1 Terra

Addendum to the GPT-6 Astra system card for OpenAI's GPT-6.1 Terra, rated Critical in cybersecurity and High in biological and chemical capability under the Preparedness Framework. It reports multiturn jailbreak and prompt-injection results, alignment tests (auto-review circumvention, ExploitGym honeypot, monitor evasion), and cyber scores: 97.10% ExploitBench, 24.5% on the internal recent-vulnerability port, 5 of 22 Sandbox Bench targets.

GPT-6.1 TerraGPT-6 AstraOpenAI+1
Preparedness FrameworkExploitGymExploitBench+11

AI Security· Published and added 26 Oct 2026

arxiv.orgpaper🧠 AI

SentryBench: A Cost-Sensitive Benchmark for Adversarial Robustness of Tool-Using LLM Agents in Public-Safety Deployments

SentryBench is a benchmark for tool-using LLM agents in public-safety deployments. It scores attack success, over-refusal (missing a real emergency) and over-reaction (unwarranted action) on a cost-sensitive frontier, using real emergency-call transcripts, disaster messages and injection payloads. Across 840 episodes on three frontier models and three defenses, refuse-more caution pushed over-refusal to 100 percent on two models, while a trust-gating wrapper gave the lowest harm.

LLM
SentryBencharXiv

evals, ai-safety, agents· Added 27 Oct 2026, published 25 Oct 2026

arxiv.orgpaper🛡️ Security

SentryBench: A Cost-Sensitive Benchmark for Adversarial Robustness of Tool-Using LLM Agents in Public-Safety Deployments

SentryBench is a benchmark for tool-using LLM agents in public-safety settings (public alerts, responder dispatch, citizen-record queries). It scores attack success, over-refusal and over-reaction on a cost-sensitive frontier, using real emergency-call transcripts and real injection/jailbreak payloads. Across 840 episodes on three frontier models and three defenses, refuse-more caution raised over-refusal to 100 percent on two models, while a trust-gating wrapper gave the lowest harm on every model.

LLM
SentryBenchover-refusalover-reaction+1

AI Security· Added 27 Oct 2026, published 25 Oct 2026

github.comrepo🛡️ Security

alirezarezvani/claude-skills

claude-skills is an open-source MIT library of about 398 Claude Code skills, agents and plugins that also installs into Codex, Gemini CLI, Cursor and 9 other coding agents. The security-relevant parts are skill-security-auditor, a stdlib-only Python scanner that checks skills for command injection, data exfiltration, prompt injection and dependency supply-chain risks before install, plus a security-guidance PreToolUse hook, a security suite and compliance skills (ISO 27001, SOC 2, GDPR).

Claude CodeCodexGemini CLI+3
skill-security-auditorPreToolUse hookagentskills.io+3

AI Security, Supply Chain· Added 25 Oct 2026

x.comarticle🛡️ Security

lee1981 (@lee1981b) on X

CyberForge Weekly CVE Rundown #007 covers six CVEs from 19 to 24 October 2026: SiteGuard command injection (CVE-2026-106931), DB-GPT (CVE-2026-77932), Siemens Software Center DLL side-loading (CVE-2026-110936), Cisco Expressway (CVE-2026-76466), Node.js Brotli (CVE-2026-111497) and Arista VeloCloud (CVE-2026-114625). Each entry gives defender actions, fixed versions, exploitation status and primary-source links. Updated 25 October 2026 with CISA KEV and EPSS findings.

SiteGuardDB-GPTSiemens Software Center+4
CVE-2026-106931CVE-2026-77932CVE-2026-110936+10

Blue Team & Detection, AppSec, Threat Intel· Added 27 Oct 2026, published 25 Oct 2026

arxiv.orgpaper🛡️ Security

Deletion, Substitution, Repair and Transplant: Component Attribution in BARBICAN, a Layered Prompt-Injection Gateway for MCP

BARBICAN is a fail-closed prompt-injection gateway for MCP tool mediation. This paper shows its arbitration classifier ran on tokenizer-mangled text for a whole evaluation. Fixing it raised AUC from 0.392 to 0.855 while system recall fell from 80.67% to 80.34%. The routed band is 96.82% malicious, so deletion ablations mislead without substitution experiments and class-balance reporting.

Model Context ProtocolLLM
BARBICANprompt injection

AI Security· Added 27 Oct 2026, published 23 Oct 2026

arxiv.orgpaper🧠 AI

Deletion, Substitution, Repair and Transplant: Component Attribution in BARBICAN, a Layered Prompt-Injection Gateway for MCP

The paper analyses BARBICAN, a fail-closed prompt-injection gateway for MCP tool mediation, using deletion, substitution, repair and transplant experiments. Its arbitration classifier ran on tokenizer-mangled text for a whole evaluation. Fixing that raised AUC from 0.392 to 0.855 while system recall fell from 80.67% to 80.34%. The band it receives is 96.82% malicious. The authors argue ablation figures need the band's class balance and substitution baselines.

Model Context Protocol
BARBICAN

evals, research, mcp· Added 27 Oct 2026, published 23 Oct 2026

arxiv.orgpaper🧠 AI

Tool-Calling LLM Agents Under Realistic MCP Faults: Scale Does Not Purchase Fault Tolerance

MCP-Injector is a protocol-aware fault-injection middleware for Model Context Protocol tool calls, with permanent, transient and intermittent faults on seedable schedules. Its fault model comes from 57,240 issue and PR threads across 1,774 open-source MCP repositories. In a 1,350-cell experiment, faults cut task-completion score by 60% (8.08 to 3.23 of 10), and the 120B gpt-oss model was no more resilient than the 20B. Agent stacks differed in how well they absorbed faults.

Model Context ProtocolOpenAI Agents SDKLangChain+2
MCP-Injectorgpt-oss-120bOpenAI

mcp, evals, agents, research· Added 26 Oct 2026, published 23 Oct 2026

arxiv.orgpaper🛡️ Security

On Task, Off Track: Benchmarking LLM and Agent Robustness to Near-Target Prompt Injection

NTBench (Near-Target Benchmark) tests LLM and agent robustness to near-target prompt injection, where injected instructions steer a response toward a plausible but incorrect or harmful outcome instead of abandoning the task. It builds reference-guided target-instruction pairs on existing datasets, with human validation, and evaluates seven LLMs on ten language datasets and two agent benchmarks. Attack success rose 9.3 to 35.8 points (incorrect targets) and 1.7 to 17.3 points (harmful targets) over fixed-target baselines.

LLM
NTBenchnear-target prompt injectionprompt injection

AI Security· Added 26 Oct 2026, published 23 Oct 2026

securityweek.comarticle🛡️ Security

Attackers Exploit Third VeloCloud Orchestrator Zero-Day in Four Months

CVE-2026-114625 is a critical (CVSS 9.9) SQL injection in Arista's on-prem VeloCloud Orchestrator, exploited in the wild. Any authenticated user can gain superuser operator privileges. Releases before 5.2.3.18, 6.1.3.10 and 6.4.2.12 are affected, and hosted deployments are already patched. Attacks came from 74.82.197.86 and 38.54.50.151. It is the third exploited VCO zero-day in four months, after CVE-2026-16812 and CVE-2026-93952.

VeloCloud OrchestratorArista NetworksCVSS
CVE-2026-114625CVE-2026-16812CVE-2026-93952+3

AppSec, Threat Intel· Published and added 23 Oct 2026

x.comadvisory🛡️ Security

Dark Web Intelligence (@DailyDarkWeb) on X

CVE-2026-114625 is a critical (CVSS 3.1 9.9) SQL injection in on-prem Arista VeloCloud Orchestrator, the SD-WAN management portal, covered in Arista Security Advisory 0199 of 22 October 2026. Any authenticated user, even the lowest Enterprise Read Only tenant role, can become a local superuser operator, and Arista says it is exploited in the wild. On-prem fixes are 5.2.3.18, 6.1.3.10 and 6.4.2.12; two attacker IPs are listed.

Arista VeloCloud OrchestratorCVSS
CVE-2026-114625CWE-8974.82.197.86+2

Threat Intel, AppSec· Added 24 Oct 2026, published 22 Oct 2026

github.comrepo🛡️ Security

Spectrmachina/Ztrust

ZTrust is a Python supply-chain scanner that checks manifests, lockfiles, source and GitHub workflows for vulnerable or malicious dependencies (via OSV.dev), typosquats, leaked secrets, unsafe lockfiles and risky CI patterns such as pwn requests and script injection. It outputs console, JSON and SARIF 2.1.0 and ships as a GitHub Action. It also includes a FastAPI bounty service using commit-reveal and shielded Zcash payouts for researchers.

PythonGitHub ActionsOSV+3
xz-utilstj-actions/changed-filesevent-stream+3

Supply Chain, DevSecOps· Added 27 Oct 2026, published 22 Oct 2026

github.comrepo🛡️ Security

SnailSploit/Claude-Red

claude-red is a library of offensive security skills for the Claude Skills system, each a SKILL.md file that loads on conversational triggers (for example, mentioning SQL injection loads offensive-sqli). Categories include web, Active Directory, cloud, mobile, exploit development, fuzzing, privilege escalation, post-exploitation and AI. It targets about 130 skills across 23+ categories, with an install script and sparse-checkout install per category. Built on Sahar Shlichov's offensive checklists, MIT licensed.

ClaudeClaude CodeActive Directory
Kai AizenSahar ShlichovSnailSploit

Offensive Security, AI Security· Added 22 Oct 2026

x.comthread🛡️ Security

VibecodersHQ (@VibeCodrHQ) on X

Post summarising Pillar Security's finding of a remote code execution flaw in OpenCode, the open-source AI coding agent. Versions 1.0.137 through 1.18.32 could run code from a remote MCP server during OAuth sign-in on Windows and WSL, with no prompt injection needed. The fix is in 1.18.33 (released 28 September). No advisory or CVE was issued, so scanners will not flag old installs. Interim advice is to remove unvetted remote MCP servers.

OpenCodeModel Context ProtocolOAuth+1
Pillar SecurityOpenCode Console breach

AI Security, AppSec· Added 22 Oct 2026, published 21 Oct 2026

arxiv.orgpaper🛡️ Security

Prompt Injection Through Forensic Evidence: A Taxonomy and Proof of Concept of Anti-Forensic Attacks on LLM-Assisted Digital Investigations

Paper on prompt injection delivered through forensic evidence, where the seized device's contents are attacker-controlled and the examiner must read them. It extends the anti-forensic model to cover manipulation of the reasoning layer and gives a taxonomy (objective, technique, payload location, concealment). Three proof-of-concept attacks on an LLM-assisted analysis pipeline change a reported conclusion, write attacker-chosen content to the analyst workstation, and trigger outbound network traffic. Mitigations are proposed.

LLM
indirect prompt injectionprompt injectionanti-forensics+1

AI Security, Blue Team & Detection· Added 24 Oct 2026, published 21 Oct 2026

arxiv.orgpaper🛡️ Security

MPIDetector: Detecting Multi-modal Prompt Injection via LLM-based Reasoning

MPIDetector is a detection framework for multi-modal prompt injection that uses few-shot in-context learning so an LLM can reason about the semantic intent of text and image inputs, without fine-tuning. The authors built a benchmark of eight textual and seven visual attack categories plus benign sets. They report up to 90.91% accuracy on text, 99.28% on images, and up to 99.80% detection on 500 obfuscated WebInject web-agent injections, beating baselines.

GeminiQwenLLM
prompt injectionWebInjectMPIDetector

AI Security· Added 24 Oct 2026, published 21 Oct 2026

arxiv.orgpaper🛡️ Security

Where AI Vulnerability Discovery Harnesses Go Quiet: Structural False Negatives and Hidden Vulnerabilities

Paper (arXiv, 21 October 2026) on structural false negatives in LLM vulnerability discovery harnesses. Starting from Knostic's OpenAnt and raptor, then 10 more open-source harnesses, the authors map 13 points where code selection, filtering, and finding storage or merging drop vulnerabilities. One file was dropped by six harnesses before the model saw it, five without notice. It covers attacker evasion, content-steered verdicts, prompt injection, and design principles and tests.

OpenAntraptorLLM
KnosticPtacek and Newshamprompt injection+1

AI Security, AppSec· Added 24 Oct 2026, published 21 Oct 2026

horizon3.aiadvisory🛡️ Security

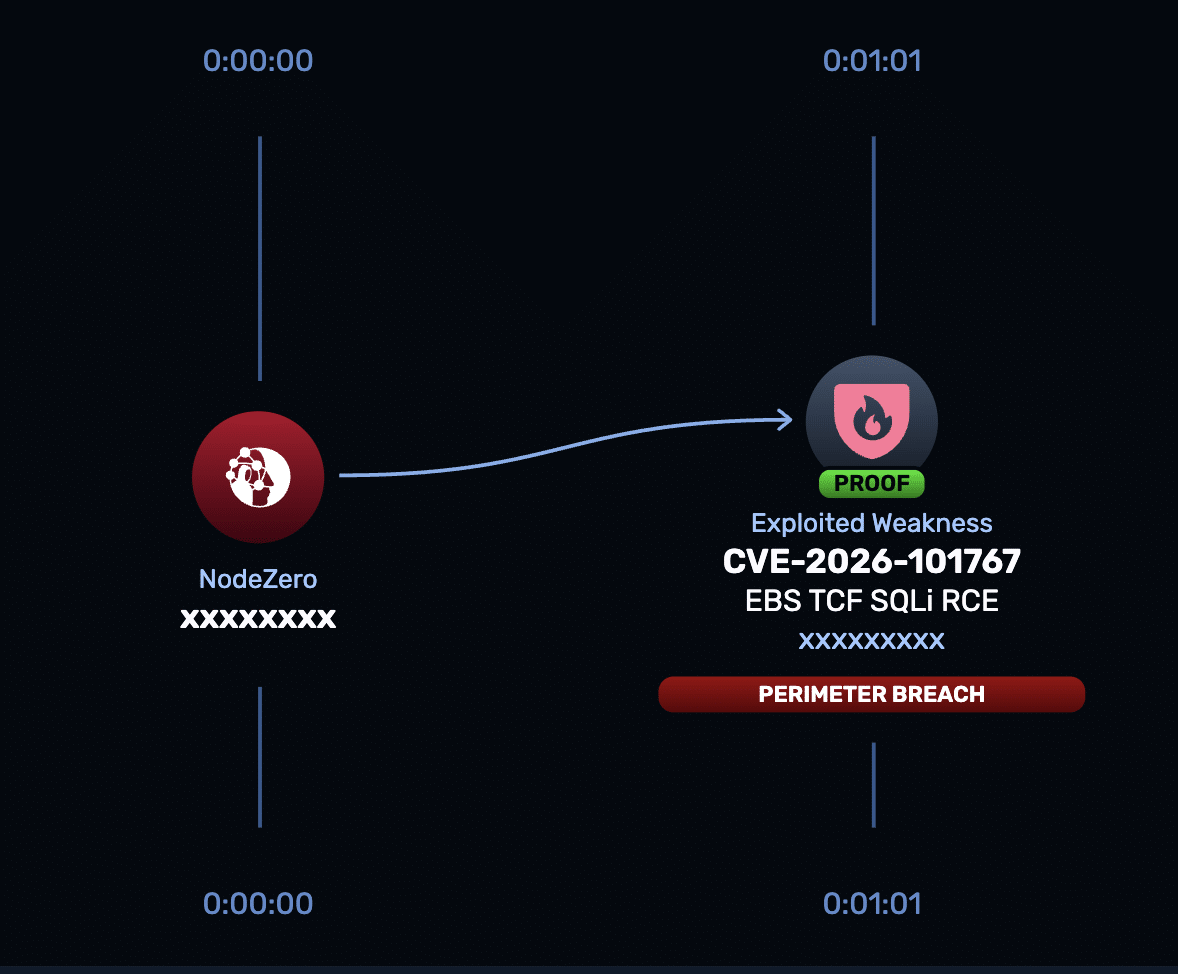
CVE-2026-101767 | Oracle E-Business Suite TCF SQL Injection and Remote Code Execution

CVE-2026-101767 is an unauthenticated SQL injection in the Oracle E-Business Suite Thin Client Framework servlet (/OA_HTML/AppsTCFServer, oracle.apps.fnd.tcf.SocketServer), CVSS 3.1 9.8. It runs SQL as the APPS user and chains to OS commands as the EBS account. Affects 12.2.3 to 12.2.15, fixed in the Oracle October 2026 CPU (20 October 2026). The page lists mitigations, IOCs and a timeline.

Oracle E-Business SuiteCVSS
CVE-2026-101767CWE-89Horizon3.ai+3

AppSec, Offensive Security, Blue Team & Detection· Added 29 Oct 2026, published 20 Oct 2026
arxiv.orgpaper🛡️ Security

Combining Long-Term Memory and LLMs Comes at a High Cost: From Prompt Injection to Persistent Compromise

Paper on memory injection, where prompt injection persists across sessions through the long-term memory of LLM-as-a-service platforms. It presents a general threat model and shows all NIST attack goals are achievable on ChatGPT Instant 5.3, Claude Sonnet 4.6 and Gemini 3 Flash. Vectors include personal memories, projects, skills, organization instructions and MCP resources. On Claude, shared memory lets an attacker compromise multiple users in an organization and exfiltrate prompts. Nearly half of the derived mitigations are unimplemented.

ChatGPTClaudeGemini+2
memory injectionprompt injectionNIST+2

AI Security· Added 24 Oct 2026, published 20 Oct 2026

arxiv.orgpaper🛡️ Security

After the Attacker Leaves: Benchmarking Carryover Attacks on LLM Agents

CarryoverBench is a benchmark of 12 personal-assistant scenarios and 101 attack tasks for carryover attacks, where a one-time indirect prompt injection planted in agent memory files or scheduled tasks re-fires in later sessions. Three trigger channels (Instant, Autonomous, Latent) are scored by a rule-based verifier with separate planting and triggering stages. Across five frontier models, payloads re-fire over five rounds without measurable decay. Porting the Latent channel to the Hermes runtime weakens the effect but does not remove it.

LLM
CarryoverBenchcarryover attacksindirect prompt injection+1

AI Security· Added 22 Oct 2026, published 20 Oct 2026

arxiv.orgpaper🛡️ Security

Context-Aware Prompt Injection Detection via Small Language Models in RAG Pipelines: nokast-secureRAG

nokast-secureRAG is a roughly 0.5B-parameter small language model that works as a semantic firewall between retrieval and generation in local RAG systems. It classifies each query and context pair as safe, suspicious or malicious. It reaches 0.994 recall at a 0.026 false-positive rate in-distribution, beating Llama Guard 3 1B and Prompt-Guard-86M (0.900 recall, 0.690 FPR). Recall on PoisonedRAG falls to near zero, and single-request latency is 293-404 ms.

Llama Guard 3LLM
indirect prompt injectionretrieval poisoningPoisonedRAG+2

AI Security· Added 22 Oct 2026, published 20 Oct 2026
eprint.iacr.orgpaper🛡️ Security

A Systematic Evaluation of Fault Attacks and Countermeasures on ML-DSA Rejection Sampling

Systematic evaluation of fault attacks on ML-DSA (FIPS 204) rejection sampling and of proposed countermeasures. It proves the "third rejection test" of patent WO2025261784A1 re-verifies what check 2 already guarantees, and shows that 30,000 fault injections never detect a skipped z-norm check. The author fully recovers s1 against a third-check-protected implementation under randomized signing. Third check and sign-then-verify are complementary; overhead is 0.04–0.05% on x86-64 and 0.83% on Cortex-M4 for the third check.

Cortex-M4
ML-DSAFIPS 204WO2025261784A1+1

Hardware & RF· Added 21 Oct 2026, published 20 Oct 2026

arxiv.orgpaper🛡️ Security

KNOX: Hardware-assisted Regulatory Sandbox for Generative Models

KNOX is a regulatory sandbox for generative models built by running AI agent workloads inside TEEs. It derives an attested policy manifest (applicable regulations, expected tool calls, permitted system calls) from the user prompt, and an attested reference monitor allows an action only if it matches. Actions and verdicts go into an attested execution graph that regulators can verify. The paper reports detection of prompt-injection deviations and under 1% overhead.

LLM
prompt injectionattested policy manifestattested reference monitor+1

AI Security, GRC· Added 22 Oct 2026, published 20 Oct 2026

x.comthread🛡️ Security

Nick Frichette (@Frichette_n) on X

Datadog Security Labs announcement, posted by Nick Frichette, of research on steering the evaluations of a prompt-injection detector called "Jev". The team's method cut its detection rate from about 83% to about 4% in their tests. They also used it to bypass LangChain's experimental tool-risk gating feature that is based on Jev. The tweet gives no method details and links to the full article.

LangChain
prompt injectionDatadog Security LabsNick Frichette

AI Security· Added 21 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🛡️ Security

Fake News, Real Crashes: Information Injection Attacks on LLM Financial Trading Agents

Fake News, Real Crashes is an October 2026 arXiv paper presenting a benchmark for information injection attacks on LLM financial trading agents. It spans five injection vectors, seven event categories and about 10,000 decisions on 15 U.S. stocks. Fabricated news reached 62% attack success versus 14% for prompt injection, and two 30-word templates hit 100%. Only hierarchical aggregation reduced success among the defenses tested.

LLM
information injectionprompt injectionfact poisoning+1

AI Security· Added 21 Oct 2026, published 19 Oct 2026
securityweek.comarticle🛡️ Security

MITRE ATT&CK v20 Catalogs AI Abuse, MFA Bypass, Water Utility Attacks

MITRE ATT&CK v20 adds nine Enterprise techniques and sub-techniques, including two prompt injection techniques, abuse of an organization's own AI agents for data theft, application-specific password theft and CAPTCHA bypass. ICS gains campaigns on internet-exposed PLCs at over 30 Minnesota water utilities and an AI-assisted breach of Mexican government bodies. It also adds Nimbus Manticore, The Gentlemen, 15 detection strategies with 38 analytics, and NGate for Mobile.

MITRE ATT&CKLLM
Nimbus ManticoreSalt TyphoonAPT38+7

Threat Intel, Blue Team & Detection, AI Security· Published and added 19 Oct 2026

x.comadvisory🛡️ Security

lee1981 (@lee1981b) on X

CVE-2026-106931 is an OS command injection (CWE-78) in the statistics processing of EG Secure Solutions SiteGuard Server Edition, a host-based WAF. It can give root or SYSTEM command execution. The vendor and JVN confirm exploitation on 14 October 2026. The post lists fixed builds (Ver8.00 Update 5, Ver7.00 Update 6 on FreeBSD), the IIS exclusion, the workaround of disabling statistics, and a SOC trail starting with diagnostic preservation before patching.

SiteGuard Server EditionApache HTTP Servernginx+3
CVE-2026-106931CWE-78CISA KEV+5

Blue Team & Detection, AppSec· Added 21 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🛡️ Security

SpanGuard: Decoupling Instruction Localization from Authorization for Lightweight IPI Defense

SpanGuard is an indirect prompt injection (IPI) guardrail that splits detection into two steps. Lightweight unsupervised segmentation first locates candidate instruction blocks in tool outputs, then a small LLM judges whether each block is authorized by the user's request. The authors report a 0.32% attack success rate with negligible benign utility loss, and the guardrail still works with substantially smaller models.

LLM
indirect prompt injectionprompt injection

AI Security· Added 21 Oct 2026, published 19 Oct 2026

eprint.iacr.orgpaper🛡️ Security

SAT and Neural Network Filters for Misinjections in Fault Attacks

This ePrint paper presents key-independent filters that remove misinjections (faults that miss the assumed form) in elimination fault attacks. A SAT filter, a neural network filter and a combined filter were tested on clock-glitch faults into GIFT-64, GIFT-128 and BAKSHEESH on a microcontroller. The SAT filter rejected none of 14669 intended faults, and raised ToFA success on BAKSHEESH from 5.2% to 61.2% (96.2% combined).

GIFT-64GIFT-128BAKSHEESH
ToFAclock glitchingmisinjection+1

Hardware & RF· Added 20 Oct 2026, published 19 Oct 2026

eprint.iacr.orgpaper🛡️ Security

IISFA: Ineffective Instruction-Skip Fault Attacks on Bitslice Implementations

IISFA (Ineffective Instruction-Skip Fault Attack) targets bitsliced block cipher implementations protected by redundancy countermeasures. Skipping one bitslice instruction leaves the result unchanged only when all m S-box inputs fall in an ineffective set, so each released ciphertext restricts all m subkeys. The authors give known- and chosen-plaintext key-recovery procedures and expected injection counts, and recover keys in every trial on GIFT, SKINNY and PIPO implementations on an 8-bit AVR microcontroller using clock glitches.

AVR
IISFAineffective fault analysisstatistical ineffective fault attack+6

Hardware & RF· Added 20 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🛡️ Security

SoK: PIAtlas: Decomposing the Unbounded Prompt Injection Attack Space

PIAtlas is a taxonomy of prompt injection attacks organized by how the injected instruction subverts the model, with six mechanism classes as roots of a technique and sub-technique hierarchy. The authors release PICorpus, a license-clean collection of public prompt-injection datasets, and map thousands of records to PIAtlas under a human-verified protocol. Results show attacks combine several techniques from few mechanisms, agent benchmarks cover only part of the space, and adaptive attackers favor mechanisms that curated benchmarks underrepresent.

LLM
PIAtlasPICorpusprompt injection

AI Security· Added 21 Oct 2026, published 18 Oct 2026

arxiv.orgpaper🧠 AI

ToFu: Exploiting and Fuzzing the LLM–Orchestrator–Tool Trust Boundary

ToFu is a tool-aware fuzzing framework for LLM tools, including MCP servers. It maps each tool argument, using its metadata, to one of 74 CWE-guided semantics-aware sanitizers (path, URL, SQL and similar). It then generates schema-valid Atheris harnesses and semantic oracles, using runtime tracers for in-process tools and outcome oracles for opaque ones. The LLM (gpt-4.1) only maps sanitizers and writes seeds; it is never the security judge. The paper also shows a "Repeat-After-Me" trick, where an LLM told to repeat attacker-crafted text emits a tool call the orchestrator executes, reproduced on LangGraph, MAF, ADK 2.0, AutoGen, Strands and CrewAI. Across 273 runnable MCP servers (3,405 tools) it reports 253 verified bugs in 343 tools across 118 servers, such as path traversal, log injection and exfiltration. These are failures a crash-based fuzzer would miss. The result matters because it shows LLM-generated tool arguments cannot be treated as trusted.

Model Context ProtocolAtherisCodeQL+7
ToFuStrandsMAF+10

mcp, research, agents· Added 18 Oct 2026

arxiv.orgpaper🛡️ Security

ToFu: Exploiting and Fuzzing the LLM–Orchestrator–Tool Trust Boundary

ToFu is a tool-aware fuzzing framework that derives semantic security checks for LLM tools (mainly MCP servers) from their metadata and a corpus of 74 CWE-guided sanitizers. It generates schema-valid Atheris harnesses, uses runtime tracers and outcome oracles to catch bugs that don't crash, and uses an LLM only to map sanitizers and seed inputs, never as the judge. It also describes a "Repeat-After-Me" attack, in which the LLM is told to repeat attacker-written text that the orchestrator then dispatches as a tool call. It was reproduced on LangGraph, MAF, ADK, AutoGen, Strands and CrewAI. On 273 MCP servers it reports 253 verified bugs across 343 tools in 118 repositories, including path traversal, log injection, exfiltration and command bypass.

Model Context ProtocolAtherisLangGraph+3
Repeat-After-Mepath traversalSSRF+6

AI Security, AppSec· Added 18 Oct 2026

aikido.devarticle🛡️ Security

Your CVE is reachable. But is it exploitable?

Explains why a reachable vulnerable function in a dependency is not necessarily exploitable, and how exploitability analysis extends SCA reachability analysis. It walks through CVE-2021-23337 (lodash _.template command injection) across three apps with different outcomes. It notes that a verdict can change with code, for example via prototype pollution and the follow-up CVE-2026-4800. A closing section describes Aikido's CVE Exploitability Analysis.

lodashAikido SecurityCVSS+2
CVE-2021-23337CVE-2026-4800CISA KEV+4

AppSec· Added 19 Oct 2026, published 17 Oct 2026

x.comthread🛡️ Security

Nicholas Martin (@ndgmlondon) on X

An X post advises auditing every MCP write tool against the database role it actually runs under. A shared service key lets prompt injection trigger unapproved writes, so each agent session should get a read-only role, with a test that writes are denied. Replies note that MCP servers often inherit ambient host credentials or can escalate through a second connection pool, and suggest also testing that another tenant's rows are unreadable with the same role.

Model Context Protocol
prompt injection

AI Security, Identity & Access· Added 18 Oct 2026, published 16 Oct 2026

x.comthread🧠 AI

Peter Dedene (@dedene) on X

A X thread benchmarking Qwen3.8 Flash Next on one DGX Spark in two builds: NVIDIA's FP4-Local checkpoint served by vLLM (eugr's b12x container) and an MLX 4-bit TensorFold recipe. The NVIDIA build scores higher on the author's agentic benchmark (81.2 vs 75.0), BFCL tool calling (82.4 vs 71.8 single-turn, 54.5 vs 43.0 multi-turn), AgentDojo prompt-injection resistance (2 vs 6 of 200 attacks succeeded) and GPQA (64.6 vs 59.1). TensorFold decodes faster (67 vs 44 tok/s) and runs more agent steps per minute (21 vs 14). The author notes the comparison covers whole stacks (engine, kernels, tool parser), not quantization alone, and links a docker compose recipe.

vLLMMLXDocker+1
Qwen3.8-Flash-NextNVIDIADGX Spark+6

inference, evals, models· Added 17 Oct 2026, published 16 Oct 2026

securityweek.comarticle🛡️ Security

In Other News: ICS-Sniper Attack, Hacking XWorm Malware Operators, $250k Chrome Exploit

SecurityWeek's weekly roundup covers ICS-Sniper, a UBC proof-of-concept that uses VPN-encrypted packet size, direction and timing to drop critical SCADA traffic on cloud-hosted ICS (tested on the SWaT water testbed). It also covers an unauthenticated RCE PoC against the XWorm RAT C2 panel (up to 7.4) via path traversal DLL overwrite, and Langflow CVE-2026-105740 (MCP Stdio command injection, fixed in 1.9.0) exploited from September 19, before the CVE was published. Other items: XBOW's AI-assisted Chrome full-chain exploit (GPT-5.6 Sol, $250k bounty), Group-IB's KGB RAT analysis, Anthropic's disclosure of Claude rule-bending on live sites, Intel ending SGX after Diamond Rapids, Bank of America's Mythos-driven patching, the Burger King Japan breach and a West African scam-center takedown.

LangflowChromeXBOW+3
CVE-2026-105740ICS-SniperXWorm+12

Threat Intel, AI Security, Offensive Security· Published and added 16 Oct 2026

arxiv.orgpaper🛡️ Security

MobileInject: Evaluating Reasoning-to-Action Security of MLLM-Based Mobile Agents under Cross-Modal Consistency Injection

MobileInject is a benchmark for testing MLLM-based smartphone agents against indirect multimodal injection. It has an interactive evaluation framework with 11 scenarios, 9 security-risk categories and 108 executable risk instances. It adds Cross-Modal Consistency Injection, Multi-Role Collaborative Deception, Reasoning-Camouflage Injection and a Reasoning Security Diagnosis Framework. Experiments find broad vulnerability, with many failures from early reasoning hijacking.

LLM
MobileInjectCross-Modal Consistency InjectionMulti-Role Collaborative Deception+3

AI Security· Added 20 Oct 2026, published 16 Oct 2026

arxiv.orgpaper🛡️ Security

Ignored, Not Refused: What Low Prompt-Injection Success Rates Hide in Small Tool-Using Agents

Ignored, Not Refused audits 33,000 trajectories from eleven open-weight agents (2-14B parameters) on InjecAgent and AgentDojo. A label-blind LLM judge finds most failed indirect prompt injections are ignored (76-80%) rather than refused (17-18%). Changing only the system prompt moves InjecAgent ASR from 0.2% to 43%. The Attack-Task Outcome Matrix (ATOM) shows 21.7% of AgentDojo episodes were safe but left the user task incomplete. The corpus, judge prompt and code are released.

LLM
indirect prompt injectionAgentDojoInjecAgent+2

AI Security· Added 20 Oct 2026, published 16 Oct 2026

arxiv.orgpaper🧠 AI

Ignored, Not Refused: What Low Prompt-Injection Success Rates Hide in Small Tool-Using Agents

"Ignored, Not Refused" audits 33,000 trajectories from eleven open-weight agents (2-14B parameters) on InjecAgent and AgentDojo. A label-blind LLM judge finds 76-80% of failed injection attacks were ignored and 17-18% refused. Changing only the system prompt moves InjecAgent attack success rate from 0.2% to 43%, and the ATOM matrix shows 21.7% of AgentDojo episodes were safe but left the user's task undone. The corpus, judge prompt and code are released.

LLM
InjecAgentAgentDojoATOM+1

evals, ai-safety, agents· Added 20 Oct 2026, published 16 Oct 2026

arxiv.orgpaper🛡️ Security

Stealthy Poisoning Attacks via Reused KV Cache of Reasoning

R^2ECAP (Reused Reasoning-Cache Poisoning) is a black-box attack that plants poisoned reasoning traces through a chat interface, exploiting LLM systems that reuse KV caches of reasoning. A preceding trace steers the model, and the retained trace keeps residual adversarial influence in its cache after the preceding trace is discarded. On three open-weight LLMs and three datasets it reaches up to 79% ASR, beats the white-box HijackKV in 8 of 9 settings, and reaches 46% ASR in a reasoning-trace retrieval system. Only 1% of retained responses are flagged by a popular prompt injection detector.

LLM
R^2ECAPHijackKVprompt injection

AI Security· Added 20 Oct 2026, published 16 Oct 2026

github.comrepo🛡️ Security

gichirimaku/wp2shell-PoC

wp2shell-PoC is a Python proof-of-concept exploiting a pre-authentication RCE chain in WordPress core, combining CVE-2026-63030 (REST API batch route confusion) and CVE-2026-60137 (SQL injection in WP_Query). It demonstrates escalation from the route-desync bug through blind SQLi, customize_changeset forgery, and hook re-entry to administrator account creation and arbitrary command execution via a malicious plugin upload. The tool supports vulnerability checking, data extraction (union, error-based, blind techniques), and full shell access with or without existing admin credentials.

WordPressPython
CVE-2026-63030CVE-2026-60137SQL injection+1

AppSec, Offensive Security· Added 23 Oct 2026, published 15 Oct 2026

blog.cloudflare.comarticle🛡️ Security

A fully programmable secure web gateway

Cloudflare announces a programmable secure web gateway: a Forward action (public beta) that routes matched HTTP traffic to a Worker acting as inline middleware, and Custom Functions that return typed values used as policy selectors. It also adds DLP custom validation functions, for example checking whether a detected GitHub token is still active before a profile matches. Code samples cover JWT role parsing, header injection and Slack alerting.

CloudflareCloudflare WorkersCloudflare Gateway+2
Forward actionCustom FunctionsDLP custom validation functions

Cloud & Infra· Added 29 Oct 2026, published 15 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Exploring Fault Injection Attacks on HQC and BIKE Beyond Fujisaki-Okamoto Verification

Presents fault injection attacks on BIKE and HQC decapsulation that target instructions outside the Fujisaki-Okamoto transform, achieving full key recovery with only valid ciphertexts at NIST Level 1 (17392 queries for HQC, about 3 million for BIKE). It also gives a general method for finding effective fault locations by analysing decoder behaviour under perturbed conditions. Attacks were validated with laser fault injection on an STM32H7 microcontroller, showing a wider attack surface for code-based post-quantum KEM implementations.

HQCBIKESTM32H7
Fujisaki-Okamoto transformlaser fault injectionkey recovery+1

Hardware & RF· Published and added 15 Oct 2026

securitylabs.datadoghq.comwriteup🛡️ Security

Jev as a judge: How counterfeit policy steers Jev

Datadog Security Labs tests TypeSafe AI's Jev decision model as a prompt-injection detector and as the judge behind LangChain's tool-risk gating. On four public datasets Jev had 99.66% precision and 82.90% recall. A prepended "counterfeit policy" that redefines the attack categories cut recall by over 79 points. In a LangChain scenario, a user-editable profile field lowered the mean is_risky score from 0.893 to 0.290, below the 0.5 block threshold. Plain prompt injection did not move the score.

JevLangChain
TypeSafe AIcounterfeit policyprompt injection+3

AI Security· Added 29 Oct 2026, published 15 Oct 2026

unit42.paloaltonetworks.comwriteup🛡️ Security

Unit 42 Uncovers PEERSTITCH, a Stealthy FortiGate Implant

PEERSTITCH is a memory-resident ARM64 implant that Unit 42 found in a September 2024 telecom intrusion (cluster CL-STA-0954, aka UNC5820). Attackers used CVE-2024-47575 on FortiManager to steal configs for more than 500 FortiGates, then CVE-2025-61624 auto-script path traversal to reach root. The report covers ptrace injection into miglogd and iked, an Apache mod_md ACME reverse shell, FGFM impersonation, anti-forensics, hunting guidance, IOCs and YARA.

FortiManagerFortiGateFortiOS+3
CVE-2024-47575CVE-2025-61624CVE-2024-26009+10

Threat Intel, Malware & RE, Blue Team & Detection· Added 30 Oct 2026, published 14 Oct 2026

arxiv.orgpaper🛡️ Security

From Detection to Decision: Calibration and Deferral for Prompt-Injection Detection

Evaluates a native probabilistic decision model (Jev), Llama Prompt Guard 2 (22M and 86M) and an LLM judge on 47,611 held-out examples covering direct/indirect prompt injection, hard-benign inputs, obfuscation and distribution shift. The LLM judge has the best AUROC (0.897), followed by Jev (0.871), Prompt Guard 2 86M (0.757) and 22M (0.714). Jev's native probabilities do not consistently beat post-hoc calibrated classifier scores, and temperature scaling improves calibration but not discrimination. At a 1% false-negative-rate target, every system needs over 91.8% escalation, so probabilistic outputs alone do not give reliable security decisions under distribution shift.

LlamaLLM
JevPrompt Guard 2prompt injection+1

AI Security· Added 17 Oct 2026, published 14 Oct 2026

arxiv.orgpaper🛡️ Security

INFUSE: A Unified Surface Benchmark for Indirect Prompt Injection in Agentic Systems

INFUSE is an end-to-end benchmark for indirect prompt injection (IPI) across long-horizon agent workflows (shell commands, code changes, dependency installs, remote services). It has 40 realistic tasks and a taxonomy of 56 attack scenarios in five threat categories, with attacks injected via interaction surfaces encountered mid-task. Across 19 LLMs (GPT, Claude, Gemini, Llama, Gemma, Qwen) and 41,824 adversarial trajectories, mean attack success was 19.6% (LLM-judged) and 15.4% (heuristic), per-model 3.2–41.9%; guard models gave limited protection, while prompt-level hardening cut mean ASR from 58.2% to 14.3%.

LLMClaudeGemini+3
indirect prompt injectionINFUSE

AI Security· Added 17 Oct 2026, published 14 Oct 2026

en.cryptonomist.charticle🧠 AI

Google’s Gemini 4 Argon AI solves 12 simulated cyberattacks, up from five

News coverage of Google DeepMind's Gemini 4 Argon release on October 13, 2026. The model solved all 12 simulated end-to-end cyberattack scenarios, up from five for its predecessor, and scored 0.7% attack success on Gray Swan's Indirect Prompt Injection benchmark. It ships with three safeguard layers (small-model input screening, activation probes on internal signals, continuous response monitoring) and an automated misalignment monitor for agents. Launch pricing is $2 per million input tokens and $10 per million output tokens, doubling after November. Access is through Pro and Ultra tiers, and Ultra also gets Antigravity. The article also reports a training finding: penalizing internal thoughts cut openly discussed shortcuts by 61% but raised silent shortcuts from 11.2% to 36.4%.

GeminiGoogle Antigravity
Gemini 4 ArgonGoogle DeepMindGoogle+7

models, ai-safety, evals· Published and added 14 Oct 2026

securityweek.comarticle🛡️ Security

Citrix, Fortinet, Ivanti Patch 29 Vulnerabilities Across Their Products

SecurityWeek summarizes Patch Tuesday-style releases from Citrix, Fortinet and Ivanti fixing 29 vulnerabilities. Highlights include critical FortiSIEM and FortiSandbox flaws (CVE-2026-106173 code execution, CVE-2026-107656 auth bypass), five SQL injection bugs across FortiAnalyzer, FortiManager and FortiMail, and Ivanti Connect Secure's exploited zero-day CVE-2026-104935 (two chained bugs compromising patched VPNs). Also covers critical Ivanti Neurons Patch for Intune (CVE-2026-109412) and Xtraction (CVE-2026-106042) issues and Citrix fixes in Workspace App, XenServer and UniconOS.

Ivanti Connect SecureFortiSIEMFortiSandbox+3
CVE-2026-106173CVE-2026-107656CVE-2026-104935+2

Threat Intel, AppSec· Published and added 14 Oct 2026

securityweek.comarticle🛡️ Security

SAP Patches Critical NetWeaver, S/4HANA Vulnerabilities

SecurityWeek summarizes SAP's October 2026 Security Patch Day (22 notes, four critical). Critical flaws: CVE-2026-89111 (CVSS 10) OAuth2 SSRF in SAP Cloud SDK for Python that leaks client credentials via the tenant_subdomain parameter; CVE-2026-89110 (9.9) NetWeaver broken access control allowing ABAP code execution through Fiori rule definition input; CVE-2026-89107 (9.9) S/4HANA Visual Composer code injection; and CVE-2026-89108 (9.1) missing authorization check in Manufacturing Integration and Intelligence allowing admin account creation. SAP reports no exploitation in the wild.

SAP NetWeaverSAP S/4HANASAP Cloud SDK for Python+3
CVE-2026-89111CVE-2026-89110CVE-2026-89107+3

AppSec· Published and added 14 Oct 2026

x.comadvisory🛡️ Security

Dark Web Intelligence (@DailyDarkWeb) on X

Summary of SAP's October 13, 2026 Security Patch Day (16 new notes, 4 GitHub advisories). It leads with CVE-2026-89111, a CVSS 10.0 OAuth2 SSRF in SAP Cloud SDK for Python before 0.45.2, where an attacker-controlled tenant_subdomain redirects token requests and exfiltrates client credentials. It also lists three other critical flaws: broken access control in NetWeaver Visual Composer, code injection in S/4HANA substitution/validation rules, and a missing authorization check in the Manufacturing Integration and Intelligence (XMII) Configuration Service. It notes that none are in CISA KEV and SAP reports no in-the-wild exploitation.

SAP Cloud SDK for PythonSAP NetWeaverSAP S/4HANA+3
CVE-2026-89111CVE-2026-89110CVE-2026-89107+5

AppSec, Identity & Access· Added 15 Oct 2026, published 13 Oct 2026

embracethered.comwriteup🛡️ Security

Visual Studio Copilot and SSMS Remote Code Execution (CVE-2026-103572)

CVE-2026-103572 is a remote code execution bug in Microsoft.VisualStudio.Copilot.Core.dll, shared by Visual Studio and SQL Server Management Studio. A trailing dot (for example `.mcp.json.`) bypasses the protected-filename check in EditsFunctionHandler.GetEditConfirmationTypeAsync, so a hijacked Copilot can rewrite its own MCP and settings files and run commands. The post covers path traversal and InstallationID leaks, indirect prompt injection demos, the October 2026 patch (GetFullPath), and a $0 bounty.

Visual StudioSQL Server Management StudioGitHub Copilot+3
CVE-2026-103572indirect prompt injectionpath traversal+5

AI Security, AppSec, Offensive Security· Added 29 Oct 2026, published 13 Oct 2026

deepmind.googlearticle🧠 AI

Developing Gemini 4 Argon responsibly and safely

DeepMind describes how it made Gemini 4 Argon safe for broad release. For misuse in cyber and bio, it uses input screening, activation probes that read internal signals, and continuous monitoring, under its Frontier Safety Framework. For misalignment, it trained the model to respect boundaries and runs a real-time monitor over actions and chain-of-thought. Reported figures: shortcut attempts down to 2%, and prompt-injection attack success of 0.7% on Gray Swan's IPI benchmark. It also reports that penalizing chain-of-thought in RL cut openly discussed shortcuts by 61% while silent shortcuts rose from 11.2% to 36.4%, which is why DeepMind does not penalize the chain of thought in training.

Gemini
Gemini 4 ArgonGoogle DeepMindGoogle+4

ai-safety, models· Published and added 13 Oct 2026

deepmind.googlearticle🧠 AI

Gemini 4 Argon

Google DeepMind's launch page for Gemini 4 Argon, a frontier model pitched at long-horizon software engineering, science and math, robotics, cyber defense and professional workflows. Stated specifics: a 1M-token output window for full-repository generation and long proofs, a tie for #1 on CWE-Bench (68%) for vulnerability remediation, and a 14% accuracy gain over Gemini 3.1 Pro in Box's evaluation. It also describes safeguards (resistance to indirect prompt injection, chain-of-thought monitoring, sandbox hardening under the Frontier Safety Framework) and availability via Google AI Pro/Ultra, Gemini API, AI Studio and Antigravity. Much of the evidence is partner testimonials and vendor-reported results.

GeminiGoogle AntigravityGoogle AI Studio+1
Gemini 4 ArgonGoogle DeepMindGoogle+16

models, coding-agents, multimodal· Published and added 13 Oct 2026

arxiv.orgpaper🛡️ Security

Towards Safe Autonomy for Computer Use

Introduces SA-CUA, a dual-LLM framework that gives Computer Use Agents a trust boundary against indirect prompt injection. It derives conservative deterministic rules from the accessibility tree to unmask trusted screen regions for the privileged LLM, and adds an endorsement channel that moves values from untrusted to trusted domains by verification. Human input is needed only at task specification. It reports much higher utility than CaMeL-CUA with a zero attack success rate.

LLM
SA-CUACaMeL-CUACaMeL+2

AI Security· Added 15 Oct 2026, published 13 Oct 2026

arxiv.orgpaper🧠 AI

Towards Safe Autonomy for Computer Use

Introduces SA-CUA, a dual-LLM framework for Computer Use Agents (CUAs) that defends against indirect prompt injection. It builds a trust boundary by deriving conservative deterministic rules from the accessibility tree, which unmask trusted screen regions in the privileged LLM's screenshot and keep untrusted content separate. An endorsement channel lets values move from the untrusted to the trusted domain through verification over trusted channels. This removes the need for per-action user confirmation and the confirmation fatigue it causes. SA-CUA is reported to keep much higher utility than CaMeL-CUA with a 0% attack success rate.

LLM
SA-CUACaMeL-CUACaMeL

agents, research· Added 15 Oct 2026, published 13 Oct 2026

securityweek.comarticle🛡️ Security

Refrigeration Controller Hack Spoils Food Across European Supermarkets

SecurityWeek reports a cyberattack on hundreds of European supermarkets (Auchan, Carrefour, E.Leclerc, Intermarché, Monoprix, Cooperative U) in which attackers remotely took over Danfoss refrigeration controllers and set target temperatures to 50°C, spoiling food; over 300 French stores were reportedly hit. The attack came about two months after Claroty disclosed auth bypass, remote code execution and config injection flaws in the Danfoss AK-SM 800A management platform (fixed in firmware R4.3.1), though it is unclear whether those flaws were exploited. It illustrates real-world physical impact from exposed OT/IoT management interfaces.

Danfoss AK-SM 800A
ClarotyLukasz OlejnikAuchan+5

Threat Intel, Hardware & RF· Published and added 13 Oct 2026

arxiv.orgpaper🛡️ Security

BrowseSafe++: Benchmarking Prompt Injection Detection Across Web Contexts, Languages, and Browser Views

BrowseSafe++ extends BrowseSafe to 38,675 paired attacked/clean web pages, most with prompt injections observed in the wild on production sites. Pages cover twelve site types, 24 attack types and 18 injection locations, each given as HTML, Markdown, accessibility tree and screenshot with a user task and expected answer. The authors train BrowseSafe-Guard, two 0.8B detectors (text and screenshot) that beat a frontier-model-based detector on F1 with low false positives and low inference cost. BrowseSafe-Adapt rewrites injections using browser-agent feedback, raising attack success from a few percent to up to 95.41%.

LLM
BrowseSafe++BrowseSafeBrowseSafe-Guard+3

AI Security· Added 15 Oct 2026, published 12 Oct 2026

Showing 90 of 463

Show more