Skip to content

81 results for β€œVals”

What you seeeverything
newsletter.semianalysis.comarticle🧠 AI

The Datacenter Backlash Goes Bipartisan: Next Week's Midterms and the 2028 Buildout

SemiAnalysis analysis of how the November 2026 US midterms could affect datacenter buildout. About 75% of the 33.8 GW due in 2027 across the top 20 states is already under construction, but 43.5 GW of 2028 additions sit in 13 states with pending approvals. The biggest risk is a prolonged Texas TCEQ permit freeze. Texas holds close to 30% of 2028 GW, and nine of 20 nominees back a pause.

SemiAnalysisTexas Commission on Environmental QualityERCOT+16

ai-policyΒ· Published and added 1 Nov 2026

ethereum-magicians.orgthreadπŸ›‘οΈ Security

Pre-ERC: Agent Pre-Sign Risk Report

Pre-ERC: Agent Pre-Sign Risk Report is a draft Ethereum Magicians proposal for an EIP-712-signed report that a risk source, identified by an ERC-8004 identity, returns about one unsigned request. It carries typed findings on tokens, approvals, addresses, payments (x402) and texts, and each finding is marked read or not read. It has no score or verdict, so the consumer applies its own policy. The author's live implementation, toll, runs on Robinhood Chain.

Ethereumx402Robinhood Chain+3
ERC-8265ERC-8004ERC-8470+8

AI Security, BlockchainΒ· Published and added 31 Oct 2026

ethereum-magicians.orgthread🧠 AI

Pre-ERC: Agent Pre-Sign Risk Report

Pre-ERC: Agent Pre-Sign Risk Report is an Ethereum Magicians draft for a signed, typed report that a risk source returns about one unsigned agent transaction. The report is bound to the request by a digest and signed with EIP-712 by an ERC-8004 identity. Findings cover tokens, approvals, addresses, x402 payments and texts, each marked read or not read, with no score or verdict. The toll service runs it live on Robinhood Chain.

x402Model Context ProtocolEthereum+6
ERC-8265ERC-8470ERC-8478+1

agentsΒ· Published and added 31 Oct 2026

arxiv.orgpaper🧠 AI

Retrieving from Your Own Mistakes: On-Policy Training of Embedding Models for Multi-Hop Retrieval-Augmented Generation

On-policy state training is a method for training chain embedding retrievers for multi-hop RAG on the states the encoder itself reaches, including those built on its own wrong retrievals. Each state is labeled with the earliest missing gold passage, other missing gold passages are masked, and updates are contrastive and mixed with teacher-forced states. It retrieves complete evidence more often than teacher-forced training and graph-based systems, and transfers to harder long-chain HotpotQA and 2WikiMultiHopQA variants the authors built.

RAGon-policy state trainingcontrastive learning+1
HotpotQA2WikiMultiHopQAarXiv

research, llm-apps, trainingΒ· Added 31 Oct 2026, published 29 Oct 2026

deploymentsafety.openai.comarticle🧠 AI

Addendum to GPT-6 Luna System Card: October 28, 2026 Update

The addendum to the GPT-6 Luna system card covers the October 29, 2026 update of GPT-6 Luna, which gives more concise answers and less agreeable language. It compares the update with GPT-6 Luna (October 7) on safe completions, under-18 evals, jailbreaks, HealthBench, MentalHealthBench, hallucination and alignment. OpenAI keeps its High rating for cybersecurity and for biological and chemical capability. Hallucination error rates rose, and HealthBench scores fell.

ChatGPT
OpenAIGPT-6 LunaGPT-6 Sol+10

models, evals, ai-safetyΒ· Published and added 29 Oct 2026

x.comthreadπŸ›‘οΈ Security

Kizuno18 (@Kizuno18) on X

Thread by Kizuno18 on the move from local stdio/Docker Model Context Protocol servers to remote HTTP/SSE endpoints in enterprise infrastructure. It names three trade-offs: credential boundary inversion (short-lived OAuth/JWT tokens instead of long-lived admin tokens on workstations), tool schema bloat solved by deferred discovery, and governance via HCP Terraform policy-as-code (Sentinel/OPA), audit trails and approvals. It is opinion, with no data or implementation detail.

Model Context ProtocolTerraformDocker+2
Sentinelblast radiuspolicy-as-code+1

AI Security, Identity & Access, DevSecOpsΒ· Added 29 Oct 2026, published 27 Oct 2026

x.comthread🧠 AI

Kizuno18 (@Kizuno18) on X

Kizuno18's X post argues that the move from local stdio and Docker MCP servers to remote HTTP/SSE endpoints matures the Model Context Protocol in enterprise infrastructure. It lists three trade-offs: short-lived OAuth/JWT bearer tokens replace mounted admin credentials, deferred tool discovery avoids roughly 20k tokens of eager schema loading, and HCP Terraform enforces Sentinel/OPA policy, audit trails and approvals server-side. Opinion post with no benchmarks or code.

Model Context ProtocolDockerTerraform+5
Kizuno18HCP TerraformOPA

mcpΒ· Added 29 Oct 2026, published 27 Oct 2026

socket.devwriteupπŸ›‘οΈ Security

Malicious Firefox Extensions Impersonate Phantom, Jupiter, and Bitget to Steal Wallet Secrets

Socket analysis of three malicious Firefox add-ons impersonating Phantom, Jupiter and Bitget wallets, using Unicode homoglyph names. They steal seed phrases and private keys and send them to brand-named subdomains of bonto[.]io. The Phantom fake adds a runtime loader that fetches and evals a second stage, and bundles a drainer backend with Telegram forwarding. Includes IOCs, hashes and wallet addresses.

FirefoxTelegramCloudflare+3
bonto.ioPhantomJupiter+14

Threat Intel, Malware & RE, BlockchainΒ· Published and added 27 Oct 2026

thedefiant.ioarticleπŸ›‘οΈ Security

US Charges Six in Alleged Madagascar NFT Wallet-Draining Scheme

The Defiant reports US charges against six people over an alleged NFT wallet-draining scheme run from Madagascar. An FBI affidavit estimates at least $516,695 in losses across 74 victim-linked wallets. It describes unlimited USDT spending approvals as the mechanism. The fetched text holds only the subtitle, so the scheme's mechanics and the defendants are not covered here.

Tether
FBIwallet drainerunlimited token approval+1

Threat IntelΒ· Published and added 27 Oct 2026

x.comthreadπŸ›‘οΈ Security

AGTP (@AGTPinsights) on X

AGTP's X thread summarizes Meta's Muse Spark 1.3 Evaluation Report. Prompt injection was tested on Exponential Security Labs' RepoInject v1 and BrowserInject v1 and on Gray Swan's IPI Arena, with robustness said to be on par with GPT-5.6 Sol. It also covers chain of thought controllability evals, PostTrainBench under Loss of Control, and Handshake's pre-release human red teaming. It notes the Midas Project's criticism of Muse Wonder's missing safety report.

Muse SparkMuse Spark Open
prompt injectionRepoInject v1BrowserInject v1+10

AI SecurityΒ· Added 27 Oct 2026, published 26 Oct 2026

x.comthread🧠 AI

AGTP (@AGTPinsights) on X

Thread summarizing Meta's Muse Spark 1.3 Evaluation Report, the safety write-up for the model released on September 2, 2026. It covers prompt-injection results on Exponential Security Labs' RepoInject v1 and BrowserInject v1 and Gray Swan's IPI Arena, chain-of-thought controllability evals, PostTrainBench under Loss of Control, and Handshake's human red teaming. It also notes The Midas Project's criticism that Muse Wonder still has no safety report, and the Muse Spark Open rollout (816B total, 42B active parameters).

Muse Spark 1.3Muse Spark OpenMixture of Experts
MetaMuseMuse Wonder+19

ai-safety, evals, modelsΒ· Added 27 Oct 2026, published 26 Oct 2026

x.comthreadπŸ›‘οΈ Security

BenjaminπŸ‘¨β€πŸ’» (@Hislordship_9) on X

Thread on Forever Security's finding that a planted Markdown "Engineering Work Guidelines" file in ~/Downloads made Codex add a "project-tools" MCP server to ~/.codex/config.toml. The server ran npm install function-color, a known malicious package, and started a child session with --dangerously-bypass-approvals-and-sandbox. Codex complied in over 90% of the firm's tests; Claude Code, via a CLAUDE.md setting ANTHROPIC_BASE_URL, about half. Advice: don't start agents in Downloads, review instruction files, and diff agent config.

CodexClaude CodeModel Context Protocol+1
Forever Securityfunction-colorAGENTS.md+4

AI Security, Supply ChainΒ· Added 27 Oct 2026, published 26 Oct 2026

securityweek.comarticleπŸ›‘οΈ Security

Stolen AI Reasoning Could Help China Build Cheaper Rivals

Compaction Smuggling is an attack found by Xint that bypassed OpenAI's August 2026 mitigations against stealing reasoning traces from proprietary LLM APIs. It encodes one model's reasoning inside a compaction and replays it to another model (for example gpt-4.1 or gpt-4o), which outputs it verbatim. OpenAI fixed it and paid a $6,000 bounty on 23 October 2026. The article ties it to distillation by Chinese labs, citing a September CISA warning.

OpenAILLMDeepSeek+3
Compaction SmugglingXintCISA+8

AI Security, Threat IntelΒ· Published and added 26 Oct 2026

x.comthread🧠 AI

Syb (@DegenOfWallSt) on X

Nanbeige4.3-33B is a 33.1B dense, Llama-style open model under Apache-2.0, released with a base model on Hugging Face. In Nanbeige's own table it beats Qwen3.8-27B on Terminal-Bench 2.1 (80.9 vs 73.0), DeepSWE (65.5 vs 42.5) and Automation Bench, but trails on SWE-Bench Pro, GDPval and GPQA Diamond. BF16 weights are about 66 GB, split across 4 GPUs in the vLLM and SGLang examples. No independent evals exist yet.

Hugging FacevLLMSGLang+4
Nanbeige4.3-33BNanbeige4.3-3BNanbeige+8

models, coding-agents, evalsΒ· Added 26 Oct 2026, published 25 Oct 2026

thomasunise.comtoolπŸ›‘οΈ Security

Argus – a free, open-source agentic security operations platform – MIT

Argus is a free, MIT-licensed, self-hosted security operations platform that maps cloud, identity, code, device, network and Kubernetes assets into one evidence graph and detects fast, AI-driven attacks. Read-only AI agents investigate and only propose actions. Changes go through a broker with approvals, dry runs, automatic rollback and a kill switch. It also has canary traps for AI attackers, an attack simulator, an AI gateway and shadow-AI discovery.

ArgusCrowdStrikeSentinelOne+3
CISA KEVprompt injectionSOC 2+1

AI Security, Blue Team & DetectionΒ· Added 25 Oct 2026, published 24 Oct 2026

arxiv.orgpaper🧠 AI

Build, Don't Play: Self-Improving LLM Research Agents Develop a Hearthstone Battlegrounds AI That Rivals Top Players

AutoTavern is a self-improving system of specialised LLM research agents with a typed shared memory and verification gates. In 20 days it built TavernGym, a full-content Hearthstone Battlegrounds simulator, and 23 versions of TavernAgent, a PPO-trained player. TavernAgent averaged placement 1.60 with 80% first places over its last 20 live games, beating the top ten players (2.34, 59%). On TavernBench (960 tasks), it answered 91% of play tasks against at most 63% for frontier LLMs.

PPOLLM
AutoTavernTavernGymTavernAgent+3

agents, research, training, evalsΒ· Added 27 Oct 2026, published 24 Oct 2026

en.cryptonomist.charticle🧠 AI

Moonshot AI reports Kim K3.1 Pro tops rivals with 64.4 on finance test

Kim K3.1 Pro is Moonshot AI's upgrade of Kimi K3, released 23 October 2026, with 3 trillion parameters, a one million token context window and a mixture-of-experts design that activates 16 of 896 experts. Moonshot reports 64.4 on OfficeQA Pro v2 (ahead of Opus 5.5 and GPT-6 Astra), 65.7% on Terminal-Bench 4.0 and 92.7% on BenchCAD (behind both). Hallucination on an internal hard test fell from 23.4% to 8.3%. Weights are due by 4 November.

LLMMixture of ExpertsKimi Delta Attention+4
Moonshot AIKim K3.1 ProKimi K3+9

models, evalsΒ· Published and added 24 Oct 2026

latent.spacearticle🧠 AI

[AINews] Kimi 3.1 Pro 104BA-2.8T: Fable-5.1-Class Open Weights narrows Closed-AI lead to 1 month... and Pro Highspeed API with 2-3Γ— speed

AINews issue for 22 to 23 October 2026 centred on Moonshot's Kimi K3.1 Pro, a multimodal mixture-of-experts model with 2.8T total and 104B active parameters and 1M context. Weights are promised for 4 November 2026. Artificial Analysis scored it 55 on its Intelligence Index (fourth place), and Arena ranked it #8 in WebDev. Standard pricing is $2/$10 per million tokens. The issue also covers a cyber-data removal approach, serving-cost objections, and paid-promotion allegations. Shorter items follow on agents, evals and inference.

Mixture of ExpertsClaude CodeCursor+7
Kimi K3Moonshot AIKimi+29

models, evalsΒ· Published and added 24 Oct 2026

blog.alexewerlof.comarticle🧠 AI

The rise and fall of Jev hype

The essay uses the launch of Jev, TypeSafe AI's "System One" general-purpose classifier trained with RLCD, to dissect AI marketing patterns: name dropping, jargon, ambiguity, inflated claims and drama. The author argues Jev's hype peaked and collapsed within about 33 days, while open-weight rivals beat it on cost and performance. It also lists incremental advances since ChatGPT and four unsolved problems: abstract reasoning, continuous learning, embodiment and the economics of running AI.

JevLLMModel Context Protocol+4
TypeSafe AITypeSafeOpenAI+14

ai-policy, modelsΒ· Added 24 Oct 2026, published 23 Oct 2026

openai.comarticle🧠 AI

What FDE means at OpenAI

Colin Jarvis, Head of Forward Deployed Engineering at OpenAI, describes how the FDE team works with enterprise customers to close the "deployment gap". Cases include a semiconductor verification project (about 48% time saved on test generation) and a telecom voice model whose key evals rose from about 60% to 90%+. Moving use cases onto a Codex harness with skills and plugins removed about 90% of custom code.

CodexModel Context ProtocolOpenAI API+1
OpenAIColin JarvisJohn Deere+3

ai-policy, coding-agents, agentsΒ· Published and added 22 Oct 2026

blog.cloudflare.comarticle🧠 AI

Introducing Clairic, a new System OneΒ class of extraction models

Clairic is Cloudflare's preview System One extraction model, hosted on Workers AI as @cf/cloudflare/clairic, with open weights planned. It reads text or images in one forward pass and returns typed values with spans, confidence, p_null, 80% intervals for estimates and forecasts. A claim-handling cascade with Clef and GLM-5.3 ran in 19.3 seconds against 61.7 for an all-LLM version.

CloudflareWorkers AILLM
ClairicClefJev+5

models, llm-apps, ai-infraΒ· Added 29 Oct 2026, published 19 Oct 2026

x.comtool🧠 AI

Bravish (@bravish_) on X

Tracekit 1.2.3 is a tamper-evident flight recorder for AI agents. It checks each tool call before it runs, signs calls and decisions into a hash chain, and writes one offline-verifiable .tkb file per run. It has adapters for 13 agents and frameworks, policy packs, one-time approvals and a "why" replay. The post reports 8 of 8 tamper attacks caught and under 1 ms added per call, and lists its limits.

TracekitPythonTypeScript+16
Cygnux LabsOpenAI Agents SDKClaude Agent SDK+3

ai-infra, agentsΒ· Added 19 Oct 2026, published 17 Oct 2026

huggingface.corepo🧠 AI

Meta Muse Spark Open (816B-A42B) open-weights model card

Model card for Meta Superintelligence Labs' Muse Spark Open, an open-weights, natively multimodal model with 816B total and 42B active parameters and a 1M-token context window. It targets coding and agentic work (tool use, long-horizon tasks, multimodal reasoning, synthetic data generation, LLM-as-judge). It ships in BF16 and NVFP4, needs about 700GB VRAM (NVFP4) or 2TB (BF16), runs on SGLang, vLLM, Transformers, TensorRT-LLM, Unsloth, llama.cpp and MLX, and supports a reasoning_effort setting. The Muse Model License requires "Built with Muse Spark Open" attribution and a separate agreement for Model-as-a-Service above $20M revenue. The card reports safety results against Kimi K3 on cyber, chem/bio and loss-of-control evals.

Hugging FaceTransformersvLLM+8
Muse Spark OpenMetaMeta Superintelligence Labs+15

models, multimodal, inferenceΒ· Added 17 Oct 2026

thingstodoapi.comtool🧠 AI

Show HN: Things to Do API

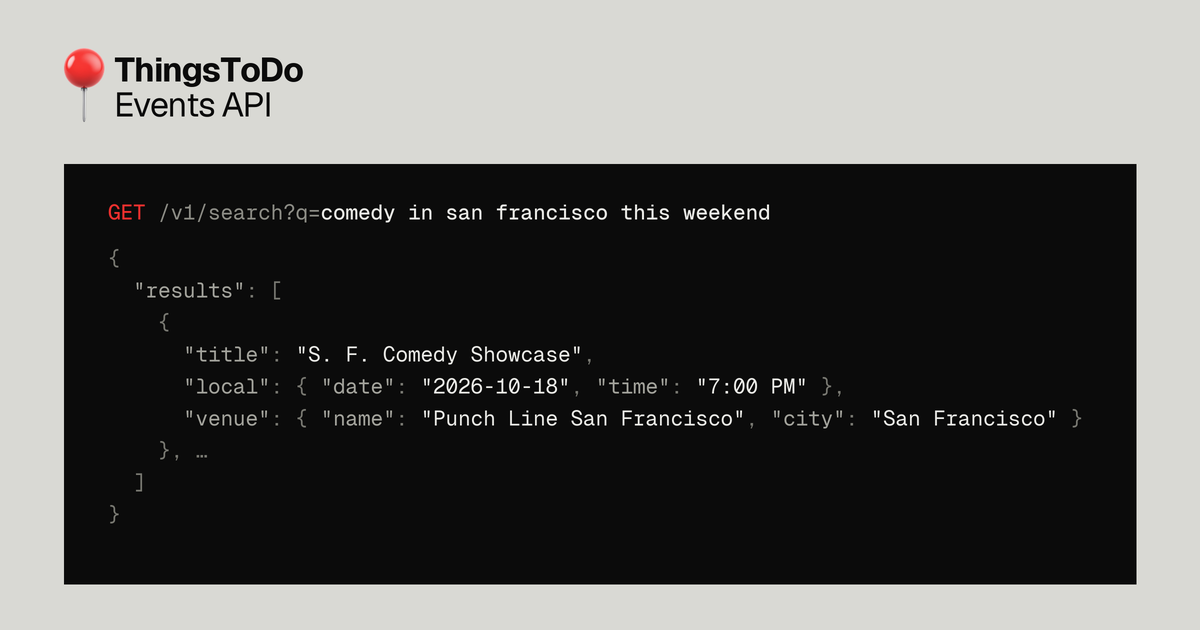
Things to Do API is a hosted knowledge base of local events (shows, talks, pop-ups, markets, festivals) that you query in natural language, for example `/v1/search?q=comedy+in+san+francisco+this+weekend`. It returns structured JSON with title, category, local start time, venue and ticket and source links. It also exposes an HTTP MCP endpoint, added with `claude mcp add --transport http thingstodo https://api.thingstodoapi.com/mcp`, so agents can use it as a tool. Coverage is live for the San Francisco Bay Area, with New York City and Los Angeles coming. Pricing is pay-as-you-go from $5 per 1,000 calls, the first 1,000 a month are free, and there is a 300 calls/min limit.

Model Context ProtocolClaude CodeREST
Things to Do APITicketmaster

mcp, llm-appsΒ· Added 18 Oct 2026, published 16 Oct 2026

claude.devarticle🧠 AI

How the Claude Code team does code review

The Claude Code team describes how it reviews code when Claude writes about 90% of it. Layers include pre-PR self-verification and fresh-context subagent review, an automated Claude review on every PR, and agents that vote on each finding. Risk-tier classifiers, trusted-author rules, merge queues, feature flags and on-call back these up. From June to September, merged PRs more than doubled while reverts fell over 40%. It also covers how they measure reviewer noise, treat incidents as evals, keep review loops converging (one PR went through 50+ rounds overnight), and spread codebase knowledge through Claude-generated explainers.

Claude CodeClaudeGitHub+2
AnthropicBoris Cherny

coding-agents, ai-policyΒ· Added 17 Oct 2026, published 16 Oct 2026

arxiv.orgpaper🧠 AI

MUB: An Identity-Masked Benchmark for Music Understanding in Multimodal Language Models

MUB (Music Understanding Benchmark) is a set of 500 identity-masked recordings with existing annotations for tempo, key, time signature and structural intervals. It covers all 24 keys, tempos of 47 to 180 BPM and 4,676 intervals, and strips titles, artists and platform IDs from inputs. Baselines reach 53.6% tempo accuracy (DSP) and 98.4% time-signature accuracy (constant 4/4). No multimodal LLM has been tested yet, and rights clearance is unresolved.

multimodal language model
Music Understanding BenchmarkMUBarXiv

evals, multimodal, researchΒ· Added 20 Oct 2026, published 16 Oct 2026

latent.spacearticle🧠 AI

[AINews] Agents disprove Polysemanticity; greatly improve Interpretability & Alignment

The 10/14–10/15/2026 AINews issue. Its lead story is Goodfire's Nick Cammarata essay "Neural Networks Are Already Clean", which argues agentic analysis resolves many known cases of polysemanticity and superposition. Neel Nanda, Leo Gao and Jake Mendel push back. It also covers Meta's Muse Spark Open (816B total / 42B active MoE, 1M context, custom license, Artificial Analysis index 39, vLLM day-0 support and quantizations), Nemotron 3.5, MAI-Base-2 and Gemini 4 Argon evals. Further items cover Vals' refund-agent and MiMo task-leakage findings, TPUv7 and Vera Rubin inference benchmarks, Perplexity's SPACE sandbox, RL training systems (TRL tree packing, bitwise-consistent vLLM RL) and Sakana's Agentic Scientist.

Mixture of ExpertsvLLMllama.cpp+10
GoodfireNick CammarataNeel Nanda+44

ai-safety, models, researchΒ· Published and added 16 Oct 2026

arxiv.orgpaper🧠 AI

Velox: Spatial Memory Makes World Models Efficient

Velox is a training-free attention router for chunked video-diffusion world models. It uses camera frustum slabs with depth intervals from streaming geometry to pick which historical token blocks to attend to, instead of letting the KV cache grow with rollout length. Frustum overlap softly modulates each layer's model-derived block importance, and uncovered regions keep the model's own routing. The fixed block granularity suits FlashAttention-style tiled execution, and slab construction runs asynchronously with denoising on the same H200. At chunk 48 it speeds up attention 4.36Γ— and denoising 2.43Γ—, and on the 158-case WBench navigation split it stays within 0.15 average points of dense LingBot-Fast-Cam.

diffusion modelFlashAttentionCUDA
VeloxLingBot-Fast-CamWBench+1

research, multimodal, inferenceΒ· Added 17 Oct 2026, published 15 Oct 2026

latent.spacearticle🧠 AI

[AINews] Modal’s $1B ARR, $16B Series D makes it NYC’s newest AI Infra Decacorn, 3x usage and 3x valuation in 5 months, 15x in 1 yr

Latent Space's AINews issue for 10/13–10/14/2026. It opens with Modal's $750M Series D at a $15.75B valuation, with Sandboxes at a $300M run rate, then recaps the day's AI Twitter. Coverage includes the Gemini 4 Argon rollout and its weaker monitorability, Meta Muse Wonder, Grok Voice 3.0, and open-weights releases (Ultramarine 1 Flash, Ling-3.1-flash, DeepSeek V4.1 Flash). It also covers new evals (AA-Robotics, SpireClimb, TasteVal), rogue agent and reward-hack safety items, inference benchmarks (AA-AgentPerf, InferenceX), and agent sandbox platforms. Useful as a dated snapshot of the field.

vLLMSGLangOpenTelemetry+5
ModalAccelLatent Space+41

models, ai-infra, evalsΒ· Published and added 15 Oct 2026

deploymentsafety.openai.comarticle🧠 AI

GPT-Live-1.1 system card

System card for GPT-Live-1.1 and GPT-Live-1.1 Quip, OpenAI's full-duplex voice models that listen and respond continuously. It reports voice-native disallowed-content evals on production and synthetic audio prompts, and finds parity overall but statistically significant regressions for GPT-Live-1.1 on sexual, mental health, emotional reliance and gore categories. It also covers alignment evals converted to audio (respecting warnings, blocker deception, broken search tool) and Preparedness Framework conclusions: neither model is High in Biological and Chemical, Cybersecurity or AI Self-Improvement.

Codex
OpenAIGPT-Live-1.1GPT-Live-1.1 Quip+5

ai-safety, multimodal, evalsΒ· Published and added 15 Oct 2026

Showing 30 of 81

Show more