Fake crypto app on Apple App Store linked to $23K wallet theft
Padre Terminal, a fake Solana meme-coin trading app on the Apple App Store, drained about $23,000 from 27 Solana wallets after users imported private keys, per blockchain investigator Iris. The app has been removed, but the drainer stayed active; Iris traced funds to two attacker wallets holding 229.66 SOL. Iris also flagged four other suspected impersonator apps (Axiom Pro: Focus, GMGN AI, HyperTerminal-HyperliquidTools, Pump Fun Tokens & Analitycs).
 bleepingcomputer.comarticleAdded 30 Oct 2026, published 29 Oct 2026🛡️ Security
 OpenAI Launches GPT-6.1 Terra, Its Half-Good AI Model at Half the Price
GPT-6.1 Terra is OpenAI's mid-tier model, released 26 October 2026 with standard API prices 50% below GPT-5.6 Terra. At low reasoning effort its factual error rate on an internal test fell from 53.6% to 16.7%, and at maximum effort it solved 50.3% of Terminal-Bench 4.0 tasks versus 21.5%. It is available in ChatGPT Work and Codex and as gpt-6.1-terra. All figures are OpenAI's own.
 decrypt.coarticlePublished and added 26 Oct 2026🧠 AI
- Introducing GPT-6.1 Terra
GPT-6.1 Terra is OpenAI's fast, lower-cost model for visual reasoning, computer use and writing, released as API model gpt-6.1-terra. OpenAI reports Terminal-Bench 4.0 at 50.3% (GPT-5.6 Terra: 21.5%) and a low-effort error rate cut from 53.6% to 16.7%. API pricing is $1 per million input tokens and $5 per million output tokens. It meets the Critical cybersecurity threshold in OpenAI's Preparedness Framework.
 openai.comarticlePublished and added 26 Oct 2026🧠 AI
 Moonshot AI reports Kim K3.1 Pro tops rivals with 64.4 on finance test
Kim K3.1 Pro is Moonshot AI's upgrade of Kimi K3, released 23 October 2026, with 3 trillion parameters, a one million token context window and a mixture-of-experts design that activates 16 of 896 experts. Moonshot reports 64.4 on OfficeQA Pro v2 (ahead of Opus 5.5 and GPT-6 Astra), 65.7% on Terminal-Bench 4.0 and 92.7% on BenchCAD (behind both). Hallucination on an internal hard test fell from 23.4% to 8.3%. Weights are due by 4 November.
 en.cryptonomist.charticlePublished and added 24 Oct 2026🧠 AI
- AI Quanting (@AIQuanting) on X
Kimi K3.1 Pro is Moonshot AI's post-trained Kimi K3 with a 1-million-token context, plus a Highspeed variant; weights are due by 4 November. It scores 65.7% on Terminal-Bench 4.0. Moonshot removed cyber data from mid-training and RL, and exploit pass@3 on xdev-bench-hard fell from 90.5% to 81.0%. The author argues this is a modest reduction.
 x.comarticleAdded 25 Oct 2026, published 24 Oct 2026🧠 AI
 [AINews] not much happened today
AINews issue for 16 to 19 October 2026 from Latent Space, a digest of Twitter and Reddit AI news. It covers DeepSeek V4.1 Flash 1017 (552B total, 16B active MoE, AA Intelligence Index 45), MiniMax M3.1 Flash, Mercury 3, Meta Muse, Google's Harness², vLLM v0.32.0 and a Terminal-Bench audit. Only the first 40,000 of 47,045 characters were available.
 latent.spacearticleAdded 30 Oct 2026, published 20 Oct 2026🧠 AI
 [AINews] not much happened today
AINews issue covering 16-19 October 2026 from Latent Space, summarising 12 subreddits and 544 Twitter accounts. It leads with DeepSeek V4.1 Flash 1017 (552B total, 16B active MoE, 1M context, MIT license, AA Intelligence Index 45), plus MiniMax M3.1 Flash, Mercury 3 and Meta Muse. It also covers vLLM v0.32.0, InferenceX results, Harness² and Terminal-Bench audit findings.
latent.spacearticlePublished and added 20 Oct 2026🧠 AI Show HN: Gemini 4 Argon plays StarCraft
StarSkirmish Bench v0.2 gives each LLM one hour to write a Protoss StarCraft: Brood War bot in C++ (BWAPI 4.4.0 on OpenBW), with tools to compile and play practice games. Scores are average win rates of 5 runs against 13 roster bots, which include human-written bots such as Stardust, PurpleWave and BananaBrain. Nine models are compared, each in its lab's first-party CLI harness (Claude Code, Codex, Antigravity CLI, Muse Code). GPT-6 Astra leads and wins only 7% against the top human bots. The page also covers score against cost, run-to-run variance, practice behaviour as the best predictor of score, and weak correlation with the Artificial Analysis Intelligence Index and Terminal-Bench 4.0.
 starskirmish.comarticleAdded 17 Oct 2026, published 16 Oct 2026🧠 AI
 [AINews] Meta Muse Wonder & Wonder Full: MSL’s Claude 5.5-tier Frontier Model
AINews daily digest (Oct 10–12, 2026) whose top story is Meta Superintelligence Labs' launch of Muse Wonder and Muse Wonder Full. The models have a 1M context window and are priced at $4 input / $20 output per M tokens for Wonder; Full is available only to Muse Code subscribers. It compiles third-party results: Artificial Analysis Intelligence Index v4.3 (Full 56, Wonder 52, Spark 1.3 48, Opus 5.5 58), Terminal-Bench 4.0 gains, Coding Agents Index, and Vals Index ranks. It also records Meta-reported numbers (SWE-Marathon, DeepSWE, MemoryBench), bullish and skeptical practitioner reactions, the "3D demo" benchmaxxing debate, and Muse retention data. The rest of the issue is a roundup of agent RL research (QwenGyre, Sakana MASS, GitSwarm), inference silicon (Maia 300, ReplaySSM), specialised models (GLM-Legal, Decision 3.0), and r/LocalLLaMA and other Reddit threads. The page text was truncated, so the end of the Reddit recap is not covered.
latent.spacearticlePublished and added 13 Oct 2026🧠 AI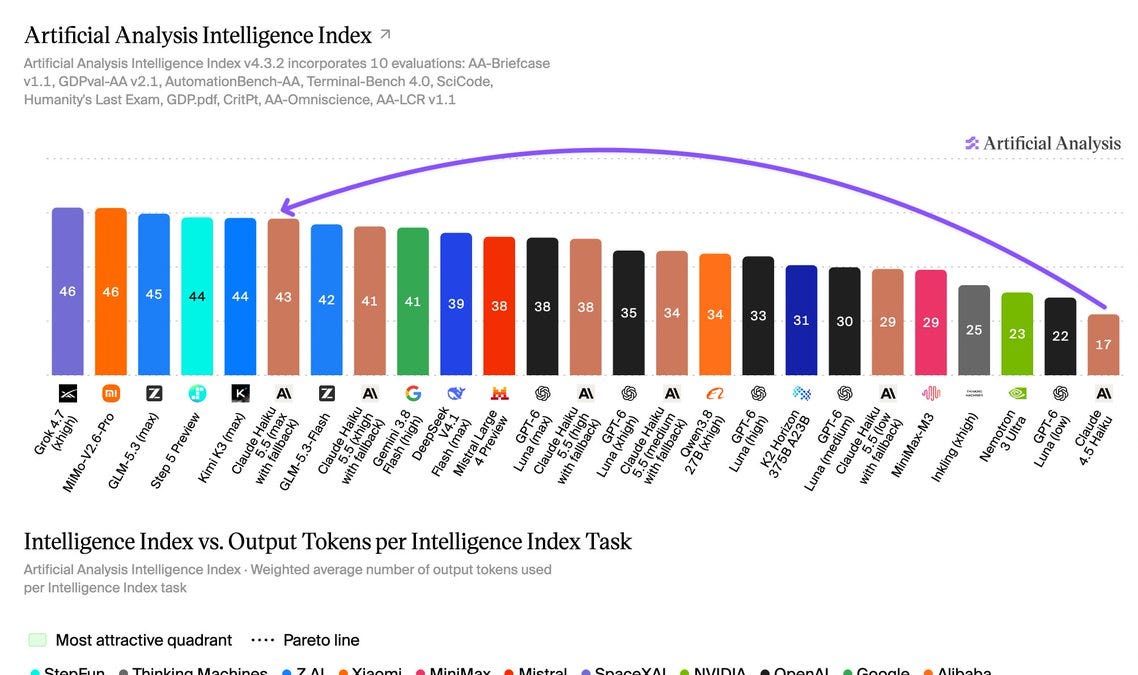 [AINews] Claude Haiku 5.5 — better than GPT-6 Luna at the same pricing
Latent Space's AINews recap covers Anthropic's launch of Claude Haiku 5.5, priced to match OpenAI's GPT-6 Luna and paired with a Sonnet 5.5 cache-read price cut and new Max/Team API credits. Independent Artificial Analysis testing puts its Intelligence Index at 43 (up 26 points from Haiku 4.5) and Terminal-Bench 4.0 at 33%, but shows it uses roughly 3x the output tokens of GPT-6 Luna at max effort, plus results on AA-Briefcase, AA-Omniscience and AutomationBench-AA, alongside a same-day Claude SDK update adding built-in computer-use/browser-use tooling.
latent.spacearticlePublished and added 8 Oct 2026🧠 AI Anthropic Launches Haiku 5.5: Its Cheapest and Fastest Claude Model Yet
Anthropic released Claude Haiku 5.5, pricing it at $0.10/$0.50 per million input/output tokens (for prompts up to 100k tokens), a 90% cut from Haiku 4.5, matching OpenAI's GPT-6 Luna pricing. The model scored 72.4% on OSWorld 2.1 and 39.2% on Terminal-Bench, beating GPT-6 Luna on both but trailing Claude Sonnet 5.5's 70.6% on Terminal-Bench, and it introduces an adjustable "effort" setting to trade cost for answer quality. Anthropic also halved Claude Sonnet 5.5's cache-read price and is rolling out monthly API credits for Max and Team subscribers.
decrypt.coarticlePublished and added 7 Oct 2026🧠 AI Introducing Mistral Large 4 ("Le Chonk")
Mistral announces Mistral Large 4 ("ML4"/"Le Chonk"), a 1-trillion-parameter natively multimodal Mixture-of-Experts model with 52B active parameters, trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own European datacenters. The post details state-of-the-art open-weight results on cybersecurity benchmarks (82% on an Artificial Analysis vulnerability-reproduction test, 93% on Cybench), agentic coding (DeepSWE, Terminal-Bench, AutomationBench), finance/legal evals (via Vals, Harvey's Legal Agent benchmark), visual grounding (beating GPT-6 Astra on Dense 200), and safety benchmarks (Lakera B3, KORA). It also describes the large-scale RL post-training pipeline (33B tokens/day at 3k GPUs) used to produce the model, with full weights promised by end of month.
 mistral.aiarticleAdded 7 Oct 2026, published 6 Oct 2026🧠 AI
 The Agent Said It Was Done. The Database Disagreed.
ThinkingBox is an agent sandbox and ThinkingBox-Bench is a 507-task stateful business-workflow benchmark (retail, auto insurance, etc.) that grades agents by checking the terminal backend database state and side effects they leave behind, not just whether tool calls succeeded or the final reply sounds right. Across 121,680 trials over 12-18 LLMs run 20 times each, the post finds most failures are clean-looking: 67% of failed trials still terminated without a tool error, yet executable checks caught wrong field values, missing effects, or unintended extra effects. It also reports pass@1 vs. 20/20 consistency gaps (e.g. Kimi K3 solves the most tasks at least once but is among the least consistent, while Claude Opus 5 and Claude Opus 5.5 are the most dependable) and cost-per-success/cost-per-dependable-task metrics, and ships the benchmark through an OpenEnv interface for reproducible evaluation.
 huggingface.coarticlePublished and added 3 Oct 2026🧠 AI
 Aleph Alpha Kolibri: How the sovereign German LLM works
A deep technical walkthrough of Aleph Alpha's Kolibri, a 78B-parameter (3.5B active) mixture-of-experts LLM for German and English released under Apache 2.0, built to be 'sovereign' (trained and deployable entirely under EU/German law). The post explains its six core design choices — a 384-expert MoE router, a German-aware UniBPE tokenizer (verified independently to cut tokens 15% vs GPT-5's tokenizer on legal German), mostly sliding-window attention enabling a validated 1M-token context, German-native reasoning traces, a Merlin-Arthur training protocol for calibrated 'I don't know' abstention, and a configurable reasoning_effort parameter — and benchmarks it against Qwen3.5/3.6/3.8, GLM-4.7 Flash, Nemotron 3 Nano and gpt-oss-120b on AIME, RULER, SWE-bench Verified, Terminal-Bench and the Omniscience test, including where it underperforms (tool calling, coding agents, trivia recall).
 tej.asarticlePublished and added 3 Oct 2026🧠 AI
 Introducing Claude Sonnet 5.5
Anthropic announces Claude Sonnet 5.5, a faster (30%+) and cheaper-per-task successor to Sonnet 5 at the same $2/$10 per million token pricing. It reports 70.6% on Terminal-Bench 4.0 (vs 10.3% for Sonnet 5), near-Opus 5.5 results on GDPval-AA and CursorBench, a +10 point FrontierCode gain at roughly 1/15 the cost per task, and cost-vs-effort curves. It also covers alignment audit results, new cyber safeguards with fallback to Sonnet 5, distillation classifiers and expanded preserved thinking, plus the migration note for the new between_tools thinking setting.
 anthropic.comarticleAdded 1 Oct 2026🧠 AI
- Introducing GPT-6.1 Sol
OpenAI announces GPT-6.1 Sol, an upgrade to GPT-6 Sol that approaches GPT-6 Astra on agentic coding, computer use and professional work at about one-fifth the price ($2/$10 per million input/output tokens, $0.10 cached input; API id gpt-6.1-sol). It reports results on DeepSWE v1.1 (matches Astra), GDP.pdf, AutomationBench (+2.2 pts over Opus 5.5), OSWorld 2.0 offline, Terminal-Bench Science 0.1 ($5.47 per task vs $23+ for Opus 5.5/Astra) and a factuality eval where errors drop from 11.4% to 7.7% at low effort. Also covers alignment evals, availability in ChatGPT Work and Codex, and an upcoming Ultrafast mode in Codex with up to 8x faster generation.
openai.comarticlePublished and added 29 Sep 2026🧠 AI  Anthropic's Claude Sonnet 5.5 Is Out, Beats Opus 5.5 at Coding for Half the Price
Anthropic released Claude Sonnet 5.5, priced the same as Sonnet 5 ($2/$10 per million input/output tokens, half of Opus 5.5) but outperforming Opus 5.5 on Terminal-Bench 4.0 (70.6% vs 66.4% per Anthropic; 63.6% vs 59.6% per independent tester Artificial Analysis). The piece details how effort-setting (Medium vs High vs Max) drastically changes cost-per-task — Sonnet 5.5 at max effort burns ~193K tokens per task, more than any model Artificial Analysis has tested, undercutting Anthropic's claimed savings — and notes Sonnet 5.5 ties Opus 5.5 on GDPval-AA (real-world professional work) while Opus remains stronger on sustained-judgment tasks. Claude Haiku 5.5 is teased for coming weeks.
decrypt.coarticleAdded 30 Sep 2026, published 28 Sep 2026🧠 AI Welcome RL Environments to the hub
Hugging Face announces that RL environments — tasksets used to train or evaluate agents — can now live as ordinary dataset repos tagged `rl-environment`, surfaced via a new filter on the Hub instead of each framework maintaining its own registry. Four frameworks (Harbor, Verifiers, OpenEnv, NeMo Gym) get dataset-library tags that auto-generate run snippets, and the post walks through concrete commands to run a reference solution or a model agent against the same task directory (e.g. terminal-bench-2.1) and read back the verifier's reward. It also lists already-tagged environments like BeyondSWE, Multi-SWE-RL-Verified, R2E-Gym-Subset-Verified, Scale-SWE-Verified, and NeMo Gym's Workplace Assistant and Structured Outputs tasksets.
huggingface.coarticleAdded 8 Oct 2026, published 28 Sep 2026🧠 AI Claude Opus 5.5
Anthropic announces Claude Opus 5.5, the first model in the Claude 5.5 family, claiming performance comparable to Claude Fable 5.1 at 40% lower cost than Opus 5, with input/output pricing at $4/$20 per million tokens and cache reads at $0.20/million. The post details agentic-coding gains against GPT-6 Astra and GPT-5.6 Sol on benchmarks like FrontierCode, Terminal Bench 4.0, CursorBench, and GDPval-AA v2.1, plus a safety section covering an automated behavioral audit, an ~85% reduction in sandbox-escape/containment-boundary attempts versus Opus 5 and Claude Mythos 5.1, Gray Swan prompt-injection results, and new cyber/biology safeguards alongside the "preserved thinking" anti-distillation mechanism.
anthropic.comarticleAdded 27 Sep 2026🧠 AI- Introducing Claude Opus 5.5
Anthropic's announcement of Claude Opus 5.5, the first model in the Claude 5.5 family, positioned to match Claude Fable 5.1 performance at 40% lower cost than Opus 5 ($4/$20 per million input/output tokens, $0.20 cache reads). The post details agentic coding gains (e.g., a 680,000-line code migration completed in under a day), efficiency improvements across partner benchmarks (FrontierCode, Terminal Bench 4.0, CursorBench, GDPval-AA v2.1), and alignment/safety results from an automated behavioral audit plus new cybersecurity, biology, and anti-distillation safeguards (preserved thinking) similar to those applied to Fable 5.1.
anthropic.comarticleAdded 26 Sep 2026🧠 AI  Terminal-Bench 4.0
 is a versioned update to the Terminal-Bench agentic coding benchmark and leaderboard, calibrating task resource limits (timeouts, CPU, memory) using a noise-quantification methodology, removing 8 saturated/flawed tasks, and fixing 19 others. It's built on the Harbor framework and available on the Harbor Hub, with Terminal-Bench now versioned as a continuously maintained (semantic-versioned) benchmark rather than discrete "sequel" releases.
 tbench.aiarticleAdded 26 Sep 2026🧠 AI
 Marimo Notebook Flaw Could Run MCP Commands Before Cells Execute in Edit Mode
The Hacker News details CVE-2026-75149, a high-severity (CVSS 8.8) code injection flaw in Marimo notebooks where a crafted notebook's configuration could supply an attacker-controlled MCP server command that runs as a local subprocess as soon as the notebook is opened in edit mode, before any cell executes. Marimo fixed it in version 0.23.15 by treating notebook metadata as untrusted and allowlisting configuration, stripping ai/mcp/completion/secrets/server sections; the article also covers the related CVE-2026-67618 (AI base_url exfiltrating API keys via notebook metadata) and the earlier CVE-2026-39987 (unauthenticated /terminal/ws endpoint granting a full PTY shell).
 thehackernews.comarticleAdded 26 Sep 2026🛡️ Security
 Critical Cursor Flaws Could Let Prompt Injection Escape Sandbox and Run Commands
Cato AI Labs disclosed DuneSlide, two critical (CVSS 9.8) Cursor flaws — CVE-2026-50548 and CVE-2026-50549 — that let a zero-click prompt injection (via MCP servers or web search results read by the agent) escape Cursor's terminal sandbox and achieve arbitrary command execution. Both abuse the file-write allowlist logic: one via the run_terminal_cmd tool's working_directory parameter, the other via a symlink-resolution fallback that trusts an in-project path when the real-path check fails; both let an attacker overwrite Cursor's sandbox helper binary or startup files like ~/.zshrc to disable the sandbox entirely. Fixed in Cursor 3.0 (April 2), affecting all prior 2.x versions; the piece also situates this alongside earlier Cursor agent-exploitation chains (CurXecute/CVE-2025-54135, MCPoison/CVE-2025-54136, CVE-2026-26268).
thehackernews.comarticleAdded 26 Sep 2026🛡️ Security [AINews] The Future of Latent Space
The daily AINews digest from Latent Space rounds up a heavy week in AI: Claude Opus 5.5 topping SimpleBench and Terminal-Bench-Science, the GPT-6 family (Astra/Sol/Luna), Gemini 3.8 Flash, and Xiaomi's open-weight MiMo-V2.6-Pro; TypeSafe's Jev system-one decision model (and open alternatives like CLM) for cheap structured judgments; agent-infra launches from LangChain Interrupt and Perplexity's Rust retrieval engine Photon; inference speedups like Liquid AI's DSpark speculative decoder and GLM-5.3 on AMD MI355X; and research on harness distillation, agent failure modes, and autonomous-science efforts led by Sakana AI's RSI Lab with Jurgen Schmidhuber.
latent.spacearticleAdded 29 Sep 2026, published 25 Sep 2026🧠 AI How UK AISI and EvalEval Are Making Benchmark Results Reproducible
UK AI Security Institute (AISI) and the EvalEval Coalition describe a collaboration to make AI benchmark results reproducible: AISI is publishing verified evaluation results, configuration details, and transcript-level data through EvalEval's Evaluation Cards platform, using the shared Every Eval Ever (EEE) reporting schema. The release covers five benchmarks (HealthBench, FrontierMath, Humanity's Last Exam, SWE-Bench Pro, Terminal-Bench 2.0) across six frontier models (Claude Opus 4/4.5/4.6, GPT-5/5.2/5.4), plus two cyber evaluations (Cyber CTFs, The Last Ones), accompanying AISI's paper on how inference compute and evaluation protocol shape benchmark performance.
huggingface.coarticleAdded 29 Sep 2026, published 22 Sep 2026🧠 AI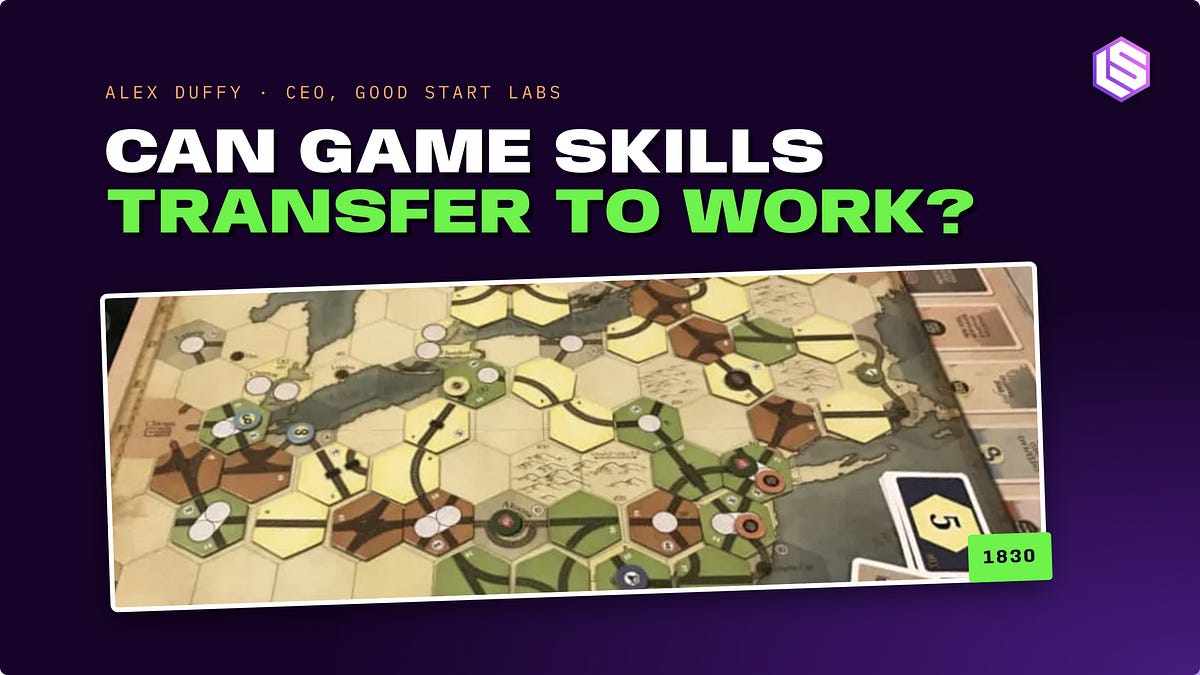 Can Skills Learned in Games Transfer to Real-World Work?
Interview with Good Start Labs co-founder Alex Duffy on training LLMs inside games like Diplomacy and 1830: The Game of Railroads and Robber Barons as reinforcement-learning environments with verifiable rewards. The company found that a multi-turn terminal-agent harness playing 1830 improved performance on the Finance-Agent benchmark, while single-turn Q&A training did not, suggesting that harness design — not just the game itself — determines whether in-game skills transfer to real-world agentic tasks like financial research and customer support.
latent.spacearticleAdded 29 Sep 2026, published 15 Sep 2026🧠 AI Granite 4.2 LLMs: How They're Built
IBM's technical write-up on Granite 4.2, its first family of dense decoder-only reasoning LLMs (3B, 8B, 30B), post-trained from Granite-4.1 base models pretrained on ~15T tokens with a five-phase schedule extending context to 512K tokens. It details the SFT data mixture (agentic vs. non-agentic, quality filtering with LLM judges GPT-OSS-120B and Gemma 4), a staged asynchronous-GRPO RL pipeline (RLVR, skill boosters, then agentic SWE/Terminal/Search stages for 8B/30B, finishing with RLHF), and the NeMo-RL/NeMo-Gym infrastructure used to run tool-using RL rollouts at scale, plus FP8/NVFP4/MXFP4/GGUF quantized releases and integration guides for vLLM, SGLang, OpenCode, Pi, and OpenHands.
huggingface.coarticleAdded 29 Sep 2026, published 25 Aug 2026🧠 AI Xygeni Malicious Code Digest 82
Xygeni's weekly malicious-package digest covers 206 confirmed malicious npm/PyPI/OpenVSX packages between July 31 and August 7, 2026. Highlights include wormgpt-cli and gpt-terminal-cli on npm (branded after the real WormGPT dark-LLM tool, nine versions published in one day), a dependency-confusion cluster of nine packages impersonating crypto wallet/signing libraries (ledger-lib, trezor-lib, bip32-js, ethers-lib, python-bitcoinlib, ckcc-protocol, hwi-lib, mnemonic-utils, ethereum-sign-utils), and QuietPolyfill — a three-stage dropper hidden in a beaver-ui-*/accounts-* package cluster that executes on require() rather than via an install script, so --ignore-scripts does not block it.
 xygeni.ioarticlePublished and added 8 Aug 2026🛡️ Security
 JFrog: Why Model Routing Backfires and How to Build Agents That Don't Burn Your Budget
A JFrog blog post explaining why routing to cheaper models (e.g. Claude Haiku) mid-session in an agentic loop can backfire: provider prompt caches (like Anthropic's ~90% discount on cached input tokens) are model-specific, so switching models, enabling gateway auto-routing, or modifying tools/system prompts mid-conversation invalidates the cache and forces a full-cost reprocessing of accumulated history. It recommends session-level fixes — short sessions, an orchestrator/subagent architecture for model diversity, and deliberate summarized handoffs before any model switch — and pitches JFrog Boost, a CLI that compacts terminal output to reduce context bloat and cache-miss penalties.
 jfrog.comarticleAdded 22 Sep 2026, published 23 Jul 2026🧠 AI
 Beyond MCP: The New Security Playbook for Coding Agents | Blog | Endor Labs
Endor Labs breaks down the expanding attack surface of coding agents beyond MCP tools — covering CLI/terminal action risks, Anthropic 'skills', and the 'lethal trifecta' threat model (untrusted input + private data access + external connectivity) — then surveys three defense categories: full sandboxing (Seatbelt, sandbox-exec, bubblewrap, cloud sandbox vendors like Runloop/Daytona/Modal), MCP gateways/proxies, and the newer agent-hooks approach used by Cursor's security partners. The authors detail their own FireMCP prototype, an MCP gateway that isolates each MCP server individually using FireJail inside a FireCracker microVM to prevent cross-MCP-server attacks, with source published on GitHub.
 endorlabs.comarticleAdded 3 Sep 2026, published 21 Jul 2026🛡️ Security
 Introducing Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber
Google DeepMind announces Gemini 3.6 Flash (a workhorse model with 17% lower output-token usage and up to 65% reduction on DeepSWE vs. 3.5 Flash, priced at $1.50/$7.50 per 1M tokens), Gemini 3.5 Flash-Lite (fastest 3.5-class model at 350 output tokens/s, $0.3/$2.5 per 1M tokens, outperforming 3 Flash on SWE-Bench Pro and OSWorld-Verified), and Gemini 3.5 Flash Cyber, a specialized model paired with the CodeMender agent for finding and patching vulnerabilities, benchmarked on CyberGym and gated to a limited-access pilot for governments and trusted partners. The post details benchmark comparisons across DeepSWE, MLE Bench, OSWorld-Verified, GDPval-AA v2, Terminal-Bench 2.1, and GDM-MRCR v2, new built-in computer-use tooling, enhanced Frontier Safety jailbreak resistance, and previews upcoming Gemini 3.5 Pro and Gemini 4 pre-training.
 deepmind.googlearticleAdded 29 Sep 2026, published 21 Jul 2026🧠 AI
- Attackers Didn’t Wait for AI. They Built Workflows Around It.
Huntress details three real-world patterns where attackers build workflows around AI adoption rather than attacking AI models themselves: SEO-poisoned/malvertised fake "Claude Code" downloads that deliver credential-stealing malware, an AMOS stealer campaign that spoofs ChatGPT/Grok-style answer pages to trick macOS users into running malicious Terminal commands (ClickFix-style), and the EvilTokens phishing-as-a-service platform, which used Railway infrastructure for on-demand session-token theft and AI-generated, role-tailored phishing lures that bypass email filtering. The piece argues AI isn't the weapon but the accelerant, making malicious activity blend into trusted, expected workflows.
 huntress.comarticleAdded 3 Sep 2026, published 22 Apr 2026🛡️ Security
- That “Friendly” Prompt is ClickFix
Huntress overview of ClickFix, a social-engineering technique that tricks users into pasting and executing attacker-supplied commands into PowerShell, Run dialogs, or terminals (via fake CAPTCHA/human-verification or tech-support lures) rather than delivering malware through links or attachments. The post cites Huntress 2026 Cyber Threat Report data showing ClickFix accounts for over 50% of malware loader activity and walks through variant types and a real intrusion chain leading to LummaC2 infostealer compromise.
huntress.comarticleAdded 3 Sep 2026, published 25 Mar 2026🛡️ Security