Skip to content

183 results for β€œConstruct”

What you seeeverything
rekt.newswriteupπŸ›‘οΈ Security

Rekt - SingularityNET - Rekt

SingularityNET exploit (19 September 2026): attackers with signing authority exposed through a cloud infrastructure breach drained 8.72M FET from the Ethereum bridge converter, then minted about 2.3 billion AGIX, NTX, WMTX and CGV. Rekt's transaction-level reconstruction puts gross liquid proceeds near $2.29M, not the $16.77M headline, and traces laundering via Chainflip, Baltex and THORChain. It notes conversionIn() skipped checkLimits() and trusted a single EOA signature.

EthereumCardanoUniswap+2
SingularityNETASI AllianceFetch.ai+19

Blockchain, Cloud & InfraΒ· Added 29 Oct 2026

arxiv.orgpaper🧠 AI

Decompose, Estimate, Select: Coverage-Aware Context Construction for Long-Form RAG

Decompose, Estimate, Select is a coverage-aware retrieval pipeline for long-form RAG. It splits a query into subquestions, ranks candidates with a coverage-trained bi-encoder, predicts a document-by-subquestion coverage matrix with a cross-encoder, and picks documents by greedy maximum-marginal coverage. On TREC RAG 2024, Ξ±-nDCG@10 rises from 0.625 to 0.702 (gold-nugget bound 0.718). A grounded self-feedback loop raises V_strict by 0.086 over two passes.

RAGbi-encodercross-encoder+1
TREC RAG 2024Ξ±-nDCG@10V_strict

llm-apps, researchΒ· Added 31 Oct 2026, published 29 Oct 2026
arxiv.orgpaper🧠 AI

RetroChessBench: A Benchmark for Reconstructing and Proving Chess Histories

RetroChessBench is a 12-task benchmark for retrograde chess: reconstructing legal game histories, exact-length constructions, unique endings and exhaustive answer sets, with references, rubrics and a terminal-reward RL environment. GPT 6 Astra High fails to give the required final answer in 22 of 24 attempts without tools and 18 of 24 with code execution. Mean terminal RL rewards are 14.75% and 27.19%. The authors link the failures to scarce worked derivations in web training data.

GPT-6 AstraLLM
RetroChessBench

evals, researchΒ· Added 31 Oct 2026, published 29 Oct 2026

arxiv.orgpaper🧠 AI

AxisQ: Depth-Adaptive Channel--Frequency Quantization for Camouflaged Object Detection

AxisQ is a post-training quantization framework for camouflaged object detection (COD) that allocates activation bits by feature depth. It uses the channel domain for shallow features and the local-frequency domain for deep features, under a fixed per-layer average bit budget. It adds a boundary-aware Hessian approximation for reconstruction. On CAMO at W2A2, weighted F-measure improves 12.7% for CFRN and 33.3% for CamoFormer-P over the strongest baselines.

CNNTransformer
AxisQCFRNCamoFormer-P+1

research, inference, multimodalΒ· Added 28 Oct 2026, published 27 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Alg\{Ossa\}: Decentralized Secure Aggregation with Rotating Committees and Eventual Delivery

AlgOssa is a decentralized secure aggregation protocol built on Ossa, a generic committee-aided, single-server construction for one-shot clients (following OPA and Willow, CRYPTO 2025). Ossa realizes secure aggregation with non-selective abort against a malicious server. AlgOssa adds Algorand-style sortition to rotate leaders and committees, bounds the chance of an honest server, and gives eventual delivery. Classical and post-quantum routes are evaluated.

Algorand
OssaAlgOssaOPA+2

otherΒ· Added 28 Oct 2026, published 27 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Then there is prompt injection, a malicious email, ...: The Wild Wide West of OpenClaw Agentic System Security

An empirical study of security concerns in the OpenClaw AI personal assistant framework, using 25K+ posts from 13 subreddits (162 security-relevant) and 358 security-tagged GitHub issues (180 retained). It maps 521 CWE instances across 59 weakness types, concentrated in access control, sensitive-data exposure, injection and unsafe execution. It extracts 543 practitioner mitigations into seven strategies and reconstructs a sensitive-data exposure path with dummy secrets.

OpenClawGitHubLLM
prompt injectionCWEtrust boundaries+1

AI SecurityΒ· Added 28 Oct 2026, published 26 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Private Information Retrieval with Accountability at Erasure-Optimal Server Redundancy

SynTrace is a single-round compiler that adds accountability to linear private information retrieval (PIR). The client mixes the retrieval query with m audit queries, so audit syndromes identify up to d deviating servers among t colluding ones before reconstruction. The paper proves perfect query privacy and zero false identification within the threshold. For Shamir-based PIR it needs k=t+d+1 servers. For a 32 KiB record from a 1 GiB database it uses 2.25 MiB, against 8.96 MiB for the Eriguchi, Kurosawa and Nuida (TCC 2022) homomorphic-MAC construction.

SynTraceEriguchi-Kurosawa-Nuida homomorphic MACTCC 2022

otherΒ· Published and added 26 Oct 2026

arxiv.orgpaper🧠 AI

SymLift: Neural Semantic Lifting for Compile-Free Vulnerability Detection in Context-Incomplete Code Fragments

SymLift is a compile-free vulnerability detection framework for code fragments that lack project context. A fine-tuned LLM reconstructs control-flow, data-flow, memory and resource relations as a constrained LLVM-like IR, and a deterministic parser turns it into facts for Datalog rules that give findings with derivation traces. SymLift-Qwen-7B reaches 94.41% Target-F1 on FormAI and 91.66% micro-averaged Target-F1 on MegaVul.

LLMQwenDatalog+3
SymLiftSymLift-Qwen-7BFormAI+2

research, trainingΒ· Added 28 Oct 2026, published 25 Oct 2026

arxiv.orgpaper🧠 AI

IntentDelta: A Human-Constructed Benchmark for Evolving User Intent

IntentDelta is a human-constructed multi-turn benchmark of 638 trajectories and 3,766 turns across WebShop and TravelPlanner. Each turn pairs a user utterance with a cumulative intention state and human reference actions. Across eleven agents, average Intention Recovery is 33.1% in TravelPlanner and 44.7% in WebShop, and average Action Score is 31.6% and 41.0%. Agents lose earlier requirements and confuse soft preferences with must-have constraints.

LLM
IntentDeltaWebShopTravelPlanner+1

evals, agents, researchΒ· Added 27 Oct 2026, published 24 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Extraction meets Distillation - cryptanalytic techniques to recover parameters from a Deep Neural Network

Extraction meets Distillation is an IACR ePrint paper (2026/2628, CSCML 2026) that combines cryptanalytic weight-direction extraction with label-based distillation to reconstruct fully connected neural networks. It adapts a ReLU extraction implementation to Leaky ReLU and proves conditional bounds for direction recovery and sign selection. On CIFAR-10 victims, reconstructed models reach 56.40% and 58.29% agreement. It separates label requests from privileged access and notes that prediction agreement does not identify parameters.

ReLULeaky ReLU
CSCML 2026CIFAR-10

AI SecurityΒ· Added 26 Oct 2026, published 24 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

When Elliptic-Curve Semiprimality Certificates Reveal Factors

The paper formalizes elliptic-curve semiprimality certificates by adapting the Goldwasser-Kilian primality criterion. For certificates built with complex multiplication, a norm-lattice reconstruction factors N from (N, S, D) alone in expected polynomial time. The author uses it, plus public-point and quadratic-twist attacks, to factor Reble's 1084-digit and Broadhurst's 5061-digit moduli, and shows that hidden-cofactor, withheld-CM-map and private-isogeny repairs also fail.

Goldwasser-Kilian primality criterionReble modulusBroadhurst modulus+4

otherΒ· Added 26 Oct 2026, published 24 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Tight Post-Quantum Multi-Key Security of the FX Construction

Rentaro Shiba and Tetsu Iwata prove a tight multi-key security bound for the FX construction (the DESX generalization) in the quantum ideal cipher model. Security holds up to about 2^((n+ΞΊ)/3) total classical and quantum oracle queries against fully adaptive adversaries, for any number of keyed instances ΞΌβ‰₯1. This improves their ToSC 2026 bound and matches the offline Simon's algorithm attack in the exponent.

FX constructionDESXoffline Simon's algorithm+4

otherΒ· Added 24 Oct 2026, published 23 Oct 2026

arxiv.orgpaper🧠 AI

Tampered ML: Evaluating LLM Judgment of Machine Learning Research

Tampered ML is a benchmark of 1,858 item-pairs, each pairing an experiment proposal reconstructed from a published ML paper with a minimally edited version that adds a targeted methodological flaw. Models must pick the sounder proposal in both presentation orders. A human study estimates 86% of items are valid (95% CI 81-91%). Opus 5 reaches 77.9% accuracy, and models are sensitive to order and favor flawed designs that look more specific, transparent, or conventional.

LLM
Tampered MLOpus 5arXiv

evals, ai-safety, researchΒ· Added 26 Oct 2026, published 23 Oct 2026

dfir.chwriteupπŸ›‘οΈ Security

Field Notes: Reconstructing an Attacker’s Workflow

Field note from dfir.ch on PowerShell scripts an attacker left on disk during an incident: a file-watching command runner using Invoke-Expression, a fake Windows credential prompt that validates passwords via Start-Process and logs them in cleartext, AD computer enumeration with WMI access testing, and SMB share discovery via NetShareEnum. It notes where script labels overstate what they prove and lists hunting strings for Event IDs 4104, 4103, 4688 and Sysmon 1.

PowerShellActive DirectoryWMI+2
TerminalFixClickFixMicrosoft+7

Blue Team & Detection, Offensive SecurityΒ· Added 24 Oct 2026, published 22 Oct 2026

latent.spacearticle🧠 AI

[AINews] OpenAI’s Patch the Planet program is 1 of 2 parties to discover PHP2Shell vulnerabilities in core PHP affecting 70% of the web, using GPT-5.6 Sol; coordinated response over 2 months

This AINews issue (20 to 21 October 2026) leads with PHP2Shell, two PHP-engine memory-corruption bugs (CVE-2026-109618 and CVE-2026-109619). Calif researchers found them with GPT-5.6 Sol under OpenAI's Patch the Planet, and Wiz reportedly found them independently with Gemini 4 Argon. It reconstructs the two-month coordinated response, Cloudflare WAF stopgaps and NSA guidance, and the dispute over vetted researcher access to models. Only the first 40,000 of 114,281 characters were reviewed.

PHPWordPressDrupal+6
CVE-2026-109618CVE-2026-109619OpenAI+18

ai-policy, modelsΒ· Added 23 Oct 2026, published 22 Oct 2026

latent.spacearticleπŸ›‘οΈ Security

[AINews] OpenAI’s Patch the Planet program is 1 of 2 parties to discover PHP2Shell vulnerabilities in core PHP affecting 70% of the web, using GPT-5.6 Sol; coordinated response over 2 months

AINews issue of 20-21 October 2026 whose top story reconstructs PHP2Shell (CVE-2026-109618, CVE-2026-109619), two PHP-engine memory-corruption bugs with reported pre-auth RCE against WordPress, Drupal and Joomla. It covers the two-month coordinated disclosure, independent discovery by Calif/OpenAI (GPT-5.6 Sol) and Wiz, Cloudflare WAF stopgaps and NSA guidance. It flags missing primary sources: fixed versions, CVSS and leak details.

PHPWordPressDrupal+3
CVE-2026-109618CVE-2026-109619PHP2Shell+9

AppSec, AI SecurityΒ· Published and added 22 Oct 2026

latent.spacearticleπŸ›‘οΈ Security

[AINews] OpenAI’s Patch the Planet program is 1 of 2 parties to discover PHP2Shell vulnerabilities in core PHP affecting 70% of the web, using GPT-5.6 Sol; coordinated response over 2 months

AINews issue of 20-21 October 2026 whose top story reconstructs PHP2Shell, two PHP-engine memory-corruption flaws (CVE-2026-109618 and CVE-2026-109619) with reported pre-auth RCE against WordPress, Drupal and Joomla. It covers the two-month coordinated response, separate discovery by Calif/OpenAI (GPT-5.6 Sol) and Wiz (Gemini 4 Argon), Cloudflare's WAF stopgap and NSA guidance. It lists open gaps: fixed versions, leak details, exploitation versus scanning.

PHPWordPressDrupal+3
CVE-2026-109618CVE-2026-109619PHP2Shell+12

AppSec, AI SecurityΒ· Added 23 Oct 2026, published 22 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

SoK: Design-Level Backdoors in Block Ciphers Constructions, Detection, and Key Recovery

SoK on design-level backdoors in block ciphers. It places four published designs (Rijmen and Preneel, Paterson, Bannier and Filiol, Peyrin and Wang) in one taxonomy and gives a sound algorithm that recovers a partition trapdoor from S-box tables. It attacks KG-DES, BEA-1 and LowMC-M: KG-DES key recovery takes minutes, and the LowMC-M MALICIOUS backdoor yields the key from 35 to 409 queries. Trapdoors hidden in linear layers leave no trace, so the authors recommend deriving constants verifiably from a public seed.

KG-DESBEA-1LowMC-M+2
Rijmen and PreneelPatersonBannier and Filiol+5

otherΒ· Added 24 Oct 2026, published 21 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Protection Is Not One Event: A Survey of RAG Protection Research by Measured Endpoint

Survey and human-coded evidence map of 118 RAG defense papers, organized by measured endpoint across a seven-family taxonomy (content disclosure, formal privacy proxies, access control, corpus-use detection, pipeline integrity). Only 17.8% of studies use disclosure or reconstruction as the primary endpoint, and most use non-adaptive attacks on general QA data. A testbed shows a normalized 8-gram guard cuts 20-token copying to 0.0%, yet a three-query adaptive attacker recovers 48.3% of hidden facts on Qwen3-8B.

QwenLLM
prompt injection

AI SecurityΒ· Added 24 Oct 2026, published 21 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Reverse Engineering IVXV: A Specification and Security Analysis of Estonia’s Internet Voting System

Reverse Engineering IVXV is an October 2026 ePrint paper by Tingfeng Yu and Thomas Haines that reconstructs a specification of Estonia's IVXV internet voting system from public source code and documentation, with an executable TLA+ model checked in TLC. It analyses individual and universal verifiability, privacy, coercion resistance and eligibility, compares IVXV with Belenios and Swiss Post, and reports new vulnerabilities, some confirmed with proof-of-concept tests, plus mitigations.

IVXVTLA+TLC
EstoniaBeleniosSwiss Post+2

AppSecΒ· Added 24 Oct 2026, published 21 Oct 2026

arxiv.orgpaper🧠 AI

Code2Video-Compass: A Comprehensive Benchmark for General-Purpose Code-Based Video Generation across T2V, I2V, and V2V

Code2Video-Compass is a benchmark of 2,104 tasks for code-based video generation, where multimodal LLMs write executable programs that produce complete videos from text (T2V), image (I2V) or video (V2V) inputs. Tasks span 10 categories and 24 subtypes. Scoring uses 12 objective metrics and five MLLM-judge metrics. Across 15 proprietary and open-weight models from nine families, performance falls as construction, dynamic animation and state-dependency complexity rise.

vision-language modelLLM
Code2Video-CompassarXiv

evals, multimodal, researchΒ· Added 22 Oct 2026, published 20 Oct 2026

depthfirst.comwriteupπŸ›‘οΈ Security

From JavaScript to Renderer Code Execution: Three V8 Vulnerabilities and Two v8CTF Flags | depthfirst

Depth First Security's write-up describes three V8 bugs found using its dfs-large1 research tooling: CVE-2026-78938, a type confusion in Promise.prototype.finally that lets an internal helper be constructed and return a primitive; CVE-2026-79236, a TurboFan load-elimination bug that keeps a stale property-array pointer after object migration; and a shared WebAssembly memory sandbox escape (issue 546253900) caused by mismatched backing-store registration during serialization. It walks through turning each memory bug into addrof/fakeobj primitives, chaining either with the sandbox escape to reclaim a freed V8 isolate via a WebSocket allocation, and pivoting through a CFI-constrained ROP chain to achieve Chrome renderer code execution, earning two v8CTF flags. Fixes landed between August 20 and 25, 2026.

V8ChromeWebAssembly+1
CVE-2026-78938CVE-2026-79236issue 546253900+8

Offensive Security, Malware & REΒ· Added 29 Oct 2026, published 20 Oct 2026

arxiv.orgpaper🧠 AI

How Benchmark Graph Construction Shapes Multi-Hop KG Navigation: A Controlled Audit of PathQuestion and PathQuestion-Large

This paper audits the PathQuestion (PQ) and PathQuestion-Large (PQL) multi-hop knowledge-graph QA benchmarks as graph-navigation tasks. It holds questions, answers, path annotations and splits fixed, and replaces each released task-filtered graph with the larger source KG. Restoration cuts released-answer accuracy and trajectory fidelity for frozen small-language-model policies and trained MINERVA policies, and graph-consistent evaluation recovers only part of the loss.

MINERVA
PathQuestionPathQuestion-LargearXiv

evals, researchΒ· Added 21 Oct 2026, published 19 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Concrete LDVR Attacks with Fewer Signers

Concrete LDVR Attacks with Fewer Signers is an ePrint paper by Renas Bacho on the low-dimensional vector representation (LDVR) problem behind adaptive security of threshold Schnorr. It combines a Chinese remainder theorem construction with a generalized birthday search to attack 488 signers with 173 corruptions over the Curve25519 scalar field, down from 5,020 signers. For adversarial evaluation points, it reaches optimal success probability and breaks 228 signers with 114 corruptions in 168.60 seconds.

Threshold SchnorrCurve25519SHA-512
LDVRgeneralized birthday attacksubset sum+4

otherΒ· Added 20 Oct 2026, published 19 Oct 2026

newsletter.semianalysis.comarticle🧠 AI

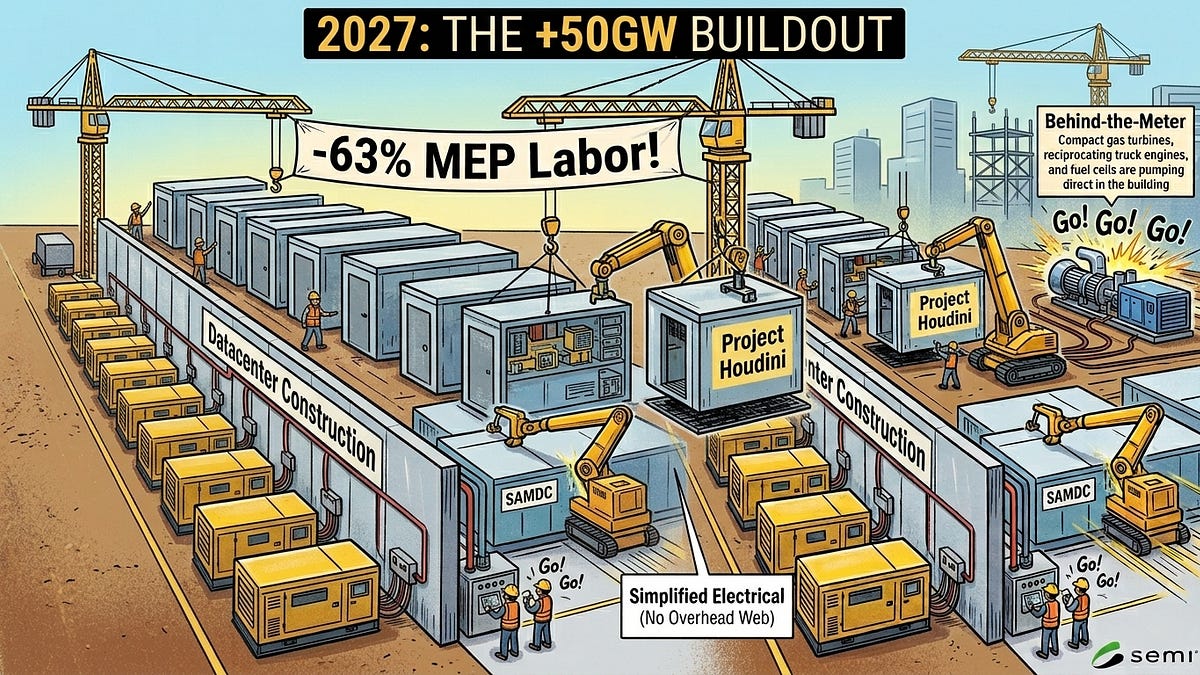
Datacenters 2027: The Year of Acceleration, +50GW in a Single Year

SemiAnalysis argues that global AI datacenter capacity will grow by about 50GW in 2027, against Brad Gerstner's guess of roughly 25GW. Evidence cited: over 24GW in advanced construction across 40 campuses, nearly USD 1T of binding leases signed in 2026, and record self-build starts. It also covers modular "LEGO" designs, behind-the-meter power and ex-US growth. The page text cuts off before the oversupply section.

Behind-the-meter generationModular datacentersPrefabricated electrical modules+2
SemiAnalysisBrad GerstnerAltimeter+20

ai-infra, ai-policyΒ· Added 29 Oct 2026, published 19 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Revisiting the Security of VDOO

Revisiting the Security of VDOO is an ePrint paper (October 2026) on VDOO, a multivariate signature scheme submitted to China's NGCC program. It models VDOO as a multilayer Rainbow construction, keeps only the last oil space to get a generalized UOV instance, and applies wedge attacks. For the 512-bit parameter set it estimates 2^432 gates (reconciliation) and 2^379 gates (intersection), below the claimed level and the specification's figures.

VDOORainbowUOV
NGCCwedge attackreconciliation attack+1

otherΒ· Added 19 Oct 2026, published 18 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Zippel: A Language, Compiler, Runtime, and Analyzer for ZK Proof Systems

Zippel is a language, compiler, runtime and analyzer for writing zero-knowledge proof systems in syntax close to the pseudocode in cryptography papers. Its type system and runtime remove vulnerability classes by construction, for example by synchronizing transcripts automatically and applying the Fiat–Shamir transform correctly. Its static analyses check completeness and soundness from the protocol description alone. The authors implemented 35 proof systems, including Sumcheck, Schnorr, KZG, Groth16, Bulletproofs, Hyrax, Spartan, Dory, HyperPlonk, DeKART and Pari. They report performance competitive with hand-written multi-core implementations.

ZippelRust
Fiat–Shamir transformSumcheckSchnorr+9

AppSecΒ· Added 17 Oct 2026, published 16 Oct 2026

anthropic.comarticle🧠 AI

Designing more efficient quantum circuits with Claude

Anthropic describes giving Claude Mythos 5 plain-language specs for eight quantum-circuit primitives plus an automated evaluator that checks and scores designs (qubits Γ— gates). Working in a closed loop with little human input, Claude found designs that beat the best published circuits, sometimes by 10x or more. Two examples: a reversible divsteps modular inversion for elliptic-curve point addition, found in a 53-hour run and verified in Lean, and a Berlekamp–Massey Reed–Solomon decoder for decoded quantum interferometry that cuts gate count about 12x versus Google's construction. The post also covers limitations such as Claude's conservatism and the mitigations used.

ClaudeLean
AnthropicClaude Mythos 5Andi Gu+9

research, agentsΒ· Added 17 Oct 2026, published 16 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Analysis of the Multi-Key Optimization for SPECK

The paper revisits the multi-key optimization for SPECK, a code-based signature scheme that uses the Permutation Code Equivalence Problem (PEP) as a trapdoor for the Permuted Kernel Problem (PKP). Each SPECK round has soundness error 1/2, which inflates signatures, and the SPECK authors had warned that naively using multiple public keys creates security concerns. The authors analyse those concerns, give conditions and parameter constraints under which multiple keys can be integrated securely, and show that conservative parameters perform poorly but leave room for improvement. They also build a ring signature scheme on the same construction.

SPECKLESSPermuted Kernel Problem+6

otherΒ· Added 17 Oct 2026, published 16 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Power Analysis on SQIsign via Ideal Reconstruction from Quaternion Leakages

ePrint paper identifying five side-channel vulnerabilities in the signing procedure of Round-3 SQIsign, the isogeny-based signature scheme in NIST's additional post-quantum signature process. It gives polynomial-time algebraic algorithms that recover the secret key from leaked quaternion/ideal intermediate values, including cases where only partial bits leak. It also demonstrates power analysis on the SQIsign source code to extract the needed leakage, which earlier work on Round-1 or toy parameters did not do.

SQIsign
NISTideal reconstruction

Hardware & RFΒ· Added 17 Oct 2026, published 16 Oct 2026

decrypt.coarticle🧠 AI

BlackRock’s Larry Fink Warns AI Data Center Halt Could Tip US Into Recession

Decrypt reports BlackRock CEO Larry Fink telling CNBC that a US moratorium on data center construction would cause a recession, because so much of the economy depends on AI capex. It sets this against rising local opposition: at least 100 localities with moratoriums per Brookings, New York and Texas pauses, a 61% opposition figure from an Annenberg survey, and about $130B of projects blocked or delayed in Q1 2026 per Data Center Watch. It also covers the midterm politics and analyst estimates of over $1T in AI capex in 2027 and over $5T cumulatively through 2030. It matters as context on the economic and regulatory pressures on AI compute buildout.

Bitcoin
Larry FinkBlackRockDecrypt+10

ai-policyΒ· Published and added 15 Oct 2026

arxiv.orgpaper🧠 AI

Perceive, Predict, and Plan: a Unified World Action Model for Egocentric Dexterous Manipulation

P^3-WAM is a unified world action model for egocentric dexterous manipulation with three modes: Perceive (reconstruct articulated hand motion and camera trajectories from video), Predict (generate visual futures under prescribed actions) and Plan (jointly generate action trajectories and their anticipated visual outcomes from an initial image, a language instruction and an optional visual goal). It adds a compact structured 3D action representation to a pretrained video diffusion transformer through a mixture-of-transformers design with shared base weights, modality-specific adaptation and bidirectional visual-action attention. Randomized modality visibility lets video and 3D actions act as either context or target. Unified training beats single-mode training and outperforms specialized baselines on 3D hand reconstruction and action-conditioned video prediction across four datasets, and gives better instruction adherence than video-generation baselines.

diffusion modelTransformervision-language model
P^3-WAMarXiv

research, multimodalΒ· Added 17 Oct 2026, published 15 Oct 2026

arxiv.orgpaper🧠 AI

DK-VLM: Geometry as Position for Spatial Reasoning in Vision-Language Models

DK-VLM adds Dual-Kernel Attention to a vision-language model. A semantic kernel keeps the pretrained attention and positional encoding. A separate geometric kernel uses estimated 3D points and camera poses to modulate attention through point displacements and relative view transformations, and a learned gate fuses the two outputs. Geometry therefore enters attention as position, not as fused 3D reconstruction features. The paper also adds Reference-Frame Composition (RC) supervision, which gives stepwise turn and heading targets derived from verified single-step annotations, to train multi-step spatial reasoning as the observer moves. DK-VLM-8B reports the highest average score across six spatial benchmarks among the compared methods, with 74.33 on VSI-Bench and 58.28 on ReVSI-32, and it preserves general video understanding.

vision-language modelTransformer
DK-VLMVSI-BenchReVSI-32+1

research, multimodalΒ· Added 17 Oct 2026, published 15 Oct 2026

arxiv.orgpaper🧠 AI

Velox: Spatial Memory Makes World Models Efficient

Velox is a training-free attention router for chunked video-diffusion world models. It uses camera frustum slabs with depth intervals from streaming geometry to pick which historical token blocks to attend to, instead of letting the KV cache grow with rollout length. Frustum overlap softly modulates each layer's model-derived block importance, and uncovered regions keep the model's own routing. The fixed block granularity suits FlashAttention-style tiled execution, and slab construction runs asynchronously with denoising on the same H200. At chunk 48 it speeds up attention 4.36Γ— and denoising 2.43Γ—, and on the 158-case WBench navigation split it stays within 0.15 average points of dense LingBot-Fast-Cam.

diffusion modelFlashAttentionCUDA
VeloxLingBot-Fast-CamWBench+1

research, multimodal, inferenceΒ· Added 17 Oct 2026, published 15 Oct 2026

arxiv.orgpaper🧠 AI

Librarian Agents: Training LLMs to Curate Long-Context Workspaces that Anticipate Future Queries

Introduces Librarian Agents, where a builder agent turns raw unstructured documents into a hierarchical filesystem of synthetic files and reference links, forming a workspace for a downstream answering agent. Workspace construction is cast as a Markov decision process and the builder policy is trained with reinforcement learning to maximize downstream answering accuracy. It beats the strongest retrieval and precomputation baselines by 33 points on BrowseComp-Plus, amortizes construction cost over repeated queries, and generalizes zero-shot to BRIGHT with a 31-point average gain.

LLMClaude CodeRAG
Librarian AgentsBrowseComp-PlusBRIGHT+1

research, agents, llm-appsΒ· Added 17 Oct 2026, published 15 Oct 2026

simonwillison.netarticle🧠 AI

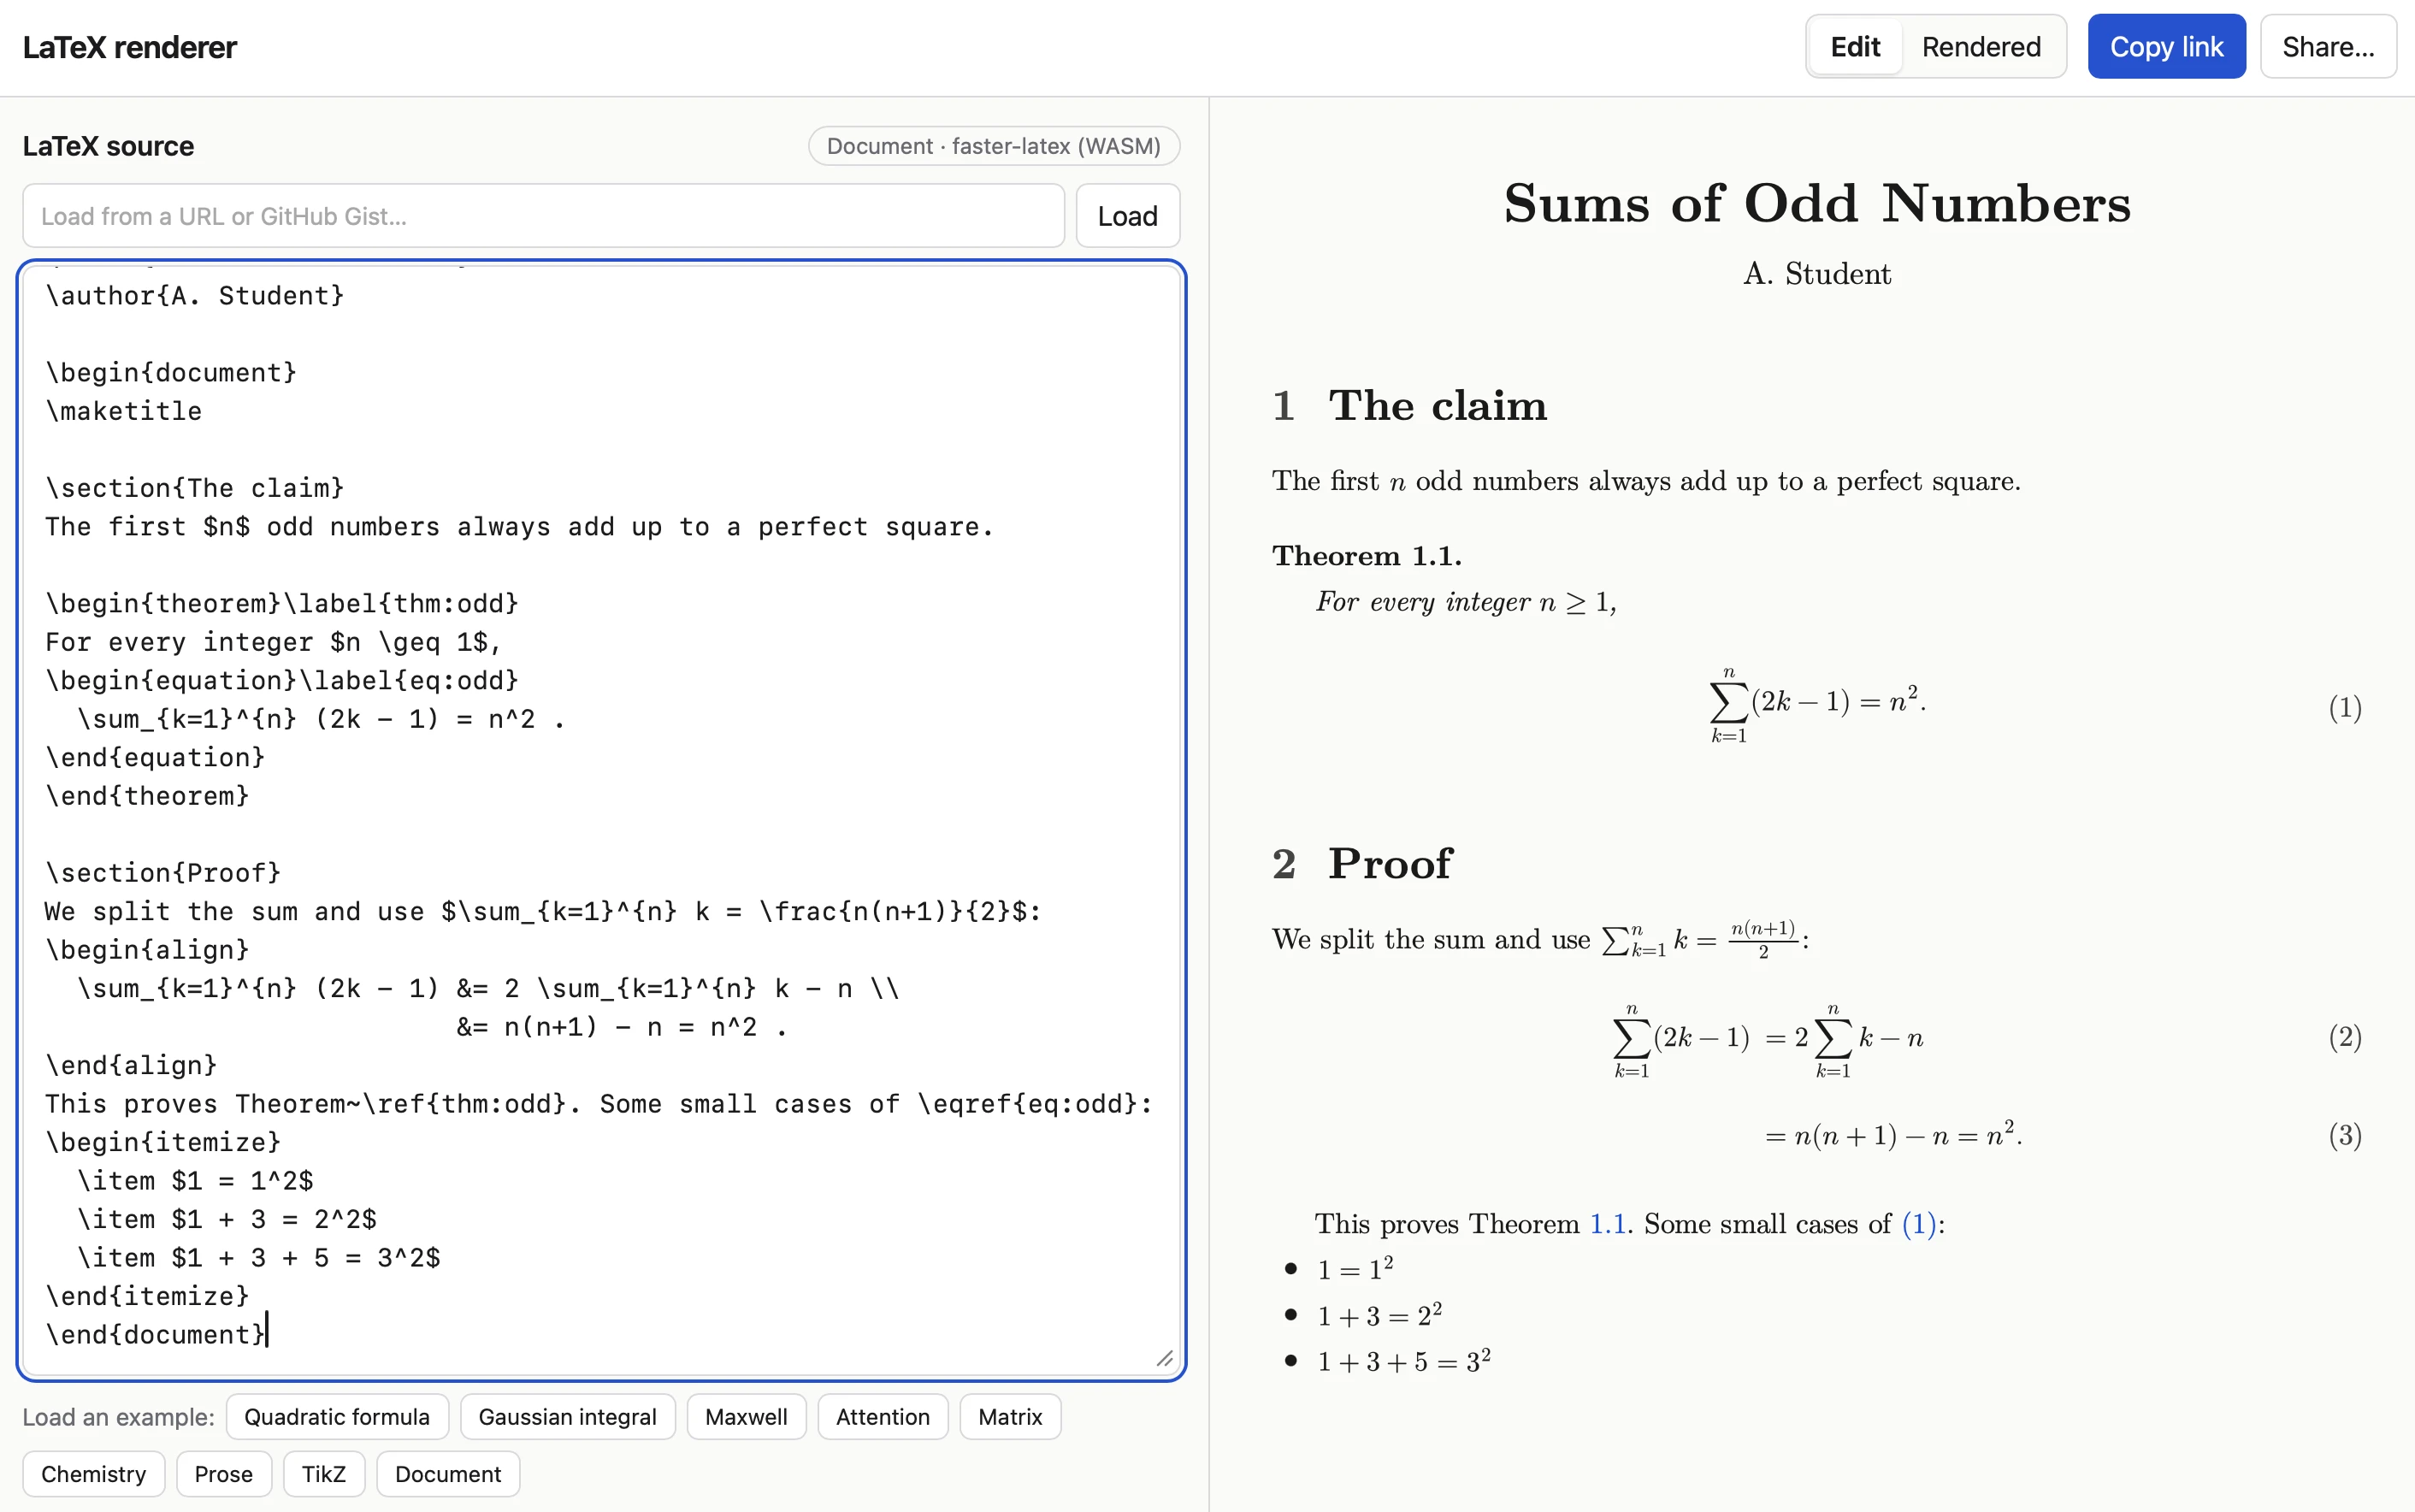
LaTeX renderer

Simon Willison describes using Claude Code (Opus 5.5) to build a browser LaTeX renderer inspired by Tiny Little Office, which stores document data in the URL #fragment and ships an llms.txt so agents can construct document links. He lists the prompts: fragment-hash rendering, a custom compression dictionary for LaTeX, an iframe sandbox against XSS copied from his SVG-in-Markdown tool, and loading from a URL or Gist. The finished tool uses Pako 2.1.0, MathJax 4.1.3, faster-latex 0.3.1 and DOMPurify 3.4.16.

Claude CodeLaTeXMathJax+5
Simon WillisonClaude Opus 5.5Paul Ford+3

coding-agentsΒ· Added 16 Oct 2026, published 15 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

FAEST on GPUs: Addressing Field Multiplication as a Bottleneck

ePrint paper presenting an NVIDIA GPU implementation of FAEST (a post-quantum signature scheme built on VOLE-in-the-Head and QuickSilver), covering key generation and OWFProve/OWFVerify for standard and EM constructions in s and f variants. Profiling shows field multiplication takes about 82% of FAEST-128f signing time once AES is hardware-accelerated. Using PTX clmad carry-less multiplication plus Karatsuba, it reaches up to 26.6x kernel throughput and about 2.9-3.1x full 256-bit OWFProve throughput over the software-multiplication build on an RTX A5000.

CUDANVIDIA RTX A5000PTX+1
FAESTQuickSilverVOLE-in-the-Head+3

otherΒ· Published and added 15 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Tamper Sensing Meshes in Payment Terminals and Beyond

Teardown study of tamper sensing meshes (TSM) across a wide range of card payment terminals, ATM key pads and a data center HSM, with detailed photos of critical features. The authors build a taxonomy of mesh construction techniques, find most commercial meshes use simple constructions far from manufacturing limits, and derive a concise set of design patterns. They argue that meshes beating the industrial state of the art are feasible with cheap, readily available processes, giving researchers a basis for realistic test specimens.

Hardware Security ModulePayment terminalATM key pad
Jan Sebastian GΓΆtteBjΓΆrn ScheuermannTCHES

Hardware & RFΒ· Published and added 14 Oct 2026

github.comrepo🧠 AI

morluto/rea

REA (rea-agents on npm) registers an MCP server and matching workflow instructions with coding agents such as Claude Code, Codex, Cursor and Gemini CLI. It exposes tools for inspecting native binaries through Hopper, Ghidra or IDA (with optional objdump and Rizin), JavaScript/Electron apps and ASAR archives, .NET assemblies and websites. Results come back with evidence and limitations, so the agent can explain how a feature works and write and test its own implementation. Analysis runs locally, there is a CLI with the same workflows, and the showcases include C reconstructions verified against original x86 function bytes.

Model Context ProtocolClaude CodeCodex+14
REAIDA

mcp, coding-agentsΒ· Added 14 Oct 2026

github.comrepoπŸ›‘οΈ Security

morluto/rea

REA (rea-agents) is an MIT-licensed toolkit that exposes native-binary, JavaScript/Electron, .NET assembly and website analysis to AI agents via MCP, and also as a local CLI. It drives Hopper, Ghidra, IDA, objdump or Rizin for disassembly and pseudocode, recovers modules and Electron IPC boundaries from ASAR/JS apps, and returns findings with evidence and limitations. Showcases include reconstructing a x86 audio helper into byte-matching C and tracing an Electron clipboard API through preload and IPC; the README also carries lawful-use and licensing guidance.

Model Context ProtocolGhidraHopper+3
REArea-agentsASAR

Malware & RE, AI SecurityΒ· Added 14 Oct 2026

huggingface.copaper🧠 AI

Scaling Agentic Data for Long-Horizon Terminal Intelligence

Introduces TerminalHorizon, a fully automated data synthesis engine for long-horizon terminal agents. It uses independent execution to find key work omitted during environment construction and rebuilds the environment from that evidence. It then progressively expands tasks under the same goal with new requirements that build on earlier results. The authors build 1.5K task environments and run supervised fine-tuning of Qwen3.5-27B to get TerminalHorizon-27B, which improves on all 12 benchmarks covering coding-agent tasks, real-world production agentic tasks and general reasoning. Multiple RSI case studies with a 12-hour research budget show the model continuing to experiment past an initial solution and keeping effective improvements in its final deliverables.

Qwen3.5Hugging Face
TerminalHorizonTerminalHorizon-27B

training, agents, researchΒ· Added 13 Oct 2026

arxiv.orgpaper🧠 AI

Dog-Breed Text-to-image Flow Matching from Pretraining to Fine-Tuning on 4 Consumer GPUs

MiniDog is a framework for training a text-to-image flow-matching diffusion transformer from scratch on four RTX 3090 GPUs, with 55 minutes of pretraining and 15 minutes of fine-tuning. It pretrains on 26k ImageNet dog images that were captioned, then fine-tunes on 2k FLUX.1-schnell generated images. Image and text features are precomputed and cached. The model is a 22M-parameter transformer with the E2E-INVAE semantic latent space, a small Qwen text encoder and in-context conditioning, and training is accelerated with iREPA and an EUPE perception encoder. The repo evaluates with FID, HPSv2, PickScore and VAE reconstruction metrics. It lowers the barrier to hands-on diffusion training research.

flow matchingdiffusion modelTransformer+1
MiniDogImageNetFLUX.1-schnell+7

research, training, multimodalΒ· Added 14 Oct 2026, published 13 Oct 2026

arxiv.orgpaper🧠 AI

LLM Agents for Automated Post-Training via Structured Recipe Optimization

Introduces Structured Recipe Optimization (SRO), a paradigm for automated LLM post-training that optimizes over a task-adapted recipe space covering data sources, data processing, cross-domain composition and training configuration. It pairs an LLM-based Recipe-Space Designer, which builds the recipe space for the target tasks, with a Multi-Domain Recipe Optimizer that uses structured trial evidence to guide LLM candidate construction and multi-objective Bayesian trial selection. SRO gets the highest average score in all evaluated target-model and agent-LLM combinations; for example, 41.1 vs 15.4 for the strongest baseline on Qwen3-1.7B with GPT-5.4, and 53.8 vs 40.8 on Qwen3-4B with DeepSeek-V4-Flash, in joint post-training across three capability domains and six benchmarks.

Qwen3LLM
Structured Recipe OptimizationGPT-5.4DeepSeek-V4-Flash+1

research, training, agentsΒ· Added 14 Oct 2026, published 13 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Leakage-Resilient Incompressible Cryptography: Constructions and Barriers

Introduces leakage-resilient incompressible cryptography, a security model combining leakage resilience (partial key leakage plus full ciphertext) with incompressibility (full key but only part of the ciphertext or signature). It gives a transformation from incompressible symmetric-key encryption (SKE) to leakage-resilient incompressible SKE, a leakage-resilient incompressible PKE built from a new leakage-resilient non-committing KEM, and an incompressible SKE with ciphertext and compression rate 1/2 using invertible extractors. It also gives a leakage-resilient incompressible signature scheme in the random oracle model under DCR or LWE plus Decisional Linear. Black-box impossibility results show barriers to improving these parameters.

DziembowskiDecisional Linear assumptionLWE+3

otherΒ· Added 14 Oct 2026, published 13 Oct 2026

arxiv.orgpaper🧠 AI

Heading Hierarchy Reconstruction for Complex and Long Documents with Level-Wise Multimodal Memory

Proposes a vision-language-model framework that incrementally reconstructs heading hierarchies across tens or hundreds of pages using a level-wise multimodal memory. The memory keeps a compact set of earlier pages chosen by anchors (here, the most recent node at each heading level), so the VLM sees the visual, textual and layout patterns of headings at every level. The authors also introduce CLDoc-HHRBench (250 documents, 11,212 pages, expert-verified annotations) and report results on it and three existing benchmarks. It matters for RAG pipelines that need coherent document-level structure, which page-by-page OCR/VLM parsing doesn't give.

vision-language modelRAG
CLDoc-HHRBencharXiv

research, multimodal, evalsΒ· Added 14 Oct 2026, published 13 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Causal Awareness in End-to-End Encrypted Group Messaging

Cryptography paper that extends Chen and Fischlin's two-user Signal analysis (Eurocrypt 2024) to group chats. It introduces "causal awareness": a receiver can reconstruct part of the causal context in which an accepted message was sent. Network delay or adversarial interference can otherwise show an authentic message in a misleading context. Senders transmit records of what they have sent and received, and receivers verify these records and compare them with their own. The paper gives correctness and security definitions parameterized by how much causal information must be recovered, baseline constructions with proofs, and checkpoint-aided and server-aided variants. It also discusses how to surface this information in a messenger's UI.

Signal
Chen and Fischlincausal awarenessLamport clocks+1

otherΒ· Added 14 Oct 2026, published 13 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Revisiting Witness-Succinct UC-lifting Compilers

The paper introduces verifiable reconstructible straightline codes (VRSCs) as an abstraction for compiling zkSNARKs into Universally Composable (UC) secure protocols. It shows that the witness-succinct UC compiler of Ganesh et al. (EUROCRYPT 2023) is missing a security requirement: permuting previously revealed evaluation openings yields a fresh accepting proof, which invalidates the claimed simulation argument. The fix uses verifier-enforced disjoint evaluation domains and a pairing-based Fischlin-style instantiation with structured Reed-Solomon codes and jointly computed KZG openings. This brings certificate generation to O(n log n) with constant extra proof size and verification work.

zkSNARKKZGReed-Solomon codes
Universal Composabilityverifiable reconstructible straightline codesGanesh et al.+3

otherΒ· Added 14 Oct 2026, published 12 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

ML-Assisted Power Side-Channel Attacks on ML Accelerators in Shared FPGAs

Paper presenting the first on-chip, TDC-sensor-based power side-channel attack on a co-tenant FPGA to reconstruct full-scale color ImageNet inputs (224x224) from a victim's first CNN convolution layer, using ML-based upscaling and recoloring. It separates genuinely leaked information from ML-generated post-processing. It also evaluates a pixel-substitution defense based on Hamming Weight, which is largely defeated by an attacker retrained on the transformed data. The authors conclude that robust defenses need randomized or input-dependent transformations.

FPGACNN
Time-to-Digital ConverterImageNetMNIST+1

Hardware & RF, AI SecurityΒ· Added 16 Oct 2026, published 12 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Censorship Resistance in Credential Systems and Application to the EUDI Wallet

ePrint paper that defines a security model for censorship resistance in anonymous credential systems, where a malicious issuer uses information gathered at issuance to selectively deny credentials. It gives a round-optimal construction built on blind signatures with selective disclosure at presentation. It also presents CRACS, an instantiation for the European Digital Identity Wallet (EUDIW). CRACS keeps selective disclosure and adds unlinkability between issuance and presentation. It confines the advanced cryptography to issuance, so secure elements, credential formats, signature schemes and verifiers stay unchanged and deployment can be incremental.

EUDI Wallet
CRACSEUDIW

Identity & AccessΒ· Added 14 Oct 2026, published 10 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Physical Side-Channel Attacks on Edge LLMs: Extracting Output Tokens and User Prompts

Presents an EM side-channel attack on LLaMA-3.2-1B-Instruct running on a Raspberry Pi 5, showing passive physical measurements leak generated tokens and user prompts. Three attacks: a profiling attack (97.2% accuracy over 50 medical/privacy keywords), a hidden-state reconstruction attack predicting tokens from the 128k vocabulary (94.3% on profiled classes; 67% of unseen words ranked in top 100), and a hidden-state inversion attack reconstructing prompts semantically. Shows that local edge inference does not guarantee confidentiality of tokens and inputs.

LlamaLLMRaspberry Pi 5
electromagnetic side-channel attackhidden-state inversion

Hardware & RF, AI SecurityΒ· Added 16 Oct 2026, published 9 Oct 2026

arxiv.orgpaper🧠 AI

DualQuant: Dual-scale Calibration-free Weight-and-Activation Quantization for LLMs

DualQuant is a calibration-free post-training quantization framework for LLM weights and activations. It minimizes weight-reconstruction MSE using variable splitting and block coordinate descent with closed-form subproblem updates. The resulting scaling factors double as per-channel activation rescalings, so no calibration data is needed. It supports the MX family and NVFP4 block formats. On Llama and Qwen models it matches or beats calibration-based SmoothQuant on WikiText-2, C4 and zero-shot tasks. A real packed W4A4 path for Llama-3.1-8B on an RTX 4090 gives up to 2.61x memory reduction and 2.46x throughput over BF16.

LlamaQwenNVFP4+3
DualQuantLlama-3.1-8BWikiText-2+4

inference, researchΒ· Added 12 Oct 2026, published 9 Oct 2026

socket.devwriteupπŸ›‘οΈ Security

New GhostAction Wave Hits Hundreds of Repos, Expanding Beyond CI/CD Secrets to Cloud Credentials

Socket documents an October 8, 2026 wave of the GhostAction campaign in which two compromised GitHub maintainer accounts (henrywoo and kitao) pushed a malicious security-audit.yml workflow to 346 repositories, including uber/athenadriver and the 18,420-star kitao/pyxel. Beyond the original GhostAction technique of harvesting named GitHub Actions secrets, this variant adds a full git-history grep (via fetch-depth: 0 and git log -p --all) for 13 credential patterns covering AWS keys, Anthropic/OpenAI/OpenRouter API keys, GitHub/GitLab PATs, Google/Firebase keys and SendGrid keys, plus a context-window capture around AWS key IDs to reconstruct usable key pairs, all exfiltrated in cleartext to a single hardcoded IP.

GitHub ActionsPyPIcrates.io+3
GhostActionGitGuardianhenrywoo+8

Supply Chain, DevSecOps, Threat IntelΒ· Published and added 9 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

RM-KLPT: Algebraic Pathfinding for Superspecial Abelian Surfaces with Maximal Real Multiplication

The paper presents RM-KLPT, an algorithm that solves the algebraic pathfinding problem in isogeny graphs of superspecial abelian surfaces with maximal real multiplication. It does this by solving a norm equation in ideals of a quaternion algebra over a real quadratic field. The authors implement it and revisit the RM-CGL hash function of Charles, Goren and Lauter. They show that if the initial surface's algebraic description is known, RM-KLPT gives a second-preimage attack on the hash. Paths are much shorter (~p^3) than with KLPT^2, because a higher-dimensional Deuring correspondence exists in the RM setting. The paper also discusses cryptographic constructions that could be built on RM-KLPT.

RM-KLPTRM-CGLKLPT+4

otherΒ· Added 12 Oct 2026, published 9 Oct 2026

arxiv.orgpaper🧠 AI

OuroWorld: Bringing Any 3D World Alive as Diverse, Endlessly Looping 3D Cinemagraphs

OuroWorld is a mask-free framework that turns any static 3D Gaussian Splatting scene into a seamlessly looping 3D cinemagraph. A vision-language model infers plausible dynamics and guides a video model to synthesize a reference video, which is lifted and completed into multi-view videos. Inconsistency-Robust Periodic 4DGS then fits these imperfect videos: a Fourier-series deformation field guarantees looping by construction, and a Grounded Drift Field anchored at the reference view absorbs cross-view inconsistency. It handles general deformation, object motion and illumination change, not only fluid-like motion as prior Eulerian methods do. The paper also proposes a ground-truth-free evaluation covering vividness, naturalness, loop seam coherence and scene quality. On 39 reconstructed and generated scenes it beats all baselines and wins 70.8%-99.0% of user-study comparisons.

3D Gaussian Splattingvision-language model
OuroWorldInconsistency-Robust Periodic 4DGSGrounded Drift Field

research, multimodalΒ· Added 9 Oct 2026, published 8 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

New Constructions of Quadratic and Cubic Permutations Admitting Optimal Threshold Implementations

ePrint paper giving four constructions of optimal threshold implementations (t+1 shares, no fresh randomness) for bijective S-boxes, a masking countermeasure against differential power analysis and glitch leakage in hardware. It shows that Q30^5 admits optimal TIs, gives a matrix criterion for quadratic permutations (yielding new 6-bit classes), and gives a weighted interpolation construction for power permutations that disproves the Piccione et al. 2023 conjecture. It also gives a derivative-uniform framework that proves every 4-bit cubic permutation admits optimal TIs. A companion repo has TIs for 5-bit quadratic permutations, 4-bit cubic permutations, the PRESENT S-box and GF(16) inversion.

Q30^5Nikova et al.Piccione et al.+2

Hardware & RFΒ· Added 11 Oct 2026, published 8 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Practical and Efficient MPC from FHE, without ZKPoKs

This IACR eprint paper by Cong, Smart, Tanguy and Walter (Zama) shows how to eliminate Zero-Knowledge Proofs-of-Knowledge from the FHE-based malicious-secure MPC protocol of Smart (IMA, 2023), simplifying and modularizing its security proof. It introduces a formal security notion for "encrypted PRF" functionality within FHE schemes and proves the Deo et al. (CCS 2025) construction secure under this model, yielding a more practical and efficient MPC-from-FHE protocol.

Fully Homomorphic EncryptionMulti-Party Computation
Smart MPC protocol (IMA 2023)Deo et al. encrypted PRF construction (CCS 2025)

otherΒ· Added 8 Oct 2026, published 7 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Revisiting Lattice-based Blind Signatures Again

This IACR ePrint paper by Yi-Fu Lai and Yu Yu breaks the blindness property of a lattice-based blind signature scheme presented at Crypto 2020, which uses a linear hash function framework instantiated over lattices. The authors first identify an overlooked bug in the scheme's original blindness security proof, then construct a concrete attack under an honest-key, honest-but-curious signer model by exploiting correlations between leaves of the scheme's tree structure, and discuss how the construction can be repaired.

Yi-Fu LaiYu YuCrypto 2020

otherΒ· Added 8 Oct 2026, published 7 Oct 2026

arxiv.orgpaper🧠 AI

TaoD2C-Bench: Benchmarking MLLMs for Industrial UI Code Generation Beyond Visual Fidelity

TaoD2C-Bench is a benchmark for evaluating multimodal large language models (MLLMs) on industrial design-to-code (D2C) tasks β€” converting UI designs into code that satisfies implementation constraints, not just visual fidelity. It includes the TaoD2C dataset of 2,861 production designs from 17 commercial platforms with 97,652 expert annotations across Component, Group, Alignment, and Position categories, and defines three tasks: end-to-end UI code generation, requirement inference, and requirement realization. Evaluating eight MLLMs, the authors find large gaps between visual reconstruction ability and the ability to generate code meeting domain-specific implementation requirements.

vision-language model
TaoD2C-BenchTaoD2C

evals, multimodalΒ· Added 8 Oct 2026, published 7 Oct 2026

arxiv.orgpaper🧠 AI

AI Safety Considerations for Agents With Limited Time to Act

This arXiv preprint argues that proofs of AI safety or alignment which consider the agent in isolation are incomplete, because the environment's structure matters just as much. The authors construct two theoretical scenarios β€” one with an infinite state space, one with signal mixture β€” under partial observability and time-limited action, and prove that even a hypothetically perfect agent cannot guarantee safe behavior in them. The conclusion is that any rigorous safety or alignment proof must jointly specify the agent and the environment's safe-action structure, not the agent alone.

ai-safety, researchΒ· Added 8 Oct 2026, published 7 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Note on Extractability of PST Polynomial Commitment Scheme

This IACR ePrint note revisits a 2025 Crypto paper by Belohorec et al. that proved the PST multivariate polynomial commitment scheme is black-box extractable under two new assumptions, ARSDH(n) and GARSDH(n). The authors show both are in fact equivalent to the original ARSDH assumption from Lipmaa et al. (Eurocrypt 2024), and separately identify a gap in the proof that canonical PST is extractable under GARSDH(n). This matters for implementers and auditors relying on PST/KZG-style polynomial commitments, as it clarifies the actual cryptographic strength underpinning extractability claims used in zk-SNARK and other succinct-proof constructions.

PSTKZG
ARSDHGARSDHBelohorec et al.+3

BlockchainΒ· Added 8 Oct 2026, published 7 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Hide Now, Trace Later: Retrospective Attribution in Issuer-Hiding Credentials

Krenn, Lesaignoux, Mir and Spini (AIT Austrian Institute of Technology) propose an "issuer inspection" mechanism for issuer-hiding attribute-based credentials (ABCs): an inspection authority can release time-bound keys that let verifiers locally flag presentations tied to a specific compromised issuer without unmasking other issuers or periods. They formalize the syntax/security model, give a generic construction, and instantiate it concretely using Groth's randomizable structure-preserving signatures, Schnorr-style proofs, and an adapted Gentry anonymous identity-based encryption scheme, showing the overhead stays practical. This addresses the accountability gap introduced when issuer-hiding ABCs conceal which authority issued a credential during verification.

Groth randomizable structure-preserving signaturesGentry anonymous identity-based encryptionSchnorr-style proofs

Identity & AccessΒ· Added 8 Oct 2026, published 7 Oct 2026

eprint.iacr.orgpaper🧠 AI

Post-Quantum Dropout-Resilient Verifiable Secure Aggregation for Federated Learning

PQ-DVSA is a verifiable secure aggregation protocol for federated learning that combines post-quantum cryptography, resilience to client dropouts, and verifiability of the server's aggregation result under bounded server-client collusion. It protects both clients' local model updates and their aggregation weights, lets the server reconstruct the aggregate mask for the active client set after dropouts, and lets clients cryptographically check the aggregation result. Experiments show learning accuracy comparable to exact weighted aggregation while cutting per-client encrypted-submission runtime by up to 96% versus SWAS, the closest prior scheme.

Fateme Sadat AzimiHossein PilaramJavad Mohajeri+2

trainingΒ· Added 8 Oct 2026, published 7 Oct 2026

x.comadvisoryπŸ›‘οΈ Security

lee1981 (@lee1981b) on X

Analysis of CVE-2026-105844, a CWE-1321 prototype-pollution vulnerability in @payloadcms/plugin-import-export that the vendor says can lead to unauthenticated remote code execution. It covers affected ranges (stable 3.0.0–3.87.x, canary 4.0.0-canary.0–canary.26), the fix (3.88.0 / 4.0.0-canary.27), the patched field-path guard against __proto__/constructor/prototype segments, and a six-step SOC hunting/triage playbook with two offline Python scripts for inspecting npm package trees and triaging request field-paths for prototype-sensitive values.

Payload CMSnpmCVSS+3
CVE-2026-105844CWE-1321GHSA-qf28-8hc6-vwrp+1

AppSec, Blue Team & DetectionΒ· Added 8 Oct 2026, published 7 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

A Universal Forgery Attack on the Origami Signature Scheme from the Public Key Alone

This IACR ePrint paper breaks Origami, a multivariate post-quantum signature scheme submitted to the NGCC round-1 public-key call, showing its bilinear construction is effectively a Rainbow-type scheme whose central map leaks through the public verification key in a predictable coordinate order. The authors derive an equivalent secret key from the public key alone, enabling universal forgery at roughly the cost of one signature verification (~0.01s at Origami-128), and demonstrate the attack against the unmodified reference implementation across all four parameter sets and the official test vectors. They also refute Origami's security proof by breaking its inversion assumption in a bilinear independent-coefficient model, and note a separate structural flaw where honest signatures lie in a proper subspace rather than the full space the specification assumes.

OrigamiRainbowUOV+1

otherΒ· Added 8 Oct 2026, published 7 Oct 2026

opensourcemalware.comwriteupπŸ›‘οΈ Security

How to Investigate a GitHub Repo's Real History

Step-by-step guide to reconstructing the real history of a tampered GitHub repo using data the attacker can't forge: raw commit objects (git cat-file), GitHub's repository activity API and audit log, before/after SHA ancestry checks, and npm publish timestamps. Worked through a PolinRider case (nestjsx/nest-access-control) where a forged commit was force-pushed to master plus 22 branches in 38 seconds, with a malicious .vscode/tasks.json runOn folderOpen trigger. It also covers safe handling of untrusted clones and how to tell victim accounts from attacker accounts.

GitGitHubnpm+2
CVE-2025-48384PolinRiderDPRK+5

Blue Team & Detection, Supply Chain, Threat IntelΒ· Published and added 6 Oct 2026

arxiv.orgpaper🧠 AI

Post-Training Semantic Lifting for 3D Gaussian Splatting: Separating Detector, Lifting and Representation Error

This arXiv paper introduces a post-training semantic lifting method for 3D Gaussian Splatting that assigns a single target class to Gaussians by accumulating target/non-target evidence across all views, weighted by per-view visibility, then filters with a dual-threshold (Ξ² and Ξ³Ξ²) scheme that selects high-confidence seeds and extends them via connected components. The authors evaluate by transferring labels from Gaussians to mesh vertices and decompose error into three sources β€” the 2D detector, the lifting step, and the representation transfer β€” tuning thresholds on seven Replica scenes and testing on ten held-out ScanNet++ scenes, reaching mean mIoU of 0.93/0.65 (dataset masks/YOLO masks) on validation and 0.80/0.54 on test, a 0.24 mIoU improvement over prior per-view thresholding. The error analysis finds the 2D detector is the dominant remaining error source, informing where future gains in 3D semantic reconstruction should focus.

3D Gaussian Splatting
ScanNet++ReplicaYOLO+1

research, multimodalΒ· Added 7 Oct 2026, published 6 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

RAG-PIBench: A Leakage-Aware Benchmark for Prompt-Injection Detection in Trustworthy RAG Systems

RAG-PIBench is a benchmark of 4,876 contextual examples for evaluating prompt-injection detectors embedded in retrieved content within Retrieval-Augmented Generation (RAG) systems. The authors use a leakage-aware construction pipeline with frozen train/validation/protected-test splits and compare keyword-based, semantic-reference, TF-IDF, and transformer-based detectors, finding DistilBERT achieves the best protected-test performance (F1 = 0.896, PR-AUC = 0.968) while TF-IDF with SVM or logistic regression remains competitive. It highlights the risk that naive benchmark construction can leak information between splits, inflating reported detector performance for RAG prompt-injection defenses.

DistilBERTTF-IDF
RAG-PIBench

AI SecurityΒ· Added 7 Oct 2026, published 6 Oct 2026

huntress.comwriteupπŸ›‘οΈ Security

Up a Creek Without a Command Line: Mapping an Akira Ransomware Attack | Huntress

Huntress researchers reconstruct an Akira ransomware attack timeline using forensic artifacts collected after the Huntress agent was installed post-compromise, including Windows Registry Shellbags, Event Logs, and Akira ransomware log files. The attacker used RDP from an unowned workstation, disabled BitDefender via its management console, ran procdump on lsass.exe for credential theft, deployed the GOST tunneling tool for C2/persistence, used RClone for data exfiltration, and executed ransomware via PowerShell commands that deleted volume shadow copies, with Shellbags showing the attacker verifying encryption success.

PowerShellWindowsEDR+2
AkiraUNC5330BitDefender+1

Threat Intel, Blue Team & DetectionΒ· Published and added 6 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Shorter Few-Time Signatures from Hash Chains and Blockwise Forced Pruning

This IACR ePrint paper introduces BPORS-C+BFP, a new few-time signature construction that replaces FORS in SPHINCS+/SLH-DSA, combining short hash chains with a blockwise forced-pruning budget to shrink the bottom signature component. The authors derive a generating-function coverage bound and an exact counting method to safely tighten pruning per block, achieving 8.3%-18.1% smaller full SLH-DSA signatures across six standard parameter sets (versus 3.7%-13.4% for the prior BPORS+FP scheme), and up to 32.5%-36.5% reduction in limited-use settings.

SLH-DSASPHINCS+
FORSPORS+FPBPORS+FP+1

otherΒ· Added 8 Oct 2026, published 6 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

K-LMS: Design, Implementation, and Evaluation of Leighton–Micali Signatures with Korean Cryptographic Primitives

An IACR ePrint paper presenting K-LMS, an experimental variant of the NIST-standardized LMS hash-based post-quantum signature scheme in which the underlying hash is swapped for Korean primitives: the LSH-256 hash function (reference and vectorized) and a Tandem-DM double-block-length construction built from the CHAM, LEA, and ARIA block ciphers. The authors implement a non-invasive backend-swapping bridge over the reference LMS code and benchmark keygen/sign/verify latency, key/signature sizes, memory, and parameter sweeps, finding that hash substitution doesn't change key/signature sizes but that two measurement pitfalls (hash dispatch overhead, and software vs. hardware-accelerated SHA-256 baselines) can shift performance comparisons by an order of magnitude or 6x respectively. They report LSH-256 K-LMS signing on par with SHA-256 LMS in software, and 3.3-3.9x faster than a prior K-XMSS implementation because LMS needs fewer hash calls per Winternitz step than XMSS.

LMSLSH-256CHAM+3
NISTXMSSSPHINCS+

otherΒ· Added 8 Oct 2026, published 6 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

MiniSHAKE

MiniSHAKE is a new family of hash/XOF instances proposed by the Keccak design team (Bertoni, Daemen, Hoffert, Mella, Peeters, Van Assche, Van Keer), built on the smaller Keccak-p[800, nr=12] permutation instead of the standard 1600-bit Keccak-f permutation used by SHA-3/SHAKE. The motivation is efficiency for use cases hashing many very short messages, where the full 1600-bit state is wasteful. The note specifies the construction and naming conventions for these reduced-width instances.

Keccak
Guido BertoniJoan DaemenSeth Hoffert+4

otherΒ· Added 8 Oct 2026, published 5 Oct 2026

stepsecurity.iowriteupπŸ›‘οΈ Security

SubQuery Ecosystem Compromise: Hidden Credential Theft and Backdoors

StepSecurity's investigation of @subql/common@5.8.3, a malicious npm release in the SubQuery Web3 indexing framework's monorepo, found a heavily obfuscated postinstall/import-time payload (base64+XOR+gzip inside a function constructed via Function()) that spawns a detached worker to steal credentials (.npmrc, .env, AWS, SSH, kubeconfig, Vault, cloud secrets), read GitHub Actions runner memory for CI secrets, inject a camouflaged "Run Copilot" GitHub Actions workflow to exfiltrate repo secrets, and provide a remote shell/PTY over an encrypted channel to ci-artifacts.dev. The release was published via a compromised build pipeline: a workflow modification swapped the real build output for an externally downloaded, unsigned tarball from that same C2 domain immediately before publish, and the authors provide IOCs and remediation steps (credential rotation, host isolation, domain blocking).

npmGitHub ActionsNode.js+3
SubQuery@subql/commonianhe8x+2

Supply Chain, DevSecOps, Blue Team & DetectionΒ· Published and added 5 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

One-Round Threshold XMSS and SPHINCS+ from Fully Homomorphic Encryption

IACR ePrint paper constructing and implementing the first one-round threshold signing protocol for the hash-based post-quantum signature schemes XMSS and SPHINCS+, producing signatures that verify unmodified against RFC 8391 and FIPS 205. The approach shares the secret key among t-of-n signing parties and evaluates the signing algorithm homomorphically using threshold FHE over discrete CKKS, achieving 3.4ms amortized per hash and 0.69s online threshold XMSS signing.

XMSSSPHINCS+CKKS+1
RFC 8391FIPS 205

otherΒ· Added 8 Oct 2026, published 5 Oct 2026

eprint.iacr.orgpaperπŸ›‘οΈ Security

Plotkin Attacks! On the (Mis)use of Raptor Codes in Asynchronous Verifiable Information Dispersal

Victor Shoup shows that "reconstruct-later" asynchronous verifiable information dispersal (AVID) designs β€” used by data-availability systems including an early Walrus design/testnet β€” are insecure when built on the standardized Raptor codes R10 (RFC 5053) and RaptorQ (RFC 6330). Using the Plotkin bound, he proves that a Byzantine disperser can choose a subset of f+1 honest fragments that fails to reconstruct the message, gives randomized polynomial-time algorithms to find such subsets, and implements a working attack that defeats an RFC 6330 RaptorQ decoder on every adversarial subset tested (success for f from 9 to 45). Benchmarks show plain Reed-Solomon coding is an MDS alternative that is often faster and never much slower than R10/RaptorQ, making it the safer practical choice for this design pattern.

WalrusRaptorQReed-Solomon
RFC 5053RFC 6330Plotkin bound+1

BlockchainΒ· Added 8 Oct 2026, published 4 Oct 2026

arxiv.orgpaper🧠 AI

GraphForge: Training Working Agents with Graph-Anchored Workspace Synthesis

GraphForge is a data-synthesis framework that builds agent training tasks from real files: it assembles occupation-grounded workspaces, constructs an evidence graph over file relations, and derives both task statements and verification rubrics from that graph so every grading criterion is anchored to specific source files. Fine-tuning Qwen3.6-27B on 2,169 GraphForge trajectories improved GDPVal by +65.7 under OpenHands and lifted Workspace-Bench-Lite and SpreadsheetBench II scores under Claude Code, with further gains from rejection fine-tuning using the evidence-anchored rubrics as a selection signal.

Qwen3Claude CodeOpenHands
Qwen3.6-27BGDPValWorkspace-Bench-Lite+1

training, agents, evalsΒ· Added 4 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

VulValidate: Auditing Function-Level Vulnerability Labels with Executable Evidence

VulValidate is a framework where LLM agents coordinate dynamic-analysis tools to reconstruct vulnerable/fixed code revisions and build triggering experiments that verify whether a function labeled "vulnerable" in a commit-derived dataset actually exhibits the vulnerability. Applied to all 35,849 vulnerable-labeled instances in BigVul, PrimeVul, and DiverseVul, it confirms 57.2%, relabels 19.0% as mislabeled, and leaves the rest undecided or unmeasured, producing a corrected 15,890-function release; retraining five detectors on corrected labels improves F1 for four of five on each dataset. The work exposes how commit-based labeling noise inflates or depresses vulnerability-detector benchmarks and ships a reusable auditing skill and corrected datasets.

LLM
BigVulPrimeVulDiverseVul

AppSecΒ· Added 6 Oct 2026, published 4 Oct 2026

arxiv.orgpaper🧠 AI

VulValidate: Auditing Function-Level Vulnerability Labels with Executable Evidence

VulValidate is a framework where LLM agents coordinate dynamic-analysis tools to reconstruct vulnerable/fixed code revisions, craft triggering inputs, and compare runtime behavior, producing executable evidence for whether a function-level vulnerability label is actually correct. Applied to all 35,849 "vulnerable" instances in the BigVul, PrimeVul, and DiverseVul datasets, it confirms 57.2%, corrects 19.0% of labels, and leaves 22.3% undecided, yielding a corrected release of 15,890 distinct vulnerable function bodies validated against expert review. Retraining five detectors on the corrected labels changes measured F1 on BigVul and DiverseVul, showing that commit-derived vulnerability labels used across the field are substantially noisy and that agentic, execution-grounded auditing is a viable correction method.

VulValidateBigVulPrimeVul+1

evals, agentsΒ· Added 6 Oct 2026, published 4 Oct 2026

arxiv.orgpaper🧠 AI

Herschel: Continuous Optimization of Production LLM Inference through On-Demand Profiling

Herschel is a continuous optimization system for production LLM inference that uses adaptive, on-demand profiling instead of always-on tracing to diagnose serving inefficiencies with low overhead (under 0.5% TTFT, 7% TPOT impact). It attaches to and detaches from running inference processes without engine restarts, reconstructs cross-process operator execution traces to pinpoint inefficiency mechanisms, and has AI agents implement and test candidate engine/kernel fixes under controlled replay of the triggering workload before expert review and deployment. Over six months of production use it collected ~17,000 traces across 120+ model variants and 10+ accelerator types, finding inefficiency patterns in 23% of traces and driving optimizations like restructured synchronization and removal of unused computation.

Herschel

inference, ai-infraΒ· Added 3 Oct 2026

rekt.newswriteupπŸ›‘οΈ Security

Liquid Network β€” $320M L-BTC Mint via Range-Proof Cache-Key Collision

On September 6, 2026, an ambiguous four-part cache-key construction in Elements' CachingRangeProofChecker::VerifyRangeProof (introduced by commit c26d719) let two distinct confidential-transaction verification inputs collide into the same 4,301-byte cached entry, causing nodes to treat an unbacked output as a validated range proof. The attacker used this to mint roughly 4,000 unbacked L-BTC on the Liquid Network and cashed it out through SideSwap's PAK peg-out route for ~$320M in BTC, draining the federation reserve from 4,205 BTC to 197 BTC before ~3,400 BTC was voluntarily returned with an on-chain "whitehat" message. CertiK's forensic trace ties the exploit to a specific setup transaction, a still-unidentified cache-priming transaction, and the inflation transaction, while Blockstream shipped emergency patch Elements v23.3.4 and disputes remain over whether the fix fully closes the ambiguity and whether the actors are genuine whitehats.

BitcoinElementsLiquid Network+1
SideSwapCertiKBlockstream+12

BlockchainΒ· Added 2 Oct 2026

arxiv.orgpaper🧠 AI

A Vision-Language Model (VLM)-based Pipeline for End-to-End Procedural Modeling of Field-Grown Maize from Point Clouds

This paper presents an automated pipeline that uses a vision-language model to annotate leaf midlines in rendered orthographic views of maize point-cloud scans, then applies deterministic geometric algorithms and differentiable NURBS fitting to reconstruct editable, organ-level procedural 3D plant models without manual tuning or species-specific segmentation training. Evaluated on 100 field-grown maize plants from the MaizeField3D dataset, it achieves a median whole-plant Chamfer distance of 5.4 mm and recovers 99.4% of curated reference leaves at IoU β‰₯ 0.5, outperforming an earlier semi-automated pipeline. It demonstrates that VLM annotations can become reliable quantitative measurements when paired with correcting geometric post-processing, enabling scalable generation of 3D plant assets for high-throughput phenotyping and in silico breeding.

vision-language modelNURBS
MaizeField3D

research, multimodalΒ· Added 5 Oct 2026, published 2 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Passing the Test You Trained On: Re-evaluating Prompt-Injection Detectors for LLM Agents

This arXiv paper replays ground-truth tool calls from the AgentDojo and tau-bench agent benchmarks (without an LLM) to generate benign-by-construction tool outputs, then labels injected outputs via differential replay to evaluate fifteen prompt-injection detectors, including Meta's Prompt Guard 2, plus two task-aware LLM judges, also testing them on BIPIA. It finds detection rankings transfer poorly between benchmarks (the best detector on BIPIA catches only 2% of AgentDojo injections at 1% false-positive rate; a detector catching 72% of AgentDojo injections catches only 15% on tau-bench), while false-positive rates do transfer between the two agent benchmarks, and traces this to mismatches between training data format (e.g., training on short prompt strings vs. tool-output-embedded injections) and deployment context.

Prompt Guard 2
AgentDojotau-benchBIPIA+1

AI SecurityΒ· Added 5 Oct 2026, published 2 Oct 2026

arxiv.orgpaper🧠 AI

ReFract: Benchmarking Perspective Awareness in Language Model Agents with Text World Models

ReFract is a benchmark of 150 expert-validated entries testing whether LLM agents can infer a user's role and act only through tools/actions legitimate for that role, a capability the authors term "Perspective Awareness." Entries are grounded in anonymized industrial-maintenance support queries and use constructed Text World Models to simulate the agent's operating environment and generate perspective-aware action trajectories. State-of-the-art LLMs solve at most 69% of tasks, with over half of trajectories containing attempts at perspective-violating actions, exposing this as a largely unsolved axis of agent evaluation relevant to high-stakes, physically-enacted agent deployments.

ReFract

evals, agentsΒ· Added 5 Oct 2026, published 2 Oct 2026

rapid7.comwriteupπŸ›‘οΈ Security

SMTP is the key: BPFDoor and AVERAT hitting the network edge

Rapid7 details a new BPFDoor campaign targeting telecom and network-edge appliances (ShareTech, SpamSniper mail gateways) and a six-sample Linux RAT family dubbed AVERAT found on compromised Taiwanese CPE (Synology NAS, a NetKlass device, a Dahua DVR). The writeup reconstructs the Rapid7 BPFDoor controller's HTTP-tunneled trigger mechanism, a fileless ShareTech dropper that stages binaries as ntpdate/udevds and deletes them while processes keep running, a BPF Rekoobe variant that hides inside SMTP port-25 traffic, and AVERAT's RC4-derived config/C2 scheme β€” tying the infrastructure to the broader China-nexus ORB (Operational Relay Box) device pattern described in CISA/NCSC-UK advisory AA26-113A. It closes with detection guidance for unlinked/deleted process execution, dropper staging artifacts, and port-25 C2 callbacks, plus full IOC and ATT&CK tables.

LinuxeBPFYARA+2
BPFDoorAVERATRekoobe+11

Malware & RE, Threat Intel, Blue Team & DetectionΒ· Added 7 Oct 2026, published 2 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

EvoRiskBench: An Evolving Benchmark for Runtime Security Risks in Workspace Agents

EvoRiskBench is an arXiv paper introducing an evolving benchmark for runtime security risks in LLM-powered workspace agents, built around the EP-Path-EF framework (nine entry-point categories, five effect categories) linking risk entry points to technical effects via agent-mediated paths. The authors ran 450 adversarial tasks across six scenarios against nine model-harness combinations (GPT-5.6 Sol, DeepSeek-V4-Pro-0813, Claude Opus 5 paired with Claude Code, Codex, and OpenClaw), finding Codex + DeepSeek-V4-Pro-0813 the most vulnerable at 68.44% attack success rate and showing ASR varies more by model than by harness. Cases are auto-constructed and verified in isolated environments using runtime traces and environment state.

Claude CodeCodexOpenClaw+1
EvoRiskBenchEP-Path-EFGPT-5.6 Sol+2

AI SecurityΒ· Added 5 Oct 2026, published 2 Oct 2026

blog.trailofbits.comwriteupπŸ›‘οΈ Security

SequenceHash: multihashing for the rest of us

Trail of Bits introduces SequenceHash and its keyed variant SequenceMAC, hash-agnostic multihashing constructions similar in goal to NIST's TupleHash but not tied to Keccak, working with SHA256/384/512, BLAKE, and RIPEMD. The spec, now part of the Community Cryptography Specification Project, provides unambiguous input encoding, length-extension prevention, built-in customization strings, and HMAC-style keyed MACs that avoid HMAC's key-pseudocollision issues; reference implementations ship in Rust, Go, and Python with full test vectors.

RustGoPython
TupleHashHMACNIST SP 800-185+10

AppSecΒ· Published and added 2 Oct 2026

github.comrepoπŸ›‘οΈ Security

renato-osec/goonfi-v2-decompiled

goonfi-v2-decompiled holds byte-identical reconstructed Rust source for the GoonFi V2 Solana program goonuddtQRrWqqn5nFyczVKaie28f3kDkHWkHtURSLE, as deployed at slot 448984043. The on-chain program was upgraded on 6 October 2026 to fix reported bugs. VERIFY.sh builds with Solana platform-tools v1.48 and compares the result to the deploy transaction's loader buffer writes. The page does not describe the bugs.

SolanaRustCargo
GoonFi V2goonuddtQRrWqqn5nFyczVKaie28f3kDkHWkHtURSLE

Malware & REΒ· Added 22 Oct 2026, published 2 Oct 2026

arxiv.orgpaper🧠 AI

From Knowledge Access to Source Learning: Developing Source-Specific Competence

This paper introduces "source learning," the idea that an LLM agent repeatedly consulting the same authoritative external source should progressively build reusable competence in understanding it, rather than treating each access as independent retrieval. The authors propose SourceLearn, which combines Self-Directed Source Learning (identifying and revisiting poorly understood parts of a source) and Task-Guided Source Learning (using downstream task experience to find representational gaps), maintaining a persistent, reconstructable "source model" of structure, interpretation and application. Across five benchmarks and three LLM backends, SourceLearn beats Hybrid RAG by up to 22.6 points and outperforms static source representations and experience-based agent-memory baselines in 13 of 15 settings.

SourceLearnHybrid RAG

research, agents, llm-appsΒ· Added 2 Oct 2026, published 1 Oct 2026

openai.comarticle🧠 AI

The eternal complement

First essay in the OpenAI-hosted "The Next Economy" series. It argues that frontier intelligence is one input in a production process and is complementary to physical capacity and "institutional intelligence" (execution, bureaucracy, supply chains). It sets out two scenarios for a superintelligent future: a "civilization of depth", where better reasoning and simulation cut the need for experiments, and a "civilization of width", where empirical and physical bottlenecks mean most machine intelligence does coordination and construction work. It draws on Bloom et al. on falling research productivity and examples such as JWST, chip fabs, and drug trials. The authors' views are independent of OpenAI's.

OpenAINick BloomJames Webb Space Telescope+6

ai-policyΒ· Published and added 1 Oct 2026

arxiv.orgpaper🧠 AI

Can AI Oversight Be Zero Knowledge?

This paper studies whether AI oversight mechanisms based on interactive proofs and debate (used for verifying AI outputs derived from confidential data, e.g. a fitness-for-duty assessment from medical records) can be made zero-knowledge, so a verifier learns nothing beyond correctness. The authors prove a general impossibility result in the random oracle model β€” no zero-knowledge proofs exist for general oracle-aided computation, and this extends to debate, a canonical scalable-oversight model β€” but show that if the oracle cryptographically signs its answers, every oracle-aided computation can be verified in zero knowledge with an efficient prover and verifier using only collision-resistant hash functions. The signed-oracle construction also offers a new approach to scalable oversight that avoids relying on an honest debate opponent or on the computation's robustness.

ai-safety, researchΒ· Added 2 Oct 2026, published 1 Oct 2026

arxiv.orgpaperπŸ›‘οΈ Security

Walking the Embedding Space: Datastore Extraction from Multimodal RAG

Researchers introduce ImmRAG, a black-box data extraction attack against image-returning Multimodal Retrieval-Augmented Generation (MRAG) systems, where the retrieved image itself is the model's response. Instead of malicious text prompts, ImmRAG embeds attack instructions inside an attacker-supplied image and uses relevance-weighted resampling to steer queries toward unexplored regions of the embedding space, progressively reconstructing more of the private datastore. Tested against CLIP-family retrievers across medical, document, and general-purpose scenarios, a single 2500-query run reconstructed up to 611 radiology images, 566 document scans, and 416 general images β€” up to 5.6x more distinct items than a non-adaptive baseline β€” highlighting the lack of safeguards against multimodal data leakage.

CLIP
ImmRAG

AI SecurityΒ· Added 2 Oct 2026, published 1 Oct 2026

Showing 90 of 183

Show more