- AI startup hacks Anthropic, gains access to employee details, internal messages
Cathedral, a security startup founded by former DOGE members, used AI agents to find flaws in third-party business software used by Anthropic. It reached sales, HR and IT systems in under 12 hours. Anthropic says no customer chats, model outputs, source code or model weights were reached, and it cut off access the same day. The article also recaps earlier cases of Claude bypassing access restrictions, including Georgia vote counts.
 indiatoday.inarticleAdded 1 Nov 2026, published 31 Oct 2026🛡️ Security
- Show HN: A language model that lives in a boot sector
bootgpt is a char-level language model that runs from a BIOS boot sector. A 512-byte hand-written asm MBR loads an 11.5 KB int8 model from 23 following sectors and runs it in 16-bit real mode on a 386, generating fake Linux dmesg boot logs. train.py quantises to int8 with power-of-two scales, and its integer simulation matches the asm output char for char.
 github.comrepoAdded 1 Nov 2026, published 31 Oct 2026🧠 AI
 We’ve received our first response from the Project Suncatcher prototype satellite.
Project Suncatcher is a Google research effort to power AI compute in space. Its prototype satellite launched on 1 October 2026 and, after commissioning, returned the first AI response from a data-center-class TPU in orbit: a haiku from the onboard Gemma 4 open model, downlinked over Svalbard. Next come thermal-stress and radiation tests, then twin interconnected satellites in 2027.
 blog.googlearticlePublished and added 30 Oct 2026🧠 AI
 TextSeal2: Distortion-Free LLM Watermarking with Copula Mixing and Memoryless Races
TextSeal2 is a distortion-free LLM text watermark that merges two or more keys into one virtual key and couples it to fresh noise through AutoMark's Gaussian copula. Under speculative decoding it verifies keyed drafts with an extra exponential race, so output matches the target model and acceptance rate is unchanged. On three LLMs at a 10^-3 false-positive rate, it detects 8 to 22 points more 100-token answers than TextSeal.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security
- TextSeal2: Distortion-Free LLM Watermarking with Copula Mixing and Memoryless Races
TextSeal2 is a distortion-free watermark for LLM output that keeps its signal under speculative decoding. It merges two or more keys into one virtual key coupled to fresh noise through AutoMark's Gaussian copula, and verifies drafts with an extra exponential race. On three LLMs it detects 8 to 22 points more 100-token answers than TextSeal at a 10^-3 false-positive rate.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI - Understanding and Mitigating Role Spoofing in LLMs
Understanding and Mitigating Role Spoofing in LLMs is an arXiv paper (October 2026) on role spoofing, a prompt injection where malicious tool output impersonates the user. It shows models track "who said what" using both content cues (semantics, style) and structure cues (control tokens, formatting). Attacks combining fake structure and content succeed often, adversarial training stops only content-based attacks, and linear probes trained to predict conversation roles detect spoofing across settings.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security - A Unified Hessian-Guided Framework for Post-Training Quantization
This preprint proposes a unified post-training quantization framework for large language models. It derives a Hessian-guided approximation of the output change caused by joint weight and activation quantization, using a tractable Fisher approximation. Quantization ranges, linear transformations and weight rounding are optimized together under one output-sensitivity objective. The authors report gains over state-of-the-art transformation and rounding methods in channel-wise and block-wise settings.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI  Google Touts Powerful Cybersecurity Capabilities in Gemini 4 Carbon Model
Gemini 4 Carbon is Google's new frontier model, announced with scores of 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Google says it beats GPT-6 Astra, Claude Opus 5.5 and Claude Fable 5.1 on these, with no guardrails. Access is limited to Fairwind Program partners at first. Pricing starts at $2 input and $10 output per million tokens, rising to $4 and $20.
 securityweek.comarticlePublished and added 29 Oct 2026🧠 AI
- SEAL: Sealed Queries for Local Sanitization against Indirect Prompt Injection
SEAL is a defense against indirect prompt injection for local LLM agents. It learns a soft prompt and scoring readout offline, then uses a frozen task model to score and delete injected tokens from tool outputs, with queries built from trusted initial context. On AgentDojo, attack success falls from 34.6% to 0.1% and Joint rises from 51.4% to 77.5%, using about 127x fewer defense tokens than PISanitizer.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security - High Precision Noise Cleaning for CKKS with Application to Asynchronous Threshold CKKS
High Precision Noise Cleaning for CKKS is an IACR ePrint preprint (2026/2675) by Zhihao Li, Cheng Hong and Tao Wei. It composes lower-degree Hermite polynomials to reach output noise bounds such as 2^-300 for noise flooding, and uses this to build an asynchronous threshold CKKS scheme with strong simulation security in the random oracle model. In OpenFHE, binary-message cleaning falls from 9.63 s to 1.54 s.
 eprint.iacr.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security
- inkGround: Benchmarking Fine-grained Visual Grounding Capabilities of Vision-Language Models for Cursive Handwriting in the Wild
inkGround is a benchmark for stroke trajectory recovery from full-page, camera-captured handwriting, with 537 page images (about 18.7k words, 163k strokes) and pseudo-label references filtered by OCR agreement and human raters. Models get a page image and a target word, then output ordered stroke points. Seven VLMs were scored with DTW, Chamfer distance, readability and style similarity. Closed-source models, notably Gemini-3.1-Pro, did best, and the ranking held on IAM-OnDB.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI  OpenAI Plans to Buy Google's AI Chips as It Looks Beyond Nvidia: Report
Decrypt reports, citing The Information, that OpenAI plans to buy Google TPUs rather than rent them, to reduce dependence on Nvidia. Neither company has confirmed, and price, volume and timing are undisclosed. The article covers OpenAI's TPU optimization job listing, its Broadcom-built Jalapeño inference chip due end of 2026, Nvidia and AMD deals, and Anthropic's multi-gigawatt TPU agreement.
 decrypt.coarticlePublished and added 28 Oct 2026🧠 AI
- Niko (@nikolayxyz) on X
Gemini 4 Carbon is Google's new frontier model, announced in a post by nikolayxyz that quotes Google's launch text. It ranks #1 on v5.0 of the Artificial Analysis Intelligence Index with 59 points, ahead of Opus 5.5 and GPT-6 Astra. Intro pricing is $2 input and $10 output per million tokens. Access starts for cyber defenders first, as Gemini 4 Argon's did. The captured text is cut off before the rollout details.
 x.comthreadAdded 29 Oct 2026, published 28 Oct 2026🧠 AI
 Gemini 4 Carbon
 is Google's frontier model, announced with cybersecurity results: 88.2% on SEC-bench Pro (finding vulnerabilities), 54.8% on ExploitGym (exploitation) and 71.0% on CWE-bench (patching). Google reports 0.0% attack success on Gray Swan's indirect prompt injection benchmark. Access starts with a subset of cyber defenders through the Fairwind Program. Pricing is $2 per million input tokens and $10 per million output tokens.
blog.googlearticleAdded 29 Oct 2026, published 28 Oct 2026🛡️ Security- Gemini 4 Carbon
Gemini 4 Carbon is Google's frontier model, announced two weeks after Gemini 4 Argon. It scores 59 on Artificial Analysis Intelligence Index v5.0, 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Pricing is $2 per million input and $10 per million output tokens. Access starts with a subset of cyber defenders through the Fairwind Program.
blog.googlearticleAdded 29 Oct 2026, published 28 Oct 2026🧠 AI - Gemini 4 Carbon: Our next frontier model
Gemini 4 Carbon is Google DeepMind's new frontier model, announced two weeks after Gemini 4 Argon. It ranks #1 on Artificial Analysis Intelligence Index v5.0 at 59 and scores 88.2% on SEC-bench Pro, 54.8% on ExploitGym and 71.0% on CWE-bench. Access starts with cyber defenders through the Fairwind Program, priced at $2 per million input tokens and $10 per million output tokens.
 deepmind.googlearticlePublished and added 28 Oct 2026🧠 AI
 The ADLC maturity model: 5 stages of agentic development security | Endor Labs
The ADLC maturity model is a proposed five-stage framework from Endor Labs for scoring security controls over coding agents, from unmanaged experimentation to continuous verification. Each stage has requirements on two tracks, agent actions (shell commands, MCP calls, package installs) and agent output (code, dependencies, secrets). It sets stage 3 at deterministic hooks that block actions, gives evidence-based assessment questions, and lists traps such as relying on prompt-level rules.
 endorlabs.comarticlePublished and added 28 Oct 2026🛡️ Security
- Genie 4: A new generation of world simulation
Genie 4 is Google DeepMind's real-time interactive world model, announced as a research preview for trusted testers. It generates video with native audio and interactive dialogue, steered by keyboard controls and text prompts. Gemini 3.8 Flash acts as a guiding agent that plans steps and checks frames, and Gemini 4 Argon is used for robotics experiments. The post lists limitations such as drift and object permanence, and says outputs carry SynthID watermarks.
deepmind.googlearticlePublished and added 27 Oct 2026🧠 AI - Is my data used for model training?
Anthropic's privacy help article on whether customer data trains its models. For commercial products (Claude for Work, Anthropic API, Claude Gov), inputs and outputs are not used for training by default. Thumbs up/down feedback stores the whole conversation for up to 5 years, de-linked from user IDs, and may be used for training. Team and Enterprise owners can disable feedback in organization settings.
 privacy.claude.comarticleAdded 28 Oct 2026, published 27 Oct 2026🧠 AI
- Muzammil Shah (@Muzammil_OX) on X
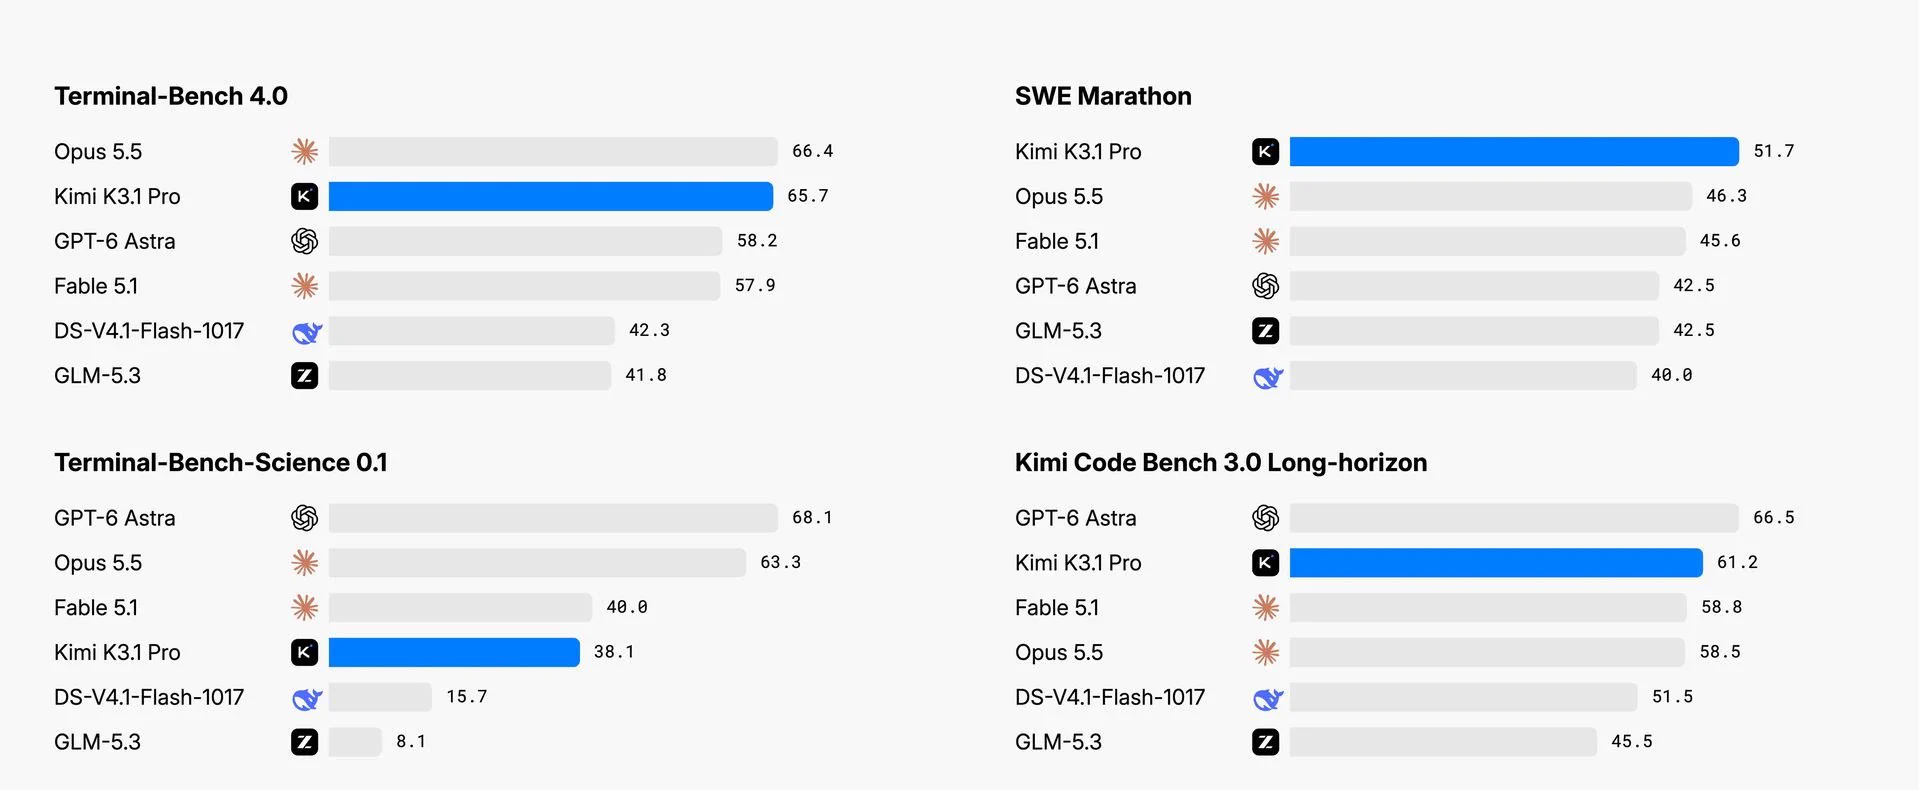
Kimi K3.1 Pro is a new model from Moonshot AI that scores 55 on the Artificial Analysis Intelligence Index, up 11 points from its predecessor, and ranks 4th overall. It has a 1M-token context window and API pricing of $2 per million input tokens and $10 per million output tokens. Weights are due by November 4. Moonshot removed cyber-related training data, which cut its internal vulnerability research score from 90.5% to 81%.
x.comthreadAdded 28 Oct 2026, published 27 Oct 2026🧠 AI - Folding Attention Biases into Keys Makes Compacted KV Caches Run on Standard Kernels
The paper folds the per-key logit bias of Attention Matching (AM) KV cache compaction into the keys along one closed-form direction per head, fitted on context queries. The result is a plain cache that FlashAttention and vLLM paged caches can use, with output error bounded by how far each query's projection on that direction is from 1. Unmodified vLLM serves folded caches through a KV connector. On QuALITY and LongHealth the fold is within noise of AM in 13 of 14 settings. Under AM's published per-head budgets it is within noise in 9 of 10.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI  GPT-6.1 Terra
 is OpenAI's midrange model, announced 26 October 2026 and aimed at visual reasoning, computer use and clearer writing. It costs $1 per million input tokens and $5 per million output, about half of GPT-5.6 Terra and GPT-6.1 Sol and roughly 10x GPT-6 Luna. Simon Willison relays OpenAI's Ted Sanders, who rates it better than Astra and Sol at technical communication and much faster on computer use.
 simonwillison.netarticleAdded 27 Oct 2026, published 26 Oct 2026🧠 AI
 Stolen AI Reasoning Could Help China Build Cheaper Rivals
Compaction Smuggling is an attack found by Xint that bypassed OpenAI's August 2026 mitigations against stealing reasoning traces from proprietary LLM APIs. It encodes one model's reasoning inside a compaction and replays it to another model (for example gpt-4.1 or gpt-4o), which outputs it verbatim. OpenAI fixed it and paid a $6,000 bounty on 23 October 2026. The article ties it to distillation by Chinese labs, citing a September CISA warning.
securityweek.comarticlePublished and added 26 Oct 2026🛡️ Security Artificial Intelligence (AI) in Cybersecurity, Part 30: Shannon – AI Pentester for Web Apps and APIs
Shannon is a white-box AI pentester (@keygraph/shannon) that analyzes an application's source code, then attacks the running instance and reports only findings with a working PoC. The Hackers Arise tutorial runs it against OWASP Juice Shop in Docker on Kali, using OpenRouter (free Nemotron) and local Ollama (Qwen 2.5 Coder 7B) via a models.json file. Output includes PDF, Markdown, JSON and SARIF reports.
 hackers-arise.comarticlePublished and added 26 Oct 2026🛡️ Security
- Introducing GPT-6.1 Terra
GPT-6.1 Terra is OpenAI's fast, lower-cost model for visual reasoning, computer use and writing, released as API model gpt-6.1-terra. OpenAI reports Terminal-Bench 4.0 at 50.3% (GPT-5.6 Terra: 21.5%) and a low-effort error rate cut from 53.6% to 16.7%. API pricing is $1 per million input tokens and $5 per million output tokens. It meets the Critical cybersecurity threshold in OpenAI's Preparedness Framework.
 openai.comarticlePublished and added 26 Oct 2026🧠 AI
- Explaining Navigation Decisions: Stage-Aware Visual Attribution for Vision-Language Navigation
A stage-aware visual attribution framework for Vision-Language Navigation (VLN) that explains a robot's action choices. It identifies "instruction-stage insensitivity", where existing explainers give similar outputs across navigation stages. The method builds action-conditioned temporal instruction-visual attributions, aggregates relevant historical evidence by stage, and applies an instruction-guided spatial filter. It improves attribution quality across several VLN policies and benchmarks, helps diagnose failure cases, and was tested on a Unitree G1 robot.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026🧠 AI  Sweden's Government Offices Block ChatGPT and Claude, Keep Microsoft Copilot
Sweden's Government Offices will block ChatGPT and Claude on staff computers from 26 October 2026 and leave Microsoft Copilot as the only approved AI tool, citing information security. Digitalisation director Mikael Wettercrantz said unvetted AI use had involved sensitive inputs and poorly handled outputs. The Tax Agency and National Board of Institutional Care have similar bans, and the European Parliament disabled AI features in February 2026. Whether Copilot has Claude models enabled is unconfirmed.
decrypt.coarticlePublished and added 24 Oct 2026🛡️ Security- Eat Your Precision: Precision Objective Mitigates Reward Hacking in Rubric-based RL
FORK is a reward for rubric-based reinforcement learning that jointly optimizes recall and a new precision objective. Precision requires each unit of a response to be necessary (rubric-driven necessity credits) and factually correct (a grader). Rubric-coverage rewards otherwise produce verbose, less accurate responses. FORK keeps similar coverage with shorter outputs, raising win rate against the base policy from 10.6% to 68.0% on RubricHub-Medical and from 22.1% to 74.1% on HealthBench.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI  Introducing Kimi K3.1 Pro
Kimi K3.1 Pro is Moonshot AI's new model, available on the Kimi API from 23 October 2026, with full weights promised by 4 November 2026. Pricing is $2.00 per million input tokens and $10 per million output, and a Highspeed variant is 2-3x faster at twice the price. Artificial Analysis scores it 55, behind only Claude Opus 5.5 (58). Simon Willison tested it with the llm CLI and pelican SVG prompts.
simonwillison.netarticlePublished and added 23 Oct 2026🧠 AI- Yash Patil (@yvshpvtil) on X
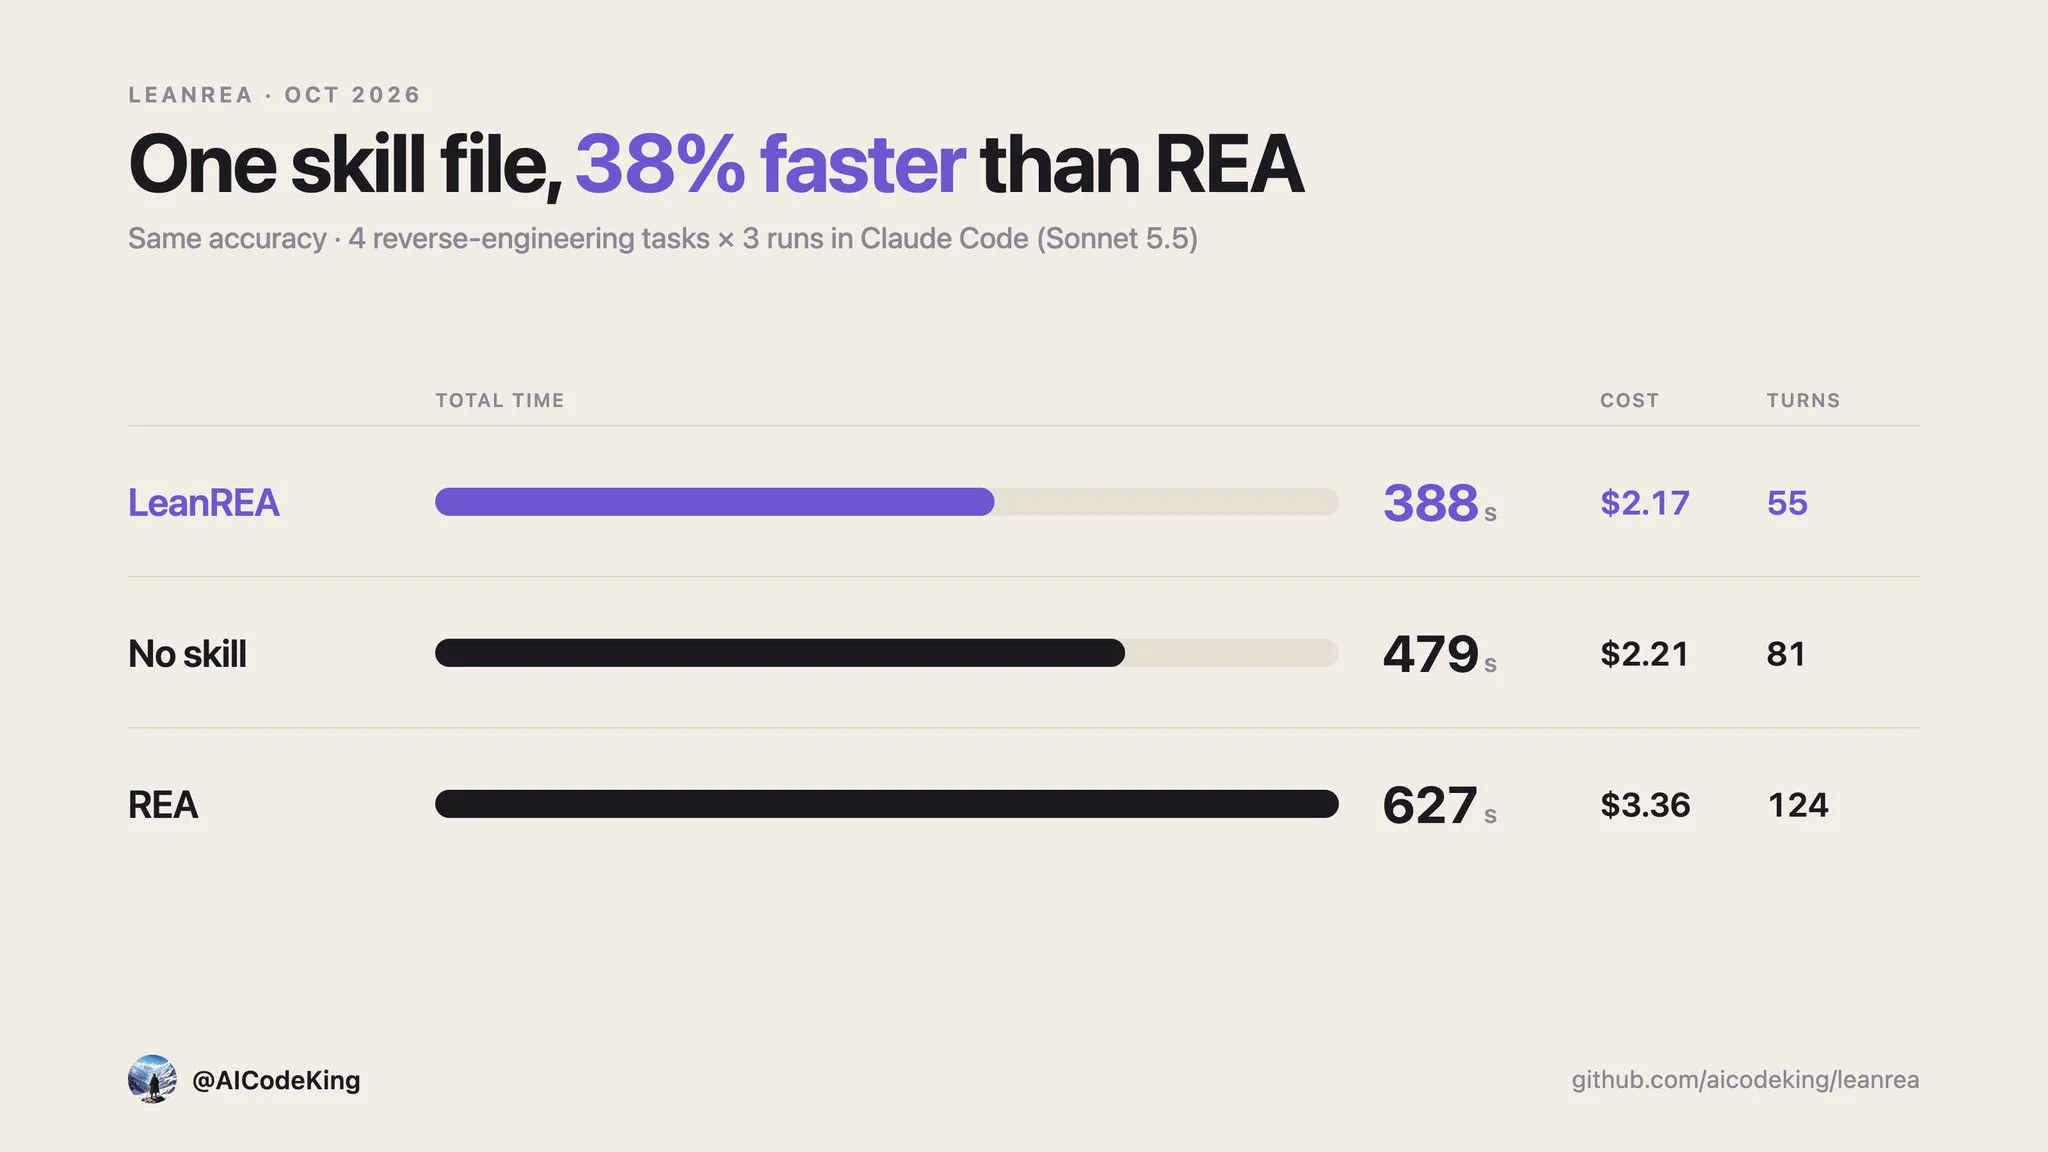
leanrea is an 8 KB skill file that tells a coding agent which plain CLI tools to use for reverse engineering, replacing the 207-tool REA MCP server. The author's test reports 38% faster, 35% cheaper, and a score of 74/75 against REA's 75/75. Caveats listed: 3 runs per task, one model, one machine, and Claude with no skill already performed decently. Replies question whether the lost point was a task where structured tool output beat parsing CLI text.
x.comthreadAdded 25 Oct 2026, published 23 Oct 2026🛡️ Security  Faster and Smaller Anonymous Credentials from Standardized Signatures
GordieHowe is a language, certifying compiler and zero-knowledge proof system for building anonymous credentials on standardized signatures (ECDSA, RSA, ML-DSA). It proves an ECDSA-signed mobile driving license presentation in 64.8 ms with a 276 KiB proof, 10.1x faster than Google's Longfellow, and an ML-DSA-44 signature in 87.3 ms with at least 116 bits of quantum security. Compiler output and security theorems are checked in Lean. It introduces series-parallel IOPs and extends the BCS transformation in the QROM.
eprint.iacr.orgpaperAdded 24 Oct 2026, published 23 Oct 2026🛡️ Security- Pairwise Independence of Ten-Round AES
Pairwise Independence of Ten-Round AES (Zhongfeng Niu, Kai Hu, ePrint 2026/2608) proves that ten rounds of AES with independent uniform round keys and input/output whitening are within 3017/2^141 (below 2^-129) statistical distance of pairwise independent. The proof bounds the averaged difference-distribution matrix over five superbox layers, using Gram moments and MDS code constraints. Final-round MixColumns omission is retained.
eprint.iacr.orgpaperAdded 24 Oct 2026, published 23 Oct 2026🛡️ Security  Daily Vibe Casting (@vibecastingapp) on X
Daily Vibe Casting thread of 24-hour tech news, with item 5/10 on Cloudflare's agent security audit skill. The skill works across models and agent harnesses, including free models, and outputs machine-readable reports. It calls for sandboxing, proof of real impact and independent checks. The thread also covers GitLab CVE-2026-110264 (CVSS 10.0, unauthenticated RCE), two AI-found PHP RCE flaws, and a Railway secret-theft warning.
x.comthreadAdded 24 Oct 2026, published 22 Oct 2026🛡️ Security- Build more responsive apps with the Decisions API
The Decisions API is an OpenAI endpoint, built on GPT-6 Luna, that answers bounded questions about text, images or native JSON inputs, up to 10x faster than Luna through the Responses API. It returns a probability (predicate), a choice or a score. It is generally available, accepts up to 400 questions per request, and costs $0.10 per million input tokens with no output charges.
openai.comarticlePublished and added 22 Oct 2026🧠 AI - Spectrmachina/Ztrust
ZTrust is a Python supply-chain scanner that checks manifests, lockfiles, source and GitHub workflows for vulnerable or malicious dependencies (via OSV.dev), typosquats, leaked secrets, unsafe lockfiles and risky CI patterns such as pwn requests and script injection. It outputs console, JSON and SARIF 2.1.0 and ships as a GitHub Action. It also includes a FastAPI bounty service using commit-reveal and shielded Zcash payouts for researchers.
github.comrepoAdded 27 Oct 2026, published 22 Oct 2026🛡️ Security  How bug bounty sharpens one researcher’s security skills
GitHub Bug Bounty spotlight interview with @r31n, a researcher known for GitHub Enterprise Server findings. They describe a source-and-sink approach to mapping trust boundaries, chaining minor bugs (open redirect plus allowlisted SSRF that follows redirects), and confirming a finding only with a working PoC. They also cover using AI for code navigation and PoC scripts, and treating model output as untrusted input.
 github.blogarticlePublished and added 22 Oct 2026🛡️ Security
- Sadra Majidi (@SadraMajidi04) on X
Impeccable is an open-source skill for AI coding agents that steers them away from generic UI output such as purple gradients and nested cards. It provides 24 commands (critique, audit, polish, typeset) and 61 detector rules that run without an LLM. It works with Claude Code, Cursor and Codex, and the repo is pbakaus/impeccable on GitHub. The source is a short tweet and gives no further detail.
x.comrepoAdded 23 Oct 2026, published 22 Oct 2026🧠 AI - The Geometry of Metaphor: Probing and Steering Metaphor Representations in Large Language Models
The Geometry of Metaphor is an October 2026 arXiv preprint that uses mechanistic interpretability to find causal subspaces for metaphor in LLMs of different architectures and sizes. The authors steer output on classification tasks across parts of speech. They also steer generation tasks, showing the metaphoricity of model output can be controlled. The abstract gives no model names or metrics.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI  OlmoEarth v1.3: State-of-the-art embeddings for the whole planet
OlmoEarth v1.3 is an open satellite embedding model from Ai2 that reads a year of Sentinel-1, Sentinel-2 and Landsat data and outputs a 128-dimensional vector per 10 m pixel (the first 64 dimensions also work alone). Its embeddings beat AlphaEarth Foundations and Tessera v2 on 20 of 27 evaluations. Precomputed global embeddings, a browser Embeddings Explorer and pre-training cost (about $2,720 of H100 time) are covered.
 huggingface.coarticlePublished and added 22 Oct 2026🧠 AI
- RIFT: KV Cache Compression for Draft Models with Complementary Compressibility Training
RIFT is a family of selection-based KV cache compression strategies for speculative-decoding draft models. It targets "decode staleness", where prefill-focused selection loses relevance as output grows, by balancing prefill information with recent generated tokens, refreshing the selection adaptively, and training drafters with sparse attention masks. Qwen3.5-4B drafting for Qwen3.5-122B keeps over 98% of full-cache acceptance length at 32K input, 4K output and an 8K KV budget.
arxiv.orgpaperAdded 23 Oct 2026, published 22 Oct 2026🧠 AI - The Good, the Bad, and the Noisy: A Systematic Analysis of Ring-Oscillator-Based Noise Generators
This IACR ePrint paper (2026/2597) systematically compares ring-oscillator-based additive noise generators, a hiding countermeasure against side-channel attacks. Experiments show many existing designs ignore output amplification and the risk of the noise being filtered out, so they lower signal-to-noise ratio too little. The authors give a guideline on inverter chain length, output amplification and frequency randomization, and build a tailored generator for an AES implementation that outperforms prior designs.
eprint.iacr.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🛡️ Security  [AINews] OpenAI’s Patch the Planet program is 1 of 2 parties to discover PHP2Shell vulnerabilities in core PHP affecting 70% of the web, using GPT-5.6 Sol; coordinated response over 2 months
AINews issue for 20-21 October 2026. The top story covers PHP2Shell (CVE-2026-109618 and CVE-2026-109619), two PHP-engine memory-corruption bugs found separately by Calif researchers using GPT-5.6 Sol under OpenAI's Patch the Planet and by Wiz, followed by two months of coordinated remediation. It also covers the Flint coding MoE, DeepSeek's DeepInfer, TorchTPU, eval critiques and agent product launches. The text is truncated.
 latent.spacearticlePublished and added 22 Oct 2026🧠 AI
- OpenAI CLI
OpenAI CLI is OpenAI's official Go command-line client for the REST API. It lets users generate images, upload and download files, create and wait on batches, call the Responses API, and query admin usage endpoints from a terminal or shell script. It supports JSON, JSONL and YAML output, GJSON transforms, shell completion, and install via Homebrew, go install or release binaries.
github.comrepoAdded 23 Oct 2026, published 22 Oct 2026🧠 AI - Monitorability Is Trainable: Post-Training for Chain-of-Thought Monitorability
Monitorability Is Trainable proposes an unsupervised post-training objective that maximizes mutual information between a model's chain of thought and its output. On three model organisms with degraded CoT (from compression, monitor optimization, and synthetic-document generalization), it recovers most or all lost monitorability. On undegraded policies it improves CoT monitor and activation probe prediction of unsafe behavior and raises consequential reasoning.
arxiv.orgpaperAdded 23 Oct 2026, published 21 Oct 2026🧠 AI  AI for the Fortune 2000: How Tenex Builds an AI-Native SDLC — Alex Lieberman & CJ Hess
Latent Space interview from AIE New York with Tenex cofounder Alex Lieberman and CJ Hess on running an AI-native engineering firm of 75 people. Covers story-point pay for engineers, the MetaHarness (plans, decisions and agent logs checked into Git with a CLI), roughly 2x engineer output in 2026, Opus 5.5 and Codex usage, and enterprise adoption rates. Also debates vertical AI and the Kill My SaaS experiment.
latent.spacetalkPublished and added 21 Oct 2026🧠 AI AI for the Fortune 2000: How Tenex Builds an AI-Native SDLC — Alex Lieberman & CJ Hess
Latent Space interview from AI Engineer New York with Tenex cofounder Alex Lieberman and CJ Hess. Tenex has 75 people, pays engineers by story points, and reports roughly 2x engineer output over the past year. CJ describes MetaHarness, a repo-based set of skills, plans and a CLI that logs agent decisions in Git. They also cover enterprise AI adoption rates, token spend, and vertical AI. The page text is truncated.
latent.spacetalkAdded 23 Oct 2026, published 21 Oct 2026🧠 AI- 0xMarioNawfal - The Roundtable Show (@RoundtableSpace) on X
TorchTPU is Google's open-source project for running PyTorch apps on its TPUs, announced the day after Amazon released TorchNeuron for its Trainium chips. Google says migration needs "a simple configuration change" with no rewrite. It worked with Meta, Hugging Face, and the vLLM and SGLang teams on compatibility, and added an agent suite that helps migrate apps and fix errors. The post is brief and gives no benchmarks.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026🧠 AI - 0xMarioNawfal - The Roundtable Show (@RoundtableSpace) on X
Headroom is an open-source GitHub project that compresses logs, files and tool outputs before they reach an AI coding agent. The tweet by RoundtableSpace claims up to 95% fewer tokens for JSON and about 20% fewer overall, with the same answers and lower API bills. The tweet gives no method or benchmarks, and the repo link is truncated.
x.comthreadAdded 21 Oct 2026, published 20 Oct 2026🧠 AI - Cache Engineering for Agents
Cache Engineering for Agents proposes letting LLM agents control their active KV cache directly, using a drop operation to exclude cache from attention and repos to adjust retained keys' position encodings, without editing the trajectory or re-prefilling. The authors build the AKV serving engine to handle history-dependent cache states. A tool-response rolling-drop policy raises average benchmark scores by 1.7 points and cuts cost by 27.7% against threshold-triggered summarization. AKV gives up to 1.2x output throughput and 1.5x faster P95 latency.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - Reward Misspecification Degrades Chain-of-Thought Monitorability
This paper shows that reward misspecification alone degrades chain-of-thought (CoT) monitorability in language models. Using a testbed of paired true and misspecified rewards across three models and three tasks, CoTs keep reasoning about task intent while outputs hack the reward. The proposed reward description training injects an LM-inferred reward description into the input and raises monitorability by an average of 24% or 42% absolute, depending on the metric.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - DeepInfer: High-performance inference framework for DeepSeek models
DeepInfer is DeepSeek's open-source inference framework for offline inference of DeepSeek-V4.1-Flash, released under Apache 2.0. It covers attention data parallelism, MoE expert parallelism with load balancing, draft-token decoding with confidence-scheduled verification, batch-invariant inference, deterministic sampling and structured outputs. It runs on NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs. The KV cache system, prefill/decode disaggregation and load balancing are not included.
github.comrepoAdded 21 Oct 2026, published 20 Oct 2026🧠 AI  Hugging Face ❤️ TorchTPU: TPUs, Natively
TorchTPU is a native PyTorch backend that makes Google TPUs a regular "tpu" device, replacing the older torch_xla path and Optimum TPU. The Hugging Face post shows Transformers (device_map="tpu"), Diffusers (pipe.to("tpu")) and Pallas kernels from the Kernels Hub running on it. It reports up to 21.5x faster decoding on Qwen3-30B-A3B at batch 64 and a 96.5% TPU test pass rate.
huggingface.coarticlePublished and added 20 Oct 2026🧠 AI- Same Simulation, Different Evidence: Where Retrieved Tool Output Costs LLM Agents Accuracy
This paper studies how keeping long tool output out of the context window, and reading it through a section index instead, costs LLM agents accuracy. Using the PHREEQC geochemistry simulator on 158 execution-verified multiple-choice items and 11,007 logged calls, GPT-5.1 and GPT-5.2 lose 11.3 and 7.9 points, while Claude Opus 4.6 and Sonnet 4.6 show no detectable cost. The authors name the failure evidence substitution: agents skip the report and misround from their own output files.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - EpiLens: Lightweight RAG for Epidemiological Knowledge Acquisition
EpiLens is a lightweight, open-source retrieval-augmented generation package that applies a fixed retrieval template and output schema to every paper in a corpus and links outputs to source passages. On a corpus of 2,297 epidemiology papers, its classifier matches or exceeds supervised and zero-shot baselines on four tasks without task-specific training data, scored against 214 manual labels. It also compares model-based study shares across parameters and pathogens.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - Advancing Coding in Low-Resource Programming Languages
OpenAI describes two evaluations for coding in low-resource languages such as COBOL, Fortran and Visual Basic. MultiLangBench has a model build a SQLite-compatible database engine in 20 languages. The COBOL migration eval requires byte-for-byte output parity. GPT-6 Astra scores 87.4% on MultiLangBench (GPT-5.6 Sol: 26.8%), and GPT-6.1 Sol reaches 86.6% on COBOL migration at low effort. The setup is on GitHub.
openai.comarticlePublished and added 19 Oct 2026🧠 AI - SpanGuard: Decoupling Instruction Localization from Authorization for Lightweight IPI Defense
SpanGuard is an indirect prompt injection (IPI) guardrail that splits detection into two steps. Lightweight unsupervised segmentation first locates candidate instruction blocks in tool outputs, then a small LLM judges whether each block is authorized by the user's request. The authors report a 0.32% attack success rate with negligible benign utility loss, and the guardrail still works with substantially smaller models.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🛡️ Security - From if to Oops: Turning a conditional into a key-recovery oracle
The paper presents a fault attack on deterministic CSIDH and OSIDH-LD. Forcing the lane-selection mask to zero (for example by skipping one instruction) makes output changes reveal whether a secret exponent reaches a threshold. Binary search then recovers the full key in at most 297 queries for OSIDH-LD and 222 for deterministic CSIDH with CSIDH-512-sized keys. Full OSIDH-LD keys were recovered in software fault simulation, and a ChipWhisperer-Lite skipped the target instruction with probability at least 0.94. The authors argue fault resistance requires giving up determinism and propose randomization countermeasures.
eprint.iacr.orgpaperAdded 20 Oct 2026, published 19 Oct 2026🛡️ Security - DeepSeek V4.1 Flash 1017 (Max)
DeepSeek V4.1 Flash 1017 (Max) is an open-weights reasoning MoE model from DeepSeek with 552B total and 16B active parameters, a 1M-token context window, text and image input, and an MIT license. Artificial Analysis scores it 45 on its Intelligence Index (open-weights median 19), at $0.30 input and $1.20 output per 1M tokens, 216 tokens per second, and 210M tokens used in the evaluation. It is available through 10 API providers.
 artificialanalysis.aiotherAdded 20 Oct 2026, published 19 Oct 2026🧠 AI
 Putting models to the secure coding test: Security rules
Second post in a Datadog Security Labs series testing whether Project CodeGuard (v1.4.0) security rules improve code written by coding agents. Sonnet 5 (Claude Code), Composer 2.5 (Cursor) and GPT 5.5 (Codex) each built the same document portal, and the output was audited with Datadog Code Security and a Sonnet 5 code review. Only GPT 5.5 closed the cross-user IDOR; Sonnet 5 and Composer 2.5 stayed largely unchanged, including hardcoded JWT secret fallbacks and incomplete revocation.
 securitylabs.datadoghq.comwriteupAdded 29 Oct 2026, published 19 Oct 2026🛡️ Security
- llm-echo 0.5
llm-echo 0.5 is a debug plugin for Simon Willison's LLM CLI. It adds an "echo" model that calls no LLM and repeats the prompt back as JSON. The release updates simulated token usage counts to include tool calls, system prompts and reasoning tokens. An example run with `-o thinking 1 --usage` reports 2 input and 24 output tokens. Willison is testing PRs ahead of a new LLM release.
simonwillison.netarticleAdded 19 Oct 2026, published 18 Oct 2026🧠 AI



Showing 60 of 367
Show more