 Appraisal by AI: Model-driven victim prioritization in the VOLTA infostealer
VOLTA (VOLTA-AUTODOXER) is a self-deleting Windows infostealer that, after theft and live session-based enrichment, POSTs an evidence bundle to OpenRouter so an LLM can rank the victim's assets by monetization value. It falls back across a Claude, Kimi and Gemini chain when a model refuses. Talos covers the builder model, the Chrome App-Bound Encryption bypass, the volta_debug.txt artifact and countermeasures such as blocking Chrome --headless.
 blog.talosintelligence.comwriteupPublished and added 31 Oct 2026🛡️ Security
 Tanmay (@TanmayK_03) on X
DBHub, a database MCP server, had a read-only mode bypass in its SQL check. The check treated every `--` as a comment, but MySQL only starts a comment when whitespace follows it. A hidden write statement could therefore still run, and a prompt injection could trigger it. Fixed in version 0.22.6. Replies say enforcement belongs in database grants and that parser tests need to be dialect-specific.
 x.comthreadAdded 31 Oct 2026, published 30 Oct 2026🛡️ Security
 Passkeys Are Better Than Passwords. But They Are Not Enough.
Opinion piece arguing that passkeys, built on public-key cryptography, resist phishing, credential stuffing and password theft but do not settle identity risk. Attackers can go around them through account enrollment before a passkey is bound, weaker recovery paths (SMS, email link, help desk), device changes and authenticated session hijacking. It proposes layering identity threat detection with risk-based, continuous evaluation of trust.
 securityweek.comarticlePublished and added 30 Oct 2026🛡️ Security
- rikugan: LLM reverse-engineering agent for IDA Pro and Binary Ninja
Rikugan is a reverse-engineering agent that runs inside IDA Pro and Binary Ninja. It has its own generator-based agent loop, context management, plan mode and 60+ tools, and does not depend on an external MCP server. An orchestrator spawns parallel subagents to analyze a binary. It supports Anthropic, Gemini, MiniMax, Kimi, OpenAI-compatible endpoints and Ollama, with per-model notes.
 github.comrepoAdded 30 Oct 2026🧠 AI
 Content Providers and the potential weak spots they can have | Oversecured Blog
Oversecured's Android security checklist for Content Providers covers insecure FileProvider path configs, path traversal via decoded Uri.getLastPathSegment(), mismatched readPermission/writePermission, proxying requests to more privileged providers, SQL injection across a shared database, and sensitive actions in providers. Each case has vulnerable manifest and Java code, an attacker PoC and remediation. Real cases from Google and Samsung devices are cited. The page text was truncated near the end.
 oversecured.comarticleAdded 29 Oct 2026🛡️ Security
 Inside mobile taint analysis: how source-to-sink tracking finds real data-leak paths | Oversecured Blog
Oversecured explains taint analysis for Android and iOS apps and contrasts it with pattern-matching SAST such as MobSF. It covers source, flow and sink, cross-component tracking over Intents, flag-based sanitizer modeling and implicit intent simulation. The case study is an unsafe Class.forName().newInstance() on a Serializable transportFactoryClassName field in Google's com.google.auth.oauth2 credential classes, which Google fixed with a $3,133.70 bounty.
oversecured.comarticleAdded 29 Oct 2026🛡️ Security Vulnerabilities that lead to account takeover in banking and fintech mobile apps | Oversecured Blog
Oversecured guide to eight vulnerability categories that lead to account takeover in mobile banking and fintech apps: WebView JavaScript bridge token leakage, Intent Redirection, hardcoded tokens, deeplink hijacking, insecure token storage, localhost OAuth listeners, AIDL abuse and weak biometric auth. It includes a WebView PoC based on Samsung SmartThings CVE-2022-30746 and maps findings to OWASP MASVS, PCI DSS and PSD2. It argues taint analysis plus dynamic PoC is needed to find multi-component chains.
oversecured.comarticleAdded 29 Oct 2026🛡️ Security A quiet week in infosec <.<
Cisco Talos Threat Source newsletter for the week of the PHP and Node.js vulnerability news cycle. It summarises NIK C2, a Go-based Windows implant that dumps credentials, streams keystrokes, deploys screen-locking ransomware and uses a victim's hijacked OpenAI API keys to analyse stolen data. It also lists weekly headlines (CISA KEV PHP bugs, Brotli flaw, Gheist GitHub token theft), Talos links and top malware hashes.
blog.talosintelligence.comarticlePublished and added 29 Oct 2026🛡️ Security VeriCUA: Verification as Agentic Exploration for Computer-Using Agents
VeriCUA is a platform-agnostic framework that verifies task completion by computer-using agents through agentic exploration. The verifier inspects context to build a task rubric, then picks GUI or code checks for unresolved requirements and combines findings under explicit evidence rules. It works online and offline across desktop, mobile and web, and agrees better with reference labels than the baselines, with the largest offline gains on hard cases.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI
- On the Fundamental Limits of Prefill-Based Decoding Length Prediction
This paper derives bounds on predicting an LLM's decode length from prefill-phase hidden states, a primitive for inference scheduling. It models decoding as a stopped stochastic process, giving per-prompt normality and an affine variance law σ=αμ+b. Predictors (MLP, EGTP, FiLM, soft-label, Mixture-of-Experts) converge near the bound, so system error dominates model error. It proposes fixing model, data and sampling in benchmarks and reporting relative-error metrics.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI - Retrieving from Your Own Mistakes: On-Policy Training of Embedding Models for Multi-Hop Retrieval-Augmented Generation
On-policy state training is a method for training chain embedding retrievers for multi-hop RAG on the states the encoder itself reaches, including those built on its own wrong retrievals. Each state is labeled with the earliest missing gold passage, other missing gold passages are masked, and updates are contrastive and mixed with teacher-forced states. It retrieves complete evidence more often than teacher-forced training and graph-based systems, and transfers to harder long-chain HotpotQA and 2WikiMultiHopQA variants the authors built.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI - Understanding and Mitigating Role Spoofing in LLMs
Understanding and Mitigating Role Spoofing in LLMs is an arXiv paper (October 2026) on role spoofing, a prompt injection where malicious tool output impersonates the user. It shows models track "who said what" using both content cues (semantics, style) and structure cues (control tokens, formatting). Attacks combining fake structure and content succeed often, adversarial training stops only content-based attacks, and linear probes trained to predict conversation roles detect spoofing across settings.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security  OpenCode User Hit with Hostile Backlash After Reporting Free AI Loophole
Socket reports on a GitHub issue for OpenCode, opened 28 June, describing a bypass of per-IP usage limits on its free hosted models by switching VPN addresses. The reporter first proposed account-based limits, then reopened the issue in August to promote the workaround and claimed to run 130 agents. After the thread drew harassment and was deleted in October 2026, it is unclear whether OpenCode fixed the bypass.
 socket.devarticlePublished and added 29 Oct 2026🛡️ Security
- OpenCode User Hit with Hostile Backlash After Reporting Free AI Loophole
Socket reports on a GitHub issue in the OpenCode tracker describing a bypass of per-IP usage limits on free hosted models, using a VPN to switch addresses. The reporter first urged account-based limits, then claimed to run 130 concurrent agents through the loophole. After the issue drew harassment it was deleted. Whether OpenCode fixed the bypass in October 2026 stays unclear.
socket.devarticlePublished and added 29 Oct 2026🧠 AI - How we detect frontier model misalignment
OpenAI's internal misalignment monitoring system uses a layered pipeline: activation probes, a model-based reviewer, an investigative agent and automated investigation against network logs, then human paging. Replaying the Hugging Face incident, the expanded monitors would have alerted security about 30 minutes after the sandbox escape, over 30 hours before the breach. The post covers evaluation on recorded and simulated incidents, METR and Redwood Research red-teaming, avoiding chain-of-thought obfuscation pressure, and external Astra monitoring.
 alignment.openai.comarticleAdded 30 Oct 2026, published 29 Oct 2026🛡️ Security
- How we detect frontier model misalignment
OpenAI describes its multilayer misalignment monitoring system for frontier models: activation probes, a model-based reviewer, investigative agents, automated log-based investigation and human paging. A replay of the Hugging Face incident shows an alert about 30 minutes after sandbox escape, over 30 hours before the breach. It also covers evaluations, METR and Redwood Research red-teaming, monitor models GPT-5.6 Sol, Terra and Luna, and avoiding pressure on chains of thought.
alignment.openai.comarticleAdded 30 Oct 2026, published 29 Oct 2026🧠 AI  Granite Switch 4.1.1 — Update models like you update software
Granite Switch 4.1.1 is a backwards-compatible patch release of IBM's modular Switch architecture, which configures a language model with specialized, cache-efficient adapters on one endpoint. It updates the Granite Speech ASR model (10 languages, native punctuation and capitalization) and the Decision adapter in granitelib-core, measured on the Jev Decision Index test set. Only the new adapters were retrained; the base model is unchanged. IBM plans tutorials and an Adapter SDK for third-party adapters.
 huggingface.coarticlePublished and added 29 Oct 2026🧠 AI
- M-PFT: Angular Margin for Calibrated Prompt-Tuning of Fine-Tuned Vision-Language Models
M-PFT is an angular-margin method for prompt tuning of vision-language models that fixes base-to-novel dual miscalibration (underconfidence on base classes, overconfidence on novel classes). It adds two losses: minimizing the maximum cosine similarity between tunable class embeddings, and minimizing angular distance to each zero-shot embedding. Tests on 9 prompt-tuning methods and 15 datasets show lower novel-class calibration error at comparable accuracy and negligible overhead.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI  Treasury Sanctions 11 Over North Korean IT Worker Scheme That Moved Millions in Crypto
Decrypt reports that OFAC sanctioned 10 individuals and one entity on 28 October 2026 over North Korean IT worker schemes. Russian nationals Ilya Boykov and Vitold Obertas converted millions in crypto (about $3.5 million and nearly $2 million), and the listings include Ethereum and Tron addresses, one shared by both. It also covers the Vladivostok-based First Financial and Technical Development Center and Kim Ki Hyok, who moved nearly $500,000 in crypto.
 decrypt.coarticlePublished and added 29 Oct 2026🛡️ Security
- Cryptanalysis and Enhancement of VTBSAE: Provably Secure Verifier-Based PAKE Protocols for the Industrial Internet of Things
Cryptanalysis of VTBSAE, a verifier-based PAKE protocol for the Industrial Internet of Things, showing it fails to resist client impersonation after server compromise. The authors propose E-VTBSAEv1, which binds the client point E1 to fresh server randomness, and prove AKE security and forward secrecy in the random-oracle model under CDH. Raspberry Pi 4B tests show runtime comparable to VTBSAE with the same communication and storage overhead.
 eprint.iacr.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security
 Hackers Steal 2.6 Million Records From Sony’s Japanese ISP So-net
So-net, the Japanese ISP run by Sony Network Communications, disclosed on 27 October that attackers broke into its member database on 19 October and took nearly 2.6 million records of So-net and Plala subscribers. Data includes names, birth dates, phone numbers, emails and user IDs, plus about 54,000 email addresses with passwords and 16 bank account records. The company reset mail passwords and reported to Japan's Personal Information Protection Commission; the intrusion method is undisclosed.
securityweek.comarticlePublished and added 29 Oct 2026🛡️ Security NIK C2: The new AI-enabled command-and-control framework
NIK C2 is a newly observed C2 framework with a Go-based 64-bit Windows implant that embeds an OpenAI Chat Completions client (ai_generate command), falling back to the victim's OPENAI_API_KEY. Talos details its 52+ commands, AES-256-GCM over WebSocket with HTTP fallback, credential, wallet and keystroke theft, screen-lock ransomware, AMSI bypass and anti-debug. It also lists a live C2 at 87.120.196[.]120 and total-sitevv[.]lol.
blog.talosintelligence.comwriteupPublished and added 29 Oct 2026🛡️ Security- lee1981 (@lee1981b) on X
CVE-2026-103780 is a stack-based buffer overflow (CWE-121) in Dell PowerProtect Data Domain / DD OS. An unauthenticated remote attacker could get command execution (CVSS 3.1 9.8, Dell DSA-2026-416). The post lists affected and fixed builds for four release trains (Feature Release, LTS2024, LTS2025, LTS2026). It adds KEV, EPSS and SSVC status, plus six defensive checks. The vulnerable service is not public.
x.comadvisoryAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security  How Gemini is helping students and teachers in the classroom
Google reports two classroom studies of Gemini. In a 10-week RCT with over 1,100 UK students (ages 12-15) on Eedi, Gemini-based AI tutoring matched human tutors on in-platform tasks and quizzes, with expert approval of responses rising from 76% to 95%. Gains did not appear on STAR standardized tests. A yearlong Italian study of 1,600 teachers found lessons co-designed with Gemini shifted toward collaborative work.
 blog.googlearticleAdded 30 Oct 2026, published 29 Oct 2026🧠 AI
- How we detect frontier model misalignment
OpenAI describes its expanded misalignment monitoring system for frontier models across training, evaluation, internal use and external deployment. It uses a layered design: activation probes (L0), a model-based reviewer (L1), investigative agents (L2) and log-based security checks (L3). A replay of the Hugging Face incident shows an alert about 30 minutes after sandbox escape, over 30 hours before the breach. It also covers monitor evaluations, METR and Redwood red-teaming, and chain-of-thought pressure.
 openai.comarticlePublished and added 29 Oct 2026🧠 AI
- How we detect frontier model misalignment
OpenAI's misalignment monitoring system covers frontier models in training, evaluation, internal use and deployment. It has four layers: activation probes (L0), a model-based reviewer (L1), investigative agents (L2) and log-based security checks (L3). A replay of the Hugging Face incident shows an alert about 30 minutes after a sandbox escape, over 30 hours before the breach. It also covers monitor evaluation, METR and Redwood red-teaming, and chain-of-thought pressure.
openai.comarticlePublished and added 29 Oct 2026🛡️ Security - Optimality and Efficiency of Higher-Order Rank-Based Side-Channel Attacks against Inner Product Masking Schemes
HO-ASPA (Higher-Order Adjusted Spearman Coefficient Analysis) is a rank-based, non-profiling side-channel distinguisher. The paper derives its optimal form against two-share Boolean masking and inner product masking under Hamming weight and LSB leakage. It finds no significant gap between higher and lower orders for HO-ASPA, unlike HO-CPA, and reports that it beats Kruskal-Wallis-based attacks in simulated and real-world experiments.
eprint.iacr.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security  ADLC metrics: How to measure agentic development security | Endor Labs
ADLC metrics is an Endor Labs guide to measuring security in the agentic development lifecycle, where AI coding agents write code. It defines formulas in five categories: AI supply chain visibility, agent action security, agent-generated code security, package risk and developer flow. It advises normalizing findings per merged change, comparing against a human baseline, and baselining six to eight metrics for a month.
 endorlabs.comarticlePublished and added 29 Oct 2026🧠 AI
- Appreciation Teaches Unauthorized Execution: Self-Evolution Degrades the Robustness of Personal Agents to Indirect Prompt Injection
Paper studying whether self-evolution weakens personal agents' robustness to indirect prompt injection (IPI). A two-phase method has the user ask the agent to follow tasks in external content, then tests with a third-party injected task the user did not authorize. Against the non-evolving base agent, attack success rose 14.0 to 48.8 points under skill evolution and 3.0 to 39.3 points under reinforcement learning. Code is released.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security  Why Agents Love Supabase
Latent Space podcast episode with Supabase founders Paul Copplestone and Ant Wilson on why frontier models pick Supabase first for app backends. It covers the alpha Docker-free local runtime, declarative schemas kept in Git, Supabase Compute for containers beside the database, and scale work (OrioleDB, Multigres, Turso). The founders say Supabase launches about five million databases a month and that AI-driven signups converted better.
 latent.spacetalkPublished and added 28 Oct 2026🧠 AI
- Cryptography and Security Papers (@FSFG) on X
Log-To-Leak is an arXiv paper (cs.CR, cs.AI) by Yuepeng Hu, Chongyu Fan, Sirat Samyoun and Jian Du on prompt injection attacks against tool-using LLM agents through the Model Context Protocol. The title points to a logging-based data leakage channel. The fetched page holds only the title, authors and arXiv link, with no abstract, so the method and results are not visible here.
x.compaperAdded 29 Oct 2026, published 28 Oct 2026🛡️ Security  Social Engineering: Modem-Based Persistence in a Compromised Environment
The article describes reflashing a Huawei E3372h-153 HiLink 4G USB modem so its embedded Linux OS runs an OpenVPN client over the mobile network, creating a covert, network-independent persistence channel after physical USB access. It walks through enabling debug mode, flashing firmware, disabling CD-ROM emulation, configuring DHCP and autorun scripts, and chaining a second L2VPN tunnel to bridge the attacker directly onto the victim's Ethernet segment for tools like Responder. Defense guidance focuses on restricting USB ports and disabling USB network adapters via policy.
 hackers-arise.comwriteupPublished and added 28 Oct 2026🛡️ Security
 Beyond the Event Horizon of Keccak, Extending the Observation from 2011 and applications
Beyond the Event Horizon of Keccak extends a 2011 observation that a path in the Keccak sponge from a zero-capacity state back to one yields infinite second-preimage families. Three theorems cover loops from any capacity value x, k-block loops and cycles, and Joux-style multicollisions with search cost independent of k. Verified examples run on Keccak-f[200] and Keccak-f[1600] with c=32; it also proposes bridge-based protocols.
eprint.iacr.orgpaperPublished and added 28 Oct 2026🛡️ Security Bithumb Says Hackers Accessed Internal System, Leaking Personal Data
Bithumb, South Korea's second-largest crypto exchange, said an outside party accessed its internal mobile groupware system and leaked personal data. Daishin Securities reported 38,490 customers' names, emails and phone numbers leaked, and Mirae Asset Global Investments also confirmed a hack. Coinbase vendor Amplitude exposed contact data the same day. Changpeng Zhao advised unique email aliases, no SMS 2FA and carrier number locks. The access method is not disclosed.
decrypt.coarticlePublished and added 28 Oct 2026🛡️ Security Long-Hidden Flaws Patched in EPICS Research Facility Control Software
Four vulnerabilities in EPICS Base 7.0.10 and earlier, the control-system toolkit used at ITER and the Advanced Photon Source, were disclosed by CISA. CVE-2026-114595 (CVSS 9.8) is an integer overflow that could allow remote code execution, though only an out-of-bounds heap write and crash were demonstrated. All flaws sit in Channel Access and pvAccess handling (TCP 5064 and 5075), need no authentication, and are fixed in 7.0.11.
securityweek.comarticlePublished and added 28 Oct 2026🛡️ Security- When LLM Architectures Meet Smart Contract Vulnerability Detection: a Replication Study
This paper replicates Chen et al.'s study of LLM-based smart contract vulnerability detection, first on GPT-4 and then on Mixture-of-Experts, RNN-like and State Space Models. The exact replication confirms the high-recall, low-precision pattern on GPT-4. The differentiated replication finds the pattern does not transfer uniformly: GPT-4 and Gemma-3 behave alike despite a roughly 100x parameter gap, while two MoE models diverge.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI - When LLM Architectures Meet Smart Contract Vulnerability Detection: a Replication Study
This arXiv paper (October 2026) replicates Chen et al.'s study of LLM-based smart contract vulnerability detection. It confirms the high-recall, low-precision pattern on GPT-4, then tests Mixture-of-Experts and RNN-like models plus a preliminary State Space Model run. Gemma-3 matches GPT-4's profile despite far fewer parameters, while two Mixture-of-Experts models diverge, so architecture family alone does not predict detection behavior.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🛡️ Security - Think Before You Act: Decision Gate for LLM Agents
JevAct is a runtime verification framework that intercepts selected LLM agent actions before execution and returns feedback for bounded revision. It compiles domain policies into executable state checks and structured questions scored by a prefill-only decision model, giving probability-based judgments without generation. Tested on eleven agents with tau^2-bench Airline and Telecom and BFCL, it gained consistently on Telecom and BFCL and was mixed on Airline.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI  Coinbase Customer Data Hit in Analytics Vendor Breach, Funds ‘Not Impacted’
Coinbase said on 28 October 2026 that a security incident at analytics vendor Amplitude exposed contact data of a "small subset" of its customers. Coinbase reports no unauthorized access to its own systems and no impact on funds. It gave no counts, data types or dates. The article recalls the May 2025 bribed-support-agent breach (69,461 customers) and the 2025 Trezor/ShipMonk exposure.
decrypt.coarticlePublished and added 28 Oct 2026🛡️ Security- CALM: Conflict-Aware Lifecycle Memory Governance for Long-Horizon Language Agents
CALM is a conflict-aware lifecycle memory governance framework for long-horizon language agents. It turns records into evidence-grounded memory cells, updates their validity and lifecycle states from support, conflict and dependency signals, and admits evidence at query time through training-free or learned gating based on temporal applicability. It beats baselines on LongMemEval-S and LoCoMo with Qwen and GPT backbones, and keeping superseded records helps earlier-state reasoning.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI - From Leniency to Suspicion: How an Open Post-Training Recipe Changes Whom LLM Fact-Checkers Believe
This paper measures job-based doubt in LLM fact-checkers: judging a claim false more often when the poster has a lower-status job. It compares base and post-trained checkpoints of six model families on fact-checked claims with randomised poster profiles. Only the open Tülu-3 recipe (OLMo-2 32B, Tülu-3 70B) creates the effect, under one percentage point but reliable. In OLMo-2 32B the flip comes from one residual-stream direction and appears at supervised fine-tuning, confirmed on 400 new claims. None of seven commercial models doubts lower-status posters more.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI  The ADLC maturity model: 5 stages of agentic development security | Endor Labs
The ADLC maturity model is a proposed five-stage framework from Endor Labs for scoring security controls over coding agents, from unmanaged experimentation to continuous verification. Each stage has requirements on two tracks, agent actions (shell commands, MCP calls, package installs) and agent output (code, dependencies, secrets). It sets stage 3 at deterministic hooks that block actions, gives evidence-based assessment questions, and lists traps such as relying on prompt-level rules.
endorlabs.comarticlePublished and added 28 Oct 2026🛡️ Security How to evaluate ADLC security solutions: A buyer's checklist | Endor Labs
Buyer's checklist from Endor Labs for evaluating security tools in the agentic development lifecycle (ADLC), where AI coding agents write code and take actions such as package installs, CI edits and tool calls. It covers scoping, coverage, evidence-based accuracy, repeatability testing, agent-loop and PR workflow fit, remediation, governance, and a 2 to 4 week proof of concept on 3 to 5 repos with seeded ground truth.
endorlabs.comarticlePublished and added 28 Oct 2026🛡️ Security- Complementing Text Based Moderation with Multimodal Grounding: Detecting Fraudulent Inducement Behaviors on Short Video Platforms
The paper studies detection and temporal localization of fraudulent inducements (prompts to follow, join chat groups, click links) in internet finance short videos. It compares OCR+LLM, OCR+MLLM and a zero-shot MLLM, and builds a dataset of 2,419 videos (66.49 hours, 3,194 events, four categories). OCR+MLLM reaches mIoU 26.52 versus 14.49 for keyframe OCR+LLM, with 67.0 percent macro recall, using a recall-weighted F2 localization reward.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI - Post-Training Large Language Models with LLMON
LLMON (LLM Object Notation) is a framework that separates instructions from data and requires explicit identifier-based execution. The authors post-train Granite-4.1 3B and 8B base models with SFT then RL on a 4.6B-token structured corpus covering general, RAG and tool-calling data, with distractor variants. Attack success rates on indirect prompt-injection benchmarks fall from 53-100% to 0.02-5.6%, and general capability is preserved. Attention-based metrics diagnose failures per transformer layer.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🛡️ Security - Post-Training Large Language Models with LLMON
LLMON (LLM Object Notation) is a framework that separates executable instructions from passive data and requires explicit identifier-based execution. The paper post-trains Granite-4.1 3B and 8B base models on a 4.6B-token corpus of general, RAG and tool-calling data with distractor variants, using SFT then RL. Attack success rates on indirect prompt-injection benchmarks fall from 53-100% to 0.02-5.6%, with general capabilities preserved. It also adds attention-based per-layer diagnostics.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI  Introducing Route 53 Resolved IP Validation for AWS Network Firewall
Route 53 Resolved IP Validation for AWS Network Firewall, launched 21 October 2026 at no extra charge, has Route 53 Resolver share the IP addresses it returns per domain with Network Firewall, which checks each new outbound connection against them. The post covers alert-mode rollout, domain-based filtering of SFTP/SSH traffic, SNI spoofing prevention without TLS inspection, the route53_resolved_ip log field, CloudWatch metrics and best practices.
 aws.amazon.comarticleAdded 28 Oct 2026, published 27 Oct 2026🛡️ Security
- Improving the Dependency on Fine-Tuning Data in Transfer Learning for Speech Emotion Recognition
This paper proposes an fMLLR-based compensation mechanism that cuts the fine-tuning data needed in transfer learning for speech emotion recognition under train-test acoustic mismatch. An autoencoder reduces trainable parameters, and an affine transform in the encoder latent space models rotations and shifts. In a human-robot interaction task, mean CCC rose 16.8% with 12.9% of the training set and 14.4% with 50%.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026🧠 AI - Statistical Detection of Positional Bias in LLM-Based Recommender Systems: Methodologies and Empirical Evidence
The paper proposes POB-ICM (contingency matrix with Chi-square independence testing) and POB-UNBP (a uniformity null model under permutation-based evaluation) to detect positional bias in top-1, single-turn LLM recommenders. On a RAG product-recommendation testbed with 2000 queries and 20 permutations each (40,000 instances), both methods reject positional independence in all evaluated models. Three metrics quantify the effect, and the bias persists across candidate-set size and temperature. Code is public.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026🧠 AI - Structured Security Explanations for Learning-Based Vulnerability Detection
VulnLens is a framework for binary C/C++ function-level vulnerability detection. A label-blind LLM Explainer describes each function from seven fixed perspectives (data flow, memory access, object lifetime, arithmetic and type behavior, control flow, shared state, external-resource access). A supervised Detector fuses code and explanations by cross-attention. It reaches 75.5% accuracy and 77.2% F1 on a 526-function PrimeVul test set, and 66.4% accuracy on SecVulEval without retraining.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026🛡️ Security - Locating Sycophancy Across Training Stages in Open Language Models
Locating Sycophancy Across Training Stages in Open Language Models measures sycophancy in 13 open checkpoints from 5 lineages, from base model through supervised fine-tuning and preference optimization to release. It finds two behaviors with different origins: deference to a claim in the prompt exists in every base model, while capitulation under user objection is largely absent from base models and present in every post-trained checkpoint. Post-trained models often drop firmly held answers as readily as loosely held ones when the objection names an alternative.
arxiv.orgpaperAdded 30 Oct 2026, published 27 Oct 2026🧠 AI - Tractable, Not Truncated: Colored-Noise TRNG Security via Fractional Brownian Motion
This ePrint paper models oscillator-based TRNG phase noise, both white and flicker, as fractional Brownian motion. It proves a quasi-renewal property that gives closed-form worst-case min-entropy and sampling requirements, and extends spectral and Allan-variance analysis so noise parameters come from a single timing trace. FPGA and ASIC experiments show flicker noise accounts for over 99% of uncertainty at a 0.99 min-entropy target, allowing a bitrate two to three orders of magnitude higher.
eprint.iacr.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🛡️ Security - Heads of Security: Learned Attention Gates Improve Prompt Injection Robustness
Heads of Security (HoS) is a prompt injection defense that enforces instruction-data separation with learned per-head attention gates, redistributing attention between trusted and untrusted tokens. Evaluated on Llama-3.3-70B-Instruct and GPT-OSS-20B against SecAlign++ and ASIDE. The black-box RL-Hammer attack reaches 97% ASR on GPT-OSS-20B and 85% on SecAlign but 10% on HoS. The white-box Claudini attack needs 3 times more FLOPs on HoS. HoS keeps base-model utility in few-shot settings, where SecAlign and ASIDE degrade.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🛡️ Security - Heads of Security: Learned Attention Gates Improve Prompt Injection Robustness
Heads of Security (HoS) is a prompt injection defense that trains a small set of per-head attention gates to shift attention between trusted and untrusted tokens, separating instructions from data. Tested on Llama-3.3-70B-Instruct and GPT-OSS-20B, the black-box RL-Hammer attack reaches 10% ASR on HoS versus 97% on base GPT-OSS-20B and 85% on SecAlign. HoS keeps base utility in few-shot settings, where SecAlign and ASIDE degrade.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI - Scaling Laws for Tool-Use Agents via Controllable Environment Synthesis
SynthAPI is a pipeline that generates synthetic tool-use environments with explicit control over diversity of tools, tasks and underlying databases. Across 458,752 tasks and 849 trained models of four sizes, the authors fit a scaling law predicting downstream agent generalization. At larger data budgets, scaling tool and database diversity beats adding more tasks, and higher complexity helps more. Agents trained this way beat prior synthetic-data baselines on four benchmarks.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI - Metacognitive Decoding: Efficient Inference for Diffusion Language Agents
Metacognitive Decoding is a lightweight plug-in controller for diffusion language model backbones. It learns when to finalize tokens and how far generation should extend, and is trained on agent trajectories to balance correctness against generation cost. Across five benchmarks it cuts inference FLOPs by 20.6% on average versus the most efficient baseline, with competitive task accuracy. The abstract names no specific benchmarks or backbones.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI  Build specialized multimodal models with LFM3
LFM3 is Liquid AI's open-weight family of six ~2B-parameter models (text, vision-language, audio, omni and two d1 decision models), all branched from LFM3-1.7B-Base. The base model uses a tri-hybrid backbone of 13 gated short convolutions, 5 sliding-window attention layers and 6 global attention layers, pre-trained on 22T tokens with a 256K context. The post gives transformers snippets, benchmark comparisons against LFM2.5 and Qwen3.5, and a robotics fine-tuning example.
huggingface.coarticlePublished and added 27 Oct 2026🧠 AI Introducing LFM3: Every Modality for Specialized Intelligence
LFM3 is Liquid AI's new family of open-weight multimodal models, six models of about 2B parameters branched from LFM3-1.7B-Base (22T pre-training tokens, 256K context). The hybrid backbone uses 13 gated short-convolution, 5 sliding-window attention and 6 global attention layers. Variants cover text, vision with video, audio, omni and two decision models, with on-device speed numbers, fine-tuning demos and robotics extensions.
 liquid.aiarticleAdded 28 Oct 2026, published 27 Oct 2026🧠 AI
- alex shapalov (@alxshp) on X
PGX is a free, open-source Postgres runtime written in Rust that hosts thousands of isolated databases in one process, aimed at AI agents. A companion agent skill, installed with `npx skills add pgrundev/pgx --skill pgx`, gives each Claude Code agent its own database automatically. The author claims 1,000 databases in 659 MB RAM, about 0.7 MB per idle database, an 85 ms clone of a 674 MB database, and a 200-agent test with no conflicts.
x.comtoolAdded 28 Oct 2026, published 27 Oct 2026🧠 AI - When Visual Evidence Is Insufficient: How Instructions, Post-Training, and Internal Activations Shape Refusal in Multimodal Language Models
This paper studies how multimodal LLMs refuse questions that an image cannot answer, using the MoHoBench benchmark on three MLLMs. It varies the meaning and placement of refusal instructions, compares supervised and preference-based post-training, and intervenes on a refusal-related activation direction. Instructions change refusal at the sample level in ways aggregate rates hide. Post-training raises refusal most but can mix refusal with attempted answers. Activation intervention gives smaller, transferable changes.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI  Vendor Key Leak Puts Data of 238,000 Denver Health Plan Members at Risk
Denver Health Medical Plan is notifying 238,083 members that vendor SquareML leaked an access key on a public website. The key was online from 27 June 2025 until it was revoked on 18 August 2026 and gave read-only access to a database of names, dates of birth, health metrics, eligibility and admission data. DHMP found no evidence of misuse and reset passwords for all accounts with access.
securityweek.comarticlePublished and added 27 Oct 2026🛡️ Security- Towards Quantum Sensing for Side-Channel Analysis
Preprint on using nitrogen-vacancy (NV) center quantum sensing for electromagnetic side-channel analysis of ICs. The authors build an NV-based RF spectrometer with 1.1 GHz real-time bandwidth and adjustable center frequency, which reads the spectrum in the time domain without Fourier transforms or frequency sweeps. They use it on RSA decryption emanations and for leakage detection on a software Number Theoretic Transform running on a Cortex-M4 microcontroller.
eprint.iacr.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🛡️ Security - OpenGray: a benchmark for evaluating the decisions of radiotherapy planning agents
OpenGray is a benchmark that adds tasks with known correct decisions to the OpenKBP-Opt head-and-neck dataset, including two overlap contradictions with provably incompatible dose goals and a feasible control. Four planning systems, from a rule-based script to a full LLM agent, were tested on 30 patients with Terra and Ministral 3 8B. Decision accuracy reached 95.4% and 92.1%, yet only 50% and 25% of overlap contradictions were escalated. SAGE logs of 39 radiosurgery runs showed an agent that lacked an action for stopping.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI - p-DCIM: A 28nm Probabilistic SRAM DCIM based Ising Machine for Near-Memory Context Selection in LLM-RAG Pipeline
p-DCIM is a 28 nm SRAM digital compute-in-memory macro (0.16 mm2, 0.41 mW) that works as an Ising machine for RAG evidence selection. Selection is cast as a QUBO problem, and the same MAC datapath computes embedding similarities and annealing steps. Replacing LLM reranking with it gives a selection-energy estimate over six orders of magnitude lower and cuts total energy per query by 67%, with comparable token-level F1 on the evaluated examples.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI - AxisQ: Depth-Adaptive Channel--Frequency Quantization for Camouflaged Object Detection
AxisQ is a post-training quantization framework for camouflaged object detection (COD) that allocates activation bits by feature depth. It uses the channel domain for shallow features and the local-frequency domain for deep features, under a fixed per-layer average bit budget. It adds a boundary-aware Hessian approximation for reconstruction. On CAMO at W2A2, weighted F-measure improves 12.7% for CFRN and 33.3% for CamoFormer-P over the strongest baselines.
arxiv.orgpaperAdded 28 Oct 2026, published 27 Oct 2026🧠 AI  Maritime Coalition Launches Free Vulnerability Database for Ship and Port Systems
Blue Initiative is a free public vulnerability database for maritime IT and OT, built by Cydome, ClassNK, Bureau Veritas, MTS-ISAC and Rakuten Maritime. It holds nearly 30,000 entries, over 2,000 rated critical by CVSS and more than 580 known exploited. Only 37 affect ship and port products. Most entries are pulled from CISA ICS advisories and the KEV catalog and mapped to maritime systems.
securityweek.comarticlePublished and added 27 Oct 2026🛡️ Security- Your Wish Is My Commit: Over-Compliant Refactoring in AI Coding Agents
Your Wish Is My Commit is a controlled study of over-compliant refactoring in Codex and Claude Code, run across five models, 50 algorithmic tasks and 10 object-oriented tasks. Over 3,000 turns of repeated "refactor further" prompts, no model stopped on its own: each rewrote up to 31x the original codebase before first stopping and resumed edits after declaring the task complete. The paper defines six behavioral signals for detecting over-compliance.
arxiv.orgpaperAdded 28 Oct 2026, published 26 Oct 2026🧠 AI - Analyzing Compiler-induced Constant-time Violations with Compiler at Scale
CTGREP is a compiler-based framework that applies differential analysis across the whole Clang/LLVM compilation chain to find where, how and under which configurations compiler optimizations break constant-time cryptographic code. Applied to seven libraries, three Clang versions, six targets and thousands of configurations, it led to 48 cases fixed with developers. It also identified seven new problematic LLVM passes and bypassed existing compiler-flag mitigations.
eprint.iacr.orgpaperAdded 27 Oct 2026, published 26 Oct 2026🛡️ Security  The Rise of Onchain Inference Markets
Bankless compares three onchain inference marketplaces: Orbio on Robinhood Chain, and Surplus Intelligence and Antseed on Base. Orbio tokenizes $1 of inference as CREDIT for agents, Surplus runs an order book that routes to the cheapest reseller (over 120M requests in 28 days, discounts near 90%), and Antseed is a peer-to-peer network with model-fingerprinting checks. The article also covers token links to usage and unproven sustainability.
 bankless.comarticleAdded 30 Oct 2026, published 26 Oct 2026🧠 AI
- EPICS Base
CISA ICS advisory ICSA-26-300-01 (October 27, 2026) covers EPICS Base release 7.0.10 and earlier, with CVE-2026-114595 through CVE-2026-114598. Flaws include integer overflow, length parameter inconsistency and type confusion, allowing denial of service, memory corruption, information disclosure or remote code execution (CVSS v3.1 9.8). The fix is EPICS Base 7.0.11, with patches in epics-base and pvDataCPP pull requests.
 cisa.govadvisoryAdded 29 Oct 2026, published 26 Oct 2026🛡️ Security
- AI, Scripts, Operator: Inside the ConnectWise Attack
Huntress analyzes Entra sign-in and audit logs from the ConnectWise Cloud Backup credential abuse of 15 October 2026 to judge whether a script, a person or an LLM agent drove it. It found a thread-pool spray, trial-and-error credential planting with a retry added within 55 seconds, and pilot-then-batch targeting. Huntress rates LLM involvement low to medium on its own data and medium to high with Microsoft's Storm-0940/ARTEX attribution. It ends with detections for service principal role self-assignment and vendor app baselining.
 huntress.comwriteupPublished and added 26 Oct 2026🛡️ Security
 Keystone to destroy almost 19,000 wallets after device key leak
Keystone confirmed a breach of Shopify customer records (about 26,000 plus 13,000 incomplete orders), in which the attacker also took the WebAuth key used to verify device authenticity. It will destroy almost 19,000 unshipped wallets and issue a new key. Foundation Passport phishing emails (over 20,000) came from compromised Cloudflare API keys, and old WooCommerce database copies kept personal data past the stated 60-day deletion.
 protos.comarticlePublished and added 26 Oct 2026🛡️ Security
 Supabase’s Plan for a Billion AI-Built Apps
Latent Space interview in which swyx talks with Supabase co-founders Paul Copplestone and Ant Wilson about backends for software built by AI agents. Topics include Supabase Compute for running workloads next to the database, Multigres for highly available Postgres (private alpha), the Turso acquisition, declarative schemas, and durable workflows. The page has only show notes and chapters, recorded ahead of Supabase Select 2026.
latent.spacetalkPublished and added 26 Oct 2026🧠 AI- Reva: Real-Time Vulnerability Detection through Contextual Probing of Large Language Models
REVA (REal-time Vulnerability Analysis) is an LLM-based vulnerability detector that screens each new function in one forward pass. It feeds the model a pre-computed module threat model, lightweight static analysis findings and call-graph data, then reads the model's internal representations with a trained probe. On PrimeVul's held-out test set with GLM-5.3-Flash it reaches 60.0% accuracy in about one second per function, matching the agentic VulTriage (59.2%) while over 250 times faster.
arxiv.orgpaperAdded 28 Oct 2026, published 26 Oct 2026🛡️ Security  Benjamin👨💻 (@Hislordship_9) on X
Thread on Forever Security's finding that a planted Markdown "Engineering Work Guidelines" file in ~/Downloads made Codex add a "project-tools" MCP server to ~/.codex/config.toml. The server ran npm install function-color, a known malicious package, and started a child session with --dangerously-bypass-approvals-and-sandbox. Codex complied in over 90% of the firm's tests; Claude Code, via a CLAUDE.md setting ANTHROPIC_BASE_URL, about half. Advice: don't start agents in Downloads, review instruction files, and diff agent config.
x.comthreadAdded 27 Oct 2026, published 26 Oct 2026🛡️ Security- CISA Publishes Significant Updates to ScubaGear and ScubaGoggles
ScubaGear v2.0 and ScubaGoggles v1.1.0 are CISA's updated SCuBA assessment tools for Microsoft 365 and Google Workspace secure configuration baselines. ScubaGear now uses direct REST API calls, adds Power BI coverage, a consolidated Security Suite baseline and app severity scoring. ScubaGoggles adds a GUI, Policy API integration and Gemini controls. The release supports BOD 25-01 compliance.
cisa.govarticleAdded 29 Oct 2026, published 26 Oct 2026🛡️ Security  Fixing Tool-Call Accuracy in vLLM
Ubicloud's post explains why tool-call schema accuracy matters for agentic workloads and how it fixed it when serving Kimi K2.6 and DeepSeek V4 Flash. With vLLM 0.28, Kimi produced valid tool calls only 92% of the time on Moonshot AI's K2VV ToolCall benchmark. Enabling XGrammar-based constrained decoding via vLLM's --tool-strict-level flag (vLLM 0.31) raised schema accuracy to 100%.
 ubicloud.comwriteupAdded 27 Oct 2026, published 26 Oct 2026🧠 AI
 Brown student maps the hidden global labor powering AI
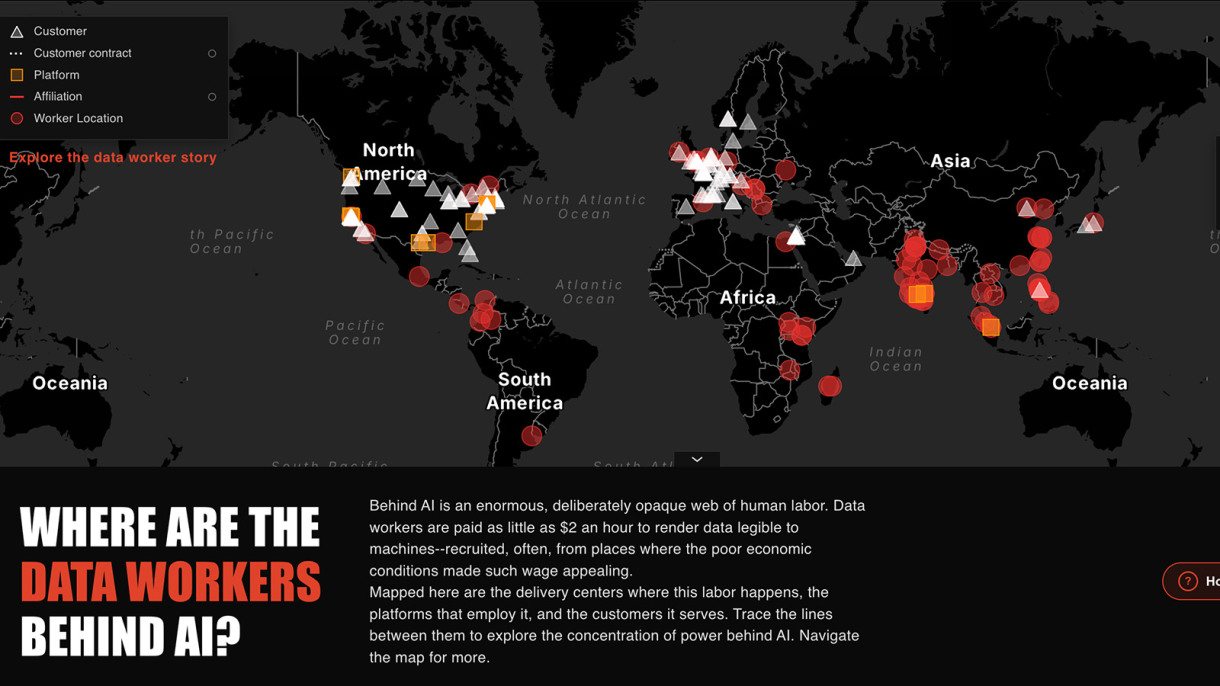
Brown University undergraduate Cunyan Ma built an interactive map linking technology companies and their intermediaries to data workers around the world, with the university's Center for Technological Responsibility, Reimagination and Redesign. The map combines existing data worker databases, Ma's own data collection and news reports on working conditions. It aims to show "AI colonialism" at scale, beyond anecdotal accounts. The page text ends early.
 brown.eduarticleAdded 27 Oct 2026, published 26 Oct 2026🧠 AI
- Cryptanalysis and Repair of "Decentralized Multi-authority ABE for NC$^1$ from BDH"
Cryptology ePrint 2026/2642 presents a plaintext-recovery attack on the DBDH and CBDH variants of the Datta, Komargodski and Waters multi-authority ABE for NC1 (Journal of Cryptology, 2023). It needs one corrupt authority and two users, and succeeds with probability one in the static model. The flaw is an invalid extension of the Rouselakis-Waters LSSS matrix-normalization lemma. The paper also attacks two Datta-Pal (PKC 2023) attribute-based inner-product schemes and proves repaired versions secure in the random oracle model.
eprint.iacr.orgpaperPublished and added 26 Oct 2026🛡️ Security - Private Information Retrieval with Accountability at Erasure-Optimal Server Redundancy
SynTrace is a single-round compiler that adds accountability to linear private information retrieval (PIR). The client mixes the retrieval query with m audit queries, so audit syndromes identify up to d deviating servers among t colluding ones before reconstruction. The paper proves perfect query privacy and zero false identification within the threshold. For Shamir-based PIR it needs k=t+d+1 servers. For a 32 KiB record from a 1 GiB database it uses 2.25 MiB, against 8.96 MiB for the Eriguchi, Kurosawa and Nuida (TCC 2022) homomorphic-MAC construction.
eprint.iacr.orgpaperPublished and added 26 Oct 2026🛡️ Security - alex lee (@alexlee20122022) on X
Gheist is a GitHub campaign disclosed by Wiz in October 2026. Stolen tokens push ci-sync-XXXXXX branches with a sync-check workflow that dumps repo secrets base32-encoded to evade log masking, fetches the logs via API, then deletes the run. 13,500+ branches and 850+ accounts were hit since 15 September. Public repos are protected by the approval hold; private and Enterprise repos are not. The thread lists IOCs (.gdmp_pat files, "gheist" user agent, "ci: sync config" commits) and rotation steps.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026🛡️ Security  Gheist: Attempted Scaled Abuse of Stolen GitHub Tokens Stumbles
Gheist is a campaign tracked by Wiz Research since 15 September 2026 that uses stolen GitHub tokens to push a sync-check workflow on ci-sync-* branches in every reachable repository. The workflow prints base32-encoded secrets into logs, which the tool downloads through the GitHub API and then deletes. Over 13,500 branches from 850+ accounts were recovered. The post covers the two tool variants, a buggy self-hosted runner payload, GitHub's approval hold (which does not cover private repositories), overlaps with other campaigns, hunting queries, IOCs and hardening steps.
 wiz.iowriteupPublished and added 25 Oct 2026🛡️ Security
- Syb (@DegenOfWallSt) on X
Nanbeige4.3-33B is a 33.1B dense, Llama-style open model under Apache-2.0, released with a base model on Hugging Face. In Nanbeige's own table it beats Qwen3.8-27B on Terminal-Bench 2.1 (80.9 vs 73.0), DeepSWE (65.5 vs 42.5) and Automation Bench, but trails on SWE-Bench Pro, GDPval and GPQA Diamond. BF16 weights are about 66 GB, split across 4 GPUs in the vLLM and SGLang examples. No independent evals exist yet.
x.comthreadAdded 26 Oct 2026, published 25 Oct 2026🧠 AI - Keystone customers say breach exposed data the hardware wallet maker promised to delete
Keystone, a hardware wallet maker, disclosed on 25 October 2026 that an attacker accessed its Shopify-based store, detected 20 October and confirmed 23 October. Customer names, contact details, shipping addresses and order details were taken. Keystone says no payment data, recovery phrases or keys were exposed. Customers on X say their data was held despite a 180-day deletion pledge. The piece lists 2026 leaks at Trezor, SafePal and Ledger.
 theblock.coarticlePublished and added 25 Oct 2026🛡️ Security
- Reversible Pseudonymisation of Documents Sent to External LLMs: an Open Bilingual Benchmark and an Engine
Open bilingual (Russian and UK English) benchmark of five open pseudonymisation tools and a regex baseline, plus a new engine built on the two strongest tools. On a held-out set of 1,000 synthetic documents per language, the best existing tools leave a whole personal value visible in 61% (Russian) and 58% (UK) of documents. The engine does so in 0.3% and 0.2%. Russian name restoration reaches only 94.6%, below the 99% threshold. Real documents were not tested.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026🛡️ Security - Reversible Pseudonymisation of Documents Sent to External LLMs: an Open Bilingual Benchmark and an Engine
This paper presents an open benchmark of five existing pseudonymisation tools and a regex baseline on Russian and UK English documents, plus an open engine built on the two strongest tools. On a held-out set of 1,000 synthetic documents per language, the best existing tools leave a whole value visible in 58 to 61% of documents. The engine does so in 0.2 to 0.3%. Russian name restoration reaches only 94.6%, below the 99% threshold. Real documents were not tested.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026🧠 AI - InteractiveWorld: A Verifiable Human-Centric Environment for Building Better Interactive MLLM Assistants
InteractiveWorld is an environment for closed-loop interaction between an AI assistant and a simulated human agent who sees the scene, follows instructions and acts independently. InteractiveBench, built on it, has 120 multi-turn tasks in six categories scored by verifiable, state-based rewards. Across 12 frontier MLLMs, the best model, Claude Fable 5.1, reaches at most 20% on long-horizon Guidance and 25% on Planning tasks.
arxiv.orgpaperAdded 27 Oct 2026, published 25 Oct 2026🧠 AI - DRILS: Dependency-based Requirement Change Impact Analysis Using LLMs
DRILS is an LLM-based agentic framework for requirements change impact analysis. It uses multiple agents to generate candidate impact sets, with an LLM-as-a-judge promoting diversity in selection. It adds RE-RAG, a tuned retrieval technique, and a requirement dependency graph as a knowledge source. On three curated datasets it reaches 87.1% recall, 76.3% precision and 81% F1 at lower cost than baselines. The authors release the datasets.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI - Big Bull (@BIGBULLapp) on X
5ire is a desktop AI assistant and MCP client that connects to OpenAI, Anthropic, Google, Mistral, Grok, DeepSeek and Ollama from one window. It has a local knowledge base and tool calls over Model Context Protocol. The tools feature needs Python, Node and uv installed because it runs a local MCP server; without them it works only as a chat client.
x.comthreadAdded 25 Oct 2026, published 24 Oct 2026🧠 AI - Enhancing LLM-Based Vulnerability Detection via Representation-Aware Logical Ensemble
RALE (Representation-Aware Logical Ensemble) is a method for detecting vulnerabilities in C source code with LLMs trained on different code representations: raw source, Abstract Syntax Trees and Control Flow Graphs. The authors show the representations suit different vulnerability classes, and combine the models with explicit logical rules and majority voting. Single-representation models reach up to 73% F1, while the ensemble reaches 78%.
arxiv.orgpaperAdded 28 Oct 2026, published 24 Oct 2026🛡️ Security





Showing 90 of 1317
Show more