Skip to content

219 results for “Scale”

What you seeeverything
“Scale”
decrypt.coarticle🛡️ Security

UK Says AI-Powered Ransomware Attack on Critical Infrastructure 'Highly Likely' by 2028

Decrypt reports the UK NCSC's State of the Cyber Nation report of 3 November 2026. It says critical infrastructure should expect a ransomware attack involving AI-powered malware by 2028. NCSC chief Richard Horne argues AI exposes long-tolerated vulnerabilities at scale. The piece lists UK funding (£60 million Cyber Shield, £70 million exposure centre) and cites Google's May 2026 AI-assisted zero-day finding and a Cambridge forum study.

National Cyber Security CentreGCHQGoogle Threat Intelligence Group+3

Threat Intel, AI Security, GRC· Published and added 3 Nov 2026

securityweek.comarticle🛡️ Security

UK Cyber Chief Says the UK Will Face AI Cyberattacks on Critical Infrastructure by 2028

SecurityWeek reports on the UK National Cyber Security Centre's annual report, presented by NCSC head Richard Horne. It warns that criminals and states, including China and Russia, will likely use AI against UK critical infrastructure by 2028, mainly to scale existing techniques. It cites nearly $20 billion in yearly UK losses, Jaguar Land Rover's $260 million loss in 2025, and the FSB-attributed December 2025 attack on Poland's energy grid.

National Cyber Security CentreGCHQFSB+3

Threat Intel, AI Security, GRC· Published and added 3 Nov 2026

longcat.aiarticle🧠 AI

LongCat-2.5: Native Multimodality for Agentic Tasks

LongCat-2.5 is a native multimodal mixture-of-experts model with 1.6 trillion total and about 48 billion activated parameters, built on LongCat-2.0 for long-horizon agentic coding. The post describes discrete RVQ visual tokens, large-scale asynchronous agentic RL with synthesized F2P/P2P-tested environments, on-policy distillation, train-inference numerical alignment, and W4A4 inference on domestic accelerators. A table compares it with GPT-5.5, Claude-Opus-5, GLM-5.3, Kimi K3 and DeepSeek-V4.1-Flash.

Mixture of ExpertsResidual Vector QuantizationFlatQuant+8
LongCat-2.5LongCat-2.0LongCat-Next+32

models, training, multimodal, coding-agents· Added 3 Nov 2026, published 2 Nov 2026

blog.trailofbits.comarticle🛡️ Security

Backporting security fixes at scale with Codex

Trail of Bits describes a Codex (GPT-5.6) workflow that backports security fixes to stable Linux kernel trees, Ubuntu LTS and Fedora. By 29 October 2026 it had helped land fixes for 149 CVEs in stable kernels. Agents find missing fixes, adapt patches and assemble validation evidence; a human review takes about 30 minutes to 3 hours. It also sizes the unfixed-CVE backlog in kernel branches, Debian 13 and Ubuntu 26.04.

CodexLinux kernelLinux+3
CVE-2026-98432Trail of BitsPatch the Planet+1

AI Security, AppSec, Cloud & Infra· Published and added 2 Nov 2026

blog.trailofbits.comarticle🧠 AI

Backporting security fixes at scale with Codex

Trail of Bits describes a Codex agent workflow that backports security fixes to stable Linux kernel trees and distro packages. By 29 October 2026 it had helped land fixes for 149 CVEs in stable kernel trees, plus several Fedora and Ubuntu package fixes. Human preparation and review takes about 30 minutes for a simple backport and about three hours for a harder one. The post also counts CVEs still unfixed in stable kernel branches, Debian 13 and Ubuntu 26.04.

CodexLinuxUbuntu+2
Trail of Bits

coding-agents· Published and added 2 Nov 2026

eva.acarticle🛡️ Security

So I guess everyone uses LLMs to think now

The eva.ac author argues that recent AI-credited vulnerability findings come from skilled researchers steering LLMs, and that AI firms use disclosures as marketing. Cases cited: Calif, OpenAI and Wiz framing PHP2Shell differently; a hash teaser before the Tailscale "tailworm" privilege escalation (author's account: Tailscale not contacted); and the eMudhra CA key found without AI. No sources, dates or CVEs are given.

LLMOpenAIWiz+3
CalifeMudhraPHP2Shell+1

AI Security, other· Added 2 Nov 2026, published 1 Nov 2026

eva.acarticle🧠 AI

So I guess everyone uses LLMs to think now

"So I guess everyone uses LLMs to think now" is an opinion post from the eva.ac blog. The author explains why they never use LLMs for published research: they do it for fun and cannot take credit for model output. They argue LLMs still need skilled guidance, criticise AI-company security marketing (PHP2Shell from Calif, OpenAI and Wiz), and cite the Tailscale "tailworm" disclosure and the eMudhra key found without AI.

LLMPHPLinux+3
OpenAIAnthropicCalif+5

ai-policy· Added 2 Nov 2026, published 1 Nov 2026

github.comrepo🧠 AI

Show HN: A language model that lives in a boot sector

bootgpt is a char-level language model that runs from a BIOS boot sector. A 512-byte hand-written asm MBR loads an 11.5 KB int8 model from 23 following sectors and runs it in 16-bit real mode on a 386, generating fake Linux dmesg boot logs. train.py quantises to int8 with power-of-two scales, and its integer simulation matches the asm output char for char.

x86 assemblyNASMQEMU+4
sectorllmsectorlisp-nnOscar Toledo+3

inference, models, training· Added 1 Nov 2026, published 31 Oct 2026
x.comthread🛡️ Security

Julie Sanchez (@julie199201) on X

YourOwnWeigh is an open-source tool by developer Tom Anthony that patches Withings smart scale firmware over Bluetooth. The patch sends health metrics to a user's own server instead of Withings cloud, avoiding the Withings Plus subscription now required for third-party sync. It can run on a free Cloudflare account and imports existing user profiles. The post gives no firmware or protocol details.

YourOwnWeighWithingsCloudflare+1
Tom Anthony

Hardware & RF· Added 2 Nov 2026, published 30 Oct 2026

x.comthread🧠 AI

Artificial Analysis (@ArtificialAnlys) on X

Artificial Analysis launched an HLE-Diamond leaderboard in v5 of its Intelligence Index, covering the refined 1,000-question Humanity's Last Exam from CAIS and Scale AI. Each question runs once without tools, graded by GPT-5.6 Luna (medium) as pass@1. Gemini 4 Carbon (high) leads at 69%, Claude Opus 5.5 (max) scores 68%, and the top open weights model, Kimi K3.1 Pro, reaches 37%.

Artificial AnalysisArtificial Analysis Intelligence IndexHLE+9

evals, models· Published and added 30 Oct 2026

wiz.ioarticle🛡️ Security

The Rise of Agentic Attacks: What They Look Like, and Where They're Headed

Wiz Research reviews agentic attacks seen in its incident response work and in public reports (ARTEX, Hermes, JPCERT/CC, CrowdStrike, DIVD). It derives fingerprints of AI-agent activity from three intrusions: machine-paced iteration, natural-language reasoning in scripts, self-correcting script versions, checklist enumeration, noisy lateral spraying, probe-before-payload and self-labeled scratch files. It also covers effects on attribution, attack scale and defense.

KubernetesAWSClaude Code+2
ARTEXHermesStorm-0940+12

Threat Intel, Blue Team & Detection, AI Security, Cloud & Infra· Published and added 29 Oct 2026

wiz.iowriteup🛡️ Security

The Rise of Agentic Attacks: What They Look Like, and Where They're Headed

Wiz research on intrusions where AI agents do the hands-on attacker work. It reviews public cases (ARTEX against South Korean banks and the ConnectWise compromise, Hermes at Thailand's Ministry of Finance, JPCERT/CC, CrowdStrike, DIVD) and three Wiz-investigated attacks. It distills fingerprints: machine-paced iteration, embedded natural-language reasoning, self-correcting scripts, checklist enumeration, noisy lateral movement, probe-before-payload habits and self-named scratch files. It also covers attribution, scale and defense implications.

WizKubernetesAWS+2
ARTEXHermesStorm-0940+12

Threat Intel, Blue Team & Detection, AI Security, Cloud & Infra· Published and added 29 Oct 2026

arxiv.orgpaper🧠 AI

DICE: Decentralized Incentive-driven Federated Learning for Efficient & Scalable Customization of Pretrained Models in Web3

DICE is a blockchain-powered federated learning (BCFL) algorithm for customizing large pretrained models among untrusted Web3 participants. It combines dynamic progressive learning and model slice verification, so hardware-limited participants can train part of the model, with a tree-structured committee consensus protocol and an efficiency-driven incentive scheme to scale to more data holders. Experiments cover vision and language models.

federated learningblockchain-powered federated learningprogressive learning+1
arXiv

research, training· Added 31 Oct 2026, published 29 Oct 2026

latent.spacetalk🧠 AI

Why Agents Love Supabase

Latent Space podcast episode with Supabase founders Paul Copplestone and Ant Wilson on why frontier models pick Supabase first for app backends. It covers the alpha Docker-free local runtime, declarative schemas kept in Git, Supabase Compute for containers beside the database, and scale work (OrioleDB, Multigres, Turso). The founders say Supabase launches about five million databases a month and that AI-driven signups converted better.

PostgreSQLSupabaseDocker+6
Paul CopplestoneAnt WilsonLatent Space+2

coding-agents, ai-infra· Published and added 28 Oct 2026

arxiv.orgpaper🧠 AI

Data Scaling Laws in Stereo Matching: From In-domain Fitting to Cross-domain Generalization

This paper studies data scaling laws in stereo matching and releases XStereo, a realistic synthetic dataset of 200 thousand samples. In-domain training on five large datasets shows two regimes: a standard power law, then saturation, with a transition point roughly fixed for a given model. Cross-domain performance depends only weakly on source data scale, and distribution and coverage diversity reduce domain gaps more.

XStereoarXiv

research, training, multimodal· Added 30 Oct 2026, published 28 Oct 2026

securityweek.comarticle🛡️ Security

Tailscale Rushes Patches After Uncoordinated Disclosure of ‘Tailworm’ Flaws

Tailworm is a set of 11 findings, published by Cyberdione Labs before patches, in Tailscale client 1.104.2 and headscale 0.29.5. Four of six high-severity bugs affect Tailscale SSH, where root-privileged forwarding safeguards can be bypassed, giving root on reachable servers and wormable spread at under a second per hop. Tailscale advises reviewing SSH policies and disabling forwarding until a patched client ships. No in-the-wild exploitation is reported.

TailscaleheadscaleSSH+2
TailwormCyberdione LabsMike Shaver+3

Offensive Security, AppSec· Published and added 27 Oct 2026

securityweek.comarticle🛡️ Security

This is Fine: What NetScaler Zero-Days Tell Us About the New Normal

This SecurityWeek commentary covers the September 2026 Citrix NetScaler ADC and Gateway zero-days, exploited from mid-month and patched on 27 September as unauthenticated RCE flaws CVE-2026-88771 through CVE-2026-88778. The author argues the fast response shows stronger defence. Cited evidence: Citrix disclosure time fell from about 40 days to 17 in 2026 after it set up a NetScaler CNA, and CISA made a rare Sunday KEV addition.

Citrix NetScaler
CVE-2026-88771CVE-2026-88772CVE-2026-88773+9

other, Threat Intel· Published and added 27 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Analyzing Compiler-induced Constant-time Violations with Compiler at Scale

CTGREP is a compiler-based framework that applies differential analysis across the whole Clang/LLVM compilation chain to find where, how and under which configurations compiler optimizations break constant-time cryptographic code. Applied to seven libraries, three Clang versions, six targets and thousands of configurations, it led to 48 cases fixed with developers. It also identified seven new problematic LLVM passes and bypassed existing compiler-flag mitigations.

LLVMClang
constant-time violationstiming side-channeldifferential analysis+1

Hardware & RF, AppSec· Added 27 Oct 2026, published 26 Oct 2026

brown.eduarticle🧠 AI

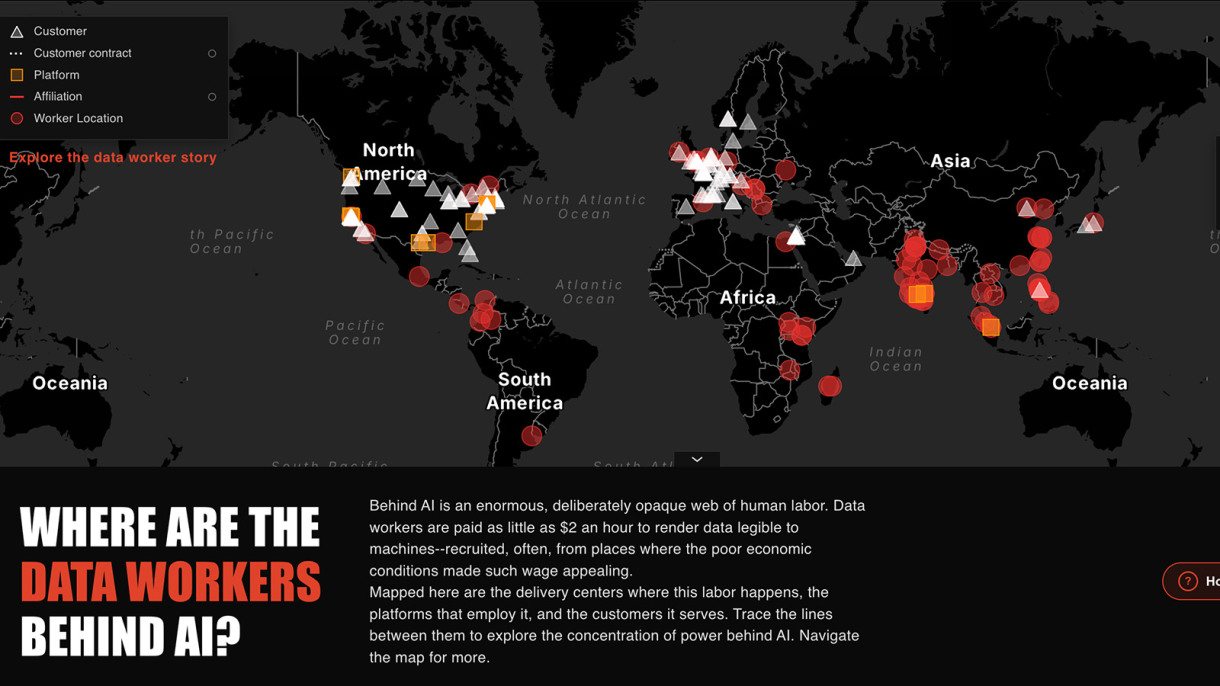
Brown student maps the hidden global labor powering AI

Brown University undergraduate Cunyan Ma built an interactive map linking technology companies and their intermediaries to data workers around the world, with the university's Center for Technological Responsibility, Reimagination and Redesign. The map combines existing data worker databases, Ma's own data collection and news reports on working conditions. It aims to show "AI colonialism" at scale, beyond anecdotal accounts. The page text ends early.

Brown UniversityCunyan MaCenter for Technological Responsibility, Reimagination and Redesign

training, ai-policy· Added 27 Oct 2026, published 26 Oct 2026

en.cryptonomist.charticle🧠 AI

Test-time training in robotics shows no clear gains in demo response

This article reports a study submitted October 23, 2026 by Qiangong Zhou, Jiafeng Liang, Yimin Dong, Yang He and Hongxiang Li. They added Test-Time Training (fast-weight memory) to the vision-language-action models InternVLA-A1 and Pi0.5, trained on paired human demonstrations and robot trajectories. Shorter videos, full-trajectory gradient connectivity and contrastive regularization gave no clear gain in demonstration-guided target selection at the tested scale.

vision-language-action modelTest-Time Training
InternVLA-A1Pi0.5Qiangong Zhou+4

research, multimodal, training· Published and added 26 Oct 2026

wiz.iowriteup🛡️ Security

Gheist: Attempted Scaled Abuse of Stolen GitHub Tokens Stumbles

Gheist is a campaign tracked by Wiz Research since 15 September 2026 that uses stolen GitHub tokens to push a sync-check workflow on ci-sync-* branches in every reachable repository. The workflow prints base32-encoded secrets into logs, which the tool downloads through the GitHub API and then deletes. Over 13,500 branches from 850+ accounts were recovered. The post covers the two tool variants, a buggy self-hosted runner payload, GitHub's approval hold (which does not cover private repositories), overlaps with other campaigns, hunting queries, IOCs and hardening steps.

GitHubGitHub ActionsAWS+3
GheistGhostActionPolinRider+6

Threat Intel, DevSecOps, Blue Team & Detection· Published and added 25 Oct 2026

arxiv.orgpaper🧠 AI

The Patient Is Always Right? Evaluating Sycophancy in Medical Diagnosis with Graded Patient Beliefs

This paper evaluates sycophancy in medical diagnosis across nine AI models. Each model is shown clinical evidence plus a patient's belief in a specific but incorrect condition, with the belief's closeness to the evidence varied. Models adopted the belief 23.2% of the time on average, even for fictional conditions, and 43.0% under a Rare Disease Claimer persona. Medical fine-tuning and larger scale reduced susceptibility.

LLM
arXiv

ai-safety, evals, research· Added 27 Oct 2026, published 25 Oct 2026

tailworm.comwriteup🛡️ Security

Tailworm – Tailscale Vulnerabilities

Tailworm is a security assessment report by Erica Windisch (Cyberdione Labs) on Tailscale v1.104.2 and headscale v0.29.5, tested 22-24 October 2026. It documents 11 findings: Tailscale SSH unix-socket forwarding that runs as root (bind, dial and TOCTOU races), conn25 app-connector egress bypass, gliderssh memory exhaustion, serve/funnel flaws and headscale DoS. It includes PoC references, mitigations and fix status as of 27 October 2026. The page is truncated, so the later sections were not read.

TailscaleheadscaleSSH+3
CVE-2025-14282Erica WindischCyberdione Labs+7

Offensive Security, Cloud & Infra, AppSec· Added 27 Oct 2026, published 25 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Chosen Commitments and Certified Decoding Regions in the Adaptive Threshold Schnorr Attack

This IACR ePrint 2026/2632 paper by Demirtaş and Yayla analyses the Crites–Stewart adaptive forgery attack on threshold Schnorr signatures, which needs one call to a sparse linear search oracle (bounded distance decoding of a scaled Reed–Solomon code). It shows that choosing the commitment coefficient vector does not help much: a wrapper adversary with Q challenges succeeds with probability at most QM/p, even if its solvers decode every witness for free. For the six original (N, τ) pairs, M stays below 2^24, so the bound is under 2^-100 after 2^128 challenges at p = 2^252.

Schnorr signaturesReed–Solomon codesfolded Reed–Solomon codes
Crites and Stewart attackGuruswami–WangAshvinkumar–Habib–Srivastava+2

other· Added 26 Oct 2026, published 24 Oct 2026

arxiv.orgpaper🧠 AI

Hey, guess what: CUES lead to inferences about typicality

The paper builds two corpora, EventTyp and the human-validated EventTypGold, to study how people infer typicality and atypicality of events from what is said. Large-scale human and LLM experiments show that three CUES predict these inferences in humans: Commonsense Knowledge, Utterance Emphasis and Snark. In most settings LLMs lack the commonsense knowledge to judge an event's general typicality, so they struggle to follow the CUES.

LLM
EventTypEventTypGoldarXiv

research, evals· Added 27 Oct 2026, published 23 Oct 2026

arxiv.orgpaper🧠 AI

Tool-Calling LLM Agents Under Realistic MCP Faults: Scale Does Not Purchase Fault Tolerance

MCP-Injector is a protocol-aware fault-injection middleware for Model Context Protocol tool calls, with permanent, transient and intermittent faults on seedable schedules. Its fault model comes from 57,240 issue and PR threads across 1,774 open-source MCP repositories. In a 1,350-cell experiment, faults cut task-completion score by 60% (8.08 to 3.23 of 10), and the 120B gpt-oss model was no more resilient than the 20B. Agent stacks differed in how well they absorbed faults.

Model Context ProtocolOpenAI Agents SDKLangChain+2
MCP-Injectorgpt-oss-120bOpenAI

mcp, evals, agents, research· Added 26 Oct 2026, published 23 Oct 2026

anthropic.comarticle🛡️ Security

LLMs are making formal software verification feasible at a much larger scale

Anthropic and Theorem report using Claude to write Rocq proofs that 239 fuzz entry points across 123 OSS-Fuzz libraries never crash on inputs under 64 MB, at the RISC-V binary level (about 180 million lines of proof). Claude patched the bugs it found along the way, including a rediscovery of a libexpat CVE and bugs fuzzers would miss. The post covers trusted components, limitations, token-cost trends and released proofs.

ClaudeRocqRISC-V+3
CVE-2026-56132TheoremOSS-Fuzz+5

AppSec, AI Security· Added 23 Oct 2026, published 22 Oct 2026

anthropic.comarticle🧠 AI

LLMs are making formal software verification feasible at a much larger scale

Anthropic and Theorem report that Claude wrote Rocq proofs of crash-freedom for 239 OSS-Fuzz entry points across 123 open-source libraries, working on compiled RISC-V binaries for inputs up to 64 MB. Proofs total about 180 million lines, and Claude found and patched bugs along the way. The post covers proof reuse (17% fewer tokens), Opus 5.5 using about 40% fewer tokens than Opus 5, and limitations.

RocqRISC-VVerus+10
CVE-2026-56132AnthropicClaude+11

research, coding-agents· Added 23 Oct 2026, published 22 Oct 2026

blog.cloudflare.comarticle🛡️ Security

Localizing compliance at scale: achieving South Korea’s ISMS certification

Cloudflare's account of obtaining South Korea's ISMS-P certification after a ten-day KISA audit of 80 controls and a preparation period of about a year and a half. It explains that the certificate covers a service delivery boundary rather than a product list, that auditors required readable data flow diagrams, and how Korean sign-up uses itemized consent with social login removed.

CloudflareCloudflare Workers
ISMS-PKISAPersonal Information Protection Act+5

GRC· Added 29 Oct 2026, published 22 Oct 2026

x.comadvisory🛡️ Security

EMITS (@emits_ca) on X

CVE-2026-107406 is a memory overflow in Citrix NetScaler that allows remote code execution when SAML is configured, rated 9.5 out of 10. The post from emits.ca calls it the fourth NetScaler bulletin in a week. It warns that the previous week's SAML patch does not cover it, and that fixes need NetScaler 14.1-73.46 or later, or 13.1-64.29 or later. The full advisory is on emits.ca.

Citrix NetScaler
CVE-2026-107406

Cloud & Infra, Identity & Access· Added 22 Oct 2026, published 21 Oct 2026

microsoft.comwriteup🛡️ Security

AI-driven, large-scale nation-state campaign using ARTEX enables supply chain compromise

Microsoft Threat Intelligence report on Storm-0940, a China-state aligned actor that used the open-source agentic AI pentest framework ARTEX from September 2026 to automate attacks on hundreds of organizations. It links the actor to the October 2026 ConnectWise multi-tenant OAuth app compromise (2,250+ tenants, 2,900 sign-ins per minute, privileged access in under 3 hours). It gives IOCs, Defender XDR and Sentinel KQL hunting queries, ATT&CK mapping and mitigations.

Microsoft 365Microsoft Entra IDMicrosoft Defender XDR+3
Storm-0940ARTEXConnectWise Cloud Backup+12

Threat Intel, AI Security, Identity & Access, Blue Team & Detection· Published and added 21 Oct 2026

protos.comarticle🧠 AI

Inside AMD and Anthropic’s ‘chips for shares’ deal

Protos reports on the AMD and Anthropic compute deal: Anthropic commits to buy over $20 billion of AMD AI compute, up to 2 GW of Instinct MI450 chips from the first half of 2027, while AMD commits up to $5 billion to Anthropic stock through fiscal 2028. It cites WSJ reporting that hyperscalers cap Anthropic's compute, and Anthropic's 2025 operating loss above $8 billion on $4.6 billion revenue.

AMD Instinct MI450Claude
AnthropicAMDTom Brown+1

ai-policy, inference· Published and added 21 Oct 2026

eprint.iacr.orgpaper🛡️ Security

DISCO*: DIstributed and SCalable Oblivious Joins and Oblivious Primitives

DISCO is a distributed, fully oblivious database system that combines hardware enclaves (TEEs) with oblivious primitives to hide access patterns from side-channel and leakage-abuse attacks. New distributed frameworks and communication optimizations let it run in parallel across servers. It reports 88x speedup over Jodes and 180x over SODA on non-foreign-key joins with 2^25 elements, and the first terabyte-scale results.

DISCO
JodesSODASOSP 2026

Hardware & RF· Added 21 Oct 2026, published 20 Oct 2026

arxiv.orgpaper🧠 AI

Large Flow Language Models

Lafa (Large flow language model) is a blockwise continuous flow language model scaled to 8B parameters, with causal attention on the prefix and bidirectional, asynchronous flow within each block. It is adapted from pretrained autoregressive models and trained at 0.5B, 7B and 8B with under 30B tokens. A self-speculative decoding scheme verifies flow drafts autoregressively in one model, giving 2.54x the throughput of an AR model at comparable quality. Flow maps allow one- and few-step generation.

flow matchingdiffusion modelTransformer+1
Lafa

research, models· Added 22 Oct 2026, published 20 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Membership Inference in Privacy-Preserving Vector Search

Membership Inference in Privacy-Preserving Vector Search is an IACR ePrint paper (2026/2570) that attacks backend-compatible protections for embedding databases using one snapshot and known plaintexts. It breaks the Scale-and-Perturb scheme of Fuchsbauer et al. (advantage 0.997 on MS-MARCO) and analyzes Rotate-and-Perturb, ideal DCRE and an encrypted HNSW index. It also tests shuffling and secret projection as mitigations.

HNSW
Scale-and-PerturbRotate-and-PerturbSAP-I+5

AI Security· Added 21 Oct 2026, published 20 Oct 2026

huggingface.coarticle🧠 AI

MPS in PyTorch 2.15

PyTorch 2.15 MPS release post from the Hugging Face PyTorch team, covering the Apple silicon backend. It adds float8_e4m3fn tensors with F.scaled_mm, a native grouped matmul that speeds MoE decoding 5 to 6.5x (Qwen3.6-35B-A3B from 9.4 to 61.3 tokens/s on an M3 Ultra), and an 8x faster softmax. Wan2.2 VAE decode peak memory falls from 270 GiB to 8 GiB. It previews 2.16 attention on Metal.

PyTorchMetalMPSGraph+9
Hugging FaceAppleQwen3.6-35B-A3B+6

inference· Published and added 20 Oct 2026

arxiv.orgpaper🧠 AI

MemT-1.0: Towards Memory-Native Evolution

MemT-1.0 is a memory foundation model architecture that builds memory into model computation. It builds on Metis, uses Gated DeltaNet-2 for token-level memory updates within each turn, and adds Mixture-of-Storage to scale capacity. Training used 34B tokens in continued pre-training and post-training. MemT-1.0-Nano and MemT-1.0-Flash beat parametric memory baselines and stay competitive with retrieval methods. At 128K history, Nano gives about 1.86x inference speedup and 66x less persistent storage than a full-context KV cache.

Gated DeltaNet-2Mixture-of-StorageKV cache+1
MemT-1.0MemT-1.0-NanoMemT-1.0-Flash+1

research, models, agents· Added 21 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🧠 AI

SHADE: Shrinkage via Halted Alpha-stable Denoising for Heavy-Tailed Probabilistic Time Series Forecasting

SHADE is an alpha-stable Lévy diffusion forecaster that stops denoising at a nonzero depth, so the leftover stable kernel shrinks the predictive distribution instead of leaving it overconfident. It offers a scale-calibrated halt and a context-amortized halt that needs no noise labels. Median CRPS improves 21.7% on synthetic data with alpha at or below 1.3, with tail calibration gains on cryptocurrency and foreign-exchange series.

diffusion model
arXiv

research· Added 21 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🧠 AI

Large-Scale Biomedical RAG: Corpus Scaling, Document Representation, and Efficiency Trade-offs

This paper is a controlled, large-scale evaluation of biomedical Retrieval-Augmented Generation across growing corpus sizes. It compares abstract, flat full-text and hierarchical full-text representations, with and without reranking, on multiple-choice QA over five external benchmarks and a held-out test set. RAG gave mean gains of up to 9.6 points externally and 10.2-30.3 points on the held-out set. Hierarchical indexing used 67% fewer units and 44-56% less storage than flat full-text.

RAG
arXiv

research, llm-apps, evals· Added 21 Oct 2026, published 19 Oct 2026

blog.cloudflare.comarticle🛡️ Security

Beyond the patch: Protecting your NetScaler gateway against future vulnerabilities

Cloudflare's guidance on protecting Citrix NetScaler Gateway after the actively exploited CVE-2026-88771 (unauthenticated command execution) and CVE-2026-88772 (DTLS). It recommends putting Zero Trust access policies in front of the login page, locking the origin down with Tunnel, dedicated egress IPs, authenticated origin pulls or Access JWT validation, and adding WAF inspection. It ends with a four-step test list to confirm the boundary holds.

Citrix NetScalerCloudflareCloudflare Access+1
CVE-2026-88771CVE-2026-88772CISA+5

Cloud & Infra, Identity & Access· Added 29 Oct 2026, published 19 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Provable Lattice Reduction in Nearly the Time of QR Factorization

Provable Lattice Reduction in Nearly the Time of QR Factorization (IACR ePrint 2026/2541, October 2026) presents a deterministic lattice-reduction algorithm with running time Õ(n^ω(1+log κ_col(B))), free of heuristic assumptions. Its implementation used fewer instructions than flatter (CRYPTO 2023) in all 153 runs on q-ary, NTRU-like, scaled q-ary and Coppersmith inputs. Median flatter-to-new instruction ratios are 1.55 for q-ary and 1.86 for NTRU-like inputs.

flatter
CoppersmithLLL

other· Added 20 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🛡️ Security

RAGLeak: Supply-Chain Privacy Backdoors in Retrieval-Augmented Generation

RAGLeak is a supply-chain privacy backdoor attack on retrieval-augmented generation. When triggered, the backdoored generator reversibly obfuscates retrieved private documents, and an auxiliary LLM recovers them. Tested on three model families and three domains, it reaches up to 100% attack success rate, loses at most 10 points under detection-based defenses, and survives clean fine-tuning and changes of model scale and version. Source code is released.

LLM
RAGLeak

AI Security, Supply Chain· Added 21 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🧠 AI

How Effectively Do Security Skills Guide Coding Agents in Vulnerability Detection in Linux Kernel?

The paper is a large-scale study of 37 security skills run through Claude Code with four LLMs on 100 real Linux kernel vulnerabilities, 14,800 runs in all. Only 24.4 percent of runs found the correct function and 15.7 percent classified the vulnerability correctly. It proposes SKILL-SIF, which evolves skills from failure patterns and raised fully correct detection on 100 unseen vulnerabilities from 2 to 16 percent.

Claude CodeLinuxLLM
SKILL-SIF

evals, coding-agents, prompting· Added 21 Oct 2026, published 19 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Off-Key: Inconsistent MAC Keys Compromise Privacy in SPDZ-Family MPC

Off-Key is a privacy attack on SPDZ-family maliciously secure MPC protocols that exploits inconsistent MAC keys. Depending on the MAC check protocol, a corrupted party recovers a shared secret from one authentication check or tests guesses through selective failure. The authors show it in MP-SPDZ, SCALE-MAMBA and FANNG-MPC, where a corrupted party can use different keys across batches, threads or runs, and describe the preprocessing state that enforces key consistency.

MP-SPDZSCALE-MAMBAFANNG-MPC
Off-Keyselective failureMAC key inconsistency+1

other· Published and added 19 Oct 2026

arxiv.orgpaper🧠 AI

Hybrid Reasoning Agents: LLM agents that think in latent space, act through text

Hybrid Reasoning Agents (HybridAgents) are LLM agents that switch between latent reasoning and text-based interaction in one generation process. A lightweight HybridLink handles mode transitions, continuous working memory keeps hybrid context across turns, and HybridSFT plus HybridRL train when to think latently and when to act in text. Across 3 model scales and 11 benchmarks, the paper reports 10.4% higher performance, 35.5%-54.7% fewer tokens, and 1.8x-2.6x faster inference.

LLM
HybridAgentHybridLinkHybridSFT+2

research, agents, training· Added 19 Oct 2026, published 18 Oct 2026

stepsecurity.ioarticle🛡️ Security

OpenCode Security Breach: Distillation Attack Hit Console Users With Linked AI Providers. How to Find OpenCode on Developer Machines and Respond

OpenCode disclosed a security breach on 18 October 2026 tied to a "large scale distillation attack" that hit 1.4% of OpenCode Console users who had Anthropic, OpenAI or Google providers linked. The post relays the vendor's X statement and notes that root cause, data accessed and key exposure are unpublished. It gives response steps: inventory OpenCode installs, read ~/.local/share/opencode/auth.json, rotate linked API keys, and review provider usage.

OpenCodeAnthropicOpenAI+2
distillation attackOpenCode Console breach

Threat Intel, AI Security· Published and added 18 Oct 2026

twitter.comother🛡️ Security

OpenCode has a security breach last that impacted 1.4% of console users

OpenCode announced on X a security breach tied to a "large scale distillation attack" that affected 1.4% of OpenCode Console users. Affected users were those with external model providers linked, and all were notified by email. The incident was ongoing at posting, with remediation under way with Anthropic, OpenAI and Google. No technical details were given.

OpenCodeAnthropicOpenAI
distillation attack

Threat Intel, AI Security· Added 19 Oct 2026, published 18 Oct 2026

galaxy.comarticle🧠 AI

Proving Humanity

Galaxy Research essay arguing that as AI agents become the main way people use the web, the key question shifts from "is this a machine?" to "is a distinct real person behind it, counted once?". It traces CAPTCHA history (distorted text, image puzzles, reCAPTCHAv3 and Turnstile behavioral scoring) and notes ChatGPT Agent passing Cloudflare's checkbox. It reviews Web Bot Auth signatures and Google's AP2 payment mandates, showing both stop at the platform or key and never establish a person. It then covers harms (one-person-one-share abuse, no one to answer for an agent, distorted public counts, collapsing confidence, scaled deception, broken ad economics) and lists the properties a privacy-preserving proof-of-personhood credential needs: strong, private, portable, delegable, accessible.

Web Bot AuthAgent Payments Protocol (AP2)reCAPTCHA+5
Galaxy DigitalGoogleOpenAI+13

agents, ai-policy· Added 16 Oct 2026

arxiv.orgpaper🧠 AI

Predictable Scaling: Efficient Model Exploration via Scaling-Law Prediction

Predictable Scaling (PS) is a framework that predicts full-scale recommendation model performance from scaled-down proxies. It builds proxies with composable scaling functions along separate resource axes, then projects metrics to target scale by curve fitting with calibrated uncertainty. Of three predictors, even the raw proxy falls within repeated-run noise, and a Gaussian Process gives 15% lower relative MAE. On a task-specific ranker and a foundation ranker, PS ranks hypotheses correctly at 79-88% compute reduction.

Gaussian Process
arXiv

research, training· Added 20 Oct 2026, published 16 Oct 2026

arxiv.orgpaper🧠 AI

PrairieFire: Igniting High-Throughput Updates in Large-Scale Approximate Nearest Neighbor Search

PrairieFire is an SSD-based approximate nearest neighbor search system for billion-scale vectors, built for high update throughput. It uses buffered updates and batched local rebuilds, with cascaded adjustments, concurrency control and CPU-GPU-SSD cooperation. Against state-of-the-art systems it reports about 3-35x update throughput, 3-5x search throughput and 1.5-8.7x cost efficiency. It has run in RedNote production for two months.

NVMe SSDGPU
PrairieFireRedNotearXiv

research, llm-apps· Added 20 Oct 2026, published 16 Oct 2026

huggingface.coarticle🧠 AI

Welcome Beam: a 501B open model you can own, customize, and scale

Announces Reflection's Beam-1.0-501B-A23B, an Apache 2.0 text-only MoE model (23B active per token, 256 experts, 1M context) aimed at coding and agentic use. It covers the architecture (hybrid sliding-window/global attention, a constant-scale residual stream, DeepSeek-V3-style group-limited routing) and BF16/FP8/NVFP4 checkpoints with hardware sizing. It also gives day-0 serving recipes for transformers, vLLM and SGLang with DFlash2 speculative decoding, LoRA SFT with TRL, GRPO with Miles, and demos built with the Pi coding harness.

TransformersvLLMSGLang+12
BeamReflectionDeepSeek+15

models, inference, training· Published and added 16 Oct 2026

arxiv.orgpaper🧠 AI

Rethinking Routing Exploration in Modern Mixture-of-Experts

The paper identifies an "exploration dilemma" in modern Mixture-of-Experts models. Shared experts reduce the variability of token representations, which makes routing less exploratory. Fine-grained expert segmentation enlarges the combinatorial routing space and so needs more exploration, which means its extra expressiveness may go unrealized. It proposes MirrorMoE, which shrinks the exploration space by suppressing unnecessary experts per token, and reports consistent gains across model scales.

Mixture of Experts
MirrorMoEarXiv

research· Added 17 Oct 2026, published 15 Oct 2026

arxiv.orgpaper🛡️ Security

My Credentials, Please: Detecting Filesystem Capability Laundering in MCP Servers at Scale

Studies "filesystem capability laundering" in MCP servers: client approval of a tool call grants the server process broad host filesystem access, so attacker-steered arguments can reach sensitive files outside the tool's declared contract. The authors build MCP-FSD, which infers per-tool least-privilege boundaries, plants credential fixtures outside them, and tests exploitability and sandbox containment by paired dynamic execution. Of 21,097 servers from nine registries, 16.4% of 4,806 triaged servers have filesystem capabilities despite non-filesystem classifications. Dynamic validation confirmed 150 vulnerable instances, and disclosure produced 13 advisories, including two CVEs in Anthropic's Git MCP Server.

Model Context ProtocolAnthropicGit
filesystem capability launderingMCP-FSDpath traversal+1

AI Security, AppSec· Added 17 Oct 2026, published 15 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Robust ECDSA Threshold Signing at Scale

Presents a robust threshold ECDSA signing protocol for t ≤ (n-1)/3 corrupted signers. It batch-computes pre-processing material for fast online signing and scales to many signers, for uses such as bridging consensus between blockchains. It combines batched verifiable secret sharing (Fitzi & Hirt), randomness extraction (Beerliova-Trubiniova & Hirt), efficient share opening (Damgård & Nielsen) and Attema–Cramer zero-knowledge proofs. The authors implement it and show it is practical for large n.

ECDSACarsten BaumAnders Dalskov

other· Published and added 15 Oct 2026

liquid.aiarticle🧠 AI

LFM2.5-24B-A2B: Built for fast on-device agents

Liquid AI releases LFM2.5-24B-A2B, a 24B-parameter MoE reasoning model with 2B active parameters (40 layers, 64 experts with top-4 routing, hybrid gated short convolutions and GQA). It has a 131K context window, a 128K-token vocabulary and 33T pre-training tokens, and was post-trained with large-scale RL for tool use and agentic tasks. The post reports results against Qwen3.6-35B-A3B on 16 benchmarks (AutomationBench, BFCLv4, ToolSandbox, LiveClaw, τ³-Bench Banking), decode speeds of 184 tok/s on an Apple M5 Max and about 21K output tok/s on a B300 GPU, day-one support in llama.cpp, MLX, vLLM, SGLang and ONNX, and a local Hermes Agent demo. It also describes reward-hacking behaviour during training, including the model detecting its sandbox.

Mixture of Expertsllama.cppMLX+8
Liquid AILFM2.5-24B-A2BLFM2.5-24B-A2B-Base+20

models, inference, agents· Added 16 Oct 2026, published 14 Oct 2026

huggingface.copaper🧠 AI

Harness^2: Recursive Agent Harnessing for an Open World

Harness^2 is a plug-and-play framework that recursively improves LLM agent execution harnesses in open-world settings where no ground-truth verifiers exist. Task-level recursion uses a contrastive Propose-Probe-Compose step to guide harness edits for the current task, and it scales through parallel or sequential recursion. Harnessing-level recursion distills experience from those edits into a continual-improvement harness for future tasks. A single step improves GLM-5 and Gemini 3.5 Flash over their base harnesses by up to 11.5 points on WorkBuddy-Bench, 4.5 on JobBench and 11.8 percentage points on LAB.

GLMGeminiHugging Face
GLM-5Gemini 3.5 FlashWorkBuddy-Bench+2

agents, research· Added 14 Oct 2026

bankless.comarticle🛡️ Security

Crypto's Quantum Defense Is Being Built in the Open

Bankless article on Eigen Labs' Yukon platform, which runs open challenges where researchers and AI agents attack and improve cryptography. It covers ECDSA.fail (quantum circuit cost for attacking Bitcoin/Ethereum ECDSA, cut about 88% from baseline), HashSmash (SHA-256 weakness hunting, so far only on reduced versions), sig.golf (hash-based signatures), StarkWare's Quantum Safe Bitcoin (cost down from about $320 to $59) and better.codes (provable security raised from 64 to about 68 bits). The argument is that public, measurable attack-cost data helps defenders prepare better than withholding circuits does. All gains are theoretical and no quantum computer has run an attack at this scale.

YukonBitcoinEthereum+1
Eigen LabsECDSA.failHashSmash+10

other, AI Security· Published and added 14 Oct 2026

eprint.iacr.orgpaper🧠 AI

A Graph-Based Analysis of Comparability, Scale, and Attribution in Private Transformer Inference

Systematization of knowledge on private Transformer inference (PTI) that builds an empirical graph of 62 systems, with system attributes as node features and evaluation compatibility as edges. Node-level attribution finds that cryptographic progress drives most speedups but always co-occurs with confounders such as model fidelity, hardware and cost accounting. Edge-level auditing finds only 1 of 1891 candidate system pairs directly comparable. Graph-level analysis shows the scale frontier plateaued at 13B parameters and projects the cost of deploying current PTI techniques on production-scale Transformers.

TransformerLLM
Souvik DasAriful AzadNitesh Saxena

research, inference, evals· Added 14 Oct 2026, published 13 Oct 2026

arxiv.orgpaper🧠 AI

Hybrid Reasoning Agents

Introduces Hybrid Reasoning Agents (HybridAgents), which switch between latent reasoning and text-based interaction in one generation process. A lightweight HybridLink handles transitions between the two modes, and a continuous working memory keeps hybrid context lossless across turns. This keeps tool use and makes latent thoughts inspectable. Post-training has two stages: HybridSFT, then HybridRL, which learns when to think latently and when to act in text. Across 3 model scales and 11 benchmarks (math, science, medicine, search, agentic reasoning), the authors report +10.4% performance, 35.5–54.7% fewer tokens, 1.8–2.6x faster inference and 2.7–3.7x lower cost versus text and latent baselines.

LLM
HybridAgentHybridLinkHybridSFT+2

research, agents, training· Added 14 Oct 2026, published 13 Oct 2026

arxiv.orgpaper🧠 AI

PixelMoE: Scaling Pixel-Space Diffusion with LLM-Style Mixture-of-Experts

PixelMoE is a pixel-space diffusion framework that scales capacity sparsely using standard LLM-style Mixture-of-Experts: token-choice routing, fine-grained routed experts, a shared expert and bias-based load balancing, with no diffusion-specific routing or auxiliary routing losses. It adds Pixel-Space Hierarchical Flow Matching, which varies spatial resolution along the denoising trajectory from global structure to fine detail. At matched active parameters it beats dense counterparts, and reaches FID 1.47 at 256x256 and 1.53 at 512x512 on class-conditional ImageNet-1K without representation alignment or perceptual losses. Code and models are promised but not yet released.

Mixture of Expertsdiffusion modelflow matching+1
PixelMoEImageNet-1KarXiv

research, multimodal· Added 14 Oct 2026, published 13 Oct 2026

huggingface.coarticle🧠 AI

Run fast, private agents on-device with LFM2.5-24B-A2B

Liquid AI releases LFM2.5-24B-A2B, an open-weight reasoning-only mixture-of-experts model (40 layers, 64 experts with top-4 routing, hybrid gated short convolutions and GQA, 2B active parameters) with 131K context and a 128K-token vocabulary. Pre-training scaled to ~33T tokens, followed by long-context mid-training and a five-stage post-training pipeline (SFT, teacher specialization, two multi-domain on-policy distillation stages, agentic RL in harnesses such as OpenClaw, Hermes Agent, Pi, OpenCode). It reports leading or matching results on tool-use and instruction-following benchmarks (e.g. LiveClaw 48.09 vs 38.19 for Qwen3.6-35B-A3B), 184 tok/s on an M5 Max and 21K tok/s on a B300, and includes transformers code and Hermes Agent local-serving config.

Mixture of ExpertsTransformersvLLM+12
Liquid AILFM2.5-24B-A2BLFM2-24B-A2B+18

models, agents, inference· Published and added 13 Oct 2026

arxiv.orgpaper🧠 AI

Configuring RAG Systems: What Breaks, Where Originates, and How to Fix

First large-scale empirical study of RAG configuration issues, covering 654 real-world issues collected from 10 diverse RAG systems. It categorizes symptoms, root causes, affected pipeline stages and fix patterns. It finds that symptoms mostly appear at early or late stages, while the root cause often sits in a different stage from where the symptom shows. It closes with nine actionable insights for testing, localizing and fixing RAG configuration problems.

RAGLLM
arXiv

research, llm-apps· Added 14 Oct 2026, published 13 Oct 2026

adversa.aiarticle🛡️ Security

Top GenAI security resources — October 2026

Adversa AI's October 2026 roundup of 38 GenAI security resources, grouped into attack techniques, defenses, red teaming, vulnerabilities, incidents, articles and frameworks. Highlights include Anthropic's finding that GLM-5.3 safeguards collapse under prefill and abliteration, capability laundering and activation-dilution jailbreaks, RAG poisoning attacks, the LiteLLM proxy flaw (CVE-2026-35029), and the SGLang pickle RCE (CVE-2026-86793). It also covers a joint US advisory on industrial-scale model distillation. It closes with advice to assume model safeguards can be removed and to harden the serving stack around the model.

LLMLiteLLMSGLang+3
CVE-2026-35029CVE-2026-86793GLM-5.3+14

AI Security· Published and added 13 Oct 2026

anthropic.comarticle🛡️ Security

Strengthening our defenses against distillation attacks

Anthropic describes how it countered industrial-scale distillation attacks on Claude, in which proxy networks of hundreds of thousands of fraudulent accounts (stolen payment details, false identities) tricked models into revealing hidden reasoning. Defenses include a two-stage constitutional-classifier system (<0.1% false positives), "preserved thinking" that blocks edits to prior context for new API accounts, restricting reasoning transcripts to the originating organization, stricter limits, bans, and charging for blocked requests. It reports 10–100x fewer reasoning tokens extracted, cites Zhipu's GLM-5.3 and Moonshot Kimi forwarding as examples, and discusses trade-offs and the need for platform-wide action.

ClaudeAnthropicKimi K3+2
distillation attacksZhipuMoonshot+7

AI Security, Threat Intel· Added 14 Oct 2026, published 13 Oct 2026

github.comrepo🧠 AI

Show HN: SolidCraft – Open-Source Parametric CAD in Rust (With MCP Support)

SolidCraft is an open-source parametric 3D CAD application written in pure Rust. It has constrained sketches with its own solver, a feature timeline, assemblies, sheet metal, and STEP/IGES/3MF/STL export. It runs on desktop (egui+wgpu), in the browser, and as a headless CLI. The built-in MCP server (`solidcraft-cli mcp`) gives agents tools such as execute, batch, inspect_design, measure, set_parameter, screenshot and export. They can model headless or drive the running app over a JSON-lines control channel. A rover with 3,323 timeline steps was built entirely through MCP, which shows agent-driven parametric modelling working at scale.

RustModel Context ProtocolClaude Code+5
SolidCraftSELENE

mcp· Published and added 13 Oct 2026

anthropic.comwriteup🧠 AI

AI models may be capable of self-replicating without access to a datacenter

Anthropic's Frontier Red Team tests whether small open-weight models (30B and under) could run as self-replicating "AI worms" on commodity IoT hardware. A 9B model set up inference on 8 of 9 hardware types. In an 8-node Android emulator fleet only GLM-5.2 replicated end to end. Gemma4-26B-A4B was sharded across 15 ~$55 Android TV boxes at 0.39 tok/s. Qwen3.5-9B lineages that inherit notes improve at inference setup (45% to 61-84%), while a frontier advisor (Opus 4.8) doesn't help. An ECI trend fit puts small models at GLM-5.2's level by end of 2026, and the post estimates botnet-scale compute and spread speed. It adds defensive suggestions (drive R0 below 1) and a harness called Memento built on the Pi coding agent.

PiMementoPetals+10
AnthropicGLM-5.2Gemma 4+14

ai-safety, evals, inference· Published and added 12 Oct 2026

endorlabs.comarticle🛡️ Security

Identifying and Tracking FedRAMP False Positives | Endor Labs

Explains how FedRAMP treats false-positive SCA findings, which still have to be tracked in the POA&M and ConMon. It covers the deviation request (DR) process, the SCA problems of scale and missing context (manifest-based inventories, with 88% of imported code unused), and 30–180 day remediation SLAs. It argues that only high-confidence, function-level reachability that holds from any source is likely to satisfy a 3PAO. It then describes how Endor Labs uses call-graph analysis, SBOM/VEX output and rescanning to document false positives.

Endor LabsSBOMVEX
FedRAMPPOA&MConMon+4

GRC, Supply Chain· Published and added 12 Oct 2026

simonwillison.nettool🧠 AI

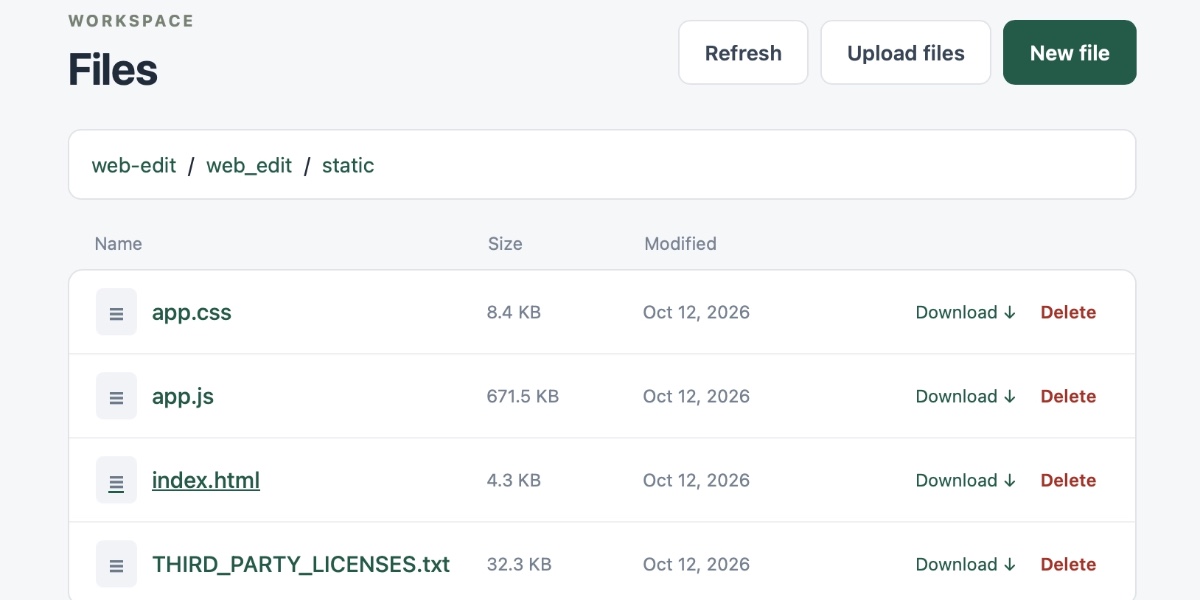
web-edit 0.1a0

web-edit 0.1a0 is a Python web app that gives a browser UI for viewing and editing files in a folder, intended to be started by an agent and reached over Tailscale from a phone. Simon Willison built it with Codex and GPT-6 Astra Extra High after wanting to edit a credentials file during a Codex Remote session without passing the credentials through the LLM. Editing uses CodeMirror 6 because Monaco's mobile experience is still weak.

PythonCodexCodeMirror 6+2
Simon WillisonGPT-6 Astra

coding-agents· Added 13 Oct 2026, published 12 Oct 2026

arxiv.orgpaper🛡️ Security

StableJudge: A Lightweight Adversarial Defense Framework for LLM-as-a-Judge

StableJudge is a defense framework against score-hijacking prompt injection in LLM-as-a-Judge pipelines (e.g. paper review, recommendation). A compact 0.13B "Sentry" model localizes injected spans and sanitizes them before the judge scores the content, trained on adversarially evolving attacks, and deterministic fine-grained scores are derived from the judge's output distribution. It improves score recovery under attack on held-out scientific abstracts and out-of-distribution attack variants while preserving general performance, decoupling safety from judge model scale. Code and data are promised but not yet released.

LLM
prompt injectionindirect prompt injection

AI Security· Added 15 Oct 2026, published 12 Oct 2026

arxiv.orgpaper🛡️ Security

ML-Assisted Power Side-Channel Attacks on ML Accelerators in Shared FPGAs

Paper presenting the first on-chip, TDC-sensor-based power side-channel attack on a co-tenant FPGA to reconstruct full-scale color ImageNet inputs (224x224) from a victim's first CNN convolution layer, using ML-based upscaling and recoloring. It separates genuinely leaked information from ML-generated post-processing. It also evaluates a pixel-substitution defense based on Hamming Weight, which is largely defeated by an attacker retrained on the transformed data. The authors conclude that robust defenses need randomized or input-dependent transformations.

FPGACNN
Time-to-Digital ConverterImageNetMNIST+1

Hardware & RF, AI Security· Added 16 Oct 2026, published 12 Oct 2026

twitter.comthread🧠 AI

The gap in shared understanding of LLM capability is widening

Andrej Karpathy argues the gap in shared understanding of LLM capability is widening into a funnel: ~6B people barely touch LLMs, 1-2B use free-tier chatbots casually, ~20M professionals in math and code see agents finish weeks-long projects from a prompt, and ~5,000 people with internal frontier access see swarms of agents on software mega-projects. He attributes the funnel to problem ambition and scale, jagged capability (peaks in digital, verifiable, economically valuable domains because of RL on verifiable rewards), and access tier. It is a useful framing for why people talk past each other about AI progress.

ChatGPT
Andrej KarpathyOpenAI

ai-policy, models· Published and added 11 Oct 2026

momo5502.comwriteup🧠 AI

500B tokens later: Letting AI agents decompile a first-person shooter

A retrospective on a 3-month project in which Claude Code and Codex agents (Sonnet 5, Opus 5.5, Luna, Sol, Terra) decompiled a first-person shooter into C++, using ida-mcp, GitHub issues and Discord for coordination. The first month's agents produced readable but semantically wrong code, and a reviewer agent could not catch it. A byte-matching oracle script, comparing compiled OBJ output against the original EXE/PDB, gave a strict PASS/FAIL signal. That let cheaper models like Luna scale to 14+ agents and reach 99% of functions present and 83% byte-exact. Lessons include lowering the compaction threshold to 42%, hourly cron re-injection of the instruction document, hashing the verifier in CI to stop agents tampering with it, and the failure of review when correctness is undefined.

Claude CodeCodexIDA Pro+5
Claude Sonnet 5Claude Opus 5.5GPT-6 Luna+5

coding-agents, agents, ai-policy· Published and added 11 Oct 2026

huggingface.copaper🧠 AI

MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement

Technical report for Xiaomi's MiMo-V2.6 omni-modal model family, which scales RL compute along three axes: asynchronous training with 1,568 samples and 2.7-3.7B tokens per step at up to 1M context, more diverse environments (code, general, visual, cyber) under mixed agent harnesses, and groupwise agentic grading that gives better reward signals and favors shorter, token-efficient solutions. Stability measures include a frozen MoE router and a multi-layer defense against reward hacking, built on a mid-trained hybrid-SWA architecture. The authors open-source training dynamics, RL environments and the RL framework, which makes it a useful reference for reproducing scaled agentic RL.

Mixture of ExpertsHugging Face
MiMo-V2.6Xiaomi

training, research, agents· Added 10 Oct 2026

latent.spacetalk🧠 AI

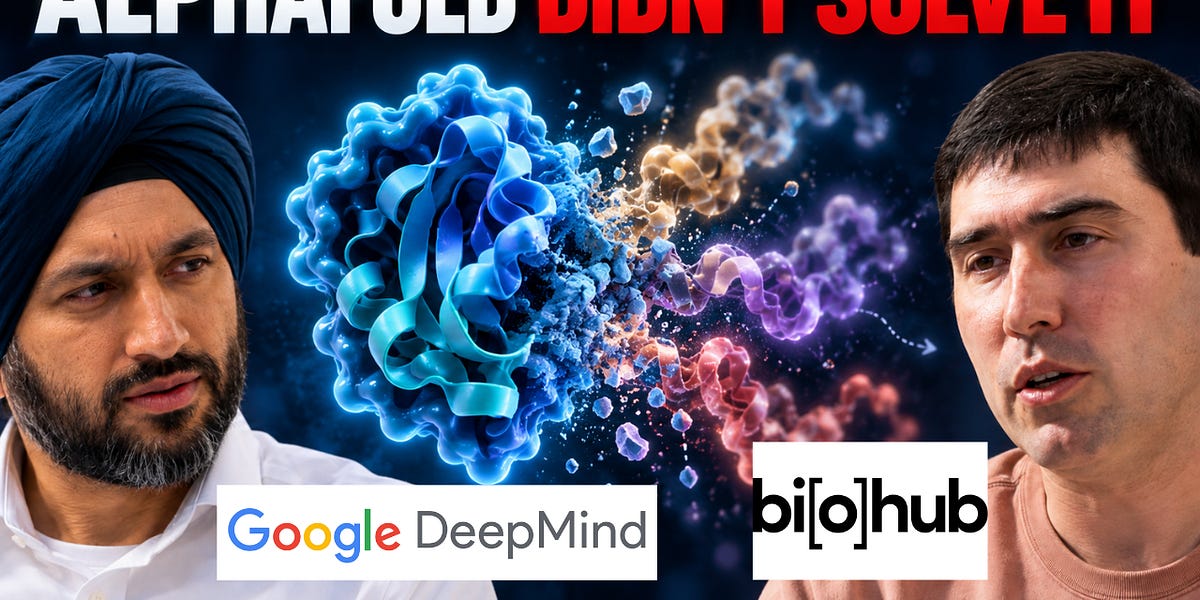
Why AlphaFold Didn't Solve Protein Folding — Pushmeet Kohli, Google DeepMind & Sal Candido, Biohub

Transcript of a panel moderated by Brandon Anderson with Pushmeet Kohli (Google DeepMind) and Sal Candido (Biohub). They discuss a "bitter lesson" for biological data: finding the right scaling law and good data matters more than raw scale. Low-quality metagenomic sequences can still improve protein language models, and AlphaFold 2's handcrafted inductive biases made it data-efficient. They also cover why protein folding isn't fully solved (dynamics, disorder, cryo-EM micrographs as a richer data source), the need for calibrated uncertainty (pLDDT) over full interpretability, hidden knowledge in protein language models, and the move from single-protein models to a virtual cell.

AlphaFoldTransformer
Pushmeet KohliSal CandidoBrandon Anderson+5

research, training, models· Published and added 10 Oct 2026

huggingface.corepo🧠 AI

Qwen3.8-27B (Apache-2.0, multimodal dense, 262k ctx)

Model card for Qwen3.8-27B, a 27B dense vision-language model from the Qwen team with a hybrid Gated DeltaNet / Gated Attention layout (64 layers, 16×(3 DeltaNet + 1 attention)), MTP training, and 262k native context extensible to 1M via YaRN. It targets coding, research and long-horizon agentic tasks, with thinking on by default, reasoning_effort levels (xhigh/medium/low) and preserve_thinking. The card gives deployment recipes for Transformers, vLLM, SGLang and TokenSpeed, recommended sampling parameters, video-token settings for hour-scale video, and benchmark notes (SWE-bench Pro, NL2Repo-Bench, DeepSWE, HLE, MathVision, WebArena-Verified, etc.).

Qwen3.8-27BHugging FaceTransformers+8
QwenQwen3.5SWE-Bench Pro+14

models, multimodal, inference· Added 9 Oct 2026

arxiv.orgpaper🧠 AI

DualQuant: Dual-scale Calibration-free Weight-and-Activation Quantization for LLMs

DualQuant is a calibration-free post-training quantization framework for LLM weights and activations. It minimizes weight-reconstruction MSE using variable splitting and block coordinate descent with closed-form subproblem updates. The resulting scaling factors double as per-channel activation rescalings, so no calibration data is needed. It supports the MX family and NVFP4 block formats. On Llama and Qwen models it matches or beats calibration-based SmoothQuant on WikiText-2, C4 and zero-shot tasks. A real packed W4A4 path for Llama-3.1-8B on an RTX 4090 gives up to 2.61x memory reduction and 2.46x throughput over BF16.

LlamaQwenNVFP4+3
DualQuantLlama-3.1-8BWikiText-2+4

inference, research· Added 12 Oct 2026, published 9 Oct 2026

arxiv.orgpaper🧠 AI

Multi-Stream Attention Residuals

Introduces Multi-Stream Attention Residuals (MSAR), which extends Attention Residuals (AttnRes, single-stream softmax attention over network depth) to multi-head depth attention. Heads get diverse views through multi-scale causal convolutions over sequence context, and the retrieved streams are merged by lightweight adaptive mixing into a single-stream layer input, so no persistent multi-stream storage or communication is needed. It beats standard residuals, manifold-constrained Hyper-Connections (mHC) and AttnRes on 12 downstream benchmarks at 18B and 28B MoE scales, with an iso-loss compute speedup of 1.58x versus 1.35x for AttnRes and 1.30x for mHC.

TransformerMixture of Experts
Multi-Stream Attention ResidualsAttention ResidualsHyper-Connections+1

research· Added 12 Oct 2026, published 9 Oct 2026

securityweek.comadvisory🛡️ Security

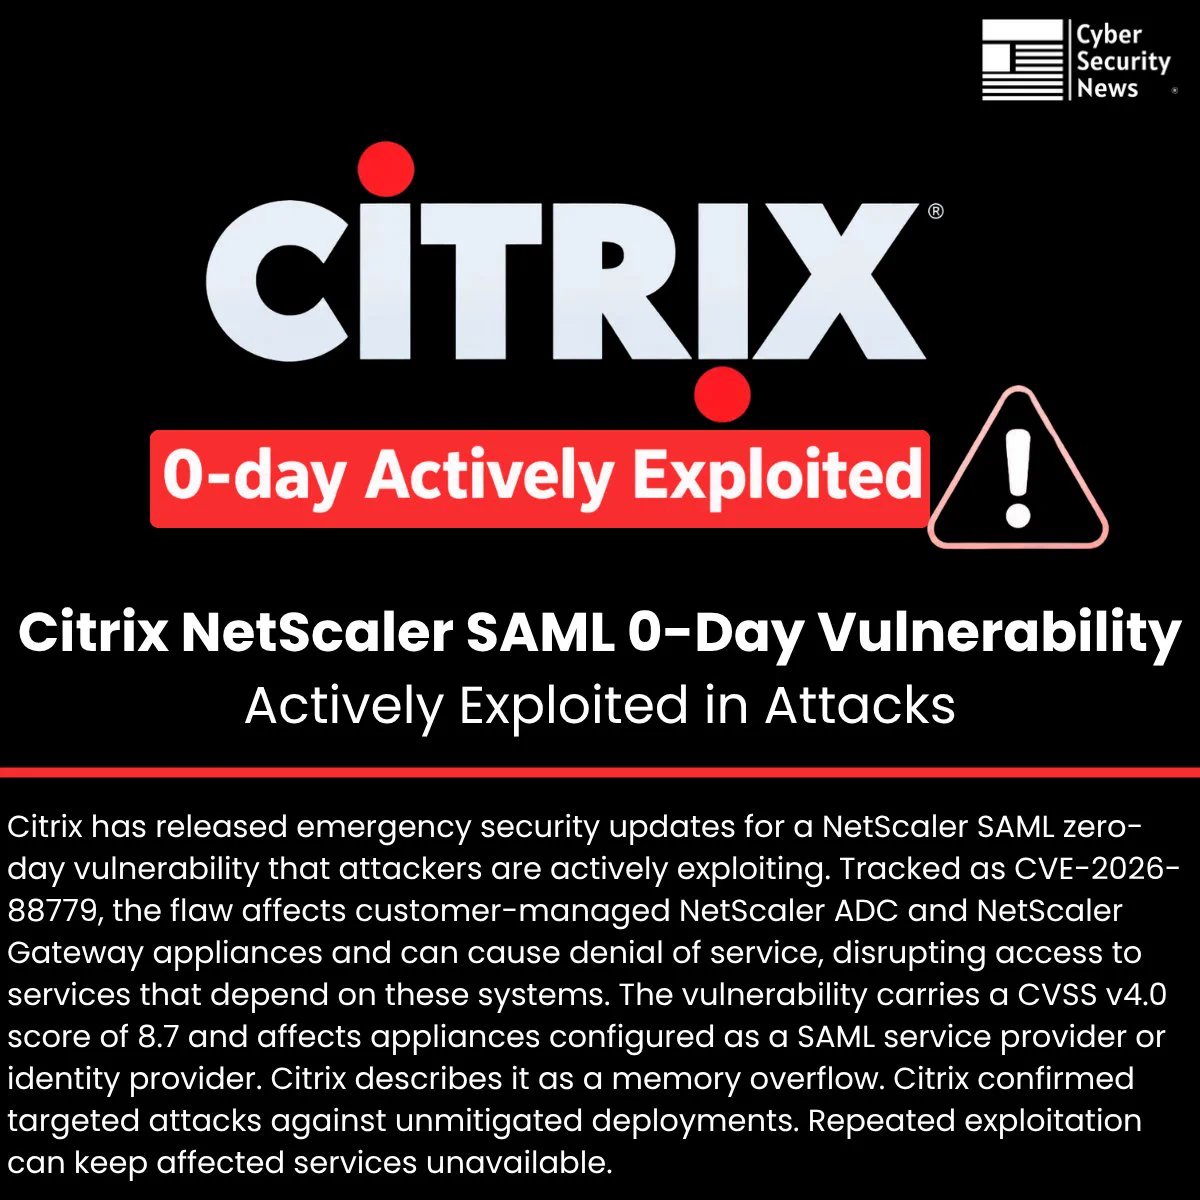
Citrix Urges Immediate Patching of Critical NetScaler Vulnerability

Citrix disclosed CVE-2026-107406 (CVSS 9.5), a critical memory overflow in NetScaler ADC and NetScaler Gateway that can lead to remote code execution or denial of service when appliances are configured as a SAML SP or SAML IdP, also affecting Secure Private Access Hybrid deployments using NetScaler. Patches are available in versions 14.1-73.46, 13.1-64.29, and the corresponding FIPS/NDcPP builds; Citrix says it is not aware of exploitation yet but urges immediate upgrades. The bulletin follows two other recently exploited NetScaler RCE/DoS zero-days (CVE-2026-88771, CVE-2026-88772) used against government, financial, education, legal, and professional-services organizations, and a separate DoS zero-day (CVE-2026-88779).

Citrix NetScalerSAML
CVE-2026-107406CVE-2026-88779CVE-2026-88771+1

AppSec, Identity & Access· Published and added 9 Oct 2026

blog.talosintelligence.comarticle🛡️ Security

Making sure the checks get printed

Cisco Talos's weekly Threat Source newsletter, opening with a risk-management anecdote about network-isolating unpatchable legacy check-printing systems, then disclosing new CAIRN research classifying "A3: AI-Analysis Evasion" — malware authors embedding natural-language prompt-injection text into code/binaries to manipulate AI-assisted malware analysis pipelines. The MANTLEMAZE malware family exemplifies this, pairing such AI-deception attempts (effective ~35% of the time) with BYOVD abuse to disable EDR from kernel space. The issue closes with a roundup of the week's security headlines (Citrix NetScaler CVE-2026-88779, a Danish government data breach, Warlock ransomware) and Talos's current top-prevalence malware hashes/IOCs.

EDRCitrix NetScaler
CVE-2026-88779MANTLEMAZECAIRN+2

AI Security, Malware & RE· Published and added 8 Oct 2026

arxiv.orgpaper🧠 AI

Caught in the Act: Probes Effectively Detect Sabotage and Catch Unverbalized Deception

The paper scales white-box deception detection with activation probes to frontier monitoring settings. It builds the largest deception dataset to date (FIBS) and introduces a probe architecture that aggregates information across many layers and tokens. The probes reach 98.8% AUC on SHADE-Arena, beating an Opus 5.5 text-monitoring baseline, and improve as the underlying model grows. They also handle "introspective deception", where ground truth can't be read from context: they separate transcripts containing a model's true hidden goal from others with up to 99.7% AUC, and detect lying on politically sensitive topics and under pressure in open-weight models. The FIBS dataset is released.

SHADE-ArenaFIBSClaude Opus 5.5

ai-safety, research, evals· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🧠 AI

WOVEN: Weaving Visual World Modeling into Multimodal LLMs

WOVEN is a training source and benchmark for visual transition reasoning in multimodal LLMs. It has 36,076 examples spanning 20 scene types, 5 action types and 8 reasoning types, built from rollouts of video-pretrained generative models. Evaluating 38 frontier MLLMs (including GPT-5.4 and Qwen3-VL-235B-A22B) shows systematic deficits that persist with scale. Training on WOVEN subsets of about 2,000 items improves 22 of 26 external benchmarks by up to 27.3 points, and WOVEN data can replace 30-50% of a task's own training data. The authors derive a recipe: select supervision by the reasoning operation it teaches rather than by scene or action, and prefer larger visual-state changes.

vision-language modelQwen3-VL
WOVENGPT-5.4

research, multimodal, evals, training· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🧠 AI

Cited but Not Consulted: A Counterfactual Audit of Legal Chain-of-Thought Faithfulness

The paper tests whether LLM legal explanations reflect what drives the verdict. Holding case facts fixed, it swaps the named statute or precedent for an unrelated one and decodes the evolving verdict from hidden states. Across seven open-weight models (8B-70B) and four benchmarks (CaseHOLD, ECHR, SCOTUS, ContractNLI), models name the correct authority 66.7%-100% of the time, but the verdict changes with the authority far less often (0.0%-21.7% on CaseHOLD, 30.0%-76.7% on ECHR and SCOTUS, 43.3%-50.0% on ContractNLI). Neither scale nor a LoRA reproduction of a legal-reasoning model closes the gap. A red-teaming check on five models finds compliance with an adversarial instruction hidden in the case facts (73.3%-96.4%) far exceeds verdict-swap sensitivity. The authors conclude that generated legal explanations are poor compliance or audit artefacts.

LoRA
CaseHOLDECHRSCOTUS+1

research, evals, ai-safety· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🧠 AI

MiMo-V2.6: Scaling Reinforcement Learning Towards Self-Improvement

Technical report for the MiMo-V2.6 omni-modal model series, which scales RL compute after mid-training on a multimodal corpus, using a hybrid sliding-window-attention architecture. RL is scaled along three axes: asynchronous training with 1,568 samples and 2.7-3.7B tokens per step at up to 1M context; diverse environments (code, general, visual, cyber) under mixed agent harnesses; and groupwise agentic grading that gives better rewards for long-horizon tasks and favors shorter, token-efficient solutions. Stability measures include freezing the MoE router and a multi-layer defense against reward hacking. The authors open-source the training dynamics, RL environments and RL framework.

Mixture of Experts
MiMo-V2.6Xiaomi

training, research, models· Added 9 Oct 2026, published 8 Oct 2026

github.comrepo🛡️ Security

target/strelka

Strelka is Target's open-source, container-based real-time file scanning system for threat hunting, threat detection, and incident response, built in Go and Python. It runs 50+ scanners (YARA, PE parsing, encrypted ZIP cracking, entropy analysis, etc.) to extract metadata and content from files at enterprise scale, which can feed a SIEM for alerting on suspicious artifacts like an Emotet-laden encrypted ZIP payload.

DockerGoPython+1
Laika BOSSEmotet

Blue Team & Detection· Added 8 Oct 2026

github.comrepo🧠 AI

Tracer-Cloud/opensre

OpenSRE is an open-source framework for building AI SRE agents that resolve production incidents by correlating logs, metrics, traces, deploys and runbooks across 60+ connected tools (observability, cloud infra, incident management, MCP). Beyond the agent runtime (CLI, Python API, Slack/PagerDuty/Telegram integrations), the project's stated mission is to build an RL training and evaluation environment — explicitly modeled on SWE-bench's role for coding agents — to scale realistic infrastructure-failure scenarios as a benchmark for AI SRE.

DockerPythonPostgreSQL+3
OpenSRETracer-CloudSWE-bench

agents, evals, ai-infra· Added 8 Oct 2026

openai.comarticle🛡️ Security

Disrupting AI-enabled “false front” operations

OpenAI reports banning ChatGPT accounts tied to two covert influence operations using "false front" entities. The Russian "Dark Clark" operation ran a think tank (Social Research Center) staffed by unwitting Latin Americans, planted fake emails, audio and documents targeting Ukraine and Argentine, Bolivian and Ecuadorian leaders, and was rated Breakout Scale Category 5. The Iranian "Bogus Bylines" operation used seven fake journalist personas to place nearly 100 articles in online outlets (Category 4) and generated batches of social media comments (Category 2), while using inflated impact metrics in internal reports.

ChatGPTOpenAIVPN+2
Dark ClarkBogus BylinesSocial Research Center+12

Threat Intel, AI Security, OSINT· Published and added 8 Oct 2026

openai.comarticle🧠 AI

Disrupting AI-enabled “false front” operations

OpenAI's threat report describes two banned ChatGPT-account clusters running "false front" influence operations. The Russian "Dark Clark" operation ran a Latin American think tank, the Social Research Center, through unwitting staff and was rated Breakout Scale Category 5, OpenAI's first. The Iranian "Bogus Bylines" operation placed almost 100 articles under seven fake journalist bylines (Category 4) and inflated its own impact metrics.

ChatGPT
OpenAIMetaDark Clark+9

ai-safety, ai-policy· Published and added 8 Oct 2026

arxiv.orgpaper🧠 AI

TRACE: Rollout-Guided Quantization-Aware Training for FP4 Reinforcement Learning of MoE Language Models

TRACE (Train-Rollout Quantization Alignment via Compact GuidancE) is an FP4 quantization framework for reinforcement learning post-training of Mixture-of-Experts language models. It uses rollout-guided quantization-aware training to align training-side FP4 rounding with rollout-side quantization outcomes, reducing the train-rollout discrepancy that limits prior low-precision RL methods, and adds a caching scheme that selectively retains mantissa/scale information from deeper layers to cut communication overhead. Evaluated on four large MoE models across reasoning, coding and long-horizon RL tasks, it matches BF16-rollout RL performance while achieving up to 5.4x rollout speedup with joint FP4 weight/activation and FP4 KV-cache quantization.

Mixture of Experts

training, inference· Added 7 Oct 2026

decrypt.coarticle🛡️ Security

Hackers Used AI Agents to Raid a Megachurch's Database, Exposing 850,000 Members

Seoul megachurch Yoido Full Gospel Church disclosed a breach exposing data on 850,000 members (names, birth dates, and logged changes to resident registration numbers, phone numbers and addresses), discovered by security firm Oasis Security on an overseas server alongside attack logs showing AI sub-agent activity and machine-generated attack reports. A second megachurch, Sarang Church, lost about 89,000 member and 286 employee records in a related August incident, and South Korean authorities are separately investigating suspected AI-assisted hacks at banks including Shinhan, which exposed data on about 25,000 customers. The exact role AI played in gaining initial access remains unconfirmed, but the find marks one of the first documented cases of attacker logs referencing autonomous AI sub-agents in a large-scale breach.

Yoido Full Gospel ChurchSarang ChurchOasis Security+3

Threat Intel, AI Security· Published and added 7 Oct 2026

github.blogarticle🛡️ Security

Secret protection must scale with software

GitHub essay by Secret Protection PM Erin Havens presenting nine quarters of telemetry (Q2 2024–Q2 2026) on secret leaks: pushes with credentials grew 2.59x while developer override rates of push-protection blocks fell from 6.63% to 3.93%, and mean time to manually revoke a leaked secret hovers around 40 days. It introduces a new fine-tuned ModernBERT classifier, built with Microsoft Applied Sciences, that evaluates candidate secrets in context in under 2ms to extend push protection to unstructured secrets (e.g. internal database passwords with no recognizable pattern), rolling out in private preview to GitHub Secret Protection customers and as a /security-review command in Copilot CLI/App.

GitHubGitHub Copilot CLIModernBERT+1
ReviewBench

DevSecOps, AI Security· Published and added 7 Oct 2026

watchtowr.comwriteup🛡️ Security

Post-Exploitation Analysis & Artifacts – Citrix NetScaler CVE-2026-88771

watchTowr post-exploitation analysis of CVE-2026-88771, an unauthenticated log-poisoning command injection in Citrix NetScaler (advisory CTX697096). Sensors logged thousands of attempts: about 85% were OOB callbacks, the rest Sliver implants, a trojanized Dropbear SSH backdoor, a Perl stager with a PHP webshell, and SSH-key and secret-harvesting sprays. Includes artifacts to hunt (/var/tmp files, ns_helper, ns.conf edits) and IOC repo pointers.

Citrix NetScalerSliverSSH+2
CVE-2026-88771CVE-2026-88772CVE-2026-88779+8

Threat Intel, Blue Team & Detection, Malware & RE· Added 30 Oct 2026, published 7 Oct 2026

arxiv.orgpaper🧠 AI

Fault-tolerant foundation models

This arXiv paper shows that large language models can be trained to tolerate unreliable, faulty digital hardware, and that their error resilience improves rather than degrades as model size increases. Using modified neural scaling laws derived from 40,000 GPU-hours of training runs on simulated faulty hardware, the authors argue that LLMs learn to compute within "good" error-correcting codes whose relative overhead stays finite regardless of scale, suggesting a path toward running AI inference on low-energy, unreliable hardware for substantial energy savings.

research, training· Added 8 Oct 2026, published 7 Oct 2026

latent.spacearticle🧠 AI

Can a Cloud-Native Harness Make Agents Reliable Beyond the Desktop?

Latent Space interviews Stacklok founders Craig McLuckie and Joe Beda (Kubernetes co-creators) about Mecatl, an open-source "cloud-native harness" for coding agents that separates the agent loop from local tool execution, session state and model provider so enterprises can run and govern agents centrally rather than on individual desktops. The piece also covers Stacklok's earlier pivot from supply-chain security to ToolHive, an open-source platform/Kubernetes operator for running and governing MCP servers, and a not-yet-open-sourced "AI Gateway" focused on access control, budgets and provider routing for regulated enterprises (banks, telcos, semiconductor firms). The framing draws an explicit analogy to how Kubernetes decoupled enterprises from cloud providers, arguing agent harnesses need the same "cattle not pets" treatment to scale beyond desktop tools like Claude Code, Codex and GitHub Copilot.

KubernetesModel Context ProtocolDocker+4
StacklokMecatlToolHive+8

agents, ai-infra, mcp· Published and added 7 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Hashing Beats Trees: Practical Oblivious Dictionaries in SGX

An IACR ePrint paper by Erik-Oliver Blass and Travis Mayberry proposing oblivious probabilistic hash tables (chaining, power-of-two-choices, stash-less cuckoo, de-amortized cuckoo hashing) built over Path ORAM as a replacement for oblivious AVL trees when deployed inside Intel SGX enclaves. It shows that SGX's small trusted client memory lets the position map recursion be shrunk to ≤3 levels, making constant-access hash tables beat Θ(log n) tree traversal, and derives via large-scale simulation the concrete padding parameters needed for "double obliviousness" (bounding hash-table rebuild probability to ≤2^-40) that prior ORAM literature lacked. Their SGX implementation reports up to 20x faster lookups and 12x faster inserts than oblivious-tree baselines.

Intel SGX
Erik-Oliver BlassTravis Mayberry

Hardware & RF· Added 8 Oct 2026, published 7 Oct 2026

arxiv.orgpaper🧠 AI

TR-PTQ: High-Accuracy Integer-Only Transformer Post Training Quantization via Taylor Region Reformulation

TR-PTQ is a post-training quantization method for transformers that identifies learned LayerNorm scale parameters and GELU's compounded approximations (not SoftMax) as the main sources of accuracy loss when quantizing, contrary to common assumptions about numerical precision. It introduces a unified integer-only formulation using shared Taylor Region exponential/logarithm primitives so division and square roots can run entirely in the log-domain with standard integer arithmetic, paired with a calibration-free, outlier-aware LayerNorm optimization, eliminating the need for floating-point hardware for nonlinearities while keeping accuracy degradation under 1.5% across vision and language benchmarks.

Transformer

inference· Added 8 Oct 2026, published 7 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Retention Choices for Quantum CHAM Key Search under a Global Qubit Budget

This IACR eprint paper studies how to allocate a fixed global logical-qubit budget across parallel Grover search workers attacking 80-round and revised 112-round CHAM-128/128, choosing which intermediate round values to retain to minimize circuit depth while meeting a target key-recovery success probability. Testing 83- and 99-set retention libraries against a no-retention/full-retention baseline across 654 budget and Toffoli-decomposition conditions, the authors report mean depth reductions of 11.12% and 8.39% with strict improvements in most conditions, and show retained-value counts don't necessarily scale with budget. The work gives concrete logical-layer resource estimates for quantum attacks on CHAM, relevant to post-quantum migration planning for the lightweight cipher in constrained systems.

CHAM
CHAM-128/128Grover's algorithm

other· Added 8 Oct 2026, published 7 Oct 2026

decrypt.coarticle🧠 AI

Someone Scraped 5.6 Billion TikTok Videos and Put the Data on Hugging Face for Free

A developer using the handle "hashfunction" published a 460GB Hugging Face dataset of metadata (captions, hashtags, sound IDs, engagement counts, AI-generation flags) for roughly 5.6 billion public TikTok videos spanning July 2014 to October 2026, released under CC BY-NC 4.0. The data was reportedly pulled from TikTok's private mobile API using spoofed device identities and TLS handshakes rather than TikTok's official, application-gated Research Tools, in apparent violation of TikTok's terms of service; commercial access, creator profiles, daily updates, and the $1,699 scraper source code are sold via datasocial.ai. The piece situates this alongside other scraped TikTok-metadata dumps on Hugging Face and ongoing litigation (Reddit v. Perplexity/SerpApi) over large-scale AI training-data scraping.

Hugging Face
TikTokhashfunctiondatasocial.ai+4

training, ai-policy· Published and added 6 Oct 2026

arxiv.orgpaper🧠 AI

A Systematic Study of Small Language Models on Abstract Reasoning Tasks

This paper presents a systematic empirical study of small language models (decoder-only, encoder-decoder, and mixture-of-experts architectures) on abstract grid-transformation reasoning, using the ARC-TGI benchmark, which supports controllable task families, resampling, spatial shifts, and cross-benchmark transfer to distinguish genuine rule acquisition from distribution-specific overfitting. Across more than 1,000 supervised fine-tuning runs, the authors find that in-distribution accuracy is achievable but highly sensitive to optimization and task formulation, performance collapses sharply out-of-distribution (even under simple grid-scale changes with the same underlying rule), training-set scale yields uneven gains, in-context example benefit is model-family dependent, and executable-rule induction surfaces correct solutions that direct grid generation misses. Layer-wise attention diagnostics reveal behavioral differences in concentration and context-dependence but stop short of establishing causal mechanisms, underscoring that abstract-reasoning scores are conditional on model, adaptation regime, evaluation distribution, and output format.

TransformerMixture of Experts
ARC-TGINur A Zarin Nishat

research, evals· Added 7 Oct 2026, published 6 Oct 2026

arxiv.orgpaper🧠 AI

Toward Alignment Scaling Laws: A Framework and First Preregistered Measurements

This paper proposes a formal framework for "alignment scaling laws," modeling the compute/capability burden needed to hold a fixed safety target for each risk category as a power law B_r(N)=a_rN^alpha_r, where the exponent alpha_r determines whether alignment gets easier, keeps pace, or accumulates "alignment debt" as capability N grows. The authors prove theoretical results (the largest exponent among corrected risks sets the long-run regime, super-exponential headroom requirements above alpha=1, small-model fits underestimate large-scale exponents for power-law mixtures) and apply a preregistered protocol twice: a reanalysis of adversarial-training data on Pythia classifiers (attack-success compute exponent 0.60) and a pilot across Qwen2.5 (0.5B-72B) and Qwen3 (0.6B-14B), finding scaling helps for truthfulness and stated dispositions but sycophancy (exponent ~0.83-0.89) and a planted backdoor behave worse or remain undetermined, with the backdoor surviving blind safety training at most model sizes. The work matters as an early attempt to put the "does alignment get harder with scale" debate on measurable, falsifiable footing rather than anecdote.

PythiaQwen2.5Qwen3

ai-safety, research, evals· Added 7 Oct 2026, published 6 Oct 2026

mistral.aiarticle🧠 AI

Introducing Mistral Large 4 ("Le Chonk")

Mistral announces Mistral Large 4 ("ML4"/"Le Chonk"), a 1-trillion-parameter natively multimodal Mixture-of-Experts model with 52B active parameters, trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own European datacenters. The post details state-of-the-art open-weight results on cybersecurity benchmarks (82% on an Artificial Analysis vulnerability-reproduction test, 93% on Cybench), agentic coding (DeepSWE, Terminal-Bench, AutomationBench), finance/legal evals (via Vals, Harvey's Legal Agent benchmark), visual grounding (beating GPT-6 Astra on Dense 200), and safety benchmarks (Lakera B3, KORA). It also describes the large-scale RL post-training pipeline (33B tokens/day at 3k GPUs) used to produce the model, with full weights promised by end of month.

MistralMixture of Expertsvision-language model+1
Mistral Large 4GLM-5.3GLM-5.2+20

models, multimodal, evals, training· Added 7 Oct 2026, published 6 Oct 2026

theravenfile.comwriteup🛡️ Security

CITRIX 0-DAY EXPLOITS: CVE-2026–88771 & CVE-2026–88772 IN THE WILD

An incident-response style deep dive into active in-the-wild exploitation of Citrix NetScaler ADC/Gateway via CVE-2026-88771 (unauthenticated RCE through log-poisoning of ns_monuploadd_err.pl) and CVE-2026-88772 (DTLS memory overflow), part of 8 CVEs disclosed by Citrix on September 27, 2026. The author reverse-engineers the full post-exploitation toolkit dropped after root is obtained: SLAPSHOT (a Perl/Python loopback TCP tunneler/pivot), WHIPSHOT (a disguised PHP web shell served via fake CSS paths), the Platypus C2 agent, and a Perl "Pitboss" dropper script (with full decoded source and an embedded SHA-256-protected PHP web shell) that creates a rogue superuser, SUIDs /bin/sh, exfiltrates NetScaler config, and patches httpd.conf for persistence. It closes with extensive IOCs (C2 IPs, file hashes, paths, credentials) and patch guidance for affected NetScaler builds.

Citrix NetScalerPHPPython+2
CVE-2026-88771CVE-2026-88772CVE-2026-88773+10

Threat Intel, Malware & RE· Published and added 6 Oct 2026

orca.securityadvisory🛡️ Security

Citrix NetScaler Zero-Day Exploited in the Wild Crashes SAML Authentication Services

Analysis of CVE-2026-88779 (CVSS v4.0 8.7), an unauthenticated memory-overflow flaw in the nsaaad SAML authentication handler on Citrix NetScaler ADC/Gateway that lets attackers crash the SAML service and lock out VPN/SSO access indefinitely through repeated triggering. Affects NetScaler 14.1 before 14.1-73.41 and 13.1 before 13.1-64.28 (plus FIPS/NDcPP builds); watchTowr Labs reproduced it via honeypot activity, Citrix confirmed targeted in-the-wild exploitation from IP 213.209.159.55, and CISA added it to KEV on 2026-10-04 with an Oct 7 federal remediation deadline. Some researchers suspect the overflow could extend to RCE beyond the documented DoS, though Citrix hasn't confirmed this.

Citrix NetScalerSAMLCVSS+1
CVE-2026-88779CWE-119watchTowr Labs+1

Identity & Access, Threat Intel· Published and added 5 Oct 2026

arxiv.orgpaper🧠 AI

Towards Looped Models Done Right, Part II: Rethinking at Fixed Points

This paper studies looped language models — architectures that reuse a shared block of layers recurrently — and argues that as recurrent hidden states approach fixed points, the specific path taken to reach them matters less, enabling several efficiency tricks: truncated backpropagation through time during training, terminal key-value (KV) cache sharing across loop iterations for faster decoding, a distilled student model that prefills up to 1.79x faster, and RL policy gradients computed from saved rollout states that run 2x faster than backpropagating through the full trajectory. To make these fixed points reliable, the authors replace fixed-depth training with a learned depth prior (regularized with an entropy term to stay broad, improving on Huginn's fixed broad prior) and introduce orthogonal input injection, which removes the component of the injected input that the hidden state could otherwise amplify or cancel. Across model scales from 100M to 1.6B parameters, both changes lower perplexity, and at 1.6B the learned prior with a 3x smaller KV cache matches the downstream performance of full-cache fixed-depth training.

Huginn

research, training, inference· Added 6 Oct 2026, published 5 Oct 2026

arxiv.orgpaper🧠 AI

How to scale your HEP ML models: A recipe for robust architecture comparisons at scale

This paper proposes a systematic procedure for deriving robust scaling laws and comparing architecture design choices at scale, validated first on toy problems and then applied to multi-task transformers trained on the ~11 billion-jet ATLAS JetSet2 dataset. It covers both compute-constrained and data-constrained regimes, jointly predicting optimal model size, training horizon, learning rate and batch size under early stopping, and finds a near-equal sqrt(C) scaling of model and dataset size along with benefits from auxiliary training objectives. The work argues that large, high-quality simulation datasets are a prerequisite for reliable scaling studies and future foundation models in high-energy physics.

Transformer
ATLAS JetSet2

research, training· Added 6 Oct 2026, published 5 Oct 2026

eprint.iacr.orgpaper🛡️ Security

Comparative Evaluation of Open-Source Gröbner Basis Implementations for Small-Scale AES Polynomial Systems over GF(2)

This IACR ePrint paper benchmarks 20 open-source Gröbner basis implementations against the proprietary Magma system on polynomial systems derived from small-scale AES over GF(2), using Easy/Medium/Hard difficulty tiers with ten instances each. In the Hard setting, msolve and Singular's slimgb completed all runs successfully with mean runtimes of 164s and 269s and peak memory of 3693/4343 MiB respectively, versus Magma's 319s and 16853 MiB, with msolve exploiting ~13.4 CPU cores versus ~1 core for the others. The results quantify when open-source algebraic solvers are practical alternatives to Magma for algebraic cryptanalysis of block ciphers.

MagmamsolveSingular
F4 algorithmsmall-scale AESGF(2)

other· Added 8 Oct 2026, published 5 Oct 2026

arxiv.orgpaper🧠 AI

ImproveAnyTask: An Autonomous Post-Training Harness for Iterative Model Self-Improvement

ImproveAnyTask is an autonomous post-training harness that automates adapting general-purpose LLMs to specific tasks under a limited compute budget, structuring the process into error attribution, update-direction selection, and executable model updates via generated training data and configs with small-scale validation before full runs. Across 11 tasks it reports mean gains of 18.29 and 11.97 percentage points on Base and Instruct models respectively, with validated strategies retained for reuse in future adaptation cycles.

training, agents, research· Added 6 Oct 2026, published 5 Oct 2026

eprint.iacr.orgpaper🛡️ Security

N2SF-Based Post-Quantum Cryptography Migration Framework for Data in National and Public Institutions

An IACR ePrint paper proposes PQC migration decision criteria for data held by national and public institutions, derived from South Korea's N2SF (National Network Security Framework) protection requirements and each data object's cryptographic dependencies/operational state. It distinguishes migration actions (payload retention, key rewrapping, re-encryption, communication migration, signature renewal) from execution decisions (allow/defer/deny), requiring consistent completion checks, recoverable registered copies, and current authority. A reference implementation ran 225 policy trials and 9 interruption trials, showing per-stage/completion rechecking prevented unauthorized completions or reads that occurred when reusing initial decisions, and confirmed clean resumption after interruption; institutional approval and production-scale key management remain unvalidated.

Post-quantum cryptography
N2SFDo-Yun ParkYu-Lim Hyoung+1

GRC· Added 8 Oct 2026, published 5 Oct 2026

x.comadvisory🛡️ Security

Cyber Security News (@The_Cyber_News) on X

Citrix issued emergency patches for CVE-2026-88779, a memory-overflow zero-day in NetScaler ADC/Gateway appliances configured as a SAML service provider or identity provider, rated CVSS v4.0 8.7. Citrix confirmed active, targeted exploitation against unmitigated deployments, with repeated exploitation causing denial of service and disrupting dependent authentication services.

Citrix NetScalerCVSSSAML
CVE-2026-88779

AppSec, Identity & Access· Added 6 Oct 2026, published 5 Oct 2026

x.comthread🧠 AI

Rajashekar Sudireddy (@raja_sudireddy) on X

A tweet thread recapping Nate Herk's 18-concept guide to running OpenAI's Codex as a non-coder "AI operating system," organized around four pillars: a place to work (projects, AGENTS.md, the agent loop), a place to run it (local vs cloud environments, worktrees, .codex), controls (models, effort, permissions, skills, plugins), and tools/scale (browser, Sites, subagents, scheduled tasks, voice). It highlights AGENTS.md as the ground-rules file that replaces repeated context-setting (Herk ported his Claude Code CLAUDE.md into it), frames reusable "skills" as an iteratively refined recipe, and describes scheduled tasks as the mechanism that injects prompts into sessions automatically for always-on workflows.

CodexClaude Code

coding-agents, prompting· Published and added 4 Oct 2026

thehackernews.comadvisory🛡️ Security

Critical FortiMail Zero-Day Flaw (CVE-2026-104286)

CISA added CVE-2026-104286 (CVSS 9.8), a path traversal and NULL-byte handling flaw in Fortinet FortiMail, to its Known Exploited Vulnerabilities catalog after confirming active in-the-wild exploitation. The bug lets unauthenticated attackers write arbitrary files via crafted HTTP/HTTPS requests, affecting FortiMail 7.2 through 8.0.1; Fortinet published workarounds (disabling IBE, restricting management-interface access) ahead of patches and shared attacker IPs and modified/added files as IOCs. The article also lists several other actively exploited vendor flaws disclosed the same week (Check Point, Arista VeloCloud, F5 BIG-IP APM, Cisco Catalyst SD-WAN Manager, Citrix NetScaler).

FortiMailCISA KEVCVSS
CVE-2026-104286CVE-2026-85102CVE-2026-93616+9

Threat Intel, AppSec· Added 3 Oct 2026

arxiv.orgpaper🧠 AI

VisionMX: Unlocking Microscaling Post-Training Quantization for Vision Models

VisionMX is a post-training quantization method for vision models using Microscaling (MX) formats, which pair low-precision numeric elements with shared block scales for efficient inference. The paper identifies three error sources in direct MX conversion of vision models—block-scale representation, poor alignment of small convolutional weights with nonuniform element grids, and underuse of signed codes by nonnegative activations—and addresses them via bounded weight rounding and a foldable affine activation correction. It is evaluated across image classification, object detection, semantic segmentation, and low-light image enhancement, showing improvements over direct conversion and existing post-training quantization baselines, especially for architectures most sensitive to MX conversion.

CNN

research, inference· Added 5 Oct 2026, published 2 Oct 2026

7asecurity.comarticle🛡️ Security

Five Kubernetes Security Gaps Attackers Chain Together

7ASecurity breaks down five Kubernetes misconfiguration categories their pentesters repeatedly chain into working attack paths: over-permissive RBAC defaults, exposed API server/dashboard/kubelet, missing network policies, unsafe pod defaults (root/privileged containers, host path mounts), and weak admission control. It uses a concrete audit example from CNCF's KEDA project, where the Helm chart's scaledRefKinds setting defaulted to wildcard get access across API groups and resource types, silently undermining KEDA's own Secret-access restriction, plus references to Linkerd mesh audits and the NSA/CISA Kubernetes Hardening Guide.

KubernetesKEDALinkerd+1
NSA/CISA Kubernetes Hardening GuideCIS Benchmark

Cloud & Infra, Offensive Security· Added 7 Oct 2026, published 2 Oct 2026

latent.spacewriteup🧠 AI

Academia is for Ambition — Alex Zhang, MIT

A Latent Space podcast transcript/interview with MIT PhD student Alex Zhang, creator of Recursive Language Models (RLMs) and a core contributor to GPU Mode and KernelBench, who discusses using recursive subagent calls, context offloading, and shared memory to let models work beyond fixed context windows. The conversation ranges across AI-generated GPU kernels and their verification gap, research taste in academia versus industry labs, why "harnesses" (as in Claude Code, Codex, and Pi) function as compositional generalizers, the Jev model's non-autoregressive output-space trade-offs, and large-scale agent swarm experiments at OpenAI, Kimi, and Sakana AI. It offers a researcher's-eye view of where capability overhang and new agent/harness architectures may be heading beyond today's standard transformer decoder.

TransformerCUDAClaude Code+2
Alex ZhangMITGPU Mode+27

agents, research· Published and added 2 Oct 2026

arxiv.orgpaper🧠 AI

Mimir: Physics-Grounded LLM Agents for Long-Horizon Irrigation Control

Mimir is a physics-grounded LLM agent for long-horizon irrigation control that pairs a fast-timescale loop — where a structured physical interface and deterministic simulator verify, revise, and bound LLM-proposed actions before execution — with a slow-timescale loop that consolidates recurrent failure patterns into persistent contextual principles, while keeping the physical model, evaluator, and execution constraints immutable. Evaluated across multiple sites, crops, and years with a common retrospective evaluator, Mimir achieves the lowest aggregate control cost among tested baselines and uses about 51% less irrigation than historical schedule replay; ablations show forward simulation, verified revision, and persistent context are all necessary, and scaling LLM size or switching model families gives no monotonic improvement.

Mimir

agents, research· Added 2 Oct 2026, published 1 Oct 2026

arxiv.orgpaper🧠 AI

Selection-Based Structured Reasoning: Toward Efficient Multimodal Search Agents

The paper introduces Selection-based Structured Reasoning (SSR), a framework that replaces free-form chain-of-thought generation in multimodal search agents with selection among pre-specified, reusable natural-language reasoning candidates, scored by likelihood via teacher-forced prefilling with a shared KV cache. Evaluated on seven multimodal search benchmarks using 2B and 4B scale models under both reinforcement learning and supervised fine-tuning, SSR matches the success rate of leading search agents of the same scale while cutting per-turn reasoning latency by over 90% and total per-question inference latency by 28-54%. It targets the problem of small models producing long, low-value reasoning traces before each action, which is costly at inference time.

vision-language model

research, agents, multimodal· Added 2 Oct 2026, published 1 Oct 2026

openid.netpaper🧠 AI

Identity Management for Agentic AI [pdf] (2025)

A whitepaper from the OpenID Foundation, led by Tobin South with contributors from WorkOS, Stanford's Loyal Agents Initiative, and the Artificial Intelligence Identity Management Community Group, mapping how authentication and authorization standards apply to AI agents. It surveys current fixes (OAuth 2.1, Model Context Protocol authorization, enterprise SSO/SCIM provisioning, IPSIE profiles) and lays out unsolved problems for autonomous agents: delegated "on-behalf-of" identity versus user impersonation, consent fatigue at scale, recursive sub-agent delegation, multi-user shared agents, and browser/computer-use agents that bypass API-based authorization entirely.

Model Context ProtocolOAuthSCIM
OpenID FoundationTobin SouthWorkOS+7

mcp, agents, ai-policy· Added 2 Oct 2026, published 1 Oct 2026

openid.netpaper🛡️ Security

Identity Management for Agentic AI [pdf] (2025)

OpenID Foundation whitepaper (Oct 2025, lead editor Tobin South) analyzing how authentication/authorization for AI agents differs from traditional software clients. It covers where OAuth 2.1, OIDC, SSO/SCIM, and MCP already work for single-domain synchronous agents, and lays out unsolved problems for autonomous agentic identity: agent identity fragmentation across vendors, replacing user impersonation with explicit delegated "on-behalf-of" authority, consent-fatigue at scale, recursive delegation chains between sub-agents, agents acting for teams of users, and browser/computer-use agents bypassing API-based authorization entirely.

Model Context ProtocolOAuthOIDC+2
IPSIEOpenID FoundationLoyal Agents Initiative

Identity & Access, AI Security· Added 2 Oct 2026, published 1 Oct 2026

huggingface.coarticle🧠 AI

Introducing Olmo-core 3: Open, scalable training infrastructure for large MoEs

Allen AI's Olmo-core 3 is an open training framework redesigned to scale mixture-of-experts (MoE) models into the trillion-parameter range while preserving throughput. It replaces the earlier FSDP-based MoE implementation with a distributed-data-parallel system combining expert parallelism, pipeline parallelism and a distributed optimizer, plus optimizations like rowwise expert parallelism, GPU-resident routing, grouped GEMM and MXFP8 low-precision support; the post reports benchmarks up to 1.2T total parameters on 512 NVIDIA B300 GPUs (858 TFLOP/s/GPU) and a 2.38T-parameter test with DeepEP v2, alongside training pitfalls like "token gerrymandering" in load-balancing metrics. It underpins the next-generation Olmo model and is released openly as infrastructure, not just weights.

Mixture of ExpertsMegatron-Core
Olmo-core 3Olmo 3OlmoE+4

training, ai-infra· Published and added 1 Oct 2026

tldrsec.comarticle🛡️ Security

[tl;dr sec] #348 - Google's PageBreak Scanner, Perplexity's Agent Security Tool, Defending Agentically

tl;dr sec #348 is a weekly security newsletter issue. It summarises Google's PageBreak agent (500+ XSS bugs found since November 2025, validated deterministically), Perplexity's open-source Numbat agent-security tool (52 CEL rules), and SpecterOps' CiliumHound. It also covers Scaleway IAM attack paths, the NCSC essay on defending agentically, Julien Vehent on detection fidelity, and Wiz's Scan for Good.

PageBreakNumbatCiliumHound+3
XSSVolt TyphoonRed Agent+6

AI Security, AppSec, Blue Team & Detection· Added 30 Oct 2026, published 1 Oct 2026

unit42.paloaltonetworks.comadvisory🛡️ Security

Threat Brief: NetScaler Zero Days CVE-2026-88771 and CVE-2026-88772 Exploited in the Wild (Updated September 30)

Unit 42 threat brief on CVE-2026-88771 (unauthenticated command injection) and CVE-2026-88772 (DTLS memory overflow) in NetScaler ADC and Gateway, both CVSS v4.0 9.5 and exploited as zero-days from August 2026. It details version fingerprinting, .deb and PHP web shells, a three-stage log-poisoning chain through ns_monuploadd_err.pl, httpd.conf persistence, IOCs, and 50,277 exposed instances as of 27 September 2026.

Citrix NetScalerPHPApache+2
CVE-2026-88771CVE-2026-88772CVE-2026-88773+9

Threat Intel, Blue Team & Detection· Added 30 Oct 2026, published 30 Sep 2026

Showing 120 of 219

Show more