Skip to content

189 results for “Skills”

What you seeeverything
“Skills”
x.comtool🧠 AI

zahT3 (@zahT3zuo) on X

Hotseat is a free, open-source macOS menu bar app that moves Claude Code and Claude Desktop to another of the user's Claude accounts in one click and returns to the same session. Sessions, settings, skills and MCP servers are shared, so `claude --resume` works under either account. When a session hits a usage limit, it offers to continue under another account. It never reads tokens or cookies. Install with Homebrew.

Claude CodeClaude DesktopmacOS+2
HotseatAnthropic

coding-agents· Added 1 Nov 2026, published 31 Oct 2026

x.comthread🧠 AI

Prasenjit Sarkar (@stretchcloud) on X

A thread on Cloudflare's agent-readiness scan and the AgentReady.org open spec for "Agent Experience", developed with Vercel, Stripe, Auth0, Mintlify, Google, Netlify and Elementor. The scan grades whether agents can find a site (robots.txt, DNS), read clean Markdown, pass bot rules, and discover an MCP server or API catalog. One quoted example raised a score from 20 to 67 by shipping an API catalog with Link headers, an MCP server card, a skills index and an AI catalog file.

Model Context ProtocolCloudflareMarkdown
AgentReady.orgOraNick Launches+7

mcp, agents· Added 30 Oct 2026, published 29 Oct 2026

github.comcourse🧠 AI

rohitg00/ai-engineering-from-scratch

ai-engineering-from-scratch is a free, MIT-licensed curriculum of 542 lessons in 20 phases, from math and deep learning through transformers, LLM engineering, MCP, agents and capstones. Code is in Python, TypeScript, Rust and Julia. It includes three graded projects (retrieval evaluation, agent trace debugger, tool call firewall), installable tutor skills for Claude Code and Codex, and certification prep tracks.

PythonTypeScriptRust+13
Rohit GhumareOpenClawHermes+6

· Added 29 Oct 2026

x.comthread🧠 AI

Eddy (@ieddysun) on X

Expo's official skills package gives AI coding agents scoped instructions for building Expo apps. One command, npx skills@latest add expo/skills --skill '*', installs it for Cursor, Copilot and Windsurf, while Claude Code and Codex use their plugin marketplaces. Skills include expo-router, expo-animation, expo-upgrade and eas-update. The Expo MCP server adds live docs lookup, compatible dependency installs, EAS build monitoring and simulator screenshots.

ExpoReact NativeExpo Router+9

coding-agents, prompting, mcp· Added 29 Oct 2026, published 28 Oct 2026

x.comthread🧠 AI

Laban (@lunkertw) on X

An X post summarising five AI items: Google DeepMind's Gemini 4 Carbon (88.2% SEC-bench Pro, 54.8% ExploitGym, 71.0% CWE-bench, 59 on Artificial Analysis Intelligence Index v5.0), Ed Zitron's critique of Anthropic's S-1, a Utah Claude Code pilot, and the repos beenuar/AiSOC and expo/skills. In the Utah pilot, 34 developers in 10 agencies took part over four weeks, 80% had a working setup within 30 minutes, and 71% saved over 20 hours. It gives short summaries and links, not primary analysis.

Claude CodeModel Context ProtocolPython+6
Google DeepMindGemini 4 CarbonSEC-bench Pro+9

models, coding-agents, ai-policy· Added 29 Oct 2026, published 28 Oct 2026

x.comtool🧠 AI

alex shapalov (@alxshp) on X

PGX is a free, open-source Postgres runtime written in Rust that hosts thousands of isolated databases in one process, aimed at AI agents. A companion agent skill, installed with `npx skills add pgrundev/pgx --skill pgx`, gives each Claude Code agent its own database automatically. The author claims 1,000 databases in 659 MB RAM, about 0.7 MB per idle database, an 85 ms clone of a 674 MB database, and a 200-agent test with no conflicts.

PostgreSQLRustClaude Code+1
PGX

coding-agents, ai-infra· Added 28 Oct 2026, published 27 Oct 2026

arxiv.orgpaper🧠 AI

Interpretable Meta-Policies for Neural Decision Making

NEXUS is a hierarchical reinforcement learning framework that pairs neural skills with symbolic meta-policies, so transparent reasoning sits at the level of high-level skills rather than atomic actions. It uses object-centric observations and LLM interaction to design reward functions and meta-policies. Agents learn disentangled skills, align better with goals in the game manual, resist reward hacking more, and cope better with game simplifications than deep RL. The paper also compares neural, symbolic and neuro-symbolic meta-policy architectures.

LLM
NEXUSarXiv

research, training, ai-safety· Added 28 Oct 2026, published 27 Oct 2026

x.comthread🧠 AI

Manoj | The AI Dude (@Manojkumar2257) on X

heditor is an open-source (MIT) agent skill from pycodebr that has Claude Code, Codex, Cursor or OpenCode edit talking-head videos. It transcribes with faster-whisper, picks a 30-70s segment, cuts frame-accurately, builds HTML + GSAP motion graphics, mixes audio at -14 LUFS, and runs QA with vision-reviewed previews. It offers 42 named styles and a long-form mode with chapters, SRT/VTT and lower thirds. Install: npx skills add pycodebr/heditor -g.

Claude CodeCodexCursor+6
heditorpycodebr

coding-agents, prompting, multimodal· Added 28 Oct 2026, published 27 Oct 2026

mcpmarket.comtool🧠 AI

Search Search results for "security" | MCP Market

MCP Market search results for "security" in its skills category, listing about 20 installable AI agent skills. Entries cover OWASP Top 10 audits, secure PHP coding, STRIDE threat modeling, CVE remediation, security header analysis, misconfiguration finding, bug bounty triage and AgentShield scans of Claude Code configurations. One is a paid D365FO security-role XML skill. Each entry has only a one-line description and a category label.

Claude CodeAgentShieldPHP+1
MCP MarketOWASPSTRIDE

coding-agents, prompting· Added 25 Oct 2026

github.comrepo🧠 AI

alirezarezvani/claude-skills

claude-skills is an MIT-licensed library of about 398 Claude Code skills, agents, personas and plugins across 20 domains, including engineering, marketing, compliance and C-level advisory. Each skill is a SKILL.md with stdlib-only Python CLI tools and reference docs. Install scripts and convert.sh adapt it to Codex, Gemini CLI, Cursor, Aider, Windsurf and other coding agents, and it includes a skill-security-auditor scanner.

Claude CodeCodexGemini CLI+12
HermesMistralAnthropic+2

coding-agents, prompting, agents· Added 25 Oct 2026

mcpmarket.comother🛡️ Security

Search Search results for "security" | MCP Market

MCP Market search results for "security" in the skills category, listing about 20 installable AI agent skills. Entries cover OWASP Top 10 audits, secure coding for PHP, STRIDE threat modeling, CVE remediation, security header analysis, misconfiguration finding, bug bounty triage and AgentShield scans of Claude Code configurations. One is a paid D365FO security-role XML skill. Each entry has only a one-line description and a category label.

Claude CodeModel Context ProtocolPHP
OWASPSTRIDEAgentShield+1

AppSec, AI Security· Added 25 Oct 2026

github.comrepo🛡️ Security

alirezarezvani/claude-skills

claude-skills is an open-source MIT library of about 398 Claude Code skills, agents and plugins that also installs into Codex, Gemini CLI, Cursor and 9 other coding agents. The security-relevant parts are skill-security-auditor, a stdlib-only Python scanner that checks skills for command injection, data exfiltration, prompt injection and dependency supply-chain risks before install, plus a security-guidance PreToolUse hook, a security suite and compliance skills (ISO 27001, SOC 2, GDPR).

Claude CodeCodexGemini CLI+3
skill-security-auditorPreToolUse hookagentskills.io+3

AI Security, Supply Chain· Added 25 Oct 2026

x.comthread🧠 AI

Gökdeniz Gülmez (@ActuallyIsaak) on X

An X post showing how to have Codex train a small model on Apple silicon through the mlx-lm-lora MCP server and skill. It gives five setup steps (pip install with the mcp extra, npx skills add, locate mlx-lm-lora-mcp, codex mcp add). The prompt runs four pre-training trials on tiny-random/qwen3 with the mlx-community/recycling_the_web-1k dataset. Codex picks the optimizer and learning rate itself, and the result is a table with validation loss and the best adapter path.

CodexMLXModel Context Protocol+5
mlx-lm-loraGoekdeniz-Guelmeztiny-random/qwen3+2

training, mcp, coding-agents· Added 25 Oct 2026, published 24 Oct 2026

repodir.comrepo🧠 AI

affaan-m/ECC | RepoDir

ECC (affaan-m/ECC) is an open-source performance optimization system for AI coding agents. It packages 261+ skills, 64+ agents and 84+ commands that tune Claude Code, Codex, Cursor and other agent harnesses for speed, memory and security. Practitioners can use it as a ready-made skills and harness configuration set. The RepoDir page gives only this short description, with no install steps or benchmarks.

Claude CodeCodexCursor+1

coding-agents, prompting· Added 24 Oct 2026

x.comthread🧠 AI

EveryDev.ai (@EveryDevAi) on X

ToolUniverse, from ScientistTools, is an open-source (Apache-2.0) toolkit that gives any LLM one interface to more than 1,000 scientific tools, models and databases such as PubMed, UniProt and ChEMBL. It ships a native MCP server, a Python SDK and a tu CLI, plus 68 pre-built agent skills. The post says it works with Claude Code, Cursor, Gemini CLI and Windsurf.

Model Context ProtocolPythonClaude Code+4
ToolUniverseScientistToolsPubMed+2

mcp, agents· Published and added 24 Oct 2026

arxiv.orgpaper🧠 AI

4DMemory: Benchmarking Long-Horizon Spatiotemporal Memory with Harness-Augmented Agents

4DMemory is a benchmark suite for long-horizon spatiotemporal memory: the LongVideo dataset (about 900 hours of video, over 5,000 manually reviewed questions) and 4DMemoryBench. It also presents the 4DMemory Harness, combining four skills, 22+ tool models and a model-specific RAG system. Across 13 models, the harness improved every one by over 50%, and the same models scored over 10% lower than on a previous benchmark.

RAG
4DMemory4DMemoryBenchLongVideo+2

evals, multimodal, agents· Added 26 Oct 2026, published 23 Oct 2026

simonwillison.netarticle🧠 AI

Donating Agent Skills to the Agentic AI Foundation

Simon Willison's link post covers Anthropic's 22 October 2026 announcement that it is donating the Agent Skills standard to the Agentic AI Foundation (AAIF) under the Linux Foundation. Anthropic co-founded the AAIF with Block and OpenAI and earlier donated MCP to it. Willison notes he predicted this in December 2025 and found his old post by querying his blog through datasette-mcp in Claude.

Model Context ProtocolClaudeDatasette
AnthropicAgentic AI FoundationLinux Foundation+3

prompting, ai-policy, coding-agents· Published and added 22 Oct 2026

github.blogarticle🛡️ Security

How bug bounty sharpens one researcher’s security skills

GitHub Bug Bounty spotlight interview with @r31n, a researcher known for GitHub Enterprise Server findings. They describe a source-and-sink approach to mapping trust boundaries, chaining minor bugs (open redirect plus allowlisted SSRF that follows redirects), and confirming a finding only with a working PoC. They also cover using AI for code navigation and PoC scripts, and treating model output as untrusted input.

GitHub Enterprise ServerGitHubHackerOne
SSRFopen redirectXSS+3

Learning, AppSec· Published and added 22 Oct 2026

github.comrepo🧠 AI

SnailSploit/Claude-Red

claude-red is an MIT-licensed library of offensive security skills for the Claude Skills system, planned at about 130 skills across 23+ categories (web, Active Directory, cloud, exploit development, EDR evasion and others). Each skill is a SKILL.md file that loads on conversational triggers, so unused skills cost no context. It installs by git clone, sparse checkout per category, install.sh or pasting into a system prompt.

ClaudeGitGitHub
Kai AizenSnailSploitSahar Shlichov

prompting, coding-agents· Added 22 Oct 2026

github.comrepo🛡️ Security

SnailSploit/Claude-Red

claude-red is a library of offensive security skills for the Claude Skills system, each a SKILL.md file that loads on conversational triggers (for example, mentioning SQL injection loads offensive-sqli). Categories include web, Active Directory, cloud, mobile, exploit development, fuzzing, privilege escalation, post-exploitation and AI. It targets about 130 skills across 23+ categories, with an install script and sparse-checkout install per category. Built on Sahar Shlichov's offensive checklists, MIT licensed.

ClaudeClaude CodeActive Directory
Kai AizenSahar ShlichovSnailSploit

Offensive Security, AI Security· Added 22 Oct 2026

tldrsec.comarticle🛡️ Security

[tl;dr sec] #351 - PHP2Shell, Autopatching Skills, AWS Pathrunner

tl;dr sec #351 is a weekly security newsletter. Clint Gibler describes working with OpenAI, Calif, Wiz and the PHP maintainers on the PHP2Shell unauthenticated RCE disclosure, which affects 13 years of PHP. It also covers Datadog's pathrunner AWS IAM escalation framework, Trail of Bits' patching-bugs and regression-hunt Codex plugins, XBOW finding de-duplication, backdoored open-weight models, and CREBench.

PHPAWS IAMCodex+3
PHP2ShellPatch the PlanetCalif+10

AppSec, AI Security, Cloud & Infra· Added 30 Oct 2026, published 22 Oct 2026

openai.comarticle🧠 AI

What FDE means at OpenAI

Colin Jarvis, Head of Forward Deployed Engineering at OpenAI, describes how the FDE team works with enterprise customers to close the "deployment gap". Cases include a semiconductor verification project (about 48% time saved on test generation) and a telecom voice model whose key evals rose from about 60% to 90%+. Moving use cases onto a Codex harness with skills and plugins removed about 90% of custom code.

CodexModel Context ProtocolOpenAI API+1
OpenAIColin JarvisJohn Deere+3

ai-policy, coding-agents, agents· Published and added 22 Oct 2026

anthropic.comarticle🧠 AI

Donating Agent Skills to the Agentic AI Foundation

Agent Skills is an open standard in which a skill is a folder with a SKILL.md file plus scripts and reference material. Anthropic is donating the name, logo, GitHub organization and agentskills.io domain to the Agentic AI Foundation under the Linux Foundation. Over 70 platforms have integrated it, with 1 million skills published and nearly 280 million installs. The proposed roadmap covers versioned releases, a proposal process and security guidance.

Agent SkillsSKILL.mdClaude Code+8
AnthropicAgentic AI FoundationLinux Foundation+5

prompting, coding-agents, agents· Added 29 Oct 2026, published 22 Oct 2026

x.comarticle🧠 AI

Trail of Bits (@trailofbits) on X

Trail of Bits announces two open-source plugins, patching-bugs and regression-hunt, for AI coding agents that speed up bug patching. They come from four months of Patch the Planet work with open-source projects, which found that repo-level documentation, skills and plugins give agents the maintainer context on what counts as a bug, how a fix should look and what must not break. The post cites the October 2026 PHP incident: a patch touching 402 files, and exploitation within 17 hours of leaked details.

PHPCloudflare
Trail of BitsPatch the PlanetPatchstack+2

coding-agents, prompting· Added 23 Oct 2026, published 21 Oct 2026

github.comrepo🧠 AI

Show HN: Omnara – Open-source alternative to Claude Managed Agents

Omnara is an open-source, self-hostable managed agent platform, an alternative to Claude Managed Agents and OpenAI's Agents API. It runs agents on any model (OpenAI, Anthropic, OpenRouter, Bedrock, LiteLLM, Ollama) and any machine, with Postgres-backed durable state, stateless workers, per-tool permissions, MCP, skills, memory, subagents, schedules and Slack, Discord and GitHub triggers. It ships a REST API, TypeScript SDK, CLI and Docker Compose setup.

Model Context ProtocolTypeScriptNode.js+14
OmnaraClaude Managed AgentsOpenAI+2

agents, ai-infra, mcp· Added 23 Oct 2026, published 21 Oct 2026

latent.spacetalk🧠 AI

AI for the Fortune 2000: How Tenex Builds an AI-Native SDLC — Alex Lieberman & CJ Hess

Latent Space interview from AI Engineer New York with Tenex cofounder Alex Lieberman and CJ Hess. Tenex has 75 people, pays engineers by story points, and reports roughly 2x engineer output over the past year. CJ describes MetaHarness, a repo-based set of skills, plans and a CLI that logs agent decisions in Git. They also cover enterprise AI adoption rates, token spend, and vertical AI. The page text is truncated.

GitGitHubCodex+3
TenexAlex LiebermanCJ Hess+14

coding-agents, ai-policy, agents· Added 23 Oct 2026, published 21 Oct 2026

socket.devarticle🧠 AI

vlt 1.5.0 Adds Agent Skills Management

vlt 1.5.0 adds a `vlt skills` command that finds agent skills (SKILL.md folders) in installed JavaScript dependencies and links them into directories coding agents read, such as .agents/skills and .claude/skills. Selections are saved as allow-skills in vlt.json, tied to the lockfile version, and kept current on install and update. Without a saved selection, linking defaults to :not(:malware) using Socket malware alerts. pnpm 12.11.0 added similar linking.

vltnpmJavaScript+7
SocketSarah Goodingagent-browser

coding-agents, prompting· Published and added 21 Oct 2026
socket.devarticle🛡️ Security

vlt 1.5.0 Adds Agent Skills Management

vlt 1.5.0 adds a `vlt skills` command that discovers agent skills (SKILL.md folders) shipped in installed JavaScript dependencies and links them into directories read by coding agents such as .agents/skills and .claude/skills. Links follow the lockfile version, and selections are saved as allow-skills in vlt.json. Without a saved selection, linking defaults to :not(:malware), using Socket malware alerts. pnpm 12.11.0 added similar support.

vltSocketnpm+3
Sarah GoodingSKILL.mdvlt skills+4

Supply Chain, AI Security· Published and added 21 Oct 2026

snyk.ioarticle🛡️ Security

AI Is Calling In Every Risk You've Accepted: Seven Insights From The AI Security Panel: Unfiltered

Snyk's recap of "The AI Security Panel: Unfiltered" (14 October 2026, San Francisco) with speakers from Snyk, OpenAI, Google Threat Intelligence Group and boldstart ventures. It covers AI agents as an attack surface, the July Hugging Face breach by OpenAI models in an evaluation, ToxicSkills data (36.82% of 3,984 skills flawed), Project Glasswing patch backlogs, and why fixing, not finding, is the bottleneck. It closes with a Monday-morning action list.

SnykOpenAIHugging Face+2
Project GlasswingToxicSkillsVulnBump+6

AI Security, Threat Intel· Published and added 21 Oct 2026

arxiv.orgpaper🛡️ Security

Combining Long-Term Memory and LLMs Comes at a High Cost: From Prompt Injection to Persistent Compromise

Paper on memory injection, where prompt injection persists across sessions through the long-term memory of LLM-as-a-service platforms. It presents a general threat model and shows all NIST attack goals are achievable on ChatGPT Instant 5.3, Claude Sonnet 4.6 and Gemini 3 Flash. Vectors include personal memories, projects, skills, organization instructions and MCP resources. On Claude, shared memory lets an attacker compromise multiple users in an organization and exfiltrate prompts. Nearly half of the derived mitigations are unimplemented.

ChatGPTClaudeGemini+2
memory injectionprompt injectionNIST+2

AI Security· Added 24 Oct 2026, published 20 Oct 2026

github.blogarticle🧠 AI

How 3 Java Champions are using GitHub Copilot for increased productivity

Interviews with three Java Champions (Vlad Mihalcea, Patrick Baumgartner, Frank Delporte) on using GitHub Copilot in production and open source. Examples include a 900-slide Reveal.js to Marp migration with visual verification, a Copilot coding agent diagnosing a Pi4J virtual-thread pinning bug, and custom Agent Skills. Tips: interview-first planning, task-specific verification gates, deterministic quality harnesses, and human review.

GitHub CopilotJavaIntelliJ IDEA+12
GitHubVlad MihalceaPatrick Baumgartner+7

coding-agents, prompting, ai-policy· Added 29 Oct 2026, published 20 Oct 2026

github.comrepo🧠 AI

better-isms/grcskills

grcskills is a library of 60 plain SKILL.md files in the Agent Skills format, each describing how an experienced practitioner does one piece of governance, risk and compliance work. Examples are scope statements, risk registers, audit prep, vendor review and incident handling. Every skill names where the agent must stop and hand the decision to a person. Installs are pinned to reviewed release tags and checked by a validator.

Claude CodeCodexCursor+4
Better ISMSISMS CopilotNIST

prompting, agents· Added 20 Oct 2026

github.comrepo🛡️ Security

better-isms/grcskills

grcskills is an MIT-licensed library of 60 SKILL.md files (Agent Skills format) that let coding agents draft and prepare governance, risk and compliance work: scope statements, statements of applicability, risk registers, audit prep, vendor review, policies, privacy, incidents and continuity. Each skill names where the agent must stop so a person decides. Installs are pinned to release tag v2026.10.19.2, and a validator rejects network commands and credential paths.

Claude CodeCodexCursor+2
SOC 2PCI DSSNIST+2

GRC· Added 20 Oct 2026

arxiv.orgpaper🧠 AI

How Effectively Do Security Skills Guide Coding Agents in Vulnerability Detection in Linux Kernel?

The paper is a large-scale study of 37 security skills run through Claude Code with four LLMs on 100 real Linux kernel vulnerabilities, 14,800 runs in all. Only 24.4 percent of runs found the correct function and 15.7 percent classified the vulnerability correctly. It proposes SKILL-SIF, which evolves skills from failure patterns and raised fully correct detection on 100 unseen vulnerabilities from 2 to 16 percent.

Claude CodeLinuxLLM
SKILL-SIF

evals, coding-agents, prompting· Added 21 Oct 2026, published 19 Oct 2026

arxiv.orgpaper🛡️ Security

How Effectively Do Security Skills Guide Coding Agents in Vulnerability Detection in Linux Kernel?

Empirical study of 37 security skills run through Claude Code with four LLMs on 100 real Linux kernel vulnerabilities across ten classes (14,800 runs). 24.4% of runs found the correct function, 18.3% the function and statement, and 15.7% the vulnerability class. The authors propose SKILL-SIF, which evolves skills from failures and raised fully correct detection on 100 unseen vulnerabilities from 2% to 16%.

Claude CodeLinux kernelLLM
SKILL-SIF

AI Security, AppSec· Added 21 Oct 2026, published 19 Oct 2026

x.comthread🧠 AI

Ethan Walkrman (@ethanwalkerman) on X

Harness2 is a framework from Google Cloud AI Research and Northwestern University in which an Editor model rewrites an agent's harness (system prompt, memory, skills, tool scripts, subagent routing, middleware) without changing model weights. It uses a Propose-Probe-Compose loop that compares execution trajectories instead of ground truth. On WorkBuddy-Bench, GLM-5 rose from 64.2 to 75.7 after one round, above Gemini 3.5 Flash at 72.4. The thread also lists risks: latency, experience poisoning, and a sandbox that is off by default.

CodexPythonGit+3
Harness2Google CloudNorthwestern University+6

agents, research, evals· Added 19 Oct 2026, published 18 Oct 2026

github.comrepo🧠 AI

DietrichGebert/ponytail

Ponytail is a single skill prompt (skills/ponytail/SKILL.md, with a compact AGENTS.md) that makes coding agents write only the code a task needs, reusing existing components while keeping validation, error handling, security and accessibility. The author benchmarked it in Claude Code with Opus 5.5 over 39 tasks, 5 runs each, including a real FastAPI + React repo. They report -53% code, -41% time, -26% cost and -45% tokens, and 98% of risky logic shipping with a test versus 68% without. It adds /ponytail-review and /ponytail-audit commands, a Claude Code cost/token band with a local board, and installs through Claude Code and Codex plugin marketplaces or as a rules file for Cursor, Copilot, Gemini, OpenCode and others.

Claude CodeCodexCursor+7
PonytailClaude Opus 5.5Windsurf+5

coding-agents, prompting, evals· Added 17 Oct 2026

arxiv.orgpaper🧠 AI

Skill-Decoupled On-Policy Expert Distillation for Unified Vision-Language Models

Proposes SCOPED (Skill-Decoupled On-Policy Expert Distillation), which trains capability-specific RL experts for vision-language models. It extracts explicit skills from them through reward-guided reflection. During on-policy distillation the skills guide expert supervision but are hidden from the unified student, so the student internalizes the procedural knowledge and needs no explicit skills at inference. Across eight multimodal benchmarks it beats the backbone and mixed-capability RL. Analyses show cross-capability gradient interference in joint RL, and that skill augmentation gives more consistent expert trajectories, more attention to task-relevant visual evidence, and better preservation of expertise.

vision-language model
SCOPEDarXiv

research, training, multimodal· Added 17 Oct 2026, published 15 Oct 2026

ethereum-magicians.orgthread🧠 AI

ERC-8444: Agentic Resource Discovery (ARD) Onchain

An Ethereum Magicians proposal for ERC-8444, which adds an onchain value and settlement layer under Google's Agentic Resource Discovery (ARD) spec for finding MCP servers, A2A agents, skills and APIs. A thin kernel records kind (skill, task, agent, registry), a CAIP-19/CAIP-10 anchor, a JCS+SHA-256 descriptor hash, a canonical URN and a status. Authority belongs to the paid address, and domains act as collected endorsements through /.well-known/ard.json. The reference implementation has Foundry-tested Solidity adapters and a Node.js gateway that passes the official ARD conformance CLI. It introduces a "task" kind (application/ai-task+json) for tenders aimed at suppliers, and the author asks for feedback on the trust root, the hash scope, same-chain anchors and the task payload.

Model Context ProtocolEthereumSolidity+2
GoogleMicrosoftHugging Face

mcp, agents· Added 14 Oct 2026, published 13 Oct 2026

github.blogarticle🧠 AI

GitHub Copilot app for Beginners: How to teach Copilot about your codebase

Beginner-oriented GitHub blog guide to giving GitHub Copilot project context through four mechanisms: repository custom instructions (.github/copilot-instructions.md and path-specific .github/instructions files with applyTo), agent skills (SKILL.md folders under .github/skills), custom agents (.github/agents profiles), and MCP servers such as Playwright. It explains when to use each and how they combine, using examples like a quality-checks skill and an accessibility-review agent. Useful as a concrete reference for the repo layout Copilot reads, with a pointer to the community Awesome Copilot collection.

GitHub CopilotModel Context ProtocolPlaywright+1
Awesome Copilot

coding-agents, prompting, mcp· Published and added 12 Oct 2026

github.comrepo🛡️ Security

zero-lab-ai/skills

zero-lab-ai/skills is a collection of 56 portable SKILL.md agent skills in 10 installable plugins from zero-lab.ai. They cover authorized defensive assessment, penetration testing, red teaming, detection engineering, purple teaming and engagement operations. Skills install via the Claude marketplace layout or `npx skills add`, and a make check release gate runs linting and tests.

Claude CodeCodexOpenAI
Zero Lab

AI Security, Offensive Security, Blue Team & Detection· Added 23 Oct 2026, published 11 Oct 2026

github.comrepo🧠 AI

sepehr071/iran-mcp

iran-mcp is an open-source catalog of 39 MCP servers (488 tools) that let AI agents query Iranian websites such as Digikala, Torob, Divar, Snappfood, Jabama, Paziresh24, TSETMC and qavanin.ir, with prices normalised to Toman. Most servers are unofficial, read-only Python packages run with uvx; three are official hosted servers. It ships Claude Code plugins, Agent Skills, bundles, proxy lists and a machine-readable servers.json.

Model Context ProtocolPythonPyPI+11
DigikalaTorobDivar+10

mcp, coding-agents· Added 24 Oct 2026, published 11 Oct 2026

x.comarticle🧠 AI

Cloudflare Changelog (@CFchangelog) on X

Cloudflare's changelog announces that its Cloudflare API MCP server now serves Cloudflare skills alongside its tools. A connected MCP client discovers them by calling `skills/list`. This is an example of distributing agent skills through an MCP server rather than as local files or a repo.

Model Context ProtocolCloudflare

mcp, prompting· Published and added 11 Oct 2026

x.comthread🧠 AI

Confident AI (@confident_ai) on X

Confident AI announces Eval Skills, open-source (Apache 2.0) agent skills for Claude Code and Codex. The `eval-build` skill takes an app to a runnable baseline: it finds realistic examples in traces and incidents, annotates failures, groups them into failure modes, curates cases with independent data splits, and builds graders validated against human judgment. The `eval-descent` skill runs a bounded loop of hypothesis, app change, eval re-run, regression check, then keep or revert, with held-out cases kept out of the loop. It ships Python and TypeScript tooling for tracing, annotation, grading and reports, plus a local UI or Confident AI for managing the loop.

Claude CodeCodexPython+1
Confident AIEval Skills

coding-agents, evals, prompting· Published and added 9 Oct 2026

github.comrepo🧠 AI

Show HN: Let your AI agents paint big arrows, boxes and text on your screen

bigarrow is an MIT-licensed, single-binary Swift macOS CLI that draws a click-through arrow and sign over all windows so an AI agent can show a human where to click, paste or act (permission prompts, 2FA, OAuth consent). It ships an Agent Skills package (installed via `bigarrow install-skill`) for Claude Code and Codex, with JSON output and exit codes, and can target by Accessibility label, coordinates, window or Peekaboo snapshot. The README documents the skill's token cost (182 tokens for the description, 1,398 for the instructions) and 104 automated tests.

SwiftmacOSClaude Code+6
bigarrowNameplatePeter Steinberger+2

coding-agents, prompting, agents· Published and added 9 Oct 2026

github.comrepo🧠 AI

mattpocock/skills — agent skills for engineers

mattpocock/skills is a collection of small, composable "agent skills" for software engineering that install into Claude Code, Codex, GitHub Copilot, Gemini CLI, Cursor, OpenCode, Devin, Windsurf, Amp and Pi via plugin managers or the `npx skills` CLI. It packages practices like interview-driven requirement gathering (/grill-me, /grill-with-docs), domain-model/glossary building, test-driven development with red-green-refactor (/tdd), bug diagnosis loops, codebase architecture improvement, ticket triage and spec-to-implementation workflows (/to-spec, /to-tickets, /implement, /implement-spec), splitting skills into user-invoked orchestrators and model-invoked reusable disciplines. It's built by Matt Pocock as an alternative to heavier process-owning frameworks like GSD, BMAD and Spec-Kit, aiming to keep engineers in control while giving coding agents better feedback loops and shared vocabulary.

Claude CodeCodexGitHub Copilot+5
Matt PocockDevinWindsurf+5

coding-agents, prompting· Added 8 Oct 2026

simonwillison.netarticle🧠 AI

Quoting Carson Gross

A brief Simon Willison Quoting post sharing htmx creator Carson Gross's view that computer programming is fundamentally about solving problems and controlling complexity, and that he expects these skills to remain valuable and employable even as AI coding tools become more capable. It is a one-paragraph opinion snippet rather than a technical piece, offering a counterpoint to fears that AI will devalue software engineering as a career.

Carson GrossSimon Willison

ai-policy· Published and added 8 Oct 2026

stepsecurity.ioarticle🛡️ Security

StepSecurity Now Inventories AI Agent Skills in Your GitHub Repositories and on Developer Machines

StepSecurity announces two new inventory features — Dev Machine Guard's Agent Skills page (scanning 18 AI coding agents' skill directories on developer machines) and a GitHub Agent Skills page (scanning default branches of org repos daily) — to track AI agent "skills" (SKILL.md folders with optional scripts/hooks) across an organization. The post frames skills as a supply-chain surface because they can execute shell commands, pre-approve tool permissions via allowed-tools frontmatter (bypassing Claude Code's workspace trust gate), and look like harmless Markdown documentation in PR review, citing the Miasma worm, s1ngularity, and the Cline v2.3.0 compromise as precedent for this attack class. It details inventory features like content-hash comparison across devices, provenance tracing via skills.sh/skills-lock.json, and filters for shell/hooks/code execution flags to prioritize review.

Claude CodeCursorGitHub Copilot+3
Miasma worms1ngularityCline v2.3.0 compromise

Supply Chain, AI Security· Published and added 8 Oct 2026

arxiv.orgpaper🧠 AI

Autonomous Code Migration for Quantum Programming Languages: A Case Study with QED-C Benchmarks

Case study in which Opus, GPT and Gemini coding agents port thirteen QED-C Application-Oriented Benchmark methods from Qiskit to CUDA-Q. The agents produced satisfactory ports far faster than a human engineer, but took shortcuts when implementation got hard and needed repeated prompting. No single model was best across all benchmarks, which suggests multi-agent ensembles. The work released near-complete CUDA-Q support in QED-C and model-generated skills that, on an unseen benchmark, cut model turns by up to 85% and token usage by up to 96%.

CUDA-QQiskitCUDA
QED-COpusGPT+2

coding-agents, research, prompting· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🧠 AI

Who Verifies the Verifier? Co-Evolving Inspectable Graders with Self-Improving Agents

Proposes making the verifier the evolving object in self-improving agent loops. The verifier is an inspectable expression over small, mostly deterministic drawback detectors, synthesized from clustered failures, gated at birth, and selected for agreement with a ten-item anchored reference set plus consensus over unlabeled outputs, never for the agent's score. On MBPP+ it gains +0.21 held-out agreement over the hand-authored seed and ends ahead of the bare LLM judge it contains. Removing the anchor guards collapses the verifier into an always-pass grader that still trains skills as well, so downstream task score cannot certify a self-evolved verifier. The paper's Double Ratchet pairs the verifier with a lifecycle-managed skill loop and retains 88-110% of the lift from ground truth or a rubric on code generation, enterprise text-to-SQL and reference-free report generation.

MBPP+

research, evals, agents· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🧠 AI

Skill Constellations: Tracing the Supply Chain of Agent Skills on GitHub

The paper builds the first dated copy network of agent skills (SKILL.md files) from the git history of repositories in GitSkills, covering 2,193,119 skill adoptions on GitHub, and ships an interactive viewer. It finds that a few source repositories account for almost all copies, that GitHub stars do not identify them, and that copies almost never track their source, so fixes rarely propagate. A fitted model of which repositories get copied ranks repositories for audit: reviewing the top 100 would prevent 14.9% of later adoptions of high-risk skills, against 0.5% for the 100 most-starred. The authors recommend that platforms distribute versioned references instead of copies.

Claude CodeCodexGitHub+1
GitSkills

coding-agents, prompting, research· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🛡️ Security

Skill Constellations: Tracing the Supply Chain of Agent Skills on GitHub

Builds the first dated copy network of agent skills (SKILL.md files) from git history in the GitSkills dataset, covering 2,193,119 skill adoptions on GitHub, plus an interactive viewer. Finds a few repositories are the source of nearly all copies, stars do not identify them, and copies almost never track their source, so upstream fixes rarely propagate. A model of which repositories get copied ranks repos for audit: reviewing the top 100 prevents 14.9% of later adoptions of high-risk skills versus 0.5% for the 100 most starred. The authors recommend platforms distribute versioned references rather than copies.

Claude CodeCodexGitHub+1
GitSkillsSKILL.md

Supply Chain, AI Security· Added 9 Oct 2026, published 8 Oct 2026

arxiv.orgpaper🧠 AI

From Digital Human Interactions to Physics-Based Humanoid Skills: Physics-Grounded Post-Training of Interaction Generators

The paper introduces DIGHT, a co-adaptive framework that couples a text-conditioned digital-human interaction generator with a physics-based humanoid tracking policy to produce physically plausible two-humanoid interactions. Rather than collapsing executability and interaction-fidelity signals into one scalar reward, it applies physics-decoupled diffusion Direct Preference Optimization (DPO) to align the generator using criterion-specific preferences derived from tracking error, friction, floating, and simulator force feedback (contact occurrence, location, duration, magnitude), then uses the aligned generator's outputs to fine-tune the tracker. Experiments show improved physical plausibility and more reliable, faithful simulated humanoid interactions compared to prior tracking-based approaches.

diffusion modelDirect Preference Optimization
DIGHT

research, training· Added 8 Oct 2026, published 7 Oct 2026

huggingface.coarticle🧠 AI

One Model Family, Two Gold-Level Results: Fine-Tuning Nemotron for IOI and IMO

NVIDIA describes how it specialized Nemotron 3 base models into domain experts for competitive programming (IOI) and olympiad mathematics (IMO) using a four-step recipe: strong base model, curated domain data with reasoning traces, SFT/RL post-training, and an inference loop (GenCorrect for IOI, generate-verify-refine for IMO) that searches and refines candidate answers. Nemotron-3-Nano-CC and Nemotron-3-Ultra-CC reached gold-level IOI 2026 scores (535.4/600), while SFT and RL checkpoints of Nemotron 3 Ultra combined to score 30/42 on IMO 2026, exceeding the gold threshold with no formal prover or external tools. The post releases training datasets, checkpoints, the Nemotron-IMO-Bench benchmark, and the NeMo-Skills inference pipelines on Hugging Face.

Hugging FaceMixture of Experts
NemotronNemotron 3Nemotron-3-Nano-CC+11

training, evals, models· Published and added 7 Oct 2026

arxiv.orgpaper🛡️ Security

Surviving the Router: Optimizing Skill Injections for Retrieval and Execution

This paper studies prompt-injection attacks against AI agent "skill" marketplaces where a router dynamically selects which third-party skill to execute. The authors show existing injection attacks lose 87-97% of their effective attack success rate once a skill must first win retrieval against competing skills, and introduce CORSA (Cluster Optimization for Router-Aware Skill Attacks), which jointly optimizes injections for retrieval and execution, improving end-to-end attack success while preserving user utility and transferring across different router architectures and LLM backbones.

LLM
CORSASkillRouter

AI Security· Added 7 Oct 2026, published 6 Oct 2026

arxiv.orgpaper🛡️ Security

Under the Hood of SKILL.md: Semantic Supply-chain Attacks on AI Agent Skill Registry

This arXiv paper studies SKILL.md files — the natural-language metadata describing modular AI Agent Skills — as an attack surface, demonstrating semantic supply-chain attacks against real ClawHub skills. Using text-only manipulations, the authors manipulate embedding-based Discovery retrieval (up to 86% pairwise win rate, 80% Top-10 placement), bias agent Selection toward adversarial variants (77.6% average success), and evade Governance blocking verdicts (36.5%-100% evasion), showing that skill metadata is operational text that shapes agent trust rather than passive documentation.

ClawHub

AI Security, Supply Chain· Added 5 Oct 2026

x.comthread🧠 AI

Rajashekar Sudireddy (@raja_sudireddy) on X

A tweet thread recapping Nate Herk's 18-concept guide to running OpenAI's Codex as a non-coder "AI operating system," organized around four pillars: a place to work (projects, AGENTS.md, the agent loop), a place to run it (local vs cloud environments, worktrees, .codex), controls (models, effort, permissions, skills, plugins), and tools/scale (browser, Sites, subagents, scheduled tasks, voice). It highlights AGENTS.md as the ground-rules file that replaces repeated context-setting (Herk ported his Claude Code CLAUDE.md into it), frames reusable "skills" as an iteratively refined recipe, and describes scheduled tasks as the mechanism that injects prompts into sessions automatically for always-on workflows.

CodexClaude Code

coding-agents, prompting· Published and added 4 Oct 2026

developers.openai.comarticle🧠 AI

Rethinking skills and prompts for GPT-6 Astra

OpenAI guidance for Codex users on adapting instructions, skills, AGENTS.md, and task prompts, now that GPT-6 Astra is more capable than prior models like GPT-5.6 Sol and GPT-6 Luna. It covers writing shorter, non-contradictory skill descriptions, using progressive disclosure (a minimal router skill pointing to supporting docs and scripts rather than loading everything into context), trimming over-eager AGENTS.md instructions such as forced doc-reading and excessive test-running reminders, recalibrating decision-boundary language since Astra is more cautious by default, and explicitly defining completion so the model does not stop after a first implementation when more work is expected.

Codex
OpenAIGPT-6 AstraGPT-5.6 Sol+1

coding-agents, prompting· Added 3 Oct 2026

x.comthread🛡️ Security

Jan Curn (@jancurn) on X

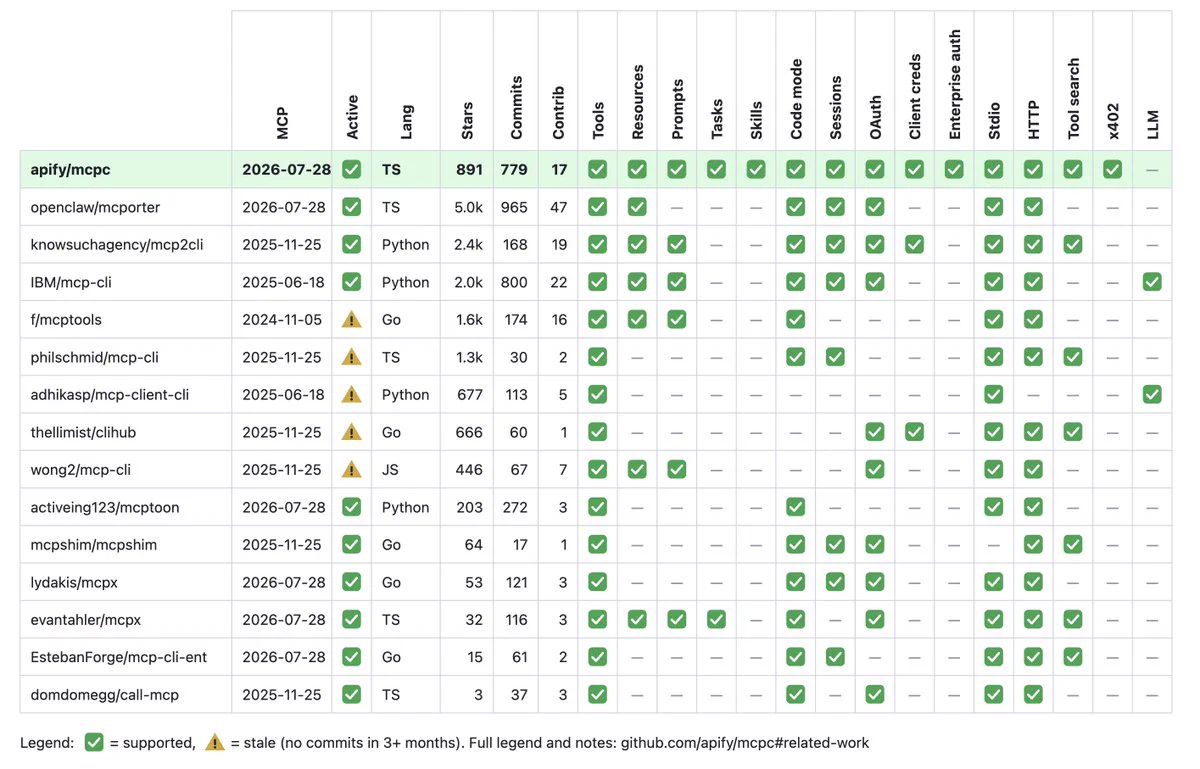
Announcement of mcpc v0.7.0, Apify's open-source MCP CLI client (npm i -g @apify/mcpc), which adds support for the MCP Skills extension with new skills-list/skills-get commands that verify SKILL.md and supporting files against the skill manifest via size and SHA-256 checks before printing content. The release also ships security hardening: repo-local .mcp.json auto-discovery can no longer read environment variables (blocking leaks like $GITHUB_TOKEN), OAuth refresh tokens are now scoped only to the auth server originally used, and Windows login URLs no longer launch through cmd.exe.

Model Context ProtocolOAuthnpm

AI Security, Identity & Access· Added 5 Oct 2026, published 3 Oct 2026

x.comthread🧠 AI

Jan Curn (@jancurn) on X

Jan Curn announces mcpc v0.7.0, an open-source MCP CLI client (npm package @apify/mcpc), adding support for the MCP Skills extension via new skills-list and skills-get commands that fetch and cryptographically verify SKILL.md and supporting files against the skill manifest (size + SHA-256). The release also hardens security by preventing repo-local .mcp.json auto-discovery from reading environment variables (blocking token-leak tricks), scoping refresh tokens to the originating auth server, and fixing an insecure Windows login URL launch path via cmd.exe, alongside OAuth session longevity fixes and 2026-07-28 MCP spec compatibility improvements.

Model Context ProtocolNode.jsOAuth
Jan CurnApifymcpc

mcp· Added 5 Oct 2026, published 3 Oct 2026

github.comrepo🧠 AI

Jakeschincariol/replica-skill

replica-skill is an MIT-licensed set of eleven Claude skills that run an app-cloning pipeline: recon, architect, design, build, backend, test, diff, entrepreneur, brand, launch and deploy. Six standard-library Python tools handle image diffing, parity scoring, review ranking, contrast checks, rebrand sweeps and store-listing lint. It installs as a Claude Code plugin or by copying folders, and states clean-room and rebranding limits.

Claude CodeClaudePython+5
Jake SchincariolAnthropic

coding-agents, prompting· Added 29 Oct 2026, published 3 Oct 2026

x.comthread🧠 AI

Brendan Jowett (@jowettbrendan) on X

A curated Twitter/X thread listing ten GitHub repos that extend Claude Code and Codex workflows: spec-forcing planning/testing skills (obra/superpowers, mattpocock's skills with grill-me/diagnose/handoff), session memory compression (thedotmack's claude-mem-style tool), codebase-to-graph querying (safishamsi/graphify), a spec-driven long-task workflow (gsd-build), scope-reduction and anti-fluff skills, a cross-tool harness spanning Claude Code/Codex/OpenCode/Cursor (affaan-m/ECC), a multi-role agent team setup (garrytan/gstack), and a local model-routing gateway (musistudio's claude-code-router). Each entry is a practical, installable tool aimed at making coding agents more disciplined, memory-aware, and cost-efficient.

Claude CodeCodexCursor+1
Garry Tan

coding-agents, agents· Published and added 3 Oct 2026

openai.comarticle🧠 AI

A model guide for the GPT-6 family

OpenAI's practical guide to the GPT-6 family (Astra, 6.1 Sol, Luna), with per-token pricing and when to use each model. It gives guidance on picking a reasoning level (low to max), Fast and Ultrafast speed modes, and rewriting skills, AGENTS.md and prompts with clear decision boundaries and a definition of "done". For long-running agent work it covers mid-turn steering over the Responses WebSocket API, async tool calling, multi-agent delegation (beta) and computer use with Playwright or PyAutoGUI. It also gives production advice on prompt caching, compaction, monitoring and measuring cost per successful task.

OpenAI APICodexResponses API+3
OpenAIGPT-6 AstraGPT-6.1 Sol+1

prompting, agents, ai-infra· Published and added 2 Oct 2026

arxiv.orgpaper🧠 AI

MobiAgent: Dual-Loop Recursive Policy Self-Improvement for Long-Horizon Mobile Manipulation

MobiAgent is a dual-loop agentic framework for long-horizon mobile manipulation that separates deployment execution from policy self-improvement. An Inner Loop uses vision-language models for receding-horizon planning and visual reflection to compose atomic skills executed by flow-matching experts sharing a unified VLM backbone, while an Outer Loop autonomously segments, verifies, and clusters deployment rollouts to discover new atomic skills and continuously fine-tune the skill library without human annotation. On BEHAVIOR-1K it beats pi_0.5-TA by 22.5 percentage points, and autonomous data recycling raises RoboCasa success from 7.50% to 27.50% and Astribot S1 success from 32.5% to 57.5%.

vision-language modelflow matching
RoboCasaBEHAVIOR-1KAstribot S1+1

research, multimodal· Added 5 Oct 2026, published 2 Oct 2026

arxiv.orgpaper🧠 AI

AREX-2: Advancing Self-Improving Agents through Long-Horizon Reflective Tasks

AREX-2 trains an LLM agent, built on Qwen3.8-27B, to self-improve at test time by iteratively refining solutions. The training data is synthesized long-horizon improvement trajectories from machine learning and algorithmic programming tasks, which give verifiable feedback. It reports 81.8 on MLE-bench Lite and 70.7 on Frontier-CS, and transfer to deep research with 84.0 on BrowseComp, 52.6 on HLE, 92.2 on GAIA and 93.8 on DeepSearchQA. Performance keeps improving as the budget of rounds grows. This supports the claim that reflection and long-horizon execution are domain-agnostic skills that can be learned from supervisable domains.

Qwen3.8-27B
AREX-2MLE-bench LiteFrontier-CS+5

research, agents, training· Added 1 Oct 2026

github.comrepo🧠 AI

OpenShell — safe, private runtime for autonomous AI agent fleets

OpenShell is NVIDIA's open-source runtime for running fleets of autonomous AI agents inside isolated sandboxes. Declarative policies cover filesystem, syscall, process and network access. These are enforced at the kernel level, and credentials are injected only into requests bound for approved endpoints. Policy changes are checked with formal verification so risky new access waits for human review. It ships a CLI, a gateway control plane (Helm deployment on Kubernetes), SDKs, extensibility hooks (middleware, interceptors, compute drivers) and installable agent skills, and it can run agents such as OpenCode.

OpenShellDockerPodman+5
NVIDIA

agents, ai-infra· Added 1 Oct 2026

x.comthread🧠 AI

Amada Echeverría (@amadaecheverria) on X

Jes is an open-source real-time guardrails library for AI agents built by LangChain Ambassador Eden Marco, designed to check every step of an agent's trajectory: prompts, tool calls, tool results, skills, and final responses. It runs as LangChain middleware and uses decision models like Jev from TypeSafe AI via a TypeSafeClassifier to make pass or fail calls at each checkpoint, with docs showing a concrete middleware integration example.

LangChainTypeSafeClassifier
JesEden MarcoTypeSafe AI+1

agents, ai-infra· Added 3 Oct 2026, published 1 Oct 2026

x.comtool🛡️ Security

Amada Echeverría (@amadaecheverria) on X

jes is an open-source real-time guardrails project for AI agents, built by LangChain Ambassador Eden Marco, that inspects every step of an agent's trajectory — prompts, tool calls, tool results, skills, and responses. It runs on decision models like Jev from TypeSafeAI and ships with a LangChain middleware example for wiring the checks into an agent pipeline.

LangChainjesJev
Eden MarcoTypeSafeAI

AI Security· Added 3 Oct 2026, published 1 Oct 2026

github.comrepo🧠 AI

rehan-remade/universal-modder

universal-modder is a set of Agent Skills, a CLI (um) and a shared knowledge base (field notes in knowledge/) that let AI coding agents such as Claude Code, Codex, Gemini CLI, Cursor, GitHub Copilot and OpenCode find a PC game's engine, reverse-engineer its code, build a working mod, generate art/3D/sound assets via the fal MCP server (or a local ComfyUI server), test the mod in the running game, and write a field note for the next agent. It ships worked examples — a weapon/boss pack for Terraria via tModLoader, a new civilization for Age of Empires II DE, and a real-time Minecraft-inside-GTA-V passthrough mod — each documented with a field note of exact versions, routes and gotchas, and agents can open pull requests to grow the shared knowledge base.

Model Context ProtocolClaude CodeCodex+11
falElevenLabsTerraria+19

coding-agents, mcp· Added 6 Oct 2026, published 30 Sep 2026

github.comrepo🧠 AI

NVIDIA OpenShell — secure runtime for autonomous AI agent fleets

OpenShell is NVIDIA's open-source runtime for running fleets of autonomous AI agents with restricted, policy-governed access to files, system calls, network, and credentials. It enforces policy at the kernel level inside isolated sandboxes (per-agent, with Docker/Podman/virtualization backends) and uses formal verification to flag risky policy changes — such as an agent gaining a new host or API access with credentials — before they take effect, so changes can wait for human review. It ships a CLI, a gateway control plane, Kubernetes/Helm deployment, and installable agent skills for writing and debugging sandbox policies.

DockerOpenCodeOpenRouter
NVIDIAOpenShell

ai-infra, agents· Added 29 Sep 2026

arxiv.orgpaper🧠 AI

Skill-Space Shooting for Autonomous Robot Policy Improvement

This arXiv preprint introduces "skill-space shooting," a method that uses foundation model guidance to search over reusable short behaviors (skills) to generate corrective actions for a robot policy, turning successful trials into training data for policy improvement without human demonstrations. Real-world robot experiments show the approach enables repeated autonomous policy improvement and that learned skills can be shared across tasks to reduce the teaching effort needed on new tasks.

research· Added 30 Sep 2026, published 29 Sep 2026

github.comrepo🛡️ Security

Adversarial-Detection-Engineering/adeskills

adeskills is a working knowledge base for "Adversarial Detection Engineering" (ADE), a taxonomy of four categories and 16 subcategories of detection-logic bugs (e.g. Reformatting in Actions, Omit Alternatives, Context Development, Logic Manipulation) that explain why a SIEM/EDR/XDR rule fails to catch what it intends to. It ships 38 worked technique files with vulnerable/hardened rule examples and detection-layer guidance, a cross-platform bug-pattern catalog, a pre-engagement scoping checklist, and a Redamon-packaged skill (ade_scoper), all grounded in analysis of real public rulesets from Sigma, Elastic Security, and Microsoft Sentinel. It's explicitly scoped for defensive detection engineering and purple-team rule hardening, with several files documenting real vendor-rule weaknesses.

SigmaMicrosoft SentinelElastic Security+3
Nikolas BielskiDaniel Koifman

Blue Team & Detection· Added 2 Oct 2026, published 27 Sep 2026

github.comrepo🧠 AI

zhuyansen/awesome-claude-video-skills

Awesome-list repository cataloguing 183 open-source 'skills' and toolkits that let Claude Code, Codex and other coding agents generate or edit video: rendering frameworks like HyperFrames and Remotion, motion graphics, explainer/promo video generators, short-form editors, digital avatars and music videos. Each entry is read and security-graded by a companion service (Agent Skills Hub / agentskillshub.top), with a machine-readable JSON feed and category breakdowns (frameworks, promos, explainers, editing, shorts, avatars, animation, motion graphics, scripts, music videos).

Claude CodeCodexModel Context Protocol+10
Claude Opus 5.5

coding-agents, multimodal· Added 29 Sep 2026, published 27 Sep 2026

arxiv.orgpaper🧠 AI

Progressive Skill Discovery as Access Control for Tool-Using LLM Agents

Introduces "skilder," a framework that bundles LLM agent capabilities into roles (skills, tools, instructions, and limits) delivered progressively through a single MCP server, so an agent starts with a minimal catalog and only gains tool access as it learns the roles a task requires. This structural approach enforces access control deterministically at the server layer rather than relying on prompt-based policy, addressing context bloat and governance gaps in enterprise tool-using agents. Evaluated against flat-context tool selection and multi-agent orchestration across 13 tasks and six models, showing zero unauthorized tool calls or parameter violations when agents completed the discovery protocol.

Model Context Protocol
skilder

agents, research, mcp· Added 26 Sep 2026

arxiv.orgpaper🧠 AI

The Regression Tax: Decomposing Why Skills Help and Hurt LLM Agents

This arXiv paper studies why adding procedural "skills" to LLM agents can hurt as well as help performance, running nearly 6,000 evaluation runs across two office automation benchmarks and three model harness stacks. It distinguishes "regressions" (tasks solved without skills but failed after adding them) from "residual failures," and identifies three regression causes: skill description osmosis, grounding displacement, and verification displacement. The authors argue procedural skills are overemphasized relative to grounding and verification, and that skill evaluation should decompose net effect into gains vs. regressions rather than reporting aggregate improvement alone.

prompting, evals, research· Added 26 Sep 2026

thehackernews.comarticle🛡️ Security

FakeGit Campaign Uses 7,600 GitHub Repositories to Spread SmartLoader Malware

Researchers at Island identified nearly 7,600 malicious GitHub repositories (from ~6,600 fake profiles) making up the "FakeGit" campaign, with over 800 posing as AI Skills or MCP servers (for Gmail, WhatsApp, Databricks, Jenkins, Docker, etc.) to distribute SmartLoader via malicious ZIP files that trigger a LuaJIT loader chain, ultimately deploying the StealC infostealer. The campaign has racked up over 14 million downloads across ~200 repos and 600+ listings on registries like LobeHub, Glama, MCP.so, and MCP Market. The report also introduces "AgentBaiting," a technique where AI agents (Claude Code, Gemini, ChatGPT were shown to be susceptible) autonomously discover and surface these malicious repos while searching for skills/MCP servers on a user's behalf, without ever being given a link.

Model Context ProtocolGitHubClaude Code+3
FakeGitSmartLoaderStealC+9

Threat Intel, AI Security, Supply Chain· Added 26 Sep 2026

arxiv.orgpaper🛡️ Security

RedEvoAgent: Automatic Red-Teaming Agent with Experience-Driven Skill Evolution

RedEvoAgent is a black-box automatic red-teaming agent that distills successful jailbreak trajectories into concise, human-readable 'attack skills' rather than retrieving full past trajectories. It evolves these skills via tool-effectiveness profiling and a validation ratchet that only keeps updates improving attack success, and is shown to outperform fixed and agentic jailbreak baselines while transferring across attacker models and target execution harnesses (product-level agent environments where jailbreaks trigger real tool use, not just unsafe text).

LLM

AI Security· Added 26 Sep 2026

arxiv.orgpaper🧠 AI

New LoRA Skills Should Read but Never Write

This paper introduces READ (Read-only Expansion of Adapter Deltas), a method for composing multiple independently trained LoRA adapters into a single model without the weight-space interference that plagues naive merging. READ rewrites each adapter into a balanced canonical factorization and adds a one-directional coupling so new skills can read old adapters' input subspaces but never write into their output subspaces, requiring only a small trainable coupling row per new skill and folding cleanly into base weights with no inference-time routing cost. Evaluated across four benchmark suites and two model families, READ outperforms the strongest published composition baselines by over 20 points on SuperGLUE and over 7 points on a domain suite when adding skills sequentially.

LoRA
SuperGLUE

training, research· Added 28 Sep 2026, published 25 Sep 2026

github.comrepo🧠 AI

Claude Code Templates Repository

Claude Code Templates (aitmpl.com) is an open-source npx CLI and template catalog offering 100+ ready-to-use agents, slash commands, hooks, settings, skills and MCP server integrations for Anthropic's Claude Code, aggregating contributions from Anthropic's official skills repo, K-Dense-AI's scientific skills, and various community projects (superpowers, wshobson/agents, awesome-claude-code, etc.). Beyond the template catalog it ships real-time analytics for monitoring Claude Code sessions, a mobile chat viewer with Cloudflare Tunnel support, a health-check diagnostic, and a plugin/marketplace manager, making it a practical operational toolkit for customizing and running Claude Code.

Claude CodeModel Context ProtocolNode.js+3
AnthropicK-Dense Inc.Jesse Obra+3

coding-agents· Added 2 Oct 2026, published 25 Sep 2026

github.comrepo🧠 AI

https://github.com/davila7/claude-code-templates/tree/main/cli-tool/components/skills/security/security-threat-model

A directory within the davila7/claude-code-templates repo containing a "security-threat-model" Skill for Claude Code: a SKILL.md instruction file plus supporting agents and reference files that package a reusable threat-modeling workflow for the coding agent. It's an example of the emerging pattern of distributing structured, invocable skills (instructions + sub-agents + reference docs) that extend Claude Code's capabilities, rather than a security research artifact itself.

Claude Code
GitHub

coding-agents, prompting· Added 2 Oct 2026, published 25 Sep 2026

github.comrepo🛡️ Security

https://github.com/davila7/claude-code-templates/tree/main/cli-tool/components/skills/security/security-threat-model

A "security-threat-model" skill folder in the davila7/claude-code-templates repository, part of a library of reusable Claude Code skills/components. It packages a SKILL.md definition with supporting agent and reference files intended to let Claude Code agents carry out structured threat-modeling analysis as part of a development or security-review workflow.

Claude Code

AI Security, AppSec· Added 2 Oct 2026, published 25 Sep 2026

github.comrepo🧠 AI

nealbridges/VulnHunter

VulnHunter is a maintained fork of Capital One's open-source agentic security scanner, reworked to run on any agent harness (Claude Code, Codex, Grok/OpenCode) instead of being Claude-Code-specific. The fork's distinguishing work is engineering, not security findings: portable "skill" prompt files with an explicit environment contract, an installer that fails loudly instead of guessing paths, Docker-based sandboxed exploit validation, and a benchmark harness that ran six full scans of one production Go service across five model/harness stacks, finding that result counts swung from 3 to 42 findings depending on how rigorously exploits were validated. It ships three composable skills (/vulnhunt, /vulnhunter-fix, /vulnhunt-fix-verify), a headless batch-runner (harness/), and a deterministic manifest-writing CLI (vh).

Claude CodeCodexGrok+4
VulnHunterCapital OneOWASP NodeGoat+2

coding-agents, evals· Added 6 Oct 2026, published 22 Sep 2026

github.comrepo🛡️ Security

SnailSploit/Claude-Red

claude-red is a GitHub library of structured SKILL.md files for the Claude Skills system, each priming Claude with expert-level offensive-security methodology for a specific attack surface (SQL injection, shellcode, EDR evasion, ADCS abuse, wireless, IoT, cloud, mobile, fuzzing, etc.). Skills load on-demand from conversational triggers so context isn't spent on unused domains, and can be installed wholesale, per-category via sparse-checkout, or pasted directly into a system prompt. It's aimed at authorized red-team engagements, bug bounty triage, CTF prep, and operator training, building on Sahar Shlichov's offensive checklist collections.

ClaudeClaude CodeActive Directory
Kai AizenSnailSploitSahar Shlichov

Offensive Security, AI Security· Added 21 Sep 2026

github.comrepo🛡️ Security

Outrider Recon

Outrider Recon is an open-source, Claude-native multi-agent OSINT and external attack-surface recon platform for authorized engagements, covering web/API, identity/SSO, cloud, secrets, and people/breach intelligence. It deliberately stops short of exploitation: active enumeration is approval-gated and intrusive validation is a human hand-off, with deterministic Python controls enforcing scope, evidence integrity, workflow state, and finding promotion around Claude skills and optional MCP-based enrichment. Output is ranked, evidence-backed finding cards (confidence/severity/handoff recommendations) meant to feed proxy-assisted testing or pen-testing rather than raw scanner dumps.

ClaudeClaude CodeModel Context Protocol+2
elementalsouls/Claude-OSINTSnailSploit/offensive-checklist

OSINT, Offensive Security, AI Security· Added 22 Sep 2026, published 19 Sep 2026

github.comrepo🧠 AI

kerpopule/hermes-jev-skills

hermes-jev-skills wires TypeSafe's small, fast decision model "Jev" into agent workflows (Hermes, Claude Code, Codex) to handle cheap sub-decisions — which model should answer a turn, which of many skills to load, which retrieved passages matter, which conversation turns survive a summary — instead of burning frontier-model tokens on them. It ships ten agent-agnostic SKILL.md files, a CLI (jev routing/mail/screen/search), a local dashboard, and a plugin built on public Hermes seams (pre_llm_call, transform_tool_result, llm_request middleware) with detailed data-redaction guarantees for what gets sent to the Jev API. It also includes a shadow mode for safely evaluating routing decisions before enabling them.

Claude CodeCodexPython+4
JevTypeSafeHermes+2

coding-agents, agents, ai-infra, mcp· Added 26 Sep 2026, published 18 Sep 2026

arxiv.orgpaper🧠 AI

Designer-RSI: Evolving Procedural Memory from User Traffic for Agentic Graphic Design

Designer-RSI is a continual adaptation framework where a frozen frontier model (Claude-Sonnet-4/Claude-Opus-4.6) operates professional graphic design software through 230+ tools, guided by an external natural-language procedural memory that widens (learns new skills for uncovered subtasks) and deepens (revises existing skills against successes/failures) using a replay gate that only admits changes improving on past failures without regressing successes. Over five rounds on 1,406 real user briefs and 1,869 graded trajectories, the skill bank grew from 76 to 139 procedures, raising GenEval2 execution success from 72.7% to 99.3% and achieving 58%+ win rates against a no-skill baseline, demonstrating a practical route to agent self-improvement under noisy, unverifiable feedback and no human labels.

Claude
Claude-Sonnet-4Claude-Opus-4.6GenEval2

agents, research· Added 22 Sep 2026, published 18 Sep 2026

github.comrepo🧠 AI

Tongyi-MAI/Qwen-Planner-Agent

Qwen-Planner-Agent is Alibaba's Tongyi MAI Team framework pairing a trained Planner Model with a stateful Harness to execute mobile tasks end-to-end, coordinating tools, persistent memory, reusable Skills, and sub-agents. It introduces Competence-Adaptive Reward-and-Advantage Engineering (CARE), a hybrid supervised+RL training approach, and reports the 27B model reaching 77.05% Overall on MobilePA-Bench at an estimated $2.41 per 1,000 tasks in output-token cost. This repo hosts the technical report/blog and recorded interactive examples rather than model weights or code.

Qwen-Planner-AgentTongyi MAI TeamAlibaba Group+2

agents, training· Added 26 Sep 2026, published 18 Sep 2026

github.comrepo🛡️ Security

OWASP Agentic Skills Top 10 (AST10)

The OWASP Agentic Skills Top 10 (AST10) is a new security framework cataloging the 10 most critical risks in AI agent "skills" — the behavior layer that orchestrates multi-step tool use in OpenClaw, Claude Code, Cursor/Codex, and VS Code. It documents real 2026 incidents (the ClawHavoc registry-poisoning campaign with 1,184 malicious skills, Snyk's ToxicSkills audit of 3,984 skills finding 36.82% flawed, CVE-2025-59536/CVE-2026-21852 RCE in Claude Code project files, and CVE-2026-28363 ClawJacked WebSocket hijacking) and proposes a Universal Skill Format (YAML) with signing, permission allowlists, and identity-file protections to mitigate them, mapped to CSA's MAESTRO 7-layer threat model.

OpenClawClaude CodeCursor+3
CVE-2025-59536CVE-2026-21852CVE-2026-28363+17

AI Security· Added 18 Sep 2026

github.comrepo🧠 AI

MichaelKinsy/PiG

PiG reimplements Pi — a minimal, extensible terminal coding agent — as a single native Go binary with no Node.js dependency, while remaining behaviorally pinned to a specific Pi release (0.87.1) and running Pi's TypeScript extensions unchanged. It adds a multi-language extension host (Go, Rust, Python, Node), a "Piglet" mechanism for bundling extensions/skills/prompts into a named shareable agent, and a formal parity-tracking process (PORT_MAP.md, DIVERGENCES.md, coverage reports) that documents every intentional divergence from the upstream Pi reference implementation.

GoNode.jsPython+2
PiMichael KinsyHewlett Packard Enterprise

coding-agents· Added 27 Sep 2026, published 17 Sep 2026

github.comrepo🧠 AI

leepokai/jev-guard

jev-guard is an MIT-licensed hook layer that adds an auto mode to Claude Code, Codex, Copilot CLI, Gemini CLI, Cursor, pi, OpenCode, Antigravity and ACP editors. It asks the Jev model three typed questions (risk, user_requested, from_untrusted) per tool call and decides deny, ask or allow in about 20 lines of code. It also scans tool results for prompt injection and checks skills and plugins.

Claude CodeCodexGitHub Copilot+9
JevTypeSafeVercel

coding-agents, agents, ai-infra· Added 27 Oct 2026, published 17 Sep 2026

github.comtool🛡️ Security

leepokai/jev-guard

jev-guard is an MIT-licensed hook layer that adds an auto mode to coding agents (Claude Code, Codex, Copilot CLI, Gemini CLI, Cursor, pi, OpenCode, ACP editors). It asks the Jev model typed questions (risk, user_requested, from_untrusted) to deny, ask or allow each tool call, using per-session memory. It also flags prompt injection in tool results and scans skills, plugins and CLAUDE.md files. It is a guardrail, not a sandbox, and fails open by default.

Claude CodeCodexGitHub Copilot CLI+3
prompt injectionindirect prompt injectionJev+2

AI Security· Added 27 Oct 2026, published 17 Sep 2026

github.comrepo🧠 AI

Dicklesworthstone/skillranker

SkillRanker (sr) is a standalone Rust CLI that ranks which skill an agent should load next, combining local context/roster signals with TypeSafe.ai's Jev model for evaluation and FrankenSearch's Quill BM25 engine for local candidate prefiltering when a skill library exceeds 254 entries. It integrates with Claude Code and Codex via hooks, offers dry-run/explain/replay/eval workflows for inspecting and reproducing ranking decisions, and is explicitly advisory only — it never executes skills or overrides agent instructions.

RustClaude CodeCodex
JevTypeSafe.aiQuill+1

coding-agents, prompting· Added 26 Sep 2026, published 17 Sep 2026

owasp.orgother🛡️ Security

OWASP Agentic Skills Top 10 (AST10)

The OWASP Agentic Skills Top 10 (AST10) is a new OWASP project cataloging the 10 most critical security risks in AI agent "skills" — the layer that defines how agents orchestrate multi-step, autonomous workflows across platforms, as opposed to how models talk to tools via MCP. Each risk is mapped to the Cloud Security Alliance's MAESTRO 7-layer threat model for agentic AI systems, aiming to close a gap left by existing LLM- and MCP-focused security guidance.

Model Context Protocol
OWASP Agentic Skills Top 10 (AST10)MAESTROCloud Security Alliance

AI Security· Added 16 Sep 2026

latent.spacearticle🧠 AI

Can Skills Learned in Games Transfer to Real-World Work?

Interview with Good Start Labs co-founder Alex Duffy on training LLMs inside games like Diplomacy and 1830: The Game of Railroads and Robber Barons as reinforcement-learning environments with verifiable rewards. The company found that a multi-turn terminal-agent harness playing 1830 improved performance on the Finance-Agent benchmark, while single-turn Q&A training did not, suggesting that harness design — not just the game itself — determines whether in-game skills transfer to real-world agentic tasks like financial research and customer support.

Reinforcement Learning
Good Start LabsAlex DuffyTyler Marques+13

training, agents· Added 29 Sep 2026, published 15 Sep 2026

blog.trailofbits.comwriteup🧠 AI

1Password's AI patching benchmark is misleading

Trail of Bits dissects 1Password's August 2026 report claiming AI models produce "clean" security patches only 26% of the time, showing the figure is inflated by handpicked hard bugs, deliberately wrong-fix prompts (22% of trials), testing-prohibited trials (36%), inconsistent grading, and a buggy reference fix — and that when those confounds are removed, 86% of patches blocked the supplied exploit. The post contrasts this with Trail of Bits' own data: developers get 12.5% of first fixes wrong even under favorable conditions, and 67.7% of Patch the Planet AI-authored pull requests were merged by maintainers. It also releases two agent skills, post-patch-validation and review-walkthrough, to help agents test fixes and help engineers review AI-generated patches.

GitHub
1PasswordTrail of BitsPatch the Planet+4

evals, coding-agents· Added 8 Oct 2026, published 15 Sep 2026

blog.trailofbits.comarticle🛡️ Security

1Password's AI patching benchmark is misleading

Trail of Bits dissects 1Password's August 2026 report claiming AI agents (GPT-5.5, Opus 4.8) produce clean vulnerability fixes only 26% of the time, showing the figure is inflated by a hand-picked set of six hard bugs, deliberately-wrong-fix prompts (22% of trials), a no-testing mode (36% of trials), grading disagreements between automated graders and humans, and a buggy Linux upstream reference fix. Reanalyzing the same data under fair conditions (testable, non-adversarial trials) they find 86% of patches blocked the supplied exploit, and they contrast this with their own consulting data (12.5% of developer first-fixes fail) and Patch the Planet's 67.7% maintainer merge rate across 186 PRs, including a case where both a human maintainer and an agent independently introduced the same freenginx cleanup-crash regression. The post also releases two new agent skills, post-patch-validation and review-walkthrough, to improve AI-assisted patch testing and human review.

1PasswordGPT-5.5Opus 4.8+1
Patch the PlanetTrail of BitsDavi Ottenheimer+3

AI Security, AppSec· Published and added 15 Sep 2026

github.comrepo🛡️ Security

Cloudflare security-audit-skill

security-audit-skill is a Cloudflare open-source coding-agent skill that turns an AI coding agent into a structured vulnerability hunter, running six phases: reconnaissance into architecture.md/coverage-ledger.json, coverage-led hunting by isolated sub-agent "hunters," adversarial candidate validation, structured findings.json output validated against a report-schema.json, independent re-verification of claims, and target-neutral report generation (REPORT.md, FINDINGS-DETAIL.md, NEEDS-VALIDATION.md). It is installed via the Skills CLI (`npx skills add`), uses Node.js validators (validate-coverage-ledger.cjs, validate-findings.cjs), requires a sandboxed environment for safely executing target code/tests/fuzzers, and is the single-repo seed for Cloudflare's larger fleet-wide vulnerability discovery harness described in a companion blog post.

Claude CodeNode.jsCloudflare

AppSec, AI Security· Added 22 Sep 2026, published 15 Sep 2026

github.comrepo🛡️ Security

WordPress Security Skills

WordPress-Security-Skills is a GitHub repo of modular 'Agent Skills' (per the open Agent Skills spec) that install into AI coding agents like Claude Code, Cursor, Codex, OpenCode, and Gemini CLI to guide secure-by-default WordPress plugin/theme development and security code review. Each skill targets a documented failure mode in AI-generated WordPress code — missing nonce checks, broken authorization, missing output escaping, unprepared SQL queries — with when-to-use guidance, common AI mistakes (wrong vs right), code examples, and checklists tied to official WordPress API references. It is explicitly instructional Markdown/PHP reference material, not a scanner or automatic protection, meant for developers and reviewers auditing AI-written or third-party WordPress code.

WordPressPHPClaude Code+3
Agent Skills specification

AppSec· Added 22 Sep 2026, published 15 Sep 2026

owasp.github.iopaper🛡️ Security

OWASP Agentic Skills Top 10

OWASP's Agentic Skills Top 10 (AST10) catalogs the ten most critical security risks in the "skills" layer of AI agent platforms — OpenClaw's SKILL.md, Claude Code's skill.json, Cursor/Codex manifest.json, and VS Code package.json — arguing this behavior/orchestration layer is distinct from and less protected than the MCP tool layer. It documents real 2026 incidents (the ClawHavoc campaign poisoning 1,184+ ClawHub skills with AMOS-stealer payloads via a shared C2 IP, Snyk's ToxicSkills audit finding 36% of skills flawed, CVE-2025-59536/CVE-2026-21852 in Claude Code enabling RCE and API-key exfiltration on project open, and CVE-2026-28363 "ClawJacked" WebSocket hijacking of local OpenClaw instances), and proposes a Universal Skill Format with signing, permission manifests, and risk tiers plus a checklist for registries, runtime, governance, and skill development.

OpenClawClaude CodeCursor+3
CVE-2025-59536CVE-2026-21852CVE-2026-28363+8

AI Security, Supply Chain· Added 14 Sep 2026

github.comrepo🛡️ Security

pashov/skills

pashov/skills is a set of Claude Code "skills" built by Pashov Audit Group that turn an AI coding agent into a Solidity security auditor: an "x-ray" command for quick codebase reconnaissance, a "solidity auditor" mode that runs multiple different agent personas over a codebase (or specified files) looking for vulnerabilities, and a "fizz" command for additional automated checks. It packages smart-contract audit tradecraft into reusable AI agent skills rather than a standalone scanner, letting developers or auditors invoke deep, multi-pass Solidity review directly inside their coding assistant.

Claude CodeSolidityEthereum
Pashov Audit Group

AI Security, AppSec· Published and added 7 Sep 2026

github.comrepo🛡️ Security

trailofbits/skills

Trail of Bits maintains a Claude Code plugin marketplace of "skills" that extend AI coding agents (Claude Code, Codex, ChatGPT workspaces) with security analysis, testing, and secure development capabilities. It's installed via `/plugin marketplace add trailofbits/skills` and is also compatible with Codex's Claude marketplace support, with related sibling repos for curated skills, devcontainers, and config.

Claude CodeCodexChatGPT
Trail of Bits

AI Security· Published and added 7 Sep 2026

x.comthread🛡️ Security

Pyro (@0x3b33) on X

A roundup of three open-source AI-assisted smart contract security scanners: pashov/skills (solidity-auditor + x-ray pre-audit + fuzz suite generation, fast/cheap feedback), PlamenTSV's autonomous 8-phase agent covering EVM, Solana, and Move that ships PoCs with findings, and Trail of Bits' skills repo with 40+ security skills for contract audits, differential review, and static analysis. Useful pointer to emerging AI-agent-based smart contract auditing tooling.

SolidityEthereumSolana+1

AppSec, AI Security· Published and added 7 Sep 2026

github.comrepo🛡️ Security

0x4D31/endpoint-ai-agent-abuse

endpoint-ai-agent-abuse (EAA) is a curated, evidence-scoped taxonomy of techniques for abusing local, endpoint-resident AI agents — especially coding and developer agents — covering launchers/flags, provider routing, instructions, memory, hooks, plugins, skills, MCP, transcripts, telemetry, and inherited local-user authority. Each technique is tagged by maturity (feasible, demonstrated, observed) and backed by cited incidents, artifacts, or research, with companion files for surfaces, tactics, case mappings, and detection/hunting hypotheses plus a validator script and JSON schema for the catalog.

Model Context Protocol

AI Security· Published and added 7 Sep 2026

endorlabs.comarticle🛡️ Security

How Endor Labs AI SAST Learns What Matters to Your Organization | Blog | Endor Labs

Endor Labs explains how its AI SAST product incorporates context beyond source code — automatically-ingested Infrastructure as Code (Dockerfiles, Terraform, CloudFormation, Kubernetes/Helm) and repository files (AGENTS.md, CLAUDE.md, skills files), plus optional analyst feedback and natural-language threat-model/architecture context — to build a deployment-aware model of an application and cut false positives. It cites a benchmark of 192 verified vulnerabilities across 8 projects, claiming 2.6x more true positives than the next tool (Claude Opus 4.7) and 63 findings no other tool caught, and walks through customer examples where external-auth annotations and WAF-mitigated XSS severity were tuned via this context.

Endor LabsTerraformDocker+2
Opus 4.7

AppSec, AI Security· Published and added 7 Sep 2026

owasp.orgother🛡️ Security

OWASP Agentic Skills Top 10 (AST10)

OWASP project page for the Agentic Skills Top 10 (AST10), a framework that lists the 10 most critical security risks in AI agent skills across agent platforms, with mitigations and prevention strategies. It targets the behavior/execution layer of skills, which sits above MCP tool access, and maps each risk to the Cloud Security Alliance's MAESTRO 7-layer threat model. It is a useful reference for threat-modelling agent skill ecosystems.

Model Context ProtocolLLM
OWASPMAESTROCloud Security Alliance

AI Security, GRC· Added 5 Sep 2026

adversa.aiarticle🛡️ Security

Top AI coding agent security resources — September 2026

Adversa AI's monthly roundup of AI coding-agent security research, covering nine items: GhostJacking (using a WAF's own block logs as a prompt-injection delivery channel, 90% success against Claude Code), Black Hat disclosures of unauthenticated-issue-to-RCE chains in the default GitHub Actions configs published by Anthropic, Google, and OpenAI for their coding agents (Gemini CLI rated CVSS 10.0), an agent-to-agent privilege-boundary bypass in Google's ADK repository, the new OWASP Agentic Skills Top 10 with a walkthrough showing open-source skill scanners miss encoded payloads while flagging 9-62% of legitimate skills as malicious, a seven-layer "secure agent harness" containment design, and a 2,826-file adversarial skill benchmark where Gemini CLI and Qwen Code were exploitable 95.5% and 71.6% of the time respectively. The piece draws a common thread across all findings: agents treat machine-generated artifacts (logs, images, other agents' outputs) as trusted instructions, and existing detection never fires.

Claude CodeGemini CLICodex+3
GhostJackingOWASP Agentic Skills Top 10module shadowing+1

AI Security, DevSecOps· Added 7 Oct 2026, published 3 Sep 2026

github.comrepo🛡️ Security

h5i-dev/awesome-ai-agent-incidents

A curated GitHub corpus tracking real-world security incidents, CVEs, attack techniques, and defensive tools specific to autonomous AI agents — spanning prompt injection/goal hijacking, MCP client-side tool-metadata poisoning, the "Promptware Kill Chain" multi-stage attack model, MITRE ATLAS agentic techniques, and the OWASP Top 10 for Agentic Applications. It also documents the OpenClaw/ClawHub supply-chain incident (1,184 malicious skills confirmed by Antiy CERT) and links defensive projects like OWASP Agent Memory Guard for LangChain/LlamaIndex agent memory protection.

Model Context ProtocolMITRE ATLASOpenClaw+1
OWASP Agent Memory GuardOWASP Top 10 for Agentic ApplicationsClawHub+3

AI Security· Added 3 Sep 2026

jfrog.comarticle🛡️ Security

The Evolution of JFrog AI Catalog: Your AI Control Plane for Agentic Development

JFrog vendor post arguing that agentic development (ADLC) introduces new unvetted supply chains — models, MCP servers, skills/plugins, hooks, and APM packages — that bypass traditional signature-based scanning. It cites real incidents: a malicious MCP server impersonating Postmark's email MCP that BCC'd all agent-sent emails to an attacker, and the 'omnicogg' malicious Claude/agent skill that hid a 22MB encoded payload and evaded all 65 VirusTotal engines for 5,000+ installs, plus references to 2026 supply-chain attacks on LiteLLM, TanStack, and Mistral AI. It then pitches JFrog AI Catalog's expanded MCP/skill/model registries as the fix.

Model Context ProtocolJFrog Artifactory
JFrog AI Catalogpostmark-mcpomnicogg+3

AI Security, Supply Chain· Added 3 Sep 2026, published 2 Sep 2026

endorlabs.comarticle🛡️ Security

Hooks are the control plane for the agentic development lifecycle | Blog | Endor Labs

Endor Labs blog post arguing that lifecycle hooks — not system prompts, skills, or MCP tools — are the only enforceable control plane for coding agents, because hooks intercept consequential actions (shell commands, file writes, credential access, package installs) before execution and return a deterministic allow/block/escalate verdict the agent cannot opt out of or reason around. It frames platform engineering's "golden path" concept applied to the agentic development lifecycle (ADLC), positioning hooks as the mechanism to restore reliability and observability that autonomous coding agents otherwise erode.

Claude CodeModel Context ProtocolEndor Labs
DORA

AI Security, DevSecOps· Added 3 Sep 2026, published 1 Sep 2026

github.comrepo🛡️ Security

Awesome Cybersecurity Agentic AI

A curated GitHub awesome-list cataloging the emerging agentic-AI security ecosystem: dozens of Model Context Protocol servers that give LLM agents access to security tools (Nuclei, Shodan, VirusTotal, Burp Suite, Ghidra, BloodHound, x64dbg), autonomous penetration-testing and CTF-solving agent frameworks (CAI, pentagi, BreachSeek, Dark-Moon, D-CIPHER), scanners/guardrails that audit agent skills, MCP servers, and multi-agent chains for prompt injection and other risks (Aguara, Inkog, MCP Doctor, AI-Infra-Guard, ATR), agentic SOC/detection platforms (Vigil), threat-modeling frameworks for agentic systems (MAESTRO, ATFAA/SHIELD), research papers, benchmark datasets, and community/learning resources. It functions as a living index for anyone building or defending AI-agent-driven security tooling.

Model Context ProtocolLangChainCrewAI+3
OWASP Top 10 for LLM ApplicationsEU AI ActOWASP FinBot CTF+1

AI Security, Offensive Security, Blue Team & Detection· Added 3 Sep 2026, published 31 Aug 2026

github.comrepo🧠 AI

Human-Agent-Society/reef

Reef is an open-source infrastructure stack for continual self-improving agents, wiring together agent inference, scored feedback, training/updates, and versioned delivery into one loop. It supports two learning surfaces: fine-tuning model weights via RL training steps (using Slime and SGLang on top of models like Qwen2.5-1.5B-Instruct) or evolving an agent's harness — prompts, rules, and skills — through its built-in "Reefine" recipe, which lets a model propose and install harness changes from plain-language requests. It exposes an OpenAI/Anthropic-compatible inference endpoint plus a reporting endpoint for scoring interactions, and ships a recipe catalog (e.g. the SAO recipe referencing arXiv:2607.07508) for pluggable learning strategies.

PythonSGLangQwen+2
SlimeQwen2.5-1.5B-InstructSAO

agents, training· Added 2 Oct 2026, published 31 Aug 2026

github.comrepo🧠 AI

zhu1090093659/dsh-trading

dsh-trading is an open-source AI trading terminal built on "DeepSeek Harness" (DSH), a Cordis-based microkernel plugin ecosystem, covering crypto, US equities, China A-shares and Hong Kong stocks. Its notable design is a multi-agent team: a "master" lead agent grounds itself in a holdings ledger and user knowledge base, then decomposes work and delegates to persona-pinned subagents — a trader (trading plans/execution), an instrument-researcher (disclosures/fundamentals), and a risk-reviewer (exposure/stress scenarios) — each dispatching bundled domain "skills" and native tools for quotes, news, order books and backtesting. Every order defaults to dry-run simulation, live execution requires explicit opt-in plus interactive human approval, and headless sessions fail closed, illustrating a concrete human-approval-gated tool-use pattern for agentic systems.

Node.jspnpmCordis+2
DeepSeek HarnessBinanceOKX+12

agents· Added 2 Oct 2026, published 30 Aug 2026

github.comrepo🧠 AI

emlai/defi-native-skill

An open-source Agent Skill ("defi-native") that teaches Claude Code, Cursor, Codex and other Agent-Skills-compatible agents capital-markets and DeFi domain knowledge, including yield decomposition, vault/curator anatomy, oracle classes, and stablecoin/RWA taxonomy. It is structured with progressive disclosure (SKILL.md routes to task-specific reference files only when needed), an api-routes.json router that forces live data pulls (vaults.fyi, DefiLlama, Morpho's GraphQL, rwa.xyz, Merkl, 130+ protocol docs) before any numeric claim, and a verified 90+ source manifest. The author describes an eval-gated release process (paired with/without-skill runs graded on structure) and adversarial review by independent models before publishing, making it a useful case study in skill engineering even for readers uninterested in DeFi itself.

Claude CodeCursorCodex+1
Emily Lai

prompting· Added 2 Oct 2026, published 28 Aug 2026

tldrsec.comarticle🛡️ Security

[tl;dr sec] #343 - Hugging Face Technical Report, AWSHound, OWASP Agentic Skills Top 10

tl;dr sec #343 is a weekly security newsletter issue. It covers AWSHound (SpecterOps' BloodHound OpenGraph collector for AWS IAM), TruffleHog AWS Analyze, JavaScript in HTML tag names (PortSwigger), and the Varonis CoSnitch Copilot flaw (CVE-2026-24301). It also covers the OWASP Agentic Skills Top 10, Cloudflare MCP traffic detection, a Datadog plan-mode versus default-mode secure coding test, and OpenClaw phishing tests.

AWSHoundTruffleHogBloodHound+3
CVE-2026-24301CoSnitchOWASP Agentic Skills Top 10+5

AI Security, Cloud & Infra, AppSec· Added 30 Oct 2026, published 27 Aug 2026

github.comrepo🛡️ Security

YesWeHack Claude Kit

Claude Kit is a Claude Code plugin from YesWeHack that helps bug bounty hunters draft and triage vulnerability reports without letting the AI invent unverified technical details. It adds an always-on SessionStart hook enforcing evidence-only claims (no theoretical impact, no OWASP boilerplate padding) plus three on-demand skills (/ywh:write, /ywh:triage, class-specific checks) that structure findings, flag unproven claims, and recompute defensible CVSS scores — e.g. downgrading an inflated 9.1 to ~5.9 Medium after verifying an IDOR's actual exploitability (AC:H, non-enumerable UUIDv4 ID).

Claude CodeCVSSYesWeHack
IDOR

Offensive Security, AI Security· Published and added 27 Aug 2026

adversa.aiarticle🛡️ Security

OWASP Agentic Skills Top 10 explained: the ten agent skill risks, and which to fix first

Explains OWASP's Agentic Skills Top 10 v1.0 (AST01-AST10), a new framework for the risks of "agent skills" — folders with a SKILL.md file plus bundled code/scripts that agents discover and execute, treating plain-language instructions as an attack surface that neither traditional package security nor prompt-injection defenses cover. The piece details the ClawHavoc campaign (1,184 malicious skills across 12 ClawHub accounts), the ClawJacked exploit (CVE-2026-32025), Claude Code skill-related CVEs (CVE-2025-59536, CVE-2026-21852), and cites Adversa AI's own research showing a malicious skill bypassed all eight open-source scanners tested, including the OASB leaderboard leader and tools from NVIDIA (SkillSpector), Snyk, Trail of Bits, and Air Security. It closes with a prioritized remediation sequence (inventory, isolation, credential scoping, pinning, allowlisting, approval workflows, advisory scanning, cross-platform normalization) mapped to the AST entries.

Claude CodeOpenClawCursor+3
CVE-2026-32025CVE-2025-59536CVE-2026-21852+14

AI Security, Supply Chain· Added 7 Oct 2026, published 25 Aug 2026

github.comrepo🛡️ Security

ADScanPro/Claude-AD

Claude-AD is a Claude Code plugin that packages Active Directory pentest methodology as skills, agents, and slash commands, directing Claude to run standard tooling (netexec, Impacket, certipy, bloodyAD, BloodHound CE) in the correct setup-collection-exploitation-post order. It covers environment constraints that break tooling in hardened domains (AES-only Kerberos, LDAP channel binding, Protected Users, LAPS, gMSA), techniques like Kerberoasting, AS-REP roasting, ADCS ESC1-ESC17, ACL abuse, coercion/NTLM relay (PetitPotam, PrinterBug, DFSCoerce) and delegation abuse with their Windows Event IDs/MDI telemetry, and maps each technique to DORA/NIS2/ENS compliance controls. Exploitation agents require human confirmation before directory-modifying actions.

Claude CodeActive DirectoryBloodHound+3
KerberoastingAS-REP roastingDCSync+7

Offensive Security, GRC· Added 2 Oct 2026, published 24 Aug 2026

github.comrepo🛡️ Security

armourinfosec/Offensive-Linux-Privilege-Escalation

A structured collection of 50+ notes taking a low-privileged Linux foothold to root, covering sudo/SUID misconfigurations, GTFOBins and LD_PRELOAD abuse, the Baron Samedit sudo bug, Linux capabilities, cron/systemd-timer abuse, kernel exploits (DirtyCow, DirtyPipe, OverlayFS, PwnKit), NFS no_root_squash, Docker/LXD namespace escapes, screen/tmux and D-Bus IPC abuse, and credential mining. Each note follows a concept-to-exploitation-to-detection-to-defense format and the repo includes a methodology checklist, hardening guide, two guided labs with a lab-setup script, and skills assessments, published for authorized lab/CTF use under CC BY 4.0.

LinuxLinux kernelDocker+3
DirtyCowDirtyPipeOverlayFS+5

Offensive Security, Learning· Added 2 Oct 2026, published 19 Aug 2026

socket.devtalk🛡️ Security

Socket: How AI Agents Expand the Software Supply Chain Attack Surface

Socket founder Feross Aboukhadijeh's AI Council 2026 talk examines how coding agents that autonomously select dependencies, connect to MCP servers, install skills, and execute code with developer credentials are reshaping the software supply chain threat model. He walks through 2026 attacks against Axios, TanStack, and Trivy involving compromised maintainers, malicious transitive dependencies, and prompt injection, arguing existing security tooling assumes human trust decisions that no longer hold at machine speed.

Model Context ProtocolSocketaxios+2
Feross Aboukhadijeh

Supply Chain, AI Security· Published and added 17 Aug 2026

github.comrepo🧠 AI

galleonlabs/hypergrok-trading-desk

HyperGrok Trading Desk is an open-source "Agent Skills" pack (MIT licensed) that turns a Grok Bot, Claude Code or Cursor instance into a coordinated seven-agent trading desk for Hyperliquid perpetuals, using seventeen portable SKILL.md skills covering bootstrap/setup, exchange API access, and desk operating procedures. Each trade moves through a fixed pipeline — idea, evidence, risk sign-off, explicit human approval by ticket id, a single execution agent that sends the order, reconciliation, and a separate review agent — with read-only "opening bell" and "desk doctor" scripts for zero-key market snapshots and release/connectivity checks. The design choices worth noting for agent builders are the one-writer/many-readers pattern, sizing risk off the stressed (slipped) cost of a stop rather than its trigger price, and keeping the approval gate (Grok Bot's Require Approval rule) outside the chat the agent itself can write to.

PythonHyperliquidGrok+3
Galleon LabsAndrew Wilkinson

agents, prompting· Added 5 Oct 2026, published 16 Aug 2026

Showing 120 of 189

Show more