en.cryptonomist.charticle🧠 AI
Revolut’s AI cost reduction hits 90% with Chinese GLM models
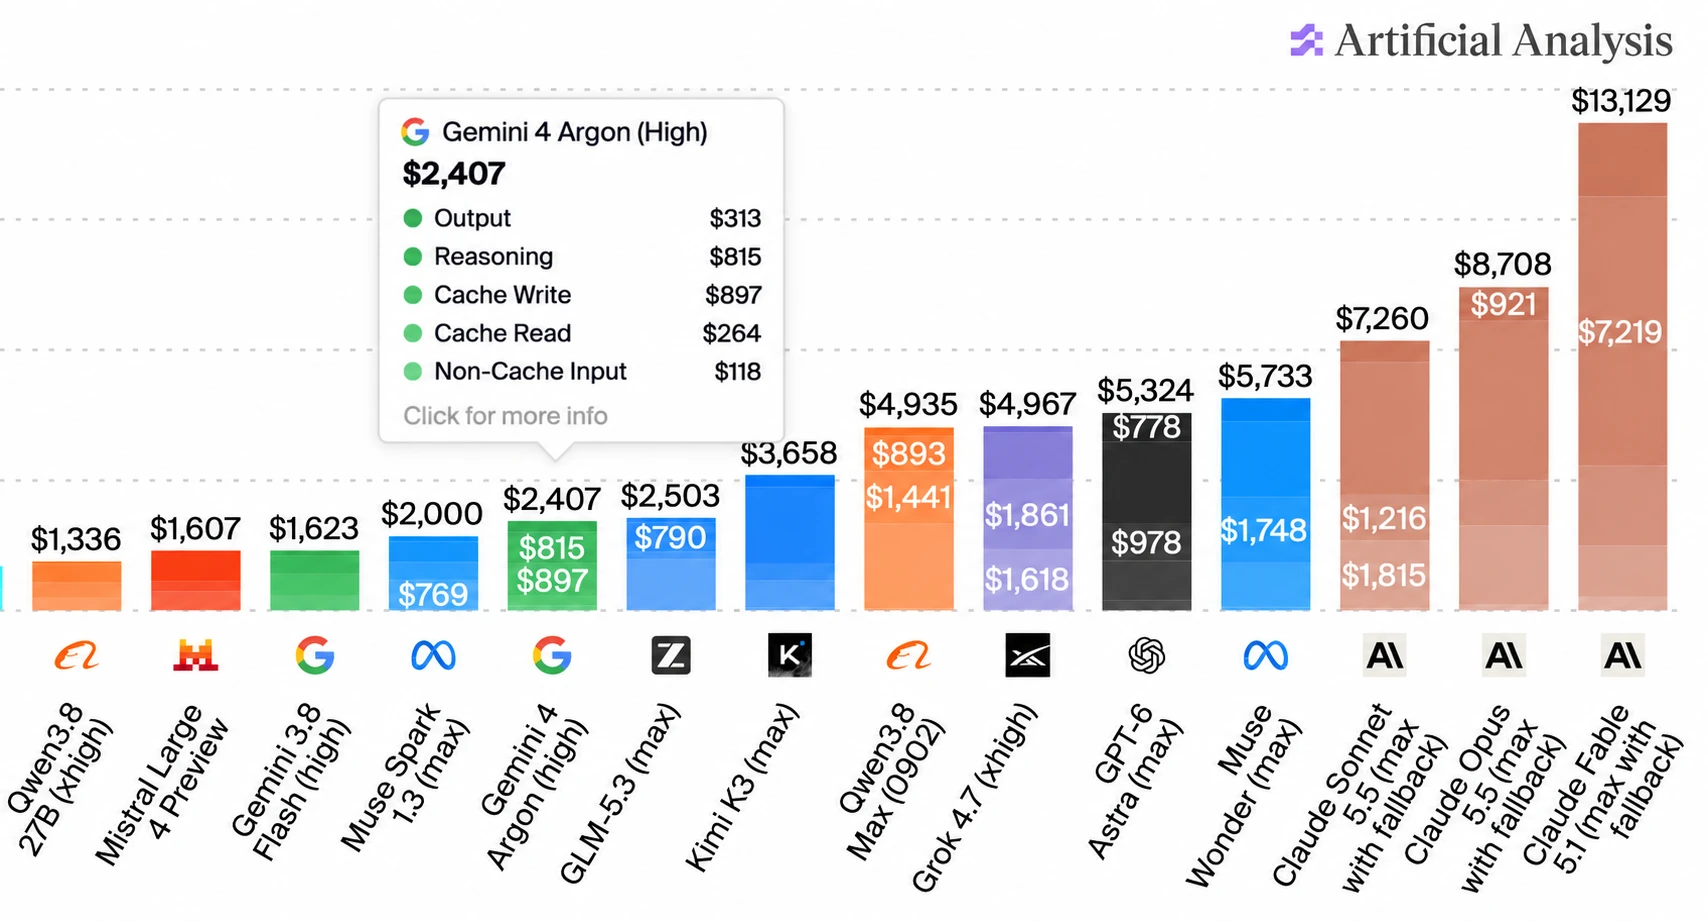
Revolut reports cutting AI costs by about 90% after moving about 2,000 engineers from OpenAI and Anthropic services to Z.ai's GLM 5.3, self-hosted on 56 NVIDIA B200 GPUs. Head of AI operations David Abitbol cites $0.30 per million tokens and time to first token falling from 14.26 to 1.68 seconds between April and August 2026. FP4 quantization and KV cache tuning drove the gains. The report gives no deployment detail beyond these figures.
GLMNVIDIA B200FP4 quantization+1
RevolutZ.aiGLM-5.3+4
inference, ai-infra, ai-policy· Published and added 3 Nov 2026